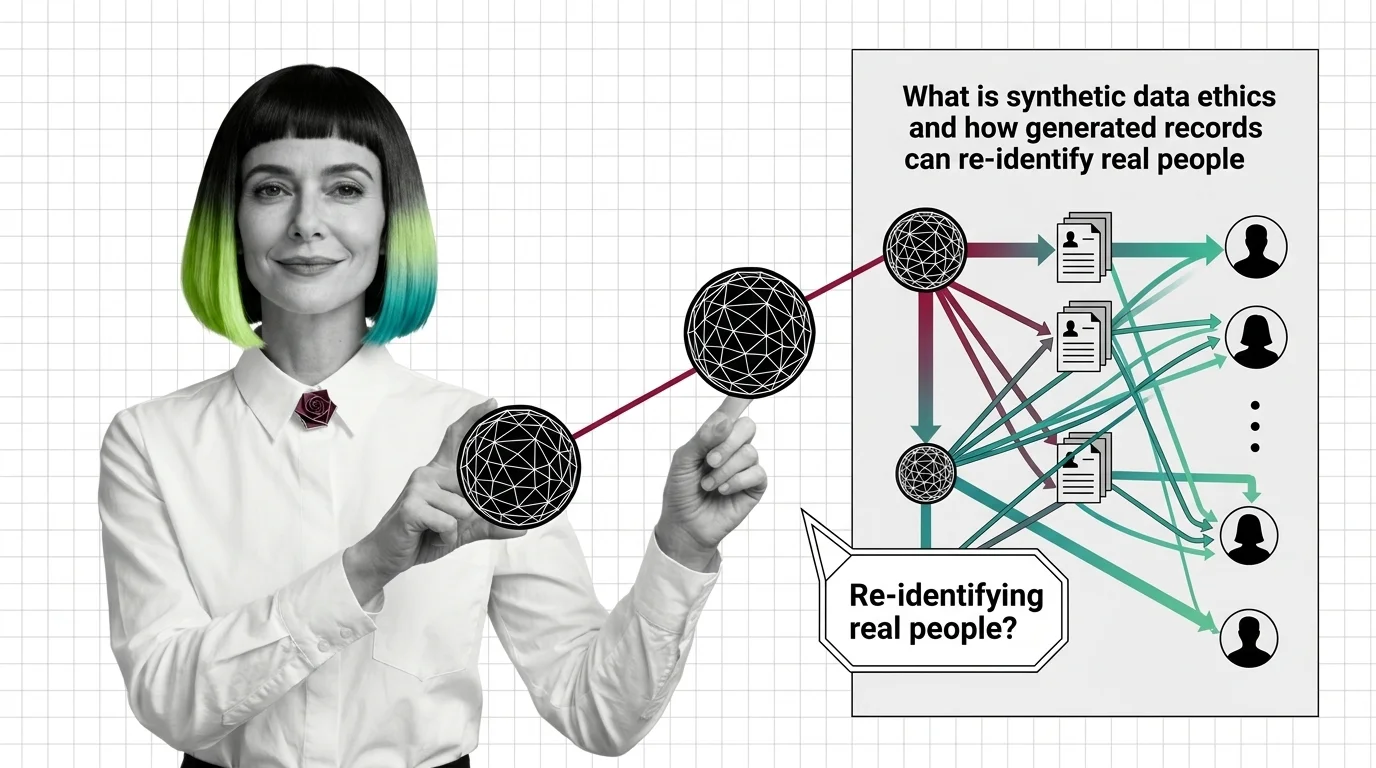
What Is Synthetic Data Ethics and How Generated Records Can Re-Identify Real People
Synthetic data ethics covers the privacy, bias, and consent risks of machine-made records. A faithful generator can re-identify the people it learned from.
Companies sit on mountains of sensitive records: patient histories, transaction logs, support tickets. They want to build and test AI systems on that data without handing real customer information to every engineer, vendor, or model. Synthetic data promises a clean way out: generate artificial records that look and behave like the real ones but belong to no actual person. Synthetic data ethics is the discipline that asks whether that promise actually holds, and what responsibilities you keep even when the data is “fake.”
The core idea is statistical imitation. A generation model studies the patterns in a real dataset (the distribution of ages, the correlation between income and default rate, the phrasing of customer complaints) and then produces new rows that follow the same patterns without copying any single original record. Done well, the synthetic set supports the same analysis or model training as the original while breaking the direct link to identifiable individuals.
The ethics enter where the imitation gets too good. If a generator memorizes rare cases (the one patient with a unique combination of conditions, the single high-value account in a small region) it can reproduce those outliers closely enough that someone with side knowledge can match a synthetic record back to a real person. This is re-identification, and it is the central risk that gives this field its name. Consent is a second fault line: data collected for one purpose, then used to train a generator, can quietly become the seed for products the original people never agreed to. Bias is a third: a generator trained on skewed historical data will faithfully reproduce that skew, and sometimes amplify it, so “synthetic” does not mean “neutral.” None of these risks announce themselves, which is why the ethics here rest on process and proof, not on good intentions alone.
The scenario most readers meet first is data sharing under restriction. A product team wants to test a new feature, train a model, or hand a dataset to an outside vendor, but the real records are governed by privacy rules (GDPR, HIPAA, internal policy) that make sharing the raw data slow or forbidden. Generating a synthetic copy looks like the unblock: the vendor gets realistic data, no real customer is named, and legal review moves faster.
In practice, synthetic data ethics shows up as the checklist that decides whether that copy is actually safe to release. Teams run privacy attacks against their own synthetic set (can any row be linked back to a real person?), measure how closely outliers were reproduced, and document the consent basis of the original data before it fed the generator. This is increasingly paired with a formal privacy guarantee such as differential privacy, which adds mathematical noise so no single individual measurably changes the output.
Before you treat a synthetic dataset as “anonymous,” ask the vendor or your data team for the re-identification test results, not just the marketing claim. A dataset is only as safe as the worst-case match on its rarest record, so look at how the outliers were handled, not the average.
Start with how generated records can re-identify real people — it lays out the mechanism the rest of the topic depends on: why a fabricated row can still point back to the real person behind it. Follow immediately with the fidelity-privacy tradeoff, which turns that mechanism into a hard limit — the same statistical closeness that makes a dataset useful is what makes it exploitable.
Once the failure mode is clear, MAX’s guide to generating privacy-safe synthetic data with MOSTLY AI, Tonic.ai, and differential privacy is the practical defense: a way to put a measurable budget on the leakage the first two articles describe. For where regulation and the market are landing, the 2026 consolidation and regulatory reckoning tracks the EU AI Act and vendor buyouts closing the loophole from two directions at once. Close with the two opinion pieces that keep the debate honest: is synthetic data a legitimate way around GDPR, or consent laundering, and does synthetic data clean bias or concentrate it.
Two topics get folded into this one, and each folding hides a different question.
| Scenario | Use | Avoid |
|---|---|---|
| Sharing realistic test data with an external vendor under privacy rules | ✅ | |
| Treating synthetic data as automatically anonymous, with no re-identification test | ❌ | |
| Training or demoing on data when real records are legally restricted | ✅ | |
| Generating from a tiny dataset full of rare, identifiable outliers | ❌ | |
| Augmenting a balanced dataset to fill a known, documented gap | ✅ | |
| Using it to sidestep consent the original people never gave | ❌ |
Q: Does enabling a tool’s differential-privacy option make my synthetic dataset compliant by itself? A: No — differential privacy sets a mathematical leakage budget, but the budget still has to be tight enough to matter and the data still has to clear a utility floor. MAX’s guide to generating privacy-safe synthetic data treats the option as one gate among several, not a checkbox that ends the review.
Q: If my synthetic data passes a bias audit, does that mean it is also safe from re-identification? A: No — bias and privacy are separate failure modes with independent tests. A dataset can look statistically balanced and still leak the rare real records behind it, because the fidelity-privacy tradeoff runs on its own axis regardless of how fair the output distribution looks.
Q: Does anonymizing the source data before generation remove the ethical risk? A: Not by itself. How generated records can re-identify real people shows the risk sits in what the generator learned, not just what the raw file contained — a model can reproduce a rare individual’s pattern closely enough to identify them even from de-identified inputs. Anonymize the source, then test the output separately.
Q: Will the EU AI Act make synthetic data legally safer to use, or just harder to use carelessly? A: The second. The 2026 consolidation and regulatory reckoning tracks transparency and watermarking obligations landing this year, with heavier high-risk duties following in 2027-2028 — the law adds audit-trail requirements, it does not certify any dataset as automatically safe.
Q: Who is accountable if a synthetic dataset trained on biased records causes real-world harm? A: The question the field has not settled. Generation adds a technical layer between the original bias and the harm it causes, which is exactly what makes assigning responsibility harder. Does synthetic data clean or concentrate discrimination argues the bias does not disappear — it just becomes harder to trace back to a decision anyone made.
Part of the synthetic data theme · closest neighbour: synthetic data generation.
Start here to see what synthetic data ethics actually rests on: how a generated record that copies no one can still point back to a real person, and why 'anonymous' is a claim that has to be tested, not assumed.
Concepts covered
Synthetic data ethics covers the privacy, bias, and consent risks of machine-made records. A faithful generator can re-identify the people it learned from.
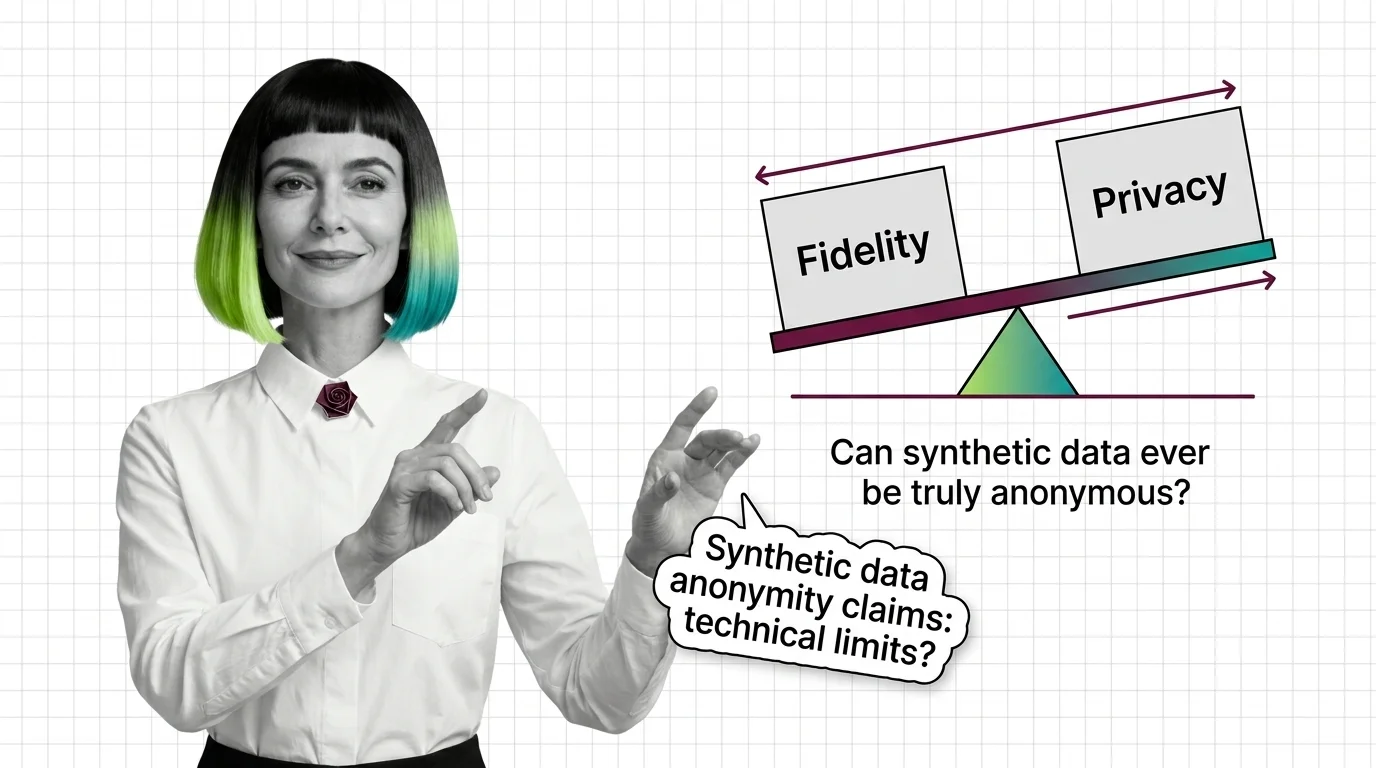
Synthetic data is not anonymous. Membership inference can reveal who was in the training set, and differential privacy trades utility for protection.
These guides cover generating synthetic data you can actually defend: which tools and privacy techniques hold up, what fidelity you give up to keep records safe, and where the trade-off between useful and exposed really sits.
Tools & techniques
Privacy-safe synthetic data needs differential privacy and a membership inference attack test, not just fake rows. MOSTLY AI's SDK runs locally.
The market and rules around synthetic data are shifting fast, with vendors consolidating and regulators deciding whether generated data counts as anonymous. Following these developments tells you when a privacy claim holds and when it is about to break.
Models & benchmarks
Updated October 2026
Big tech is absorbing synthetic-data startups while the EU AI Act and privacy research expose its anonymity promise as conditional, not guaranteed.
Before you treat synthetic data as a privacy fix, weigh what it can quietly do: leak the identities it was meant to protect, concentrate the bias in its source records, and let an organization claim consent it never actually obtained.
Risks & metrics
Generating synthetic data from real records is itself GDPR processing, and membership inference attacks can still expose the outliers it claims to protect.
Synthetic data can both reduce and amplify bias depending on method. Naive generation and differential privacy distort underrepresented groups most.