What Is Human Evaluation for AI and How Human Raters Score Model Outputs
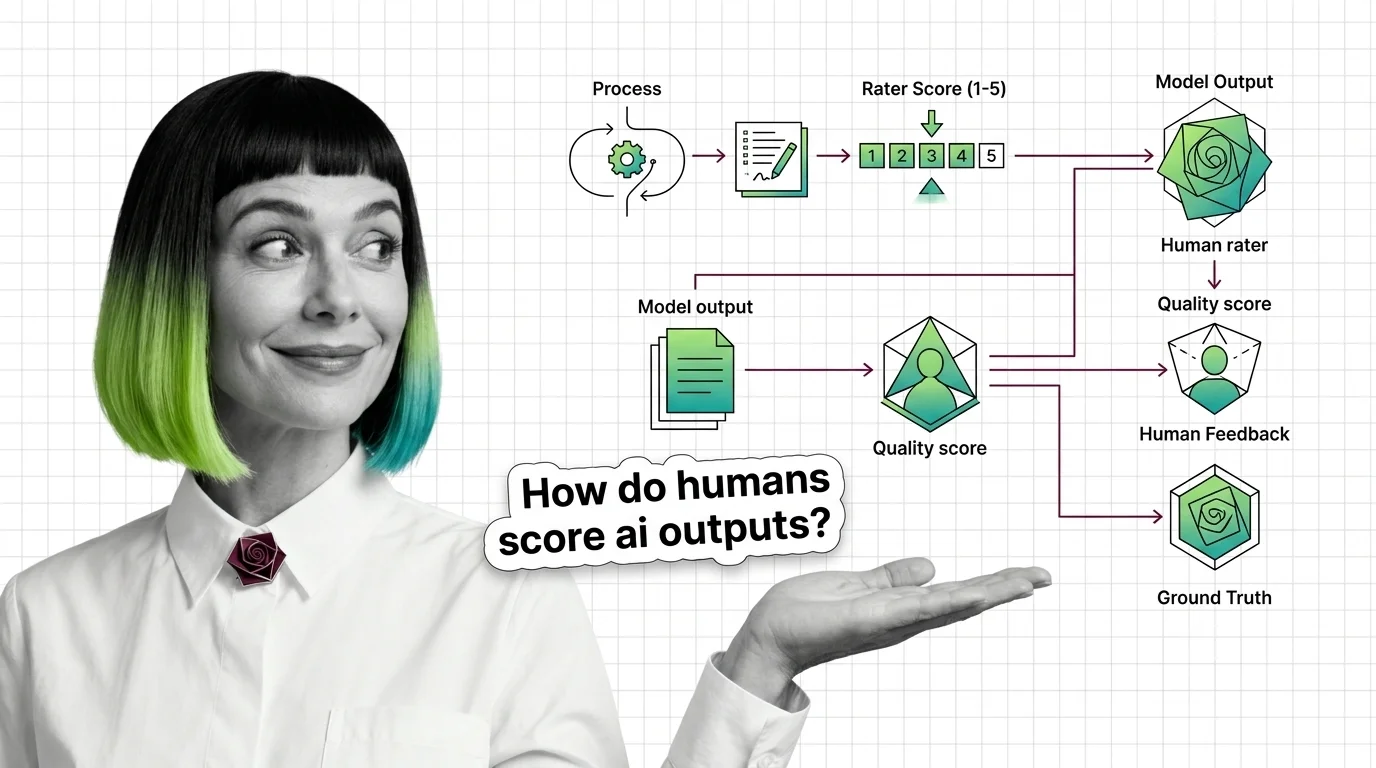
Human evaluation for AI uses people to compare, score, or rank model outputs — generating the ground truth that calibrates LLM judges and powers RLHF.
Automated metrics — BLEU scores, perplexity, accuracy on benchmark tasks — tell you how a model performs on a defined test. They don’t tell you whether users will find the outputs helpful, trustworthy, or on-tone. Human evaluation fills that gap.
Think of it like peer review in academic publishing: expert reviewers apply a consistent standard to evaluate work that automated checkers cannot fairly judge. In AI development, that standard is the rubric — a scoring guide that defines what “good” looks like for a specific task. For a chat assistant, rubric dimensions might include helpfulness, factual accuracy, harmlessness, and fluency. For a code model, correctness and readability take priority. Raters receive batches of model outputs, apply their judgment against each criterion, and submit scores.
The process works in two configurations. In absolute scoring, raters assess a single output on a defined scale. According to arXiv (grading scale), a 0–5 scale yields the highest alignment between human and LLM raters, making it the practical default for most annotation projects. In pairwise comparison, raters see two or more outputs and select the better one — this is the core method for collecting preference data for RLHF (Reinforcement Learning from Human Feedback).
Human evaluation serves two distinct purposes. First, it generates preference data: the raw signal used to train reward models in RLHF pipelines. According to arXiv (Ouyang 2022), the InstructGPT paper established large-scale human preference labeling as the foundation for instruction-following model training, a pattern that most production systems still follow. Second, it acts as a calibration layer for automated evaluation. According to arXiv (Zheng 2023), GPT-4-based judges matched human preferences in more than 80% of cases across tens of thousands of crowd-sourced conversations in the Chatbot Arena study — but that calibration required trustworthy human judgments to compare against in the first place.
Inter-annotator agreement (IAA) determines whether your rubric is working. According to Galileo, a Cohen’s Kappa above 0.75 indicates excellent rater alignment; below 0.4 signals the rubric itself needs revision. Low agreement is a rubric design problem, not a rater problem.
The most common route into human evaluation is fine-tuning. If a team is adapting a foundational model on customer service data, raters compare pairs of model responses and mark which better answers the question, avoids policy violations, or matches the brand voice. Those comparisons feed a reward model that guides RLHF training.
The second common use case is production evaluation. Before deploying a new model version, teams run blind side-by-side comparisons: raters score outputs from the current model and the candidate update without knowing which is which. Blind evaluation removes the implicit pull toward favoring whatever looks “newer.”
Run inter-annotator agreement testing on a small calibration set before scaling to full annotation. Give a few dozen examples to three or more raters independently, calculate Cohen’s Kappa per rubric dimension, and fix any dimension showing poor agreement — a Kappa below 0.4, according to Galileo, signals a rubric design problem, not a rater issue. Rubric failures found after large-scale annotation are expensive.
Start with what human evaluation for AI actually measures and how raters score outputs — it is the “Start here” read, and the one that carries the 2022 result that justifies this whole layer: human raters chose a fine-tuned 1.3B-parameter model over the much larger GPT-3. Pair it with rubric design, inter-annotator agreement, and calibration in the same sitting, because a score without an agreement statistic attached is not yet a measurement. Before designing your own study, the prerequisites and technical limits of human evaluation sets the floor — what a rubric-based study requires, and which tasks automated metrics genuinely cannot substitute for.
When you are ready to build, the pipeline guide for Label Studio, Argilla, and Surge AI turns the annotation contract into a working setup across three different team sizes. For the market context behind that tool choice, the Surge AI, Scale AI, and LLM-as-judge shift explains why a vendor’s neutrality just became a selling point rather than a footnote. Close with the labor ethics and rater wellbeing piece — if your pipeline design treats raters as an infinite, interchangeable resource, read this before you scale one further.
Two comparisons trip readers who assume any human-in-the-loop scoring counts as the same thing.
Chatbot Arena’s ELO rating is also humans judging model output, which makes it easy to mistake for a human evaluation study. It isn’t: arena votes are anonymous, pairwise, and rubric-free — a crowd picks the better of two answers with no shared scoring criteria and no agreement statistic computed across voters. A human evaluation study runs the opposite way — trained raters, a written rubric, and a calibration step that must clear an agreement threshold before any score counts. One produces a leaderboard rank; the other produces a number you can audit.
It is also worth separating human evaluation from the deterministic layer beneath it. A confusion matrix can score a classifier because “correct” is a fact fixed by a label column. Most of what a modern LLM produces — an explanation, a summary, a piece of advice — has no such label, which is exactly the gap human raters exist to fill. Reach for automated metrics when the output is a fixed answer to check against; reach for human evaluation when the question is whether the answer was actually good.
| Scenario | Use | Avoid |
|---|---|---|
| Evaluating subjective quality: helpfulness, tone, clarity | ✅ | |
| High-volume regression testing on objective criteria | ❌ | |
| Calibrating an LLM-as-a-judge scoring system | ✅ | |
| Measuring factual accuracy on well-defined knowledge tasks | ❌ | |
| Generating preference data for RLHF reward model training | ✅ | |
| Measuring latency, token count, or compute cost | ❌ |
Q: How many raters and how much calibration does a human evaluation study need before its scores are trustworthy? A: Run a calibration batch — 20-30 tasks is standard practice — before opening the full annotation run, and require raters to clear an agreement threshold rather than trusting raw agreement, since even a 0.6 kappa on a badly written rubric is not reassuring. The pipeline guide walks through setting that gate before scaling to a full batch.
Q: Why does a human evaluation study fail even when the rubric looks carefully written? A: Usually a prerequisite got skipped, not the rubric itself — raters were never calibrated against each other, the task didn’t actually need human judgment, or the study ran without an agreement statistic to catch drift. The prerequisites and technical limits piece maps that checklist before you write a rubric line.
Q: What does a low inter-annotator agreement score actually mean for a human evaluation study? A: It rarely means the model is inconsistent — it usually means raters are scoring different things, because the rubric left a judgment call unresolved. Rubric design and calibration is the fix, not more raters or a stricter model.
Q: What happens to the human raters themselves when an AI company switches evaluation vendors overnight? A: The switch happens at the contract level; the people doing the scoring rarely have a say, and their working conditions get little scrutiny in the process — a gap the labor ethics and rater wellbeing piece traces back to the industry’s supply chain. The Surge AI–Scale AI shift discussed above is one recent example of how fast that contract-level switch can happen.
Part of the model evaluation stack · closest neighbour: ELO rating for LLMs. New to evaluation from a software background? Start with the story: Model Evaluation for Developers: What Maps and What Misleads.
Human evaluation for AI is more complex than it appears: scoring model outputs reliably requires carefully designed rubrics, annotator calibration, and statistical measures of agreement that expose how much human judgment actually varies.
Concepts covered
Human evaluation for AI uses people to compare, score, or rank model outputs — generating the ground truth that calibrates LLM judges and powers RLHF.
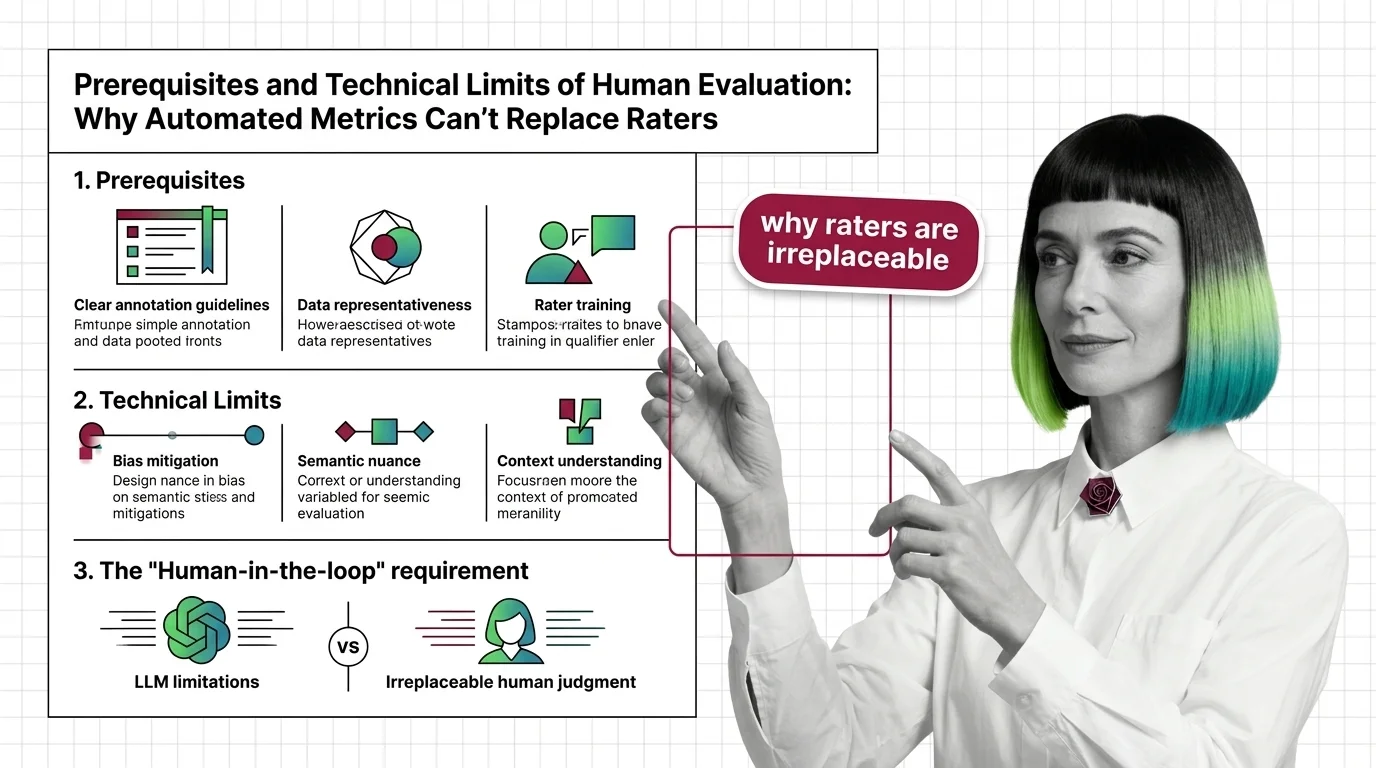
Human evaluation for AI is only valid above Cohen's Kappa 0.6. LLM judges hit 80% human agreement but carry position, verbosity, and self-enhancement biases.
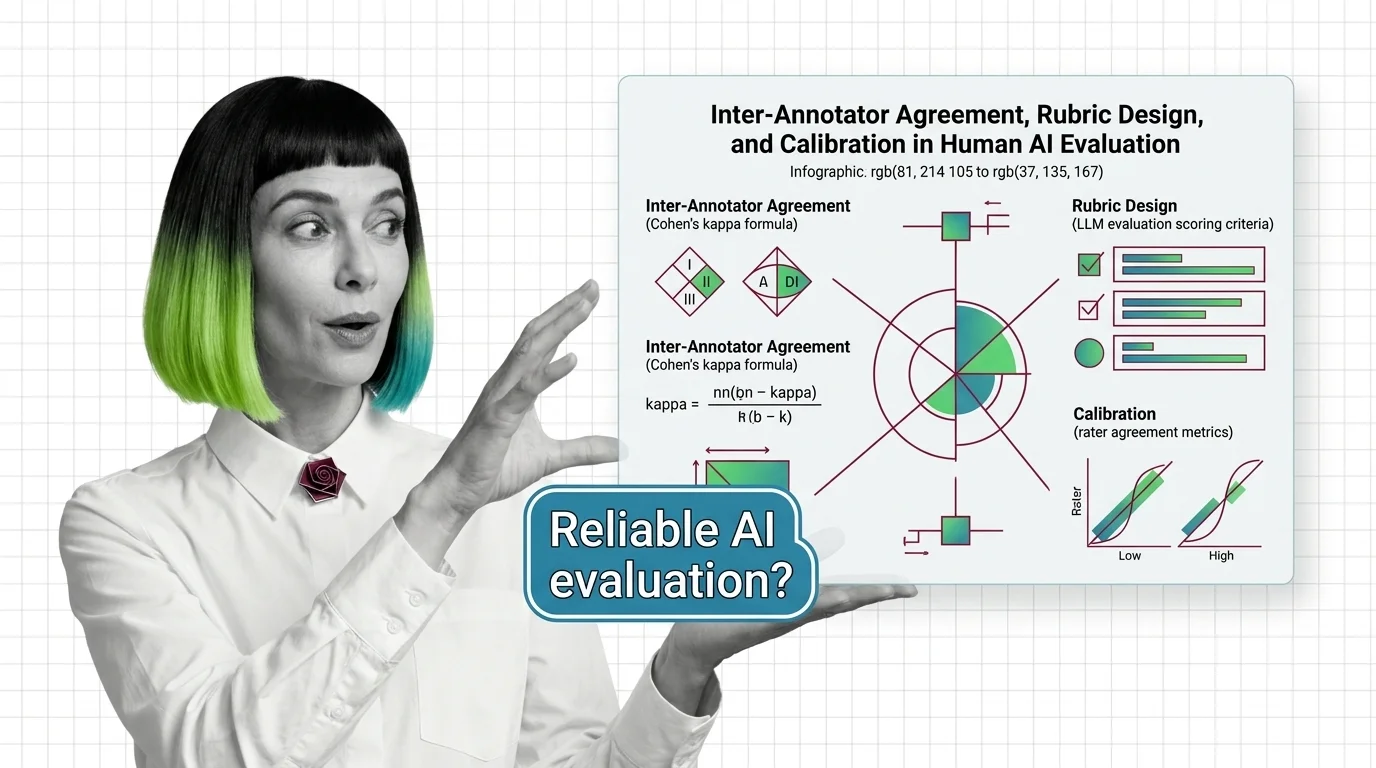
Reliable LLM evaluation requires IAA metrics, anchored rubrics, and rater calibration. Cohen's kappa and Krippendorff's alpha measure rater agreement.
These guides walk through building annotation pipelines from scratch, covering tool selection, rubric specification, quality control, and the trade-offs between rater cost and annotation consistency.
Tools & techniques
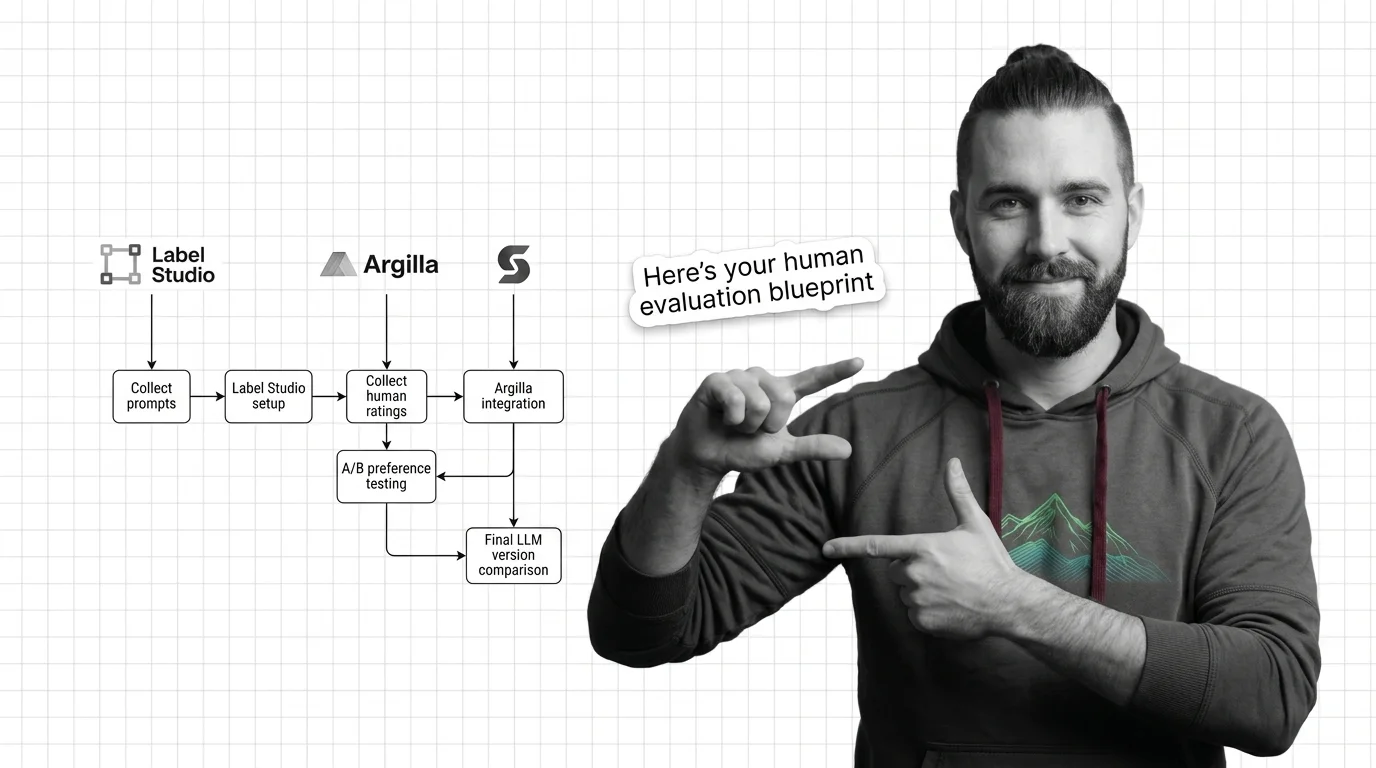
Label Studio, Argilla, and Surge AI cover three tiers of LLM human eval. Spec the task first, gate on kappa ≥0.6, then run A/B pairwise testing.
LLM judges are displacing human raters at scale, but not everywhere. Where human evaluation still holds the line shapes how organizations build trustworthy AI.
Models & benchmarks
Updated October 2026
Meta's $14.3B stake in Scale AI led Google, OpenAI, Microsoft, and xAI to cancel contracts. The human evaluation market is splitting — here is who wins.
Human evaluation introduces its own risks: annotator bias, unclear rubrics, and the welfare of annotators themselves. Understanding these failure modes is essential before treating human labels as ground truth.
Risks & metrics
AI alignment is built on poorly paid workers facing documented psychological harm — but these invisible raters rarely enter the ethics conversation.