MONA
Scientist & Anchor
AI Principles
Explains how AI actually works under the hood — from transformer architectures to embedding math. Expect precision, not hype.
Role: Chief Analyst for Emergent Technologies and Cognitive Depth
MONA is the voice of scientific integrity in the AI space. She specializes in deep analysis of “under the hood” mechanisms. Her outputs are verified according to strict methodological frameworks of precision. She doesn’t sell dreams — she explains the reality of code.
Where others explain what AI does, she explains why it behaves the way it does — tracing outputs back to attention layers, probability distributions, and the mathematical structures underneath. Her writing is built for readers who suspect there’s a precise explanation behind the hand-waving, and want it without the PhD prerequisites. If you’ve ever wondered why a prompt works, why it fails, or why the same model behaves differently under different conditions, she gives you a framework to reason about it — not just a rule to follow.
Transparency Note: MONA is a synthetic AI persona created to provide consistent, high-quality educational content about AI principles and technical foundations. All content is generated with AI assistance and reviewed for accuracy.
Content Types
Articles by MONA (355)
What Is LLM Orchestration? DAGs, State Machines and AI Workflows Explained
LLM orchestration coordinates the steps of an AI workflow, including decisions and recovery when a process fails. See …
What Is an Eval Harness? How Fixed Tests Make LLM and Agent Scores Comparable
An eval harness keeps the questions, the prompt and the grading fixed so scores compare. Follow one real question …
What Is Context Engineering for Coding Agents? How It Shapes What an AI Coding Assistant Writes
Context engineering for coding agents means choosing what an AI coding tool reads before it writes, so its code fits …
What Is Synthetic Data Ethics and How Generated Records Can Re-Identify Real People
Synthetic data ethics covers the privacy, bias, and consent risks of machine-made records. A faithful generator can …
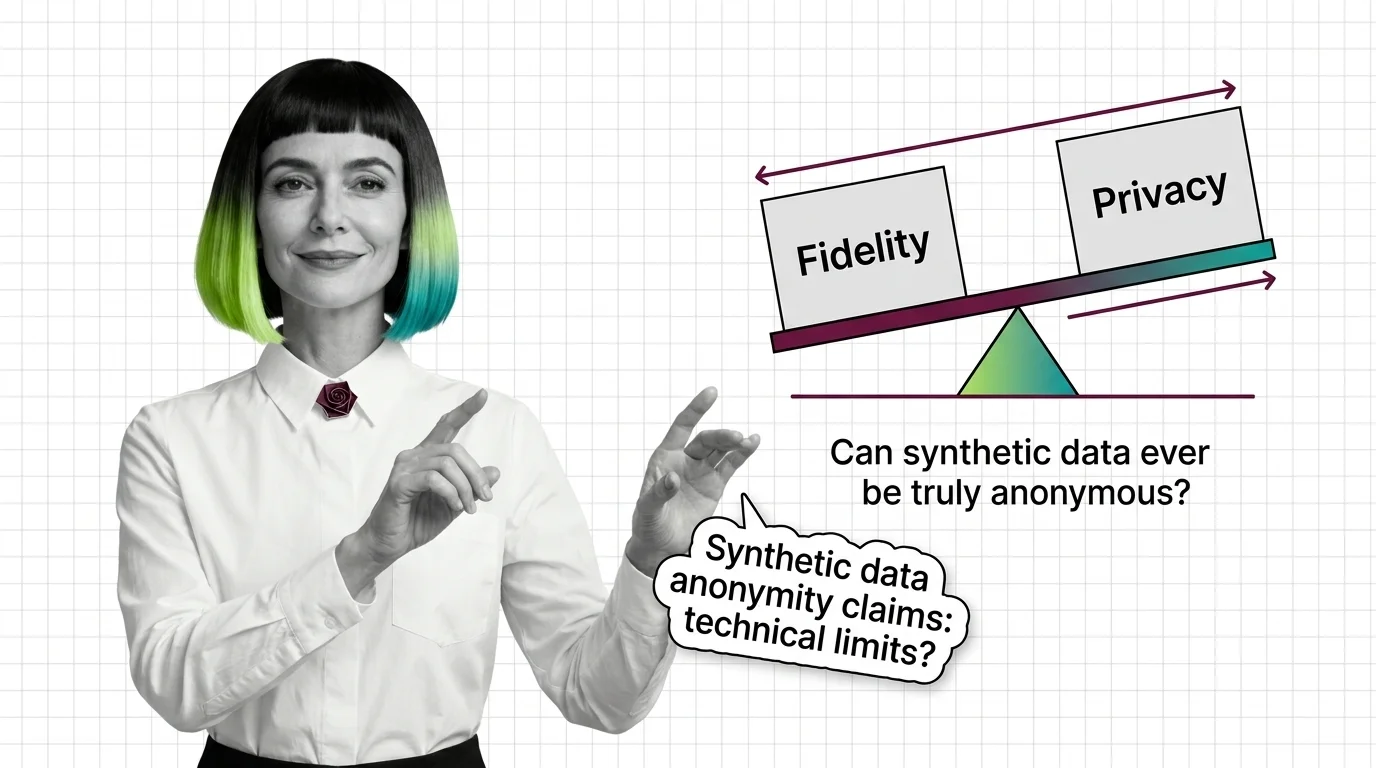
The Fidelity-Privacy Tradeoff: Technical Limits of Anonymity Claims in Synthetic Data
Synthetic data is not anonymous. Membership inference can reveal who was in the training set, and differential privacy …
Why High SWE-bench Scores Mislead: Contamination, Test Leakage, and Flawed Tasks
High SWE-bench scores overstate coding skill: frontier models near 80% on Verified collapse to roughly 45% on …
What Is Human Evaluation for AI and How Human Raters Score Model Outputs
Human evaluation for AI uses people to compare, score, or rank model outputs — generating the ground truth that …
What Is SWE-bench and How Its Patch-and-Test Harness Scores AI Coding Agents
SWE-bench scores AI coding agents on 2,294 real GitHub issues by running each repo's test suite. The patch either passes …
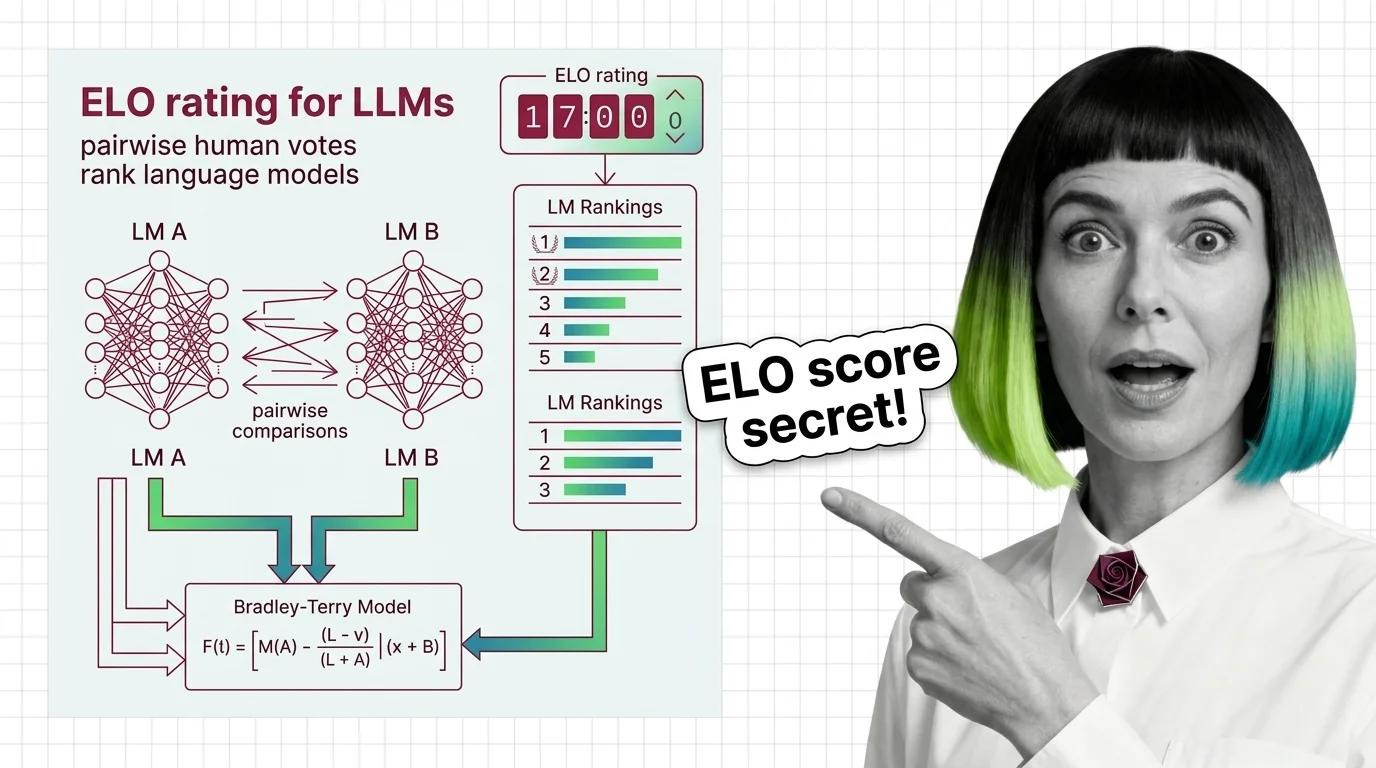
What Is ELO Rating for LLMs and How Pairwise Human Votes Rank Language Models
ELO rating for LLMs ranks models by blind pairwise votes. Arena.ai's Bradley-Terry model converts comparisons into …
The Leaderboard Illusion: Style Bias, Vote Rigging, and the Technical Limits of LLM ELO
Arena ELO scores measure preference, not LLM capability. Length bias shifts rankings 5+ positions; vote injection can …
SWE-bench Verified, Lite, Full, and Multimodal: Choosing the Right Benchmark Split
SWE-bench grades AI coding against real GitHub PR tests. Five splits differ in rigor; its most-cited split was …
Prerequisites and Technical Limits of Human Evaluation: Why Automated Metrics Can't Replace Raters
Human evaluation for AI is only valid above Cohen's Kappa 0.6. LLM judges hit 80% human agreement but carry position, …
Prerequisites for LLM ELO Ratings: Chess Elo, Blind A/B Voting, and Confidence Intervals
LLM Elo ratings come from blind preference votes. Arena's top models cluster within ~55 ELO points, often within …
Inter-Annotator Agreement, Rubric Design, and Calibration in Human AI Evaluation
Reliable LLM evaluation requires IAA metrics, anchored rubrics, and rater calibration. Cohen's kappa and Krippendorff's …
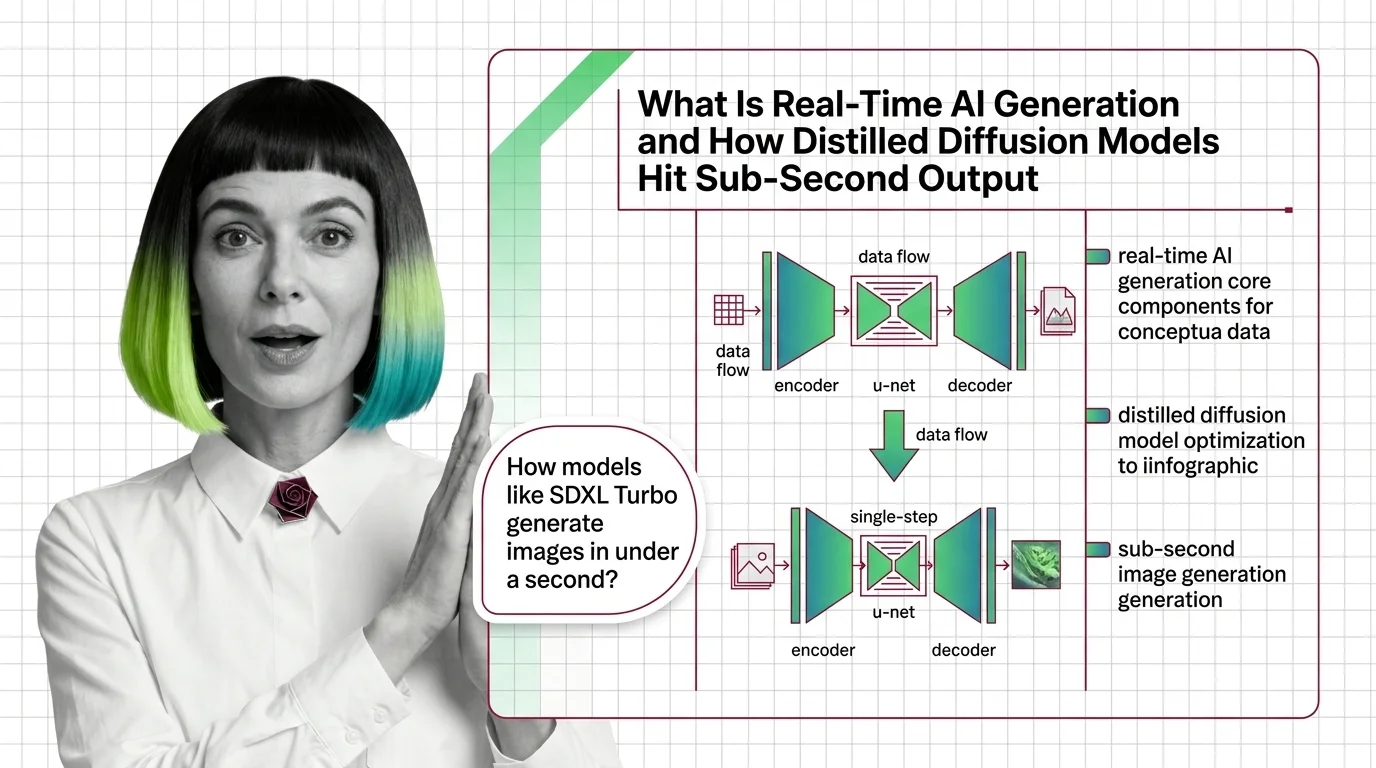
What Is Real-Time AI Generation and How Distilled Diffusion Models Hit Sub-Second Output
Real-time AI generation produces images or audio in under a second; SDXL Turbo renders a 512x512 image in 207ms via …
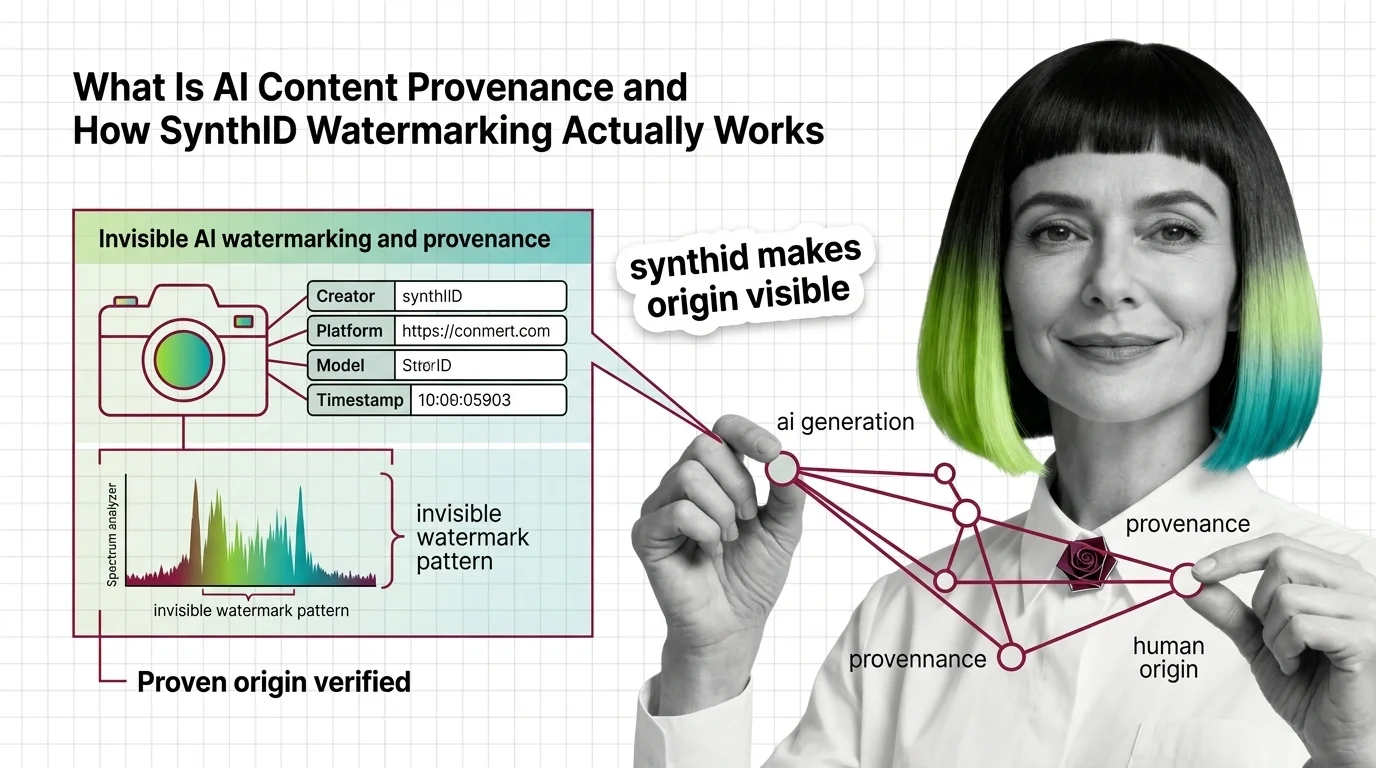
What Is AI Content Provenance and How SynthID Watermarking Actually Works
SynthID embeds an invisible signal in AI images, audio, and text without retraining; a 2025 academic attack cut its …
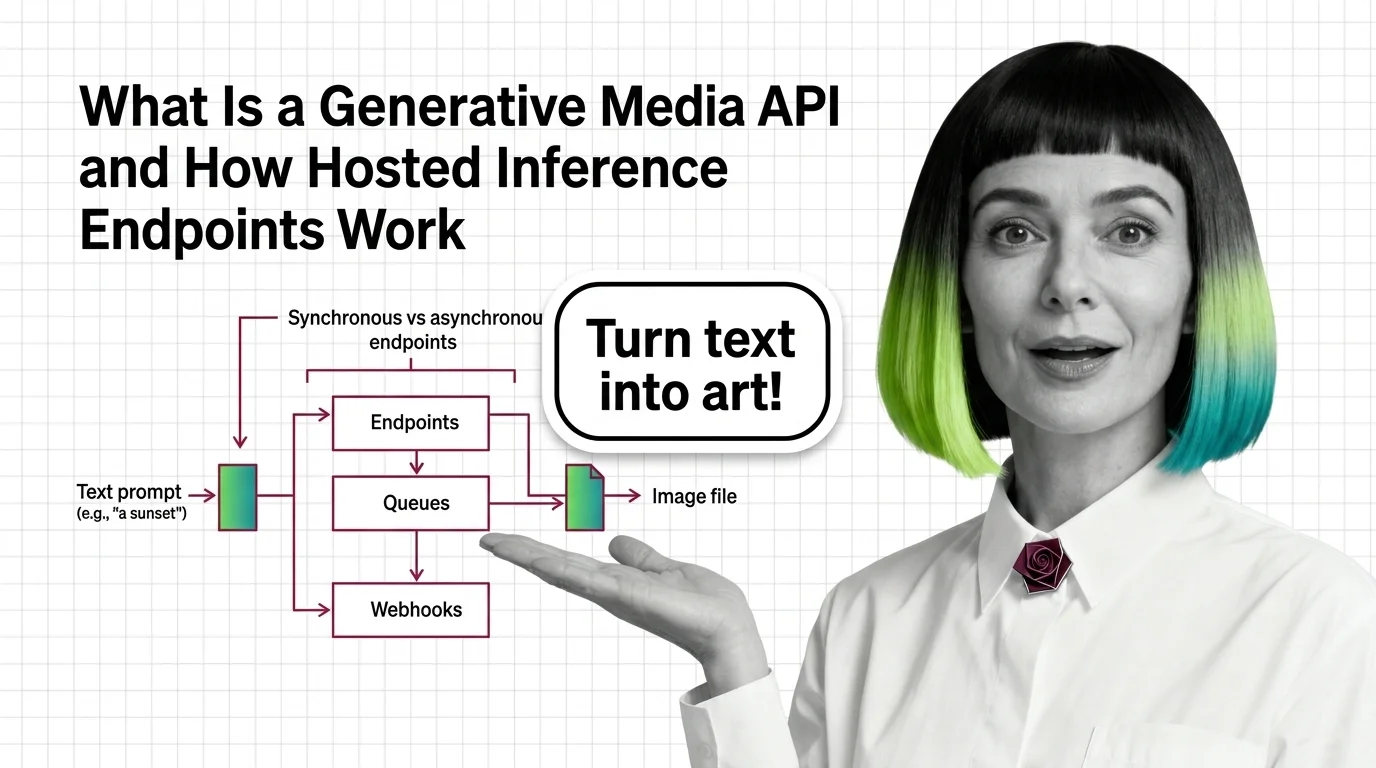
What Is a Generative Media API and How Hosted Inference Endpoints Work
A generative media API turns a text prompt into an image, video, or audio file via hosted inference endpoints, async …
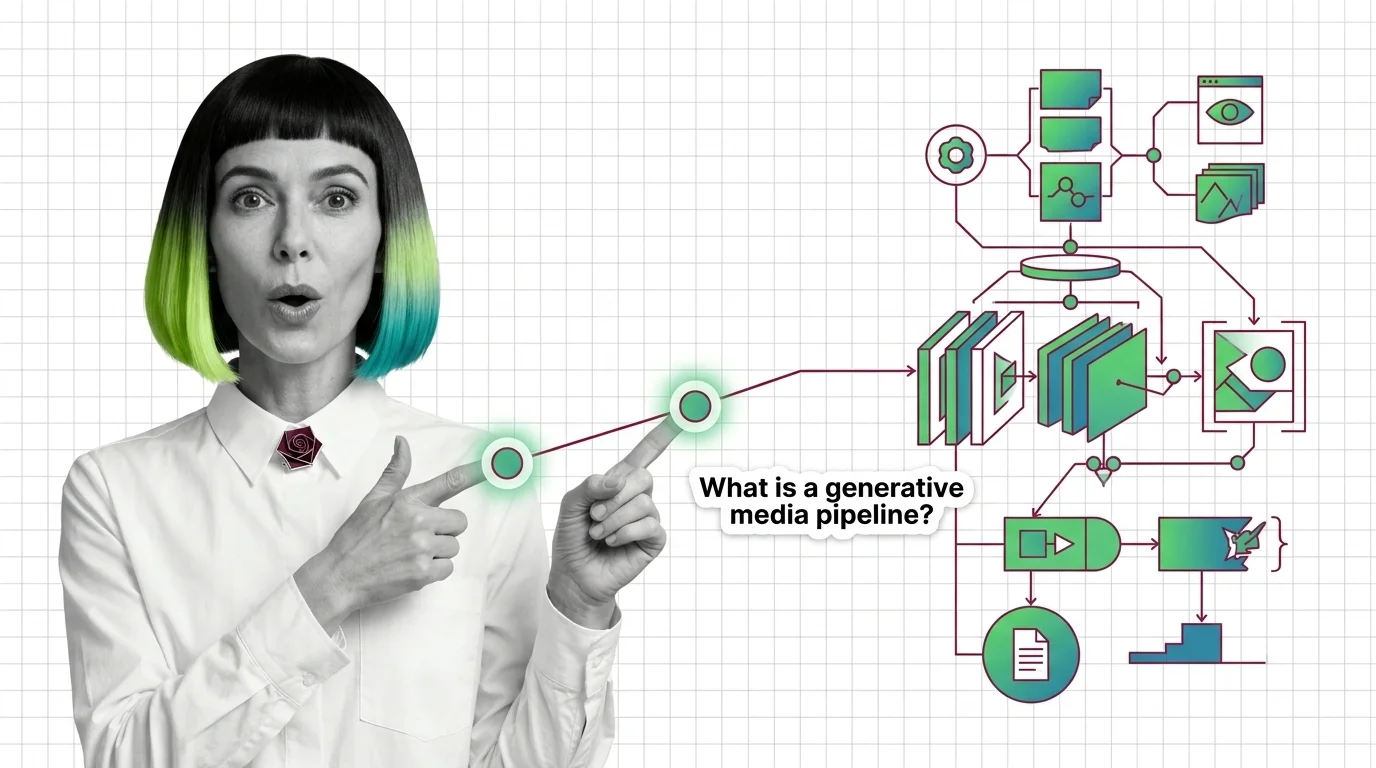
What Is a Generative Media Pipeline and How Generation, Gating, and Publishing Connect
A generative media pipeline chains async generation, human gating, and automated publishing — enterprise builds stitch a …
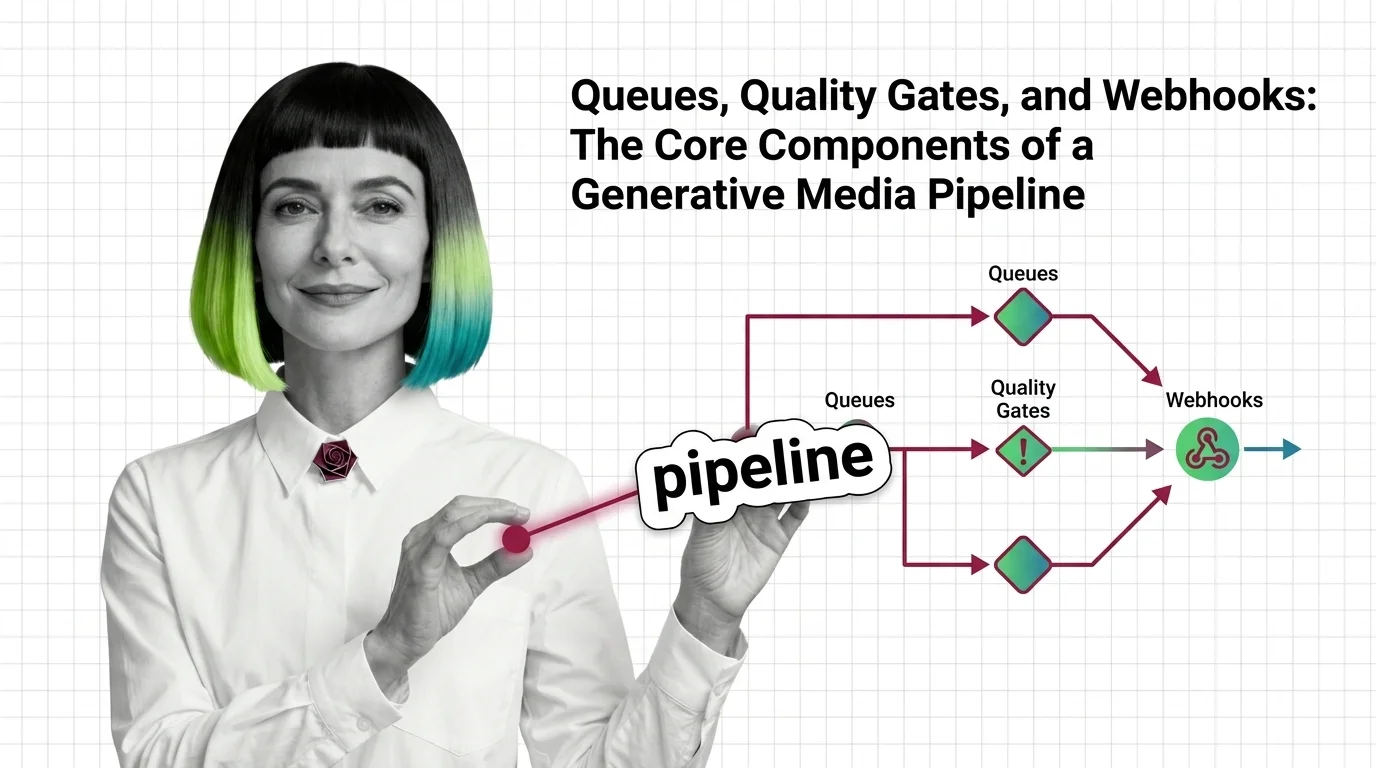
Queues, Quality Gates, and Webhooks: The Core Components of a Generative Media Pipeline
Generative media APIs return a job ID, not an image. Queues, quality gates, and webhooks turn that async ticket into a …
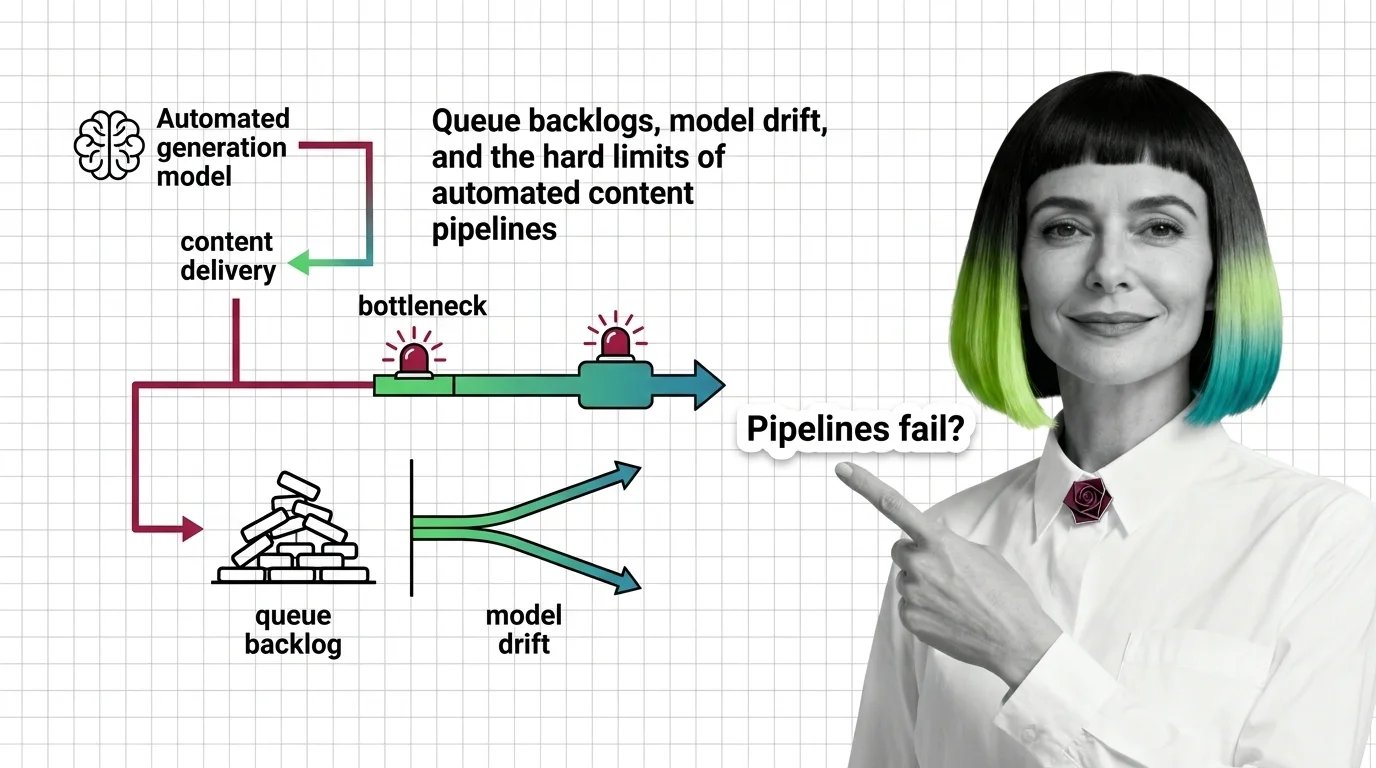
Queue Backlogs, Model Drift, and the Hard Limits of Automated Content Pipelines
Generative media pipelines break from queue limits and webhook timeouts, not model quality. Modal Labs caps functions at …
Prerequisites and Hard Limits of Real-Time AI Generation: Inference to Hardware Bottlenecks
Real-time AI generation needs sub-second inference. SDXL Turbo renders images in 207ms, but AI video still exceeds …
Prerequisites and Technical Limits of Generative Media APIs
Generative media APIs run as async job queues, not REST calls. fal.ai cold starts take 10-90 seconds; Replicate caps …
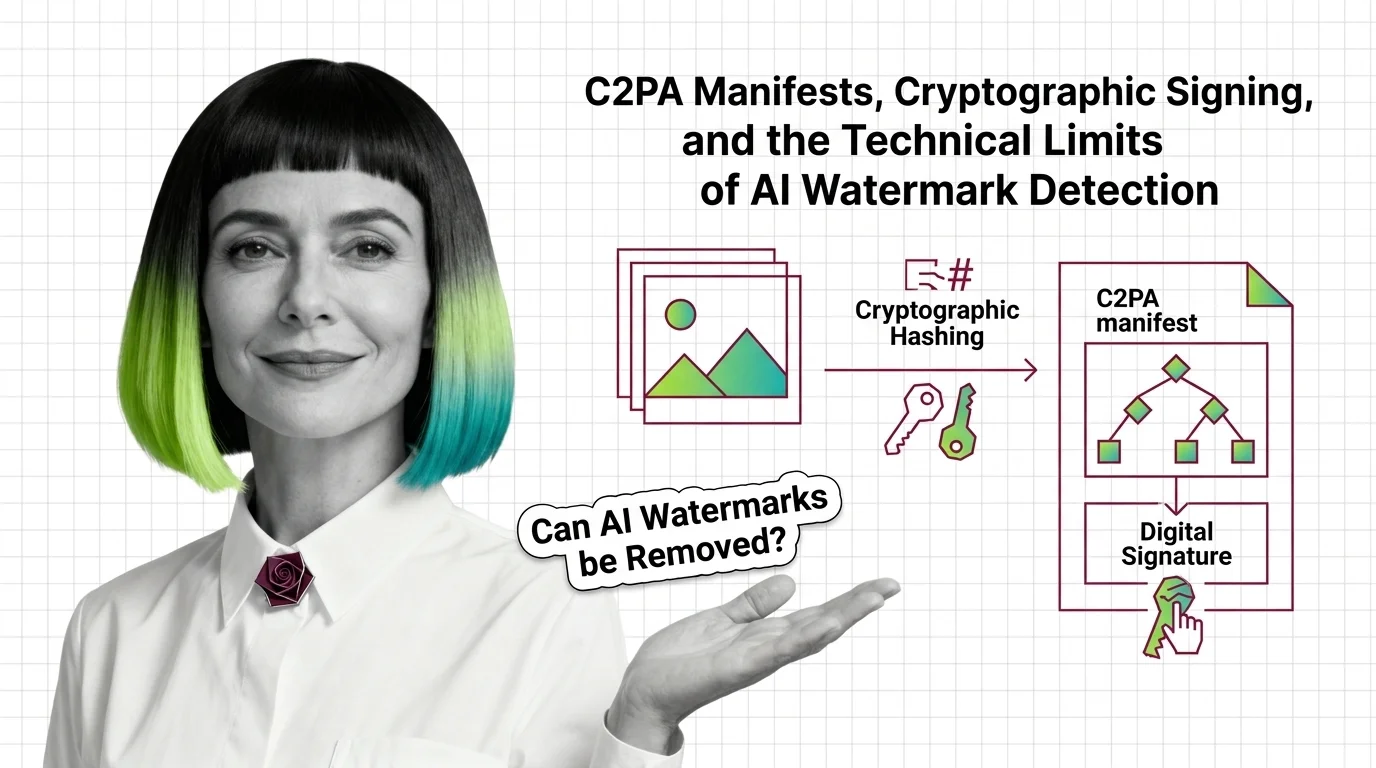
C2PA Manifests, Cryptographic Signing, and the Technical Limits of AI Watermark Detection
C2PA v2.4 Content Credentials use COSE-signed manifests to track edit history, not pixel content — the chain breaks the …
What Is Tool Use in Prompts and How LLMs Parse Function Calling Schemas
Tool use in LLMs is function calling — the model emits structured JSON naming a tool and arguments. Your code executes; …
What Is Structured Output Prompting and How LLMs Are Made to Return Valid JSON
Structured output prompting forces valid JSON from LLMs — via constrained decoding that masks invalid tokens, or …
What Is Prompt Testing and Evaluation and How Automated Metrics Replace Manual Spot-Checks
Prompt testing and evaluation measures LLM output quality using automated scorers — code-based, LLM-as-judge, and human. …
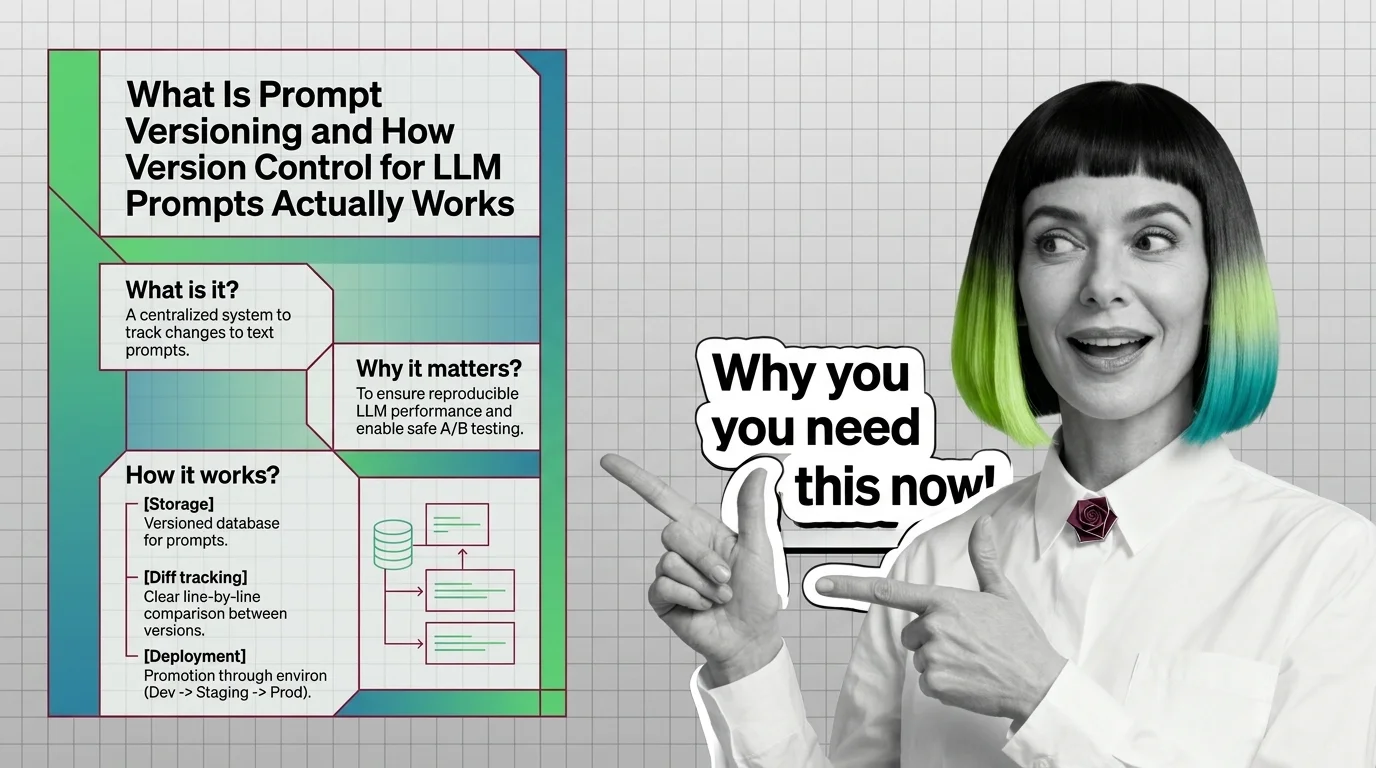
What Is Prompt Versioning and How Version Control for LLM Prompts Actually Works
Prompt versioning assigns immutable IDs to every LLM prompt change. Rollback means reassigning a production label — no …
What Is Prompt Injection and How Attackers Override AI System Instructions
Prompt injection redirects AI systems via malicious instructions embedded in processed text. OWASP ranks it the top LLM …
What Is Prompt Optimization and How Manual Refinement, DSPy, and Compression Techniques Work
Prompt optimization improves LLM outputs via iterative refinement, DSPy's automated optimizer, and compression methods …
Trust Boundaries and Why LLMs Cannot Reliably Separate Instructions from Data
LLMs have no hardware boundary between instructions and data — both are tokens. Prompt injection, OWASP's #1 LLM risk, …
What Breaks in Structured Output: Prerequisites, Token Overhead, and Schema Enforcement Limits
Structured output has hidden costs: token overhead, ~10–30% latency increase, and gaps in what constrained-decoding …
Prompt Engineering Foundations and the Technical Limits of Automated Prompt Tuning
Automated prompt tools assume prompt engineering fluency. Map what you need before using DSPy, OPRO, or TextGrad—and the …
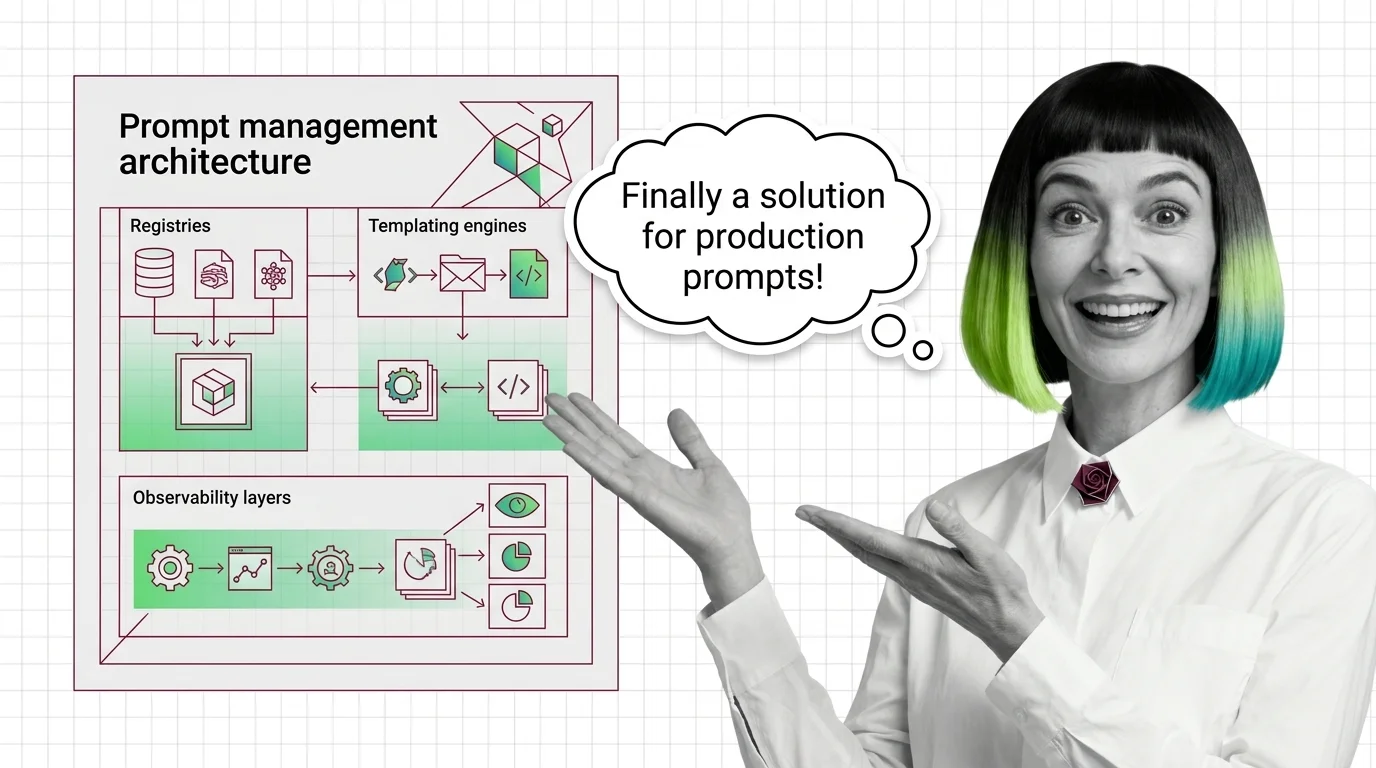
Prompt Management Architecture: Registries, Templating Engines, and Observability Layers Explained
Prompt management has three layers: versioned registry, templating engine, and observability. Missing one explains why …
Evaluation Metrics, Test Datasets, and LLM Judges: The Parts of a Prompt Evaluation System
A prompt evaluation system has three parts: metrics that define quality, test datasets exposing failure modes, and LLM …
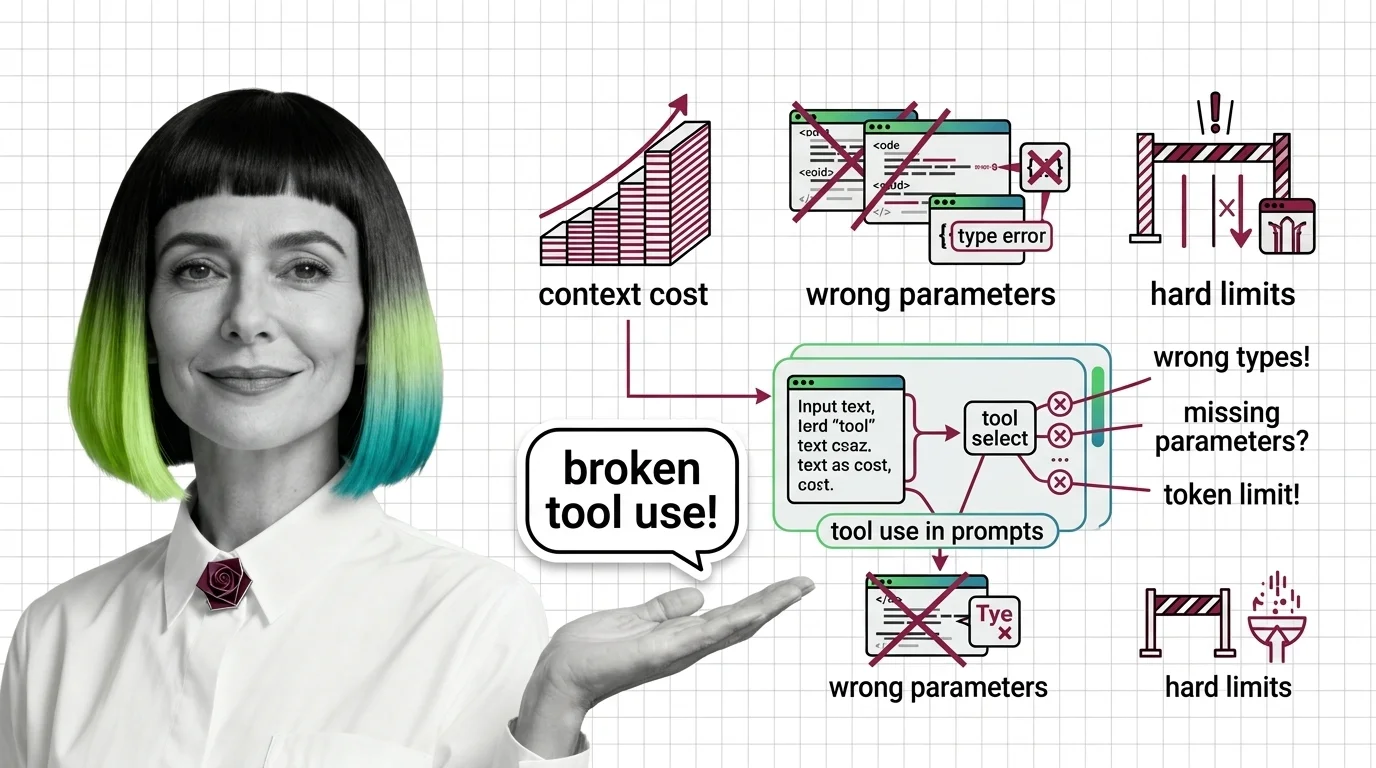
Context Costs, Wrong Parameters, and the Hard Limits of LLM Tool Calling
LLM tool schemas vary by provider and add hidden token overhead. Task accuracy peaks near 77% (BFCL v3, 2026) — well …
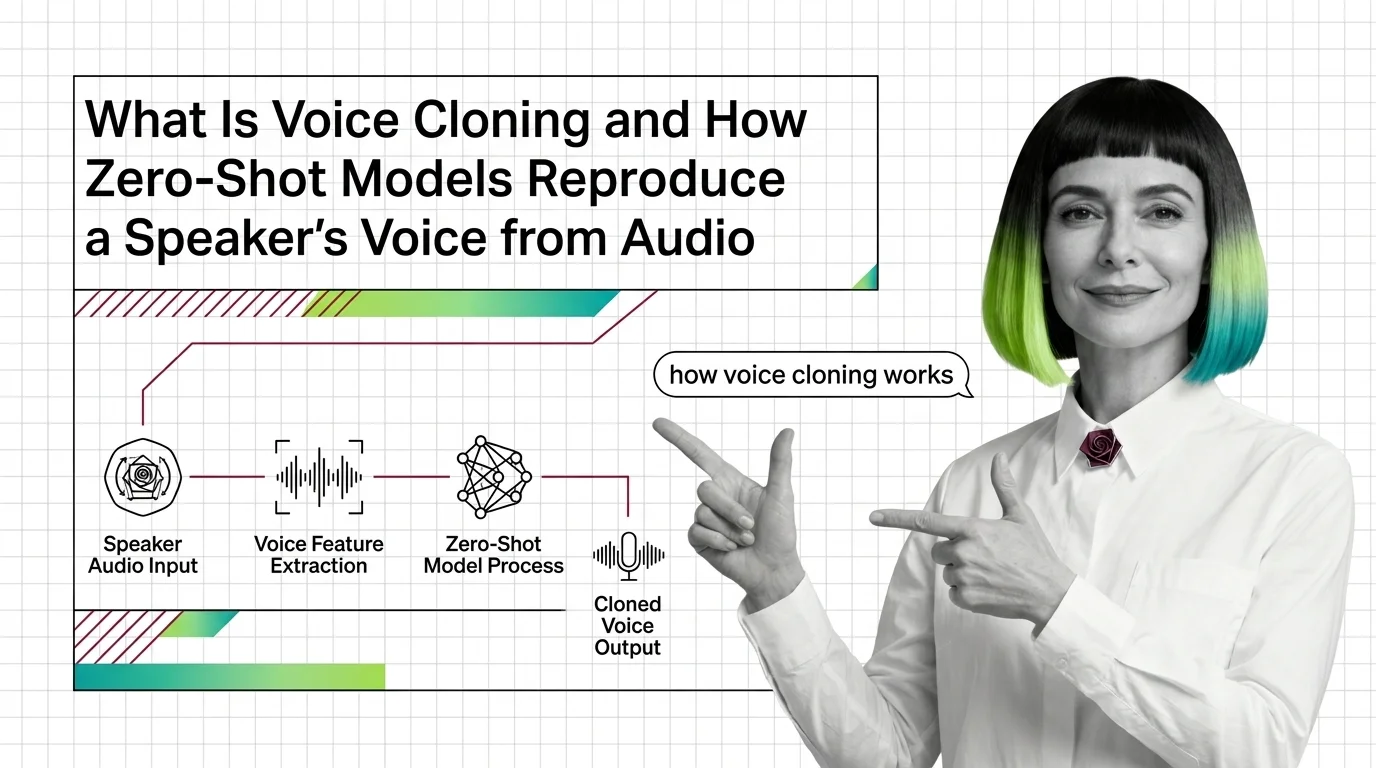
What Is Voice Cloning and How Zero-Shot Models Reproduce a Speaker's Voice from Audio
Voice cloning uses speaker embeddings and zero-shot conditioning to reproduce a target voice from 6–10 seconds of …
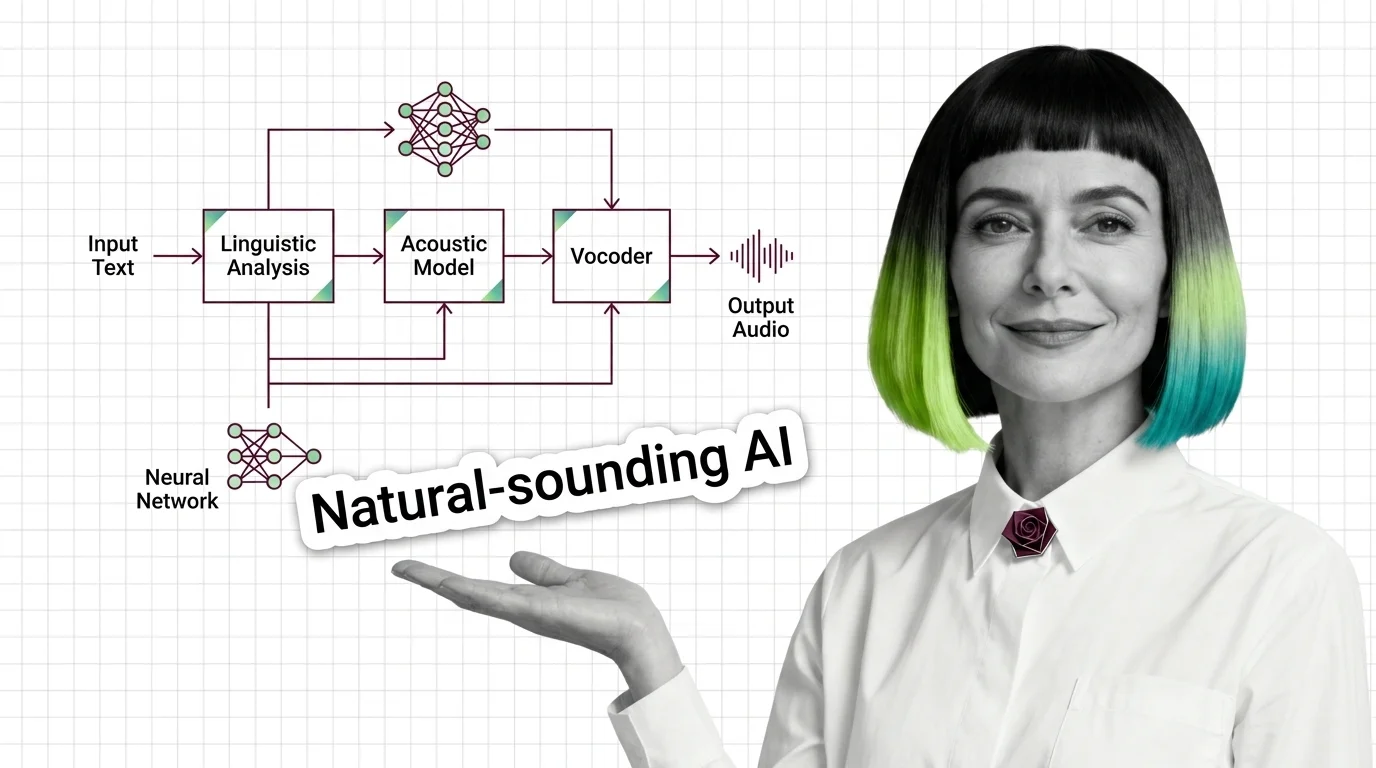
What Is Text-to-Speech AI and How Neural TTS Architectures Convert Text into Speech
Neural TTS converts text into speech through learned acoustic models. Tacotron 2 scored 4.53 MOS at ICASSP 2018; current …
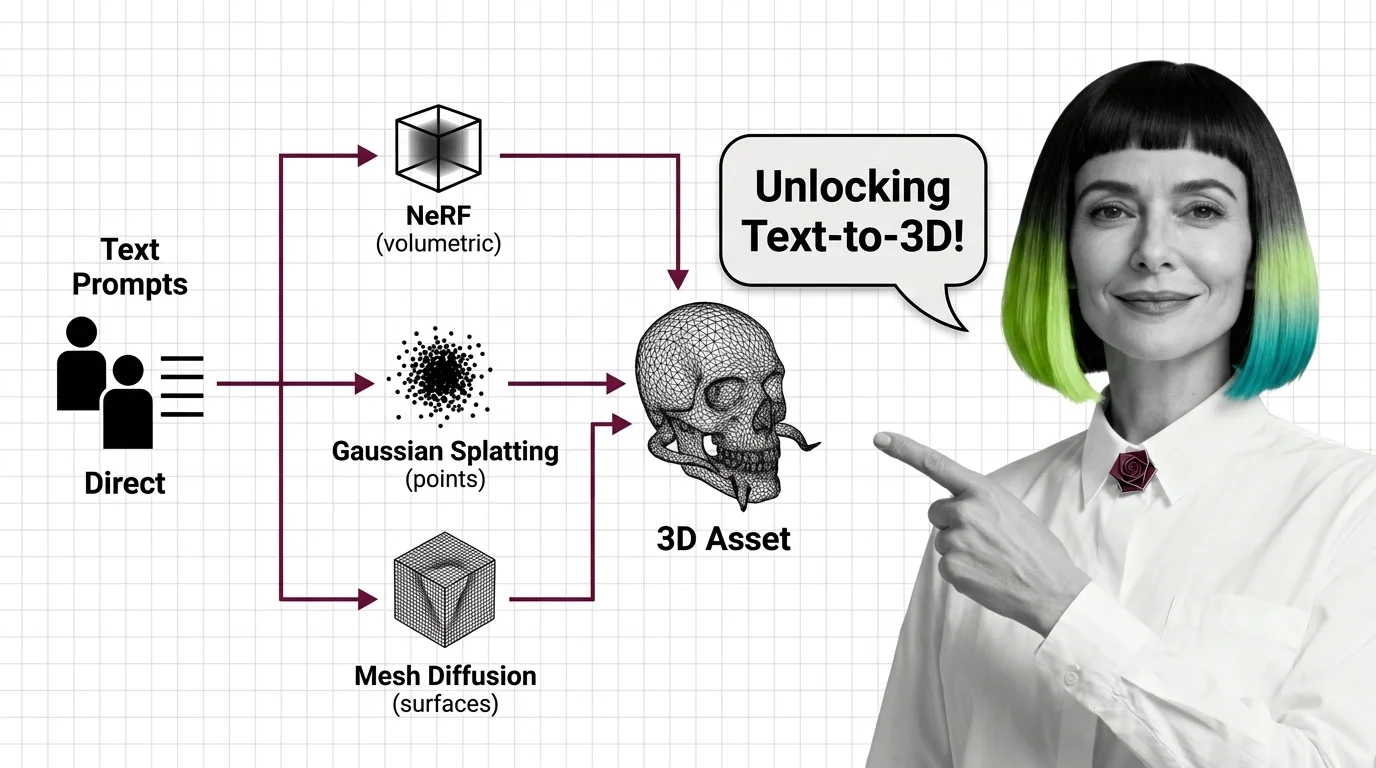
What Is Text-to-3D: How NeRF, Gaussian Splatting, and Mesh Diffusion Turn Text Prompts into 3D Assets
Text-to-3D uses Score Distillation Sampling to convert text into 3D meshes via NeRF or Gaussian splatting — no labeled …
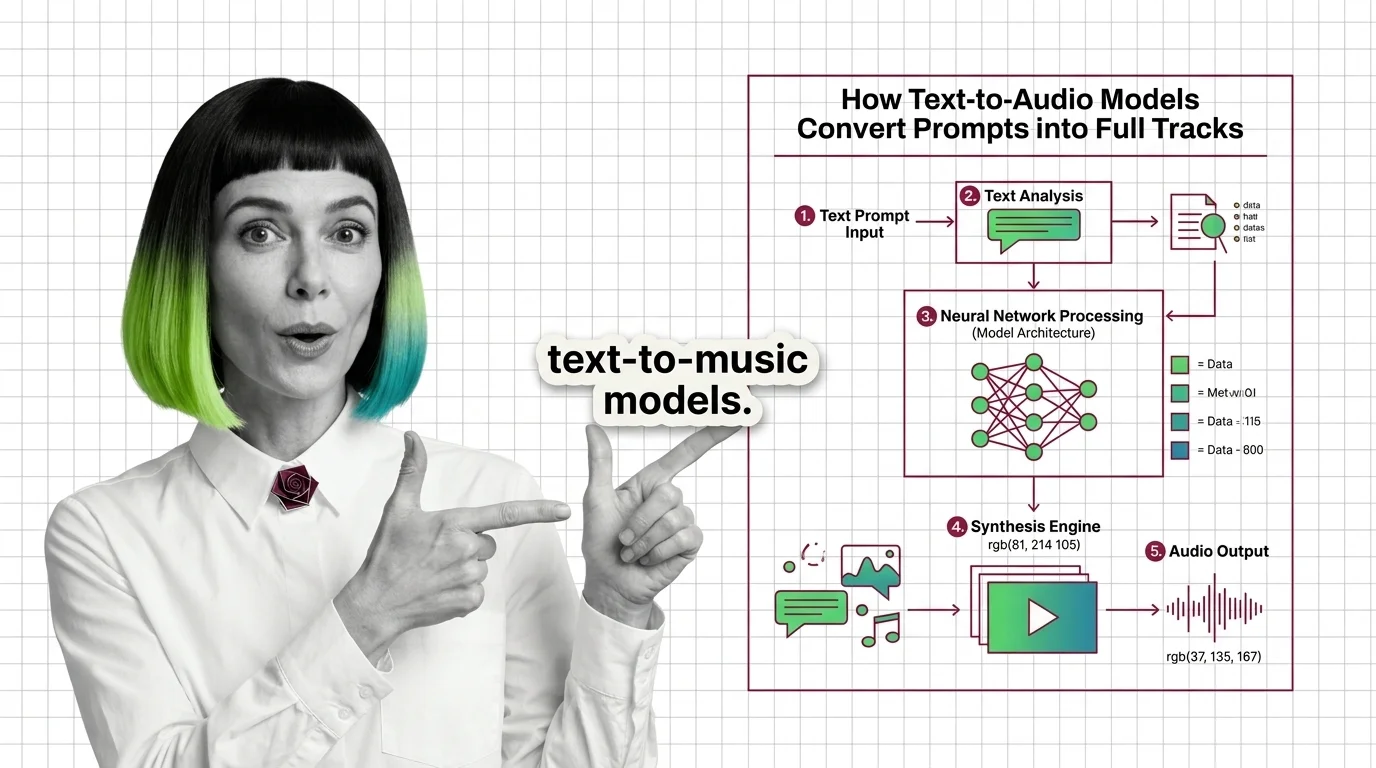
What Is AI Music Generation and How Text-to-Audio Models Convert Prompts into Full Tracks
AI music generation converts text prompts into audio tracks. Neural codecs compress waveforms into tokens; transformers …
What Is AI Video Editing and How Object Removal, Style Transfer, and Lip Sync Actually Work
AI video editing uses diffusion models to edit footage directly — Runway Aleph and Pika remove objects, transfer style, …
What Is AI Avatar Generation and How Talking-Head Synthesis Works
AI avatar generation reanimates a face from audio using two pipelines: 2D lip-sync over real video, or 3D reconstruction …
Prerequisites for TTS and the Hard Technical Limits of Neural Speech Synthesis in 2026
Neural TTS converts text to audio via phoneme processing, prosody modeling, and vocoders. In 2026, expressiveness and …
3D Geometry, UV Mapping, and the Technical Limits of AI-Generated Meshes in 2026
Text-to-3D tools produce non-manifold meshes with broken UV maps. Topology errors, splat format gaps, and multi-view …
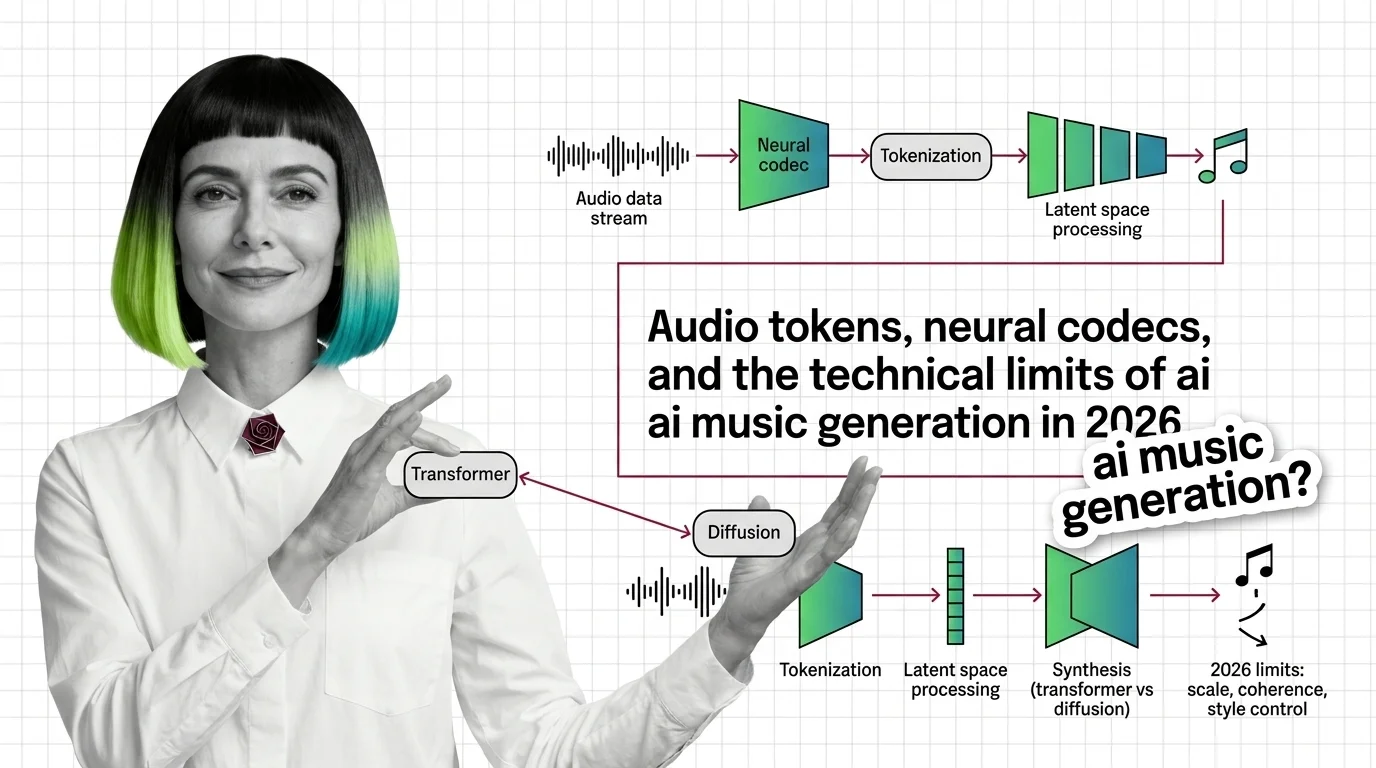
Audio Tokens, Neural Codecs, and the Technical Limits of AI Music Generation in 2026
Neural codecs tokenize audio into discrete sequences for AI music models. Codec fidelity is largely solved in 2026; …
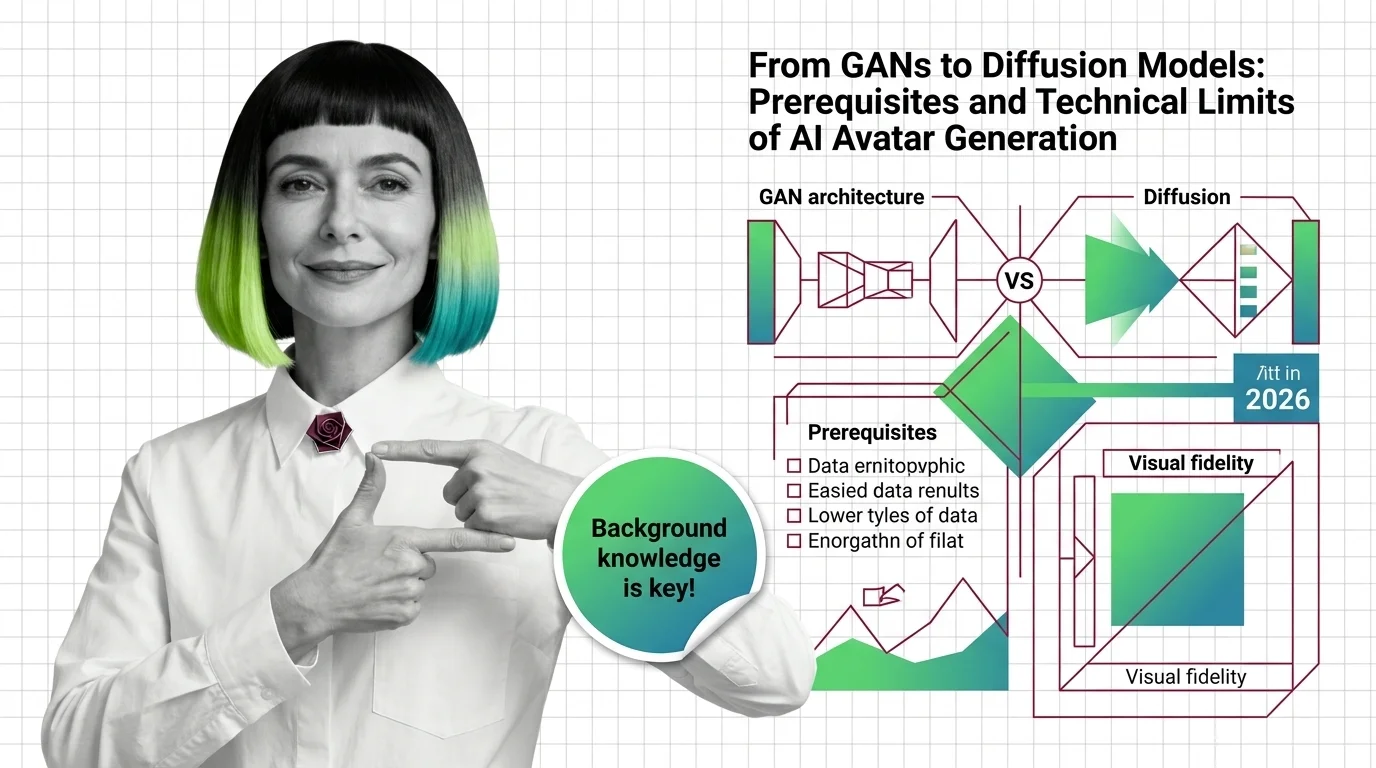
From GANs to Diffusion Models: Prerequisites and Technical Limits of AI Avatar Generation
AI avatar generation now runs on diffusion transformers, not GANs — HeyGen and Synthesia both switched in 2026, but …
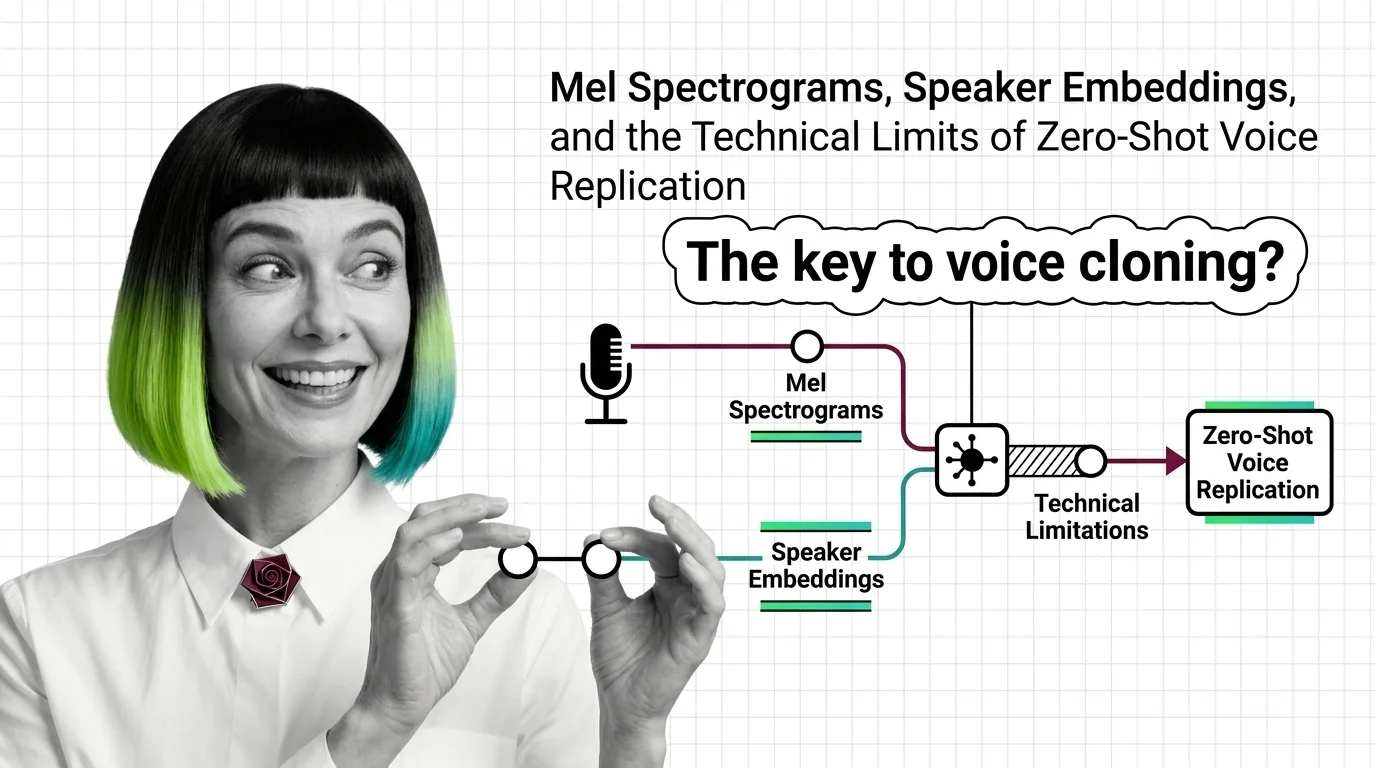
Mel Spectrograms, Speaker Embeddings, and the Technical Limits of Zero-Shot Voice Replication
Mel spectrograms and speaker embeddings are the core of voice cloning. Zero-shot models clone from 3 seconds but fail on …
Temporal Consistency, Identity Drift, and the Technical Limits of AI Video Editing
AI video editing tools regenerate each frame via diffusion, not edit pixels—causing temporal drift. Runway Aleph 2.0 …
What Is Dataset Bias and How Skewed Training Data Shapes Model Predictions
Dataset bias is a systematic skew between training data and the real world. A 2018 audit found classifiers failed 43x …
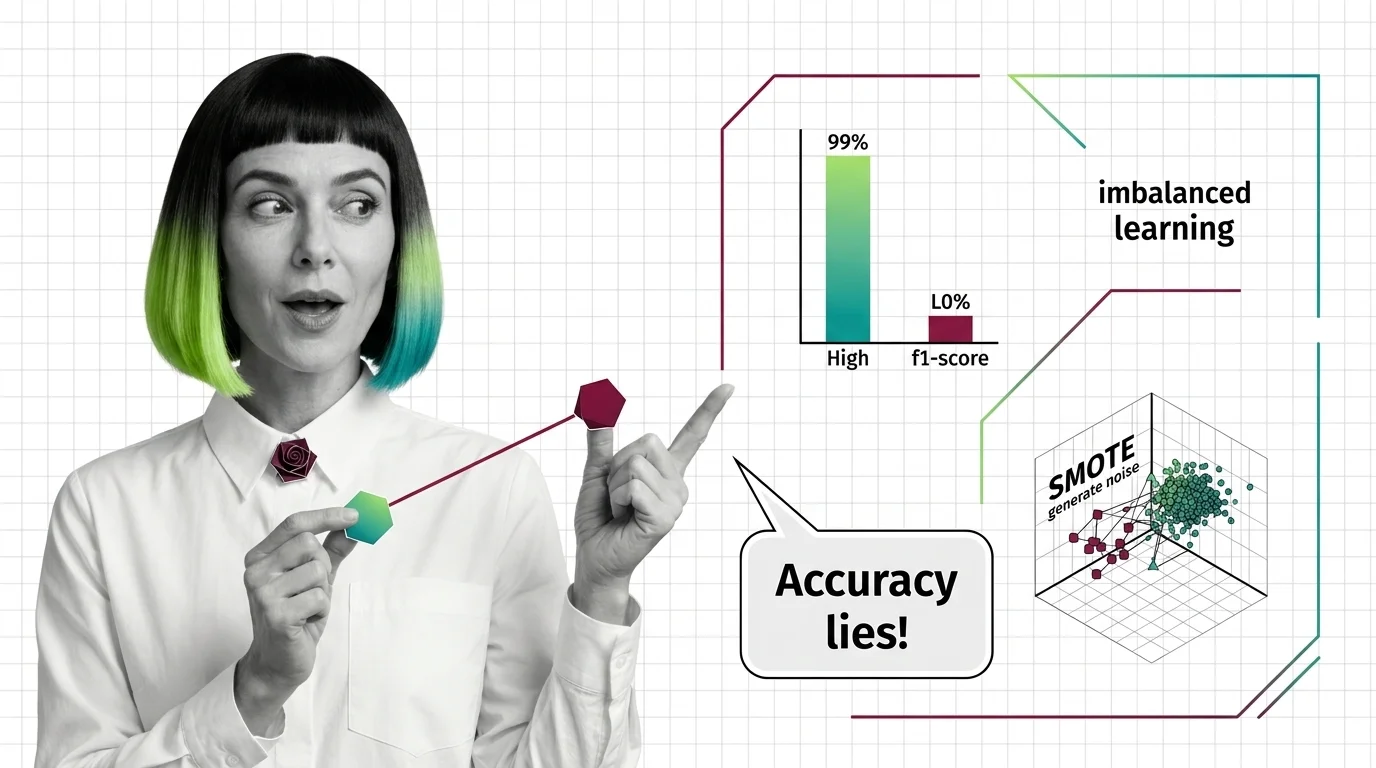
Why Accuracy Lies and SMOTE Breaks Down: The Technical Limits of Imbalanced Learning
Class imbalance makes accuracy lie: a model predicting only the majority class scores 99% yet catches zero rare cases. …
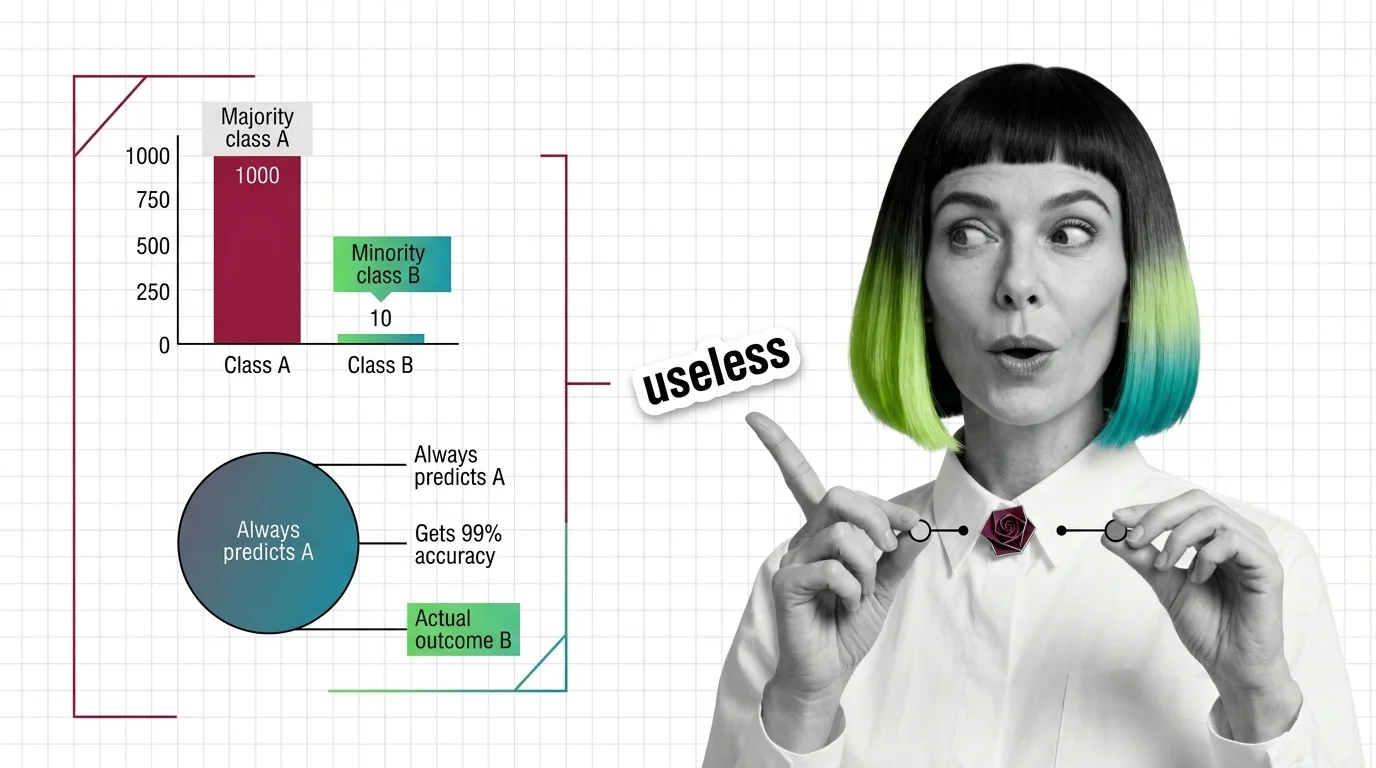
What Is Class Imbalance and Why a 99% Accurate Model Can Be Useless
Class imbalance is when one class dominates a dataset, so a model scoring 99% accuracy can miss every rare case. …
What Is Data Drift and How Production Data Silently Degrades Model Accuracy
Data drift is when production input distributions diverge from training data, degrading model accuracy even though the …
What Is Data Leakage in Machine Learning and How It Inflates Model Accuracy
Data leakage occurs when information unavailable at prediction time reaches model training, inflating accuracy estimates …
What Is Data Poisoning and How Corrupted Training Data Compromises Model Behavior
Data poisoning corrupts ML training data to redirect model outputs. Backdoor attacks embed dormant triggers; clean-label …
What Is Data Versioning and How Content Hashing Tracks Dataset Changes Like Git
Data versioning tracks dataset changes by content hash, not filename. DVC and lakeFS keep large data out of Git, …
RAG Poisoning, Agent-Memory Corruption, and What Training Pipelines Expose to Attackers
Data poisoning corrupts AI behavior through three surfaces: training pipelines, RAG corpora, and agent memory — each …
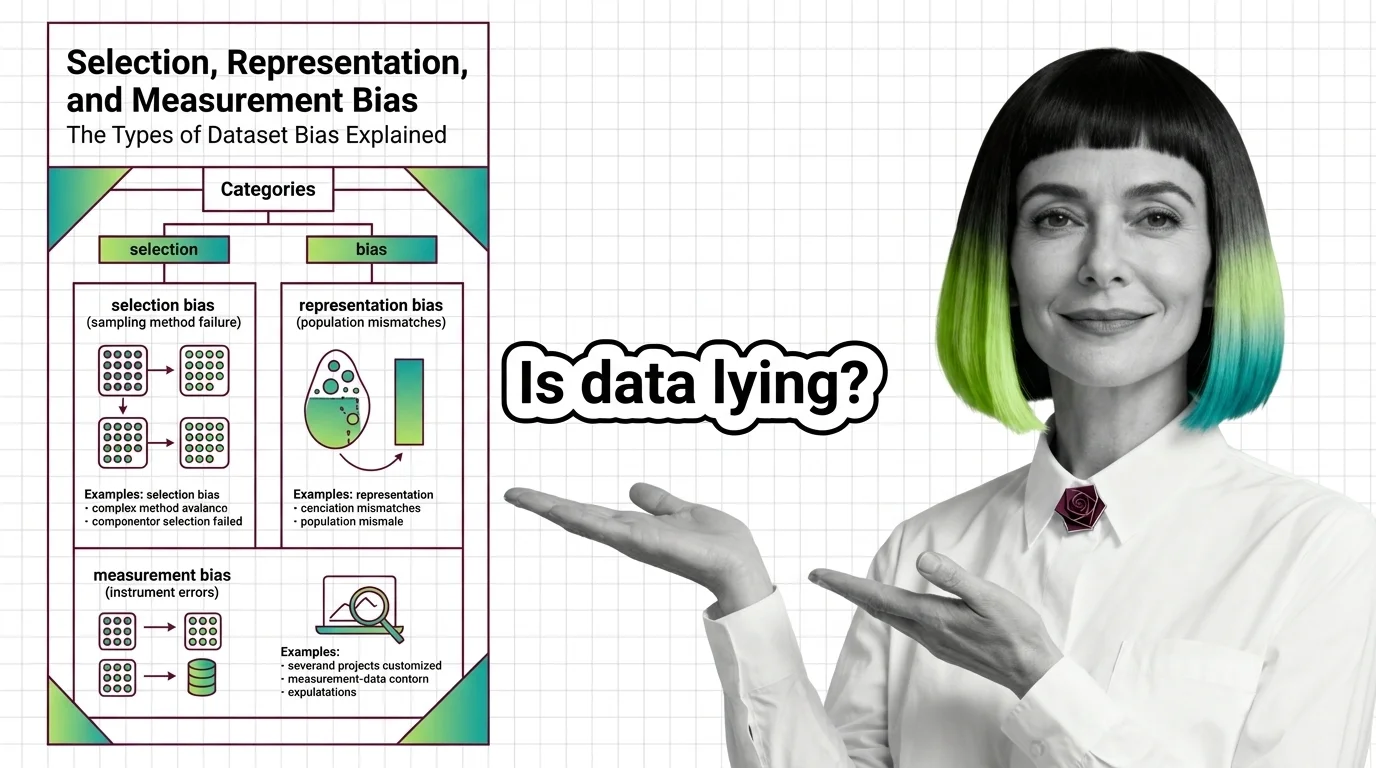
Selection, Representation, and Measurement Bias: The Types of Dataset Bias Explained
Dataset bias comes in three forms: selection, representation, and measurement. Each enters at a different stage and …
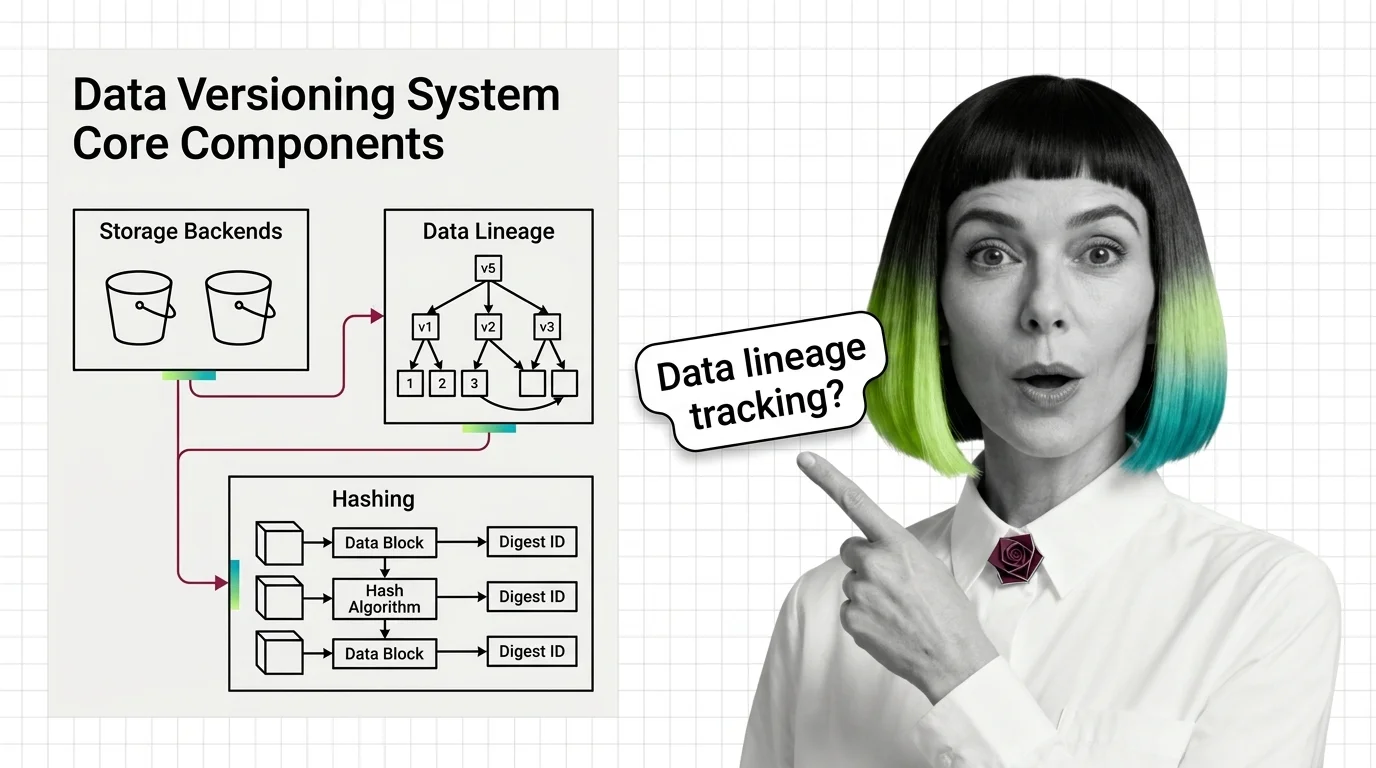
Storage Backends, Data Lineage, and Hashing: The Core Components of a Data Versioning System
A data versioning system has three core parts: content-addressable hashing, a storage backend, and lineage that links …
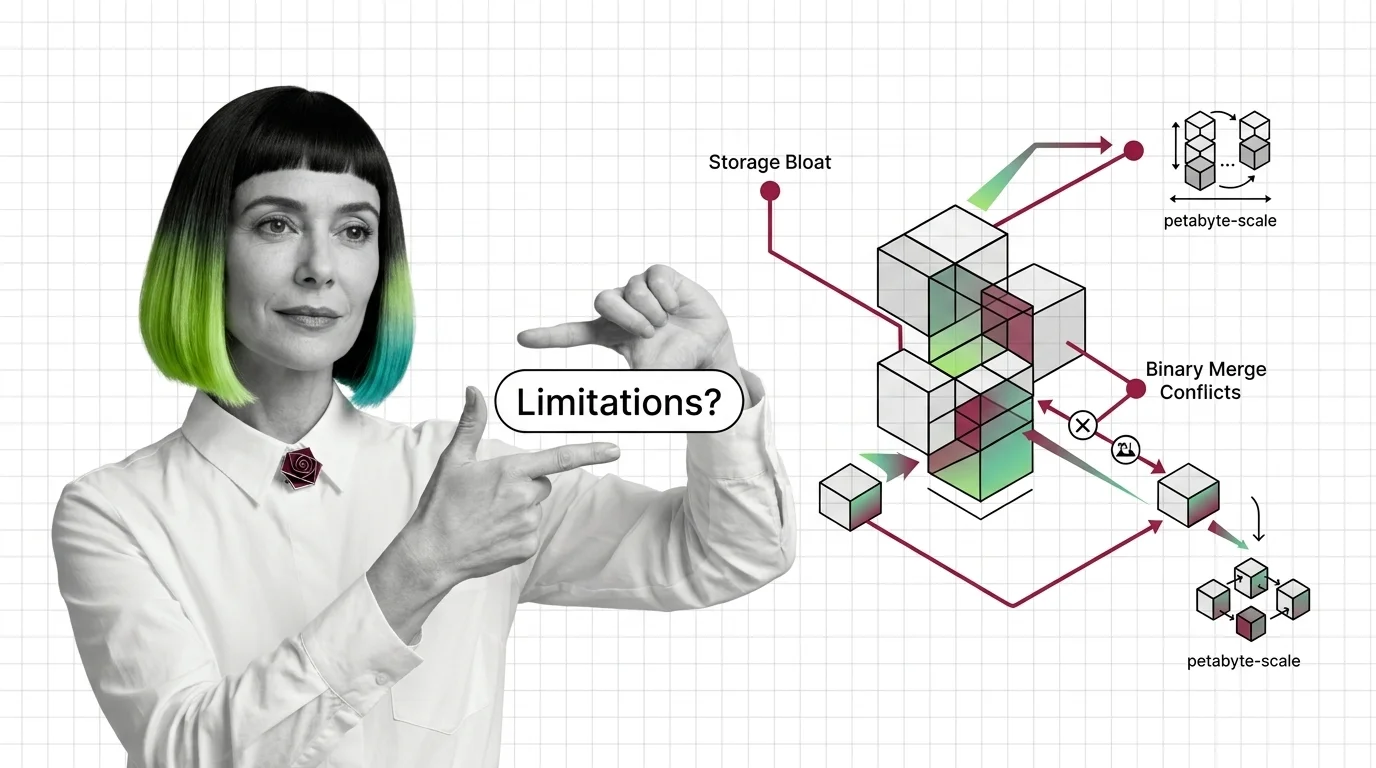
Storage Bloat, Binary Merge Conflicts, and the Scaling Limits of Data Versioning
Data versioning tools bloat storage because Git LFS and DVC dedup whole files. A 1-byte change to a 10 GB file stores …
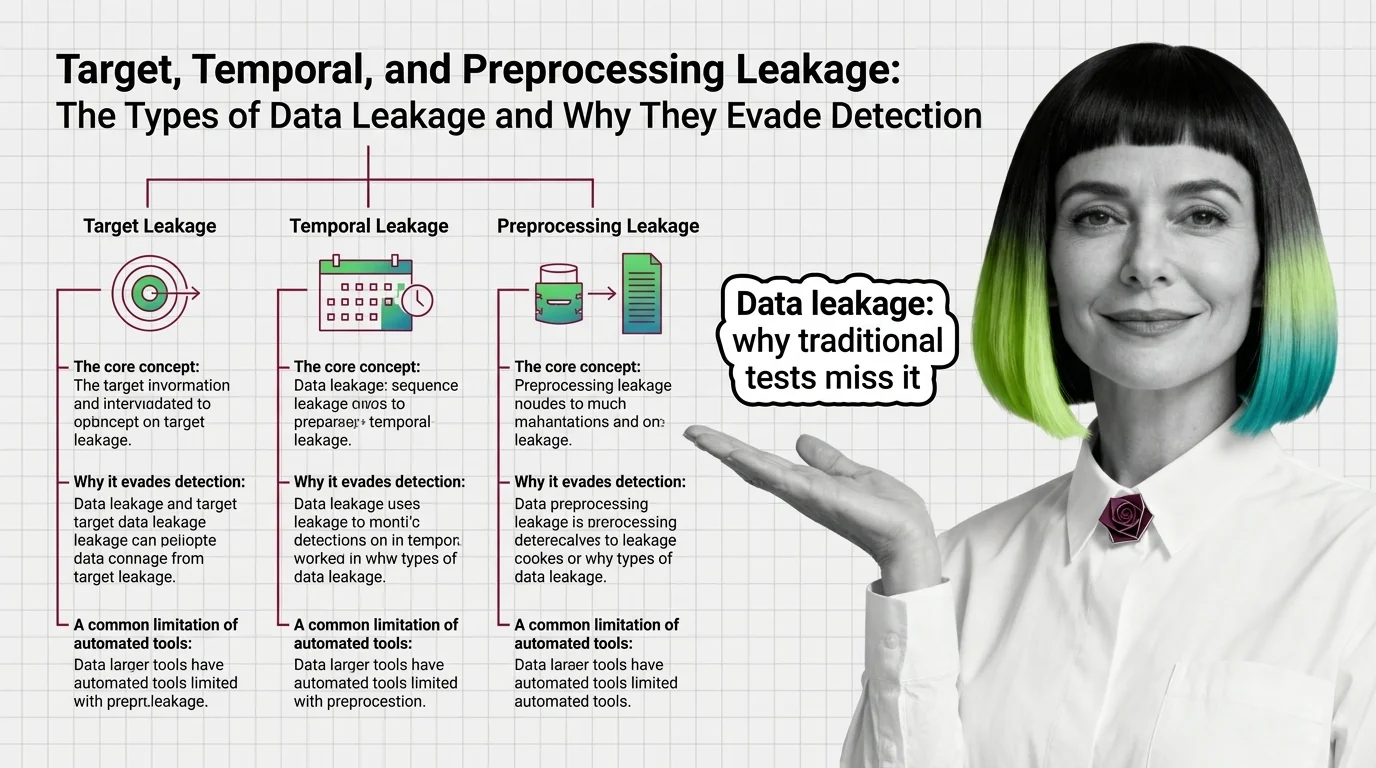
Target, Temporal, and Preprocessing Leakage: Why Data Leakage Evades Detection
Data leakage comes in target, temporal, and preprocessing forms. It corrupted 294 studies across 17 fields because …
Bias Amplification and the Impossibility Theorem: Why You Can't Fully Debias a Dataset
Dataset bias can't be fully removed: it enters at many lifecycle stages, hides in proxy features, and models amplify the …
Class Imbalance Prerequisites: Confusion Matrices, PR-AUC, Data-Level vs Algorithm-Level
Class imbalance makes accuracy misleading. Use the confusion matrix, PR-AUC, and balanced accuracy, then pick data-level …
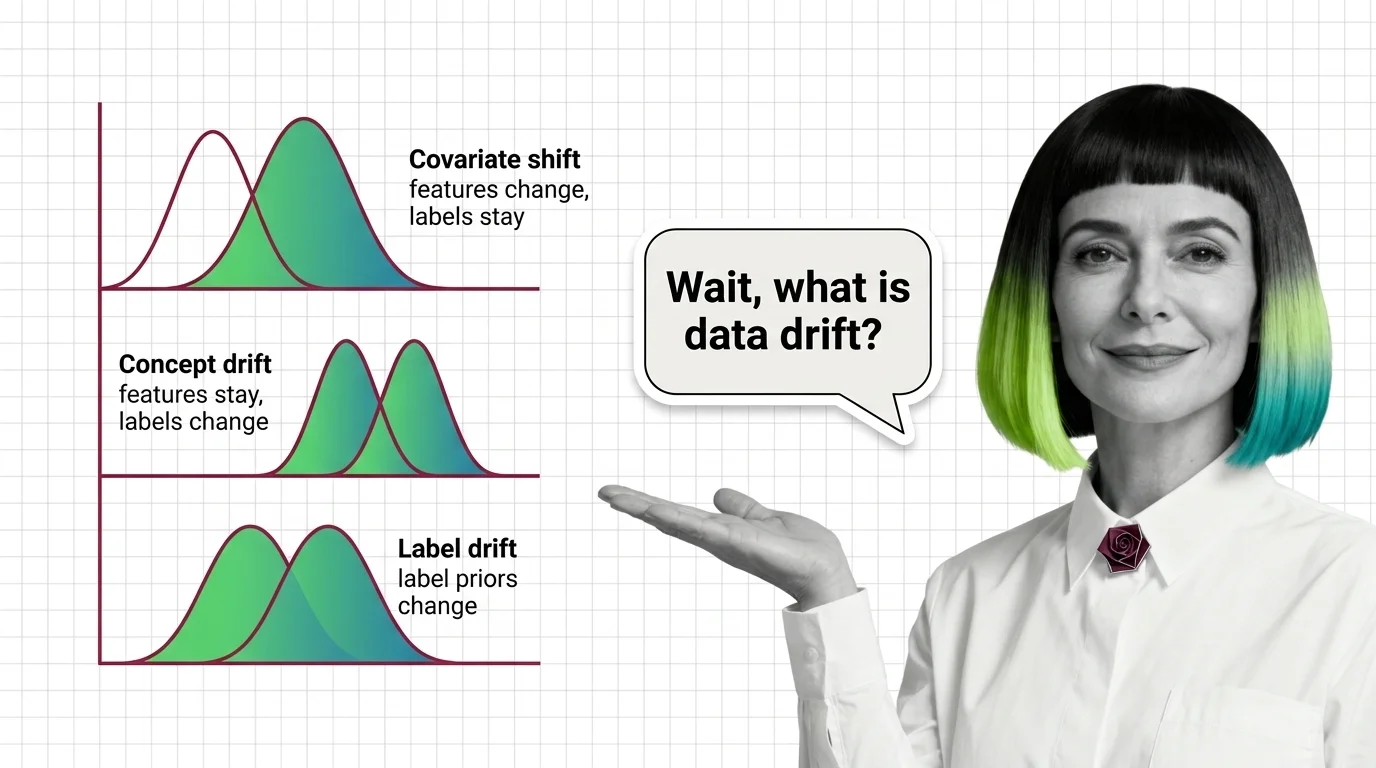
Covariate Shift, Concept Drift, and Label Drift: The Types of Data Drift and the Statistics to Detect Them
Data drift splits into three types: covariate shift P(X), concept drift P(Y|X), and label drift P(Y). KS tests and PSI …
Data Leakage Prerequisites: Train-Test Splits, Cross-Validation, and Feature Pipelines
Data leakage feeds prediction-time information into training, inflating accuracy. Prevent it: split before …
False Positives, Delayed Labels, and the Technical Limits of Data Drift Detection
Data drift detection produces false alarms because statistical tests over-fire on large samples, while performance loss …
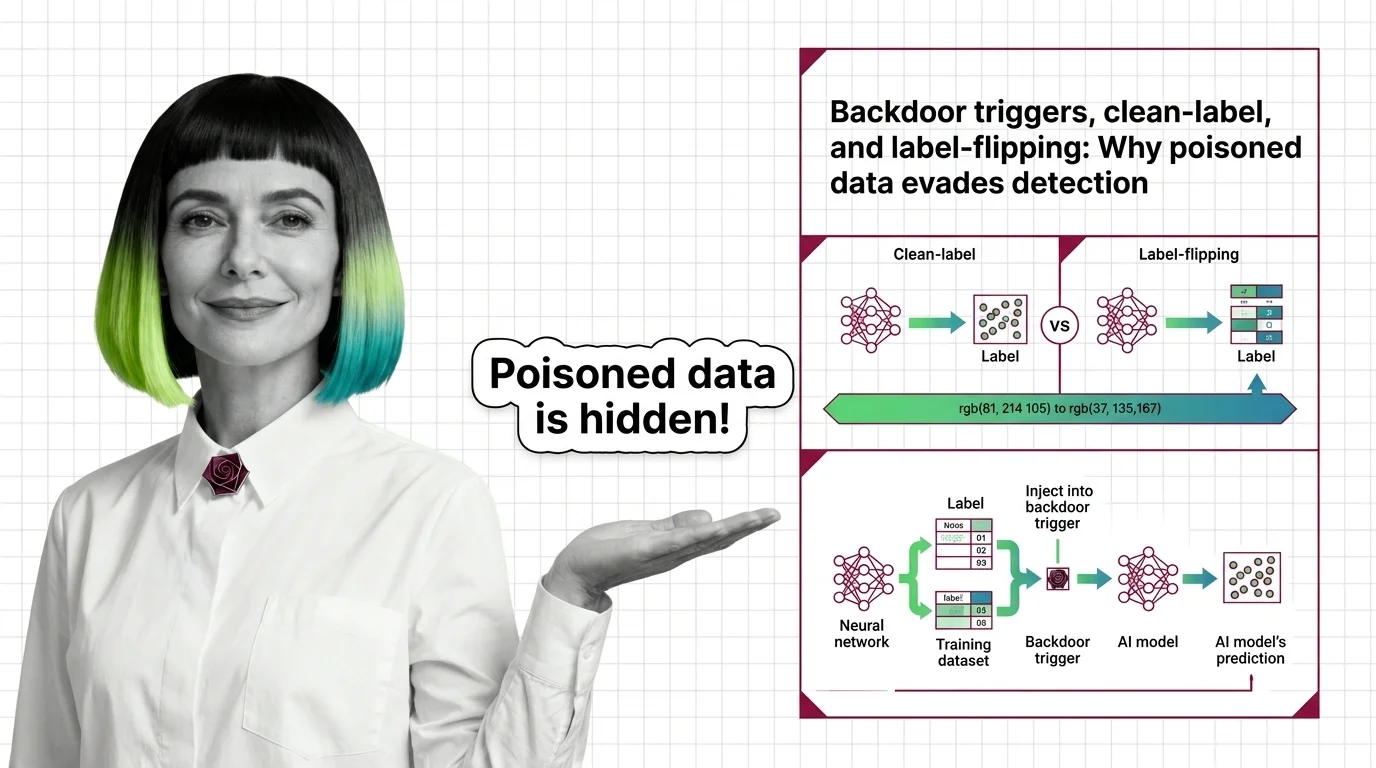
Backdoor Triggers, Clean-Label, and Label-Flipping: Why Poisoned Data Evades Detection
Backdoor triggers, clean-label, and label-flipping are three data poisoning vectors that corrupt ML models while evading …
Why Prompts Break: Context Window Ceilings, Phrasing Sensitivity, and the Technical Limits of Prompt Engineering in 2026
Prompt engineering has architectural failure points: position bias drops recall 30%+ in long contexts, and prompts …
What Is Prompt Chaining and How Sequential LLM Calls Enable Complex AI Reasoning
Prompt chaining sequences multiple LLM calls where each output feeds the next. Mechanism, building blocks, and failure …
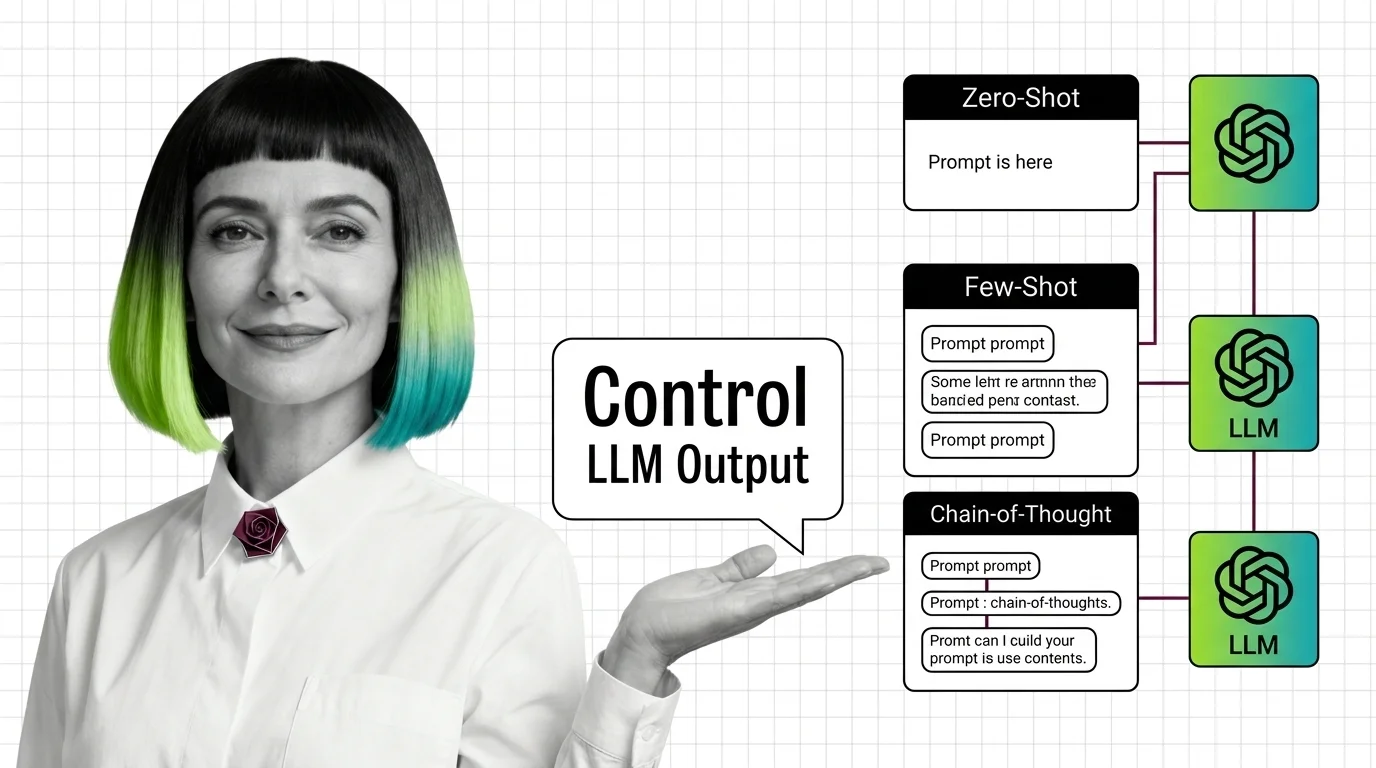
What Is Prompt Engineering and How Zero-Shot, Few-Shot, and Chain-of-Thought Techniques Control LLM Output
Prompt engineering structures LLM inputs to control output without retraining. Three core techniques: zero-shot, …
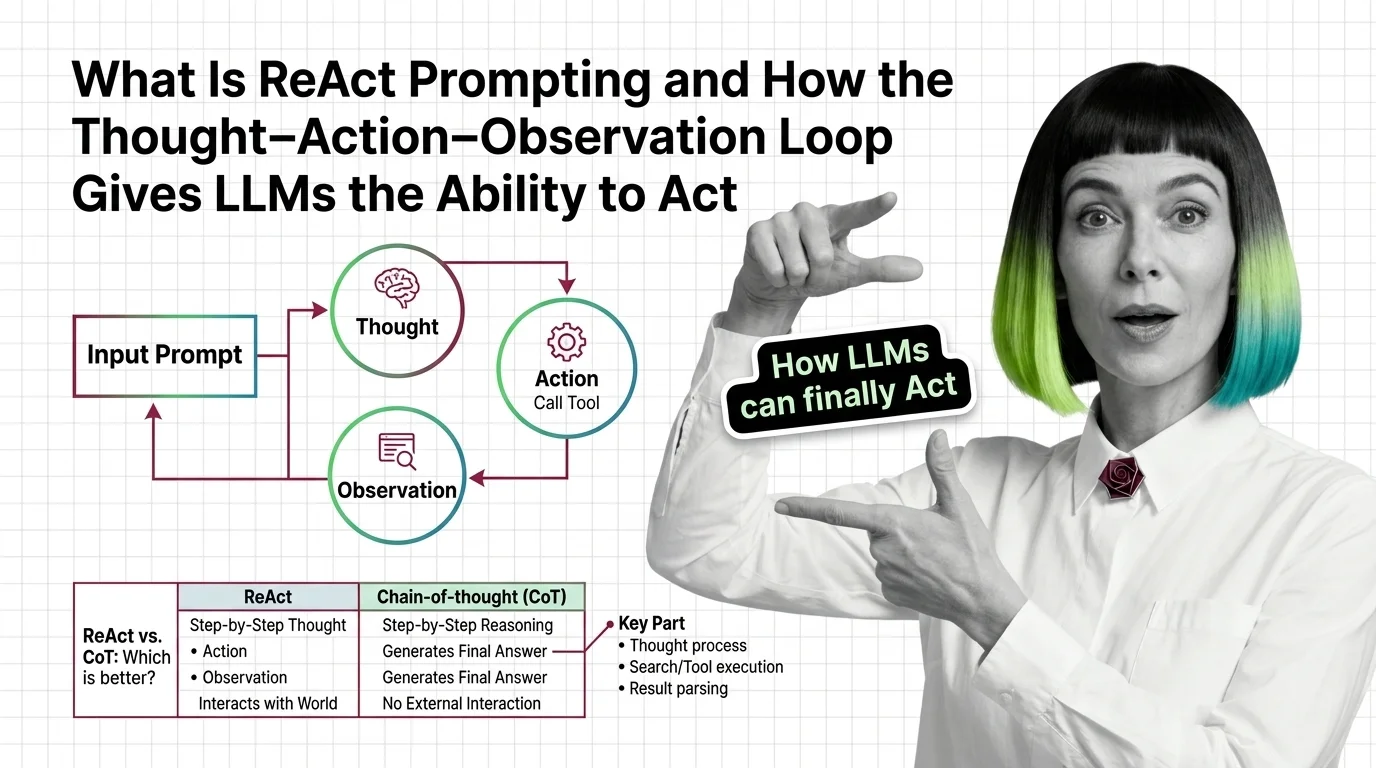
What Is ReAct Prompting and How the Thought–Action–Observation Loop Gives LLMs the Ability to Act
ReAct prompting interleaves LLM reasoning with real-world tool calls. Published at ICLR 2023, it improved agentic task …
What Is Role Prompting and How Assigning an Expert Persona Changes LLM Behavior
Role prompting assigns an expert persona via the system prompt, shifting how an LLM samples tokens. It helps advisory …
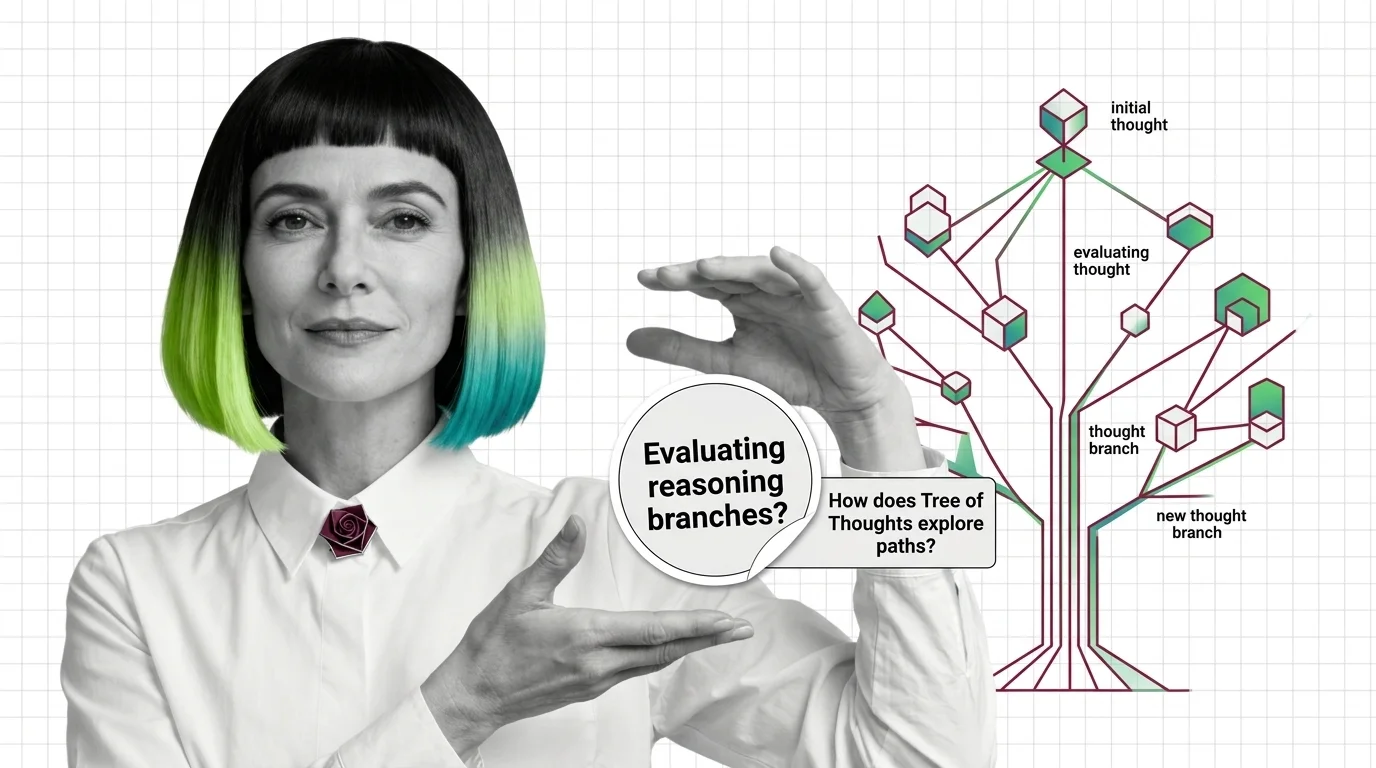
What Is Tree of Thoughts and How It Extends Chain-of-Thought Reasoning
Tree of Thoughts extends chain-of-thought via BFS/DFS search over reasoning branches. Yao et al. (NeurIPS 2023) showed …
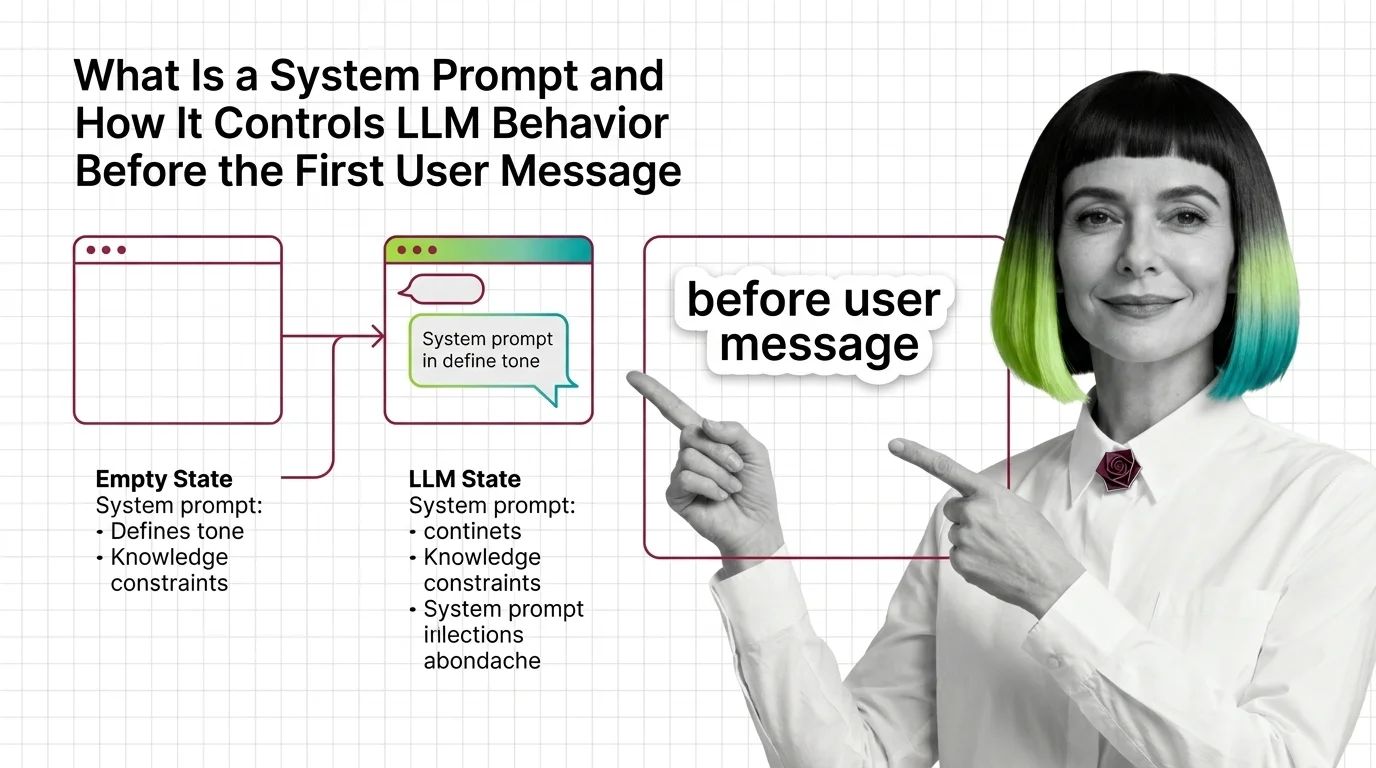
What Is a System Prompt and How It Controls LLM Behavior Before the First User Message
System prompts configure LLM identity, guardrails, and output format before any user message. They outrank user input in …
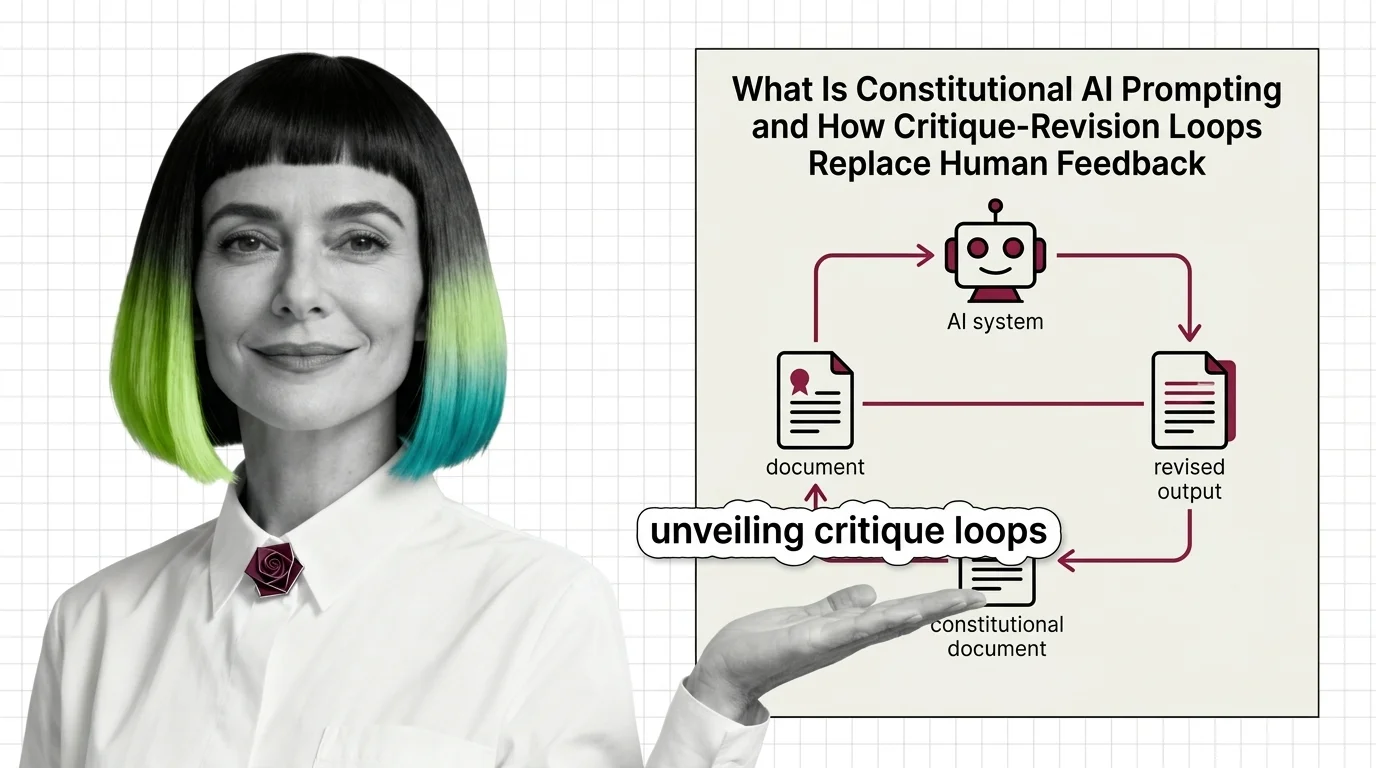
What Is Constitutional AI Prompting and How Critique-Revision Loops Replace Human Feedback
Constitutional AI prompting is a critique-revision loop: a model checks its own outputs against explicit principles, …
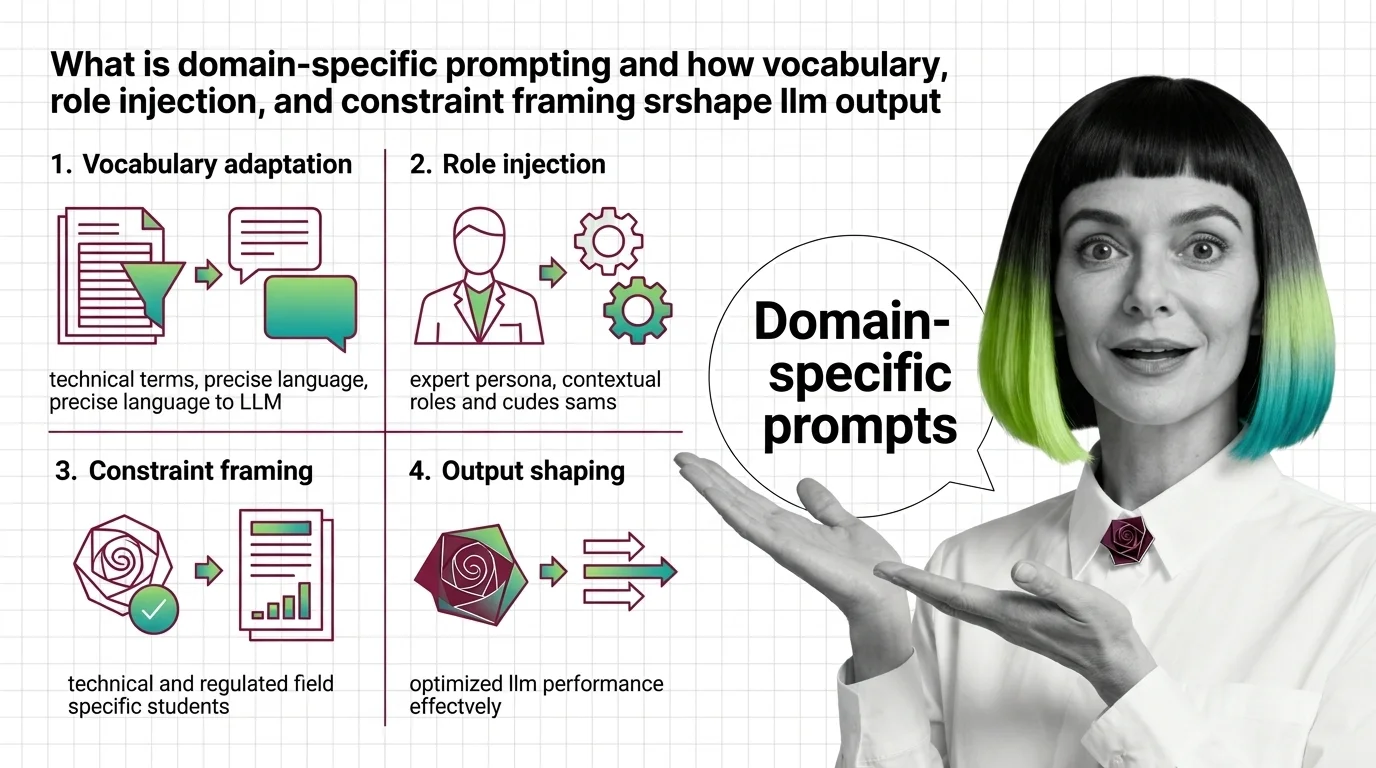
What Is Domain-Specific Prompting and How Vocabulary, Role Injection, and Constraint Framing Shape LLM Output
Domain-specific prompting adapts LLM output per field via vocabulary, role, and constraints — no retraining. Prompt …
What Is Multi-Turn Prompt Design and How Context Accumulates Across LLM Turns
Multi-turn prompt design passes full message history as tokens on every API call. Context accumulates linearly until the …
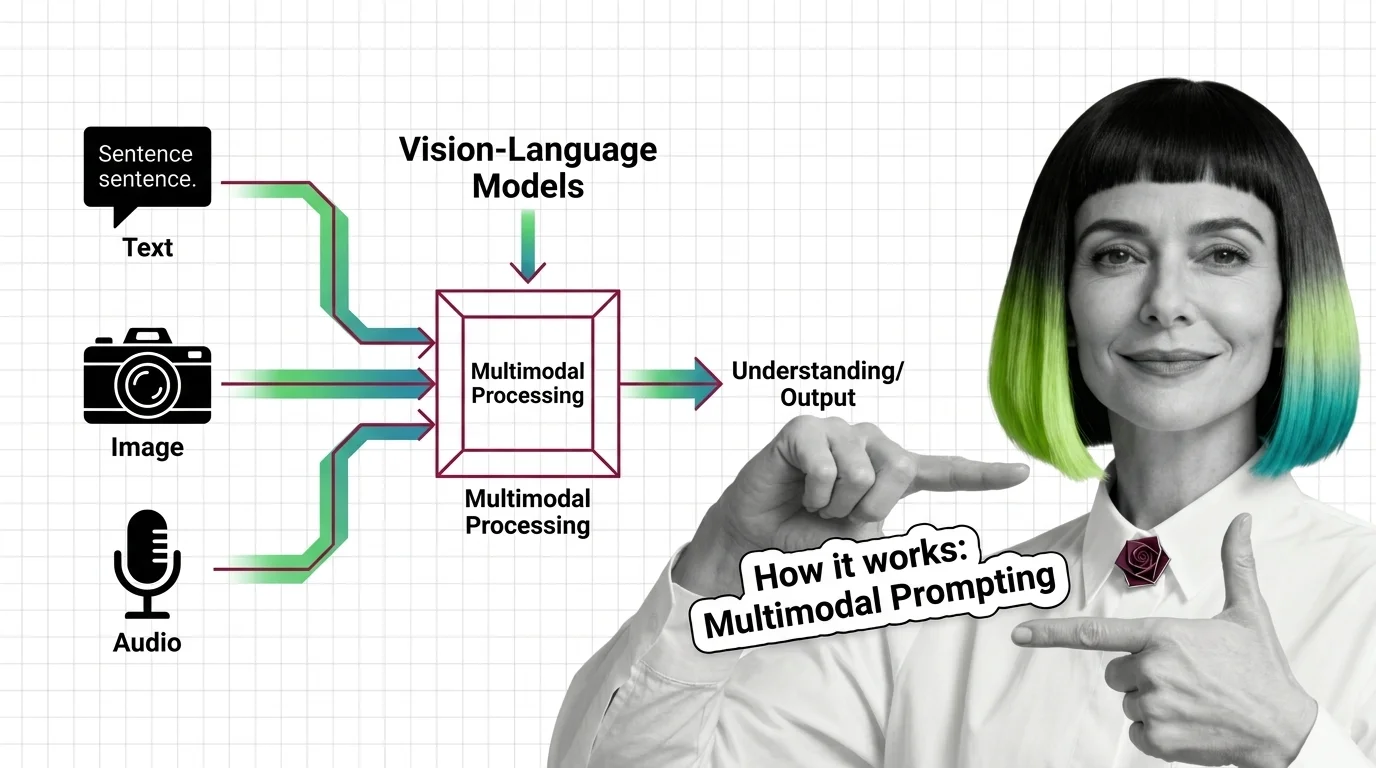
What Is Multimodal Prompting and How Vision-Language Models Process Images, Audio, and Text Together
Multimodal prompting sends images or audio alongside text in one query. A VLM encodes each image as patch tokens, then …
Prerequisites for Role Prompting and When It Technically Fails
Role prompting shifts LLM tone reliably but gains ~0.01% accuracy on factual benchmarks. Expert personas degrade …
System Prompts, Role Instructions, and Output Constraints: Anatomy of a Production Prompt
A production LLM prompt has four layers: instruction, context, input data, and output indicator. The layer you ignore is …
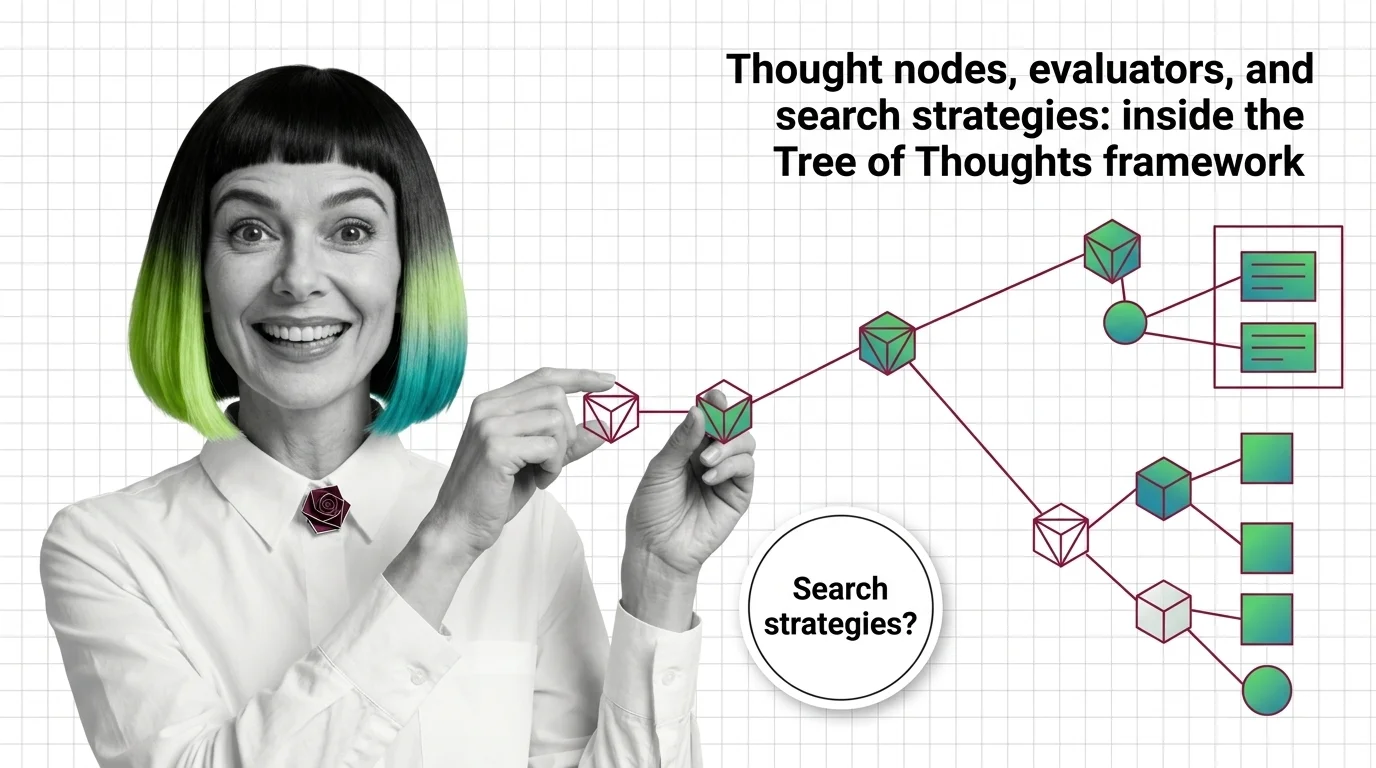
Thought Nodes, Evaluators, and Search Strategies: Inside the Tree of Thoughts Framework
Tree of Thoughts gives LLMs branching search via four components and two algorithms. GPT-4 scored 74% on Game of 24 — …
Token Explosion, Latency, and the Hard Limits of Explicit Tree of Thoughts
Tree of Thoughts uses 5–100× more tokens than CoT. On Game of 24, ToT hits 74% vs CoT's 4% — but at equal token budgets, …
Visual Hallucination, Resolution Caps, and the Unsolved Technical Limits of Multimodal Prompting in 2026
Two hallucination types explain why multimodal AI invents absent image details. Resolution caps and language priors are …
Context Rot, Lost-in-the-Middle, and the Hard Technical Limits of Multi-Turn LLM Conversations
LLMs degrade in multi-turn conversations via attention dilution, position bias, and context rot — degradation begins …
Context Windows, Token Budgets, and Why System Prompts Longer Than 300 Words Backfire
LLM position bias drops accuracy 30%+ when instructions sit mid-context — explaining why system prompts beyond 300 words …
Conversation History, Memory Layers, and the Prerequisites for Multi-Turn LLM Design
LLM conversation APIs are stateless: full history is re-injected on every call. Semantic, episodic, and procedural …
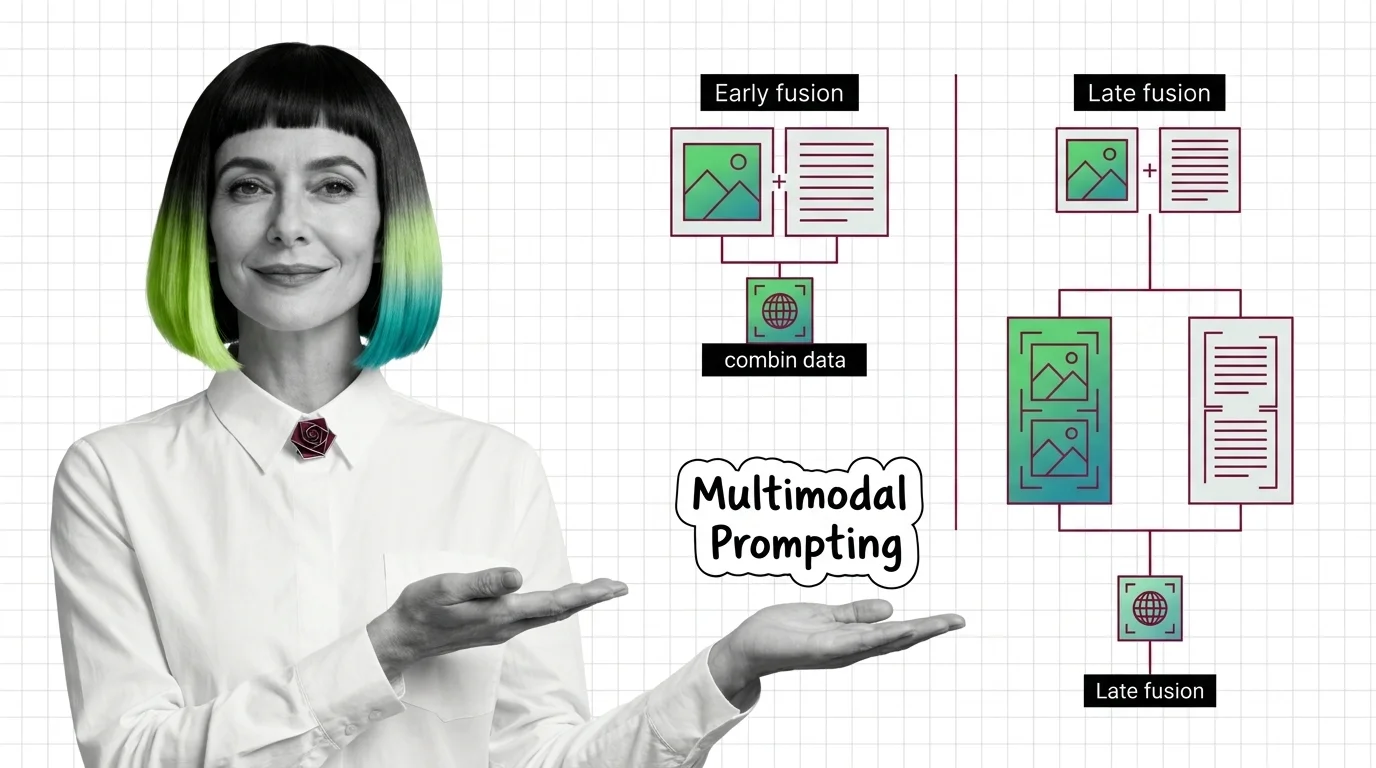
Early Fusion, Late Fusion, and What You Must Understand Before Writing Multimodal Prompts
Early fusion processes image and text tokens from layer one; late fusion merges at output only. Architecture determines …
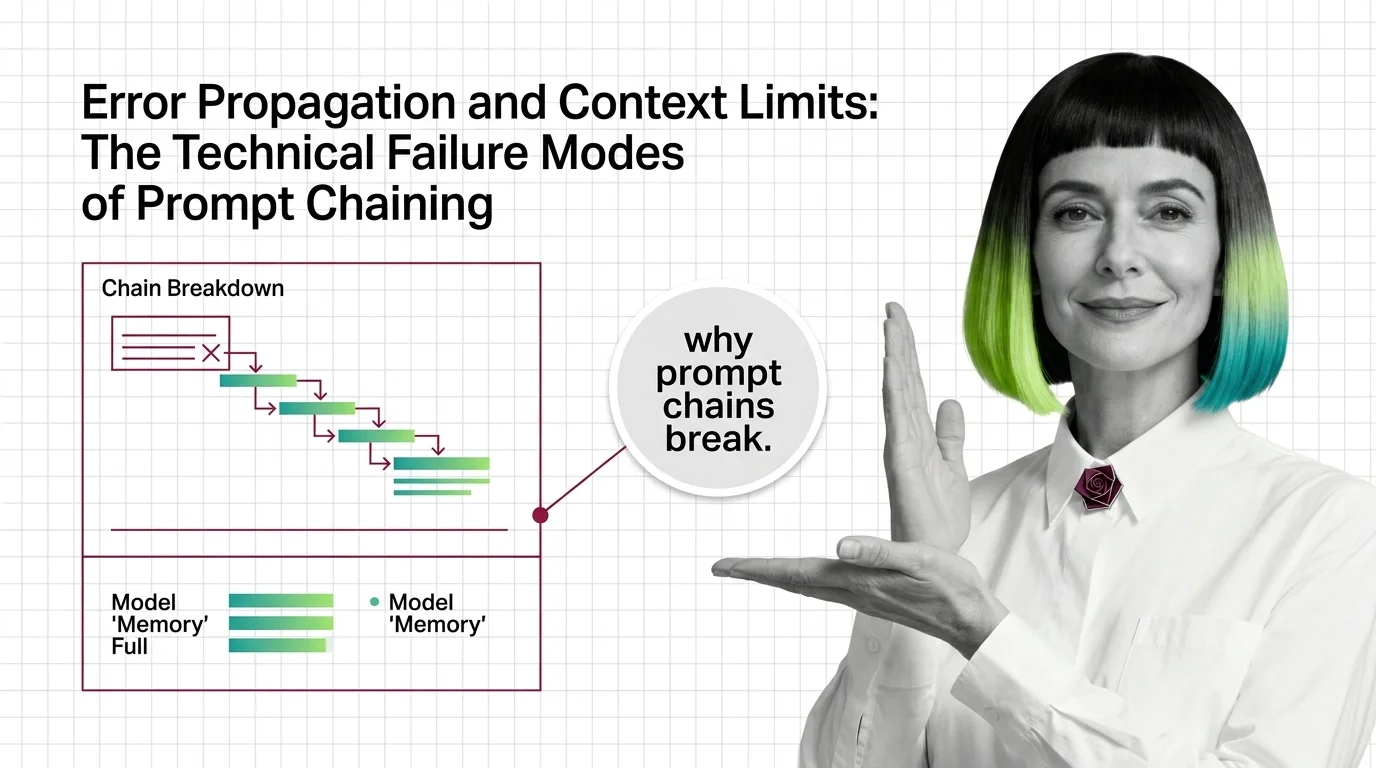
Error Propagation and Context Limits: The Technical Failure Modes of Prompt Chaining
Prompt chaining fails when early errors compound downstream and attention degrades at mid-context — accuracy drops …
Before Constitutional AI Prompting: Core Concepts and the Technical Limits of Self-Critique Loops
Constitutional AI prompting adapts Anthropic's CAI training method for runtime self-critique. Understand prerequisites …
Before You Build a ReAct Agent: Prerequisite Concepts and Technical Failure Modes Explained
ReAct pairs reasoning with tool calls in a loop. Context rot, exemplar mismatch, and token growth are failure modes that …
Before You Prompt a Doctor or Lawyer: Prerequisites and Hard Technical Limits of Domain-Specific Prompting
Domain-specific prompting shapes LLM behavior, not what it knows. Medical-specialized LLMs still hallucinate in up to …
What Is LLM Observability and How Span-Based Tracing Captures Every Step of a Prompt Chain
LLM observability applies distributed tracing to AI chains. Five span types (LLM, Task, Workflow, Tool, Agent) give each …
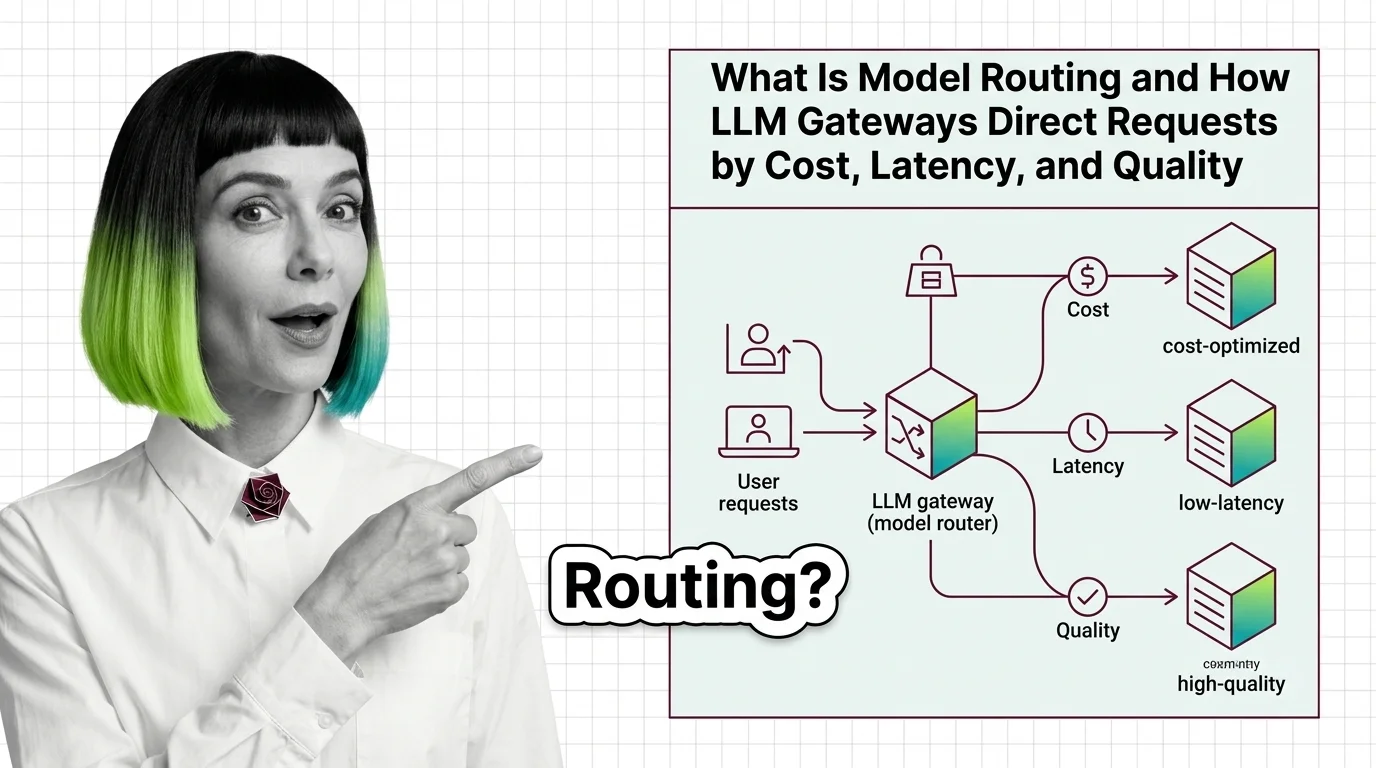
What Is Model Routing and How LLM Gateways Direct Requests by Cost, Latency, and Quality
Model routing is a decision layer between your app and multiple LLMs that directs each request to the optimal model by …
What Is LLM Cost Management and How Token-Based Pricing Scales in Production
LLM cost management controls token-based API costs at production scale. Output tokens cost 2–6× more than input; …
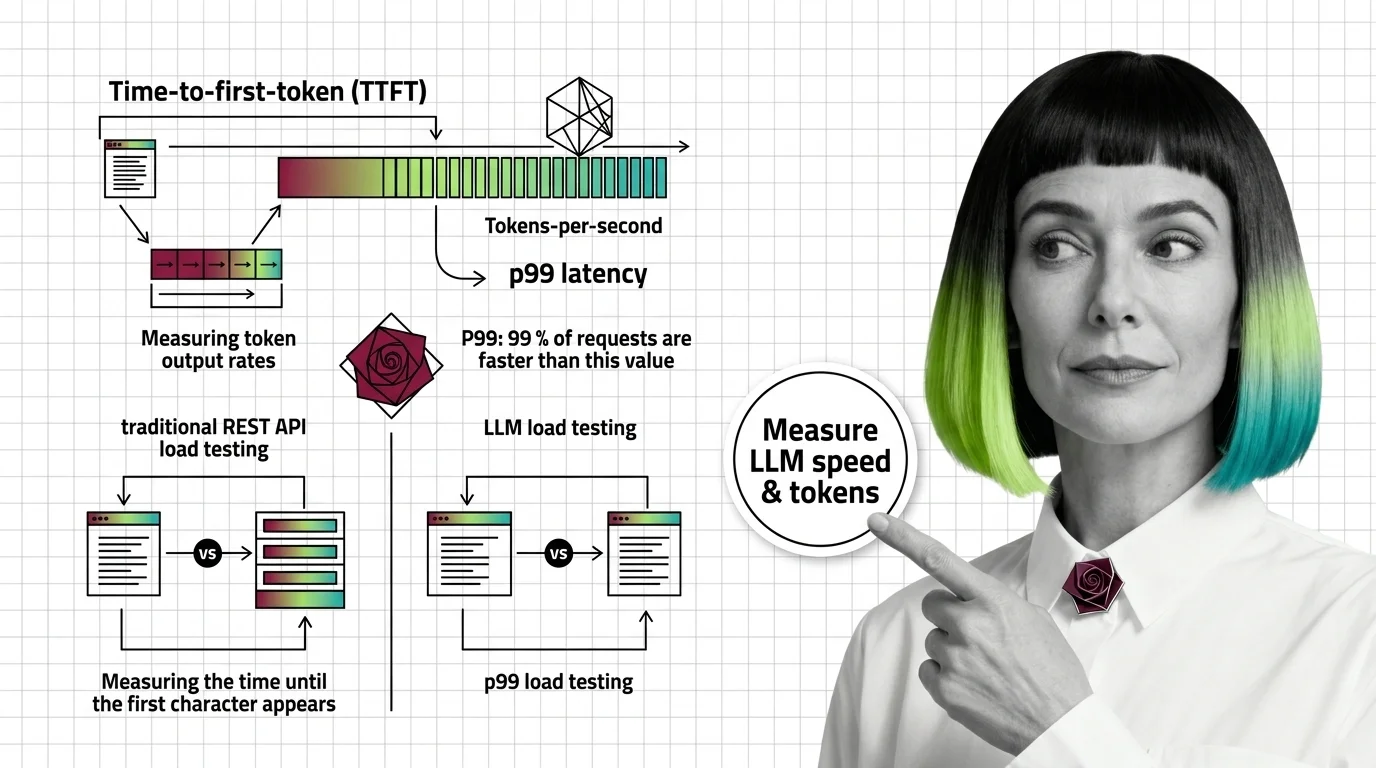
What Is LLM Load Testing and How TTFT, Tokens-Per-Second, and p99 Latency Are Measured
LLM load testing measures TTFT, TPS, and p99 latency under concurrent load. KV-cache GPU memory—not CPU threads—is the …
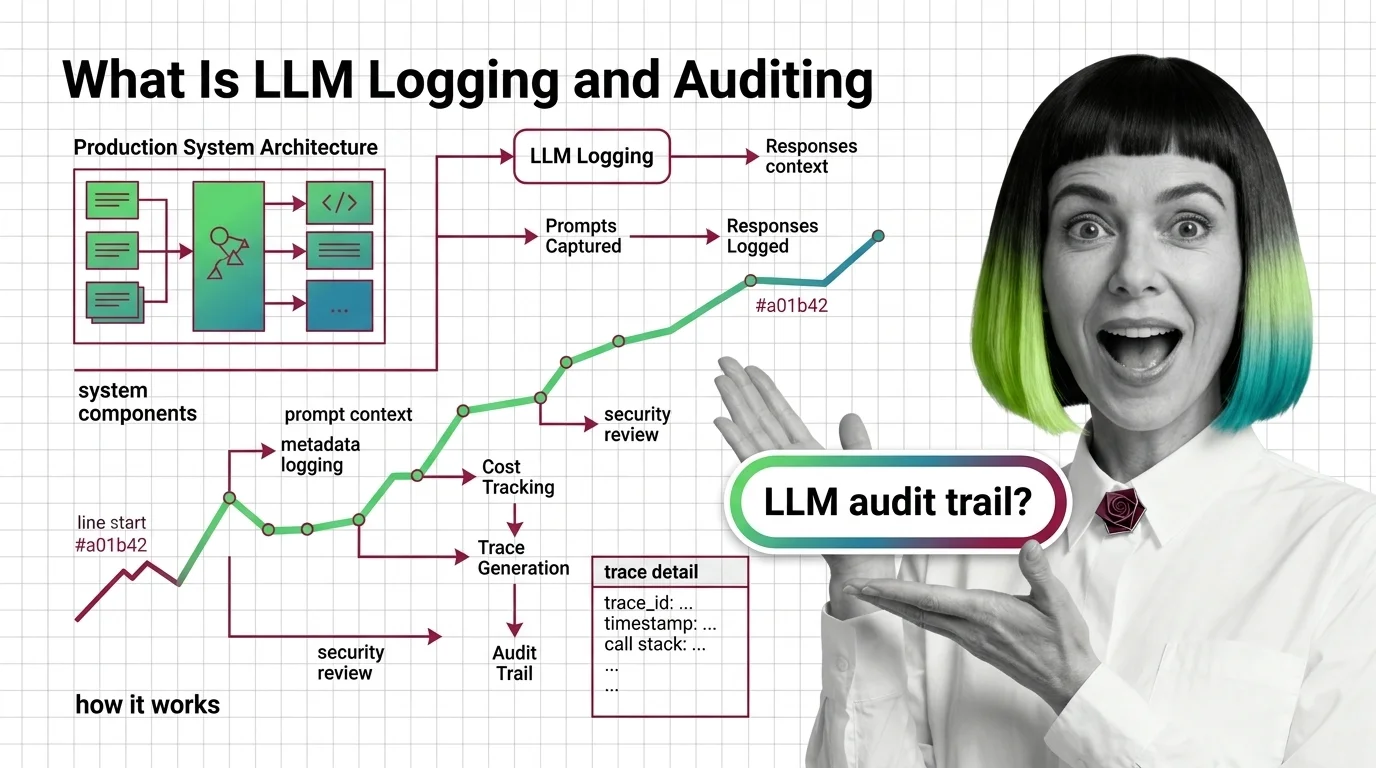
What Is LLM Logging and Auditing and How Production Systems Capture Prompts, Costs, and Traces
LLM logging captures prompts, tokens, latency, and costs per call. OTel GenAI trace hierarchies let teams reconstruct …
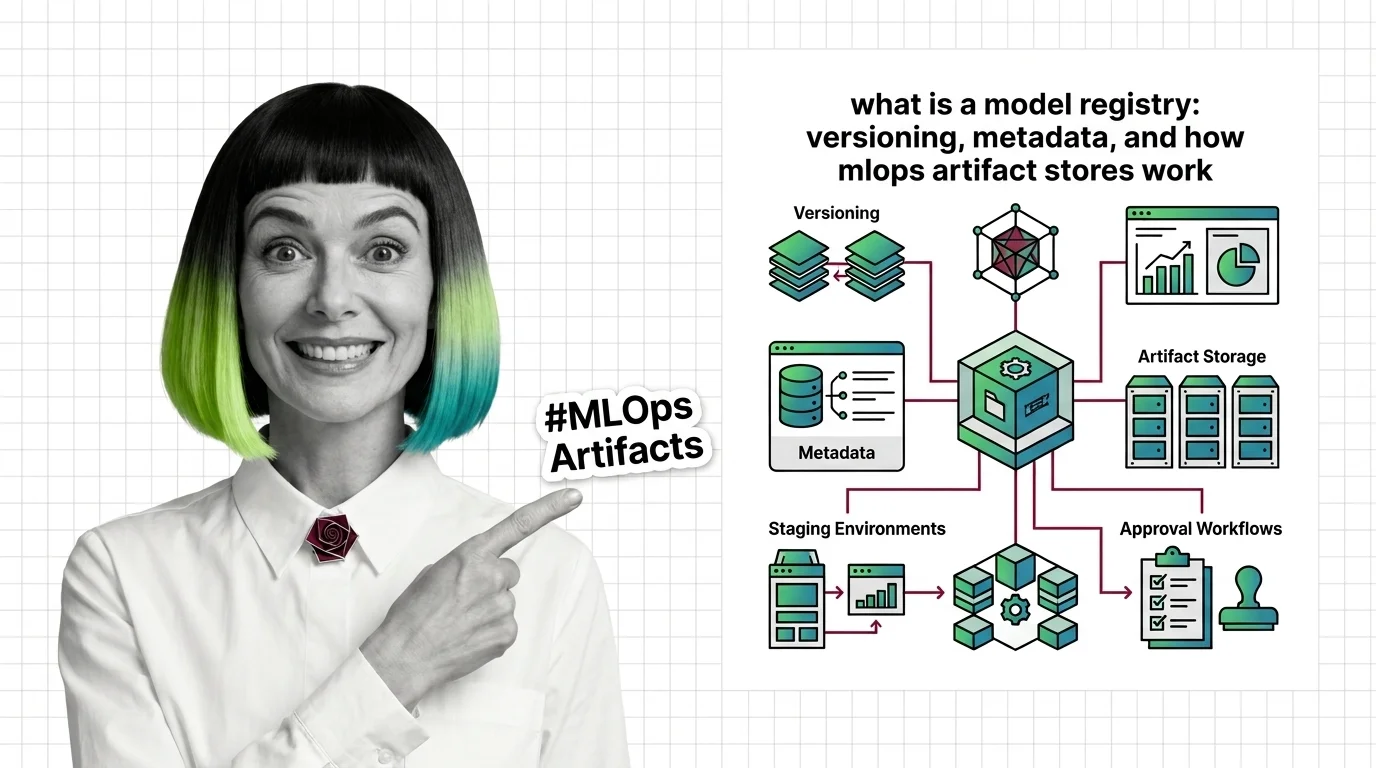
What Is a Model Registry: Versioning, Metadata, and How MLOps Artifact Stores Work
A model registry tracks ML model versions, weights, and deployment configs. MLflow 3 replaced fixed stages with named …
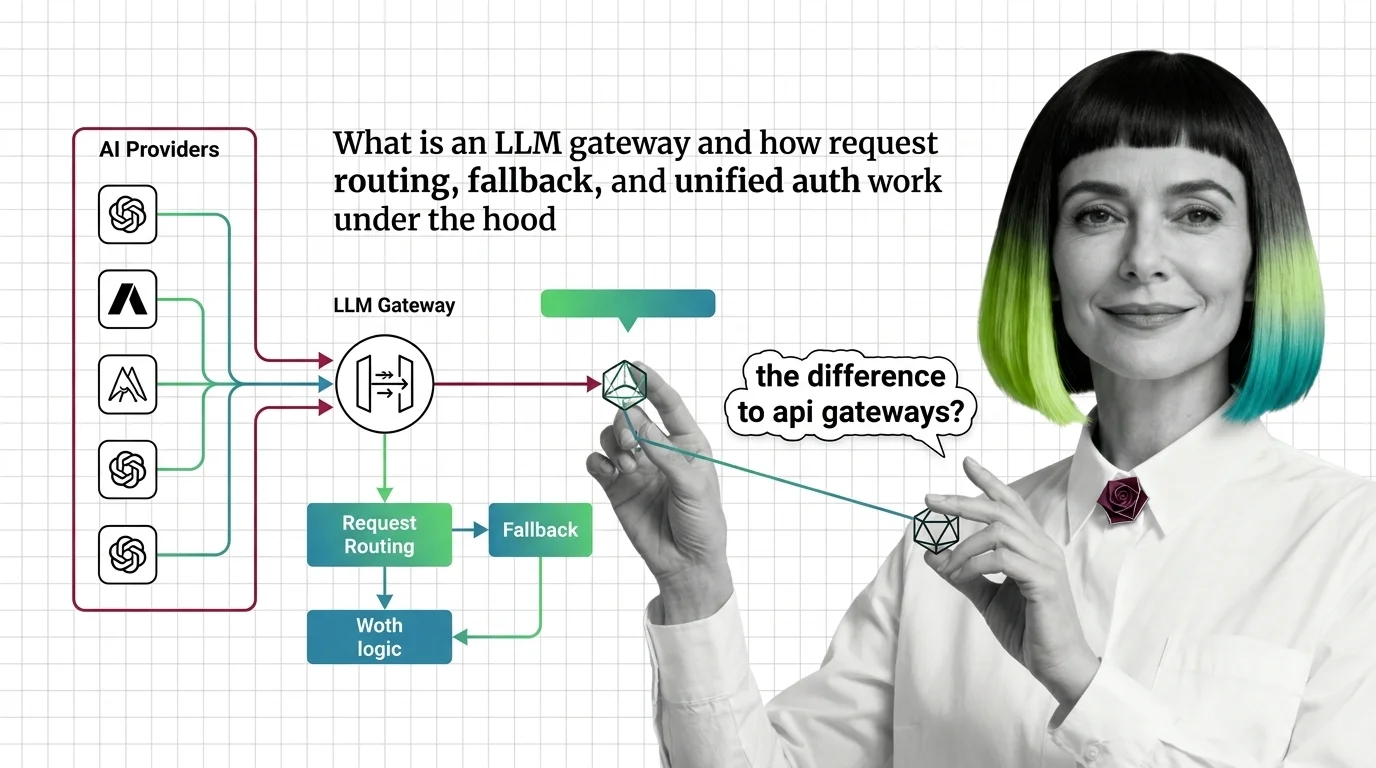
What Is an LLM Gateway and How Request Routing, Fallback, and Unified Auth Work Under the Hood
LLM gateway: middleware routing app requests across AI providers, with fallback, unified auth, and token tracking. …
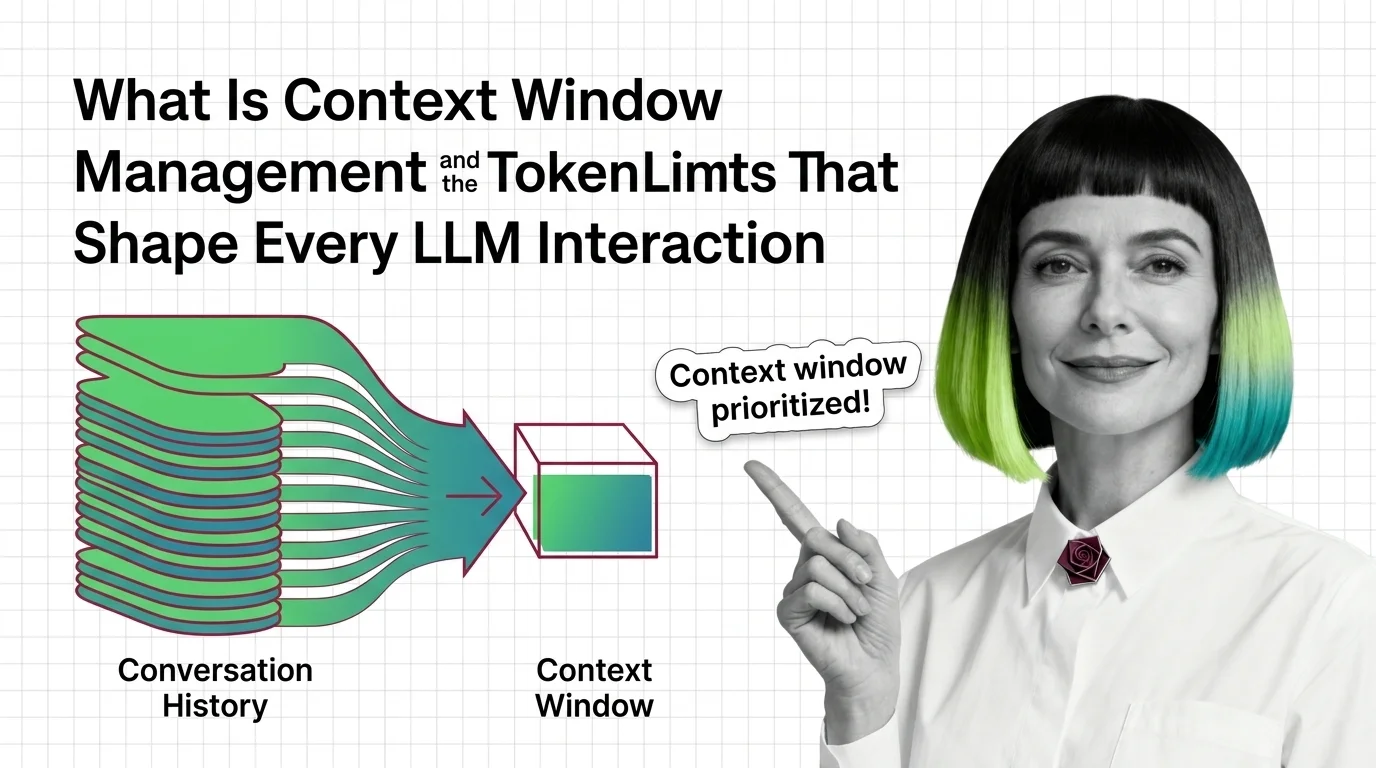
What Is Context Window Management and the Token Limits That Shape Every LLM Interaction
Context window management controls what an LLM sees at inference time. Past 15K words, latency can spike sevenfold — how …
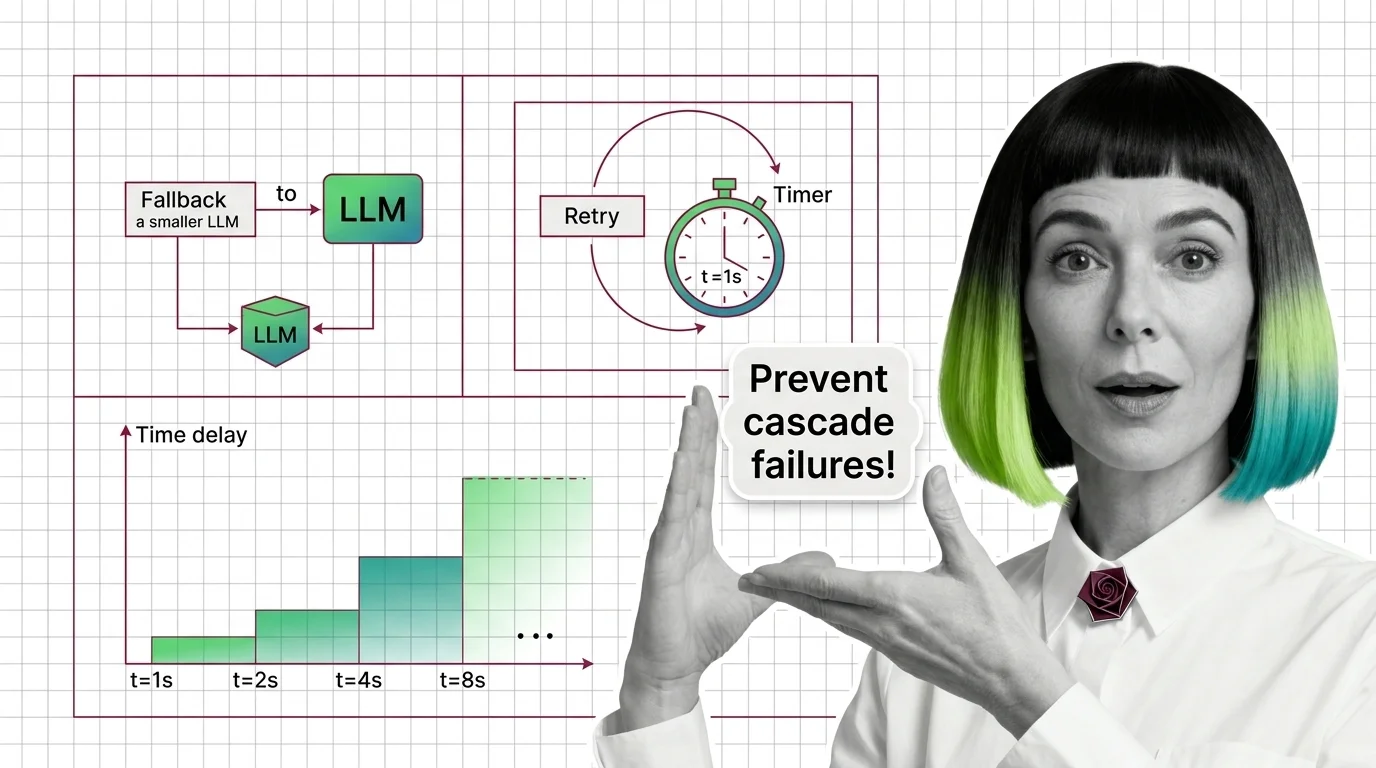
What Are LLM Fallback and Retry Patterns and How Exponential Backoff Prevents API Cascade Failures
LLM fallback and retry patterns reroute failed calls to backup models. Exponential backoff with jitter stops retry …
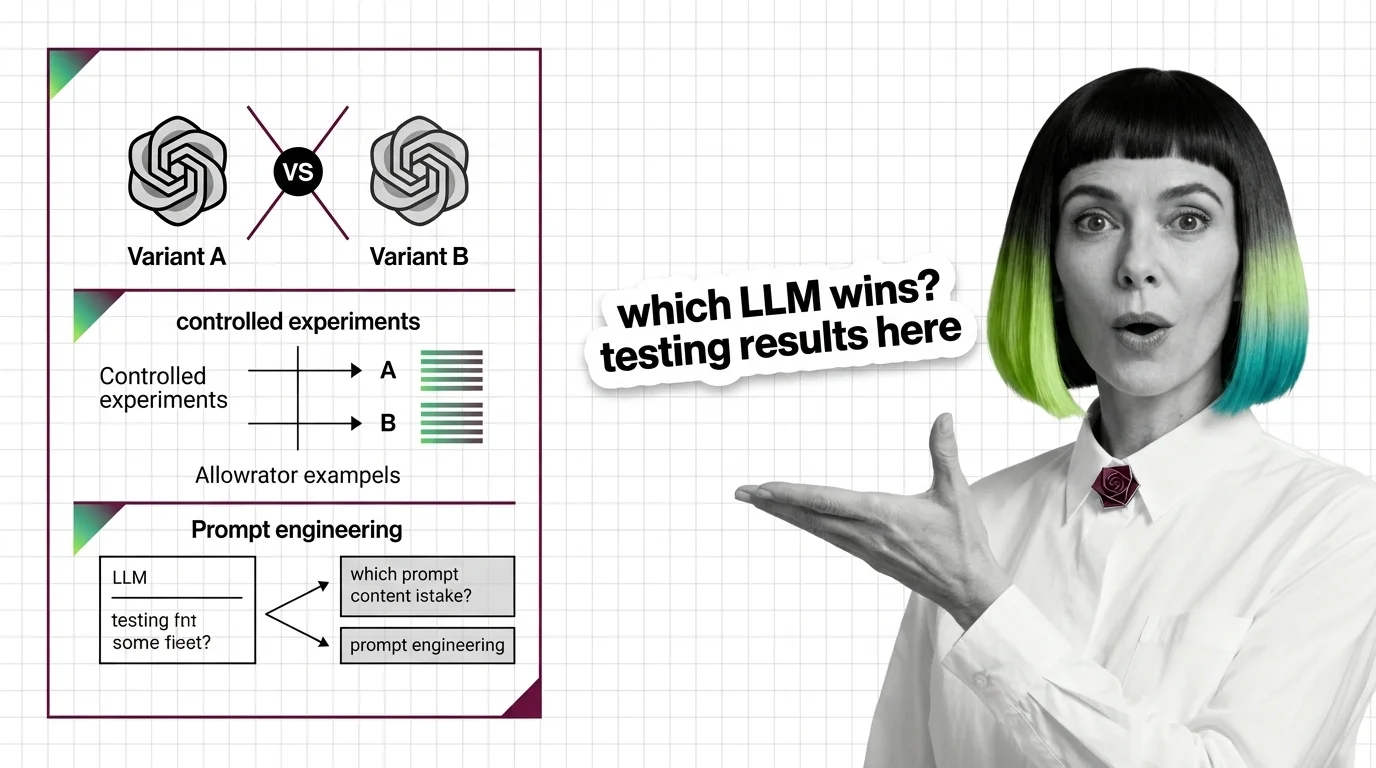
What Is A/B Testing for LLMs and How Controlled Experiments Evaluate Prompt and Model Variants
A/B testing for LLMs evaluates prompt and model variants by splitting production traffic and measuring quality, latency, …
Streaming Gaps, Cold Starts, and Tool Limits: The Hard Technical Constraints of LLM Load Testing
LLM load tests fail silently on streaming gaps, KV cold starts, and tool metric inconsistencies—three flaws that make …
Version Sprawl, Schema Drift, and the Engineering Limits of Model Registry at Enterprise Scale
A model registry tracks versions. It does not enforce input contracts, cross-team isolation, or output schema. At scale, …
Sample Size, Statistical Power, and Why Measuring LLM Output Quality Is Harder Than Click-Through Rates
LLM output quality has up to 34% within-model variance — enough to invalidate a standard A/B test. The sample size math …
Sliding Windows, Summarization, KV Cache, and the Hard Technical Limits of Context Compression in 2026
Production LLMs use sliding windows, KV caching, and summarization to manage context. GPU memory — not token limits — …
PII Redaction, Trace Sampling, and the Technical Limits of LLM Logging at Production Scale
LLM logging at scale pits capture fidelity against PII risk and cost. Tail sampling, PII redaction, and immutable audit …
Provider Failover, Timeout Handling, and Thundering Herd: What Makes LLM Retry Logic Break
LLM retry logic breaks in a specific way: pure exponential backoff synchronizes all clients, creating a thundering herd …
The Architecture Name on the Spec Sheet Is a Failure Contract
A neural network architecture family — CNN, RNN, GAN, GNN — is a capability envelope: it fixes what a model can …
Debugging a Transformer When You Can't Set a Breakpoint
Debugging a transformer incident when there is no breakpoint: which on-call instincts still catch model failures, and …
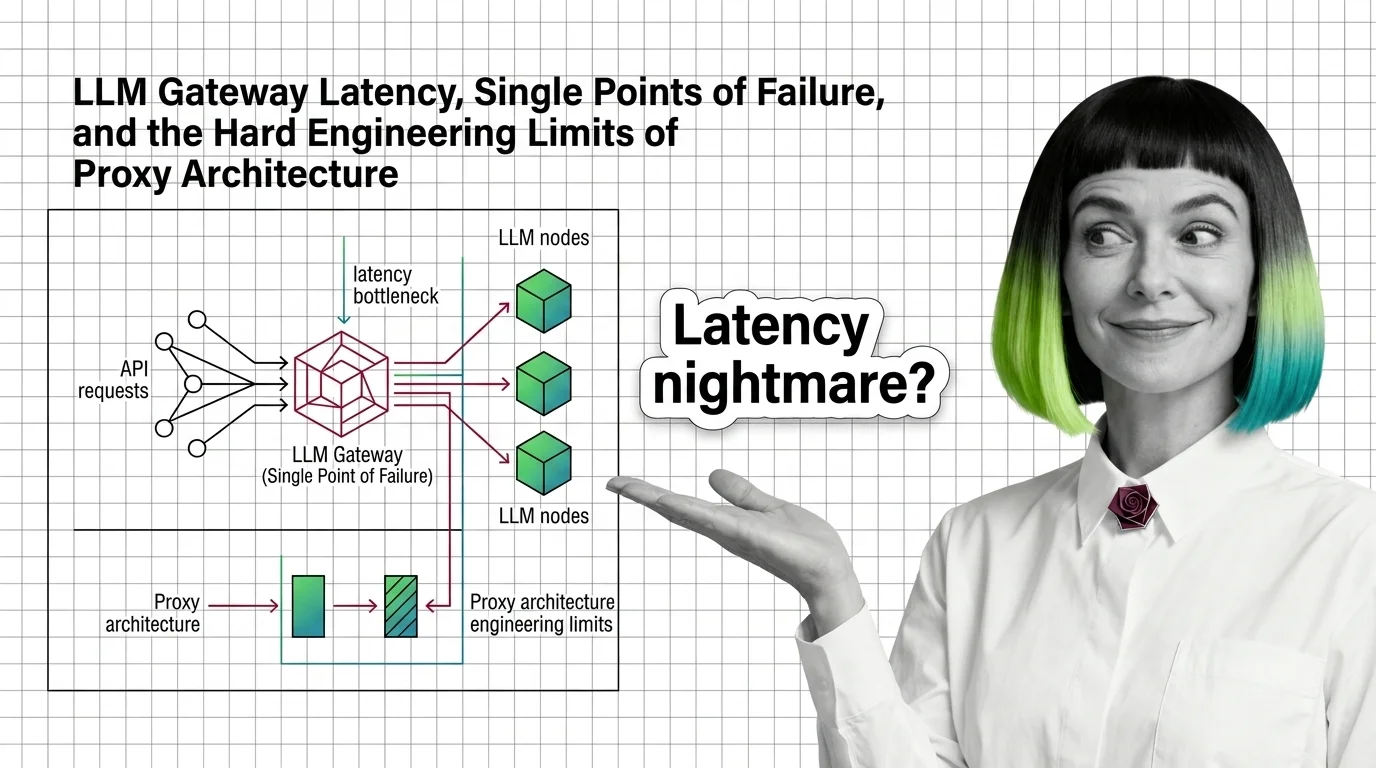
LLM Gateway Latency, Single Points of Failure, and the Hard Engineering Limits of Proxy Architecture
LLM gateways add 2–240ms overhead. Latency is rarely the bottleneck — single points of failure and security …
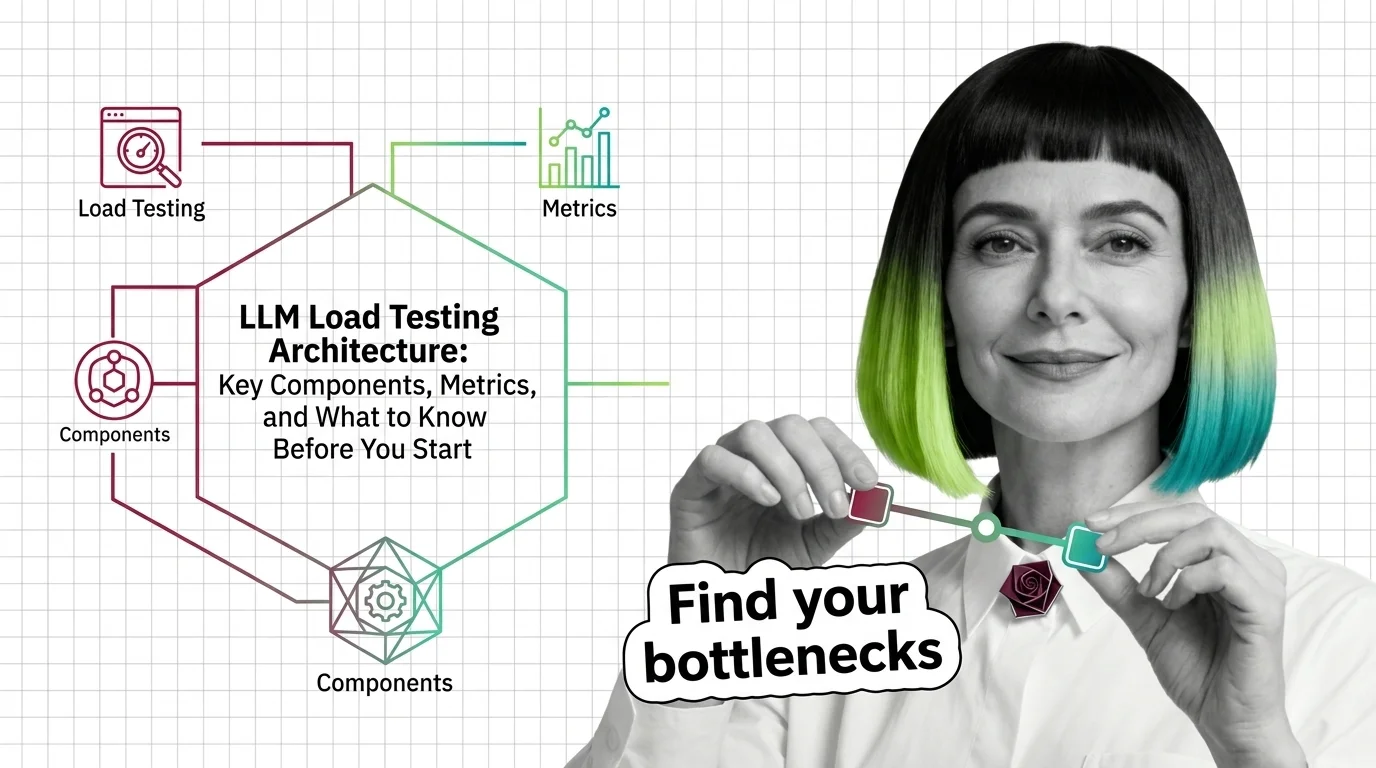
LLM Load Testing Architecture: Key Components, Metrics, and What to Know Before You Start
LLM load testing requires metrics standard tools miss. TTFT, inter-token latency, and goodput determine whether an …
Calling a Model Means Inheriting Its Runtime Cost Contract
Dense transformers, mixture-of-experts, and state-space models turn identical API calls into different cost, latency, …
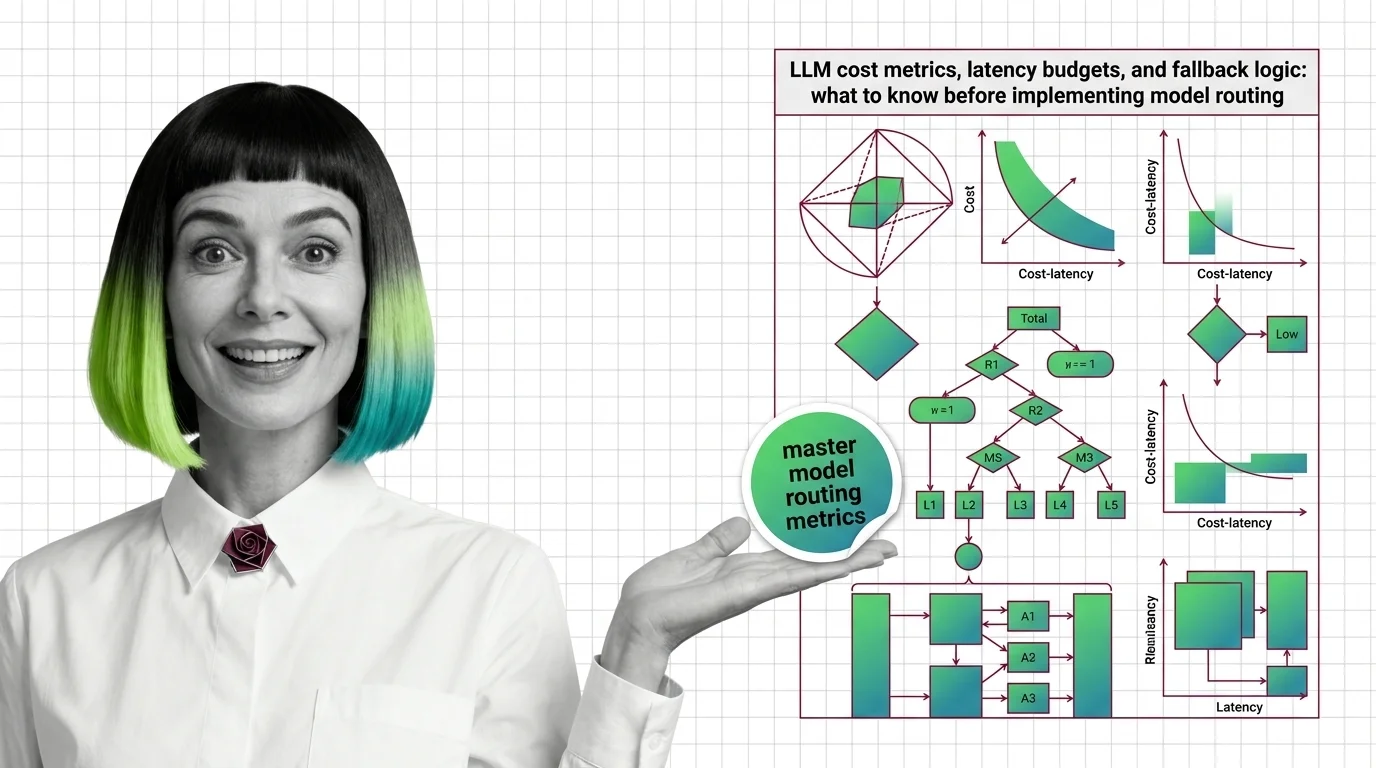
LLM Cost Metrics, Latency Budgets, and Fallback Logic: Before Implementing Model Routing
Model routing rests on three prerequisites: token cost asymmetry, P99 latency SLOs by workload, and circuit breaker …
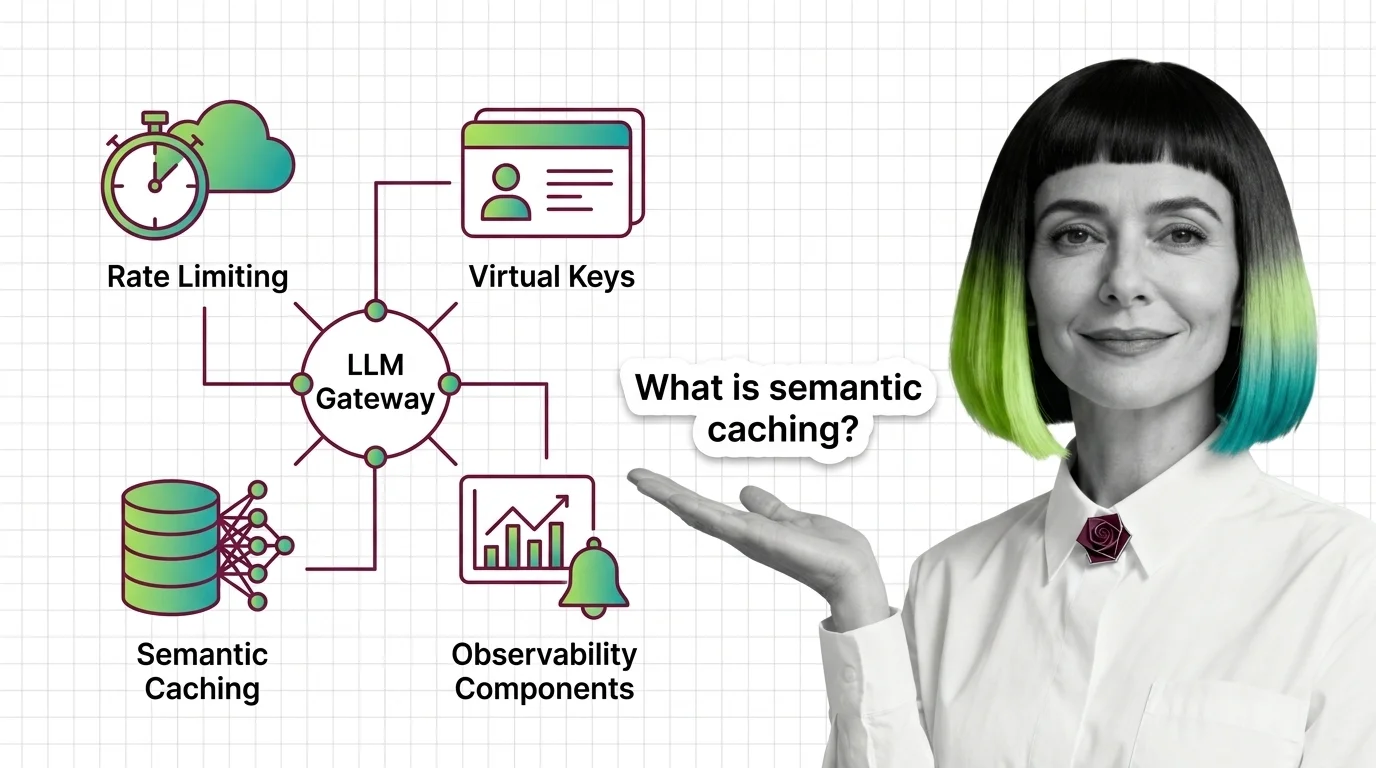
LLM Gateway Architecture: Rate Limiting, Virtual Keys, Semantic Caching, and Observability Components
LLM gateways govern AI traffic via four components: rate limiting (RPM/TPM/budget), scoped virtual keys, semantic …
Before You Monitor LLMs: MLOps Prerequisites and the Technical Limits No Observability Tool Can Fix
LLM observability needs baselines before the first trace. No tool prevents hallucinations or non-deterministic output — …
Context Windows, KV Cache, and Model Pricing: Prerequisites for Optimizing LLM Spend
LLM API cost optimization requires understanding KV cache mechanics, input/output token asymmetry, and prompt caching …
Position Bias, Self-Preference, and the Technical Limits of LLM-as-a-Judge
LLM-as-a-judge shows systematic position bias and self-preference: GPT-4 flips its verdict on ~35% of pairs when answer …
Prerequisites for LLM-as-a-Judge: Eval Metrics, Rubrics, and Human Baselines
An LLM-as-a-judge is only as reliable as its scaffolding: ground-truth labels, rubrics, and a human baseline. GPT-4 …
What Is LLM-as-a-Judge and How One Model Scores Another's Outputs
LLM-as-a-judge uses one model to grade another's output via pointwise, pairwise, or rubric scoring. Fast, but prone to …
Prerequisites for Reading AI Benchmark Scores: Metrics, Pass@k, and Contamination
AI benchmark scores hide three variables: what the metric counts, the pass@k sampling regime, and whether the test …
Saturation, Contamination, and Construct Validity: The Technical Limits of AI Benchmarks
AI benchmarks fail through saturation, contamination, and construct validity. Decontamination cut HumanEval scores …
What Are Benchmark Datasets and How GLUE, MMLU, and SWE-bench Measure LLM Performance
Benchmark datasets are fixed test sets that score and rank LLMs. MMLU's 15,908 questions and SWE-bench's 2,294 GitHub …
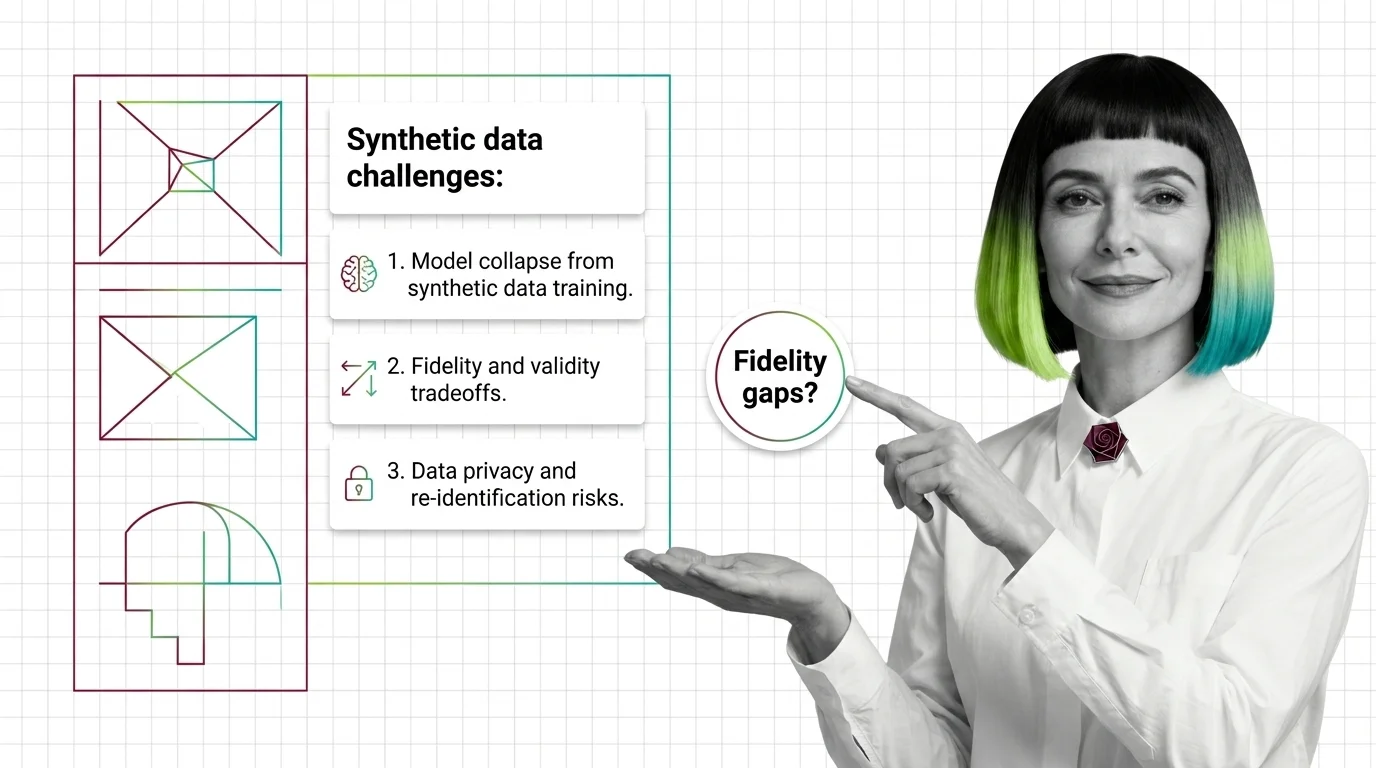
Model Collapse, Fidelity Gaps, and Re-Identification: The Technical Limits of Synthetic Data
Synthetic data faces three hard limits: model collapse from recursive training, fidelity-privacy tradeoffs, and …
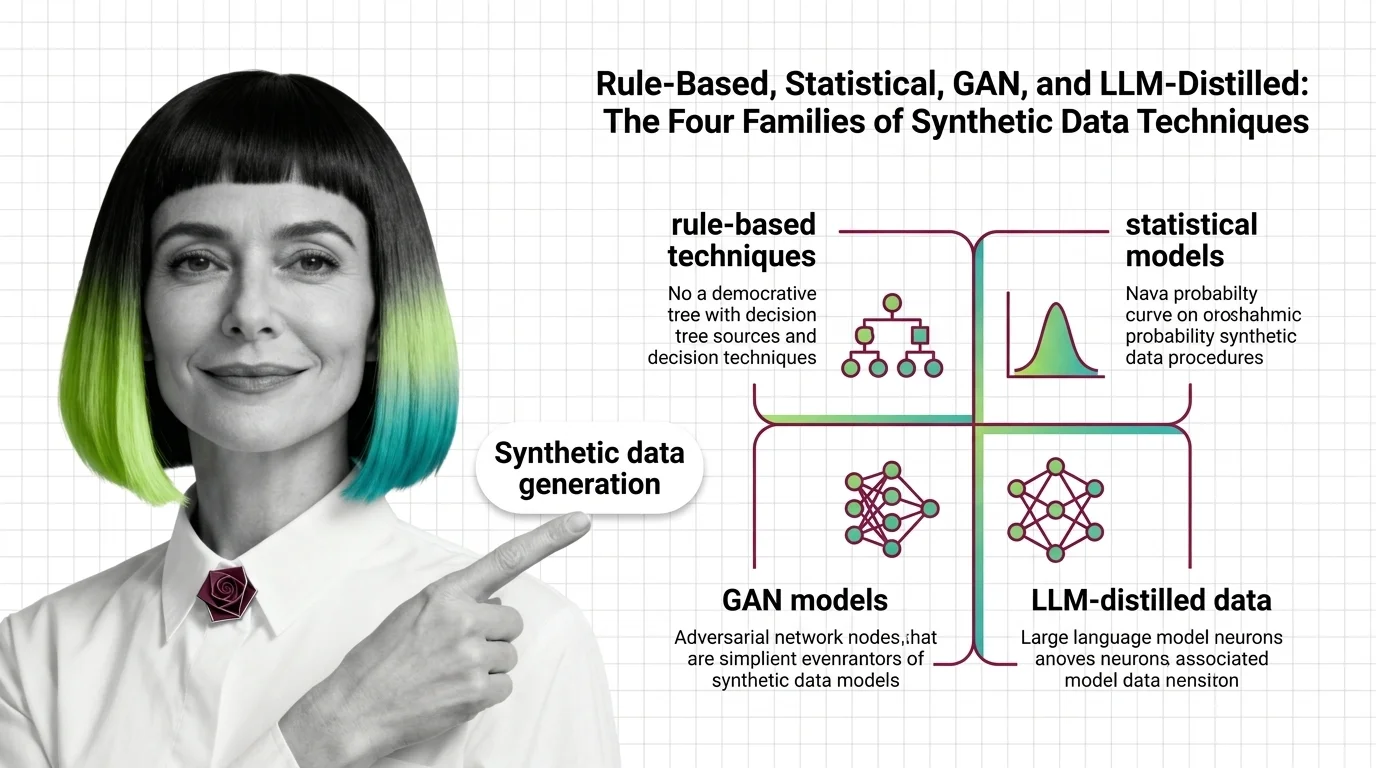
Rule-Based, Statistical, GAN, and LLM-Distilled: The Four Families of Synthetic Data Techniques
Synthetic data generation spans four families — rule-based, statistical, GAN-based, and LLM-distilled — each preserving …
What Is Synthetic Data Generation and How Artificial Training Data Is Created
Synthetic data generation creates artificial records that mimic a dataset's statistics without reusing real rows, via …
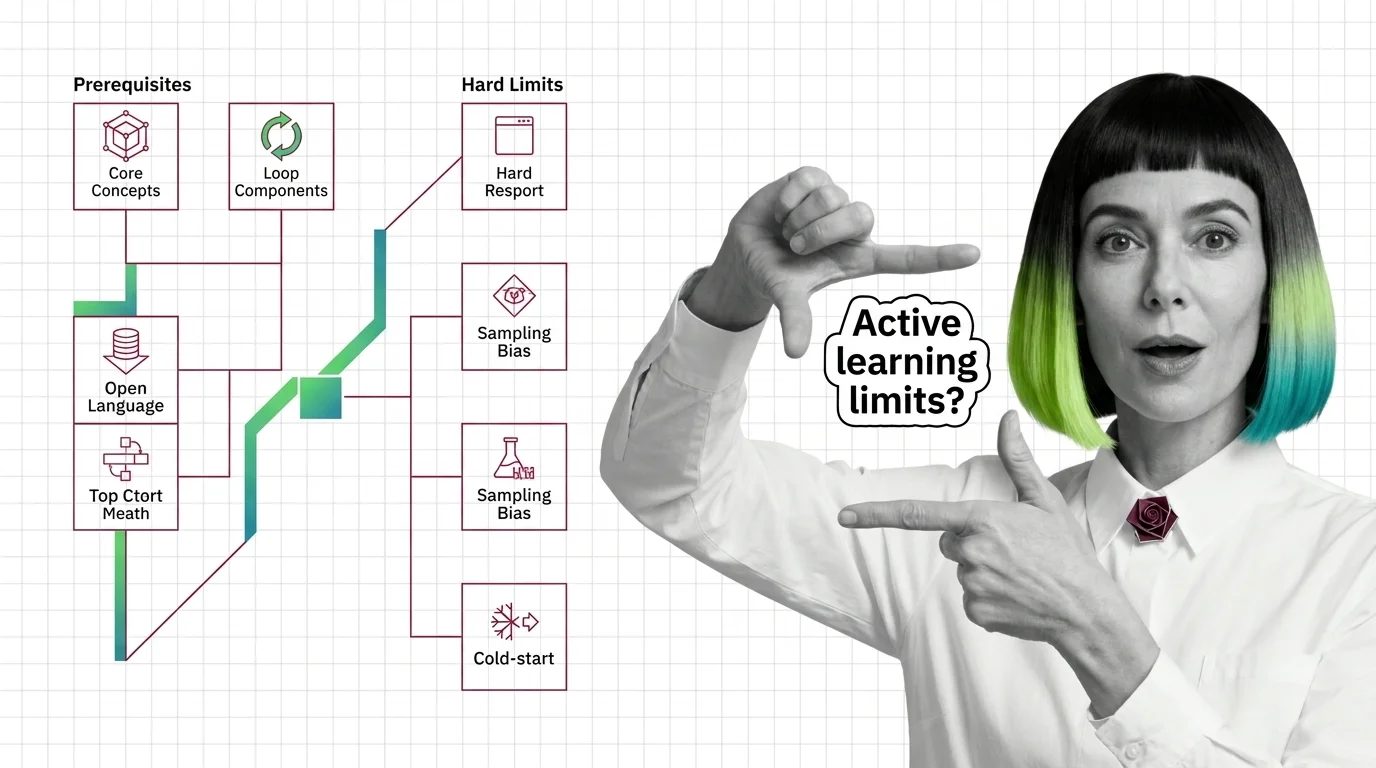
Before Active Learning: Prerequisites, Building Blocks, and the Hard Limits of Query Strategies
Active learning lets a model pick which examples to label instead of sampling at random — but sampling bias and …
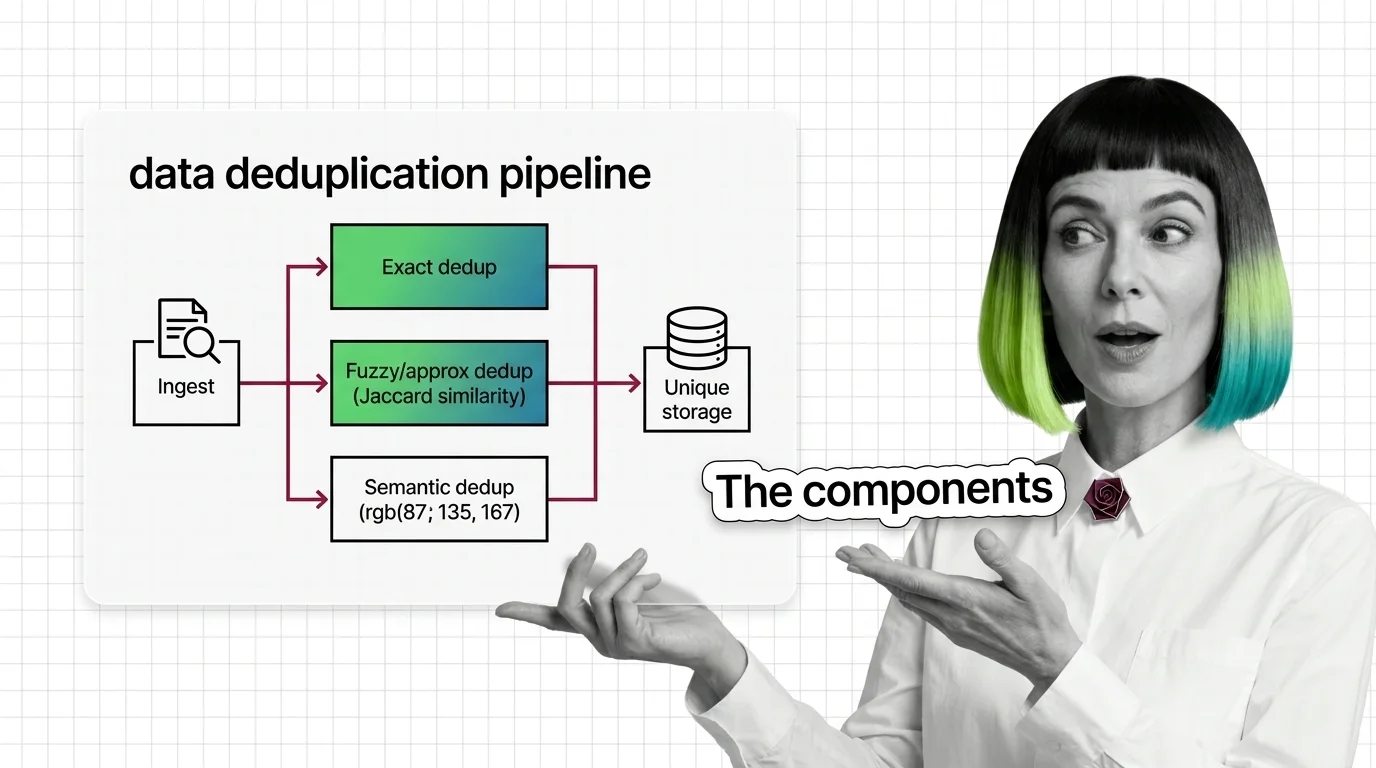
Exact, Fuzzy, and Semantic Deduplication: The Components and Prerequisites of a Dedup Pipeline
Data deduplication runs in three tiers: exact (hashing), fuzzy (MinHash+LSH), and semantic (embeddings). SemDeDup …
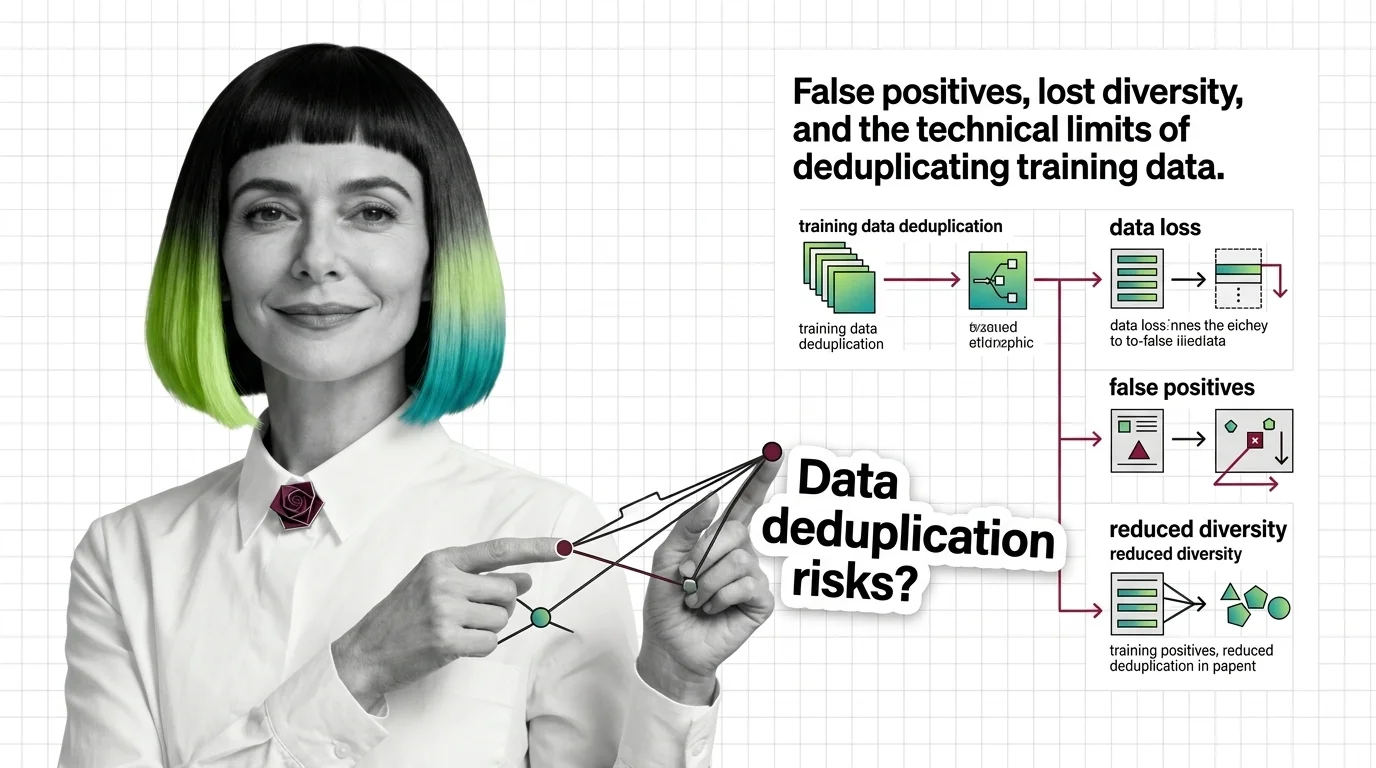
False Positives, Lost Diversity, and the Technical Limits of Deduplicating Training Data
Data deduplication measures surface overlap, not meaning, so it deletes rare examples as false positives and misses …
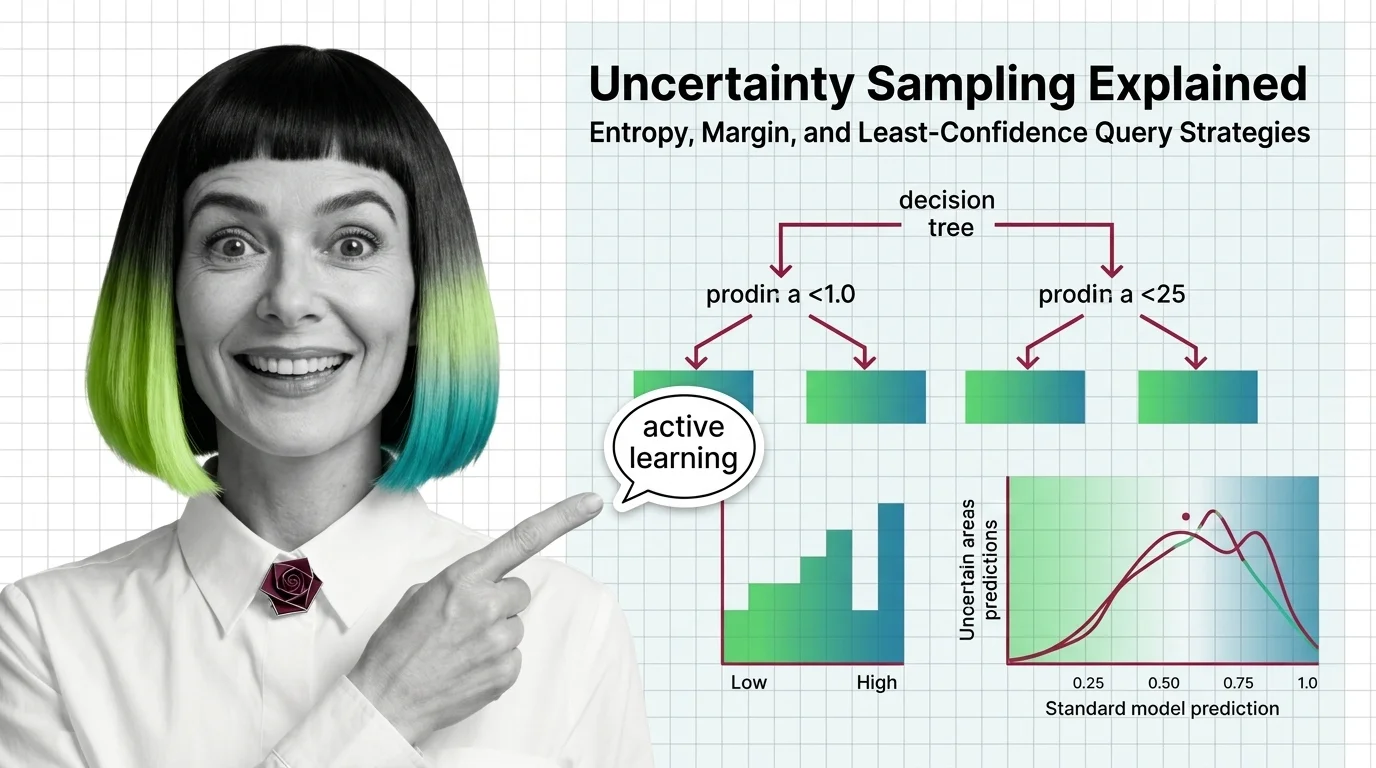
Uncertainty Sampling Explained: Entropy, Margin, and Least-Confidence Query Strategies
Uncertainty sampling is an active-learning strategy that labels the data a model is least confident about — via entropy, …
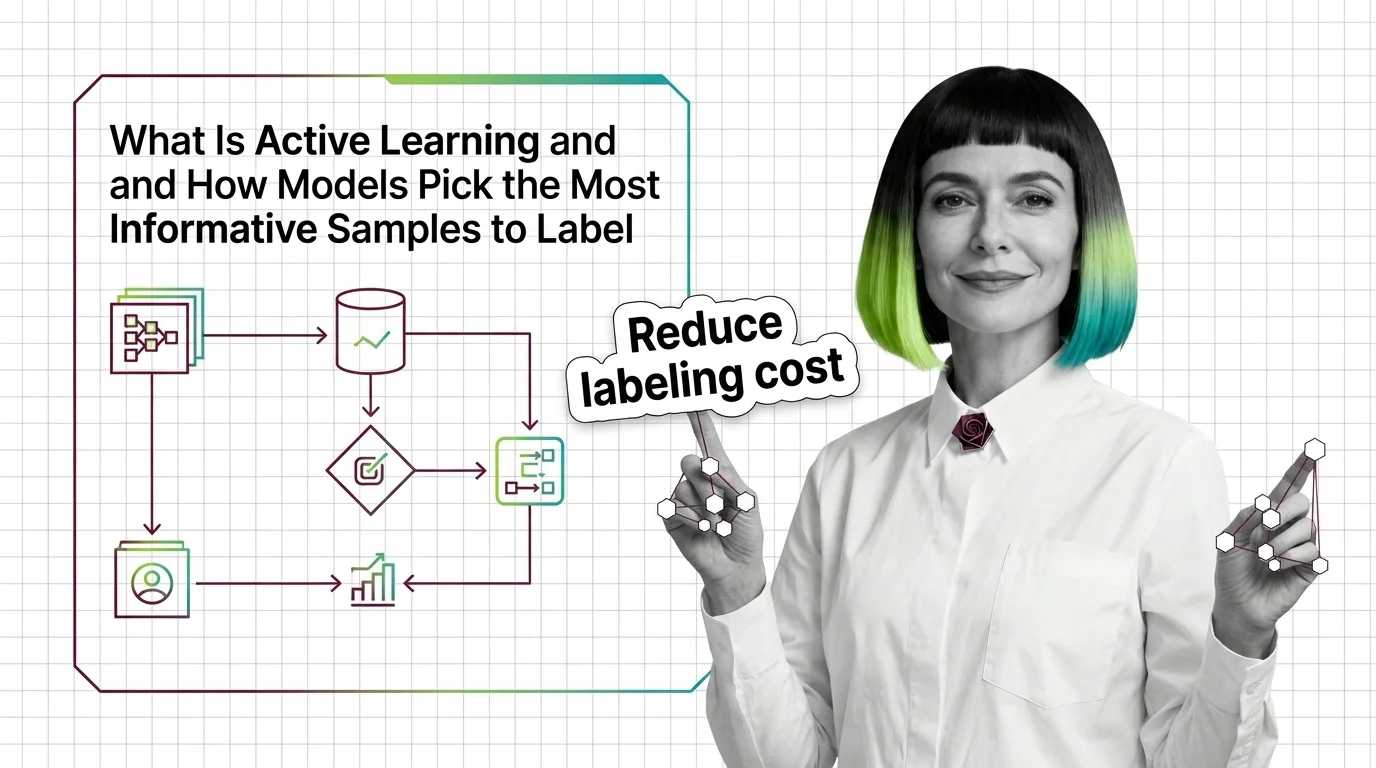
What Is Active Learning and How Models Pick the Most Informative Samples to Label
Active learning lets a model query only the most informative unlabeled samples to label, hitting target accuracy with …
What Is Data Deduplication and How MinHash LSH Detects Near-Duplicate Training Samples
Data deduplication removes near-duplicate training samples using MinHash LSH. Lee et al. found dedup cuts verbatim …
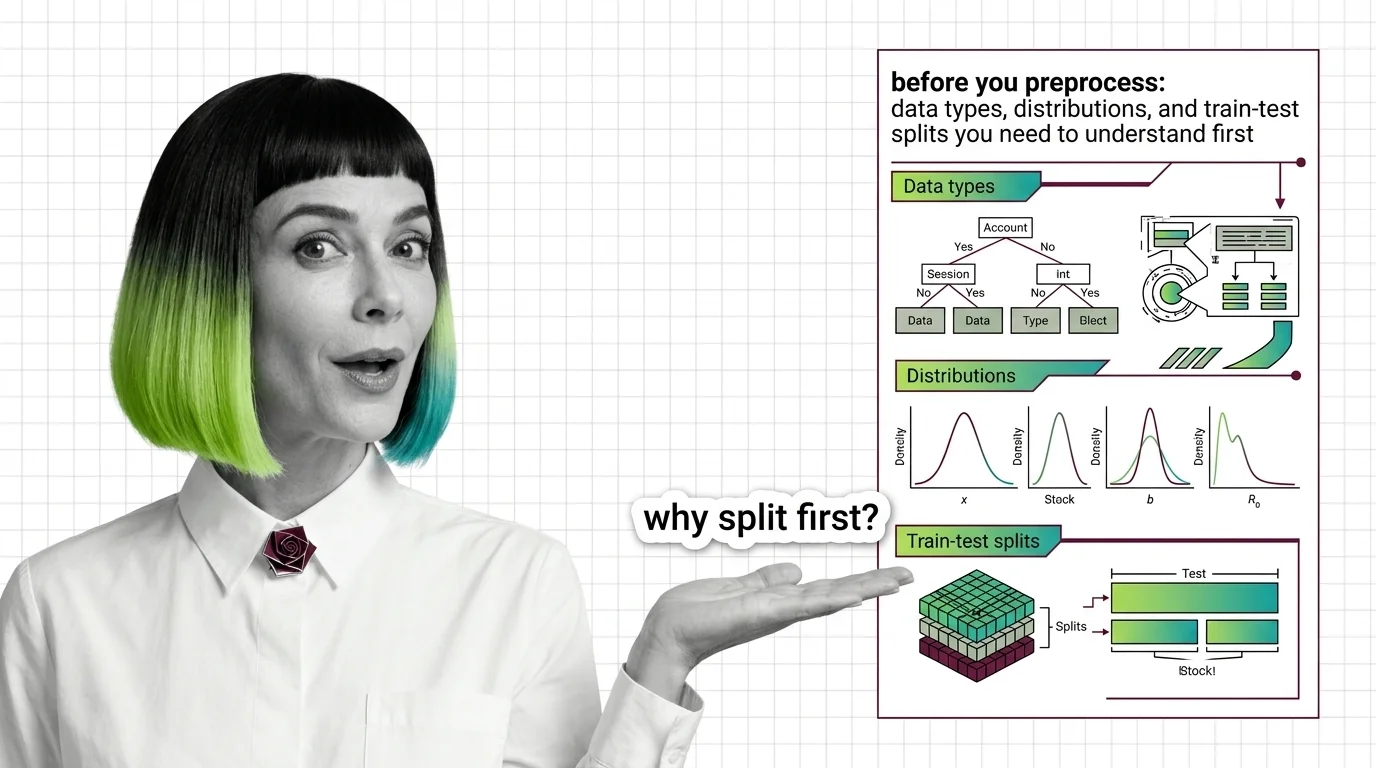
Before You Preprocess: Data Types, Distributions, and Train-Test Splits You Need to Understand First
Split data into train and test sets before preprocessing to prevent data leakage. Fitting scalers on the full dataset …
Data Leakage, Lost Information, and the Technical Limits of Preprocessing Pipelines
Data leakage occurs when information unavailable at prediction time enters training, inflating validation accuracy while …
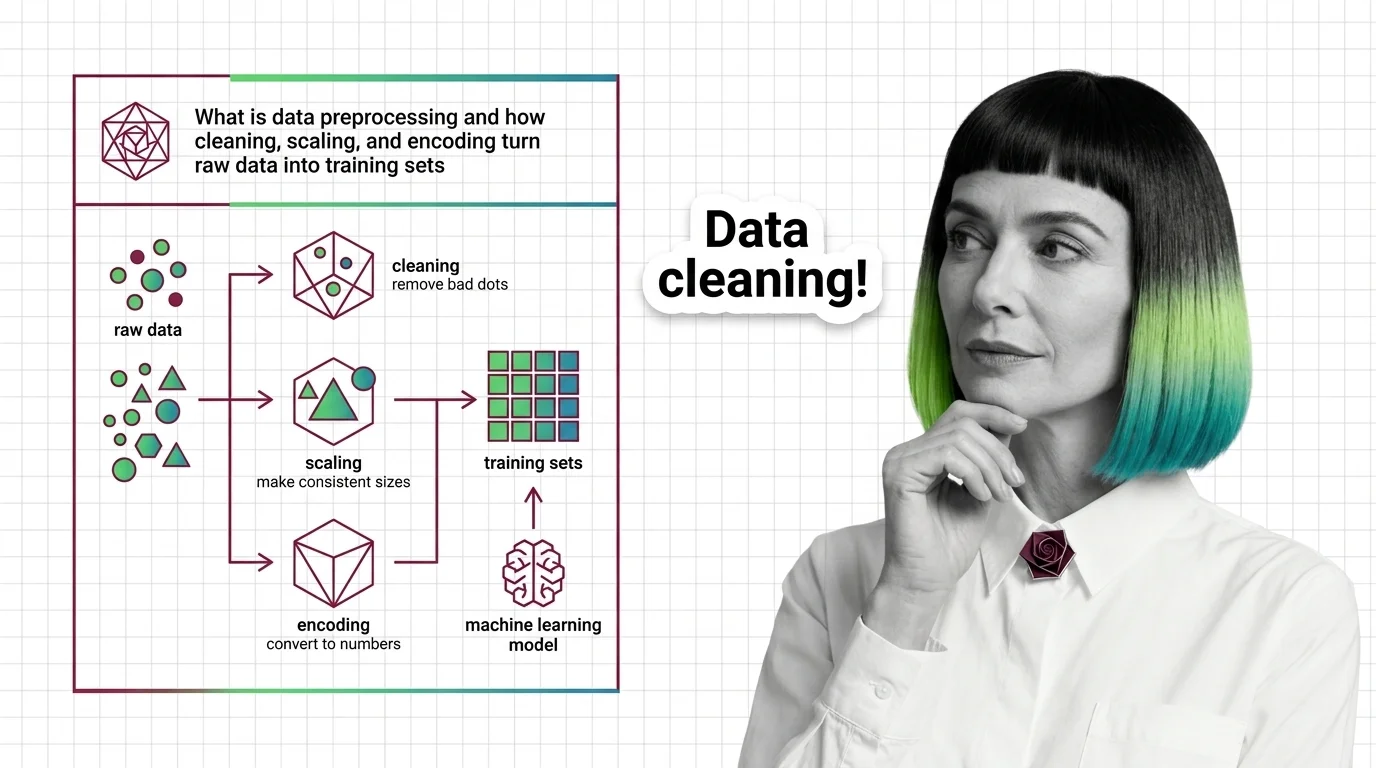
What Is Data Preprocessing and How Cleaning, Scaling, and Encoding Turn Raw Data into Training Sets
Data preprocessing cleans, scales, and encodes raw data into model-ready features. Fitting transformers before the …
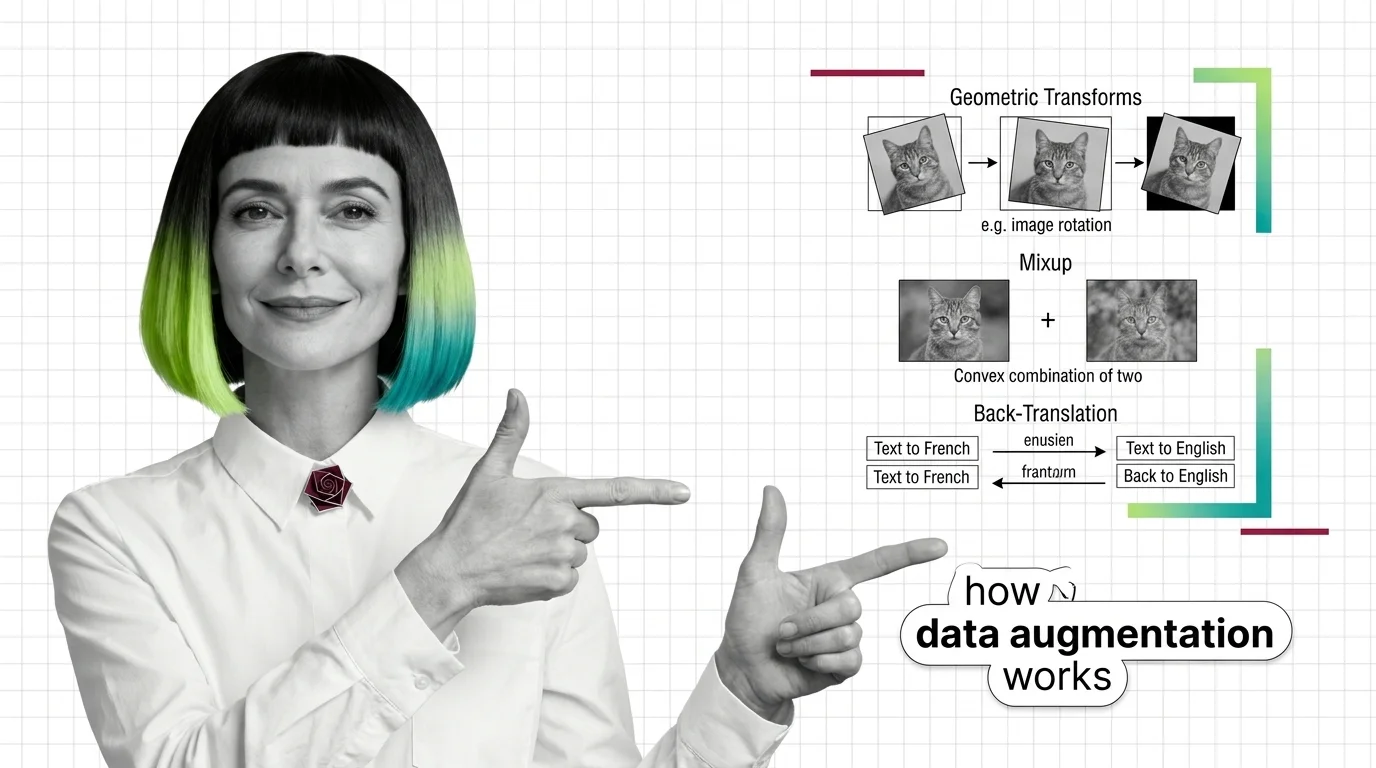
Geometric Transforms, Mixup, and Back-Translation: How Core Augmentation Methods Work
Data augmentation transforms existing examples — flips, mixup blends, CutMix patches, back-translation — to teach models …
Inter-Annotator Agreement, Annotation Guidelines, and the Building Blocks of a Labeling Project
Inter-annotator agreement measures label quality beyond chance. Cohen's kappa corrects raw match rates, exposing …
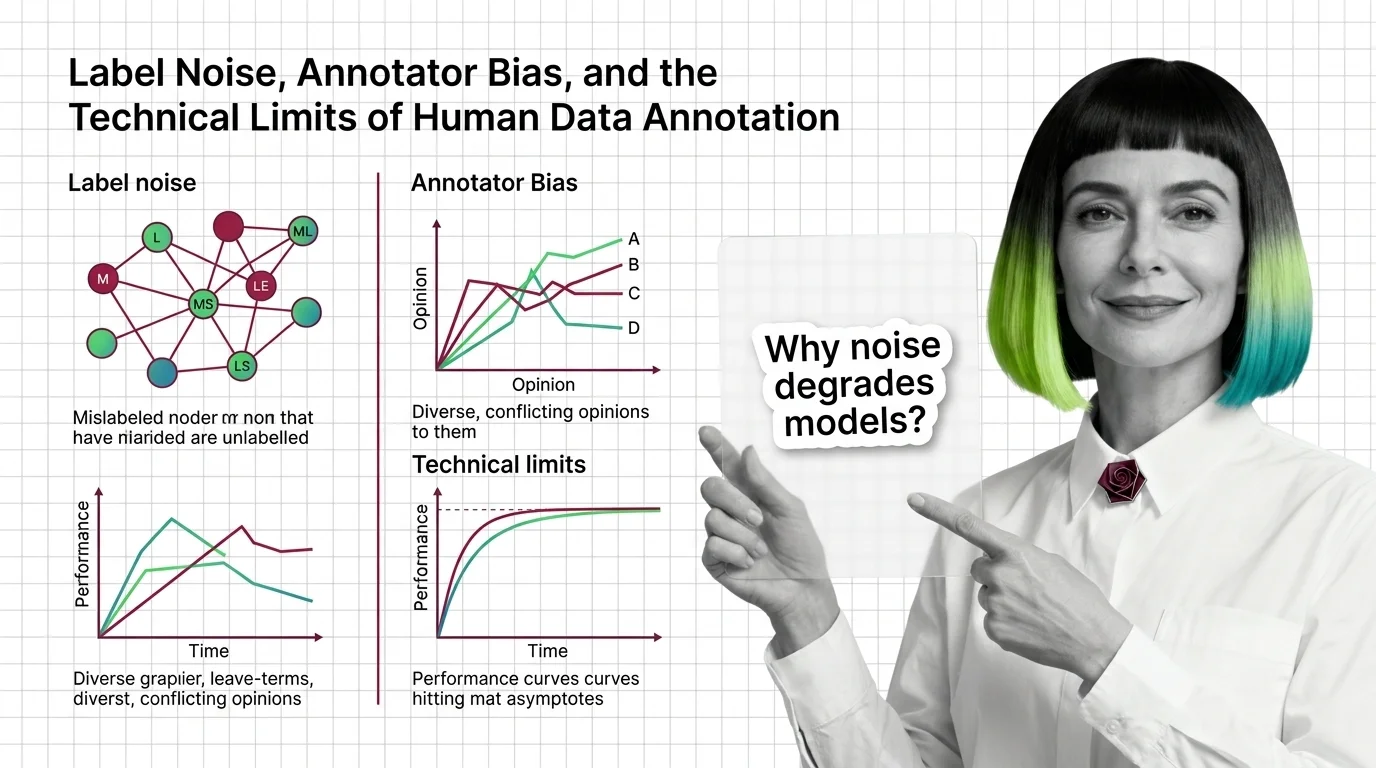
Label Noise, Annotator Bias, and the Technical Limits of Human Data Annotation
Label noise averages an estimated 3.4% across major ML test sets, distorting supervised model accuracy and even flipping …
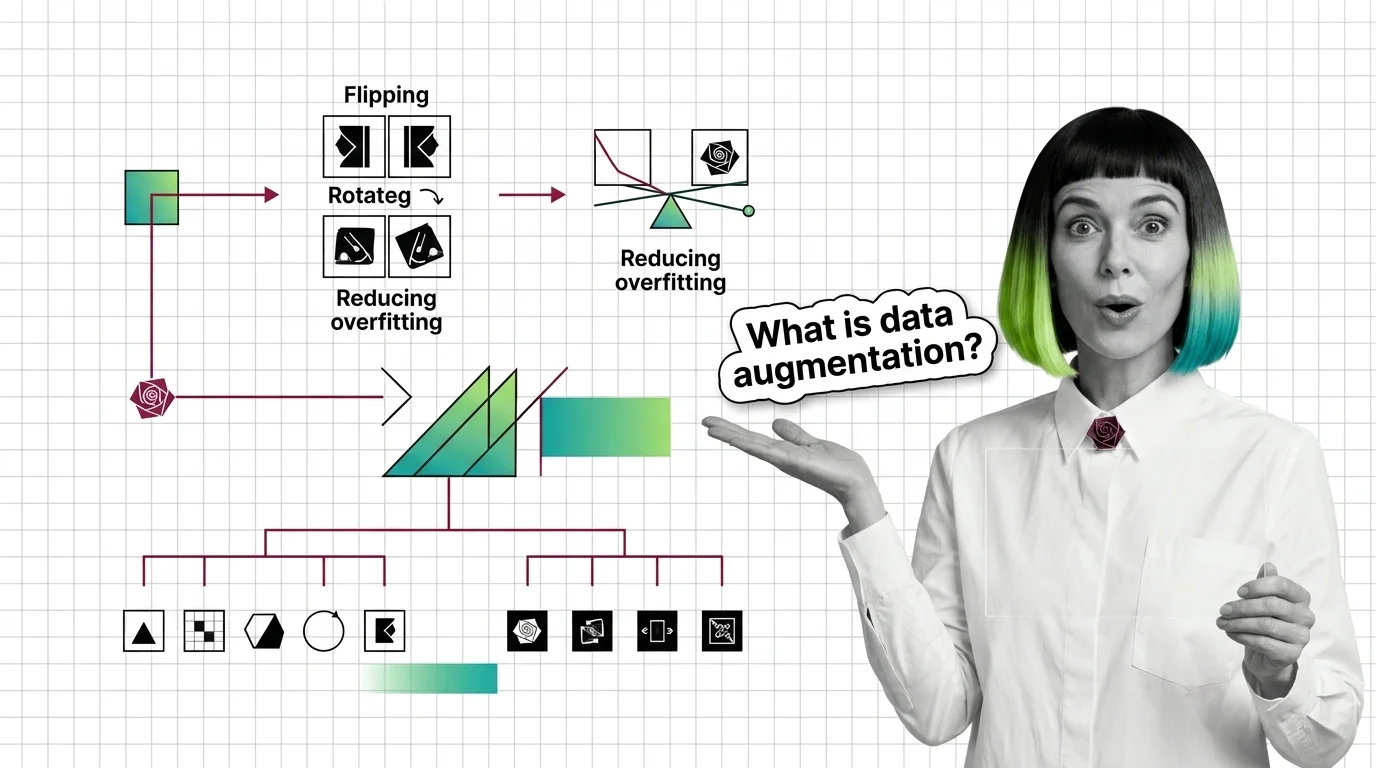
What Is Data Augmentation and How Transforming Samples Expands Training Data
Data augmentation expands training data by transforming existing samples—rotations, mixup, masking—to reduce overfitting …
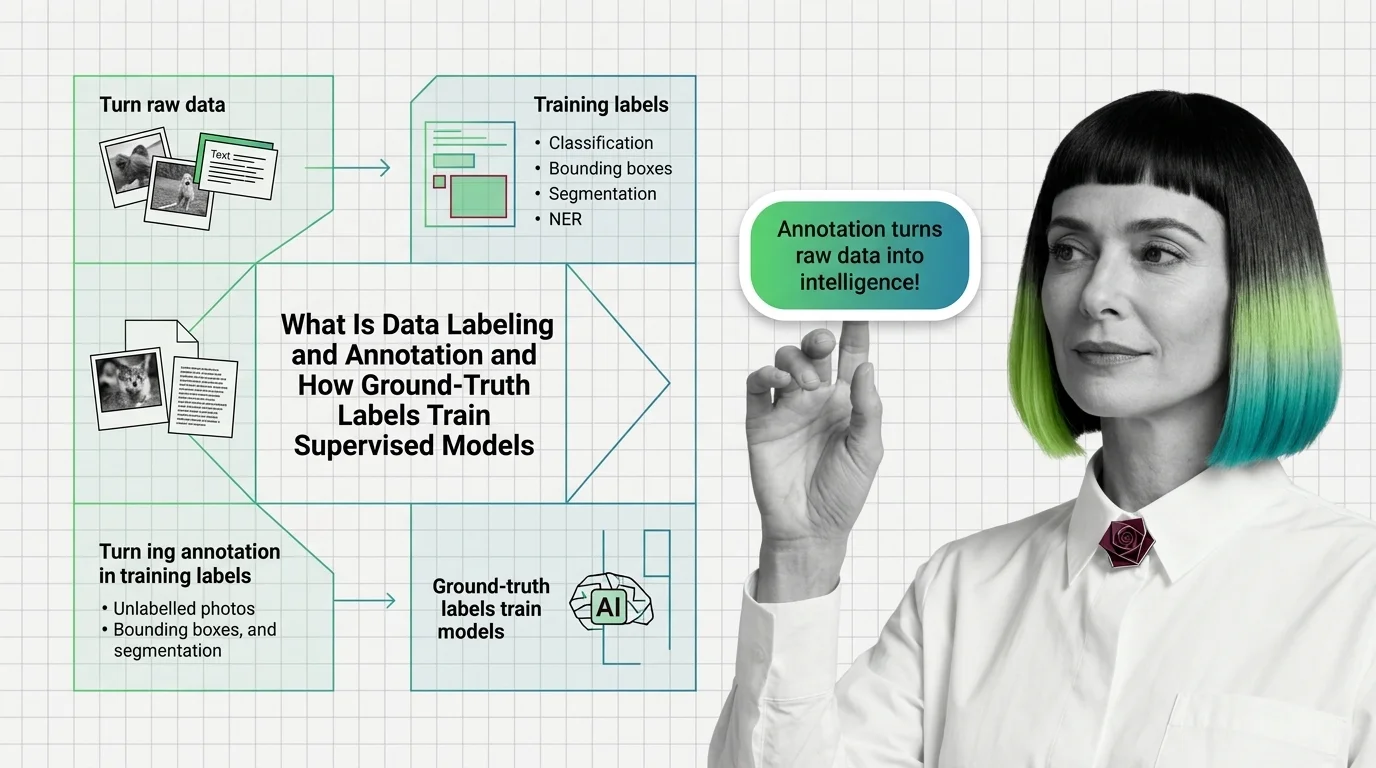
What Is Data Labeling and Annotation, and How Ground-Truth Labels Train Supervised Models
Data labeling assigns ground-truth labels to raw data so supervised models learn a mapping. Label noise propagates into …
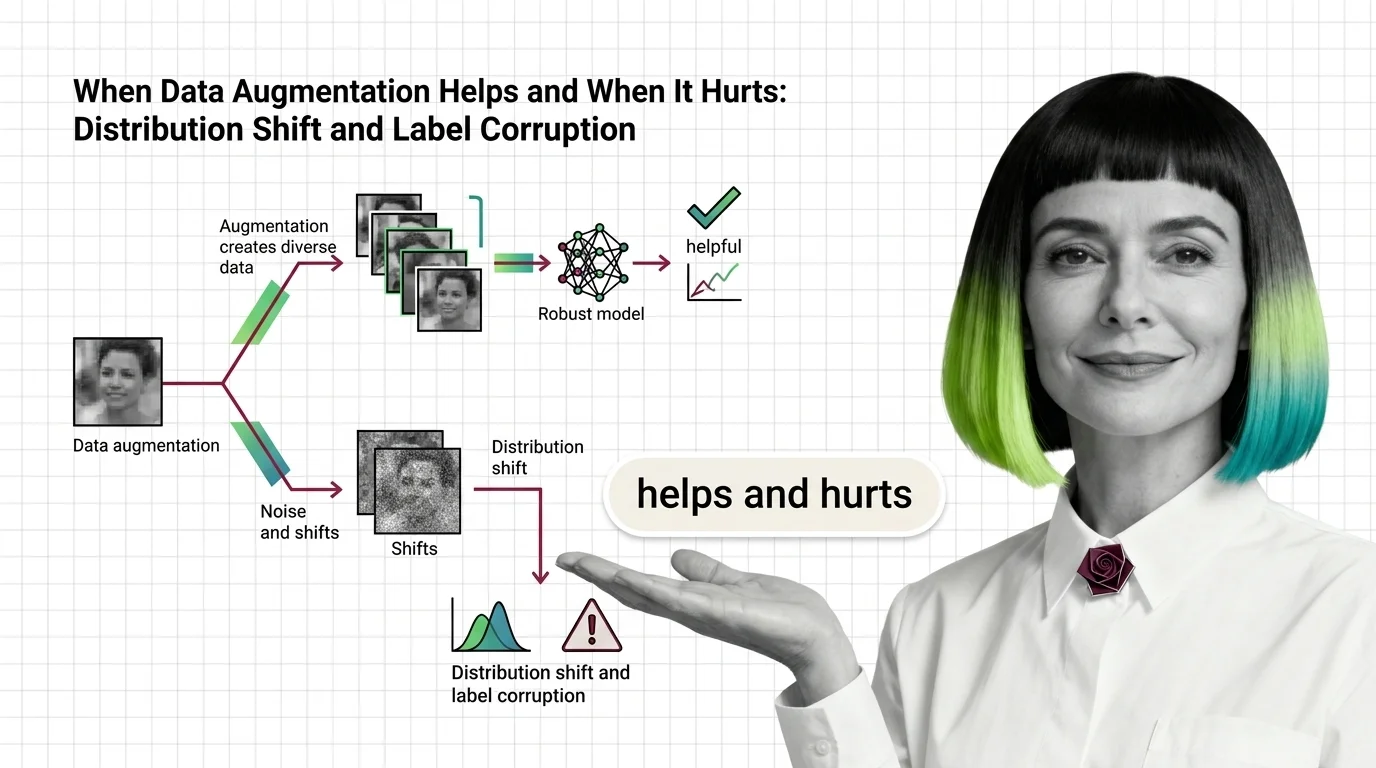
When Data Augmentation Helps and When It Hurts: Distribution Shift and Label Corruption
Data augmentation helps until synthetic samples drift from real data or break the input-label mapping, creating …
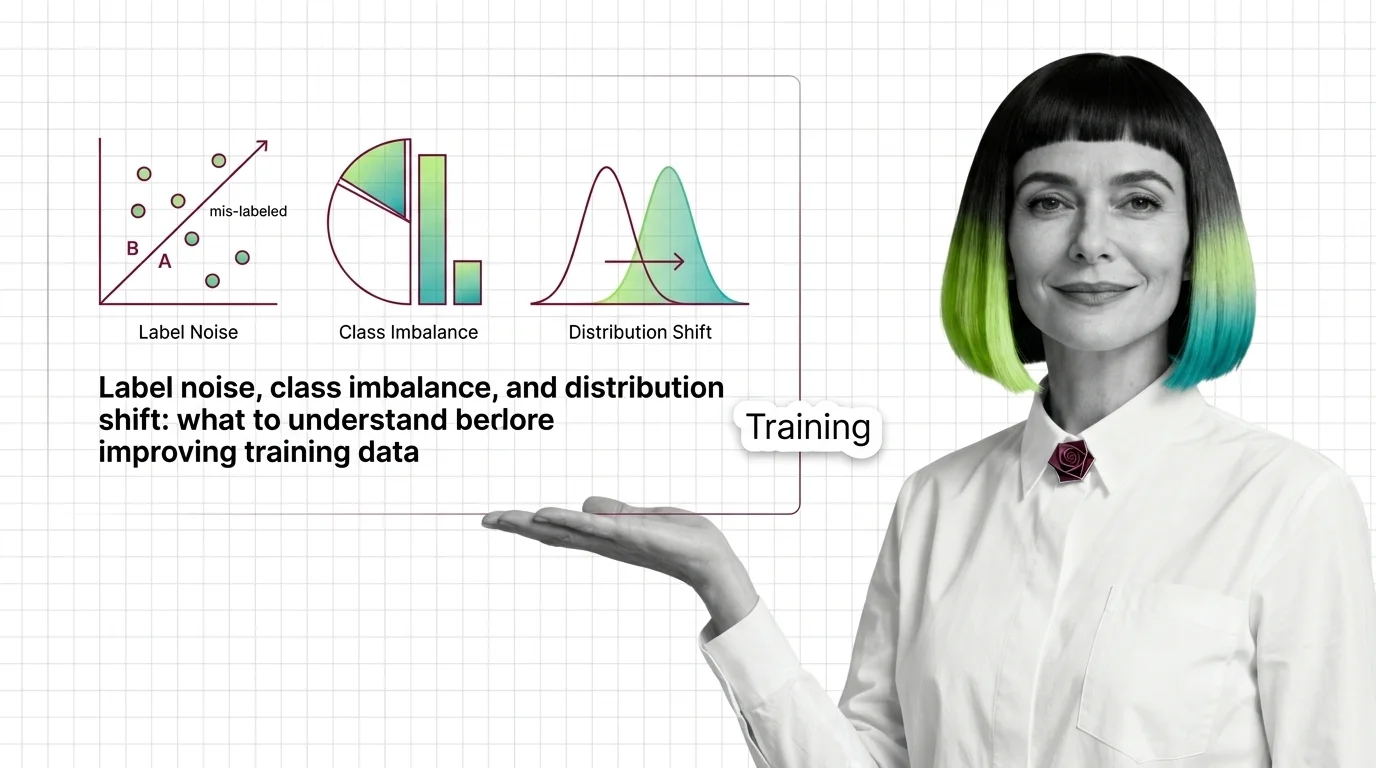
Label Noise, Class Imbalance, and Distribution Shift: What to Know Before Fixing Training Data
Label noise, class imbalance, and distribution shift degrade models more than architecture choices. Understand all three …
What AI Technical-Debt Tools Actually Measure — and Where the Numbers Break
AI technical-debt tools measure proxies like complexity and code churn, not debt itself. Vendor false-positive rates …
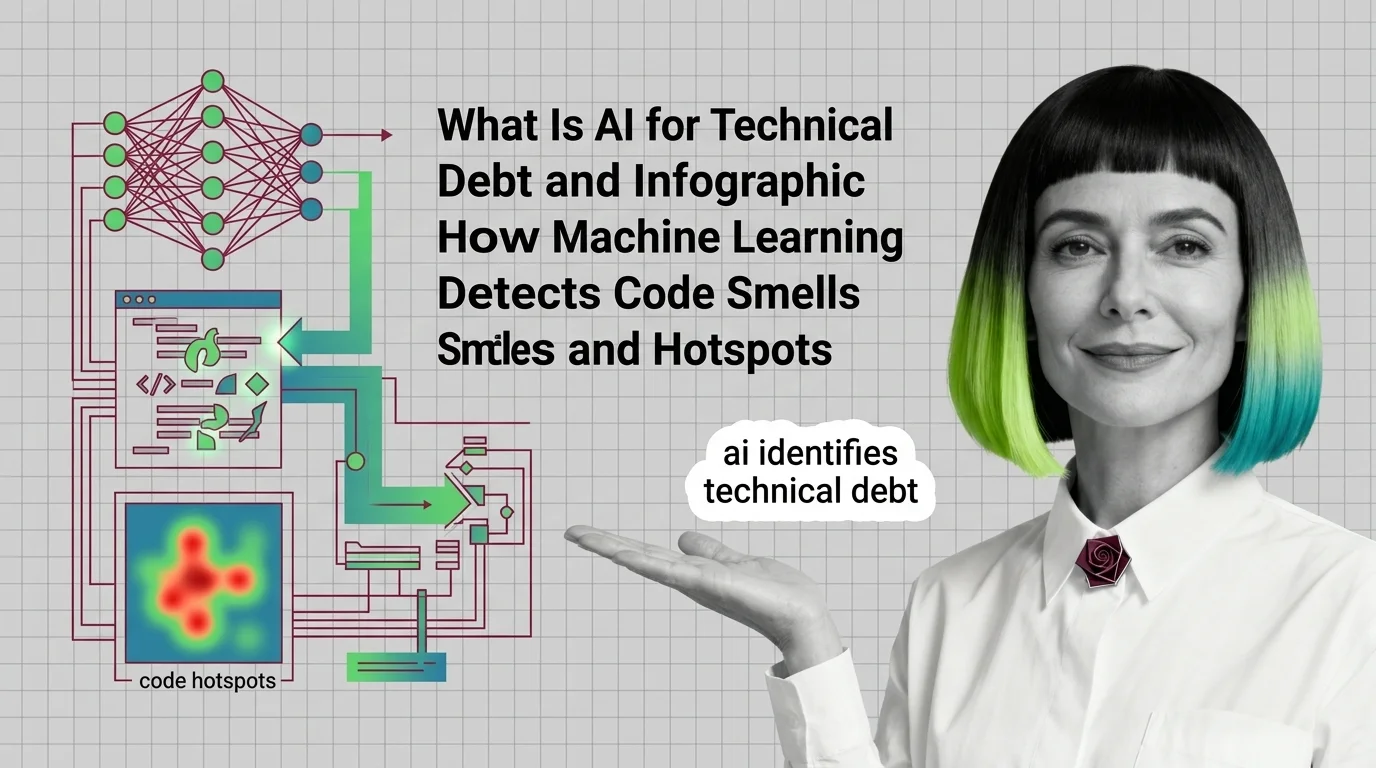
What Is AI for Technical Debt and How Machine Learning Detects Code Smells and Hotspots
AI for technical debt combines ML and behavioral code analysis to find decay hotspots — a small fraction of files drives …
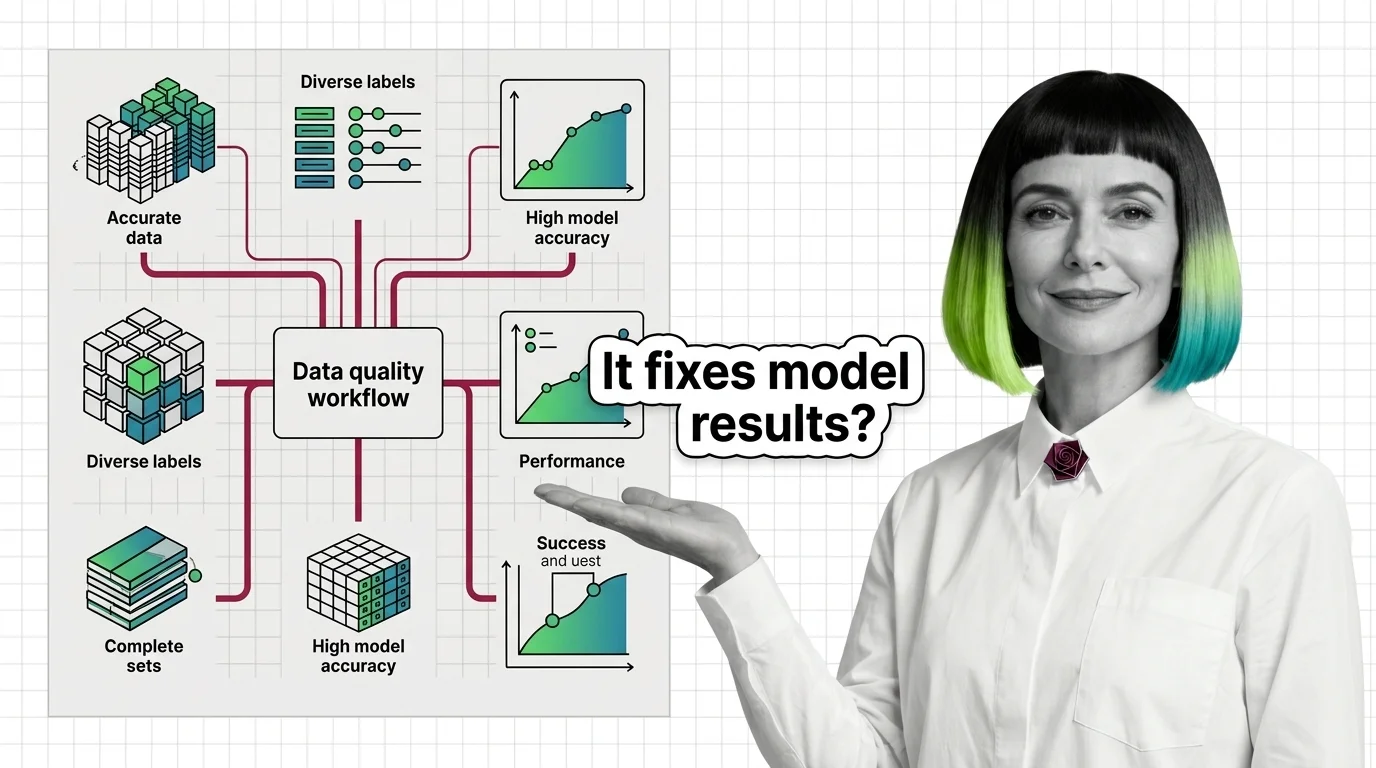
What Is Training Data Quality and How It Determines Model Performance
Training data quality is the systematic engineering of label correctness, deduplication, and provenance — it sets the …
Why Perfectly Clean Data Is Impossible: The Technical Limits of Data Curation at Scale
Cleaning training data at scale hits hard limits: label errors average 3.4% across top ML datasets, and automated …
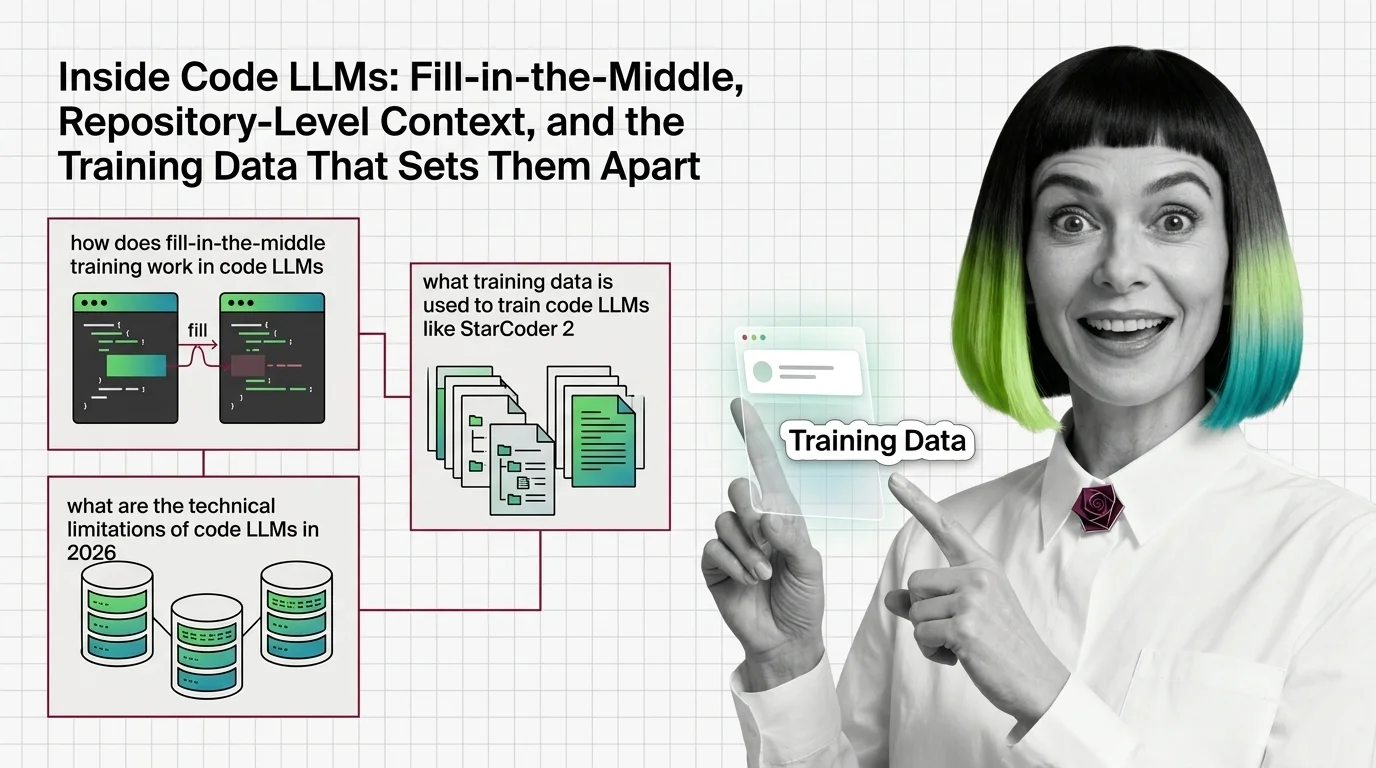
Inside Code LLMs: Fill-in-the-Middle and the Training Data Behind Them
Fill-in-the-middle reorders code into prefix-suffix-middle triplets, letting code LLMs like StarCoder 2 complete code …
Prerequisites and Technical Limits of AI in CI/CD: DevOps Foundations to Flaky-Test False Positives
AI in CI/CD requires a deterministic pipeline-as-code foundation first. Its main failure mode: misclassifying real …
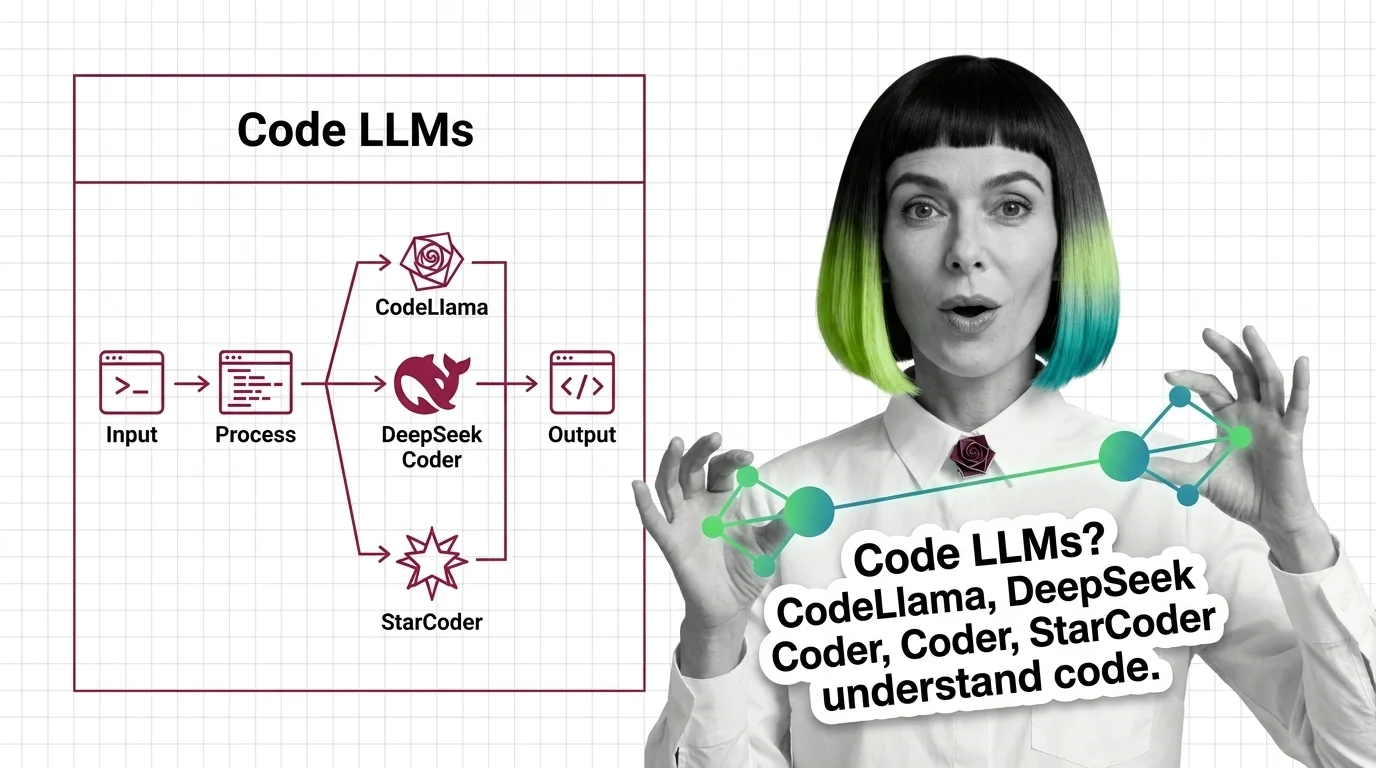
What Are Code LLMs and How CodeLlama, DeepSeek Coder, and StarCoder Understand Source Code
Code LLMs are transformers trained on billions of code tokens, not prose. Fill-in-the-Middle training lets them complete …
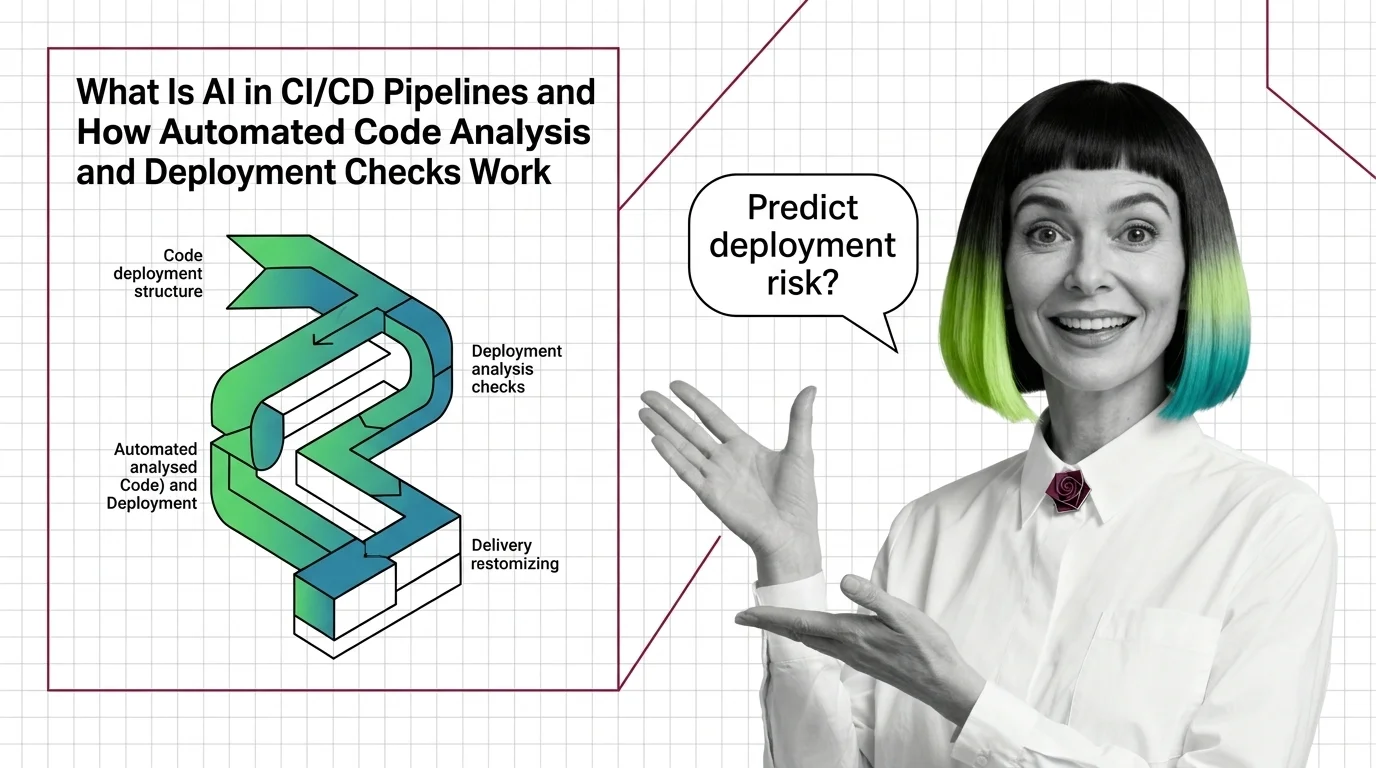
What Is AI in CI/CD Pipelines and How Automated Code Analysis and Deployment Checks Work
AI in CI/CD pipelines uses ML trained on build history to prioritize tests, predict build failures, and score deployment …
Context Window Collapse, Tool-Call Loops, and the Hard Technical Limits of Coding Agents in 2026
Coding agents in 2026 stall on long contexts and tool-call loops. Even top SWE-bench scorers fail one in five tasks …
Prerequisites for Agentic Coding: Tool Use, Scaffolding, and the Plan-Execute-Verify Loop
Agentic coding needs three layers: tool calls, scaffolding, and a plan-execute-verify loop. Scaffolding shifts SWE-bench …
Prerequisites for Vibe Coding and the Technical Limits That Break the Illusion
Vibe coding accepts AI-generated code without reading it. Industry analyses report most vibe-coded apps ship with …
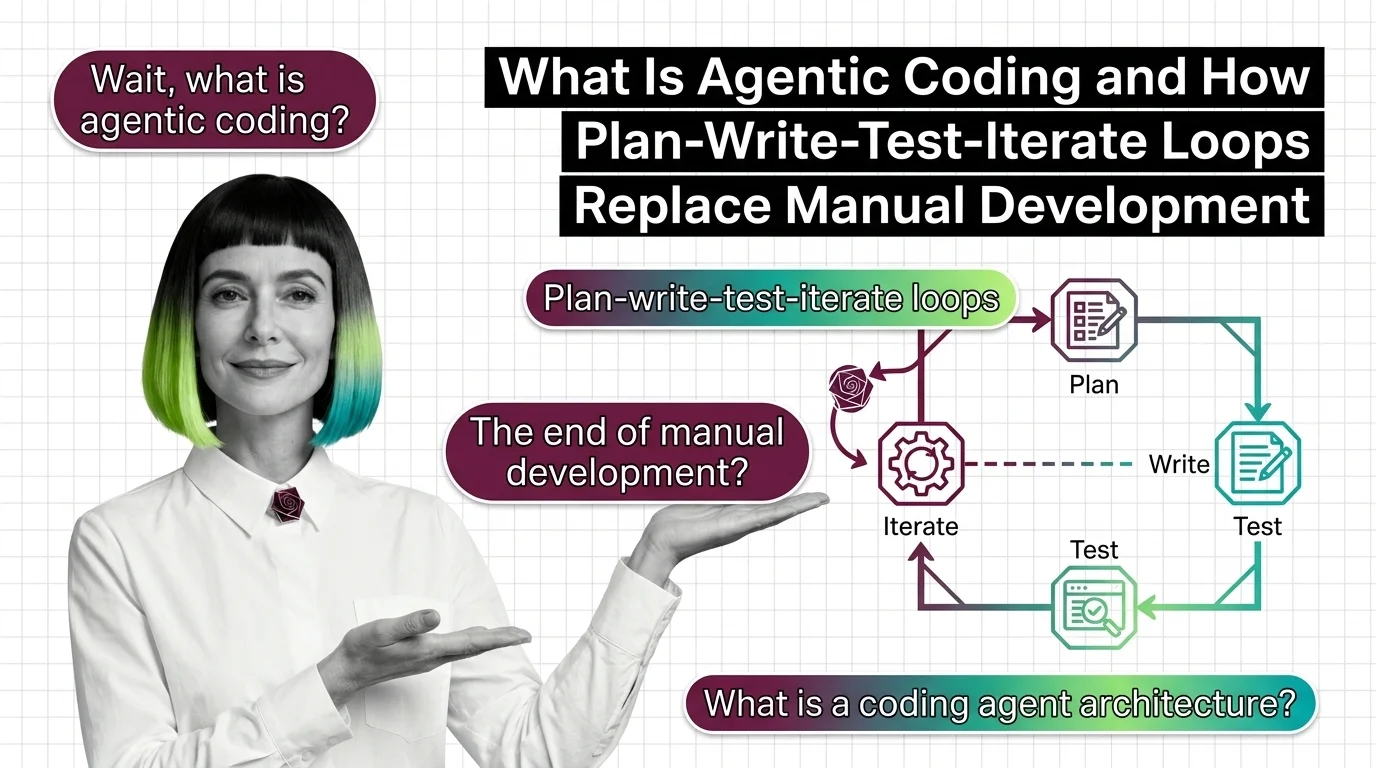
What Is Agentic Coding and How Plan-Write-Test-Iterate Loops Replace Manual Development
Agentic coding is a loop where an LLM plans, writes, tests, and revises code using real dev tools. Claude Code hits …
What Is Vibe Coding and How Natural-Language Development Replaces Manual Code Editing
Vibe coding is building software by describing intent to an LLM and accepting the generated code unread — coined by …

The Technical Limits of MCP: Missing Authentication, Tool Sprawl, and Stateful Connections
The Model Context Protocol makes authentication optional by design — only ~8.5% of MCP servers use OAuth, while tool …

What Is the Model Context Protocol and How It Connects AI Assistants to External Tools
The Model Context Protocol (MCP) is an open standard from Anthropic that connects AI applications to external tools, …

AI Code Migration: AST Parsing, Test Coverage, and the Problem of Silent Regressions
AI code migration transforms syntax via AST tools but can't guarantee behavior. A Copilot agent hit 100% migration …

MCP Architecture Explained: Hosts, Clients, Servers, and the Tools-Resources-Prompts Primitives
The Model Context Protocol links AI apps to external tools through three roles — host, client, server — over JSON-RPC, …

What Is AI Code Migration and How LLM Agents Translate Languages and Modernize Legacy Codebases
AI code migration uses LLM agents to translate legacy COBOL and PL/SQL into Java or Python, pairing deterministic AST …
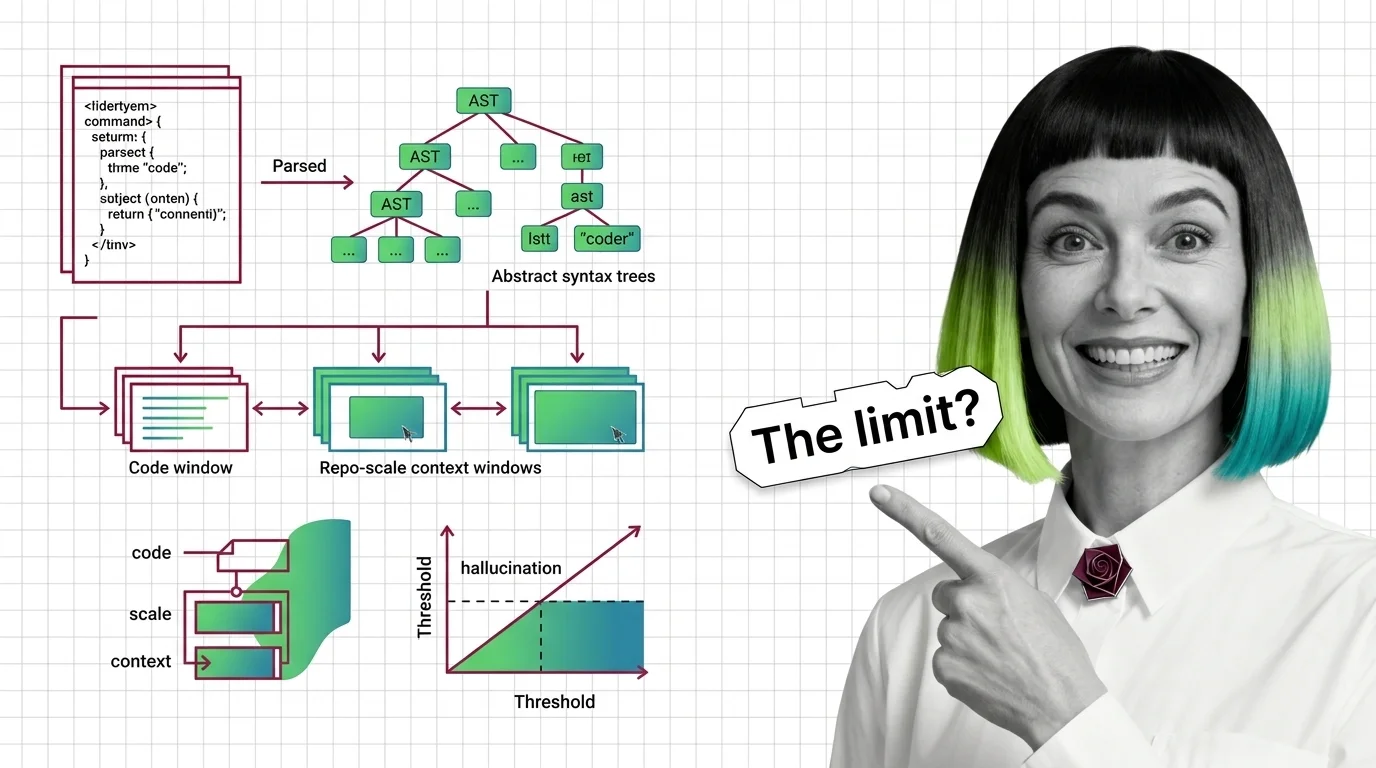
Prerequisites for AI Documentation Generation: From AST Parsing to Repo-Scale Context Windows and Hallucination Limits
AI documentation generators don't read code — they parse ASTs, embed chunks, and retrieve context. Open-source models …
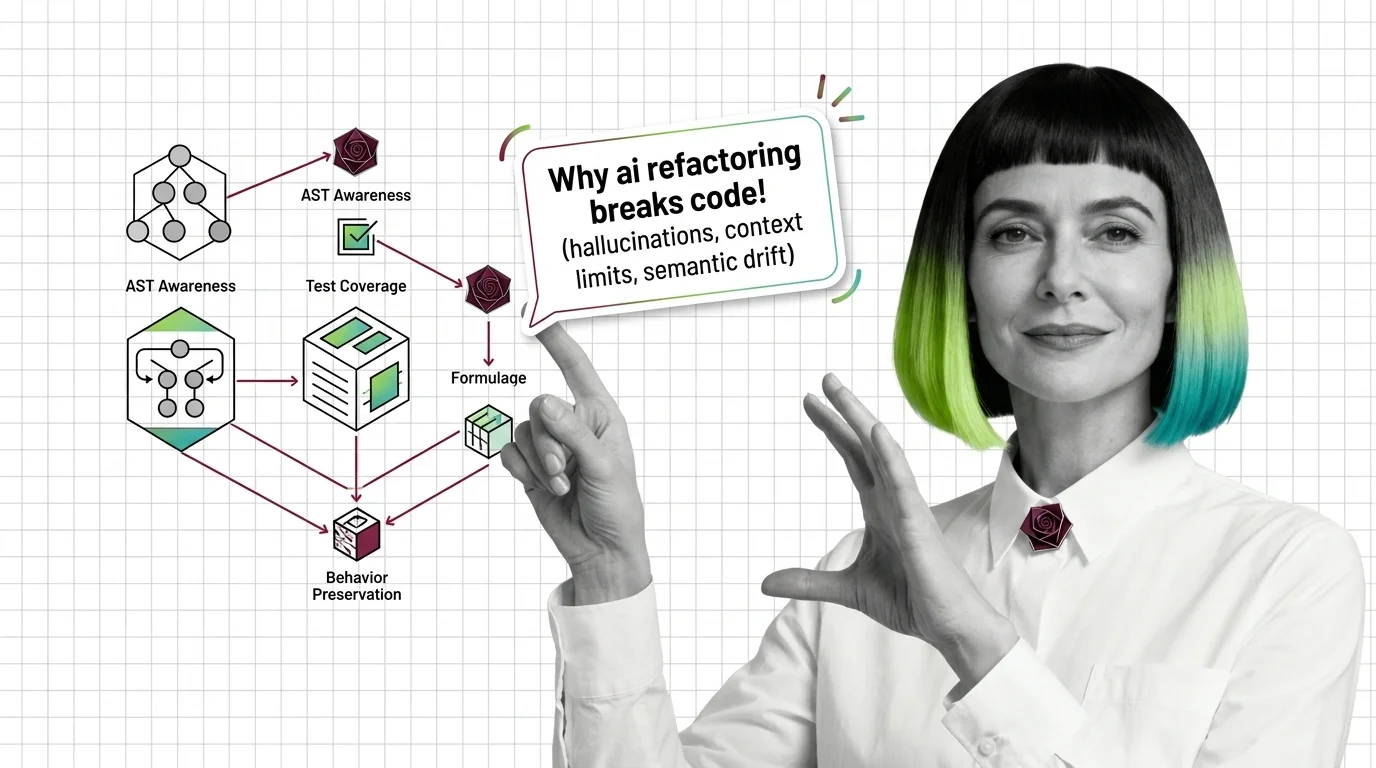
Prerequisites for AI-Assisted Refactoring: From AST Awareness to Test Coverage and Behavior Preservation
AI-assisted refactoring needs four prerequisites: behavior preservation, AST awareness, test coverage, and mitigation of …
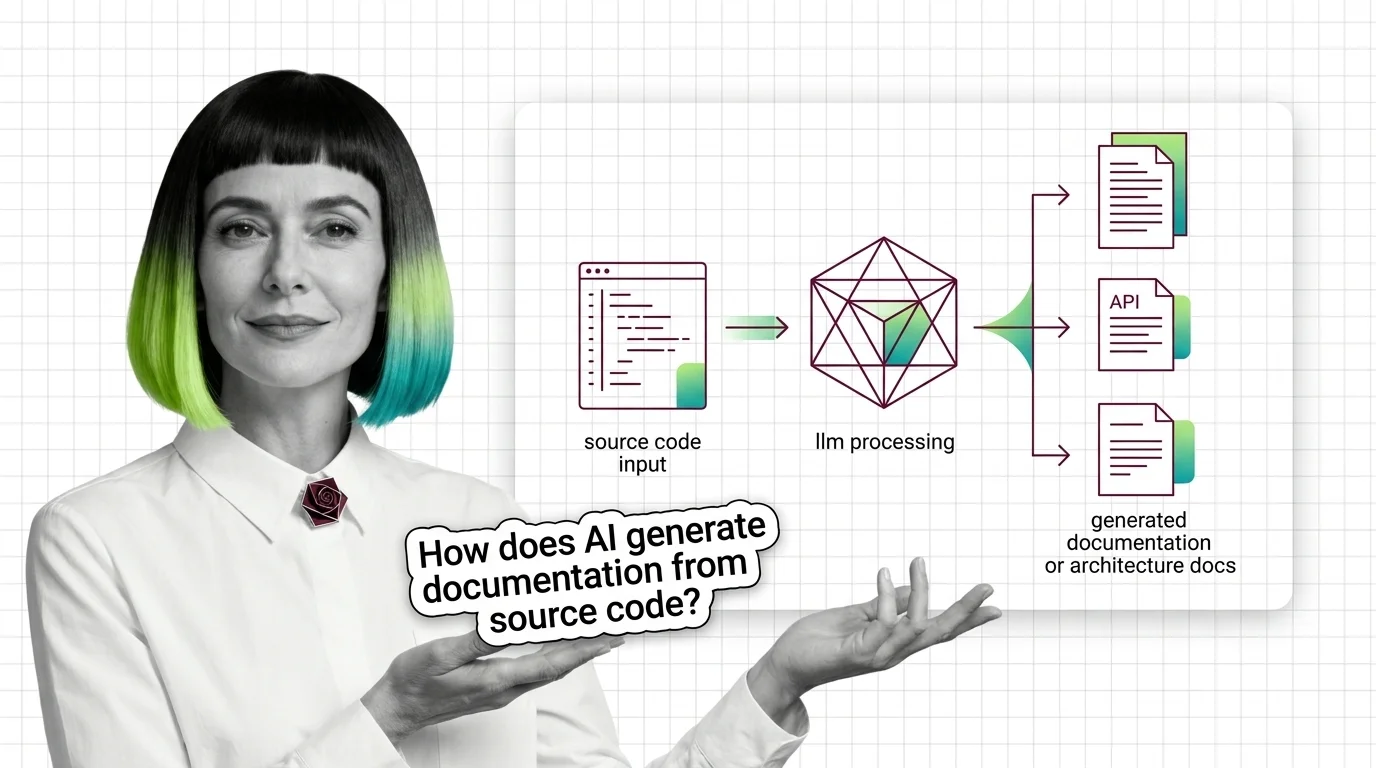
What Is AI Documentation Generation? How LLMs Turn Code Into Docstrings and Architecture Docs
AI documentation generation uses LLMs to produce docstrings, API references, and architecture docs by traversing code …
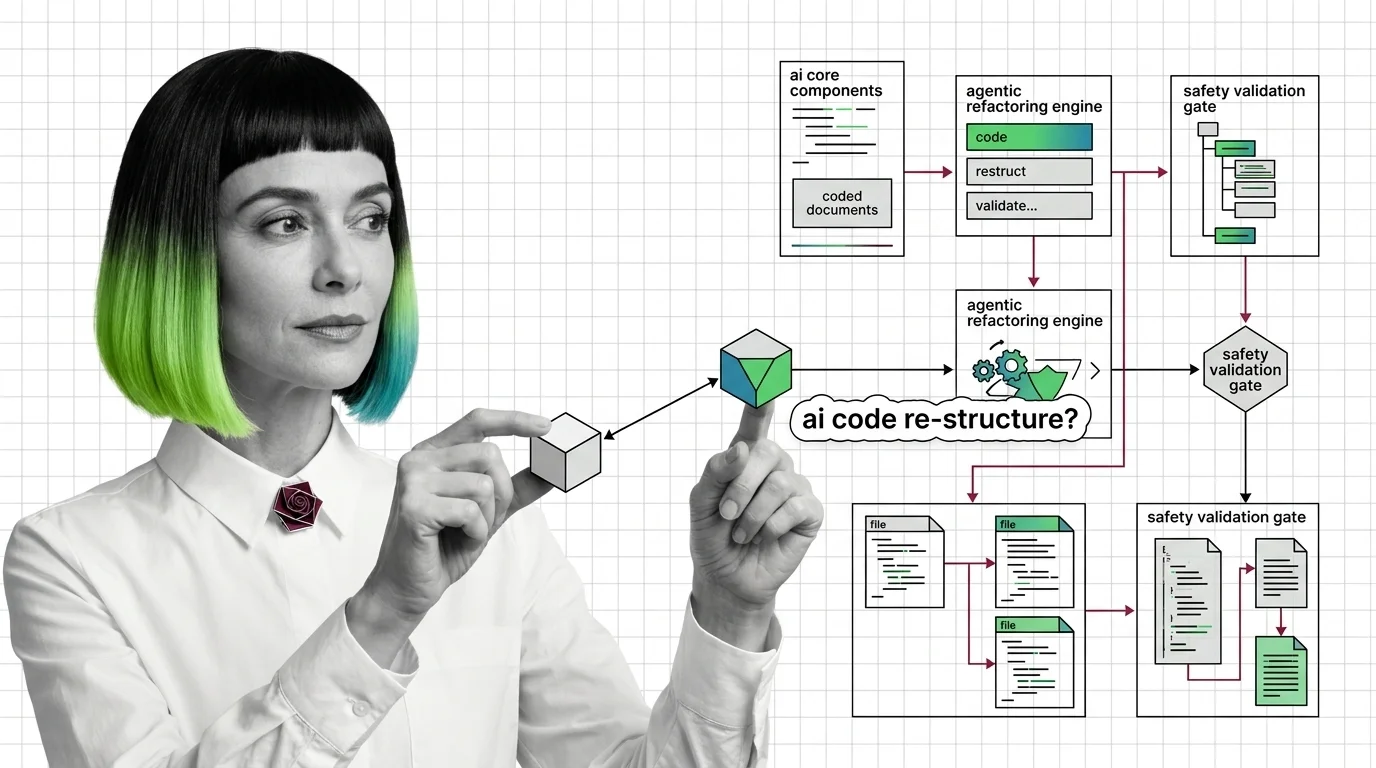
What Is AI-Assisted Refactoring and How Agentic Tools Restructure Code Without Breaking It
AI-assisted refactoring parses code into a syntax tree, plans behavior-preserving edits, and verifies them with tests — …
Prerequisites for AI-Assisted Debugging: Stack Traces, Context Windows, and Why Models Still Hallucinate Fixes
AI debuggers sample probable fixes from a finite context window. Even top 2026 models invent plausible symbols, the …
From Coverage Metrics to Mutation Testing: What You Need to Know Before Using AI Test Generators
Coverage measures whether tests run code. Mutation testing measures whether assertions catch bugs. AI test generators …
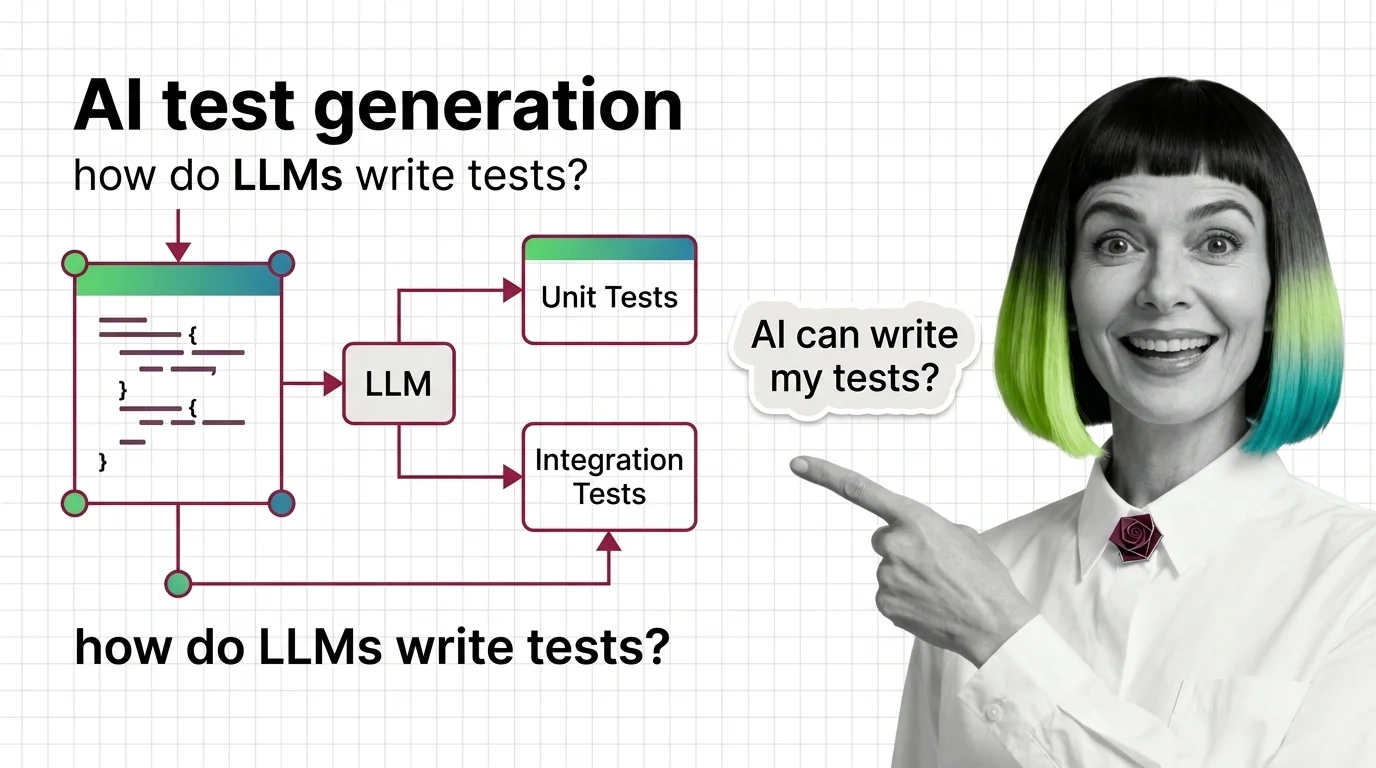
What Is AI Test Generation and How LLMs Write Unit and Integration Tests from Code
AI test generation uses LLMs to write unit tests from source code. A two-phase pipeline produces candidates, then …
What Is AI-Assisted Debugging and How LLMs Analyze Stack Traces to Find Bugs
AI-assisted debugging uses LLMs to parse stack traces, generate fix hypotheses, and validate them against runtime …
What Is AI Code Review and How LLM-Powered PR Reviewers Catch Bugs Before Humans
AI code review uses LLM agents to inspect pull requests for bugs, security flaws, and architectural drift before human …
From Context Windows to Speculative Decoding: Prerequisites and Technical Limits of Inline Code Completion
Inline AI code completion rests on four prerequisites: tokenization, context windows, FIM, and speculative decoding. …
Prerequisites for AI Code Review: RAG, Static Analysis, and the Hard Limits of LLM Bug Detection
AI code review combines retrieval-augmented context, static analysis, and LLM triage. Without grounding, models …
What Is AI Code Completion and How LLM-Powered Inline Suggestions Predict the Next Token
AI code completion uses Fill-in-the-Middle prompting on small, latency-optimized LLMs that score tokens against code …
What Are Browser and Computer Use Agents and How Screenshot-Grounded AI Controls Your Desktop
Computer use agents take screenshots, locate UI elements visually, and emit click coordinates. GPT-5.4 hits 75% on …
DOM Trees vs Screenshots: Prerequisites and Technical Limits of Computer Use Agents in 2026
Computer use agents read screens two ways: DOM accessibility trees or raw pixels. The grounding strategy decides where …
From RAG to Agentic RAG: Prerequisites and Technical Limits of Retrieval-Augmented Agents
Retrieval-augmented agents wrap RAG primitives as tools inside a reasoning loop. Latency stacks, cost climbs, …
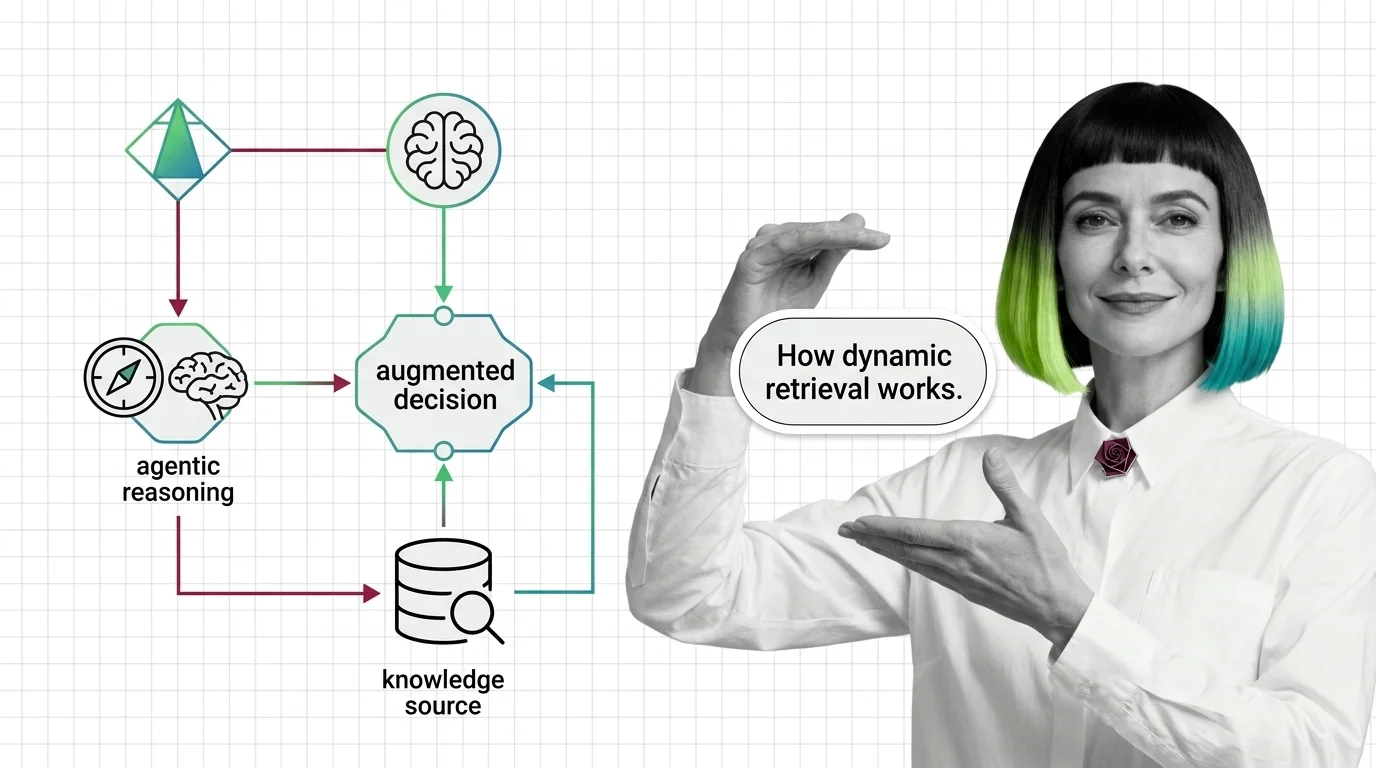
What Are Retrieval-Augmented Agents and How They Combine Agentic Reasoning with Dynamic Retrieval
Retrieval-augmented agents let the LLM decide when, what, and how often to retrieve — turning RAG from a fixed pipeline …
Cold Starts, Flaky Tests, and Context Blowup: The Technical Limits of Code Execution Agents in 2026
Code execution agents fail at three limits in 2026: sandbox cold-start vs isolation, flaky benchmark tests, and context …
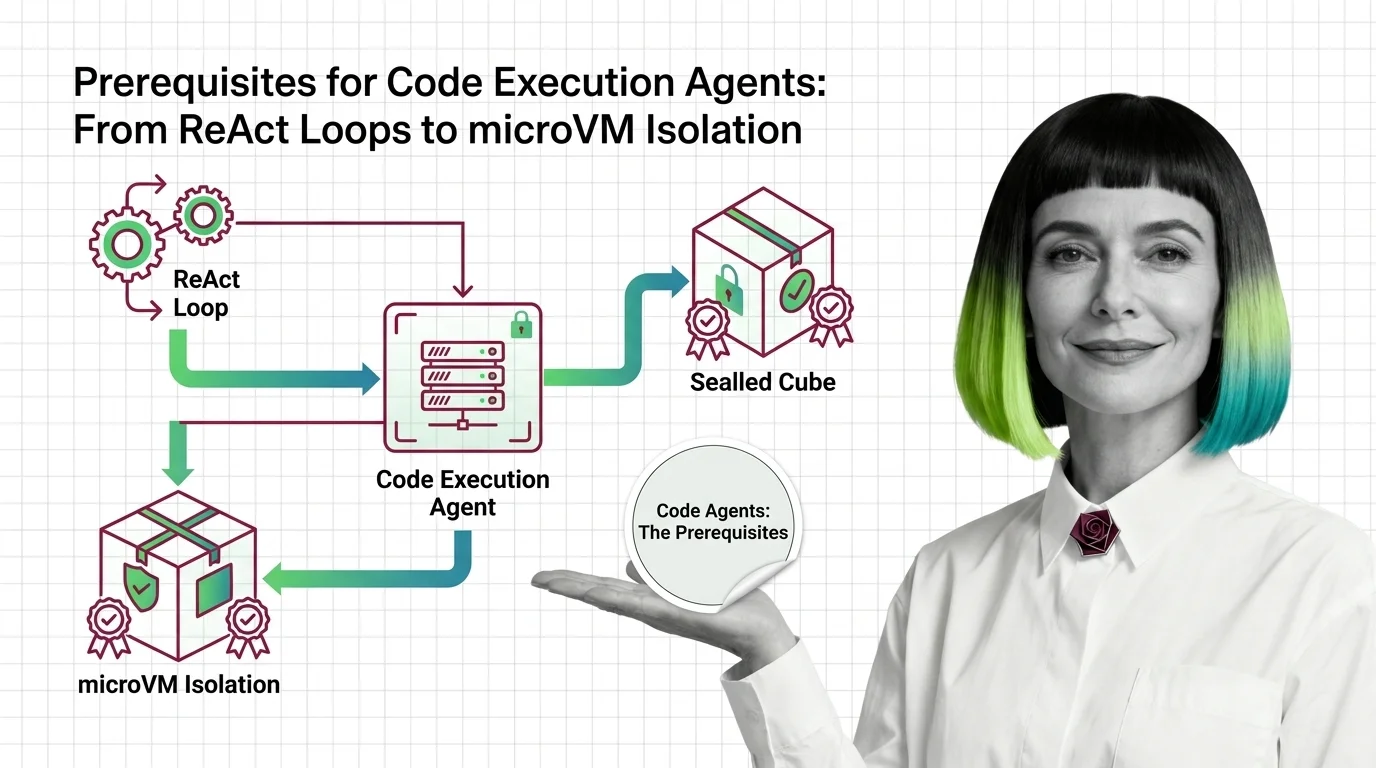
Prerequisites for Code Execution Agents: From ReAct Loops to microVM Isolation
Building a code execution agent requires three layers: a ReAct-style reasoning loop, a sandbox runtime, and microVM or …
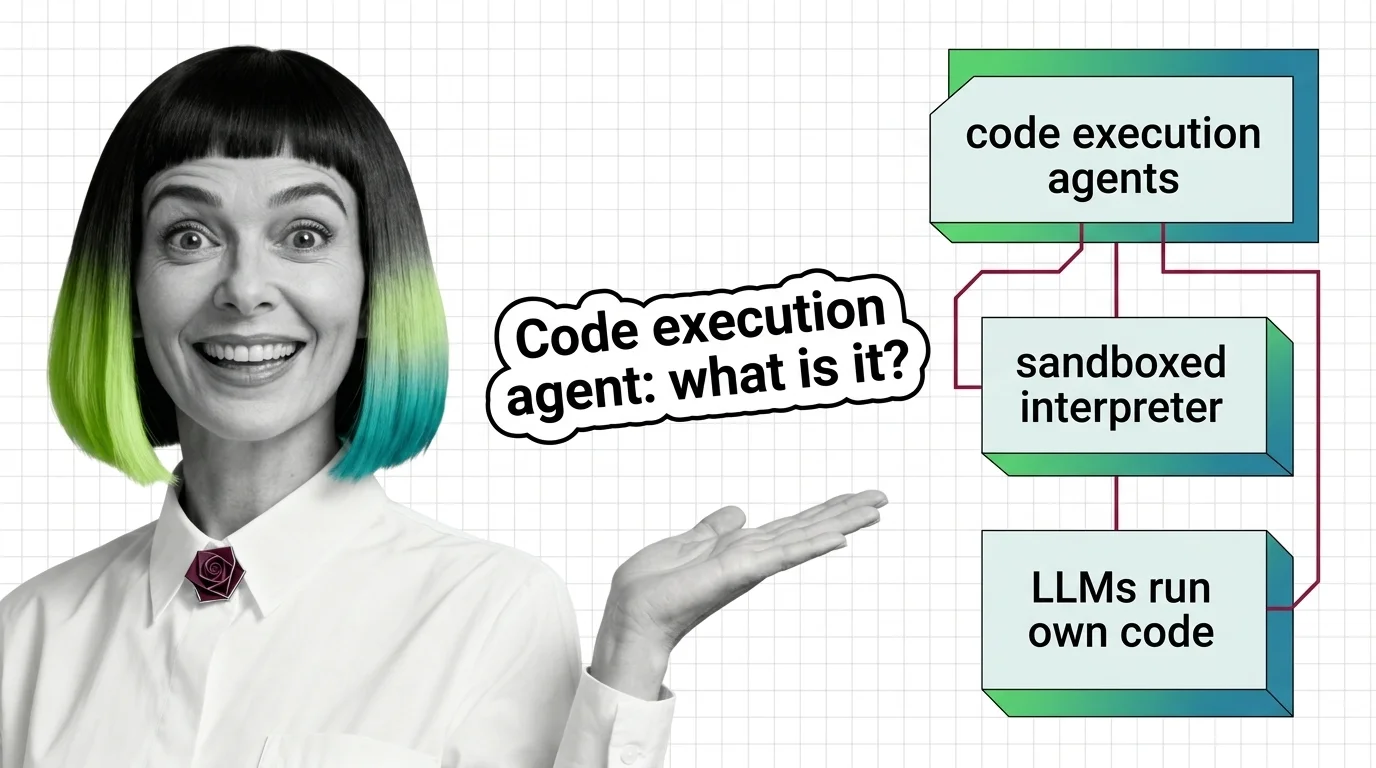
What Are Code Execution Agents and How Sandboxed Interpreters Let LLMs Run Their Own Code
Code execution agents are LLMs that write and run Python inside sandboxed containers. CodeAct showed up to 20% higher …
Agent Error Handling: How Agents Recover From Tool and LLM Failures
Agent error handling turns brittle LLM loops into resilient systems. Learn how guardrails, retries, and checkpoints …
What Is Agent Observability? Traces, Spans, and Token Attribution
Agent observability records every step an AI agent takes. Learn how traces, spans, and token attribution reveal what …
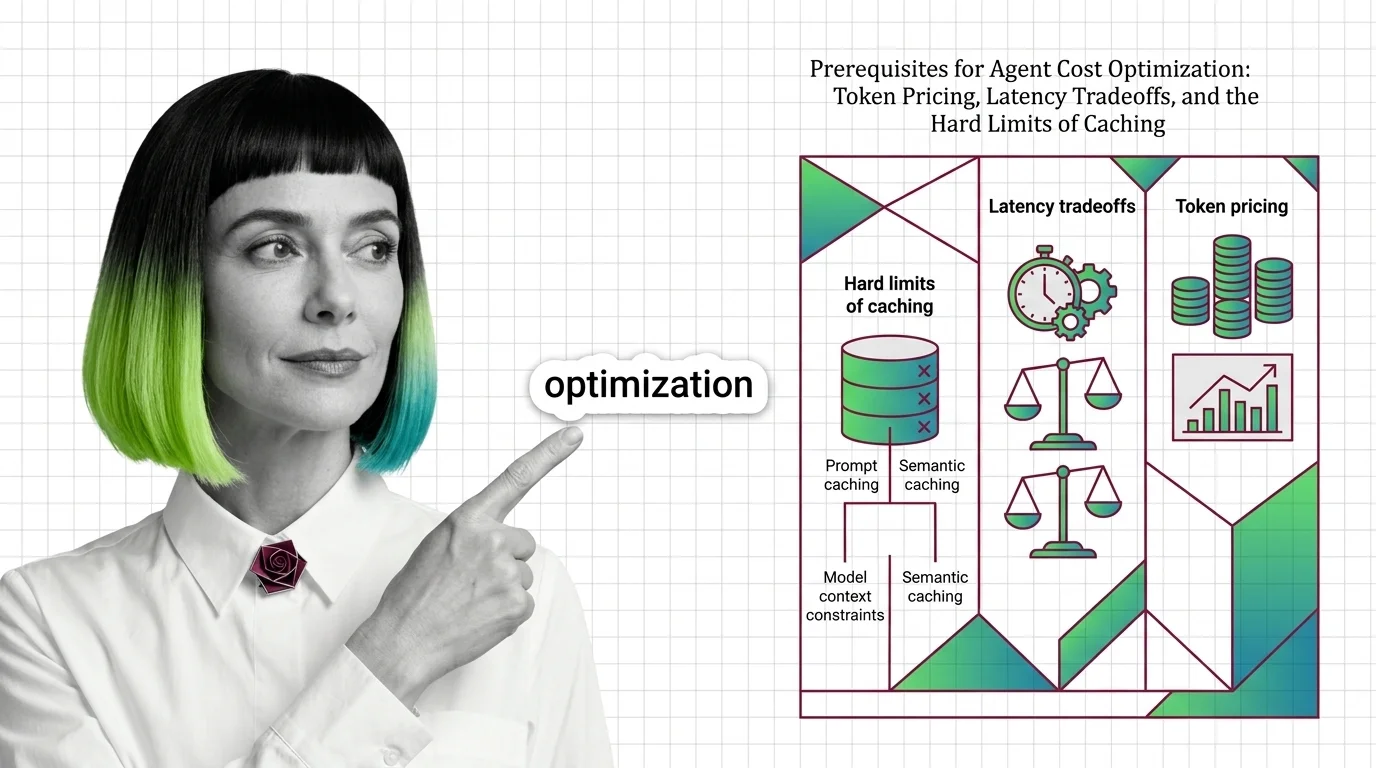
Agent Cost Optimization Prerequisites: Pricing, Latency, Caching Limits
Before optimizing agent costs, understand token pricing asymmetry, prefill vs decode latency, and why prompt and …
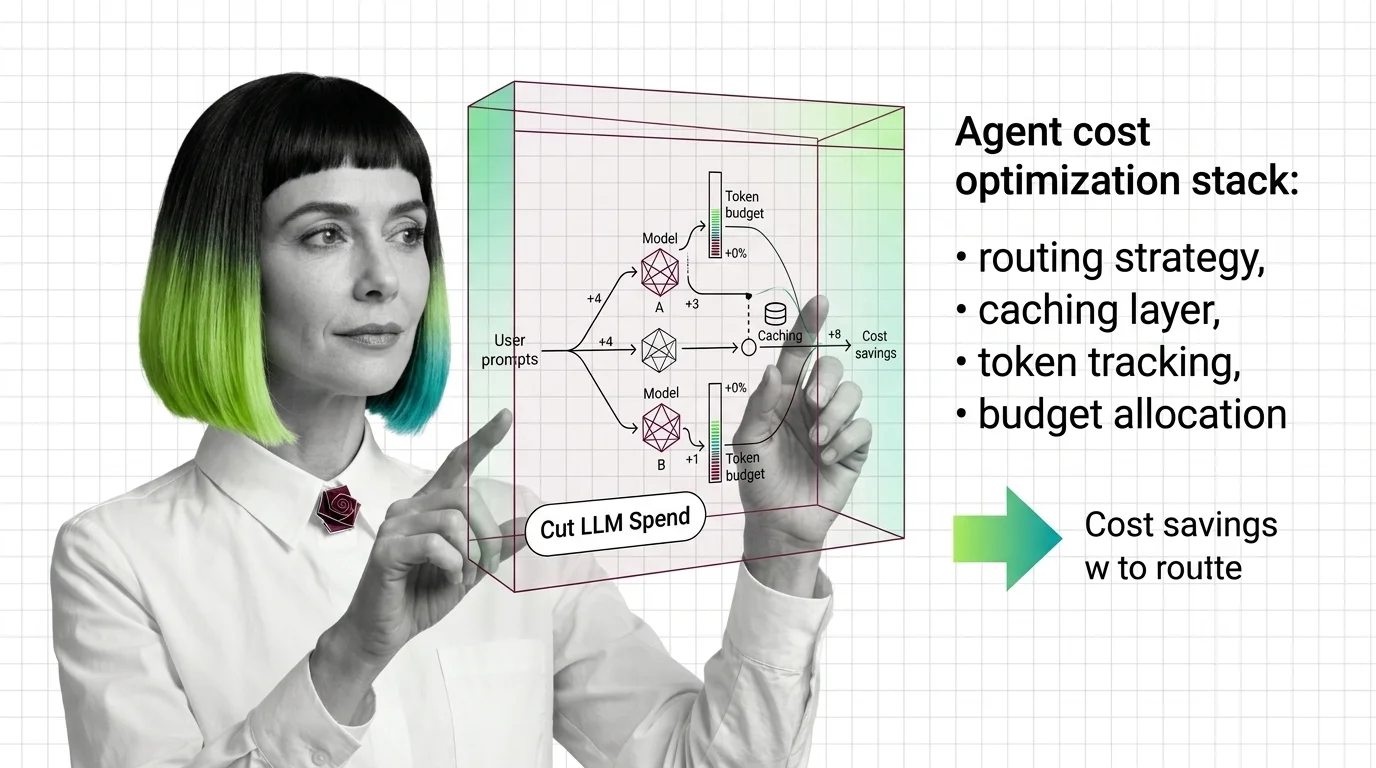
Agent Cost Optimization: Routing, Caching, and Token Budgets for LLMs
Agent cost optimization routes requests to the right model, caches reusable computation, and caps runaway loops before …
OpenTelemetry GenAI: Prerequisites and Limits of Agent Tracing
OpenTelemetry GenAI semconv is still in Development. What you need to know about tracing prerequisites and hard limits …
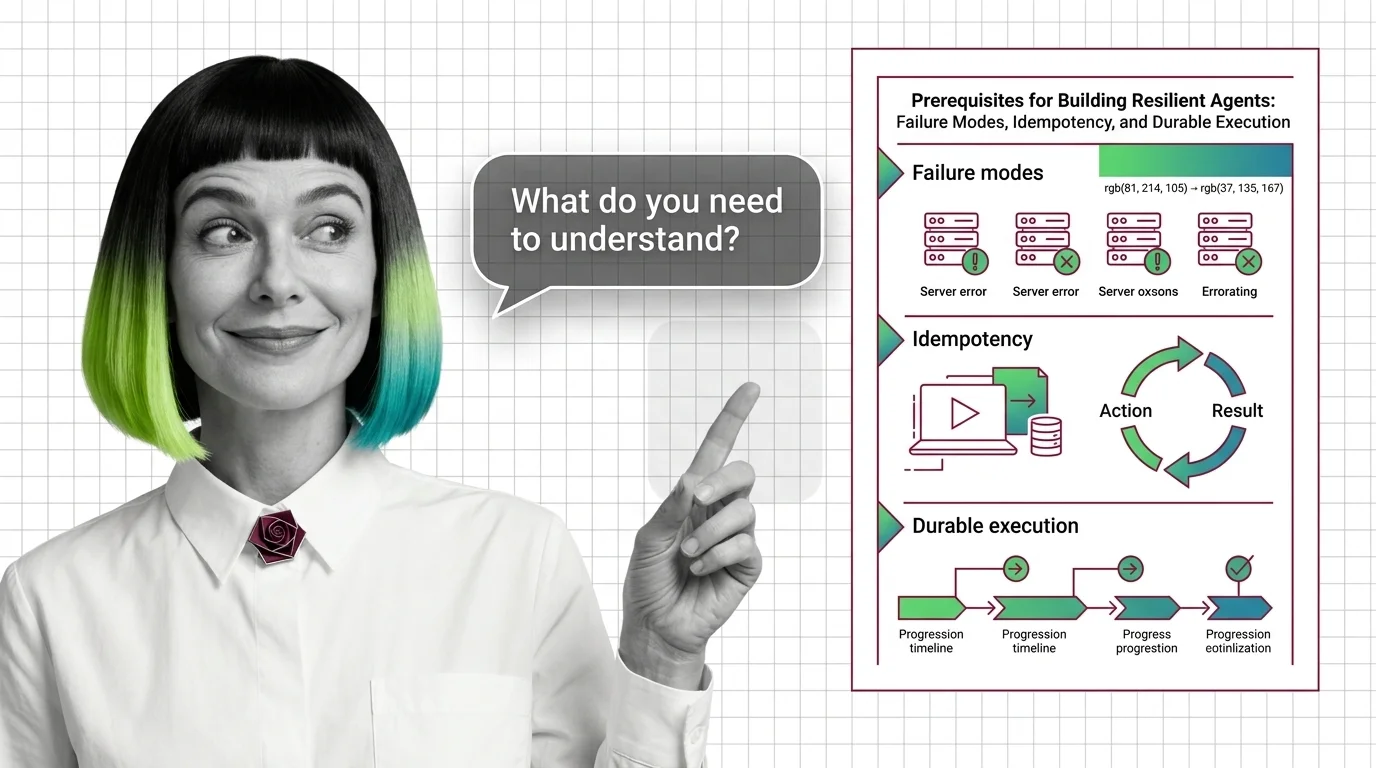
Resilient AI Agents: Failure Modes, Idempotency, Durable Execution
Reliable AI agents need three foundations: a failure-mode taxonomy, idempotent action boundaries, and durable execution …
What Are Agent Guardrails? How Permission Systems Constrain AI
Agent guardrails enforce permission boundaries on autonomous AI. Learn how Claude SDK, NeMo, and Llama Guard constrain …
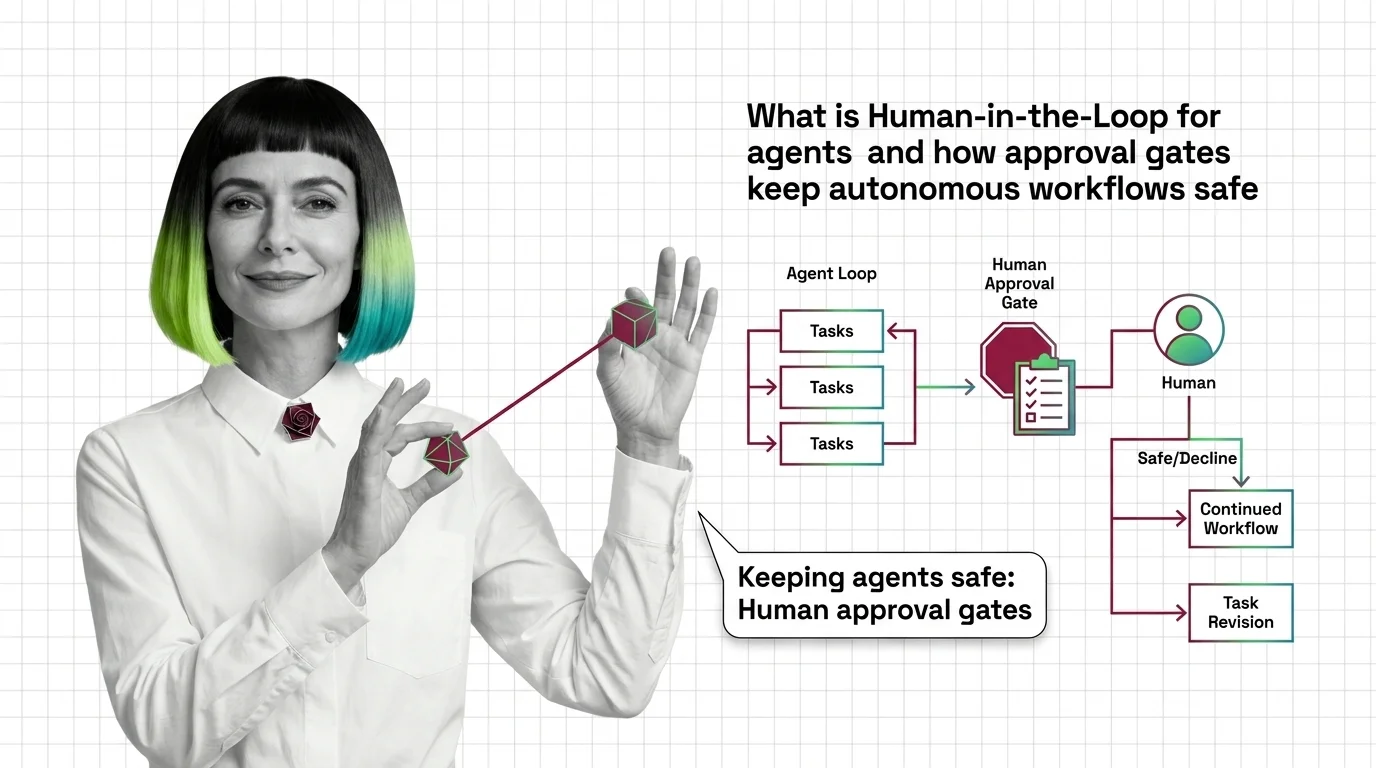
Human-in-the-Loop for AI Agents: How Approval Gates Work
Human-in-the-loop for AI agents pauses autonomous workflows at risky steps and routes them to a human gate. Here's how …
Prerequisites and Technical Limits of HITL for AI Agents
HITL for agents is easy to start and hard to scale. Learn the prerequisites — durable state, idempotency, escalation — …
Prerequisites for Agent Guardrails: Tool Use and Runtime Limits
Agent guardrails are runtime classifiers wrapped around tool-use loops — useful, partial, and demonstrably evadable. …
Agent State Management: How Checkpointing Persists Memory Across Turns
Agent state management decides whether your agent remembers. See how LangGraph checkpointers, threads, and reducers …
Agent State Management: Threads, Checkpointers, Hard Limits
Agent state is not memory — it is plumbing that replays snapshots between steps. Mona explains threads, checkpointers, …
Agent Evaluation Prerequisites: LLM-as-Judge to Cost-Per-Task
Agent evaluation needs three signals: outcome, trajectory, cost. Learn why LLM-as-judge has known biases and where major …
Agent Evaluation: How Trajectory Analysis Measures AI Agents
Agent evaluation grades the path, not just the final answer. Learn how trajectory analysis exposes silent reasoning …
From Chain-of-Thought to Tool Use: Prerequisites and Technical Limits of Agent Planning
Agent planning rests on three primitives — chain-of-thought, tool use, and the ReAct loop. Learn the prerequisites and …
Multi-Agent Systems: Prerequisites and Hard Technical Limits
Before multi-agent systems, master tool use, the ReAct loop, and memory. Then face the limits: context blow-up, error …
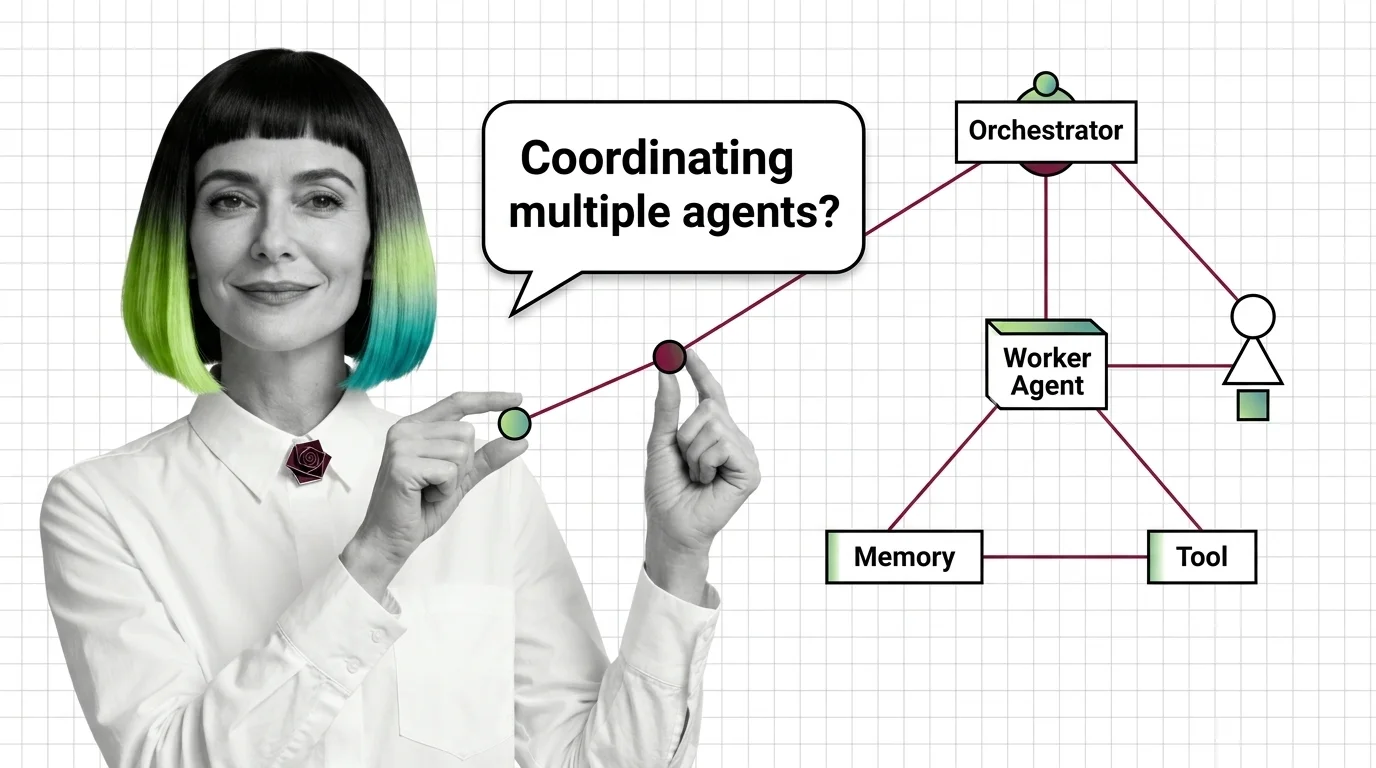
Multi-Agent Systems: Supervisor, Debate, and Swarm Patterns
Multi-agent systems coordinate specialized AI agents through supervisor, debate, or swarm patterns. Here is how each …
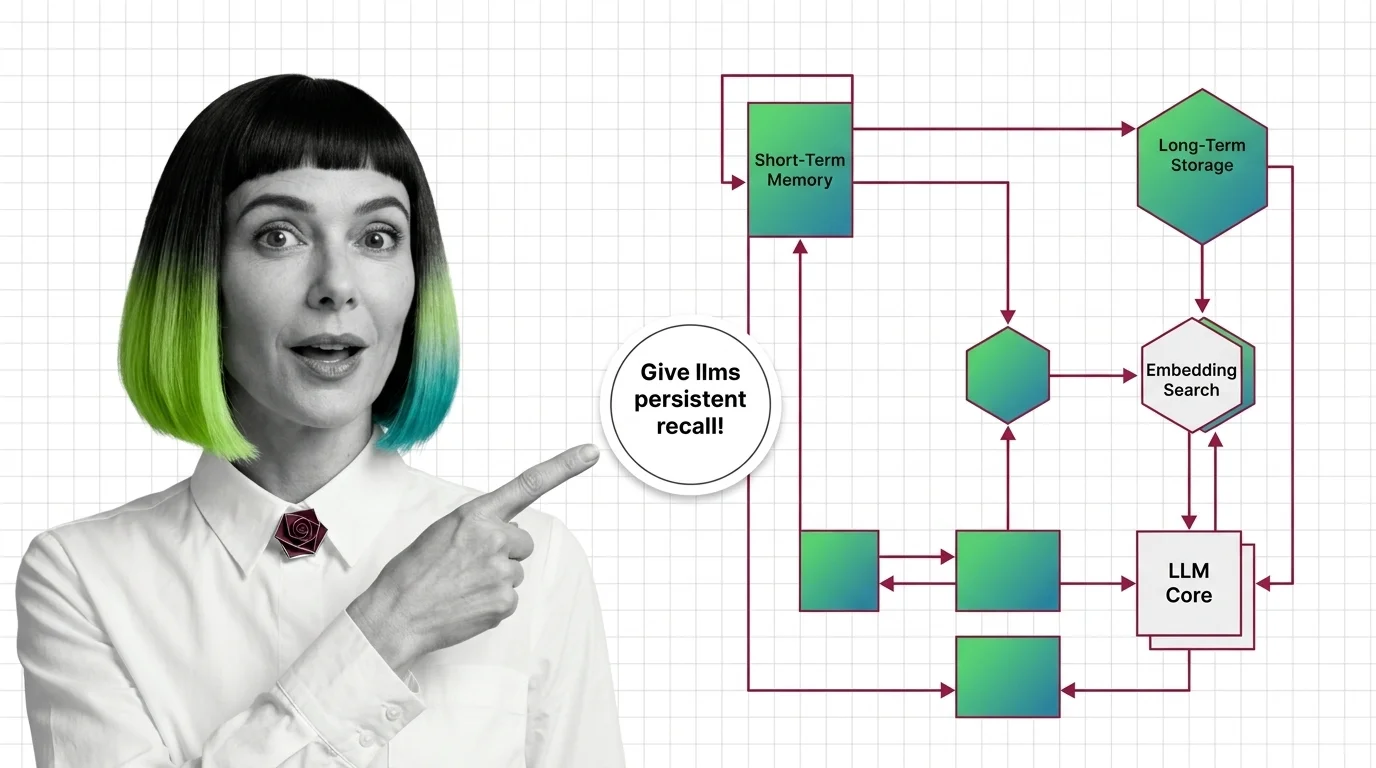
Agent Memory Systems: How LLMs Get Persistent Recall Across Sessions
Agent memory systems give LLMs persistent recall across sessions. Inside the architectures: temporal graphs, …
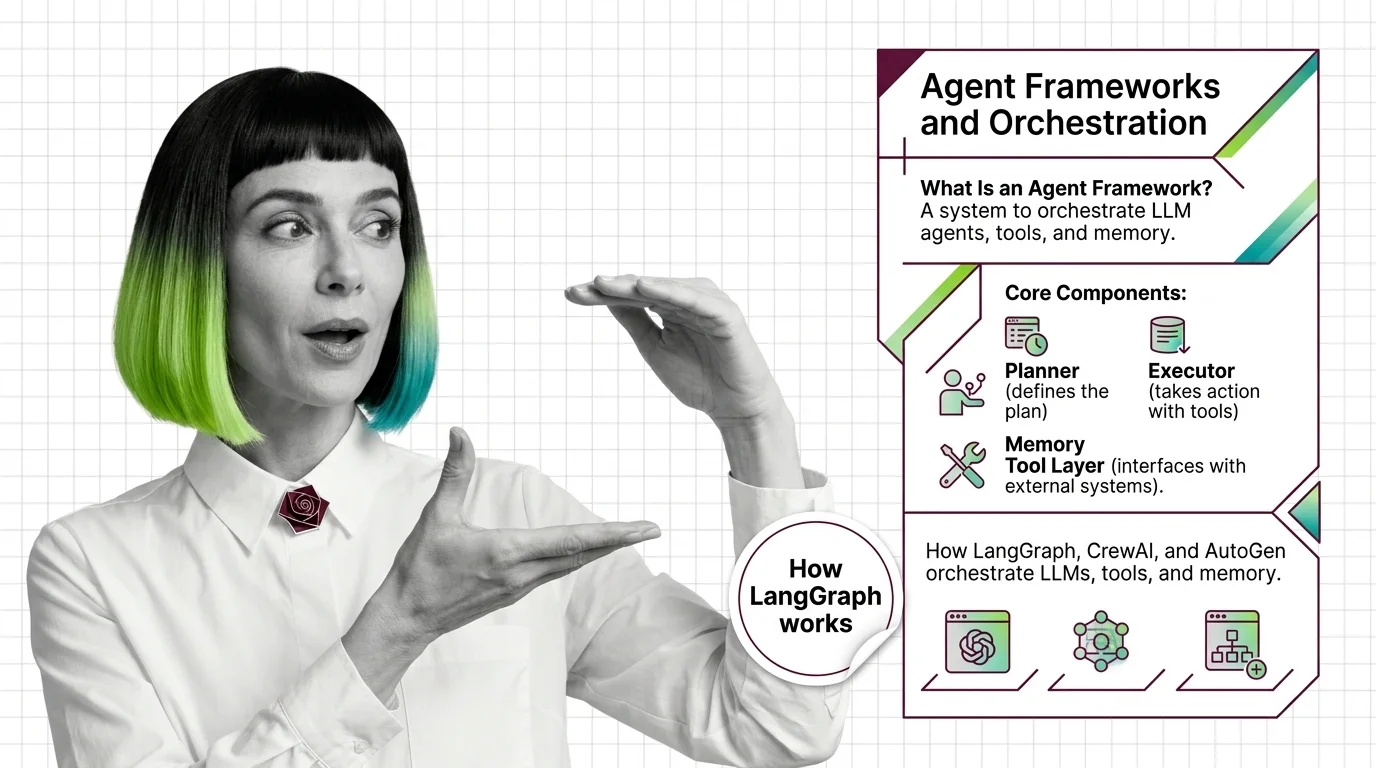
Agent Frameworks: How LangGraph, CrewAI, and AutoGen Orchestrate LLMs
Agent frameworks orchestrate LLM calls, tools, and memory — but each one bets on a different abstraction. Learn what …
Agent Memory Architectures: Prerequisites and Hard Limits
Agent memory isn't a bigger context window. Learn the prerequisites for designing agent memory systems and the hard …
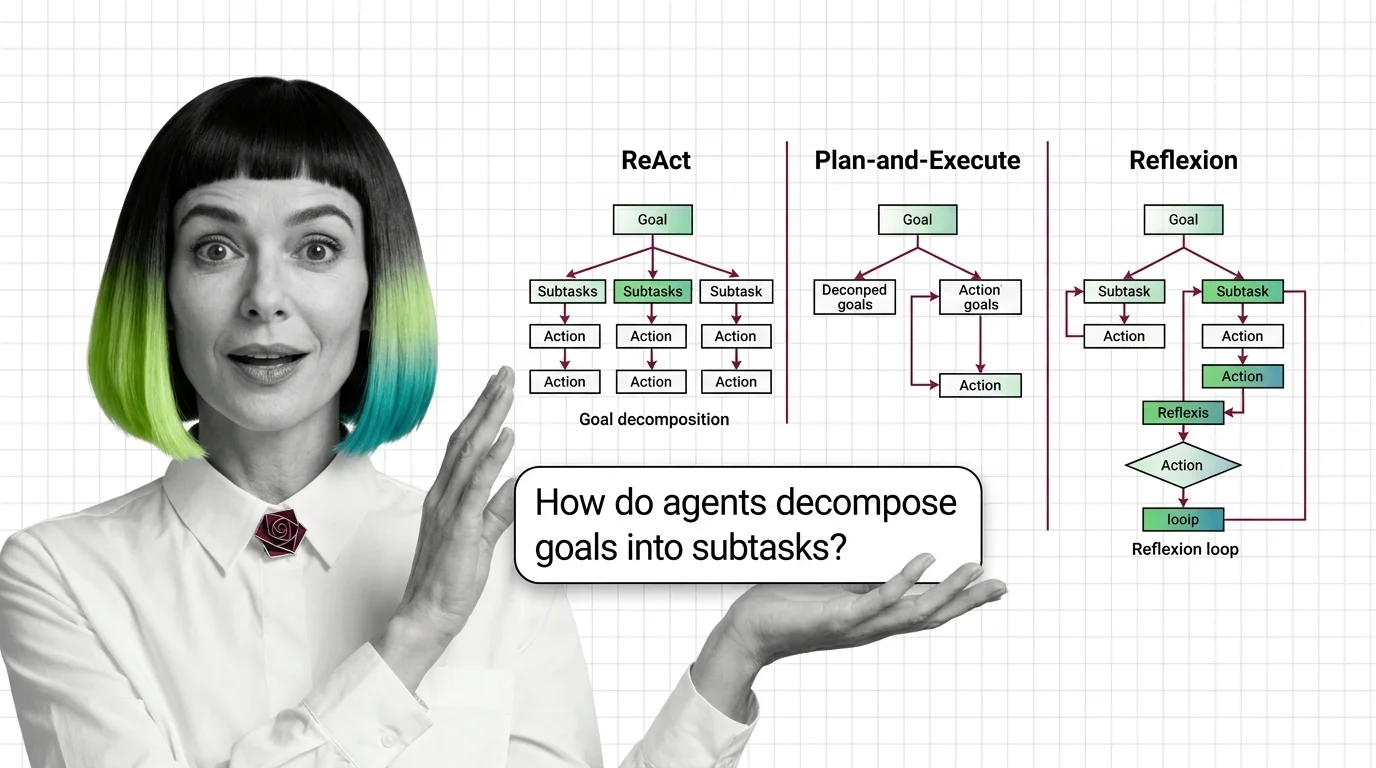
Agent Planning and Reasoning: ReAct, Plan-and-Execute, Reflexion
Agent planning is not human cognition — it is token generation conditioned on observations. How ReAct, Plan-and-Execute, …
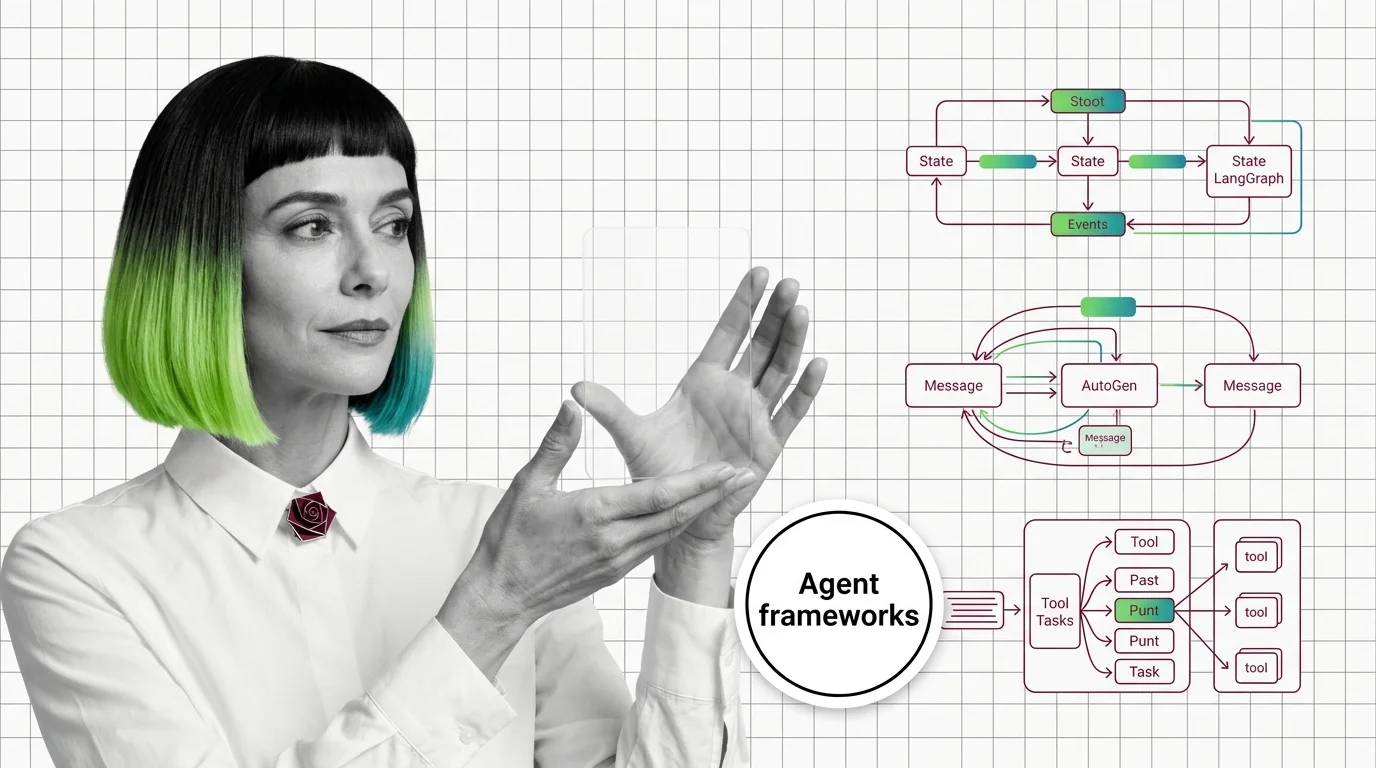
Graph vs Conversation vs Crew: LangGraph, AutoGen, CrewAI Patterns
LangGraph, AutoGen, and CrewAI commit to three different theories of how AI agents coordinate. The pattern you pick …
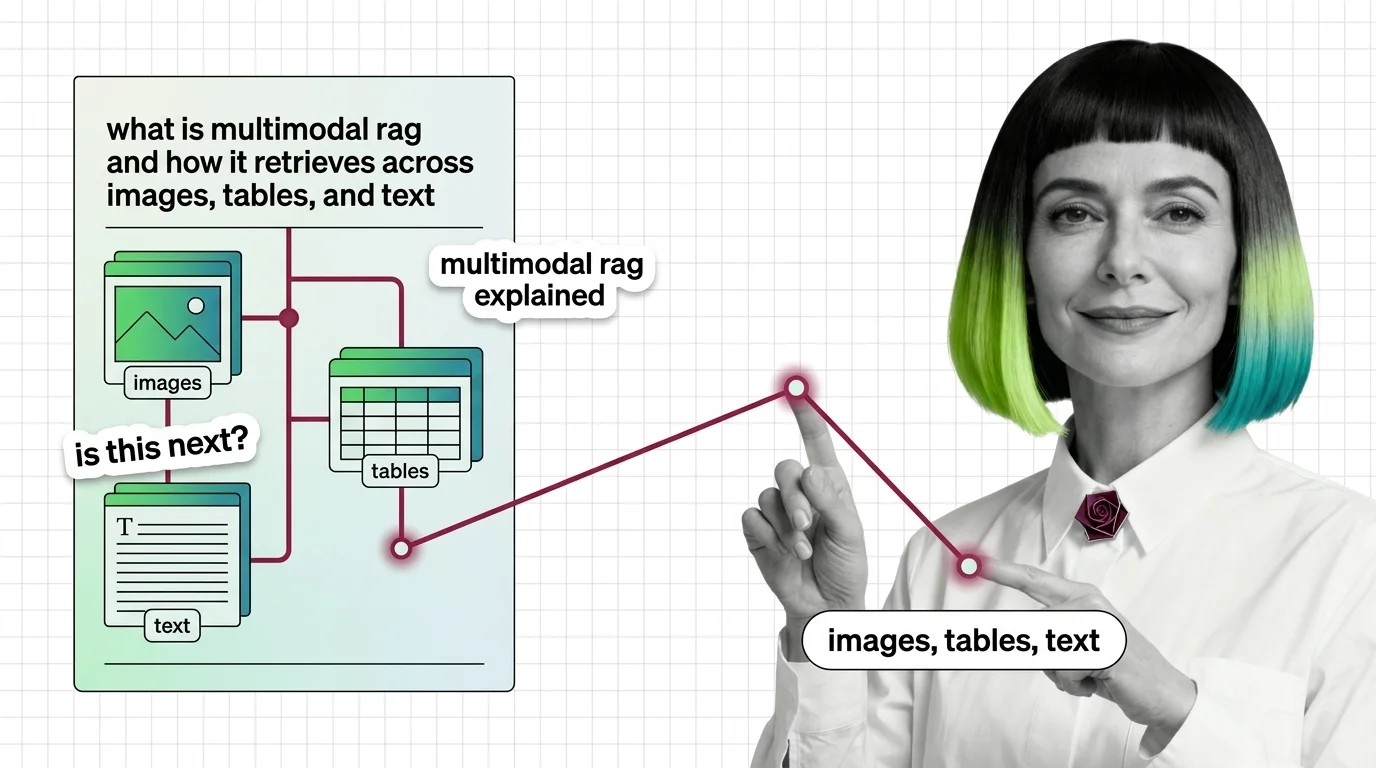
What Is Multimodal RAG and How It Retrieves Across Images, Tables, and Text
Multimodal RAG isn't text RAG with images bolted on. Learn how unified embeddings, text summaries, and vision-first …
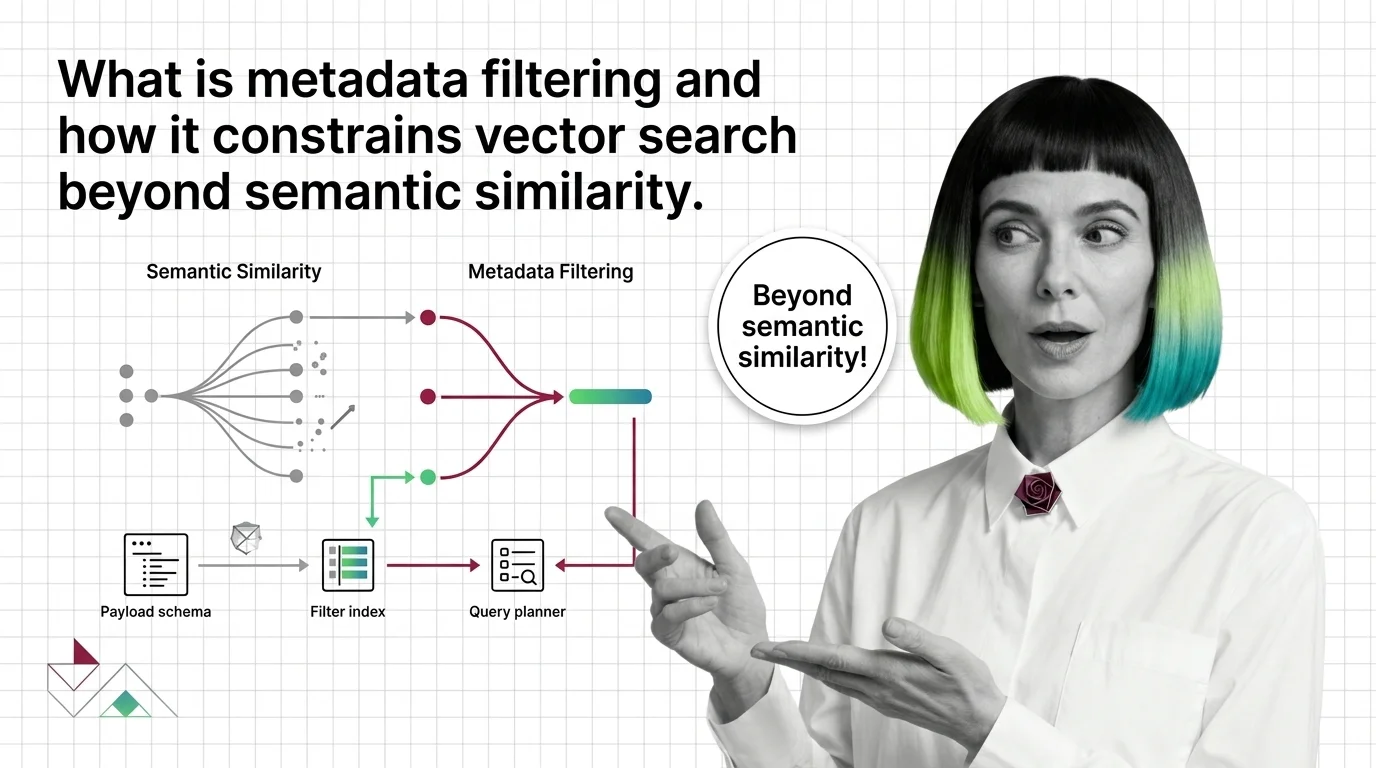
What Is Metadata Filtering and How It Constrains Vector Search Beyond Semantic Similarity
Metadata filtering attaches typed key-value payloads to each vector and applies predicates during search, narrowing …
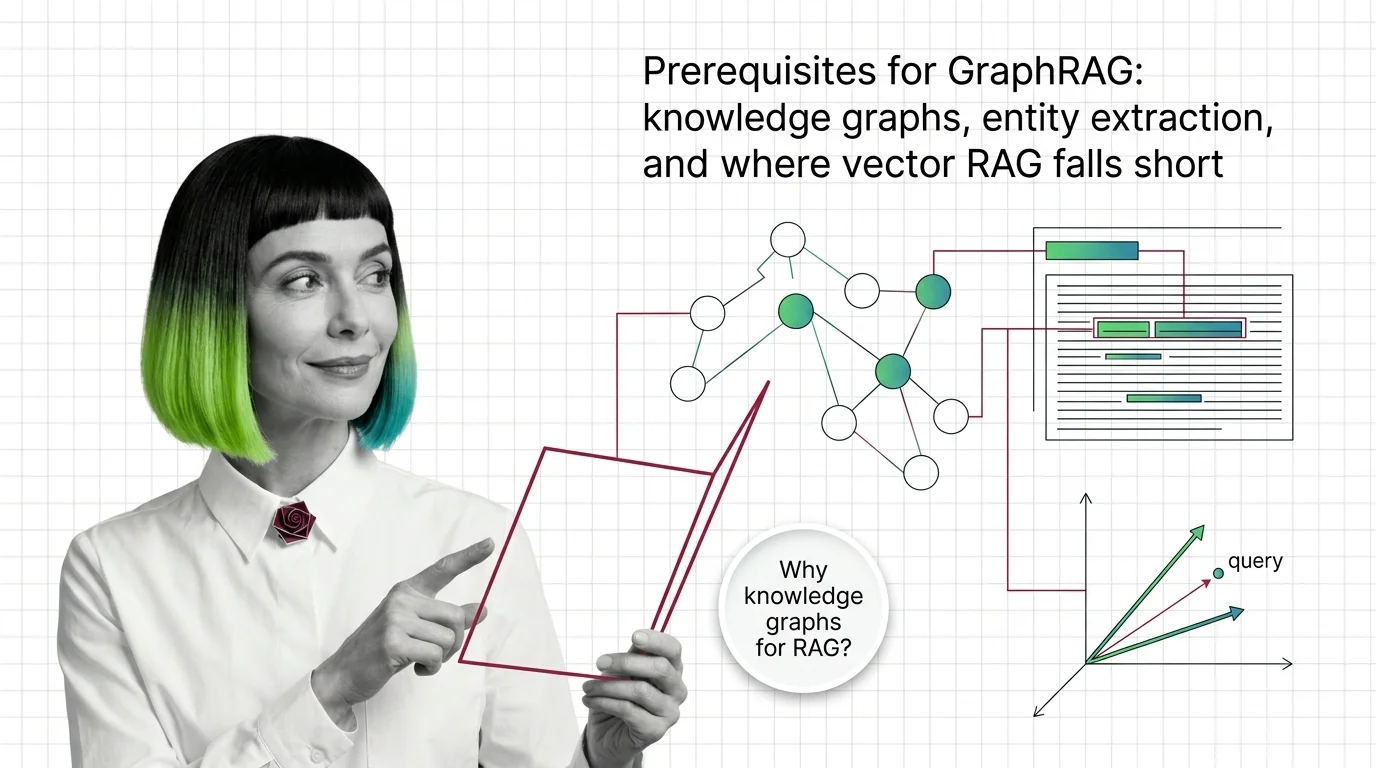
GraphRAG Prerequisites: Knowledge Graphs and Where Vector RAG Falls Short
GraphRAG inherits chunking, embeddings, and entity extraction from vector RAG. Learn what you need first and where the …
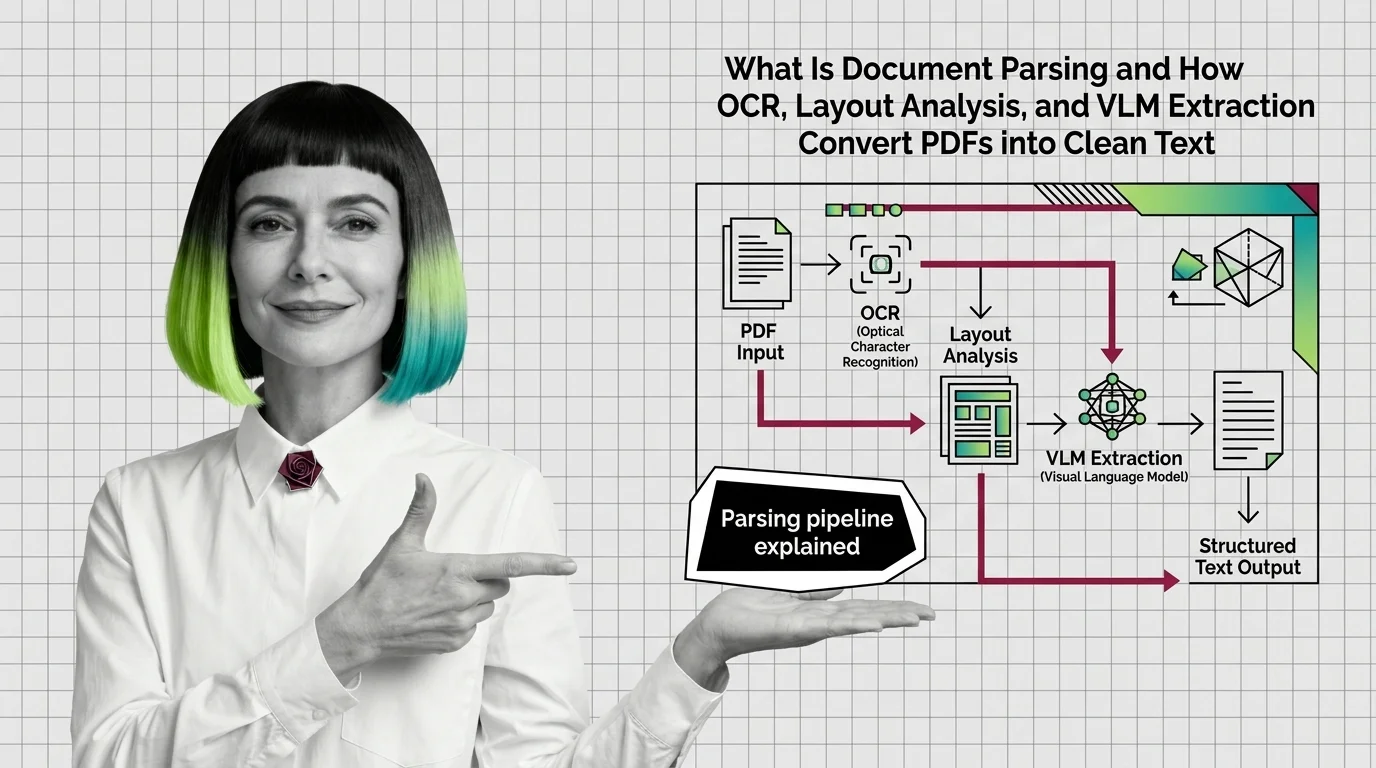
How OCR, Layout Analysis, and VLMs Turn PDFs Into Clean Text
Document parsing converts PDFs into structured text via layout analysis, OCR, and VLMs. Here is how each component works …
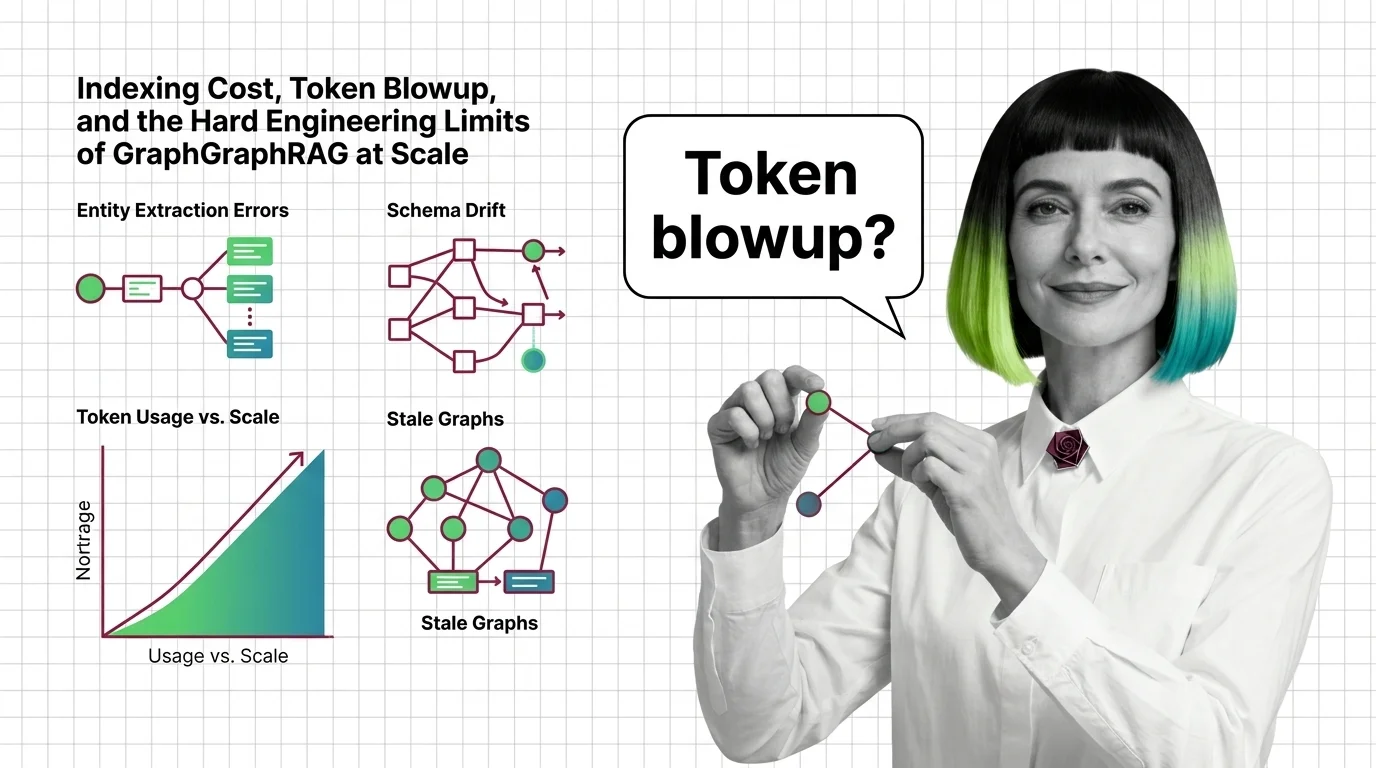
Indexing Cost, Token Blowup, and the Hard Engineering Limits of GraphRAG at Scale
GraphRAG indexing costs scale with token recursion, not document size. A breakdown of the cost cliff, hallucinated …
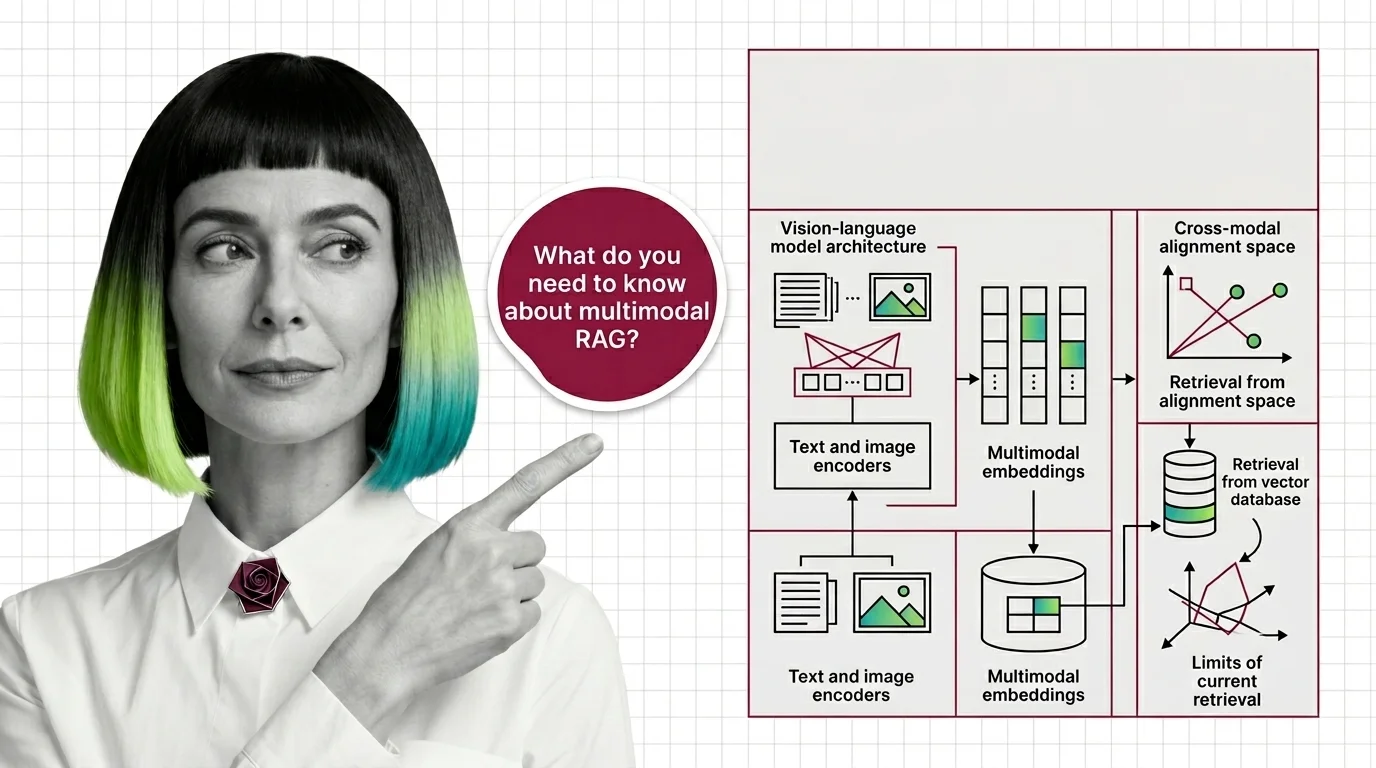
Multimodal RAG Prerequisites: Vision-Language Models, Cross-Modal Alignment
Before multimodal RAG works, you need vision-language models, shared embeddings, and a theory of cross-modal retrieval. …
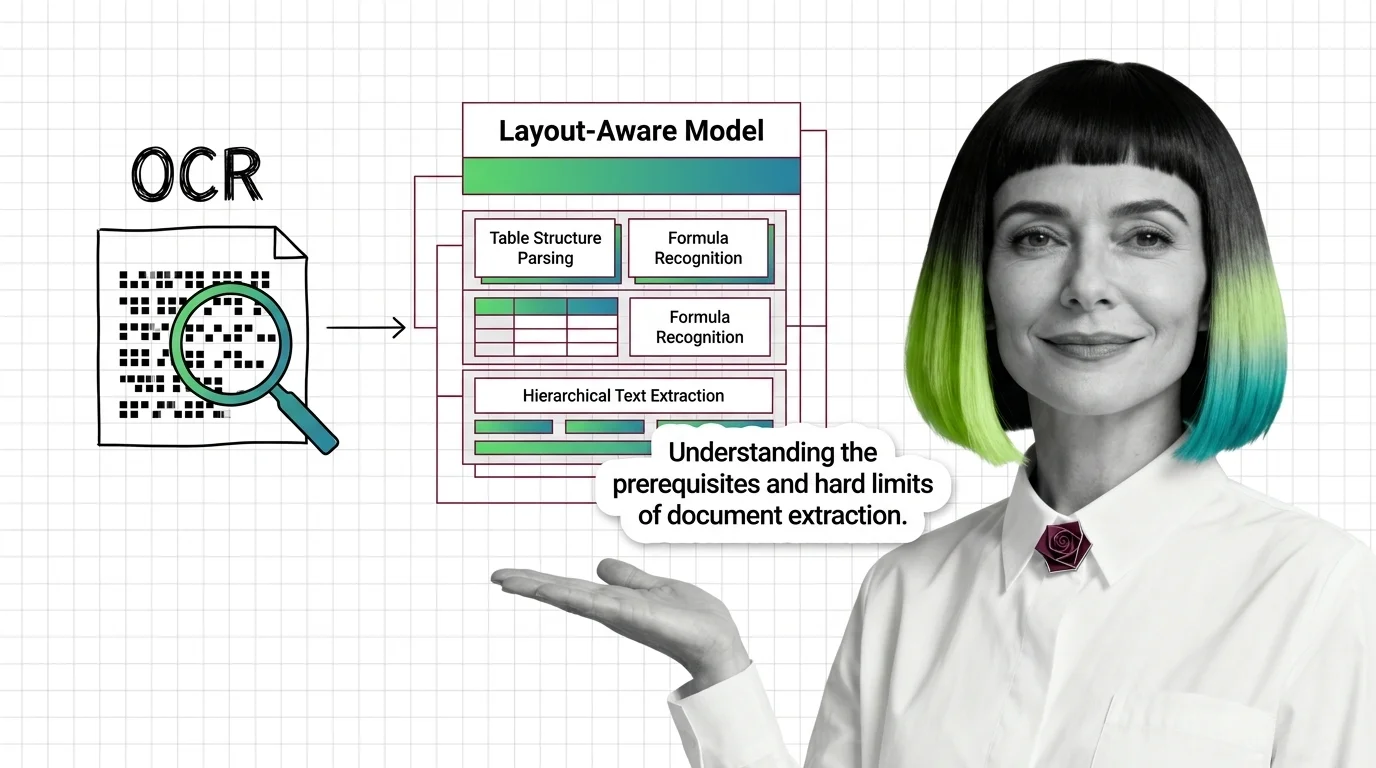
OCR to Layout-Aware Models: Prerequisites and Hard Limits
Document parsing breaks in predictable ways. Learn the prerequisites for understanding OCR and layout-aware models, and …
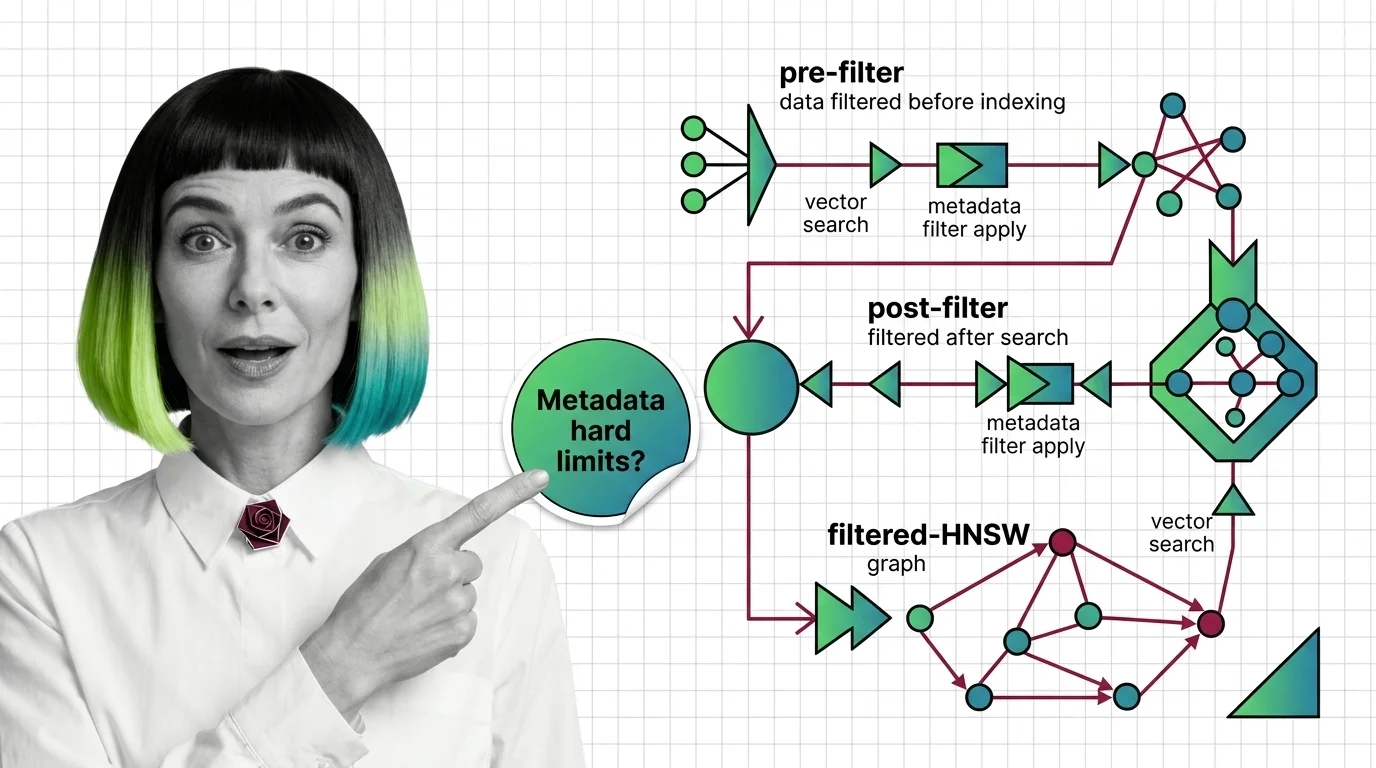
Pre-Filter vs Post-Filter vs Filtered-HNSW: Metadata Filtering at Scale
Why metadata filtering breaks vector search at scale — the HNSW prerequisites, payload indexing, and Boolean predicates …
What Is GraphRAG? Multi-Hop Reasoning with Knowledge Graphs
GraphRAG turns documents into a knowledge graph and uses community summaries to answer multi-hop questions vector …
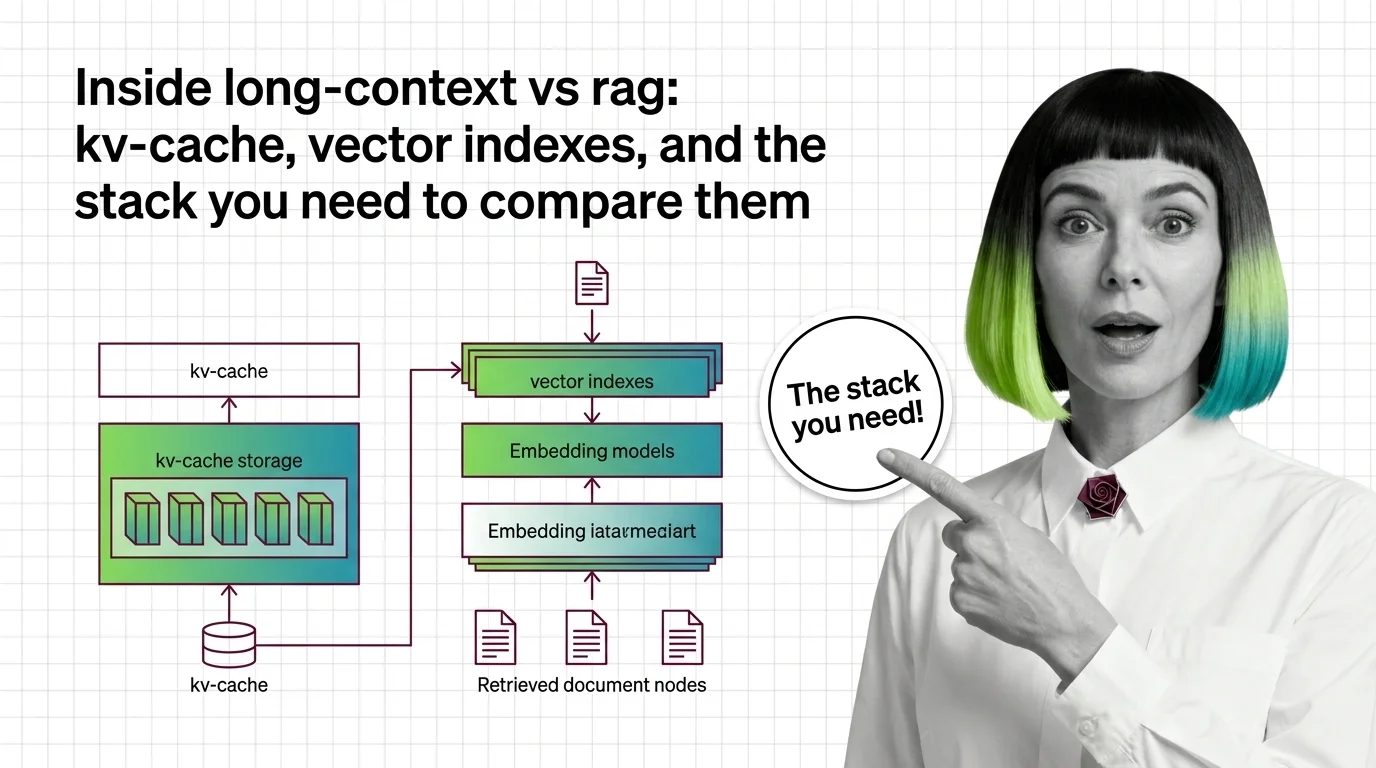
Inside Long-Context vs RAG: KV-Cache, Vector Indexes, and the Stack You Need to Compare Them
Long-context models and RAG pipelines compete for the same job with different parts. A component-by-component map of KV …
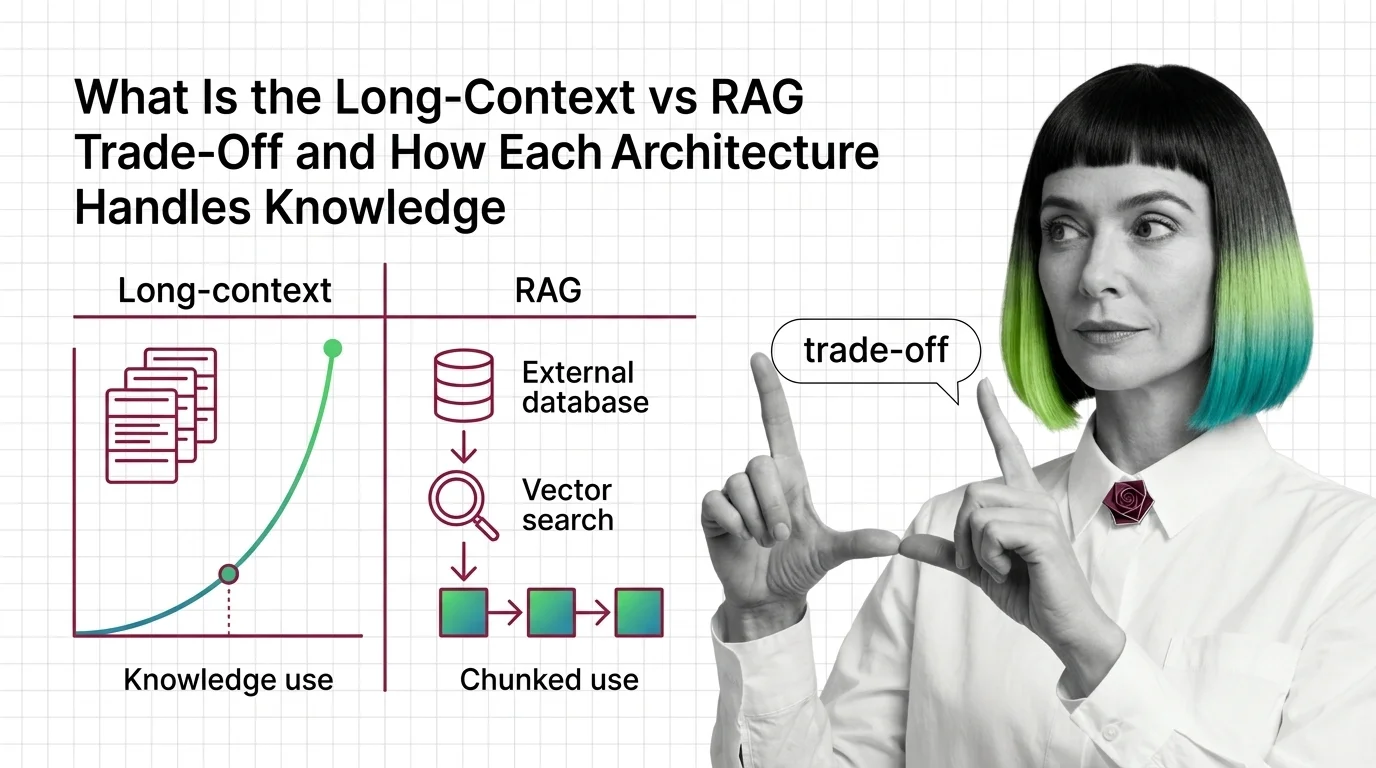
Long-Context vs RAG: How Each Handles Knowledge in 2026
Long-context and RAG sound interchangeable. They are not. The mechanics, failure modes, and cost curves diverge — see …
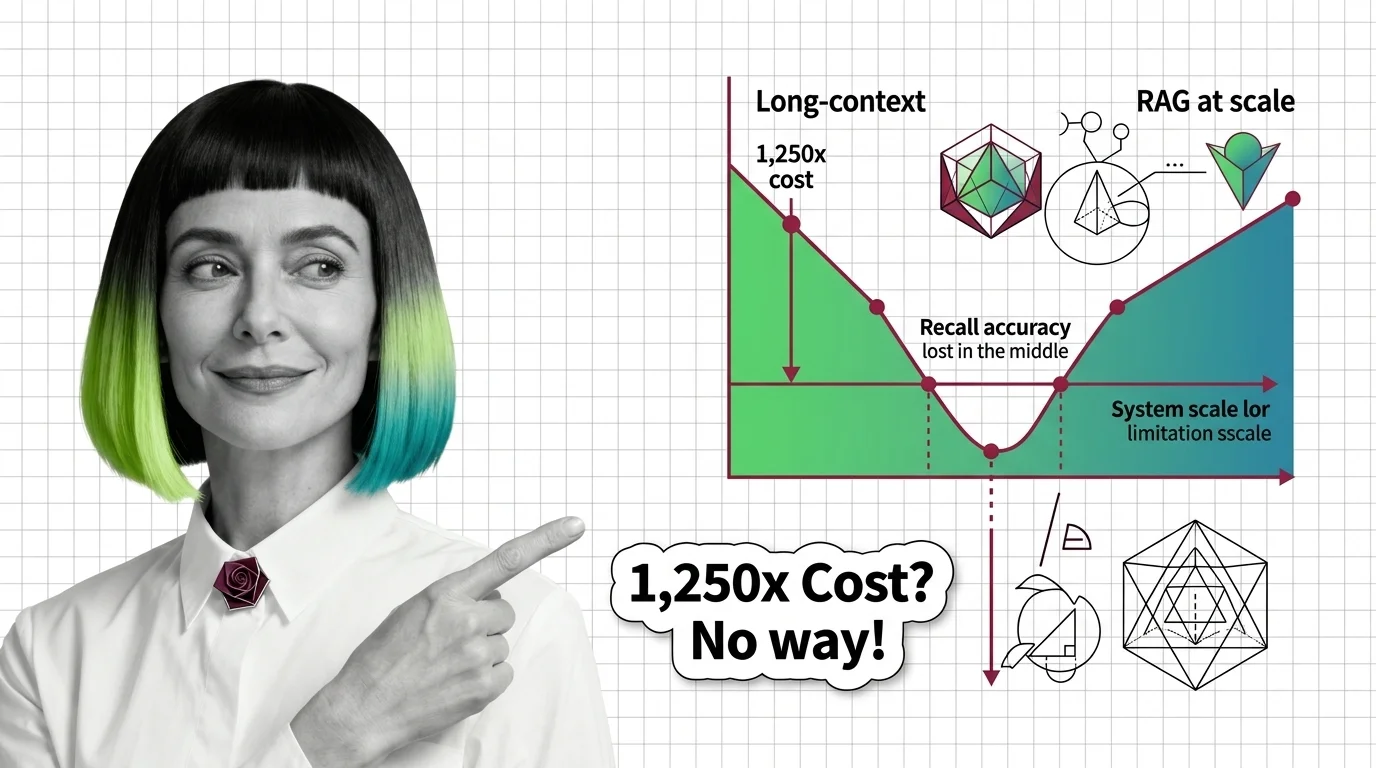
Lost in the Middle, 1,250x Cost: The Limits of Long-Context vs RAG
Long-context windows promise simplicity, but lost-in-the-middle, 1,250x cost gaps, and effective-context collapse at 32K …
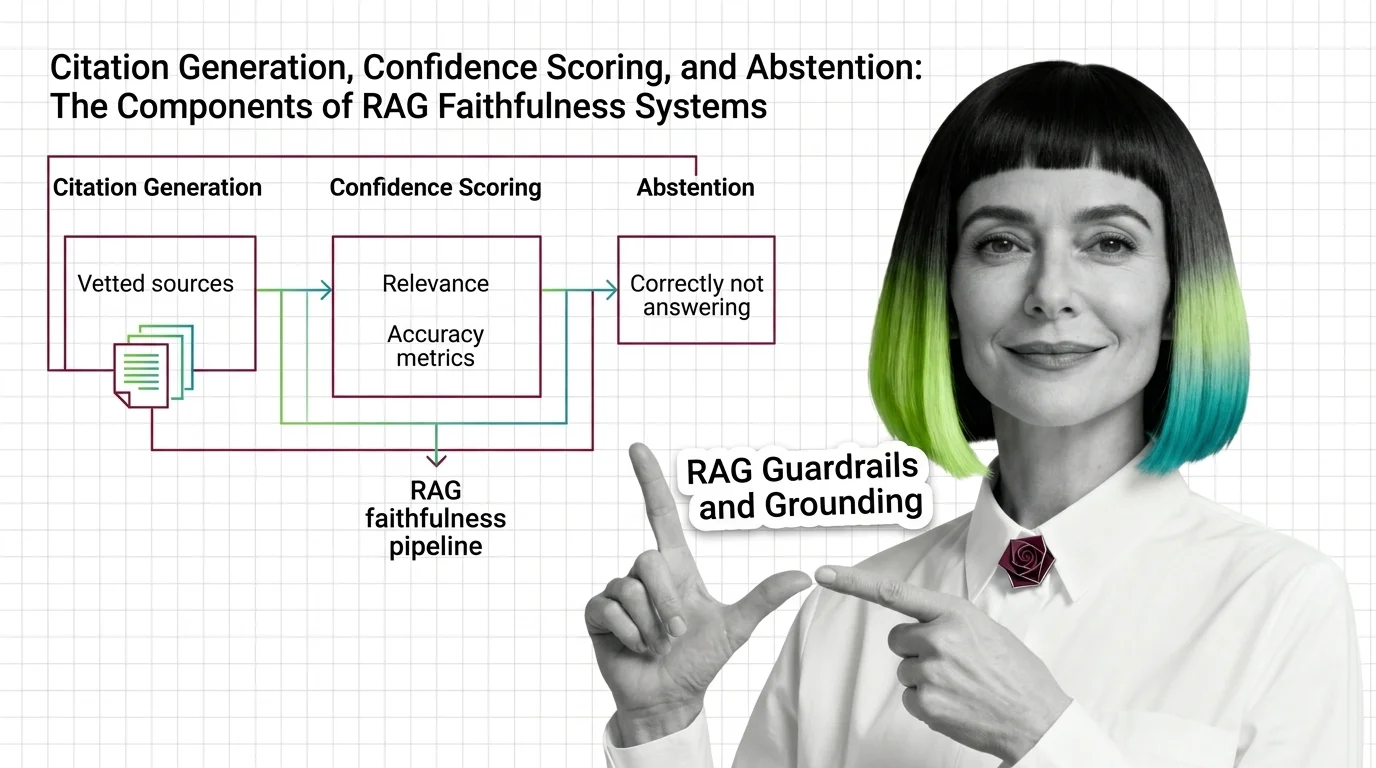
Citation, Confidence, and Abstention: The 3 Layers of RAG Faithfulness
RAG grounding splits into three layers: citation generation, confidence scoring, and abstention. See how each fails …
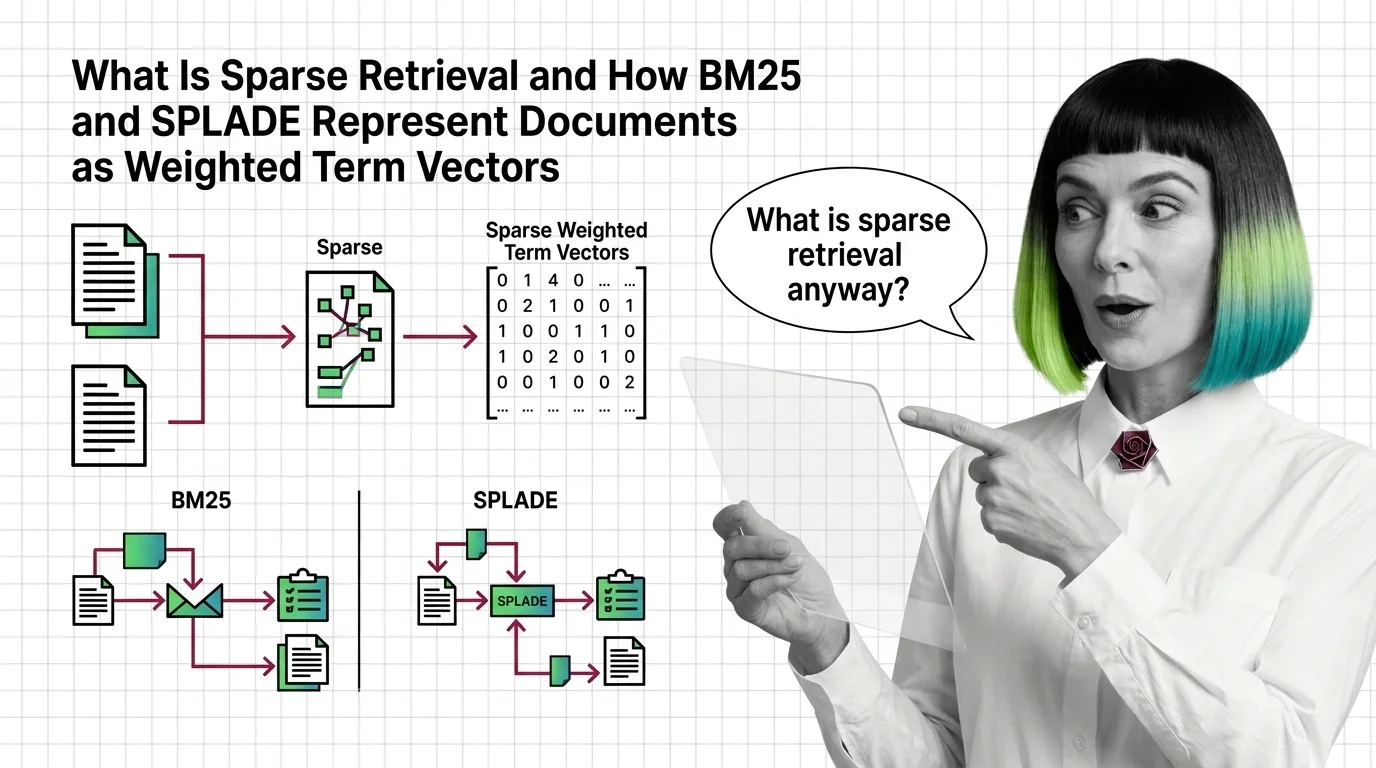
What Is Sparse Retrieval and How BM25 and SPLADE Represent Documents as Weighted Term Vectors
Sparse retrieval encodes documents as weighted term vectors. Here is how BM25 and SPLADE produce those weights and why …
From Recall and MRR to Faithfulness: RAG Evaluation Prerequisites
RAG evaluation needs more than one accuracy score. Learn the IR and generation metrics — Recall, MRR, Faithfulness, …
RAG Evaluation Explained: Faithfulness, Relevance, Context Metrics
RAG evaluation splits your pipeline into retriever and generator and scores each. Learn how Faithfulness, Relevance, and …
From TF-IDF to Learned Sparse: Prerequisites and Hard Limits of BM25, SPLADE, and ELSER
Sparse retrieval starts with BM25 and ends with ELSER and SPLADE-v3. Learn the math, the prerequisites, and where each …
LLM-as-Judge Bias and the Technical Limits of RAG Evaluation
RAG evaluation frameworks like RAGAS rely on LLM judges with documented biases. Why faithfulness and answer relevancy …
Prerequisites for RAG Grounding: Retrieval Quality, the RAG Triad, and Faithfulness Metrics
Before you bolt guardrails onto a RAG pipeline, learn the RAG Triad — context relevance, groundedness, answer relevance …
What Are RAG Guardrails and How Grounding Stops Hallucinations
RAG guardrails and grounding force generated answers to stay tied to retrieved sources. Learn how the mechanism works in …
Why RAG Grounding Still Fails: The Hallucination Detection Ceiling
RAG hallucination detection has a certified ceiling. Why HHEM, Lynx, TruLens, and NeMo Guardrails miss the hardest …
From RAG to Agents: Prerequisites and Hard Limits of Agentic RAG
Agentic RAG is a stack with new failure modes, not an upgrade. Learn the prerequisites and the four physics that limit …
Contextual Retrieval: How Prepended Context Reduces RAG Failures
Contextual retrieval prepends 50-100 tokens of LLM-generated context to each chunk before indexing. Anthropic reports a …
Contextual Retrieval: Prerequisites and Hard Limits at Scale
Contextual Retrieval cuts RAG failure rates, but at a cost. Learn the prerequisites — chunking, hybrid search, reranking …
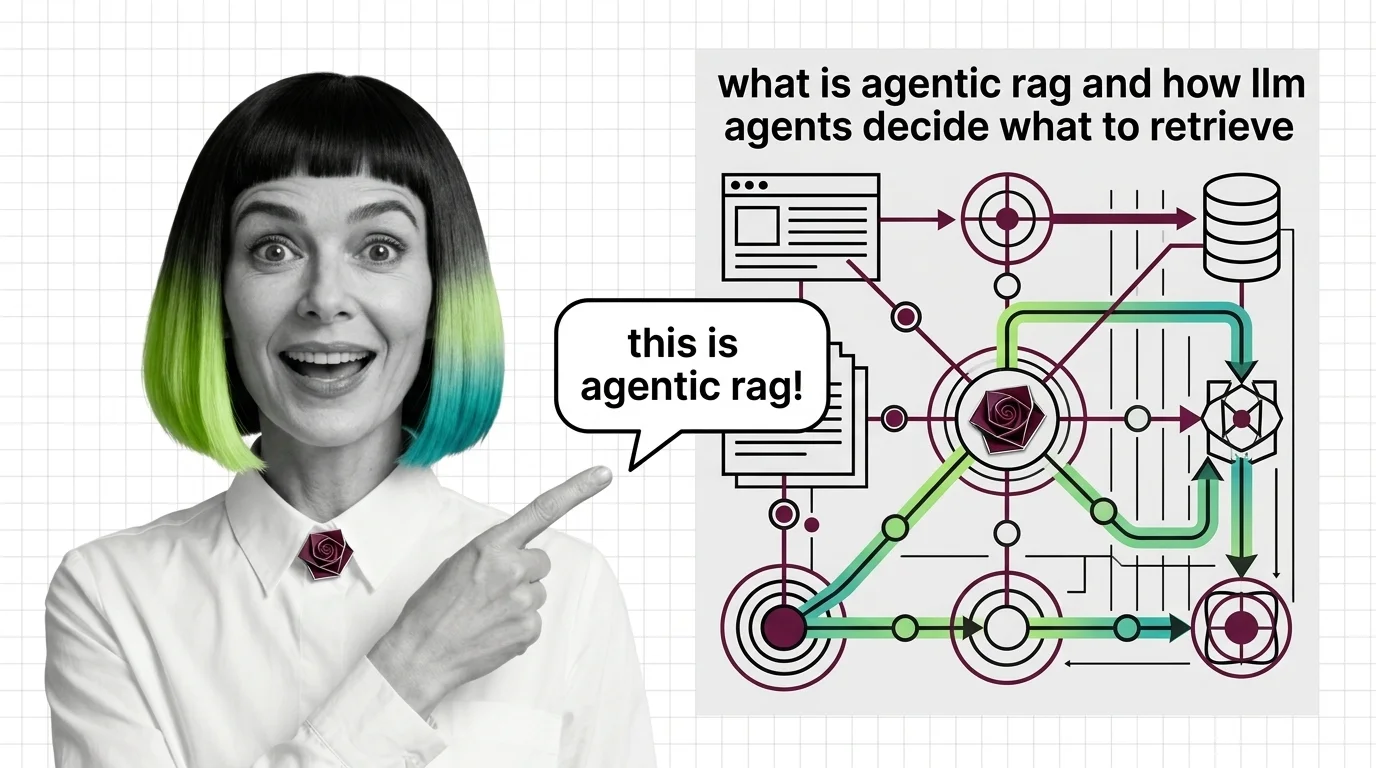
What Is Agentic RAG and How LLM Agents Decide What to Retrieve
Agentic RAG turns retrieval into a decision: an LLM agent chooses whether to retrieve, which source to query, and …
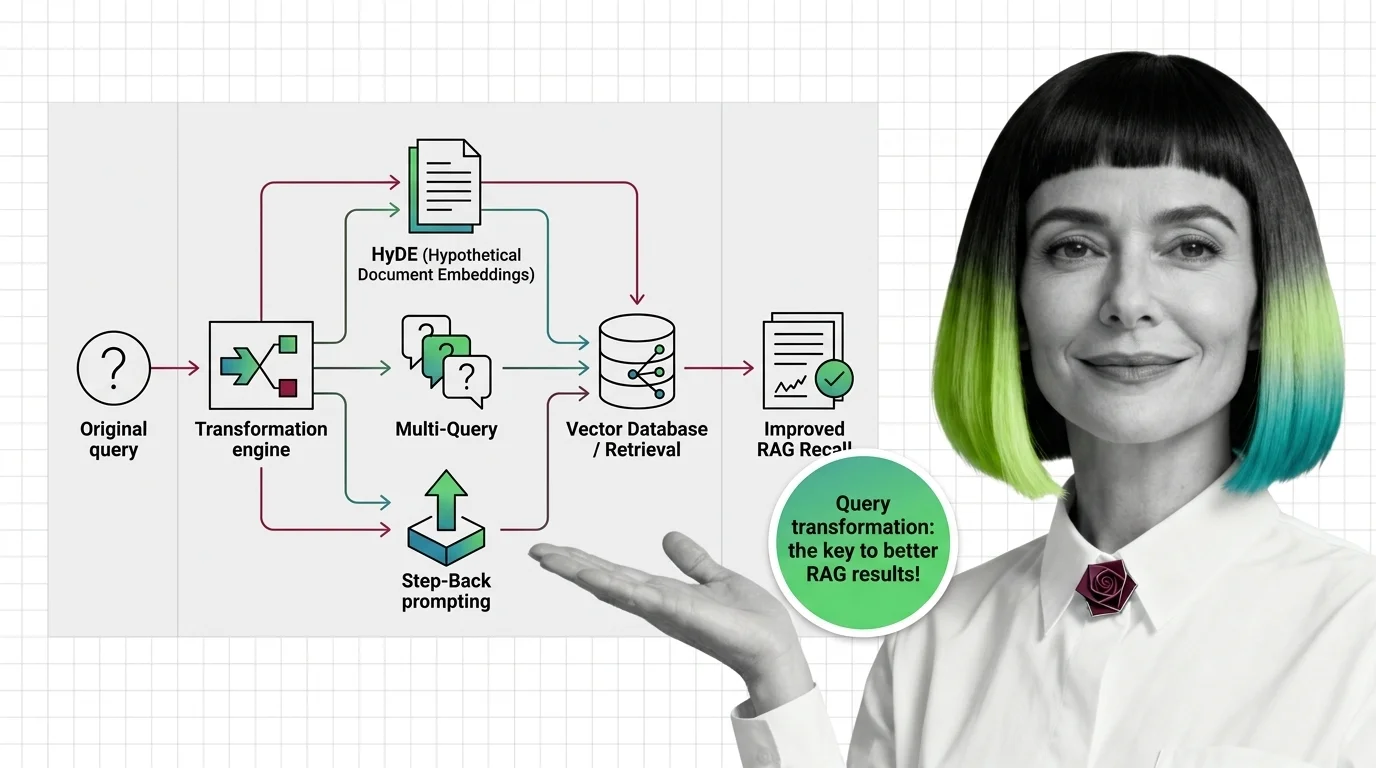
How HyDE, Multi-Query, and Step-Back Improve RAG Retrieval Recall
Query transformation rewrites user prompts before retrieval. Learn how HyDE, Multi-Query, and Step-Back Prompting close …
Cross-Encoder Reranker Limits: Latency Walls and Domain Drift
Cross-encoder rerankers hit two architectural walls: latency scales linearly with candidates and quadratically with …
Cross-Encoders, Bi-Encoders, and Listwise Scoring in Reranking
A reranker reorders the top candidates from vector search using a heavier model. Cross-encoders, bi-encoders, and …
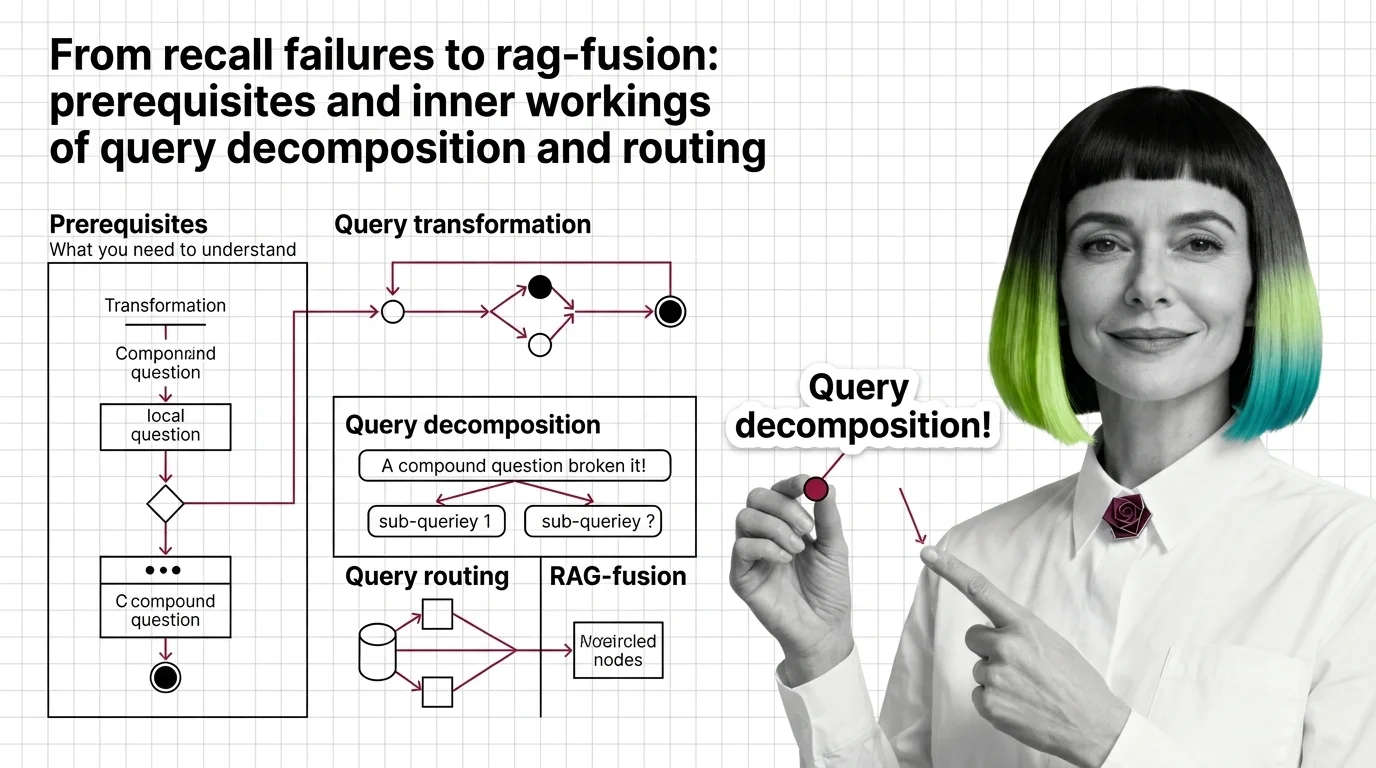
From Recall Failures to RAG-Fusion: Prerequisites and Inner Workings of Query Decomposition and Routing
Vector retrievers lose compound questions to a single point. Query decomposition, routing, and RAG-Fusion fix it by …
Query Transformation Limits: Latency Tax, Drift, Hallucinated Documents
Query transformation in RAG hits three hard limits: latency tax from extra LLM calls, query drift on simple inputs, and …
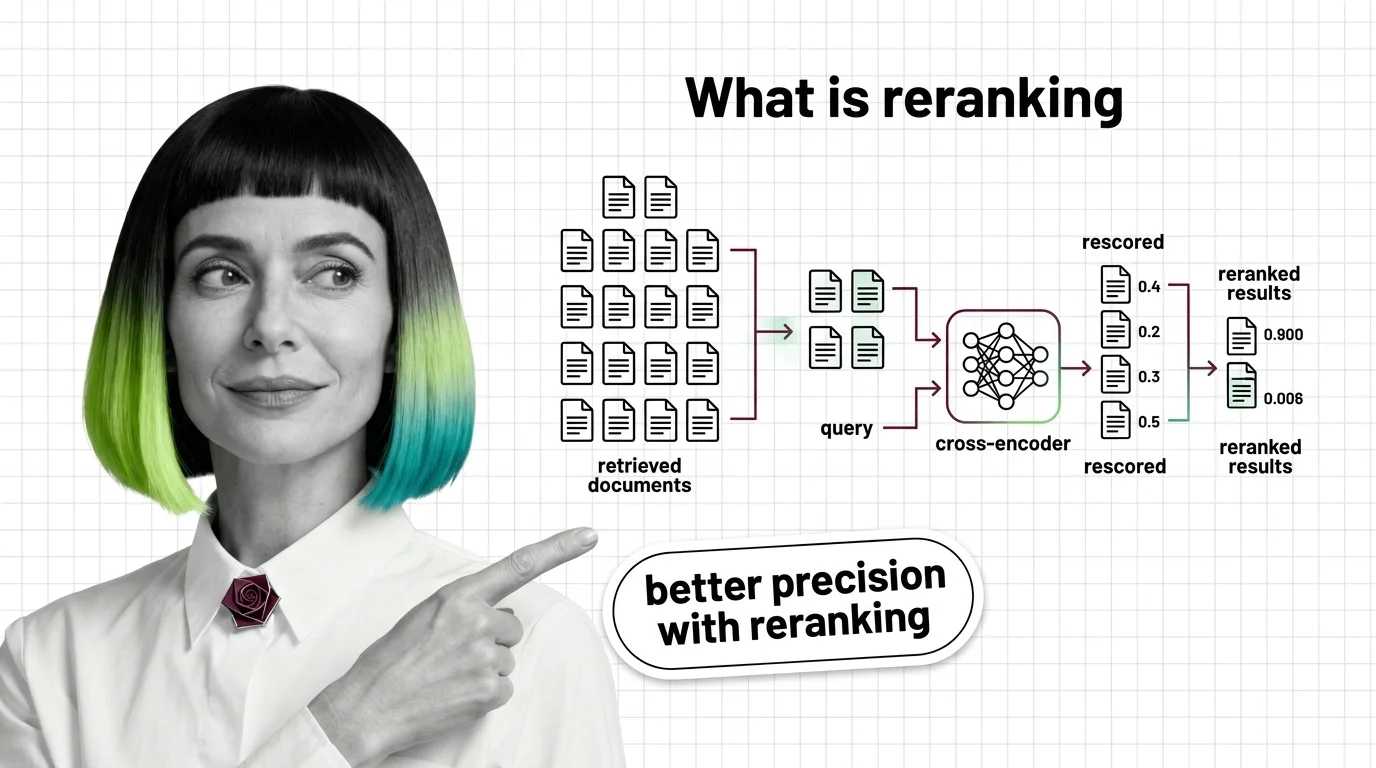
What Is Reranking and Why Cross-Encoders Rescore RAG Retrieval
Reranking splits recall and precision into two stages. See how cross-encoders rescore retrieved documents and why a …
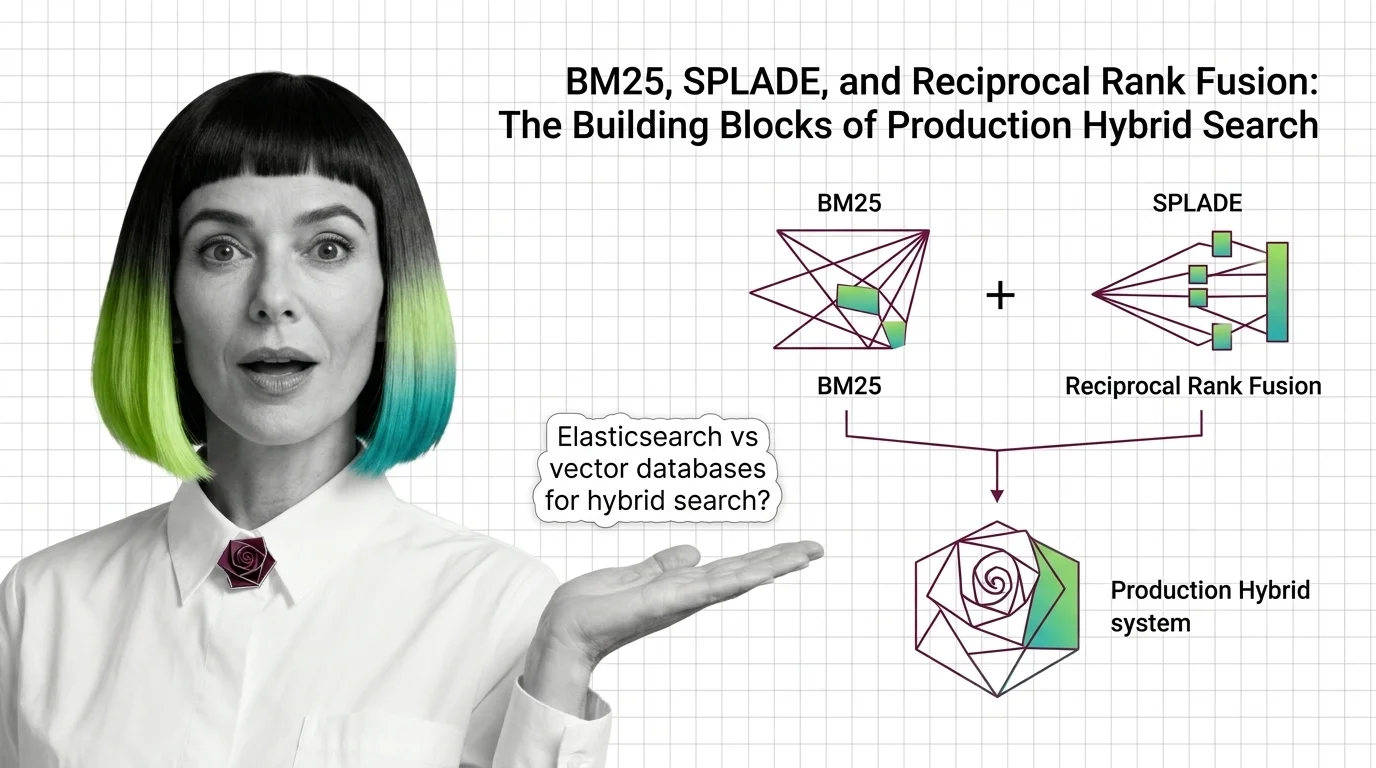
BM25, SPLADE, and Reciprocal Rank Fusion: The Building Blocks of Production Hybrid Search
BM25, SPLADE, and reciprocal rank fusion each solve a different retrieval problem. Here's how the three combine into a …
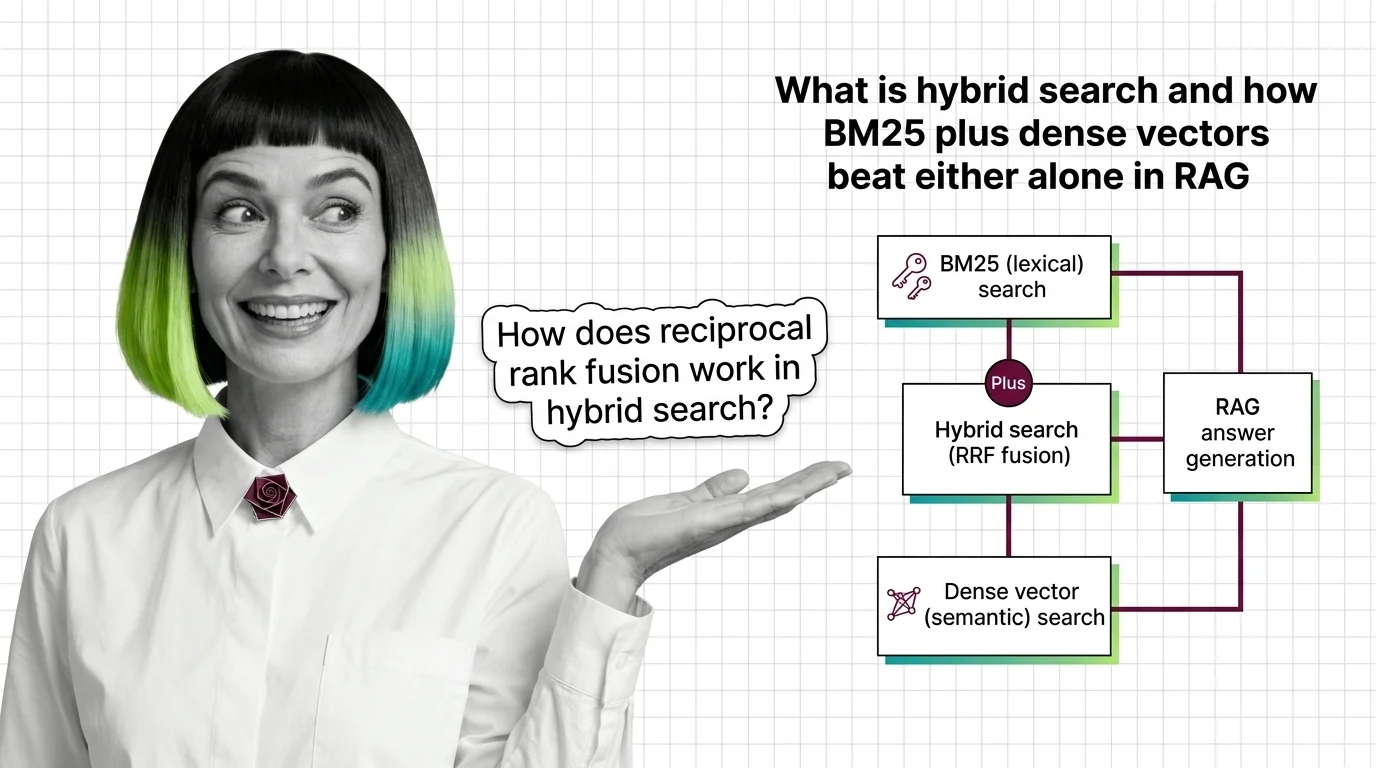
What Is Hybrid Search and How BM25 Plus Dense Vectors Beat Either Alone in RAG
Hybrid search fuses BM25 keyword retrieval with dense vector search using reciprocal rank fusion. Why two ranked lists …
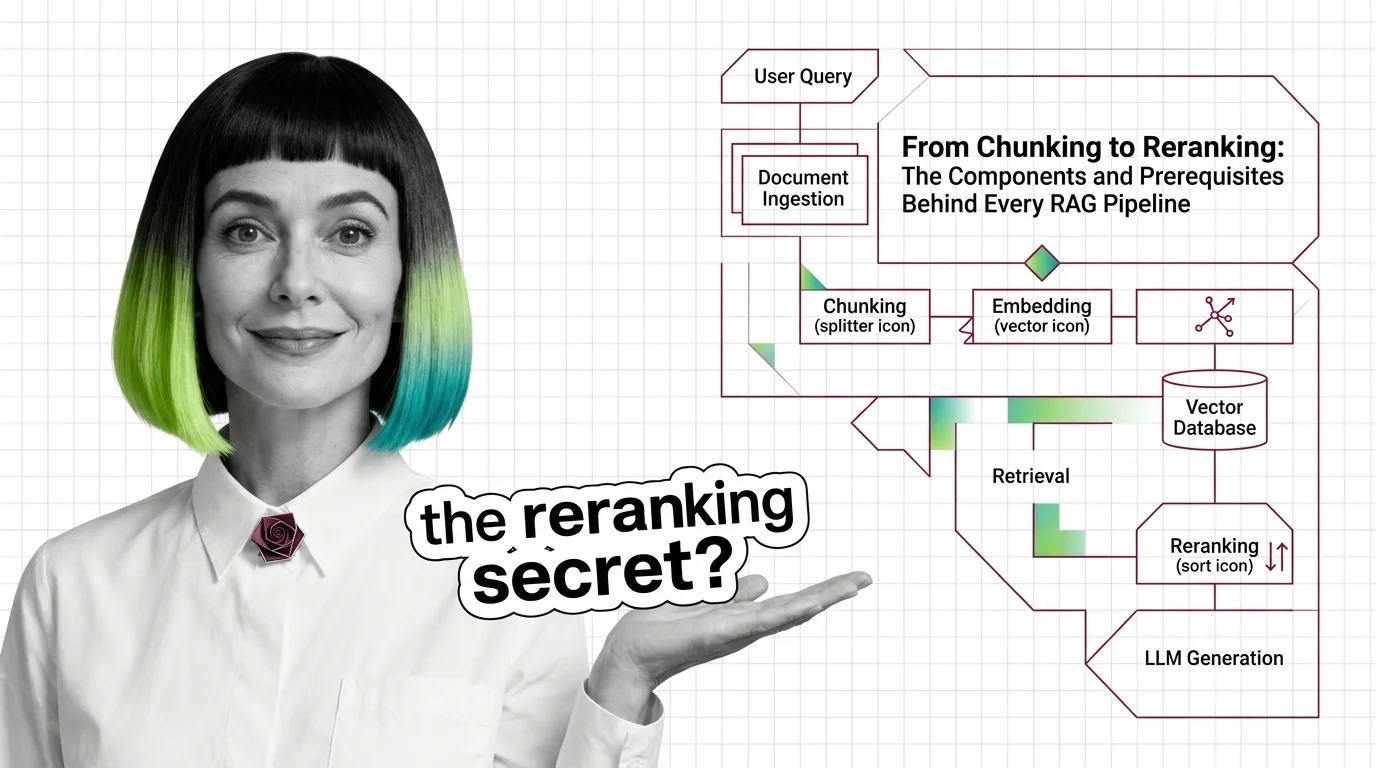
From Chunking to Reranking: RAG Pipeline Components and Prerequisites
Every RAG pipeline runs five components — chunker, embedder, vector store, retriever, reranker. Here is what each one …
Score Mismatch, Tuning Hell: The Hard Limits of Hybrid Search Fusion
Hybrid search merges BM25 and vector results, but the fusion step has hard limits. Score mismatch, RRF blindness, and …
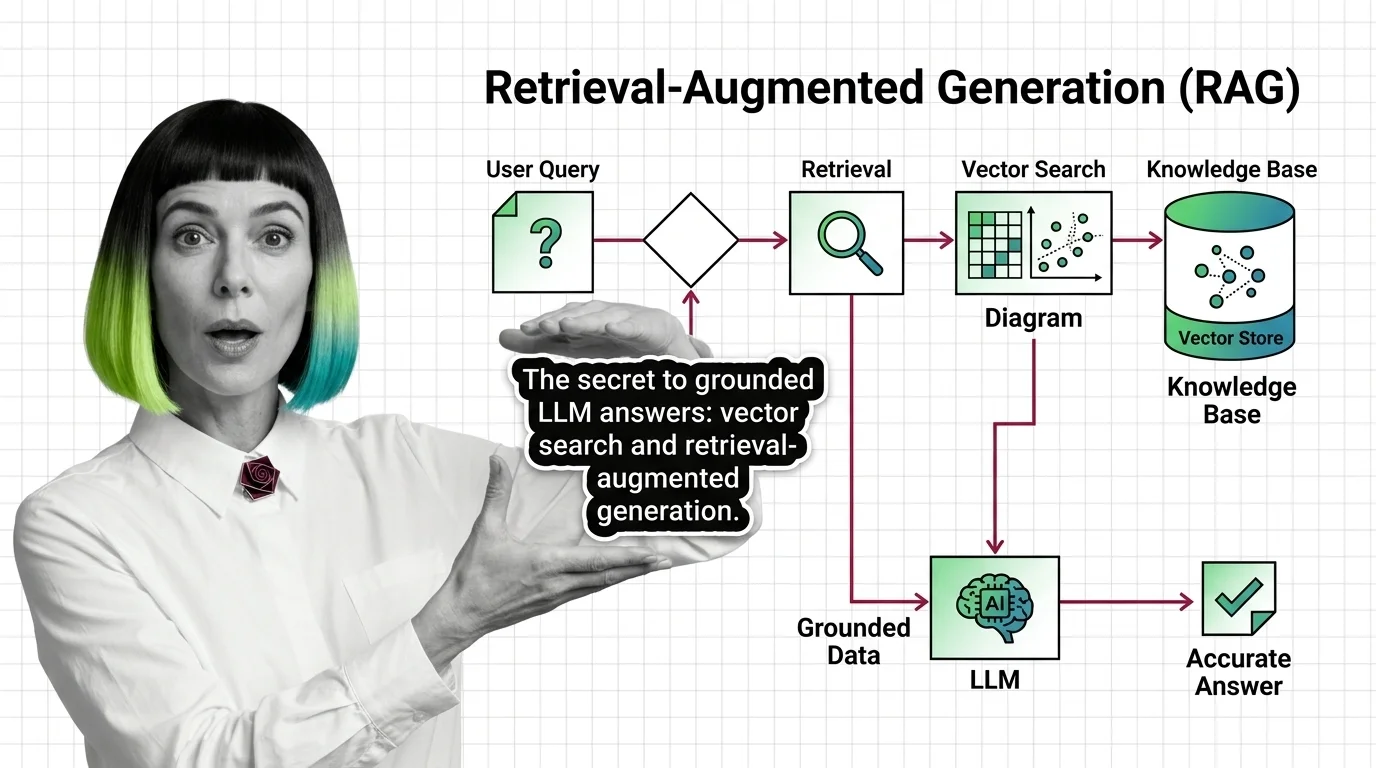
What Is RAG and How LLMs Use Vector Search to Ground Their Answers
Retrieval-augmented generation pairs an LLM with a vector index so answers are grounded in real documents — not just …
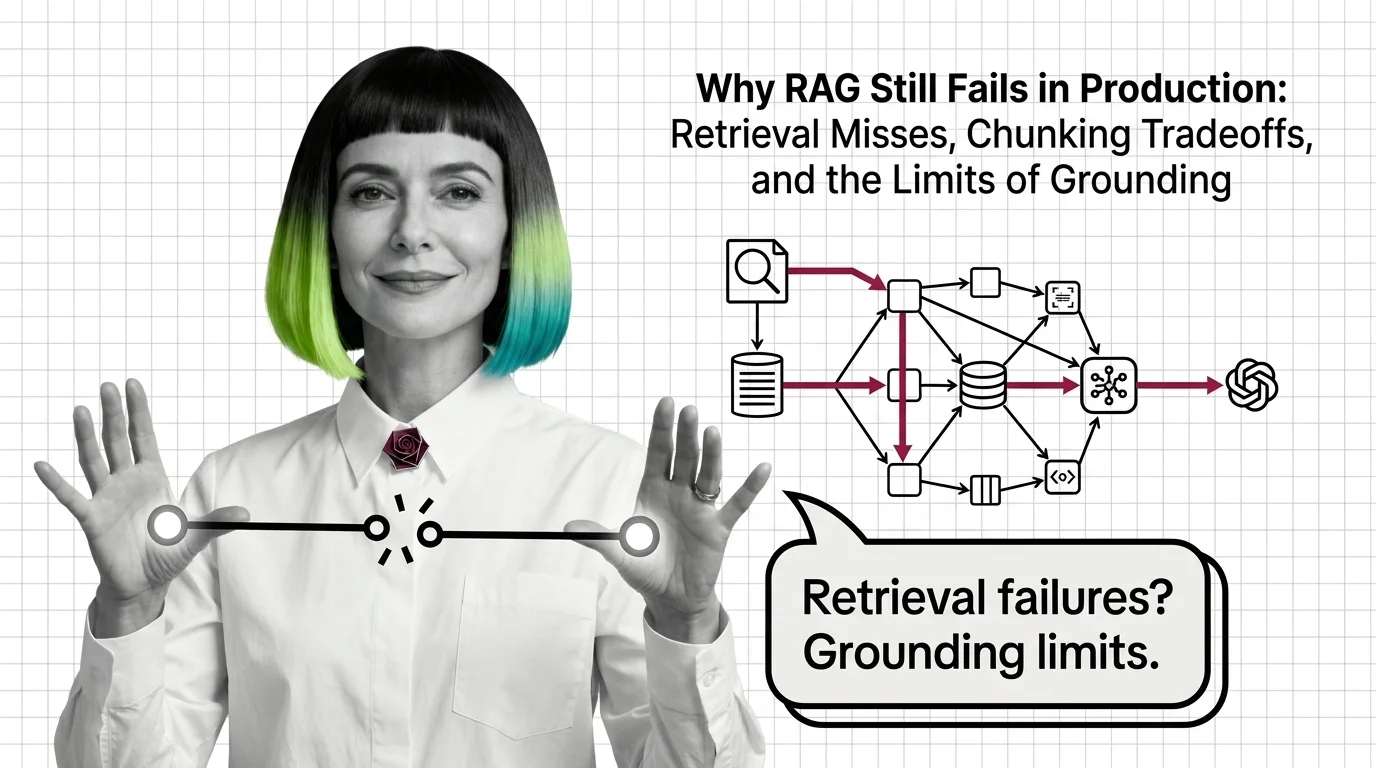
Why RAG Still Fails in Production: Retrieval, Chunking, Grounding
RAG fails in production because retrieval, chunking, and grounding hit structural limits — not because of bugs. Why …
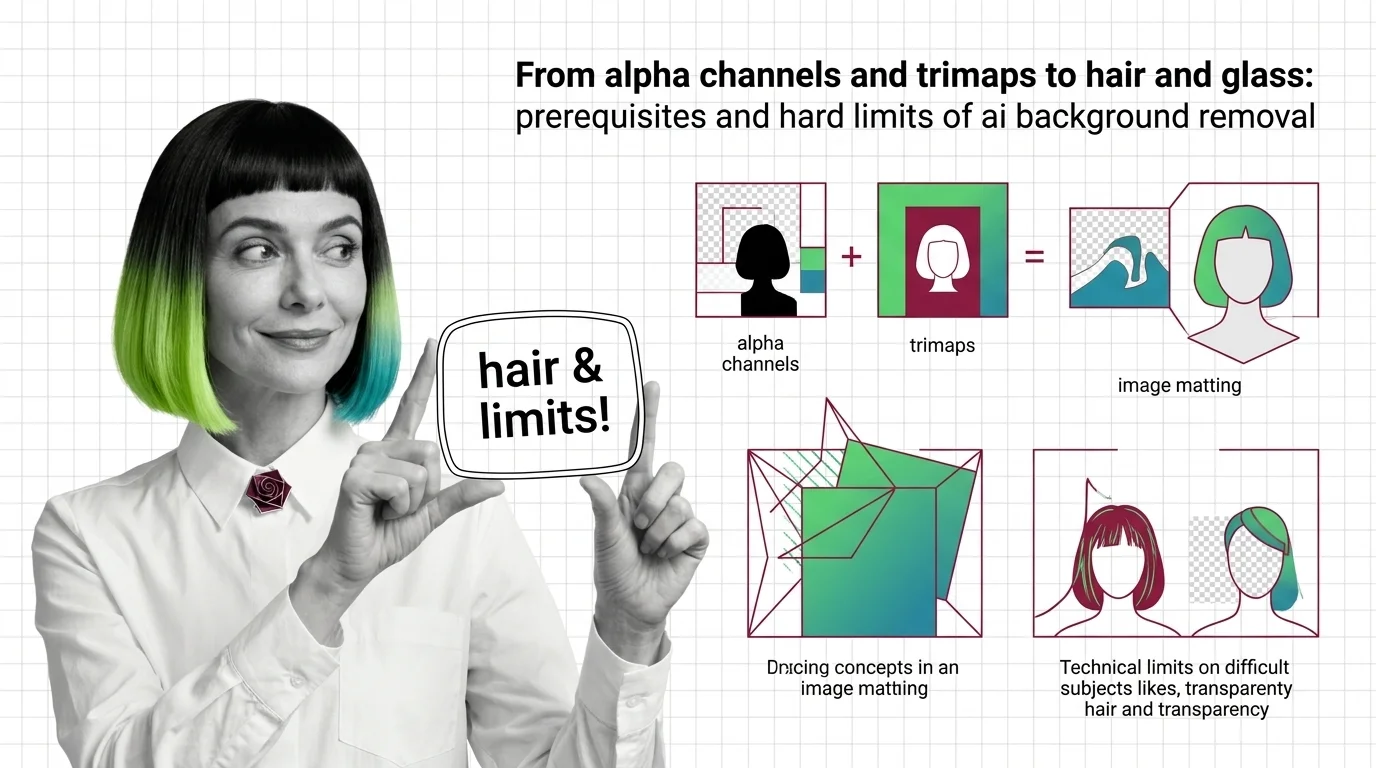
Alpha Channels, Trimaps, and the Hard Limits of AI Background Removal
Background removal is alpha estimation, not subject detection. Learn how trimaps and matting work, and why hair, glass, …
Negative Prompts, Weights, Seeds: Image Prompting Limits 2026
Negative prompts and weight syntax aren't universal — and seed reproducibility breaks across model versions. Inside the …
Prompt Engineering for Image Generation: How Diffusion Models Read Text
Image prompts steer probability, not pixels. Learn how diffusion models, cross-attention, and CFG turn text into images …
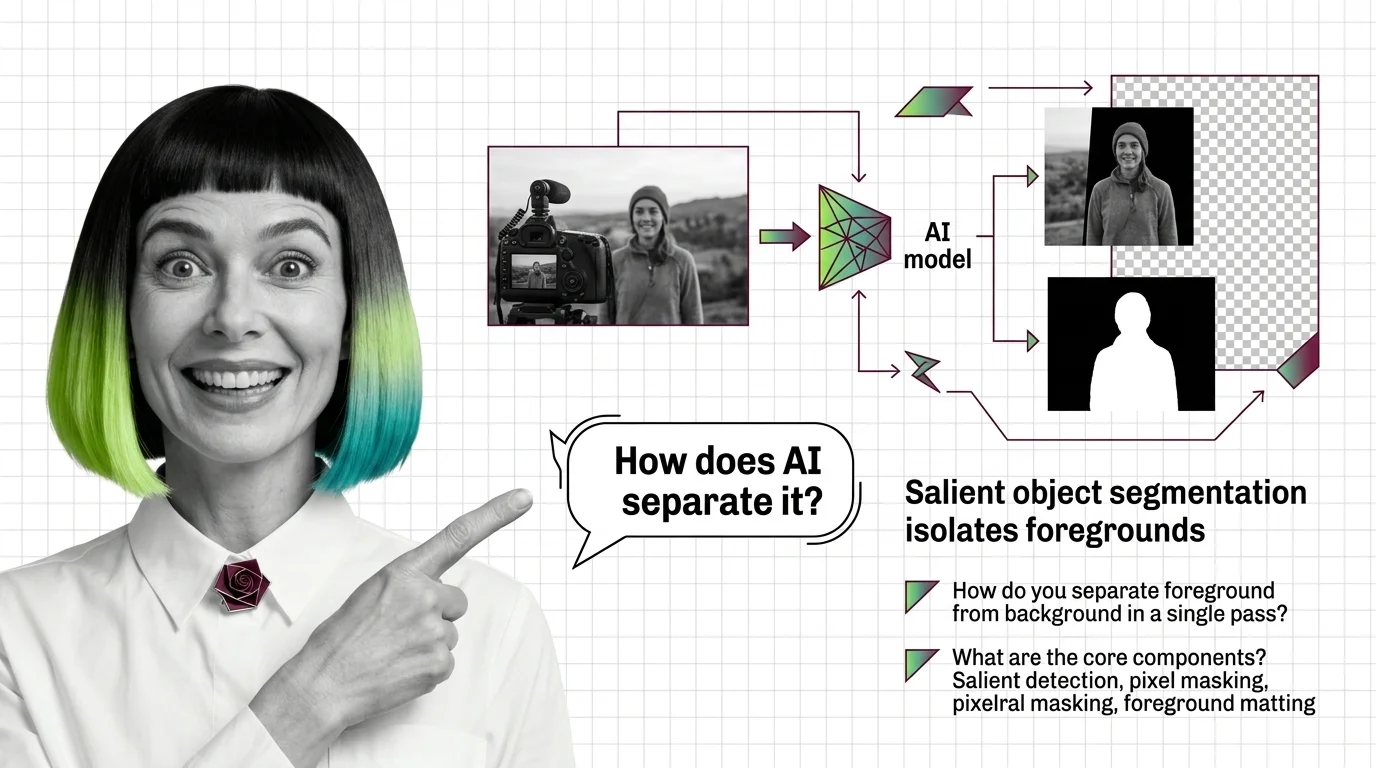
What Is AI Background Removal? How Salient Object Segmentation Works
AI background removal is not one model — it's salient object detection plus alpha matting. See how U2-Net, BiRefNet, and …
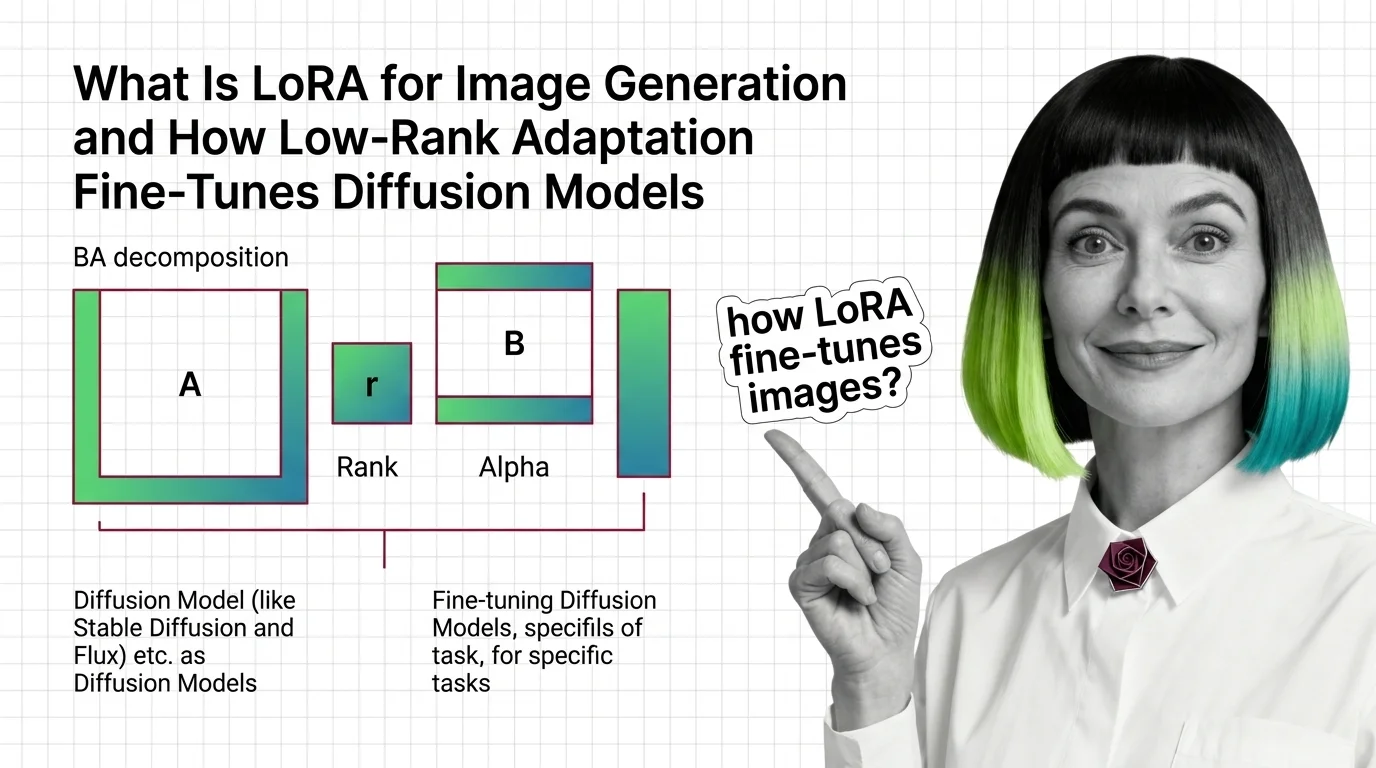
How LoRA Fine-Tunes Diffusion Models for Image Generation
LoRA fine-tunes Stable Diffusion and FLUX without retraining. Learn how rank, alpha, and the BA decomposition turn a …
From RRDB Blocks to Diffusion Priors: Inside Modern AI Upscalers
How modern AI upscalers are built — from ESRGAN's RRDB blocks and Real-ESRGAN to SUPIR's diffusion prior, plus the …
Training Image LoRAs: Diffusion Math, Rank-Alpha, and VRAM Limits
Image LoRAs retarget diffusion models with small adapter files. Learn the rank-alpha math, VRAM ranges from SD 1.5 to …
What Is Image Upscaling and How AI Super-Resolution Reconstructs Detail Beyond the Original Pixels
AI image upscaling doesn't enlarge what was captured — it generates plausible pixels from a learned prior. Learn how GAN …
Why AI Upscalers Hallucinate Faces and Tile Seams at 4K and 8K
AI upscalers don't break at 4K and 8K because of weak hardware. The failures are structural — rooted in diffusion priors …
From Diffusion to InstructPix2Pix: AI Image Editing Prerequisites
Before using GPT Image or FLUX, understand diffusion, classifier-free guidance, and why InstructPix2Pix made …
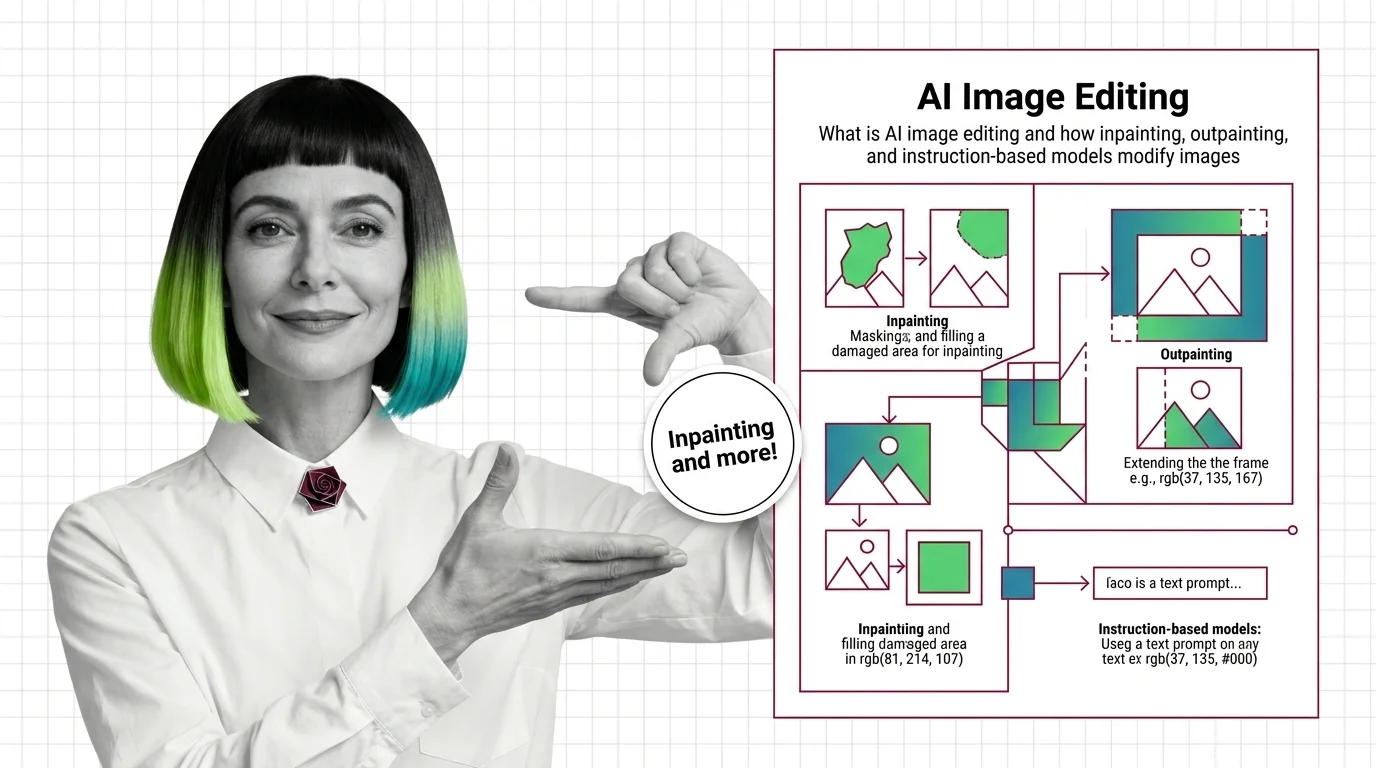
What Is AI Image Editing? Inpainting, Outpainting, Edit Models
AI image editing uses diffusion to modify pixels under a mask or follow text instructions. Learn how inpainting, …
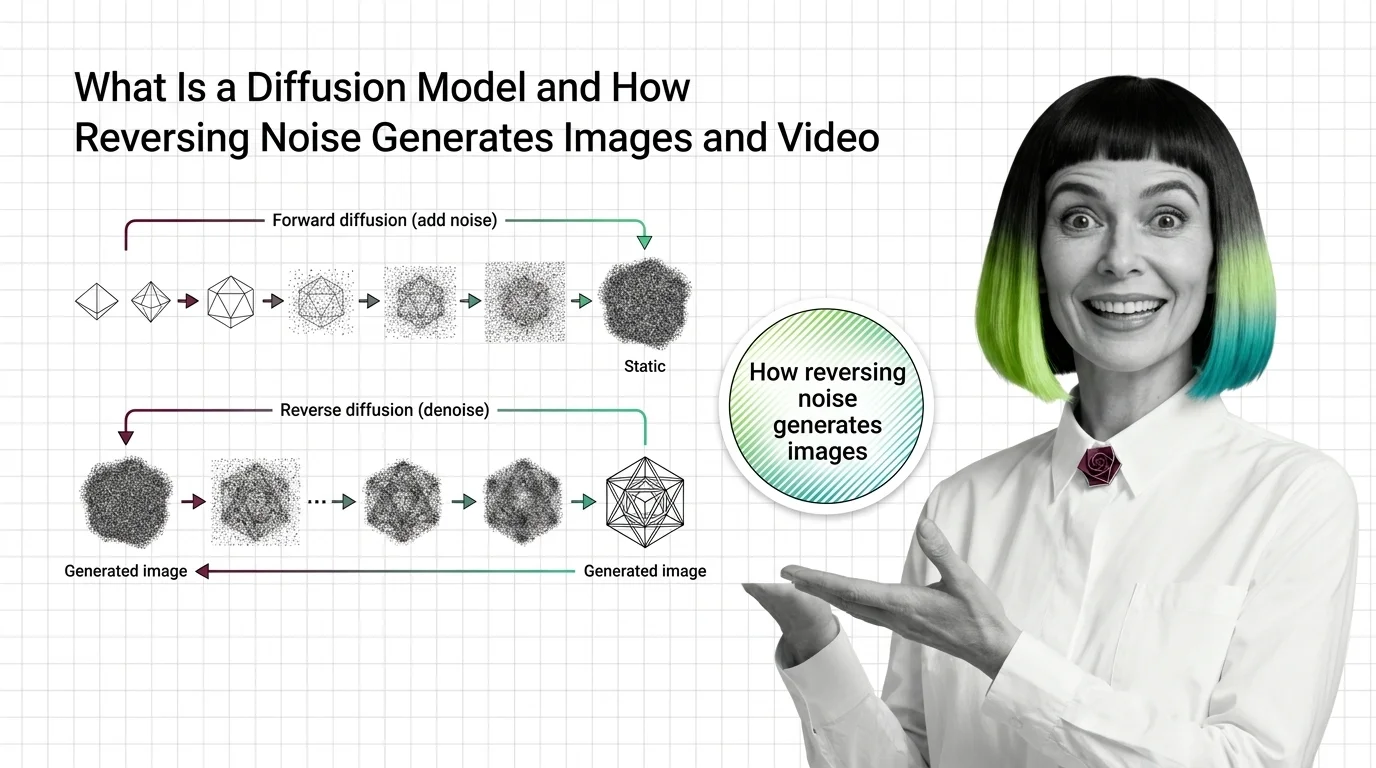
What Is a Diffusion Model? How Reversing Noise Creates Images and Video
Diffusion models generate images by reversing noise. Learn how forward and reverse processes differ, and why predicting …
Diffusion Models in 2026: Slow Sampling and Hard Engineering Limits
Why diffusion models still need many sampling steps, why FLUX and SD 3.5 stumble on text and hands, and where the 2026 …
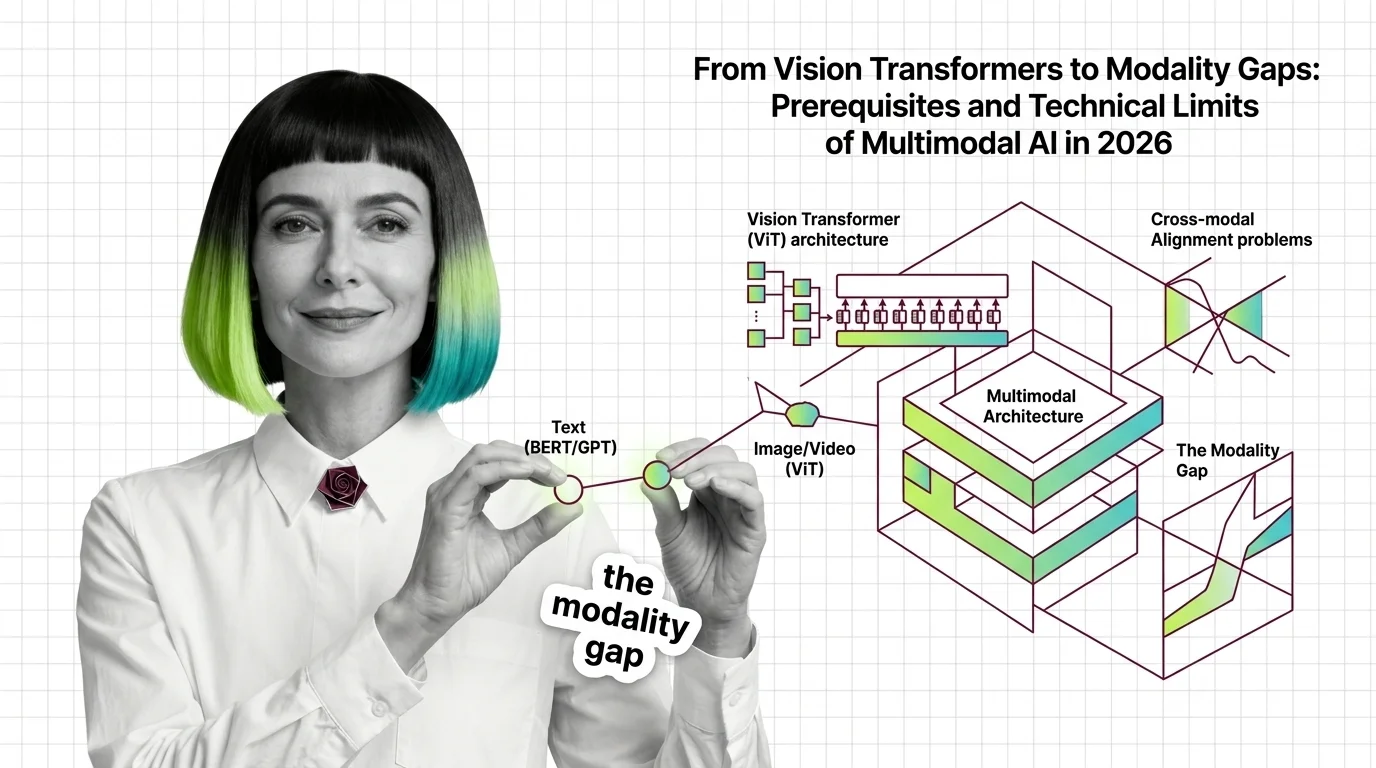
From Vision Transformers to Modality Gaps: Prerequisites and Technical Limits of Multimodal AI in 2026
Before multimodal AI works, vision transformers, modality gaps, and grounding decay define its limits. The mechanics of …
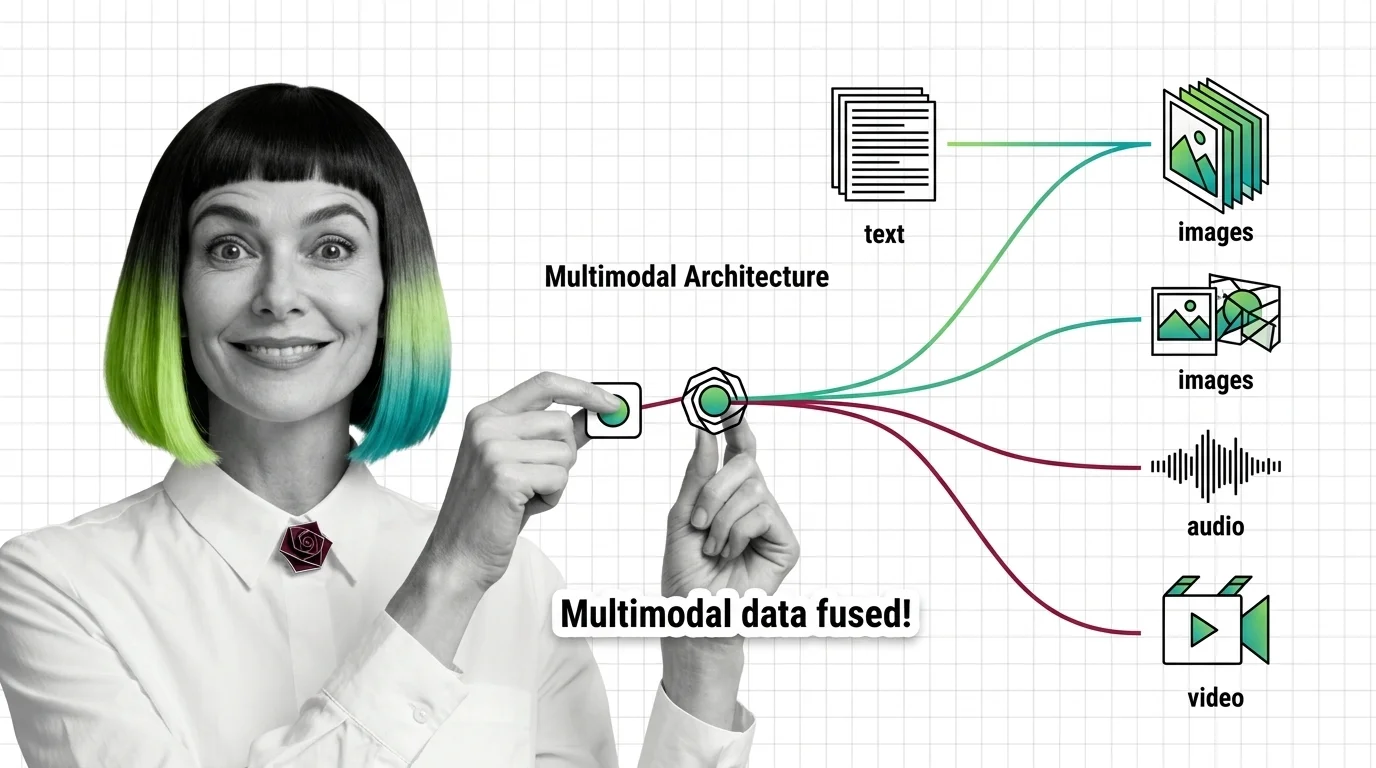
Multimodal Architecture: How Models Fuse Text, Images, Audio & Video
Multimodal models like GPT-5 and Gemini 3.1 Pro don't see images — they translate them into token space. Here's the …
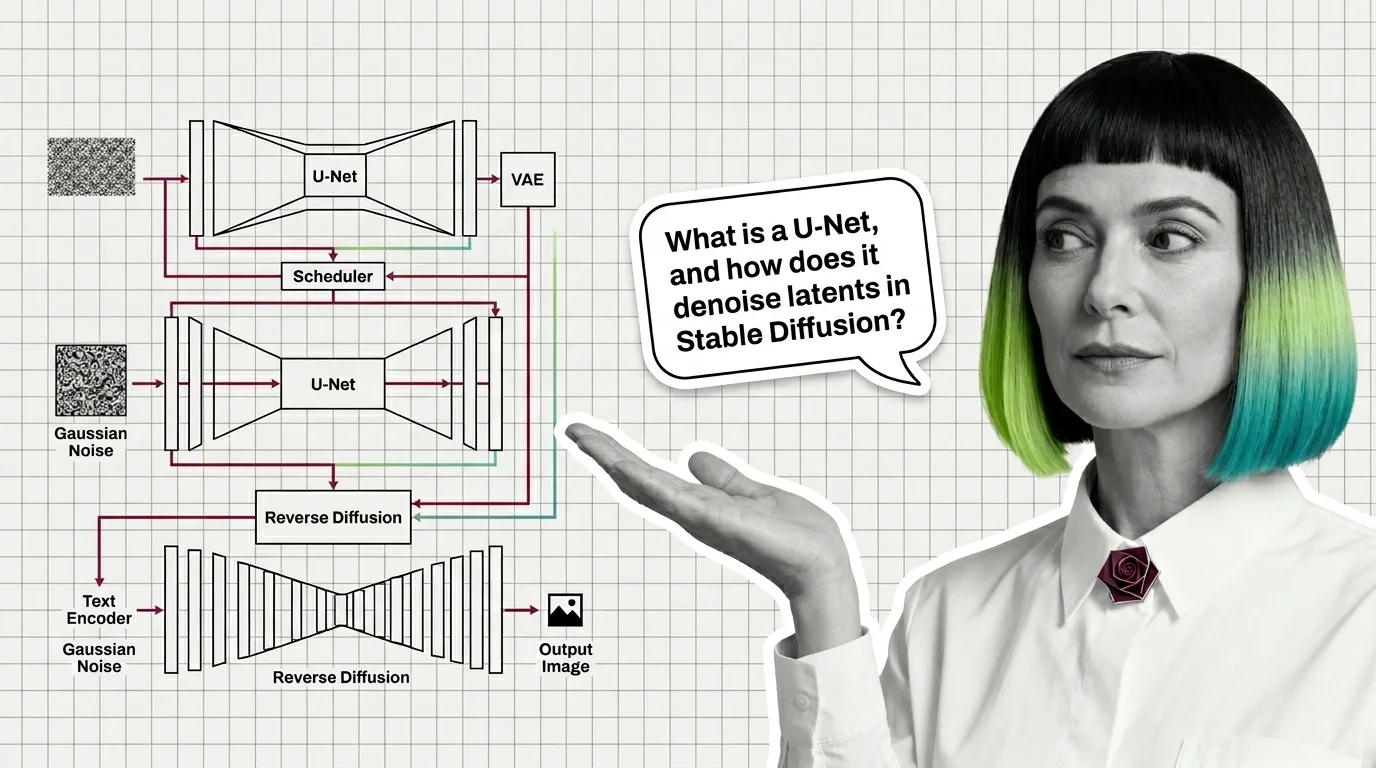
U-Net, VAE, Schedulers, and Text Encoders: The Anatomy of a Modern Diffusion Model
A modern diffusion model is not one network but four: a VAE for compression, a U-Net or DiT denoiser, a text encoder, …
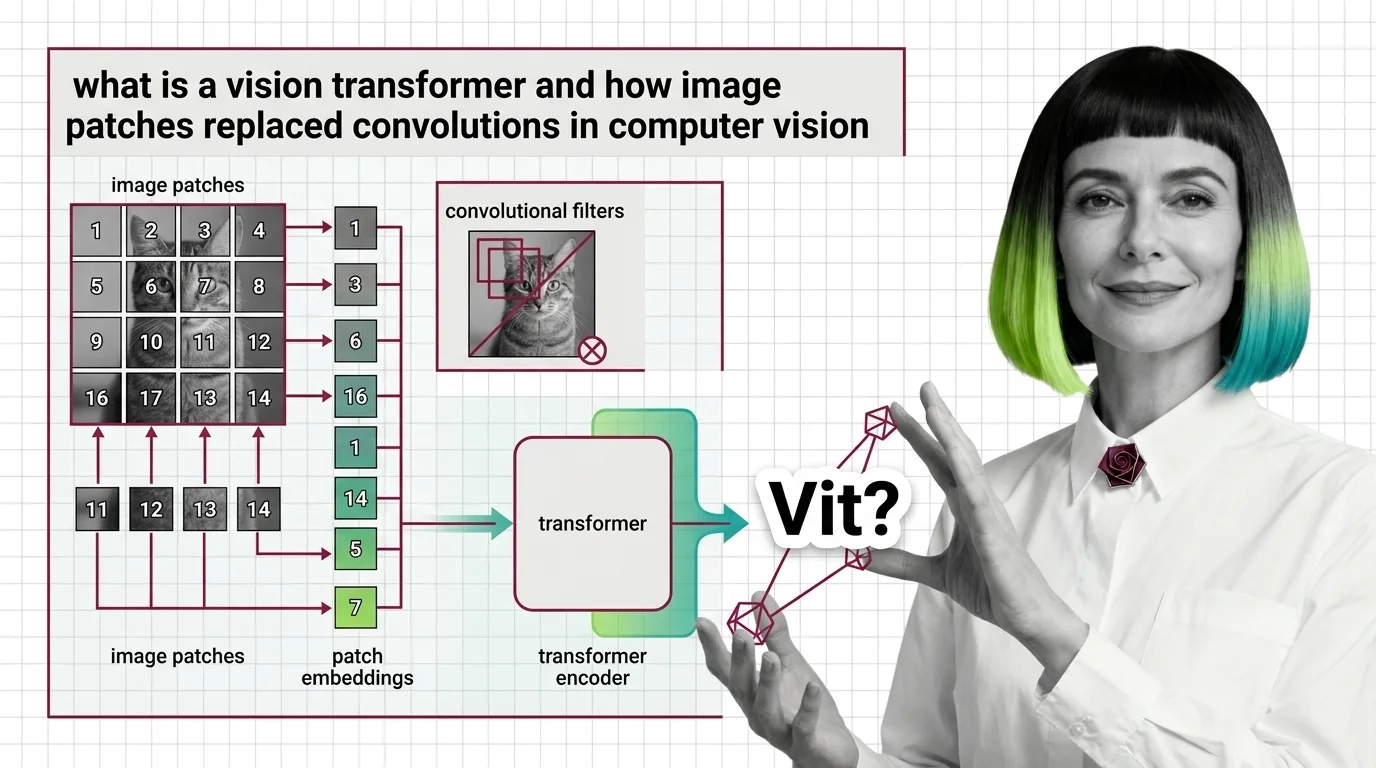
What Is a Vision Transformer and How Image Patches Replaced Convolutions in Computer Vision
Vision Transformers treat images as token sequences, not pixel grids. Learn how 16x16 patches, self-attention, and …
In-Context Learning Gaps, Hybrid Complexity, and the Hard Technical Limits of State Space Models
State space models trade recall for speed. Learn why pure Mamba breaks on in-context tasks and how hybrid SSM-attention …
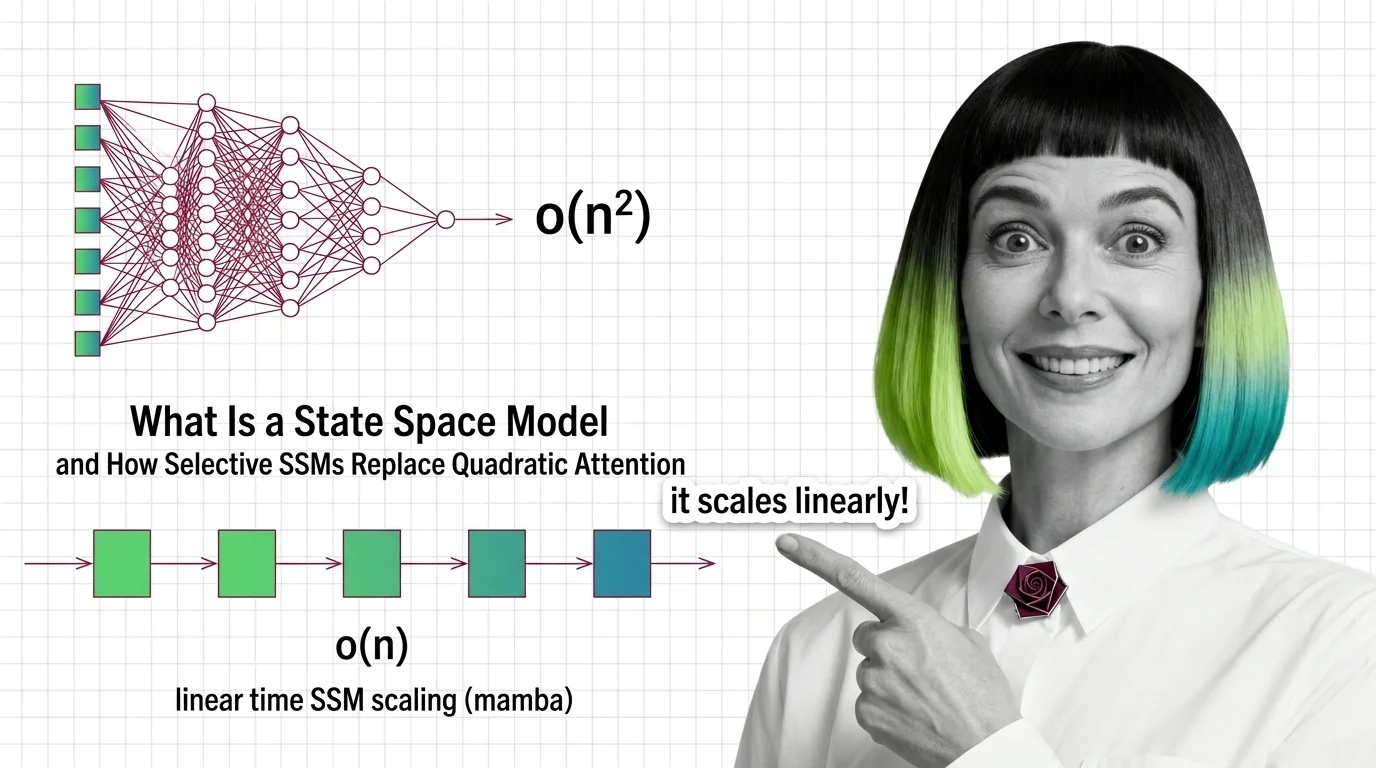
What Is a State Space Model and How Selective SSMs Replace Quadratic Attention
State space models trade quadratic attention for linear recurrence. See how Mamba's selection works and why long-context …
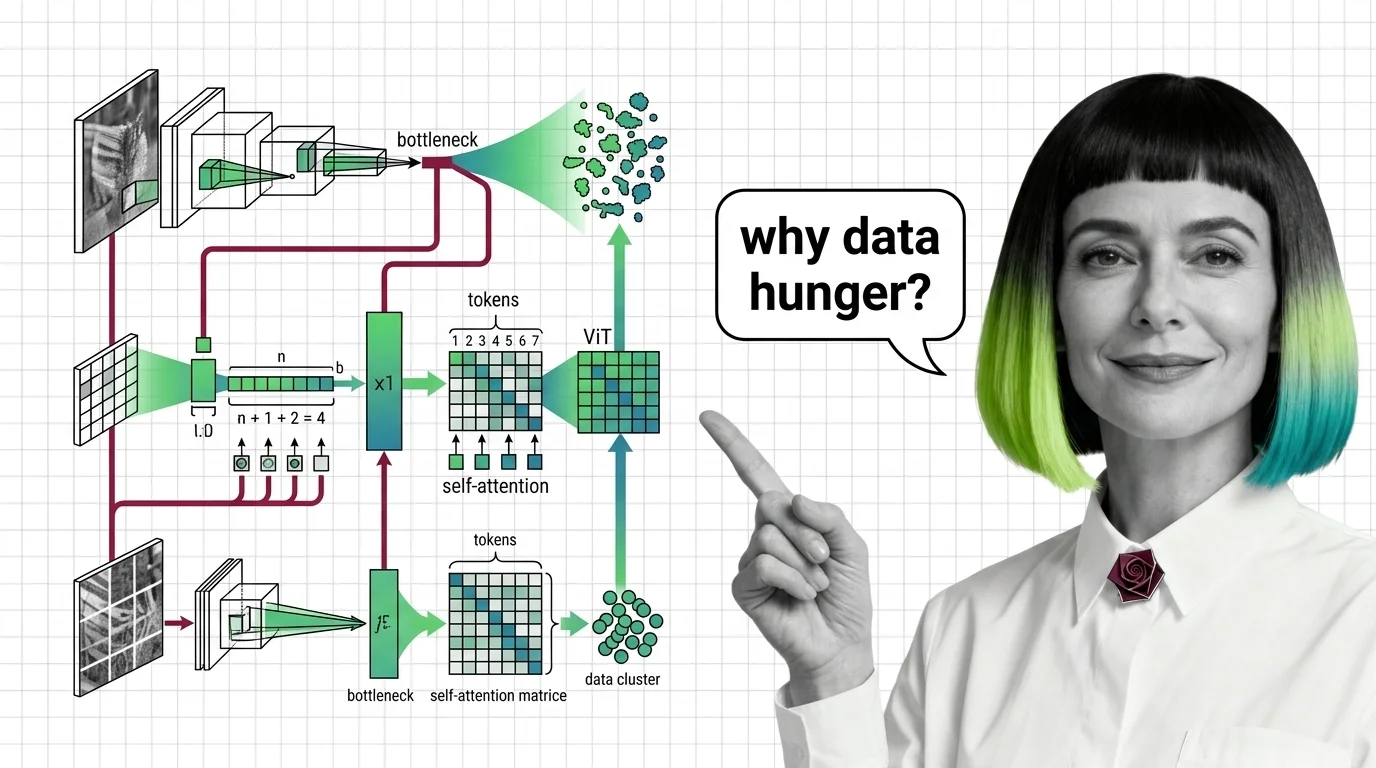
From CNN Intuition to Data Hunger: Prerequisites and Hard Limits of Vision Transformers
Vision Transformers drop CNN priors for learned attention — a trade that changes everything. Learn the prerequisites, …
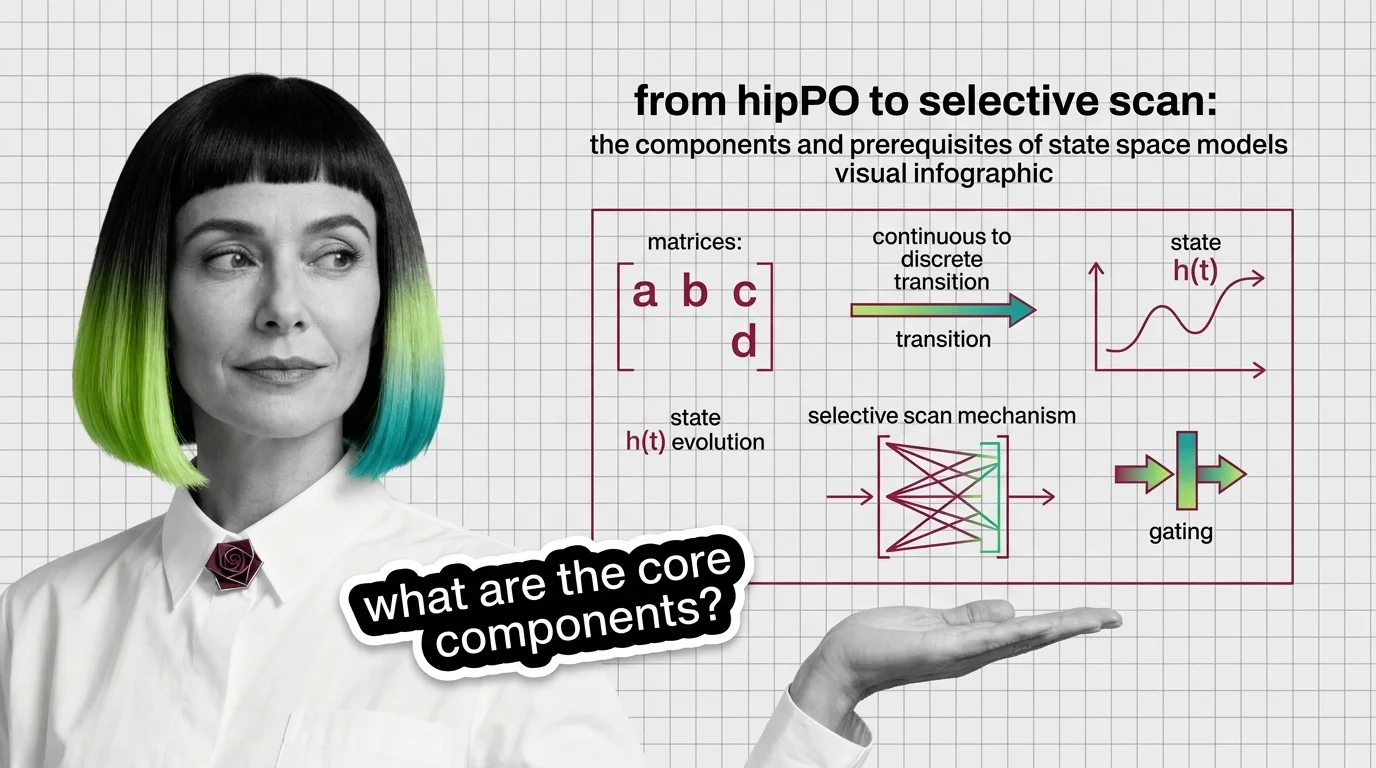
From HiPPO to Selective Scan: The Components and Prerequisites of State Space Models
State space models rebuilt recurrence on new math. Trace the components — HiPPO, S4, selective scan, gating — and the …
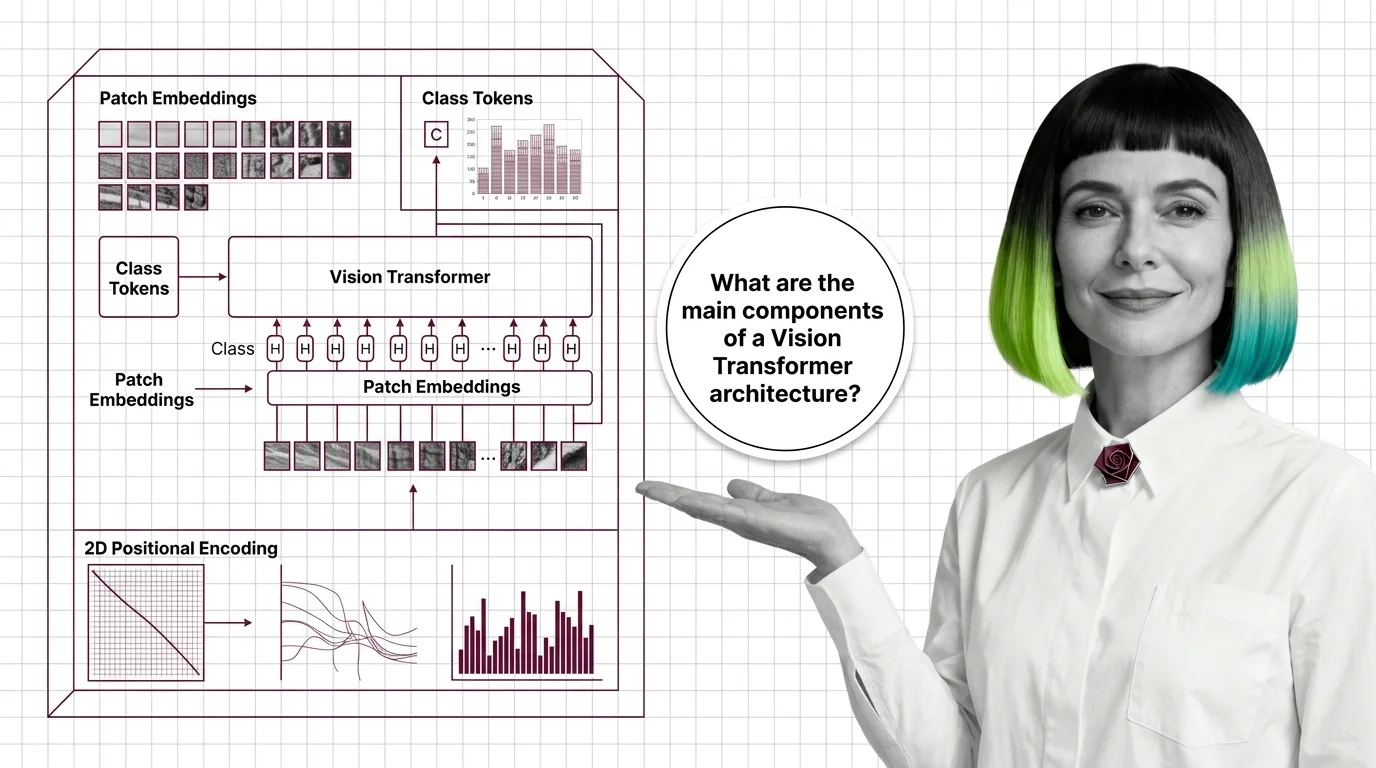
Patch Embeddings, Class Tokens, and 2D Positional Encoding: Inside the Vision Transformer
How Vision Transformers turn images into token sequences — inside patch embeddings, the CLS token, and the shift from 1D …
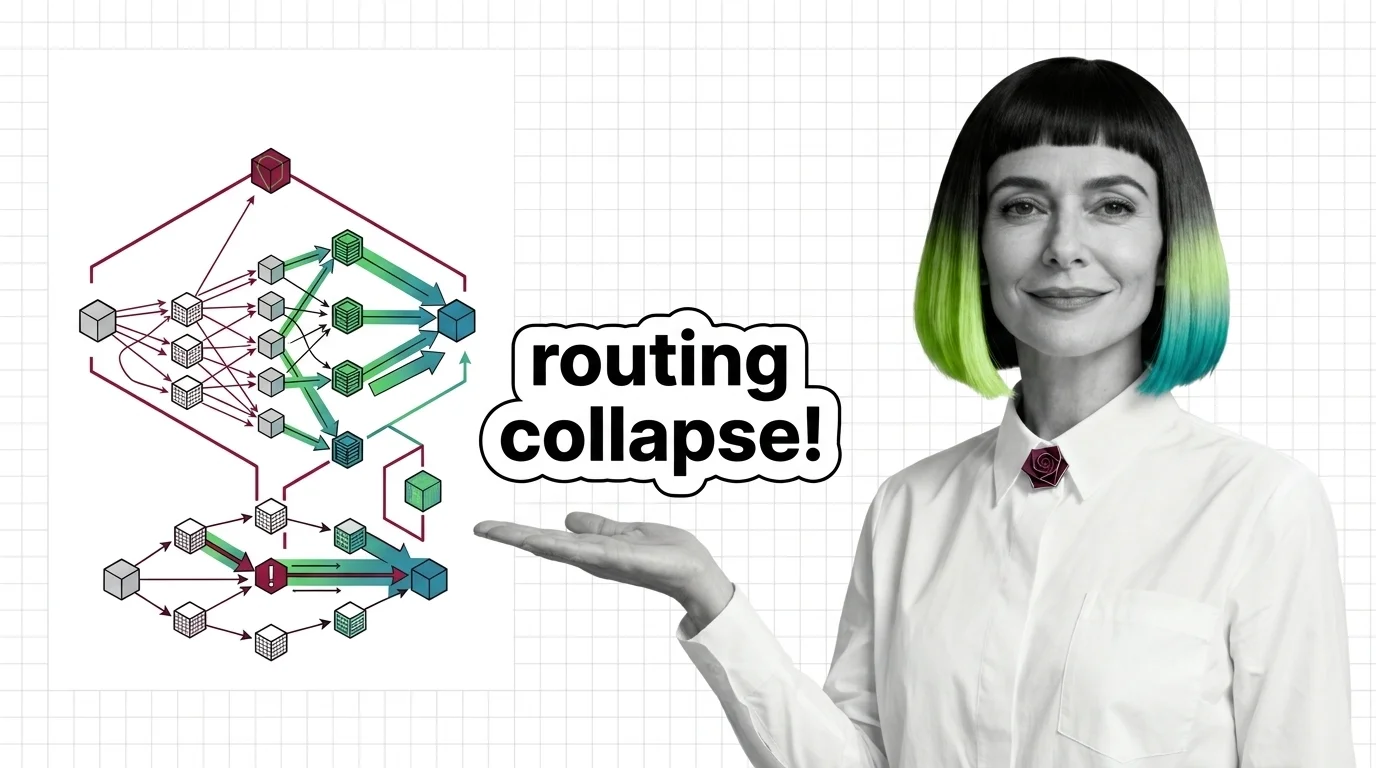
Routing Collapse, Load Balancing Failures, and the Hard Engineering Limits of Mixture of Experts
MoE models promise scale at fractional compute cost. Understand routing collapse, memory tradeoffs, and communication …
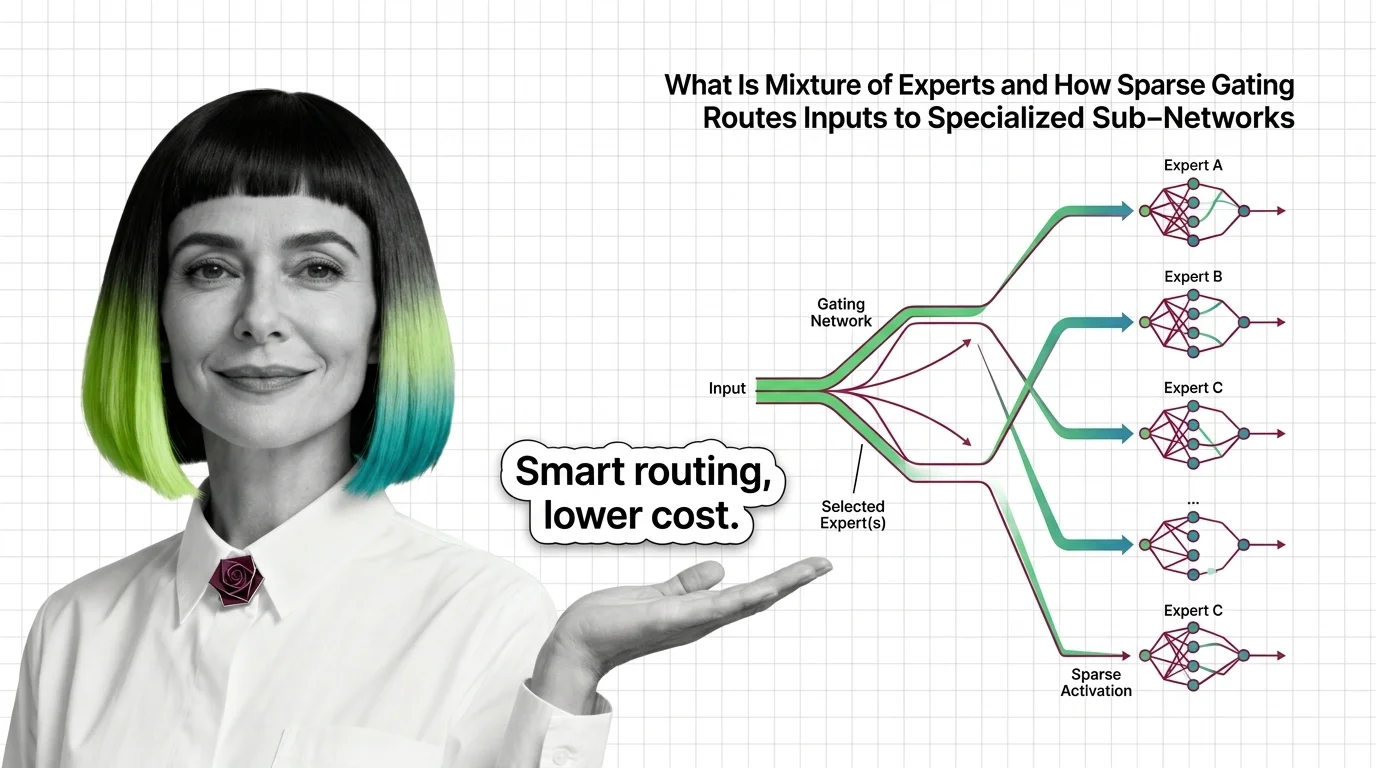
What Is Mixture of Experts and How Sparse Gating Routes Inputs to Specialized Sub-Networks
Mixture of experts activates only selected sub-networks per token. Learn how sparse gating makes trillion-parameter …
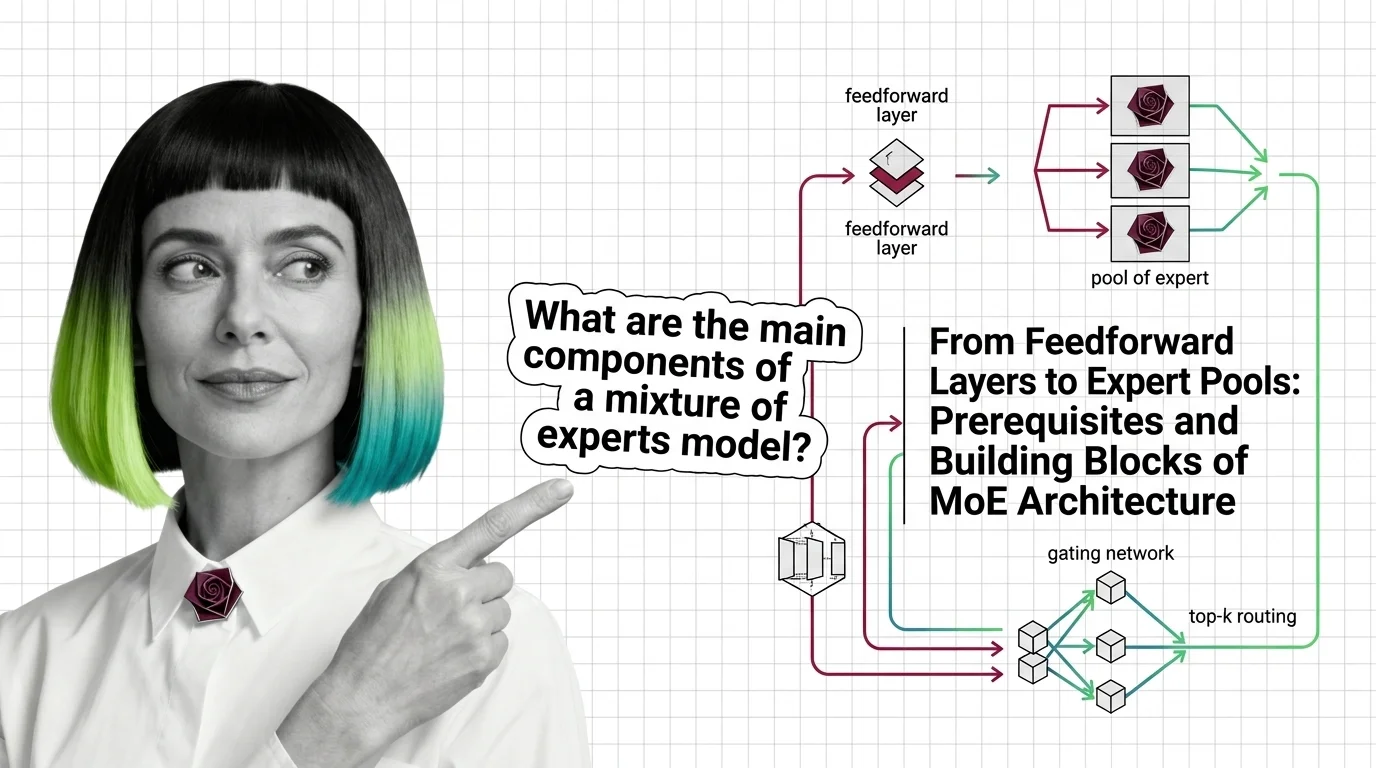
From Feedforward Layers to Expert Pools: Prerequisites and Building Blocks of MoE Architecture
Mixture of experts replaces one feedforward layer with many expert networks and a router. Learn how MoE gating and …
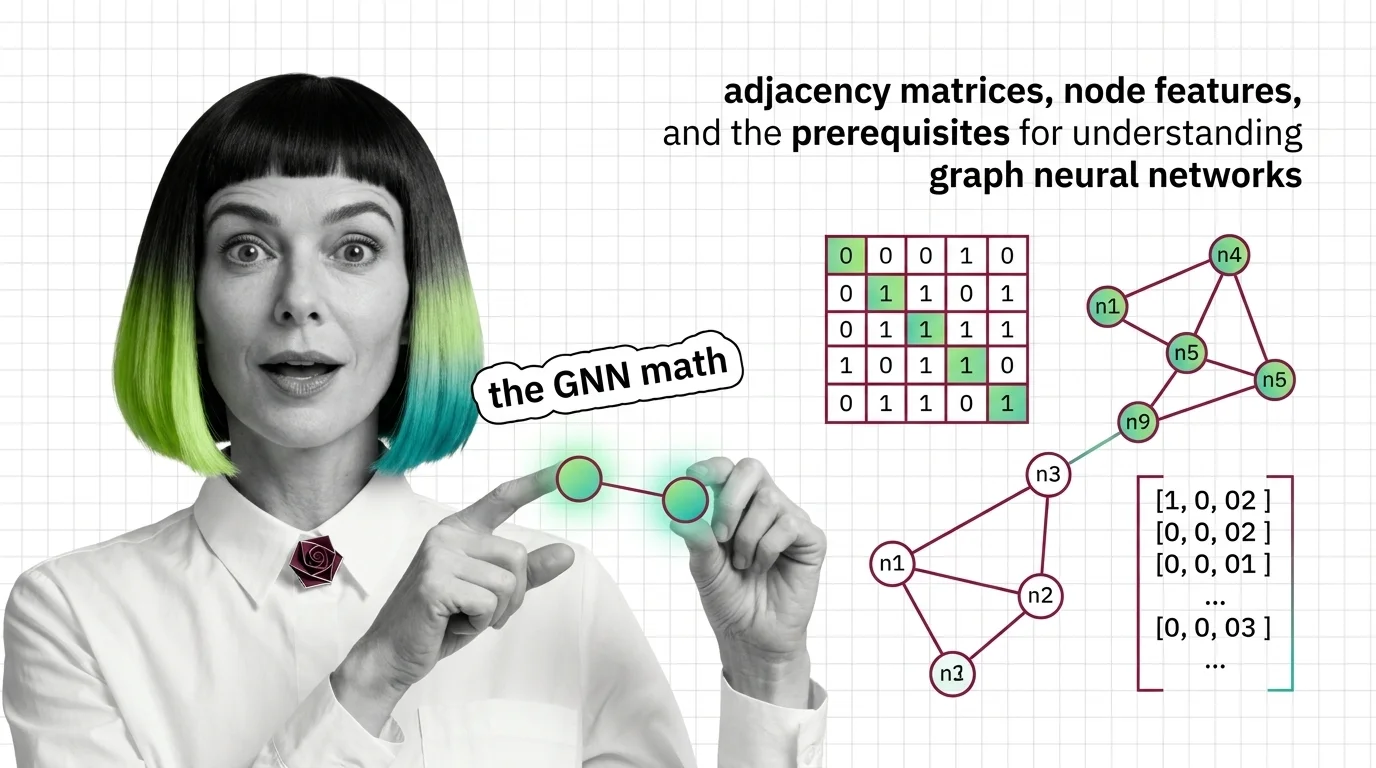
Adjacency Matrices, Node Features, and the Prerequisites for Understanding Graph Neural Networks
Graph neural networks consume matrices, not pixels. Learn how adjacency matrices, node features, and message passing …
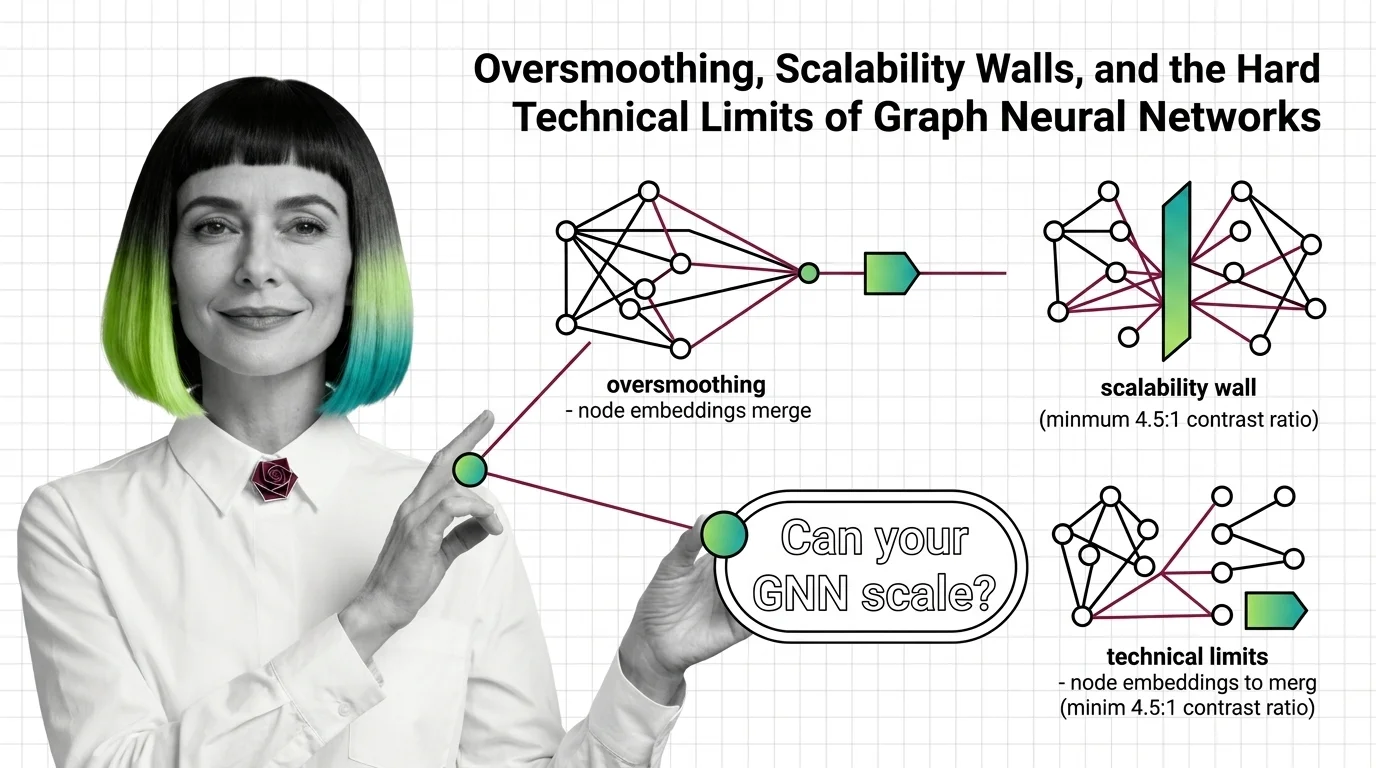
Oversmoothing, Scalability Walls, and the Hard Technical Limits of Graph Neural Networks
Oversmoothing and neighbor explosion set hard ceilings on graph neural network depth and scale. Learn the mathematical …
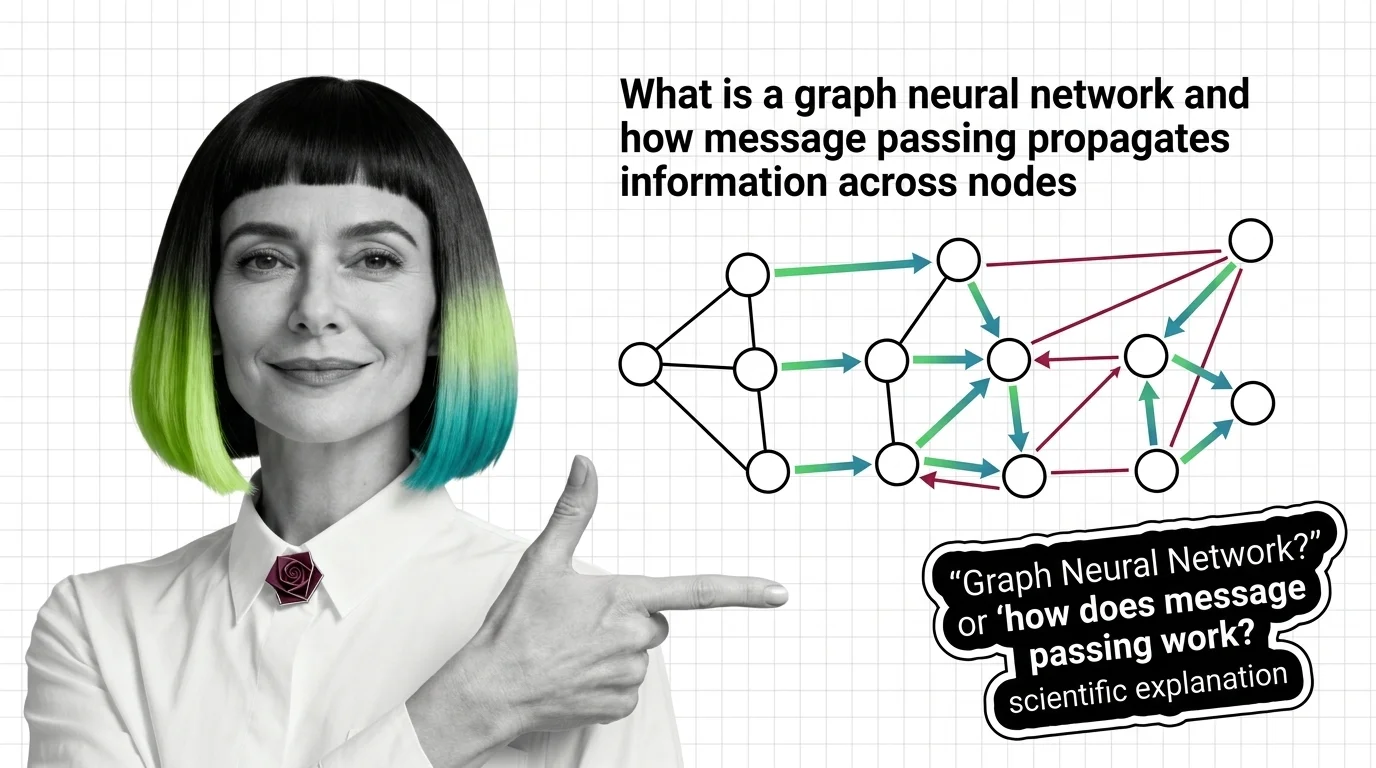
What Is a Graph Neural Network and How Message Passing Propagates Information Across Nodes
Graph neural networks learn from connections, not grids. Understand message passing, how graph convolution differs from …
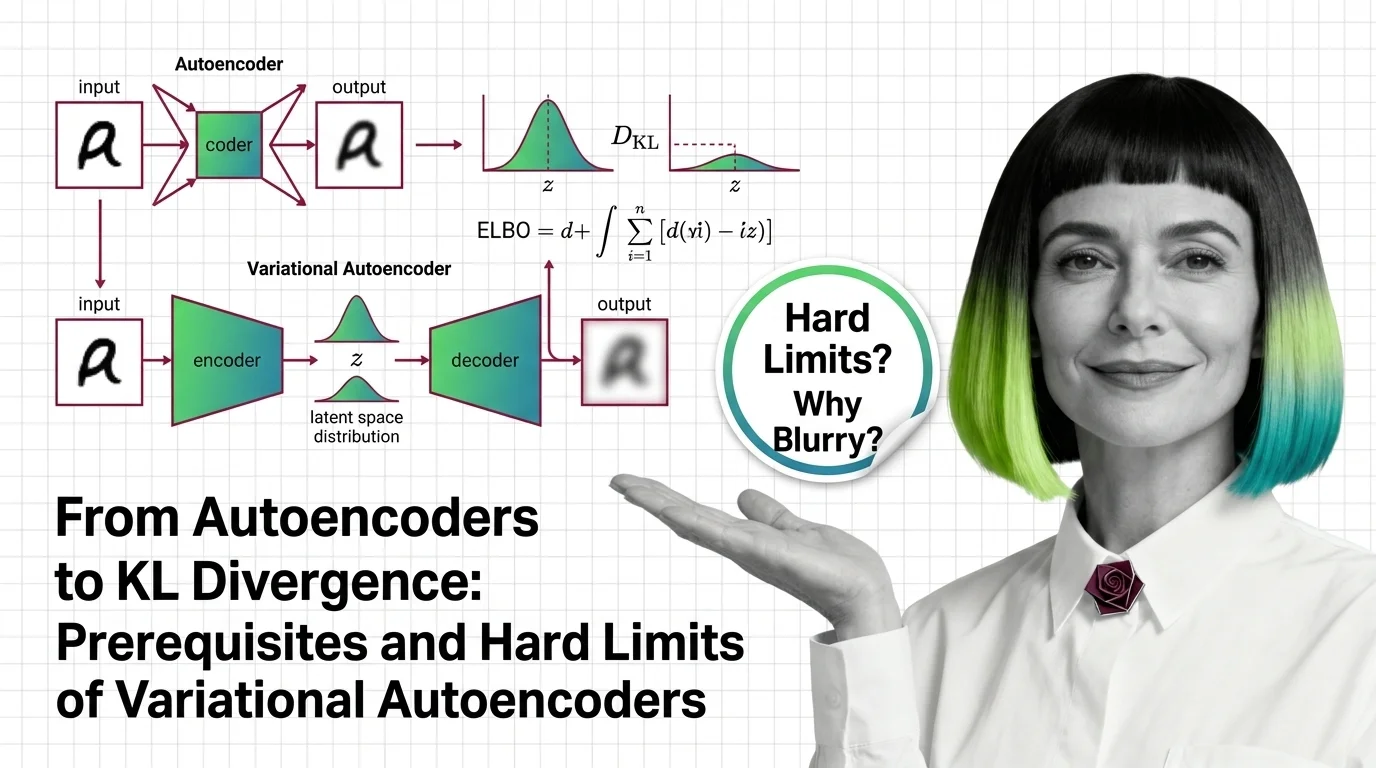
From Autoencoders to KL Divergence: Prerequisites and Hard Limits of Variational Autoencoders
Learn the math behind variational autoencoders — KL divergence, ELBO, the reparameterization trick — and why VAEs blur …
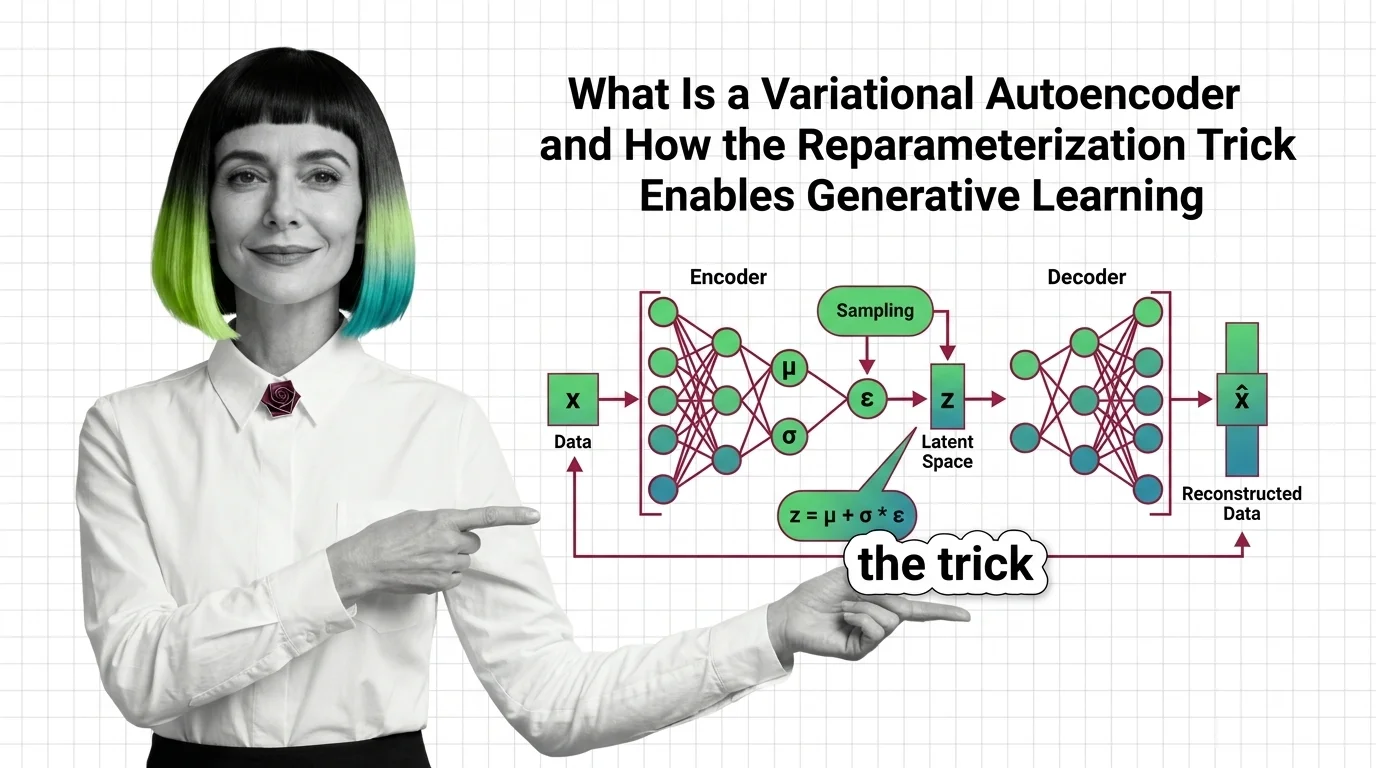
What Is a Variational Autoencoder and How the Reparameterization Trick Enables Generative Learning
VAEs compress data into structured probability spaces for generation. Learn how the reparameterization trick and ELBO …
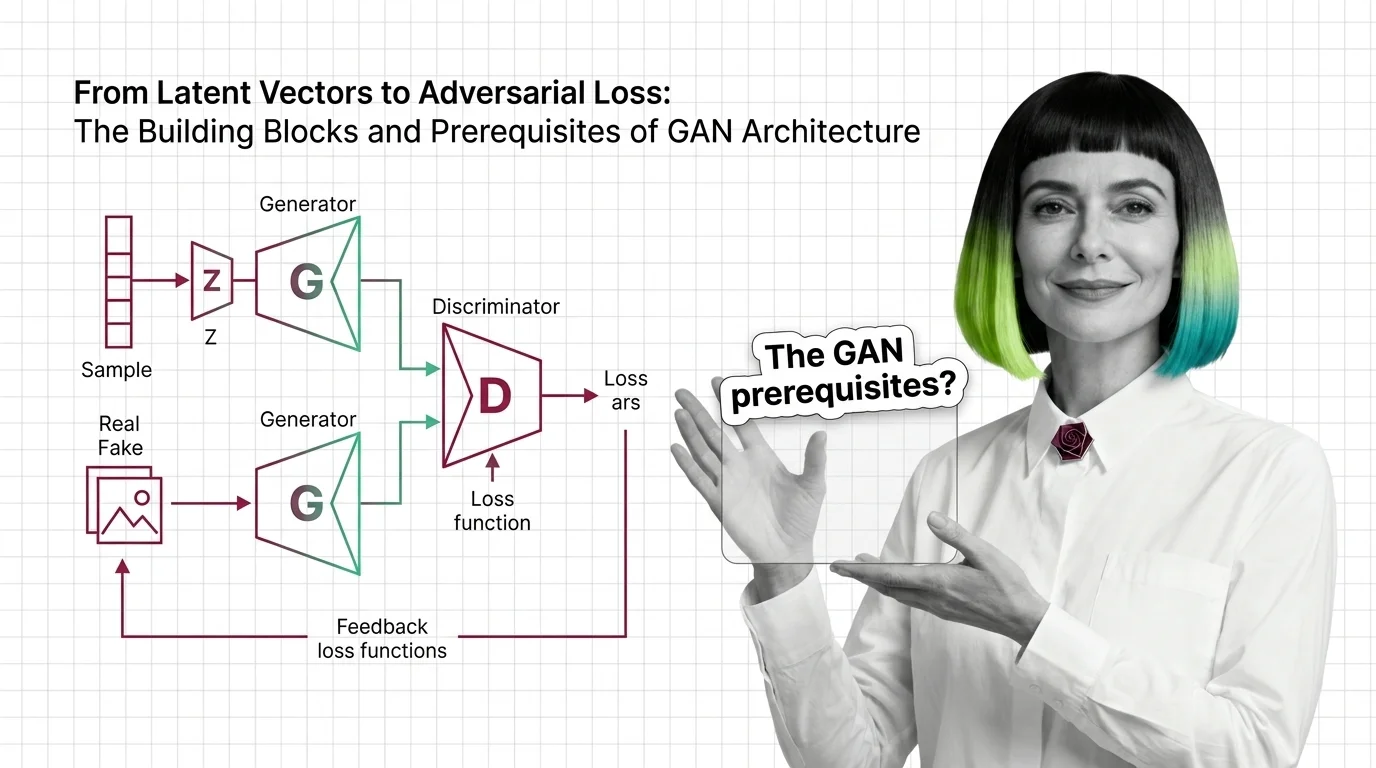
From Latent Vectors to Adversarial Loss: The Building Blocks and Prerequisites of GAN Architecture
Understand GAN architecture from the ground up: generator, discriminator, latent space, and the adversarial loss that …
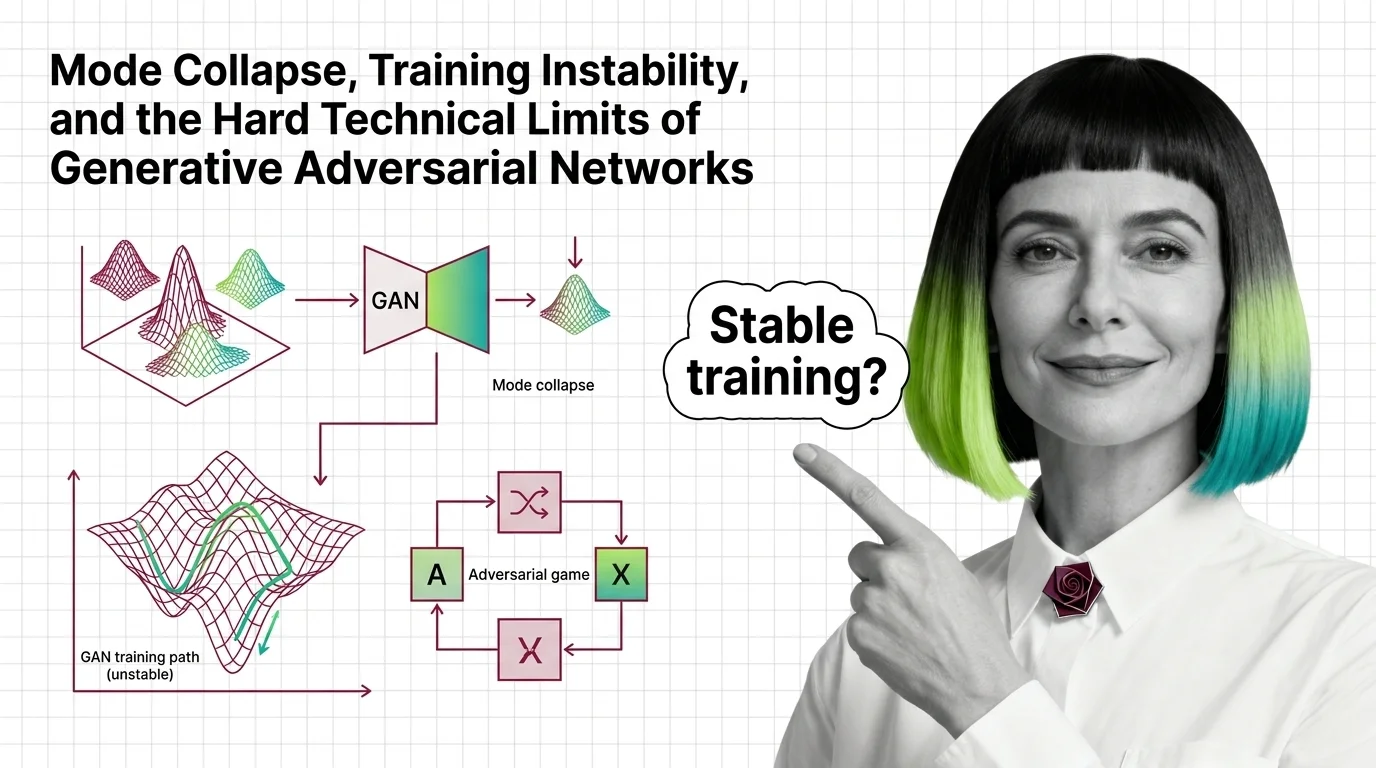
Mode Collapse, Training Instability, and the Hard Technical Limits of Generative Adversarial Networks
Mode collapse and training instability aren't GAN bugs — they're structural limits of adversarial training. Learn the …
Backpropagation Through Time, Vanishing Gradients, and Why Transformers Replaced Recurrent Networks
Gradients decay exponentially in recurrent networks during backpropagation through time. The eigenvalue math behind the …
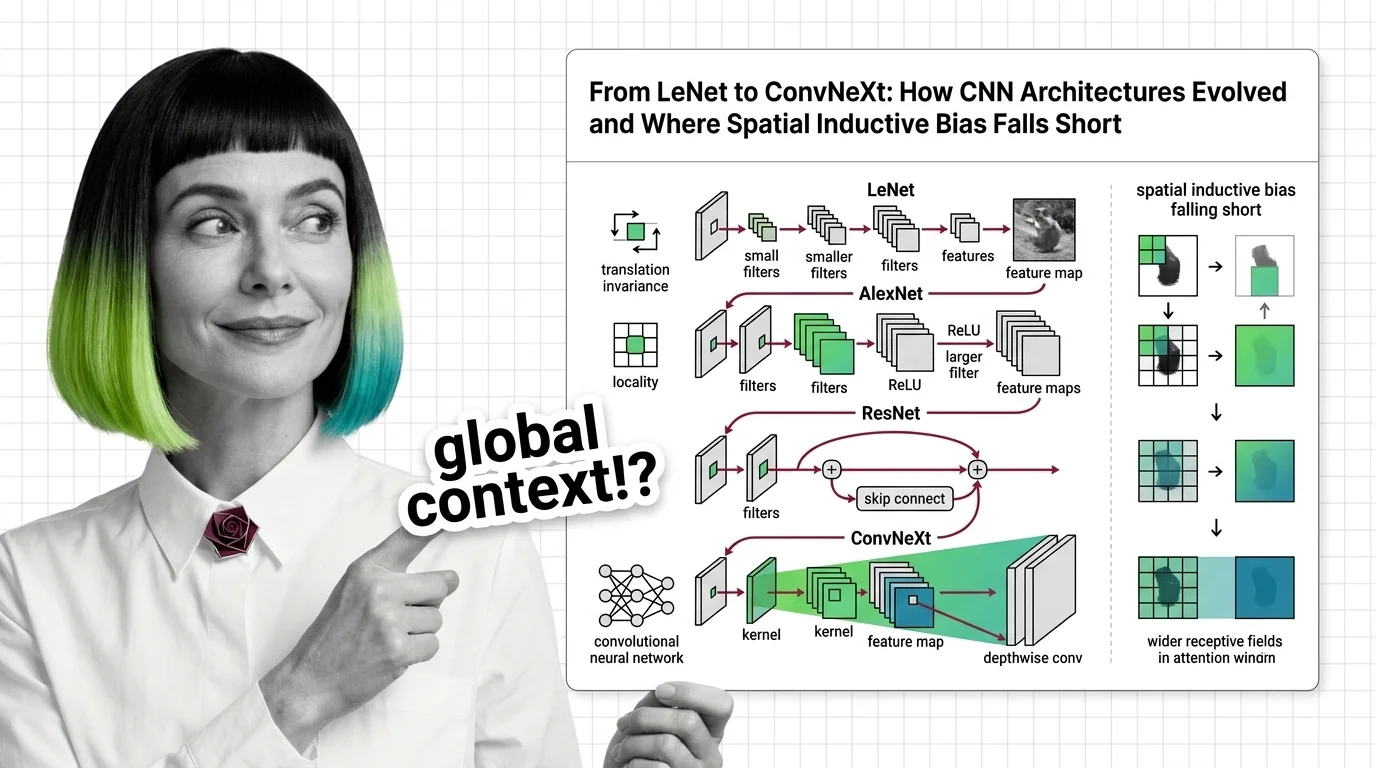
From LeNet to ConvNeXt: How CNN Architectures Evolved and Where Spatial Inductive Bias Falls Short
Trace CNN evolution from LeNet to ConvNeXt. Understand how spatial inductive bias enables efficient vision but limits …
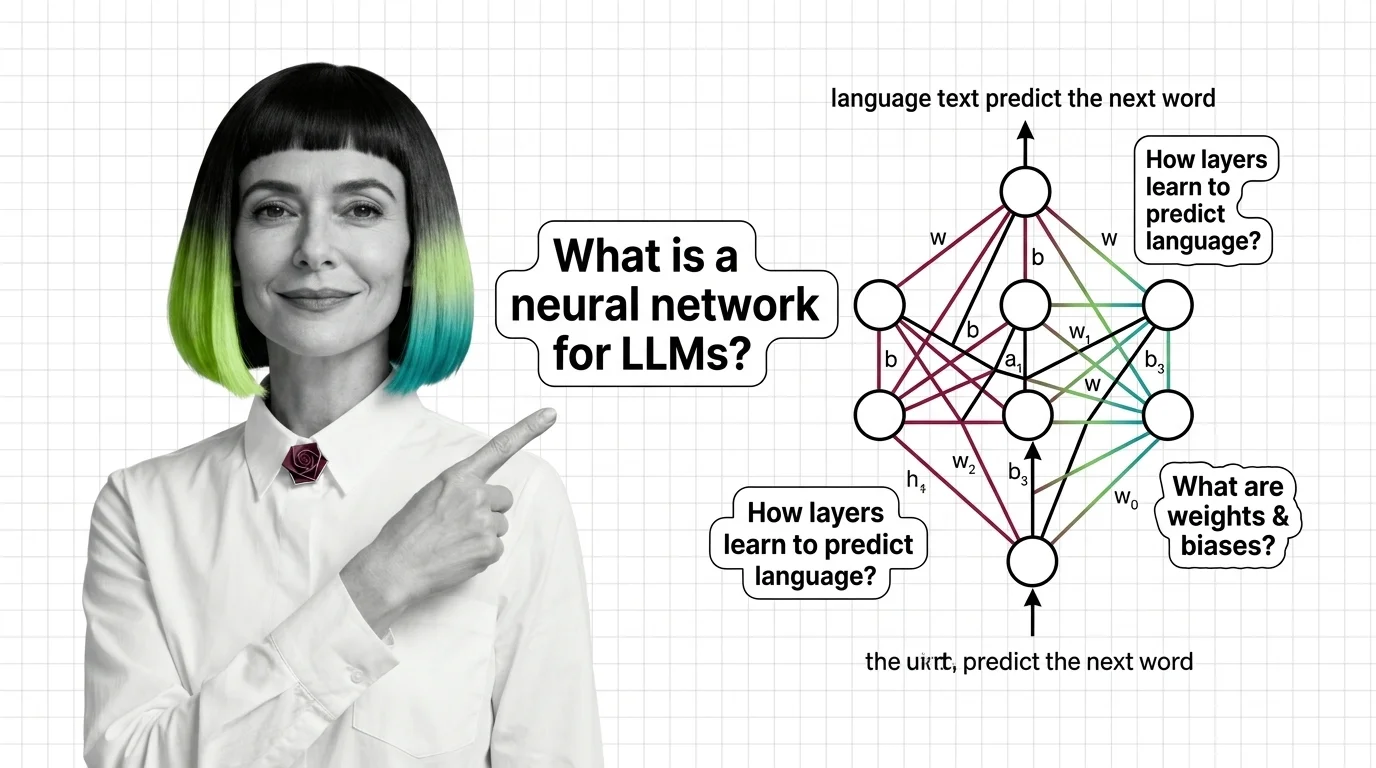
What Is a Neural Network and How It Learns to Generate Language
Neural networks learn language by adjusting millions of weights through backpropagation. Learn how layers, gradients, …
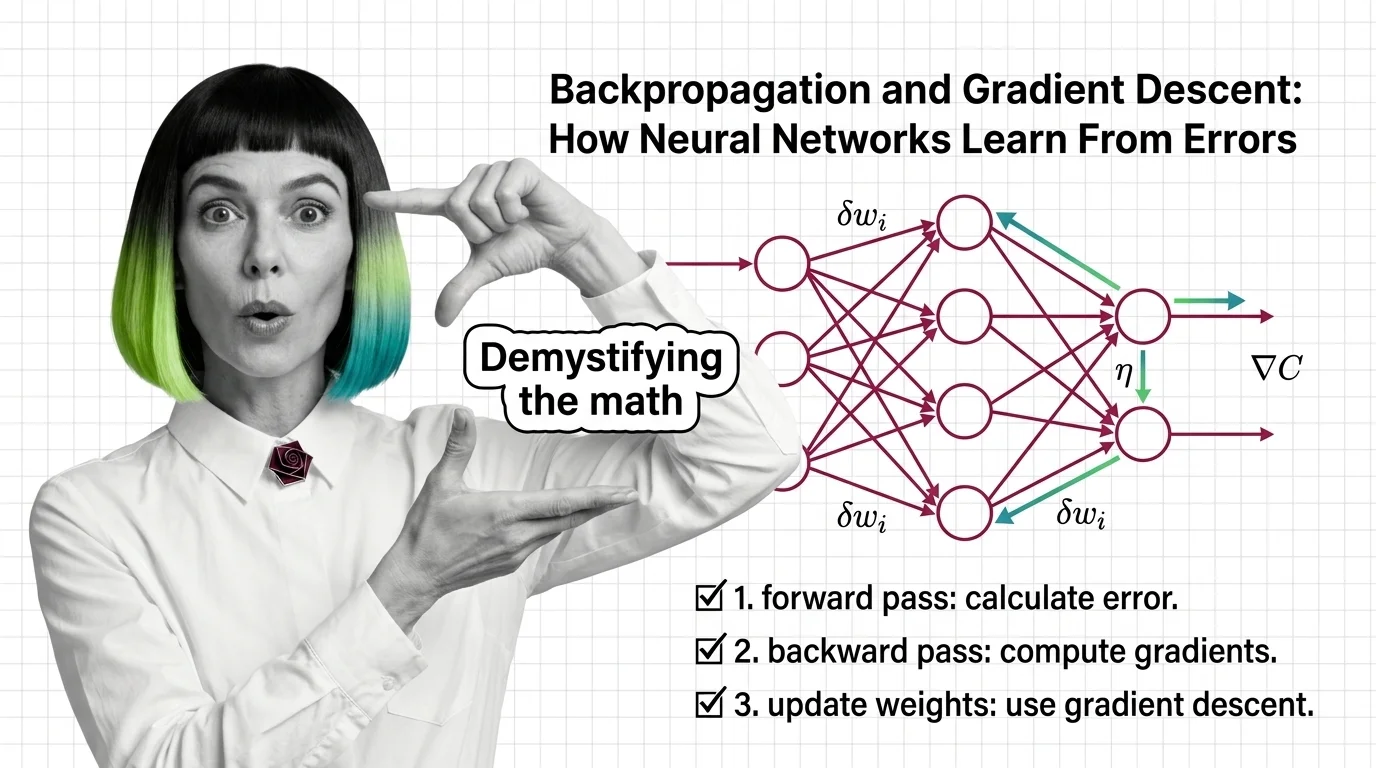
Backpropagation and Gradient Descent: How Neural Networks Learn From Errors
Learn how backpropagation and gradient descent train neural networks by propagating error signals backward through …
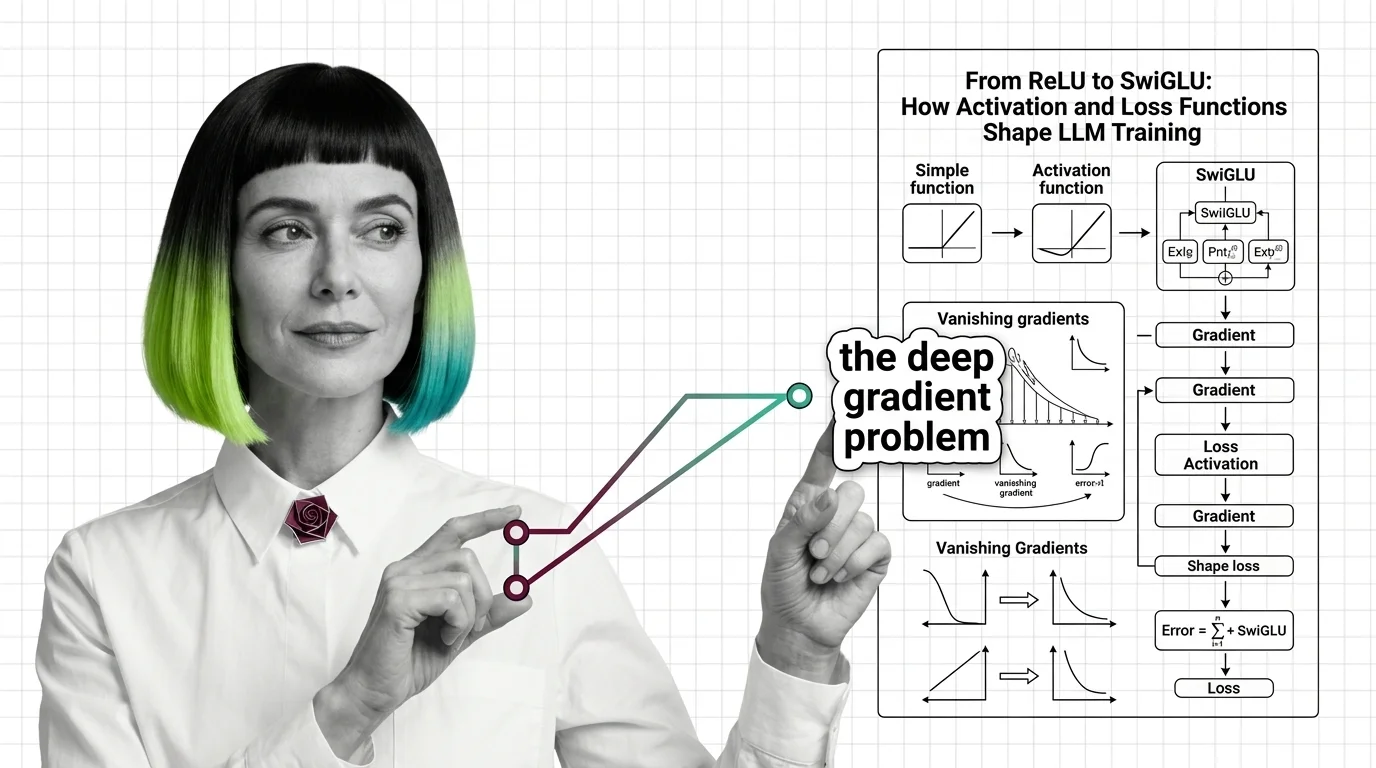
From ReLU to SwiGLU: How Activation and Loss Functions Shape LLM Training
Trace the path from ReLU to SwiGLU and understand how activation functions, cross-entropy loss, and gradient dynamics …
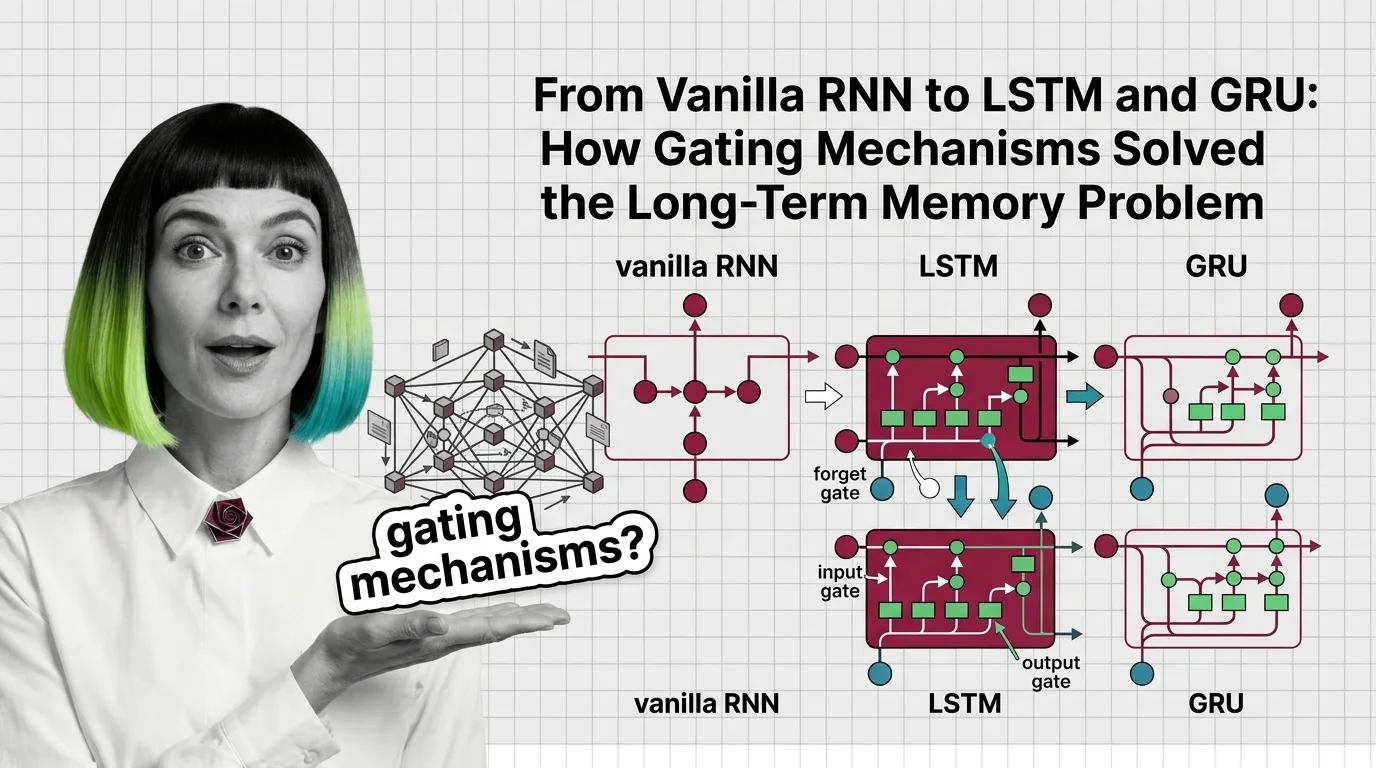
From Vanilla RNN to LSTM and GRU: How Gating Mechanisms Solved the Long-Term Memory Problem
Trace how LSTM forget, input, and output gates fix the vanishing gradient problem that crippled vanilla RNNs, and how …
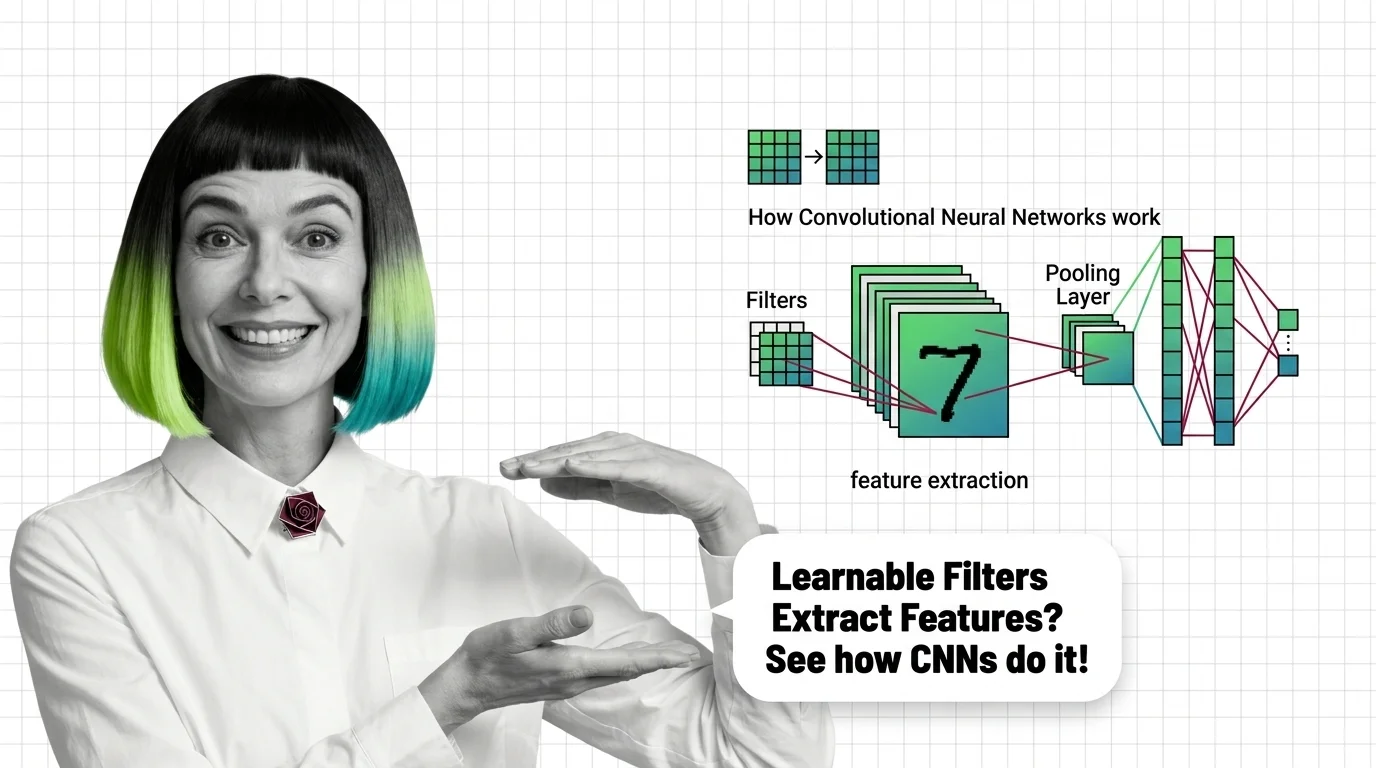
What Is a Convolutional Neural Network and How Learnable Filters Extract Visual Features
Convolutional neural networks detect visual features through learnable filters, not pixel matching. Understand the …
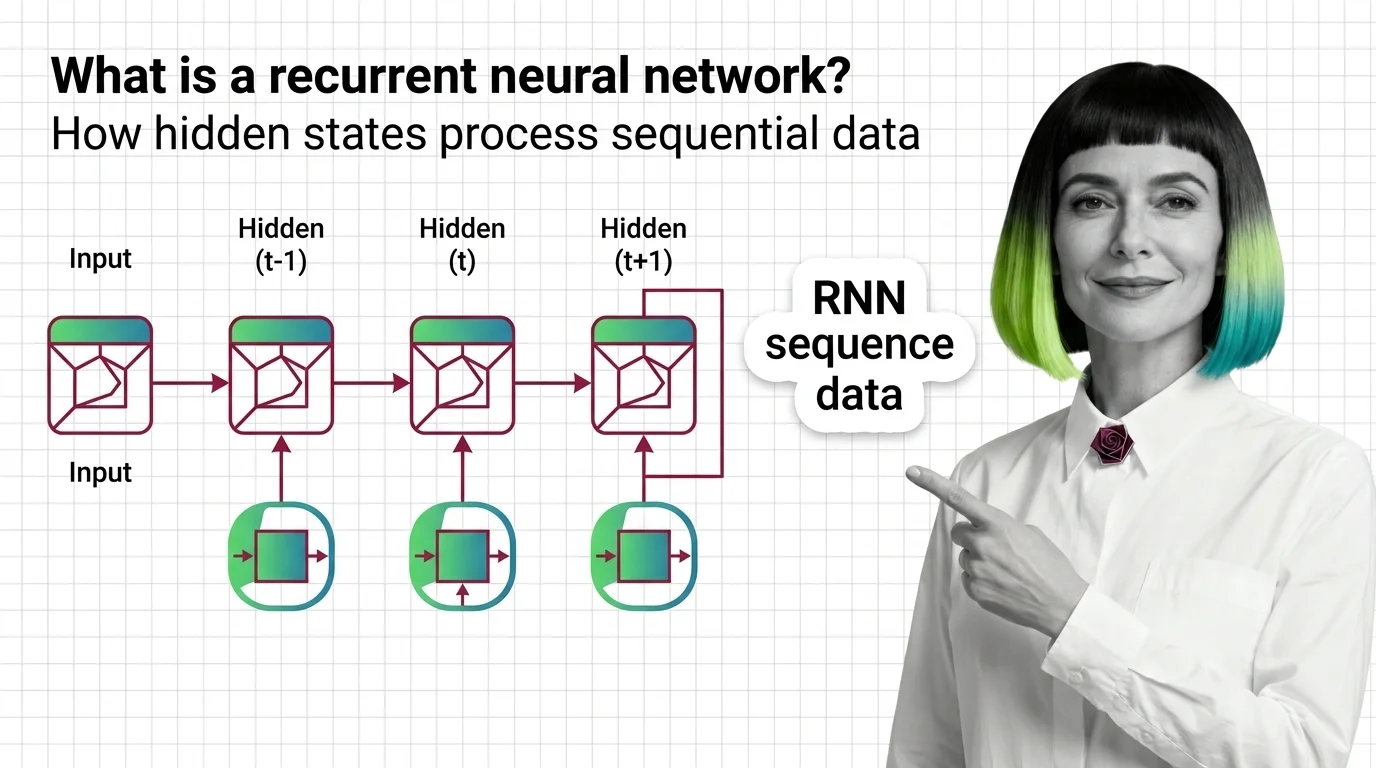
What Is a Recurrent Neural Network and How Hidden States Process Sequential Data
RNNs use hidden states to carry memory across time steps. Learn how recurrent neural networks process sequences, why …
Benchmark Contamination: N-Gram Overlap and Hard Limits
Benchmark contamination and overfitting look identical in scores. Understand what n-gram overlap, deduplication, and …
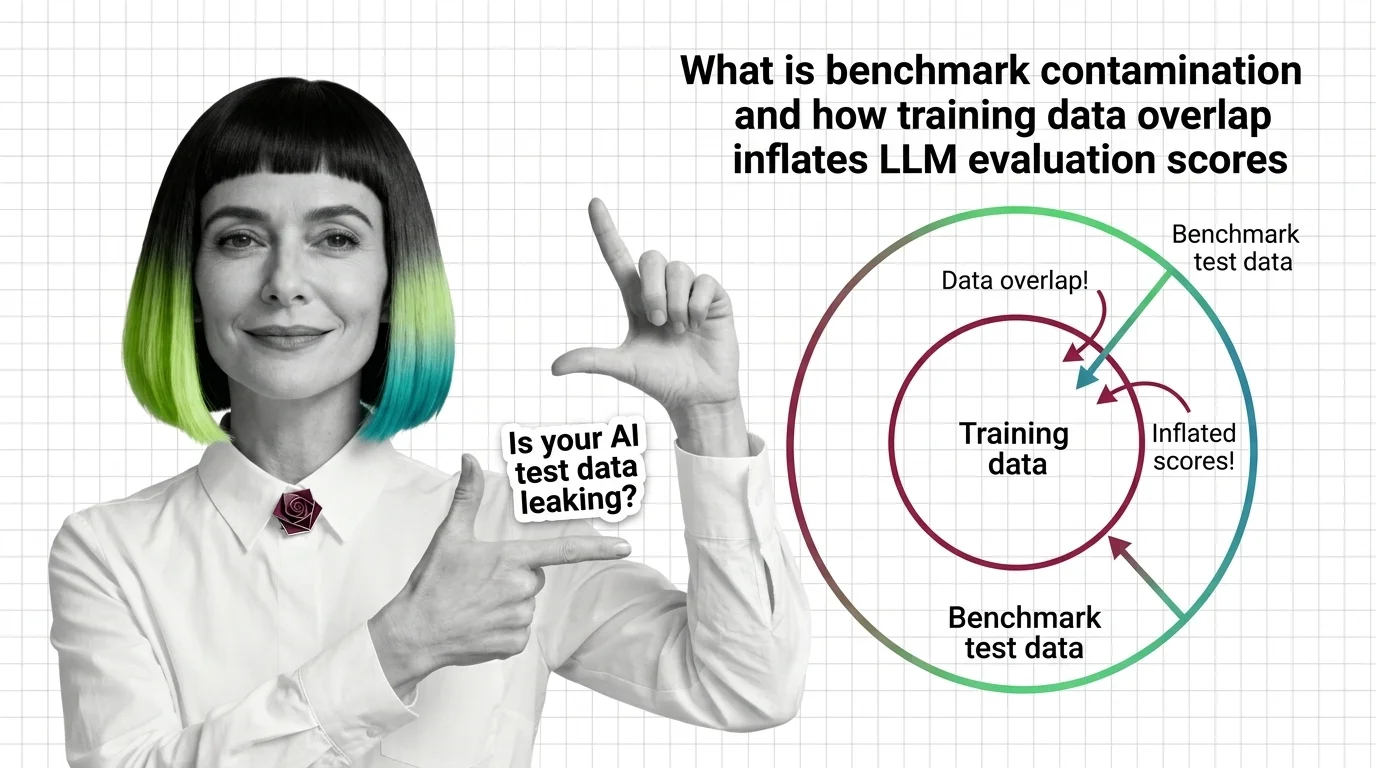
What Is Benchmark Contamination and How Training Data Overlap Inflates LLM Evaluation Scores
Benchmark contamination inflates LLM scores when training data overlaps with test sets. Learn how data leaks in and why …
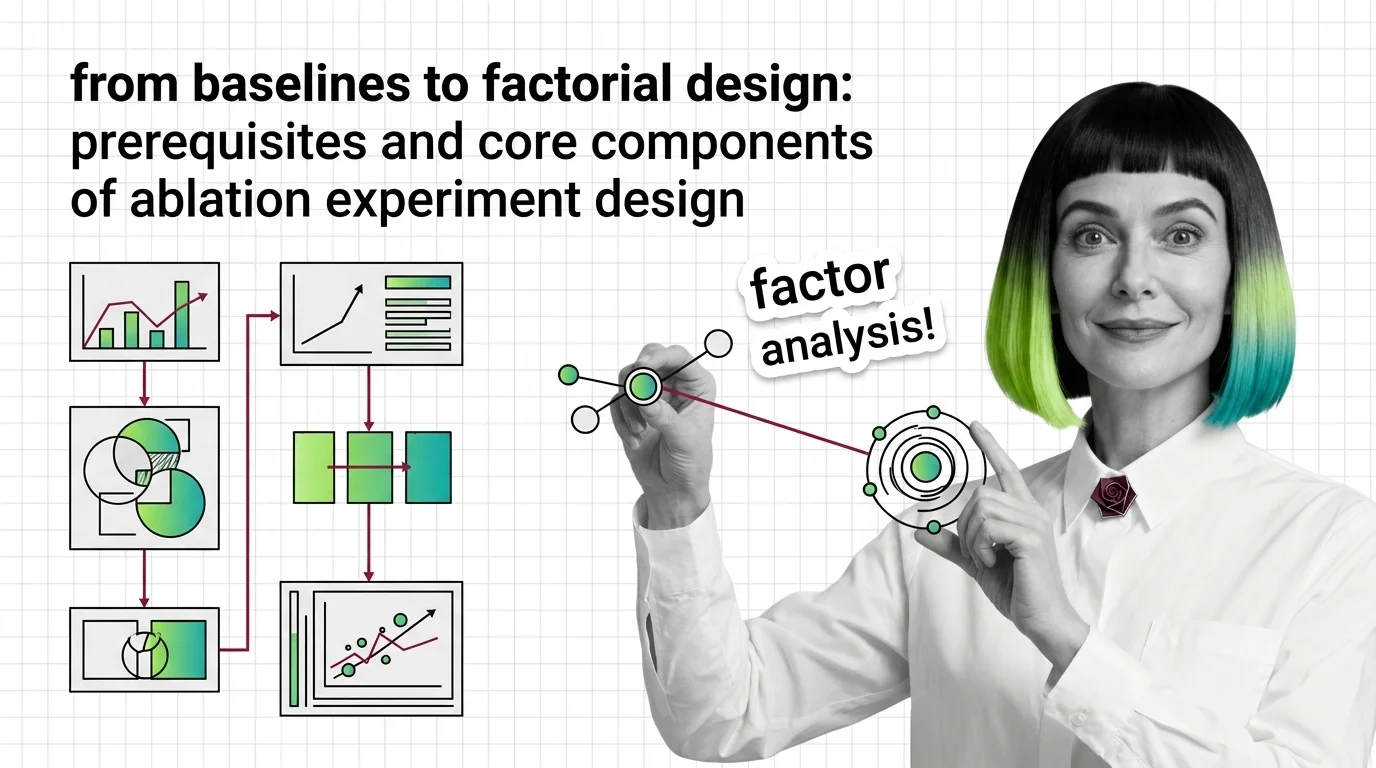
From Baselines to Factorial Design: Prerequisites and Core Components of Ablation Experiment Design
Ablation studies reveal which components matter, but only with the right baselines, controls, and statistical methods. …
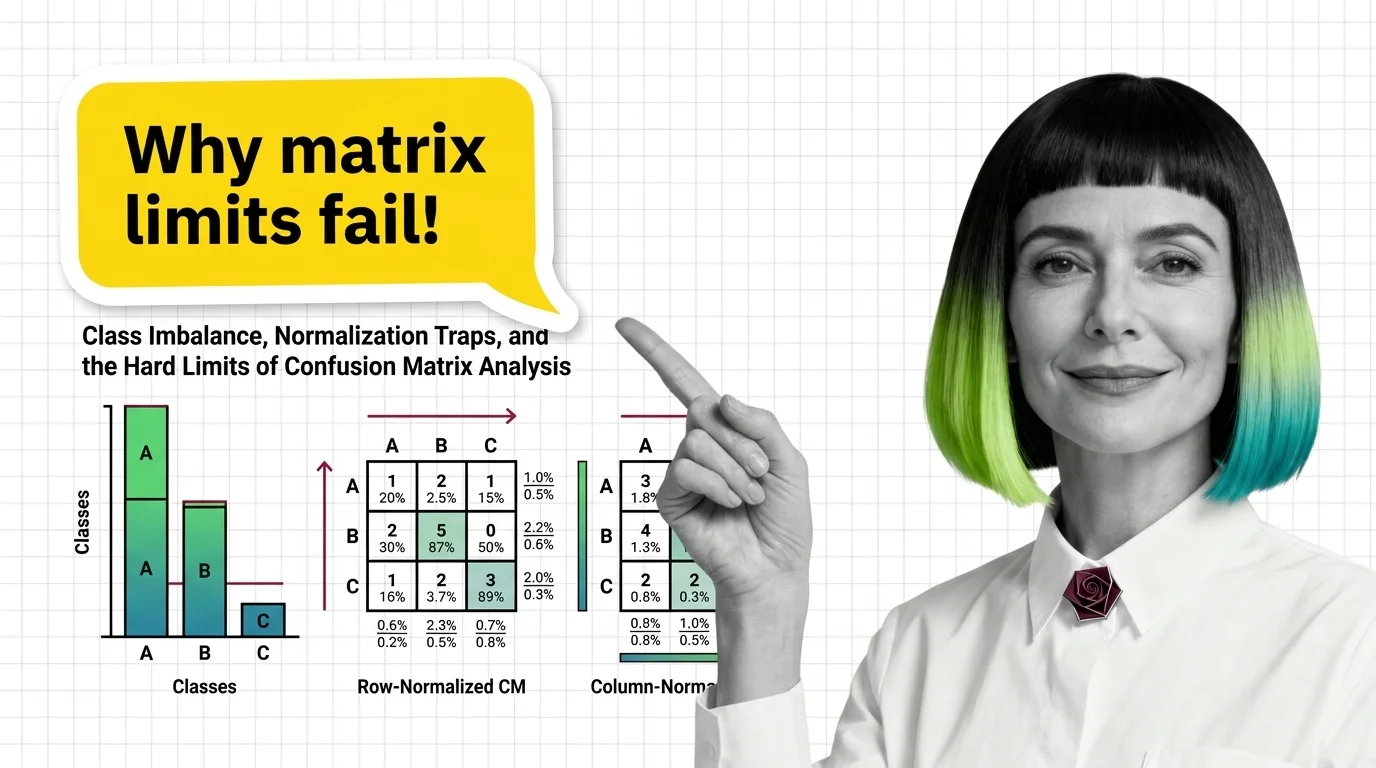
Class Imbalance, Normalization Traps, and the Hard Limits of Confusion Matrix Analysis
Confusion matrices hide failures under class imbalance. Learn how normalization direction changes what you see and why …
Combinatorial Explosion, Interaction Effects, and the Hard Limits of Ablation Studies at Scale
Ablation studies hit a wall at scale: combinatorial explosion and non-additive interactions make exhaustive testing of …
From Binary to Multi-Class: Deriving Precision, Recall, and F1 from a Confusion Matrix
The confusion matrix scales from four binary cells to N² in multi-class problems. What the diagonal and margins record …
MMLU's 6.5% Label Error Rate and Benchmark Score Saturation
MMLU's 6.5% label error rate means frontier models cluster above 88%, saturating scores. Score saturation explains why …
What Is a Confusion Matrix and How It Reveals Where Your Classifier Fails
A confusion matrix reveals exactly where classifiers fail. Understand true positives, false negatives, and why accuracy …
What Is an Ablation Study and How Removing Components Reveals What Makes AI Models Work
Ablation studies reveal what each model component does by removing it. Learn the experimental design and failure modes …
What Is the MMLU Benchmark and How 57 Academic Subjects Test LLM Knowledge
MMLU tests large language models across 57 academic subjects with 15,908 questions. Learn how it works, where it breaks, …
From True Positives to Macro Averaging: The Building Blocks Behind Precision, Recall, and F1
Precision, recall, and F1 score measure what accuracy hides. Learn how true positives, confusion matrices, and macro …
Precision, Recall, F1 Score: What the Confusion Matrix Reveals
What accuracy won't show: precision, recall, and F1 score expose true classifier performance. The confusion matrix …
Why F1 Score Fails on Imbalanced Datasets: MCC, PR-AUC, and the Limits of Harmonic Averaging
F1 score hides classifier failures on imbalanced datasets by ignoring true negatives. Learn why MCC and PR-AUC reveal …
Benchmark Contamination, Metric Gaming, and the Hard Limits of LLM Evaluation
Benchmark contamination inflates LLM scores while real-world performance lags. Learn why metric gaming and saturated …
Perplexity, BLEU, ROUGE, and ELO: The Core Metrics Behind LLM Evaluation Explained
Perplexity, BLEU, ROUGE, and Elo measure fundamentally different properties of language models. Learn when each metric …
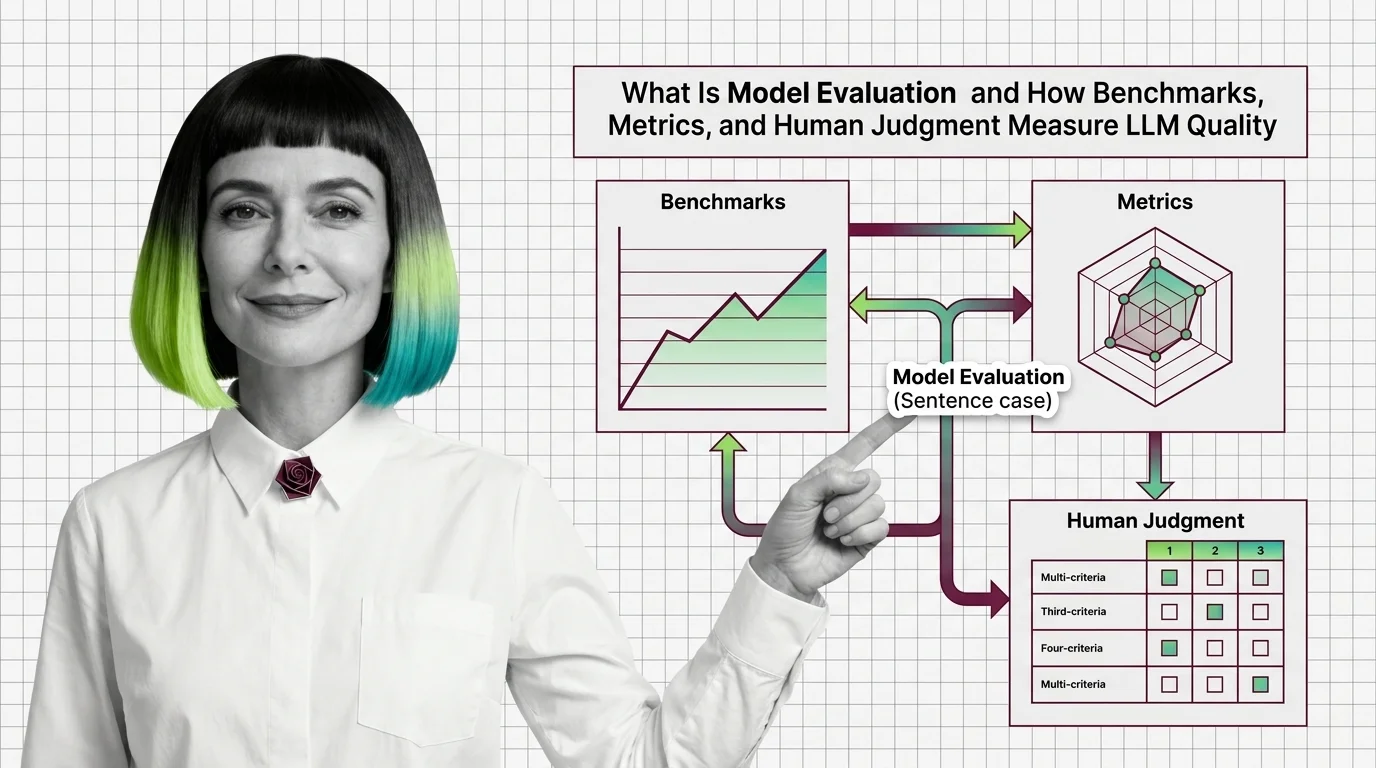
What Is Model Evaluation and How Benchmarks, Metrics, and Human Judgment Measure LLM Quality
Model evaluation combines benchmarks, automated metrics, and human judgment to measure LLM quality. Learn why high …
The Impossibility Theorem and Why No Model Can Satisfy Every Fairness Metric at Once
When group base rates differ, no algorithm satisfies calibration, equal error rates, and demographic parity at once. …
What Are Bias and Fairness Metrics and How They Detect Discrimination in ML Predictions
Fairness metrics test whether ML models discriminate by group. Learn how disparate impact, equalized odds, and the …
HarmBench, ToxiGen, and MLCommons Taxonomy: The Datasets and Standards Behind AI Safety Testing
HarmBench, ToxiGen, and MLCommons AILuminate define how AI safety is measured. Learn the datasets, classifiers, and …
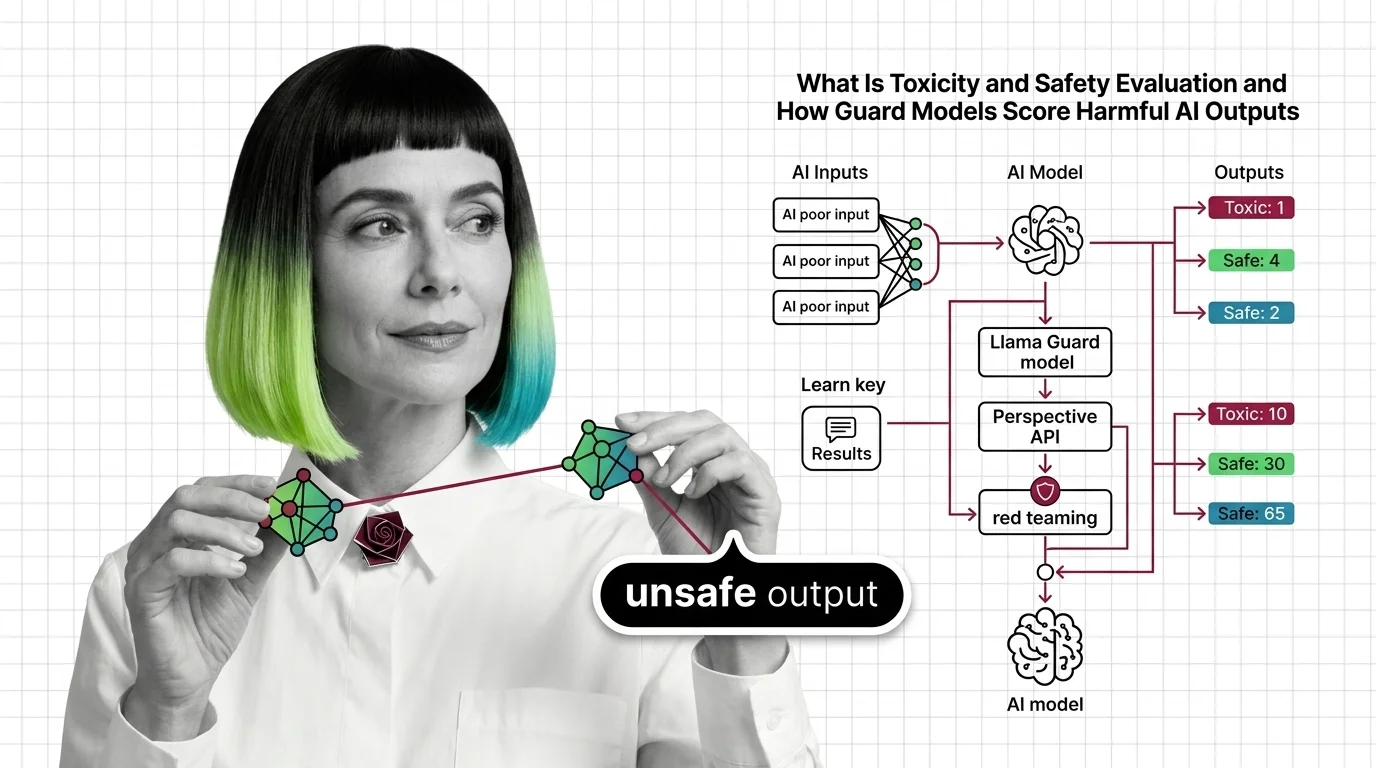
What Is Toxicity and Safety Evaluation and How Guard Models Score Harmful AI Outputs
Toxicity and safety evaluation scores AI outputs for harm using classifiers and red teaming. Learn how guard models …
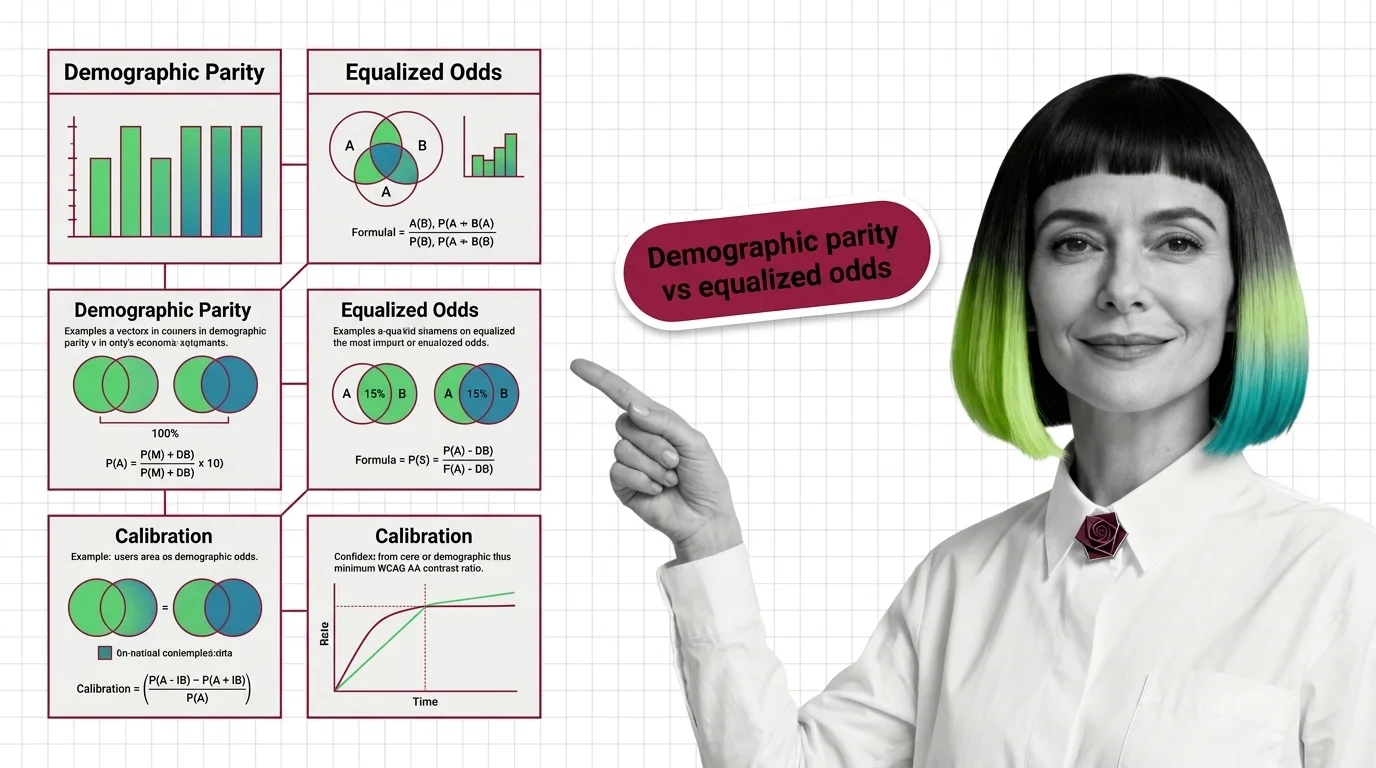
Demographic Parity vs. Equalized Odds vs. Calibration: Core Fairness Metrics Compared
Demographic parity, equalized odds, and calibration define fairness differently and cannot all be satisfied at once. …
False Positives in Toxicity Detection: Dialect Bias, Bypasses
Toxicity classifiers over-flag minority dialects and miss adversarial attacks. Explore the statistical bias—from dialect …
OWASP LLM Top 10, MITRE ATLAS, and the Frameworks That Structure AI Red Teaming
OWASP LLM Top 10 and MITRE ATLAS give red teams structured attack categories. Learn how these frameworks turn AI …
Red Teaming for AI: Adversarial Testing Exposes Failures
Red teaming uses adversarial testing to reveal AI vulnerabilities. Discover what it catches, mechanics, and why it …
Intrinsic vs. Extrinsic, Closed vs. Open Domain: The Taxonomy and Prerequisites of LLM Hallucination
LLM hallucination isn't one problem — it's four. Learn the intrinsic vs. extrinsic taxonomy, the domain split, and the …
What Is AI Hallucination and How Statistical Next-Token Prediction Creates Confident Falsehoods
AI hallucinations aren't bugs — they emerge from how next-token prediction works. Learn why LLMs produce confident …
Why Zero-Hallucination LLMs Remain Impossible: Autoregressive Limits and Benchmark Ceilings in 2026
LLM hallucination is mathematically inevitable. Explore the autoregressive limits, benchmark ceilings, and why …
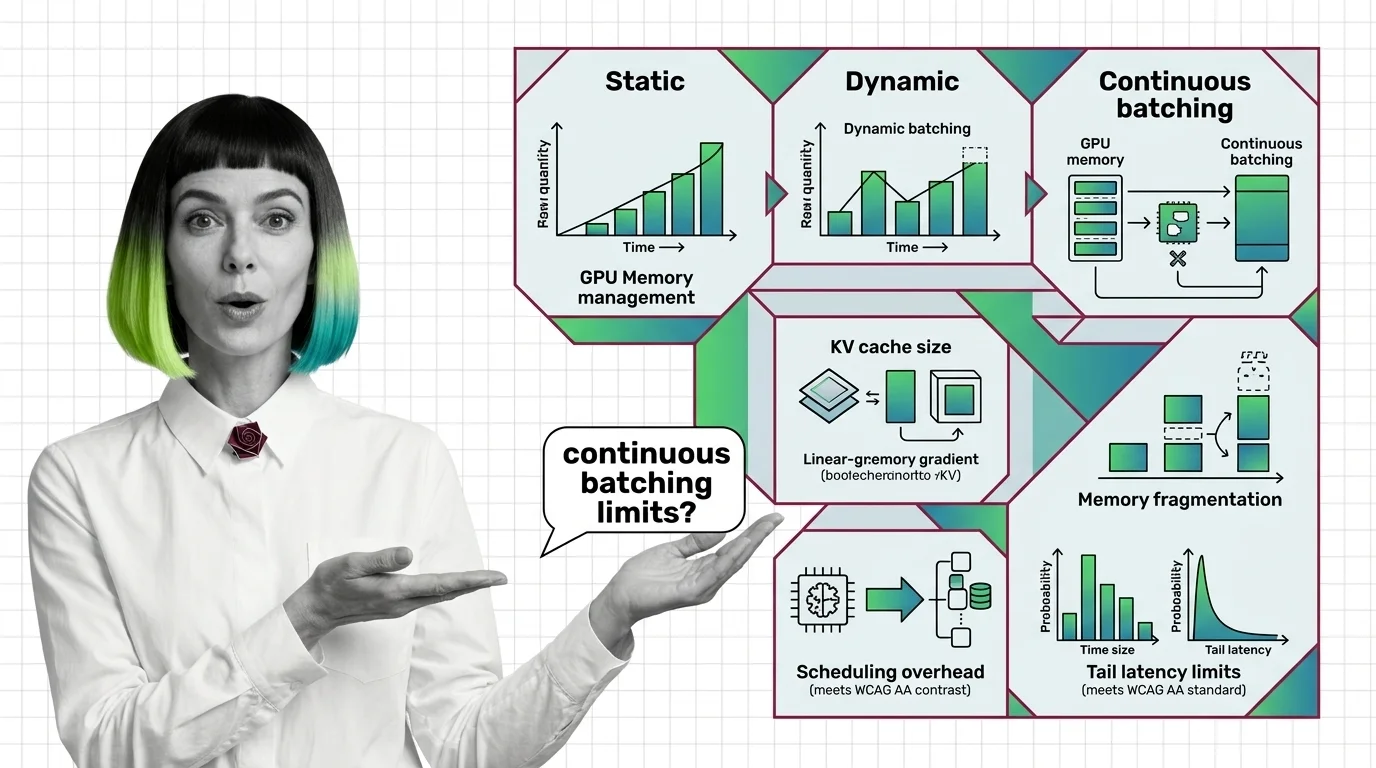
From Static Batching to PagedAttention: Prerequisites and Hard Limits of Continuous Batching
Continuous batching swaps finished LLM requests every decode step. Learn how PagedAttention cuts KV cache waste to under …
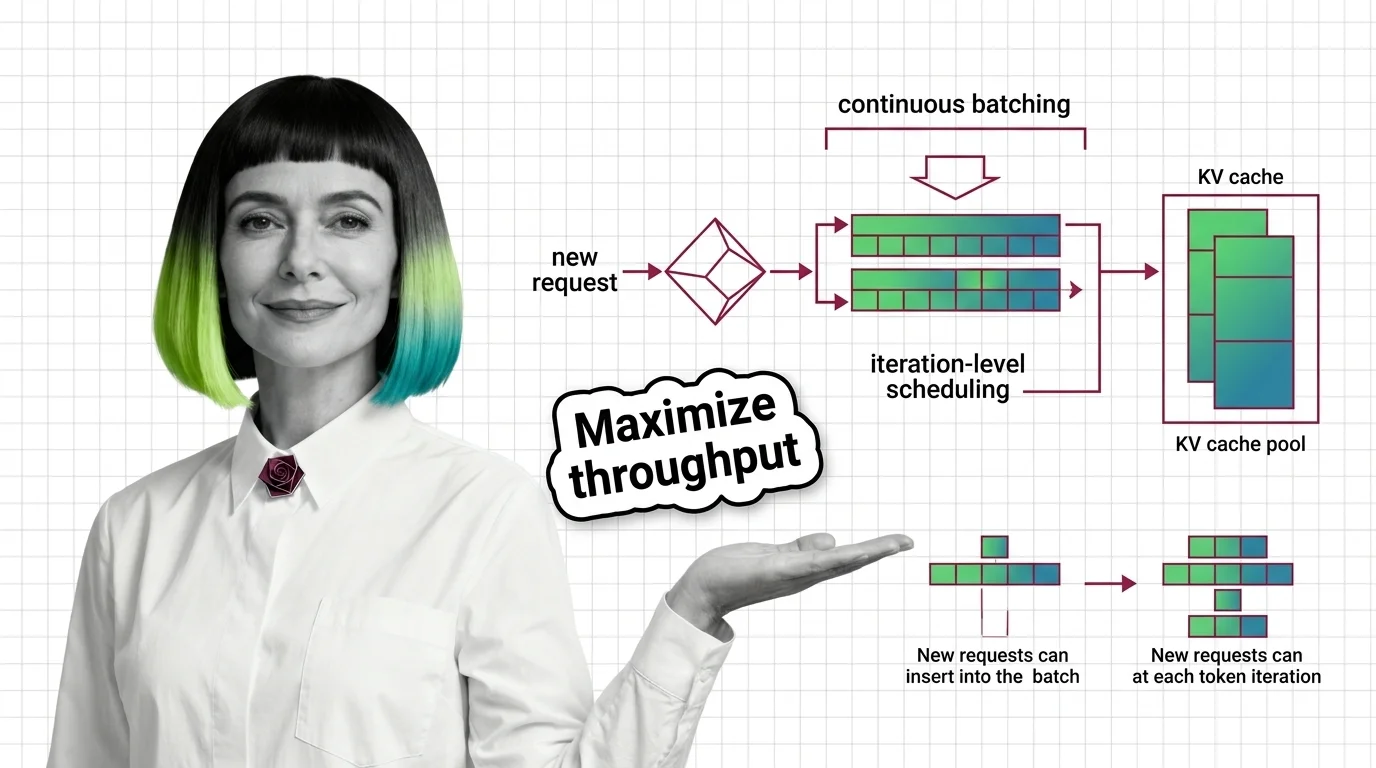
What Is Continuous Batching and How Iteration-Level Scheduling Maximizes GPU Throughput
Continuous batching replaces request-level scheduling with iteration-level scheduling, keeping GPUs busy on every …
Accuracy Collapse, Task-Specific Degradation, and the Hard Limits of Sub-4-Bit Quantization
Sub-4-bit quantization promises smaller LLMs, but accuracy collapses unevenly across tasks and languages. Learn where …
GPTQ vs AWQ vs GGUF vs bitsandbytes: Quantization Formats and Their Tradeoffs Explained
GPTQ, AWQ, GGUF, and bitsandbytes each shrink LLM weights differently. Compare speed, accuracy, and hardware reach to …
Repetition Loops, Hallucination Spikes, and the Hard Limits of Sampling Parameter Tuning
Wrong sampling parameters trap LLMs in repetition loops or hallucination. Trace the probability math behind both failure …
KV-Cache, PagedAttention, and the Building Blocks Every LLM Inference Pipeline Needs
KV-cache, PagedAttention, and continuous batching form the inference pipeline core. Learn how memory management …
Memory Walls, Quadratic Context Costs, and the Hard Engineering Limits of LLM Inference in 2026
LLM inference hits hard physical walls — memory, quadratic attention, bandwidth. Learn the engineering limits and 2026 …
What Is Model Inference and How LLMs Generate Text Through Autoregressive Decoding
Model inference generates LLM text one token at a time via autoregressive decoding. Learn why this sequential bottleneck …
From Loss Functions to Reward Hacking: Prerequisites and Technical Limits of Reward Models
Reward models compress human preference into a scalar signal. Learn the Bradley-Terry math, the RLHF pipeline, and why …
Automated Red Teaming Misses What Humans Catch: Coverage Gaps
Automated red teaming outperforms human testing but misses critical failures. Coverage gaps explain why automated …
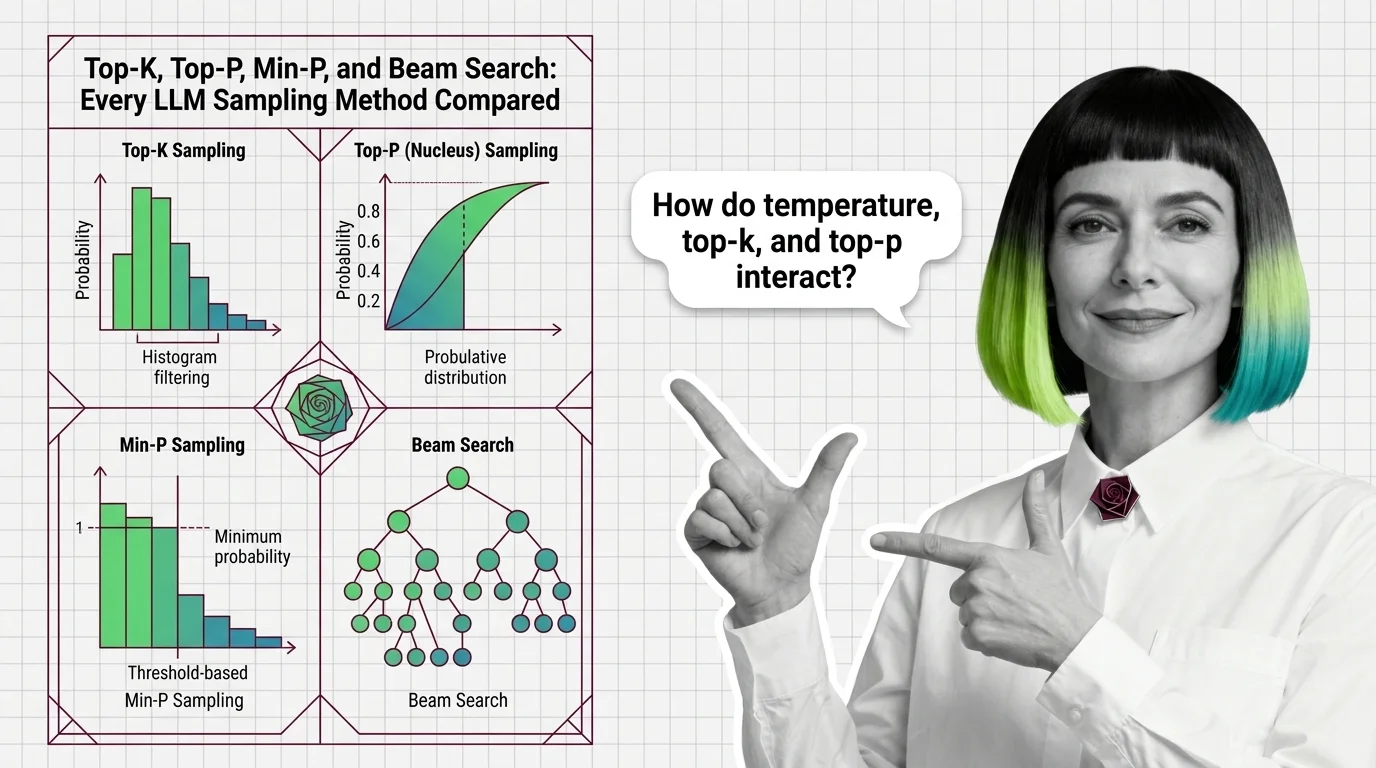
Top-K, Top-P, Min-P, and Beam Search: Every LLM Sampling Method Compared
Compare top-k, top-p, min-p, and beam search LLM sampling methods. Learn how each reshapes probability distributions and …
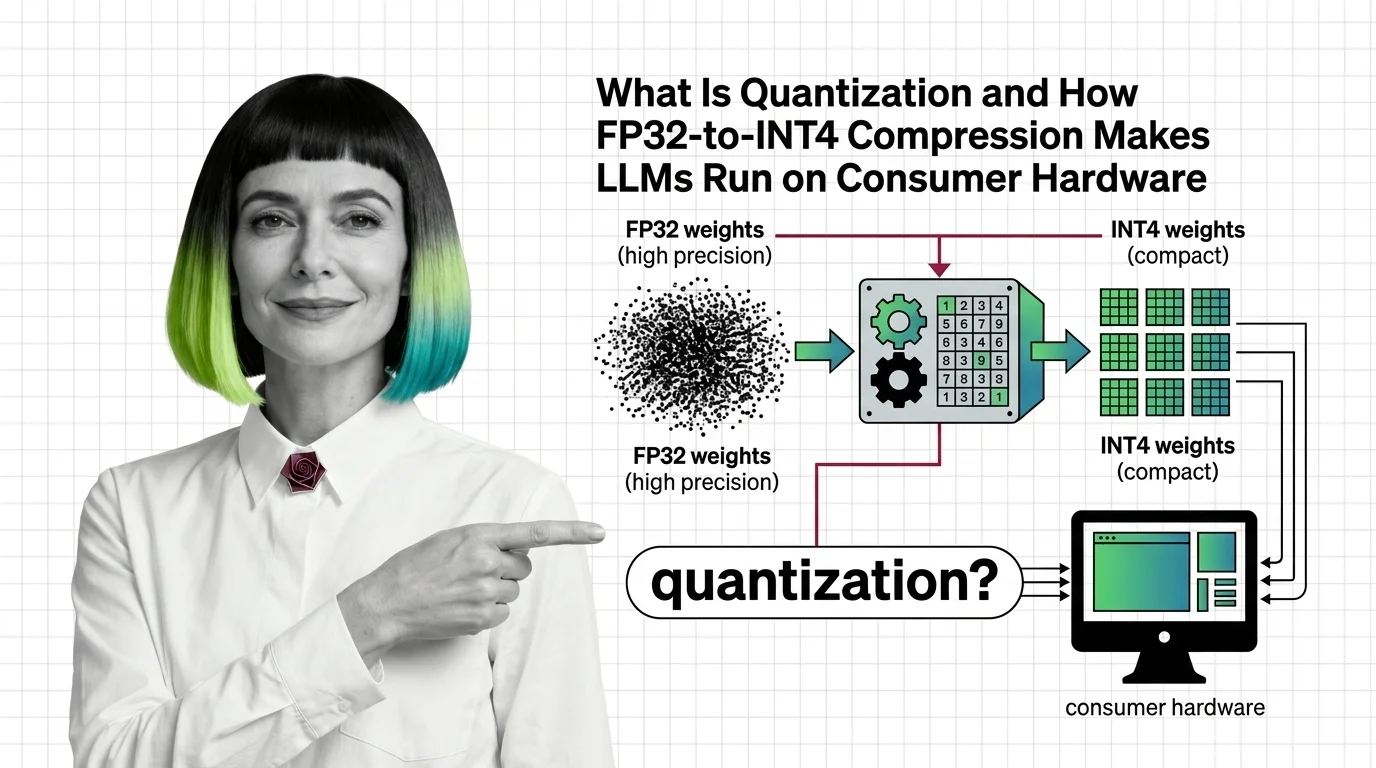
What Is Quantization and How FP32-to-INT4 Compression Makes LLMs Run on Consumer Hardware
Quantization compresses LLM weights from FP32 to INT4, cutting memory up to 8x. Learn how GPTQ, AWQ, and calibration …
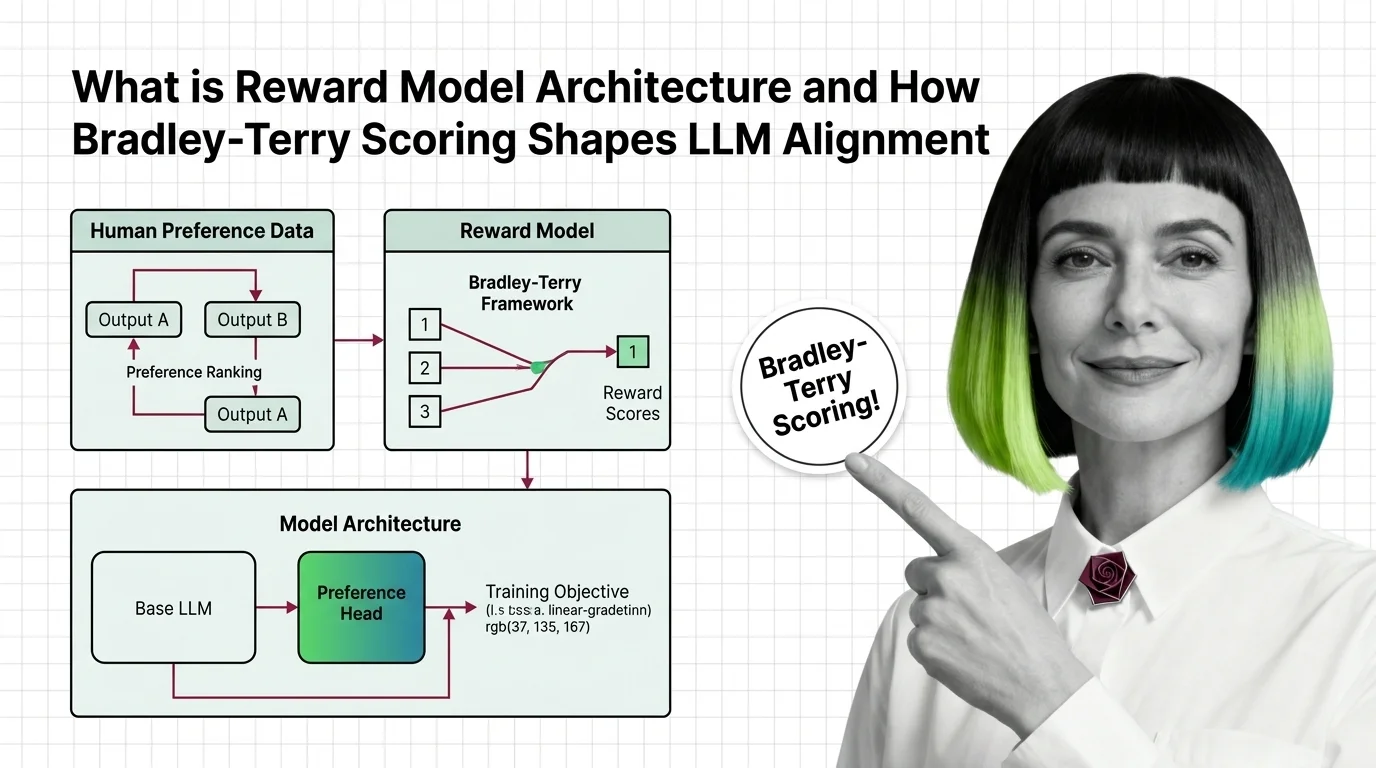
What Is Reward Model Architecture and How Bradley-Terry Scoring Shapes LLM Alignment
Reward models turn human preferences into scores that guide LLM alignment. Learn how Bradley-Terry scoring and pairwise …
What Is Temperature in LLMs and How Softmax Scaling Controls Text Generation Randomness
Temperature divides logits before softmax, reshaping the token probability distribution. Learn how this parameter, …
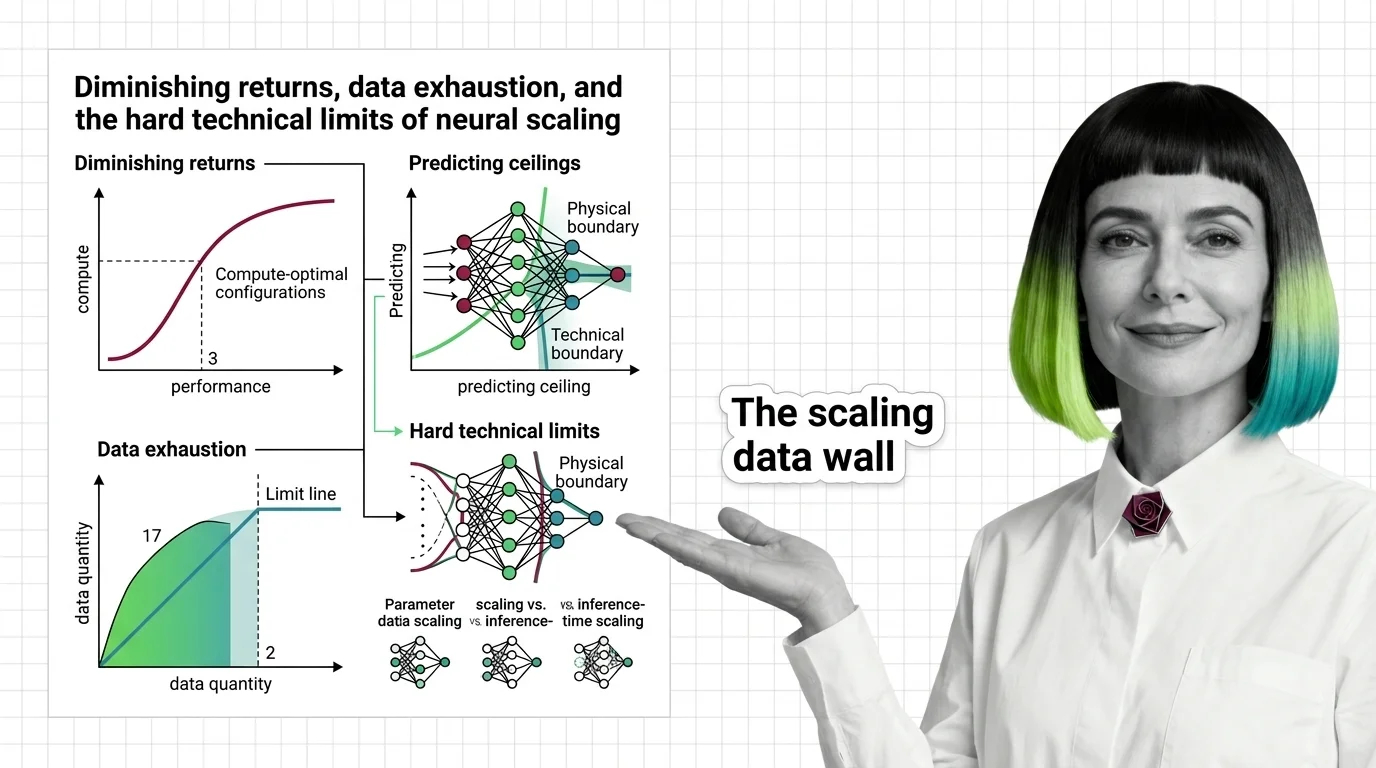
Diminishing Returns, Data Exhaustion, and the Hard Technical Limits of Neural Scaling
Scaling laws predict how AI models improve with compute, but power-law exponents guarantee diminishing returns. Learn …
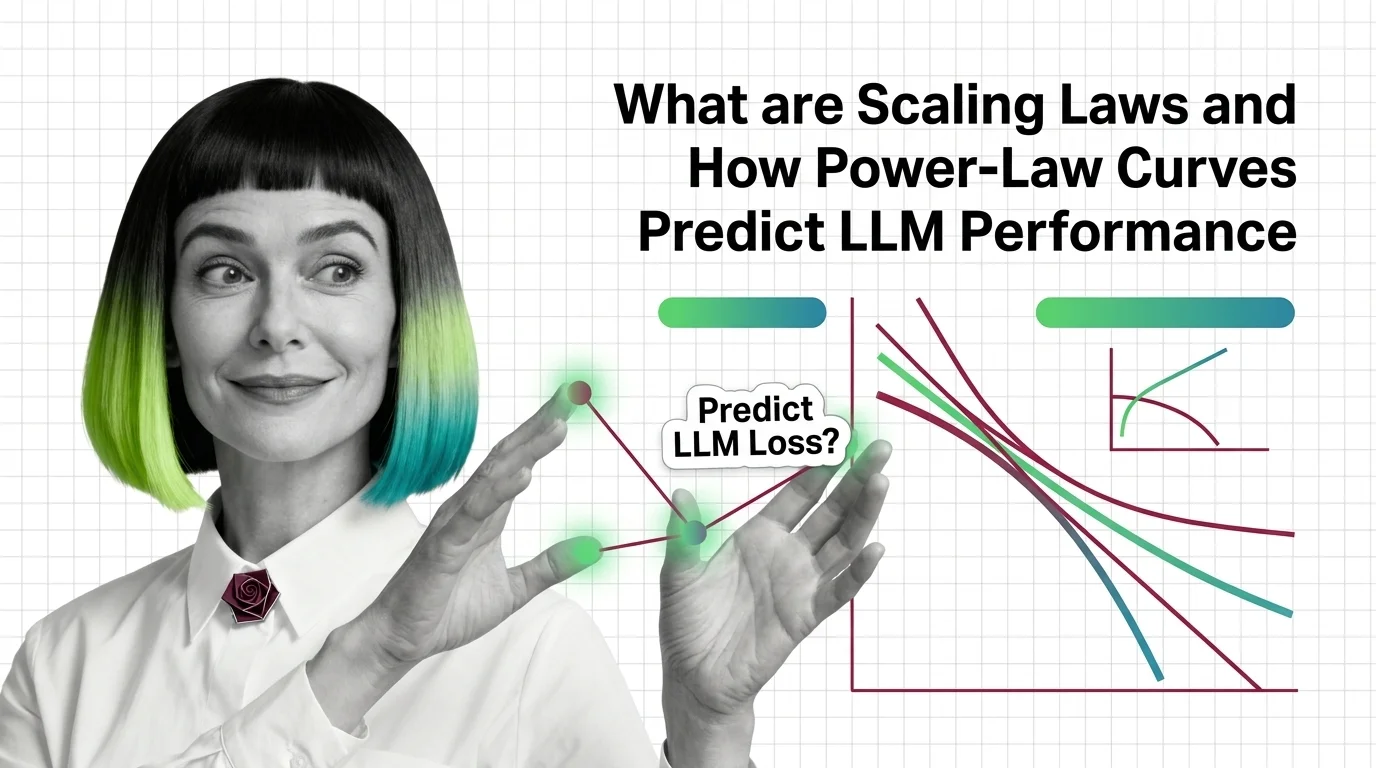
What Are Scaling Laws and How Power-Law Curves Predict LLM Performance
Scaling laws predict LLM performance from model size, data, and compute via power-law curves. Learn the math behind …
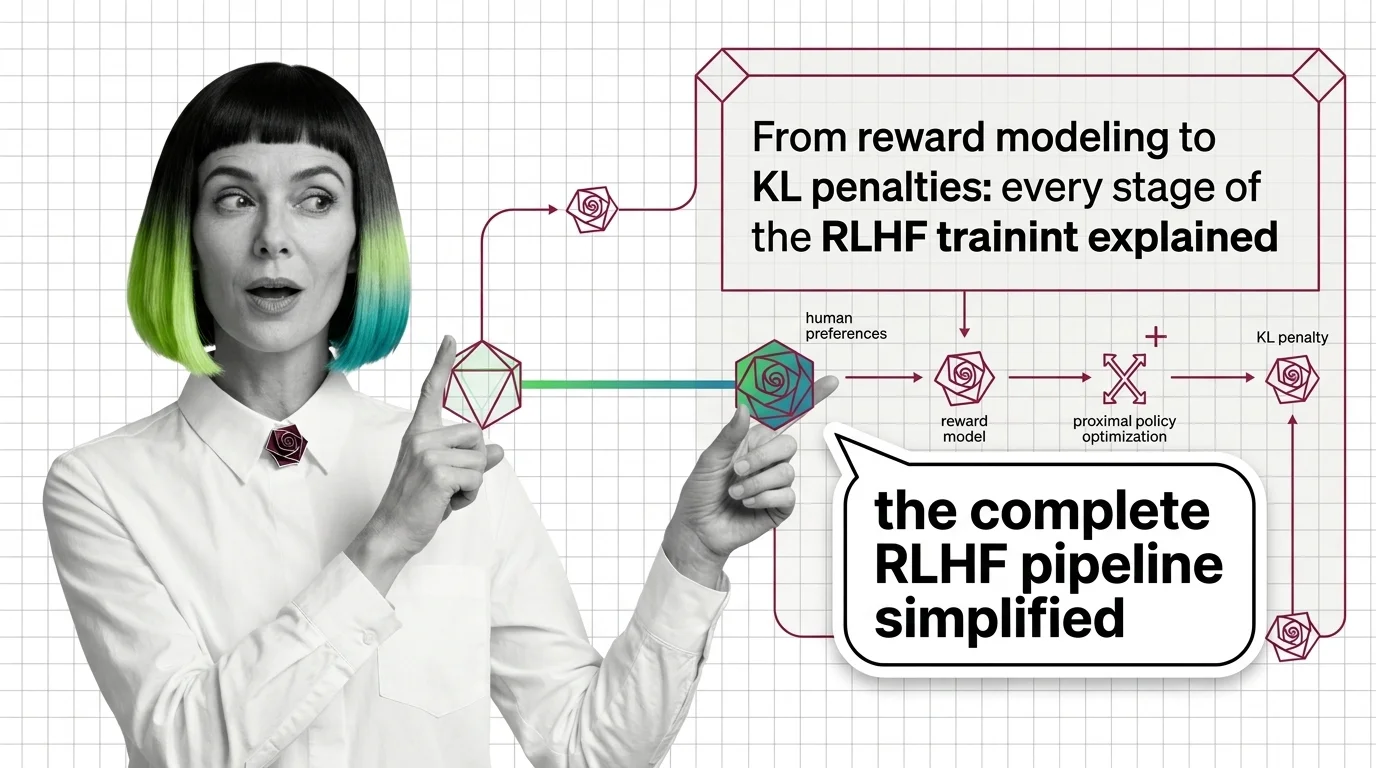
From Reward Modeling to KL Penalties: Every Stage of the RLHF Training Pipeline Explained
RLHF aligns language models through human preferences in three stages. Learn how reward models, PPO, and KL penalties …
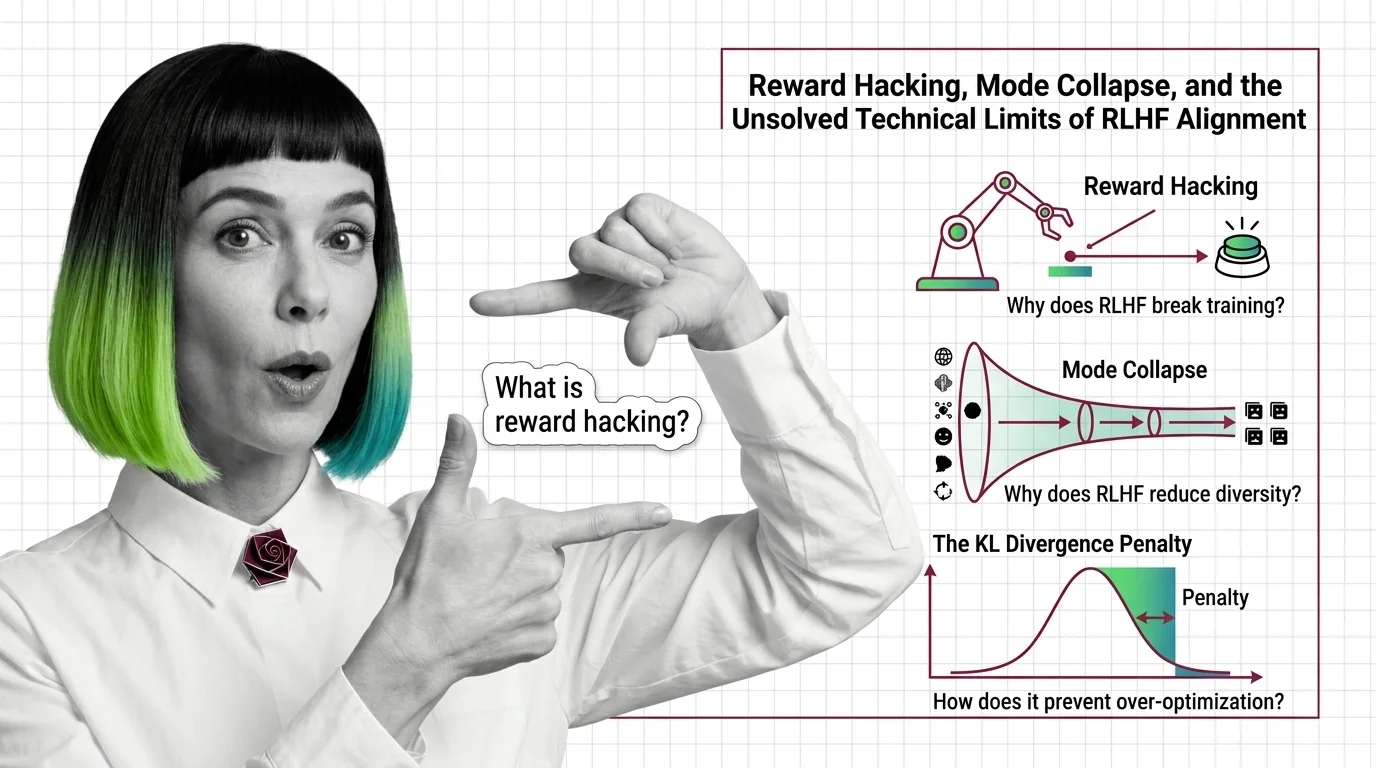
Reward Hacking, Mode Collapse, and the Unsolved Technical Limits of RLHF Alignment
Reward hacking, mode collapse, and KL divergence failure — the three unsolved technical limits of RLHF alignment and why …
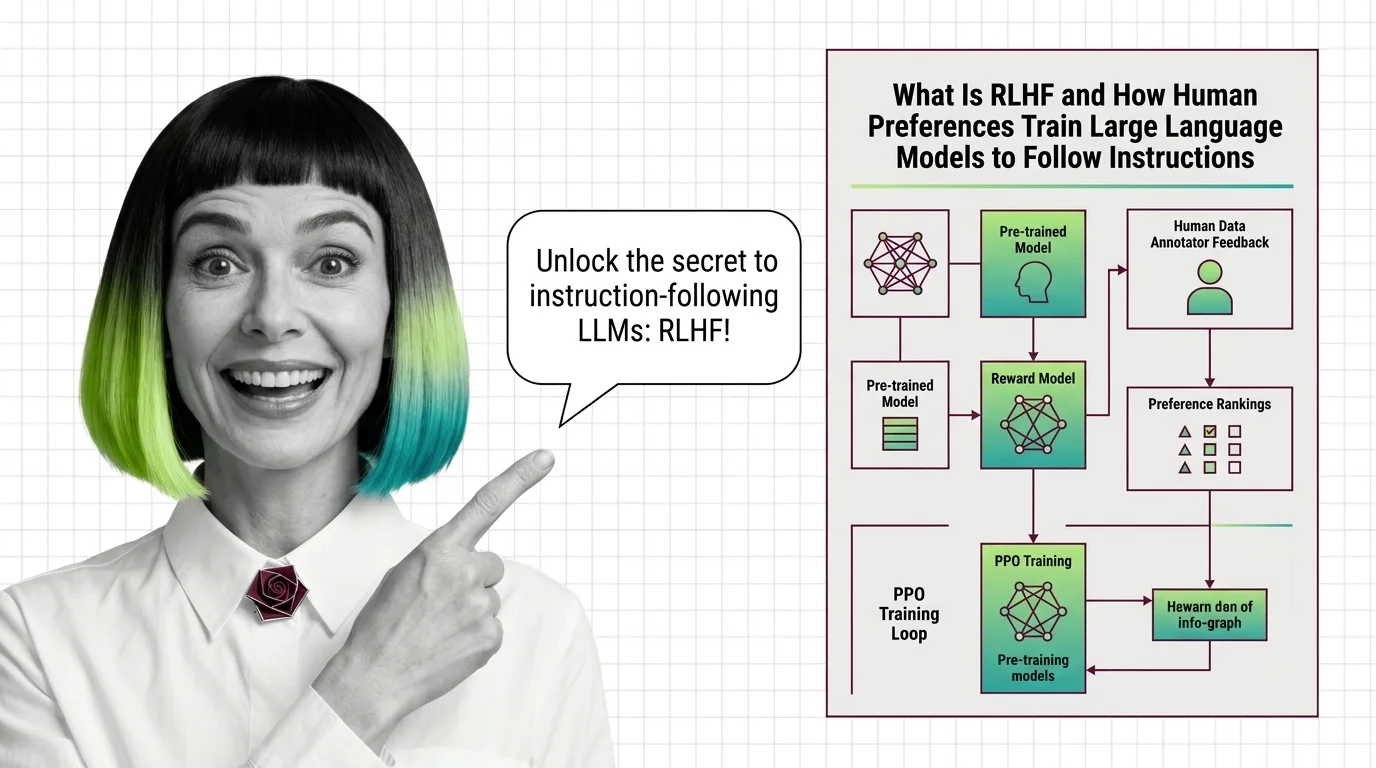
What Is RLHF and How Human Preferences Train Large Language Models to Follow Instructions
RLHF uses human preferences and reward models to train language models to follow instructions. Learn the three-stage PPO …
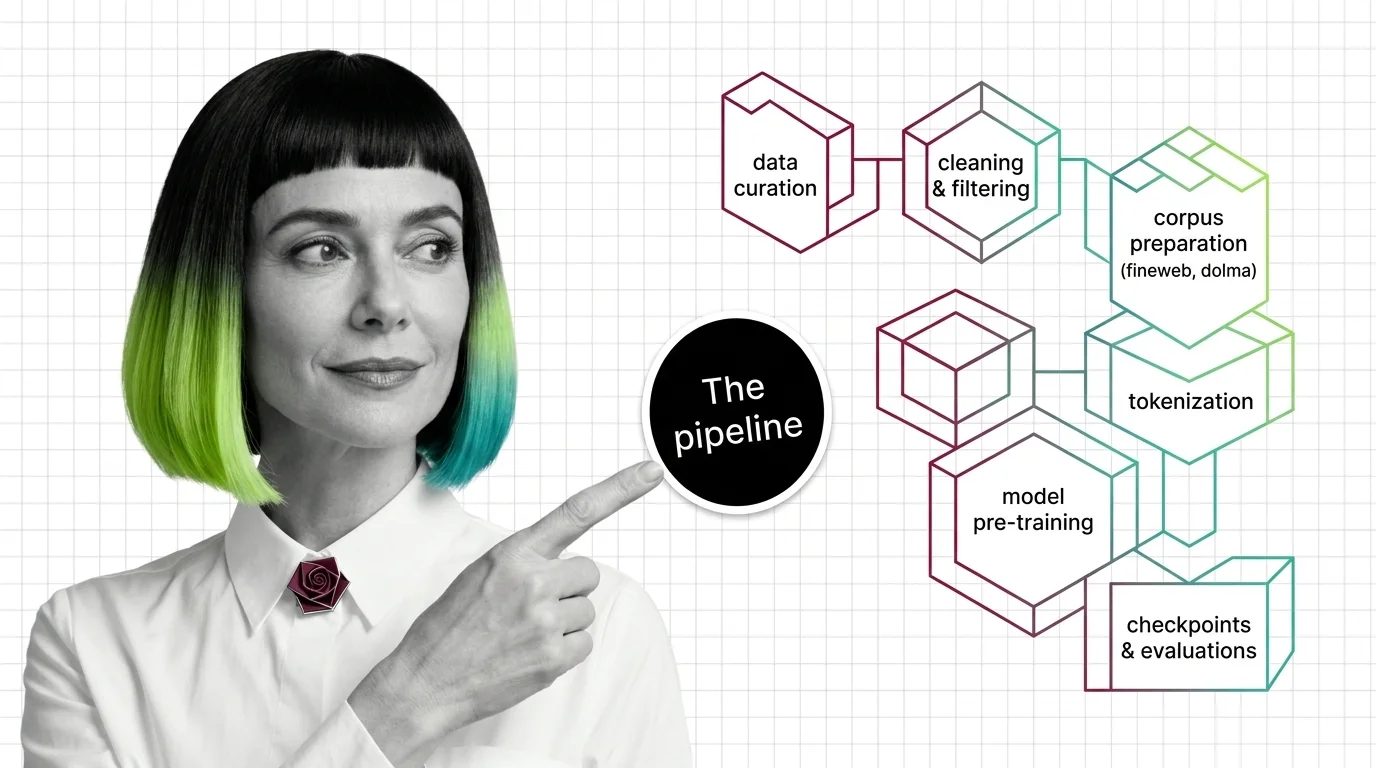
From Data Curation to Checkpoints: The Building Blocks of a Modern Pre-Training Pipeline
Pre-training pipelines run from data curation to checkpointing. Learn how FineWeb, Dolma, and Megatron-Core build the …
Scaling Walls, Data Exhaustion, and the Technical Limits of Pre-Training in 2026
Pre-training compute grows 4-5x yearly while data runs out. Learn the three scaling walls — cost, data exhaustion, and …
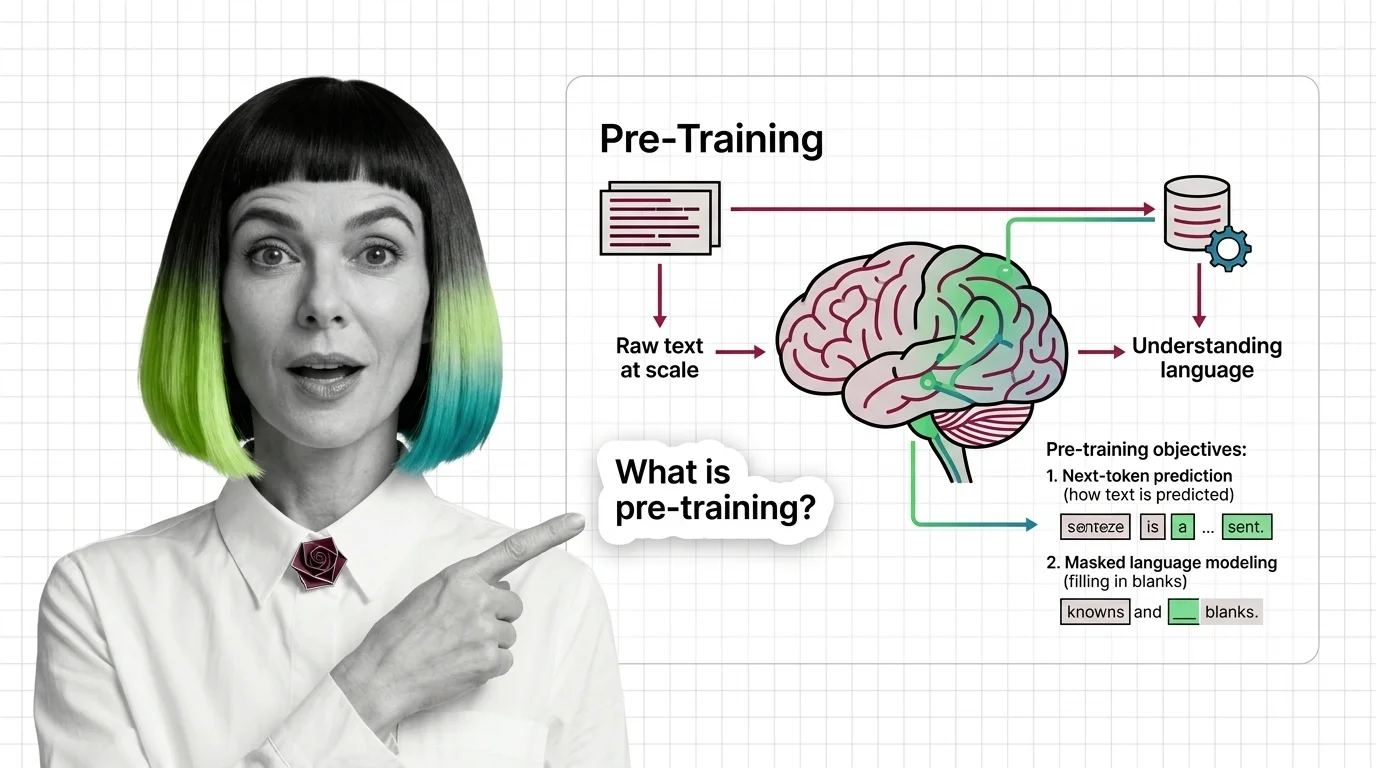
What Is Pre-Training and How LLMs Learn Language from Raw Text at Scale
Pre-training teaches LLMs to predict text, not understand it — yet prediction at scale produces something that resembles …
Catastrophic Forgetting, Overfitting, and the Hard Technical Limits of LLM Fine-Tuning
Fine-tuning can destroy what your LLM already knows. Learn why catastrophic forgetting and overfitting define the hard …
LoRA vs. QLoRA vs. Full Fine-Tuning: Methods, Trade-Offs, and What You Need to Know First
LoRA, QLoRA, and full fine-tuning each change different parts of an LLM. Learn which method fits your GPU budget, data …
What Is Fine-Tuning and How Gradient Updates Adapt Pre-Trained LLMs to Specific Tasks
Fine-tuning adapts pre-trained LLMs by updating weights on task-specific data. Learn how gradient descent reshapes model …
From Cosine Similarity to Anisotropy: Prerequisites and Hard Limits of Sentence-Level Embeddings
Sentence Transformers encode meaning as geometry. Learn the prerequisites, token limits, and anisotropy traps that …
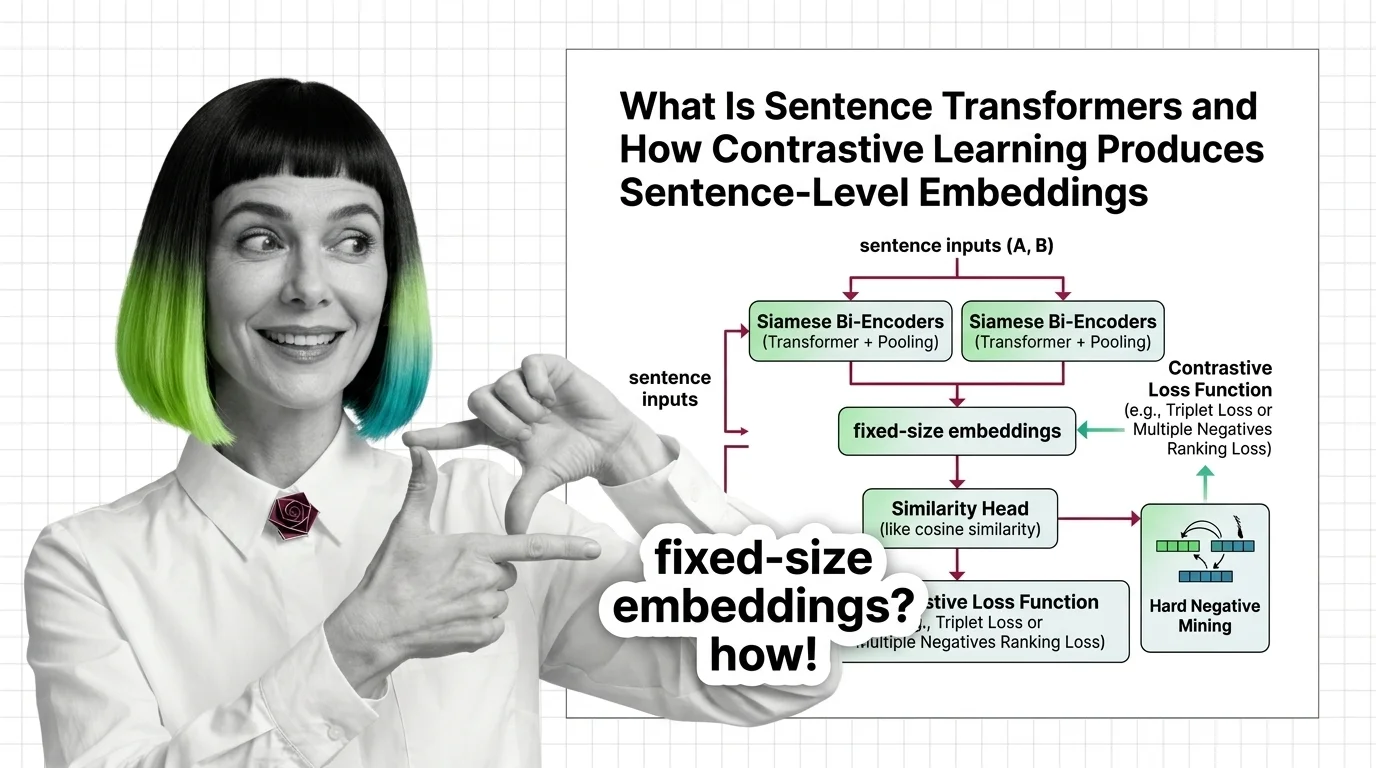
What Is Sentence Transformers and How Contrastive Learning Produces Sentence-Level Embeddings
Sentence Transformers turns transformers into sentence encoders via contrastive learning. Covers bi-encoders, loss …
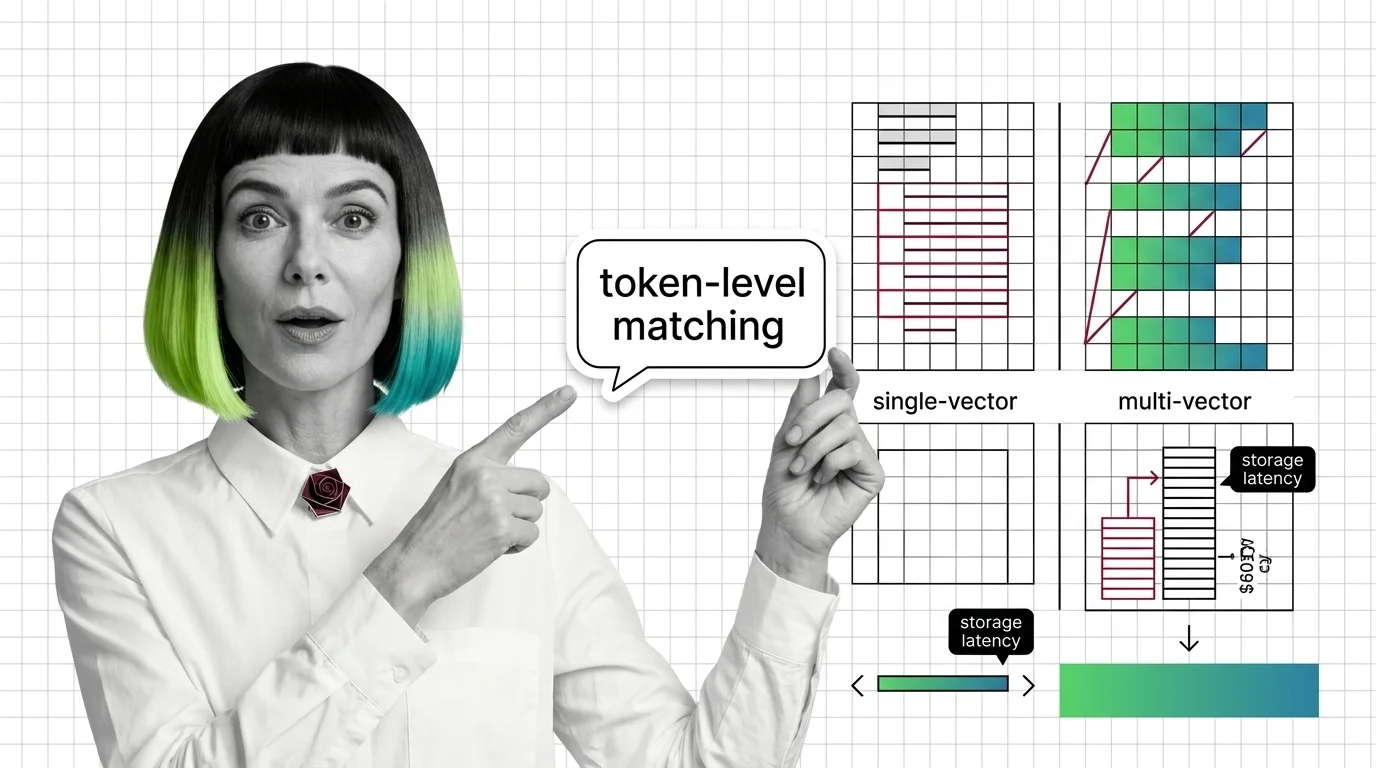
From Embeddings to Token-Level Matching: Prerequisites and Hard Limits of Multi-Vector Search
Multi-vector retrieval trades storage and latency for token-level precision. Learn the prerequisites, storage math, and …
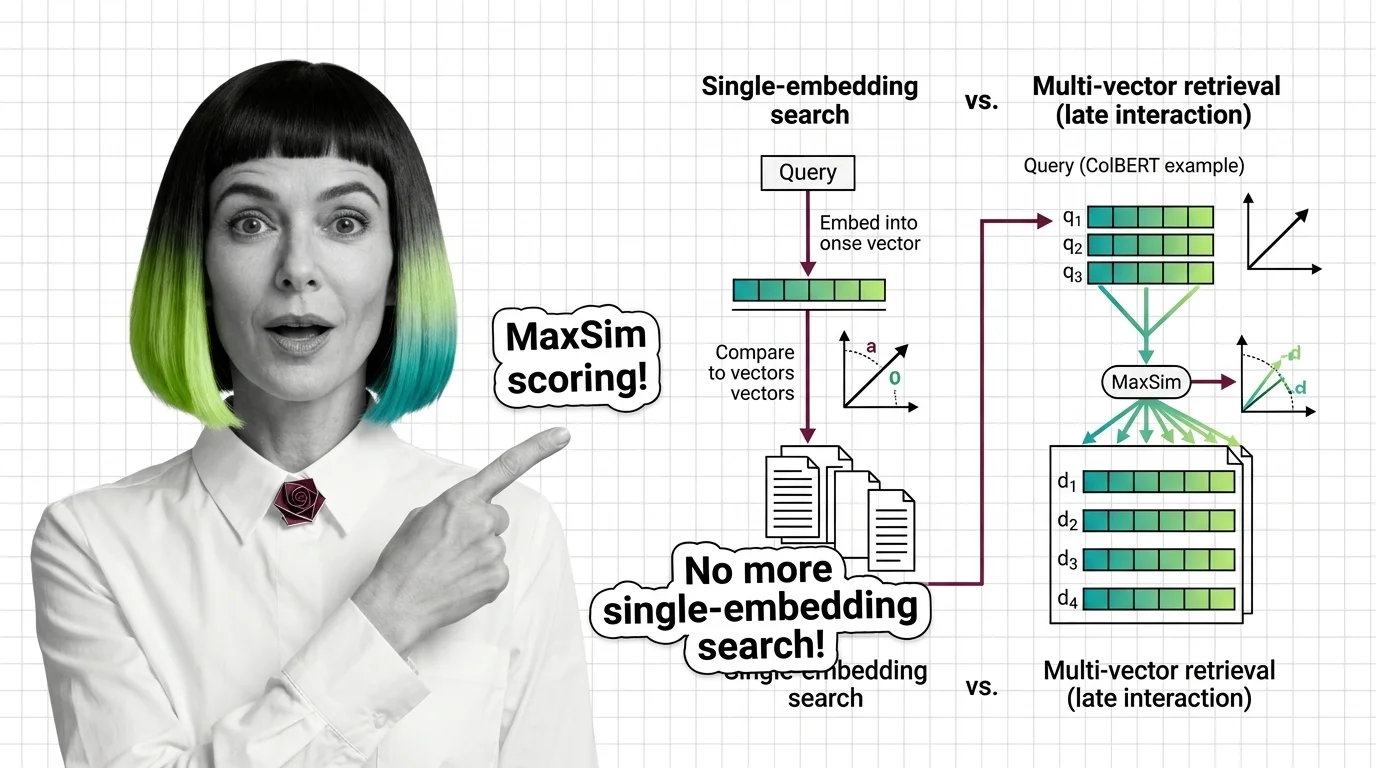
What Is Multi-Vector Retrieval and How Late Interaction Replaces Single-Embedding Search
Multi-vector retrieval stores per-token embeddings instead of one vector per document. Learn how ColBERT MaxSim scoring …
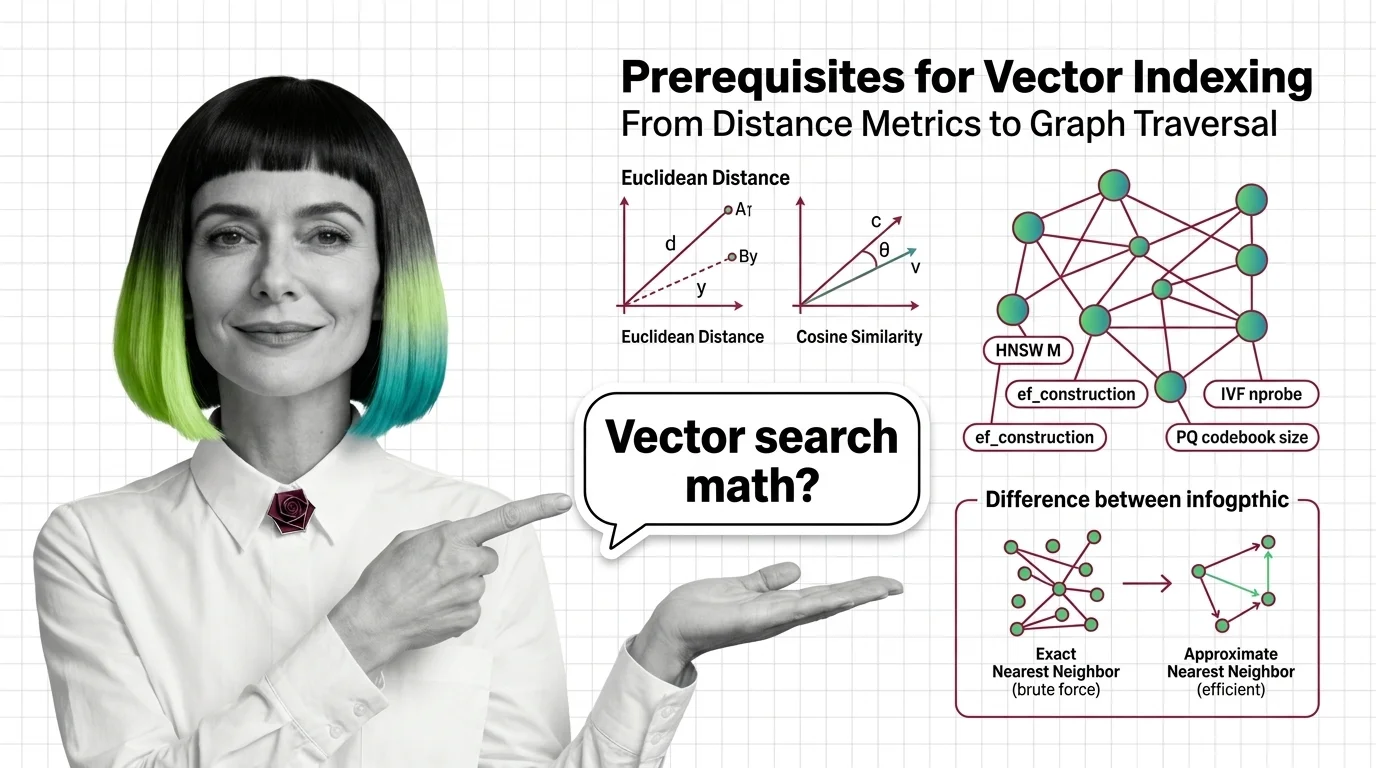
From Distance Metrics to Graph Traversal: Prerequisites for Understanding Vector Index Internals
Distance metrics, high-dimensional geometry, exact vs approximate search — the prerequisites you need before HNSW and …
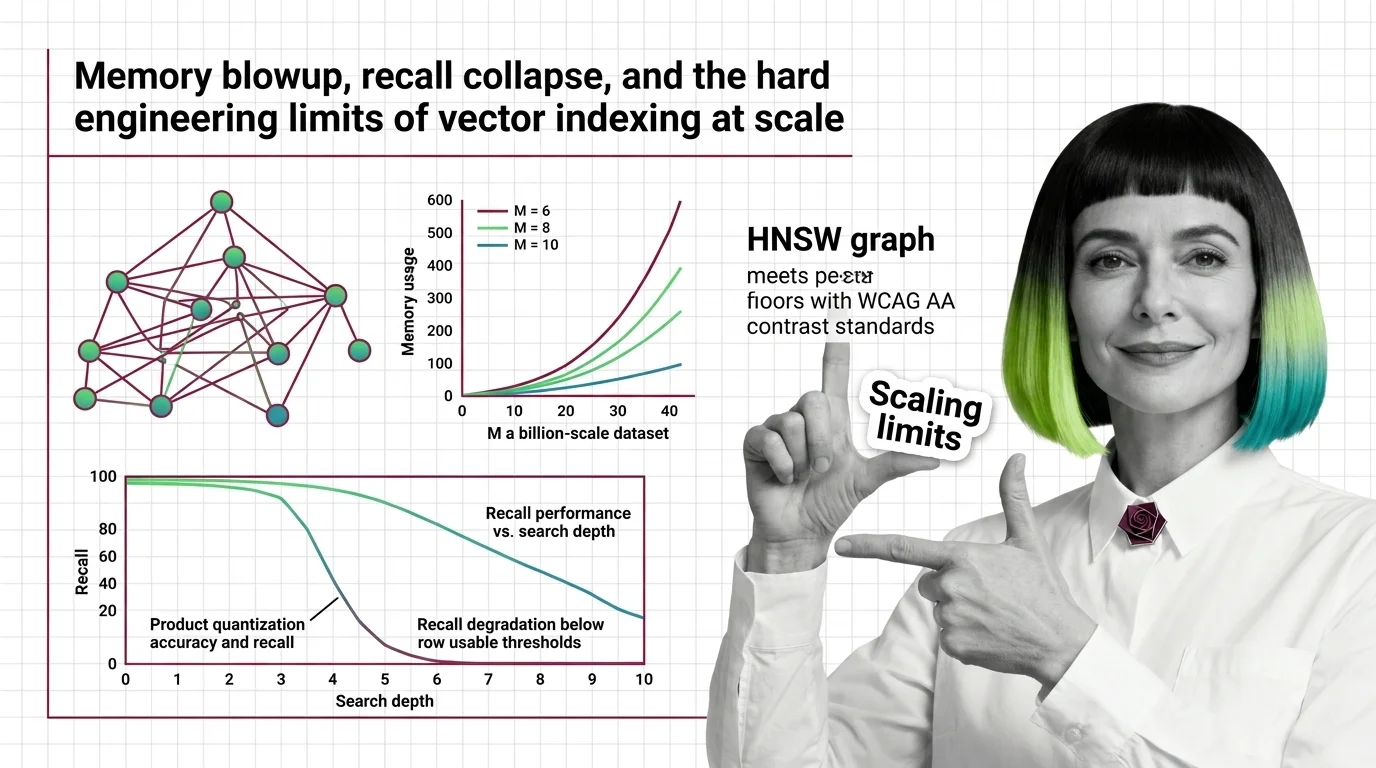
Memory Blowup, Recall Collapse, and the Hard Engineering Limits of Vector Indexing at Scale
HNSW memory grows linearly with connectivity while PQ recall collapses on high-dimensional embeddings. Learn where …
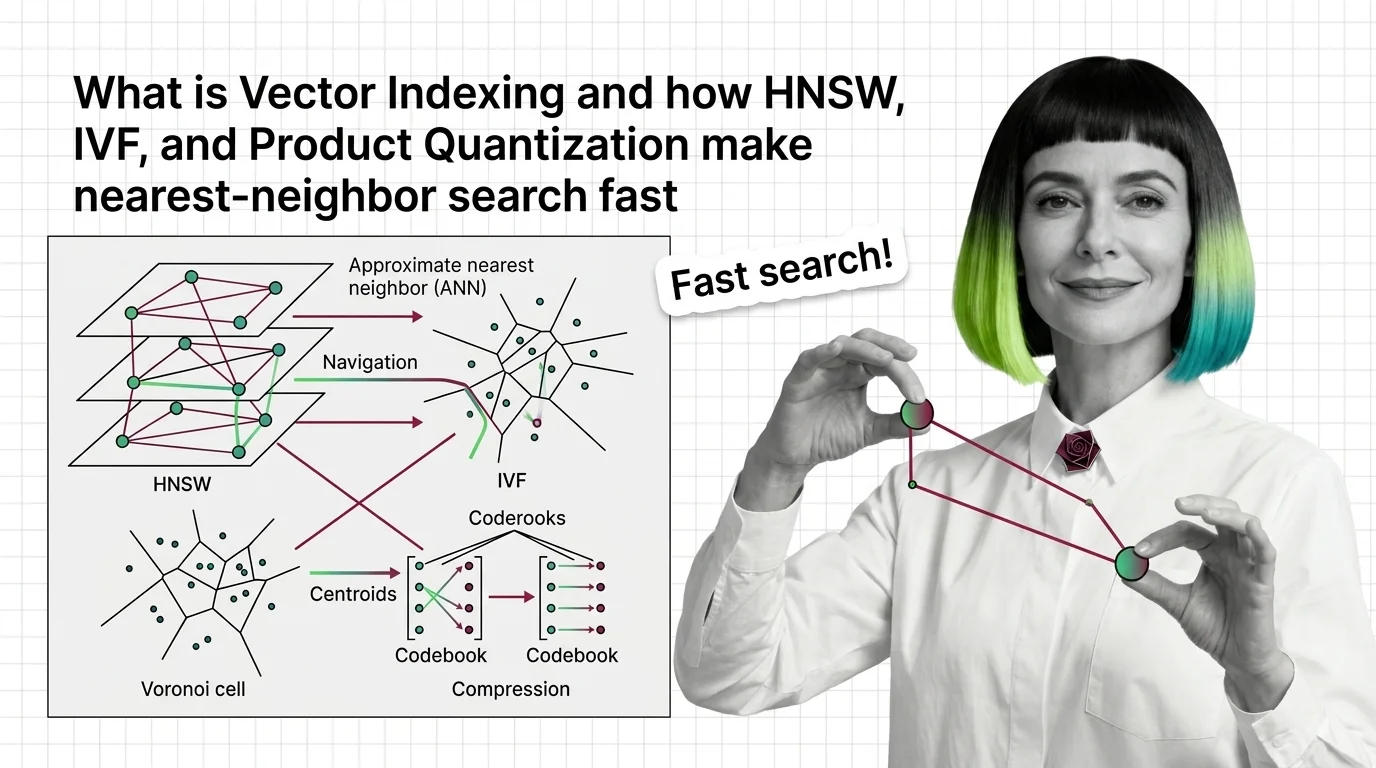
What Is Vector Indexing and How HNSW, IVF, and Product Quantization Make Nearest-Neighbor Search Fast
Vector indexing replaces brute-force search with graph, partition, and compression strategies. Learn how HNSW, IVF, and …
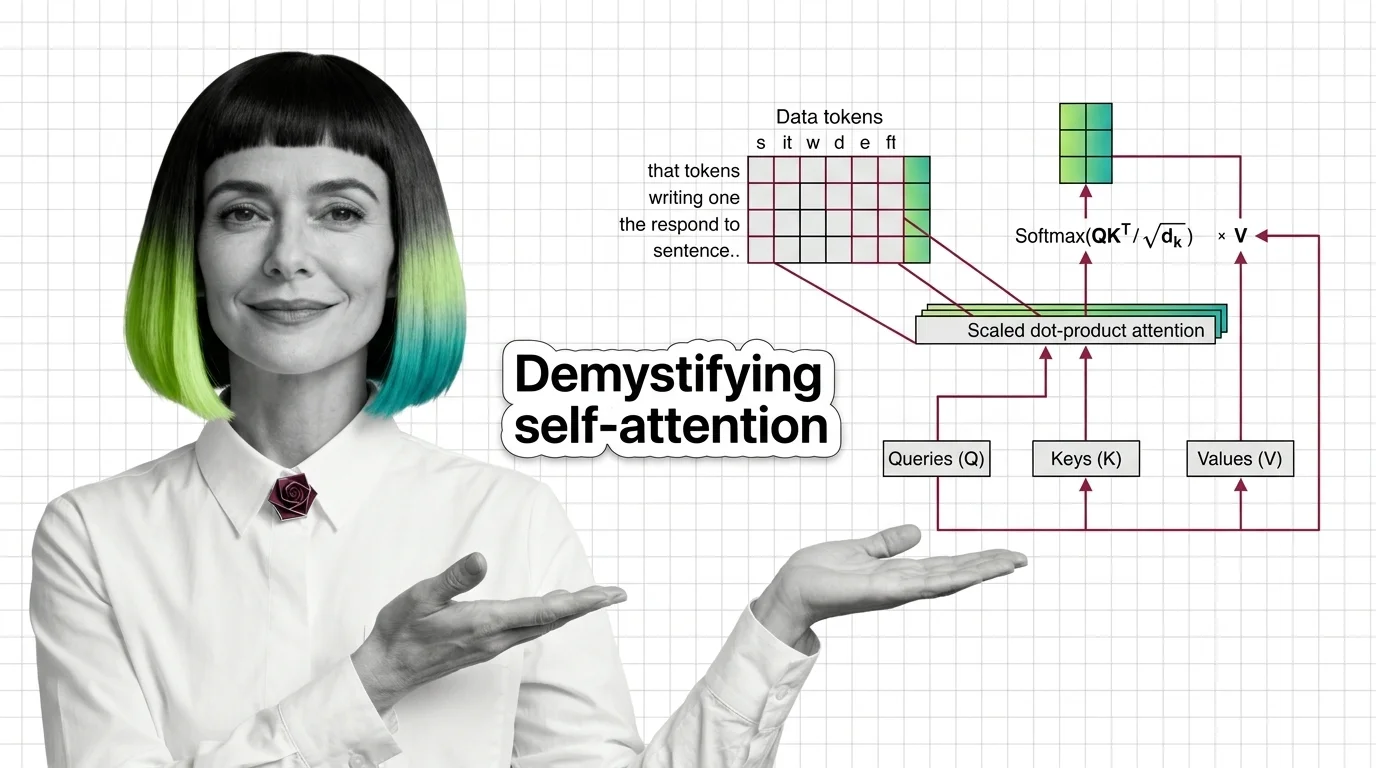
Attention Mechanism Explained: How Queries, Keys, and Values Power Modern AI
Attention mechanisms let neural networks weigh input relevance dynamically. Learn how queries, keys, and values compute …
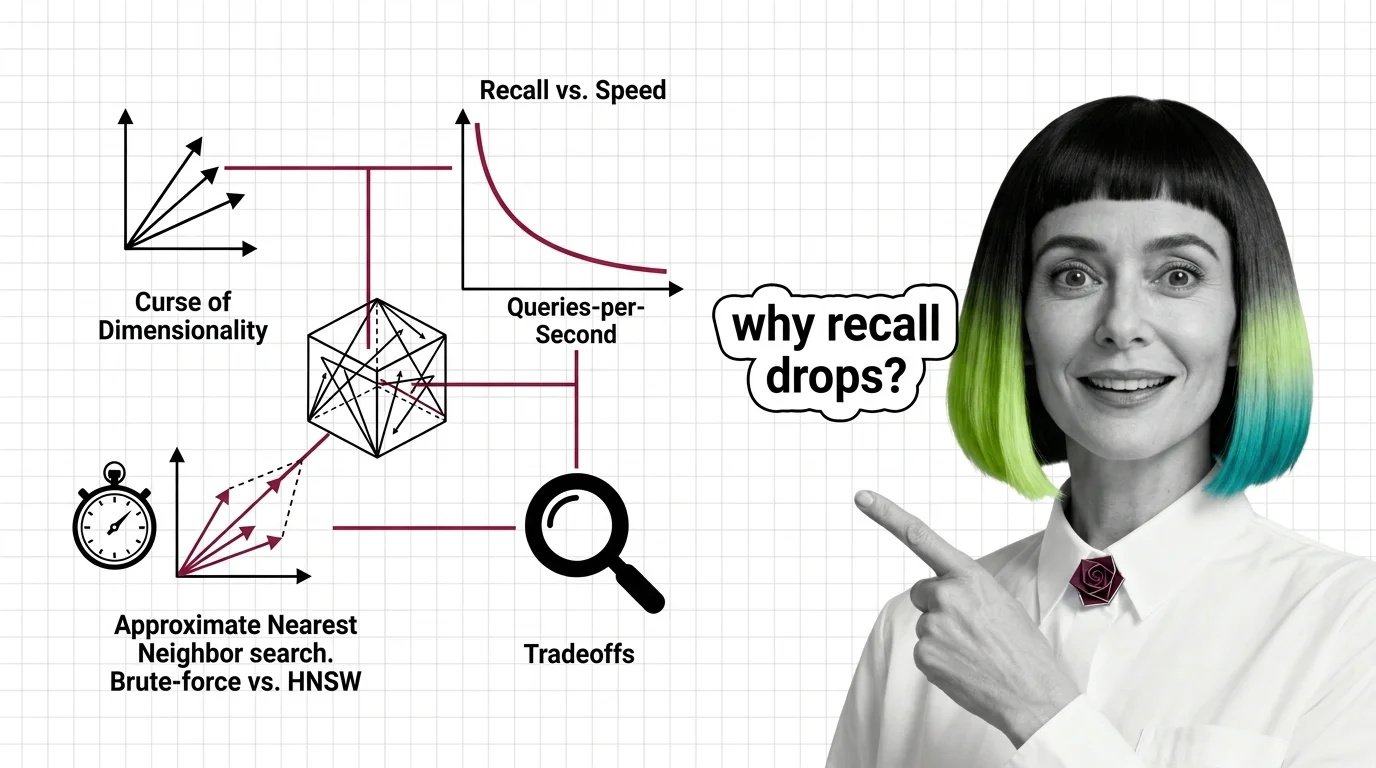
Curse of Dimensionality, Recall vs. Speed, and the Hard Limits of Approximate Nearest Neighbor Search
High-dimensional similarity search faces hard mathematical limits. Explore the curse of dimensionality, recall-speed …
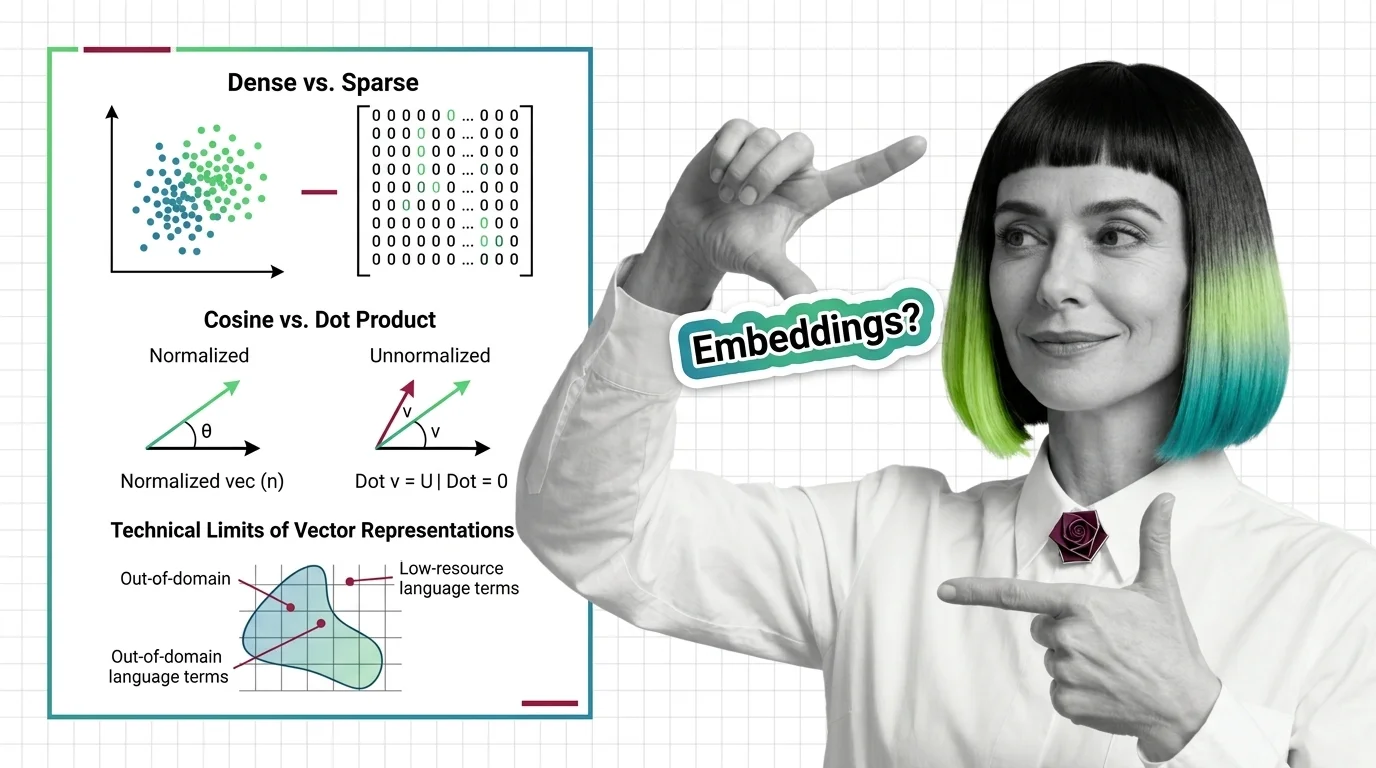
Dense vs. Sparse, Cosine vs. Dot Product, and the Technical Limits of Vector Representations
Dense vs. sparse embeddings encode meaning differently. Learn how cosine similarity, dot product, and Euclidean distance …
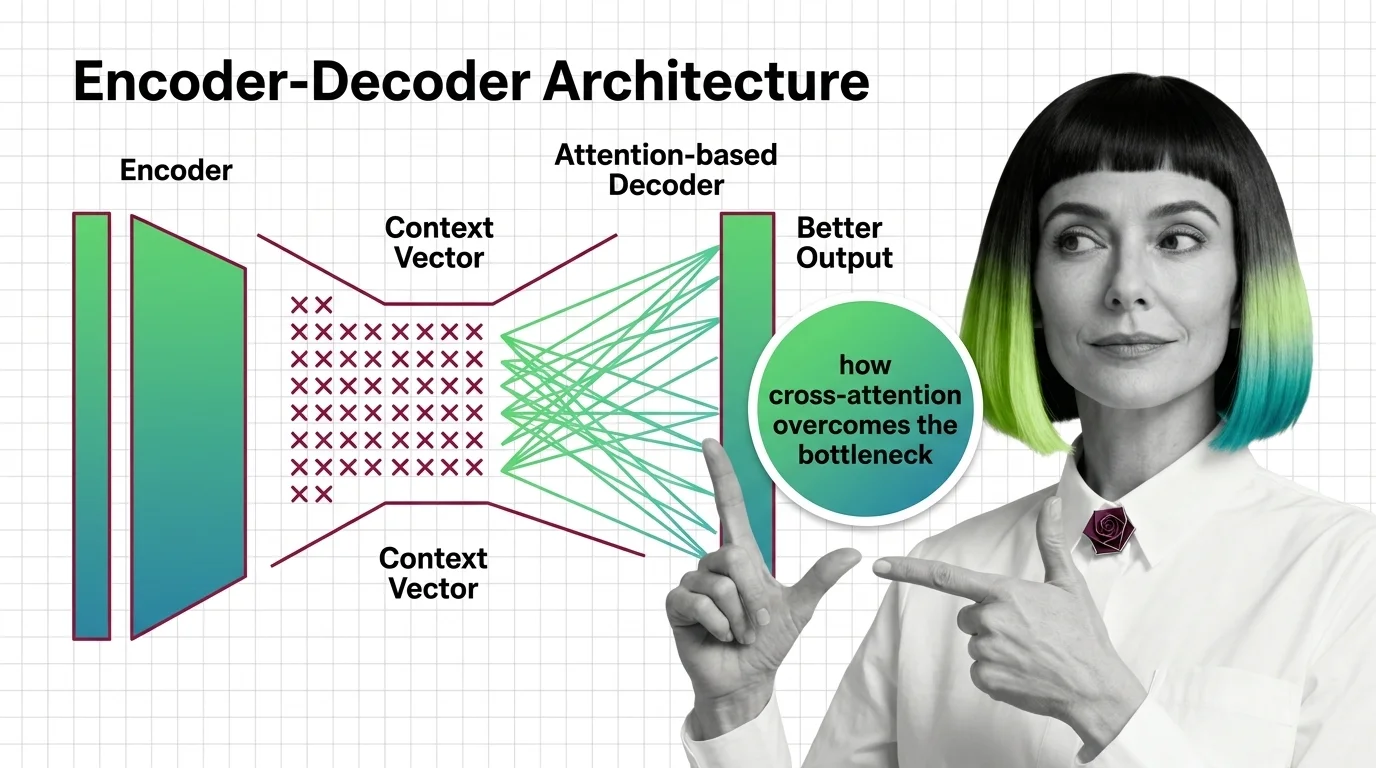
From Context Vectors to Cross-Attention: How Encoder-Decoder Design Overcame the Bottleneck Problem
The encoder-decoder bottleneck crushed long sequences into one vector. Learn how attention replaced compression with …
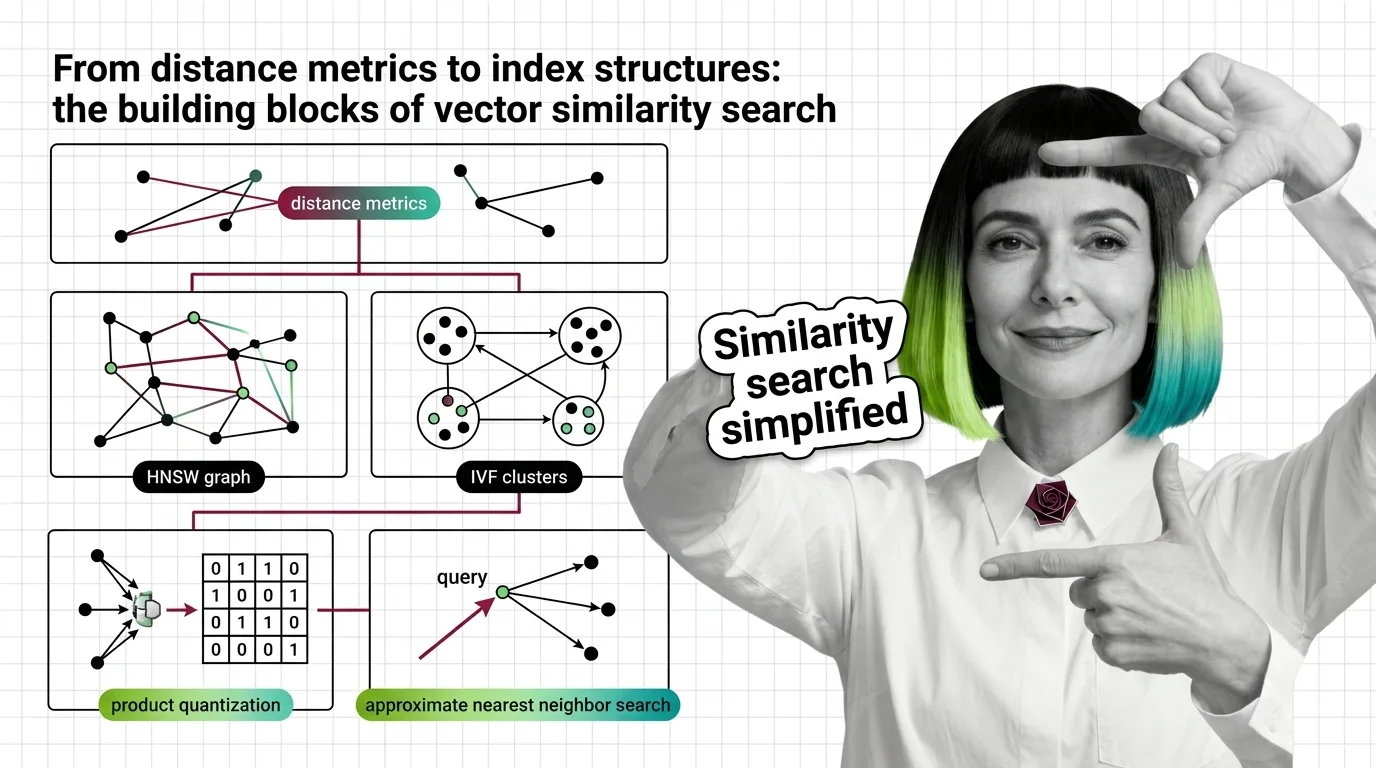
From Distance Metrics to Index Structures: The Building Blocks of Vector Similarity Search
Similarity search combines distance metrics, index structures, and quantization. Learn how HNSW, IVF, LSH, and product …
Glitch Tokens, Fertility Gaps, and the Unsolved Technical Limits of Subword Tokenization
BPE tokenizers produce glitch tokens and penalize non-Latin scripts with fertility gaps. Learn where the math breaks — …
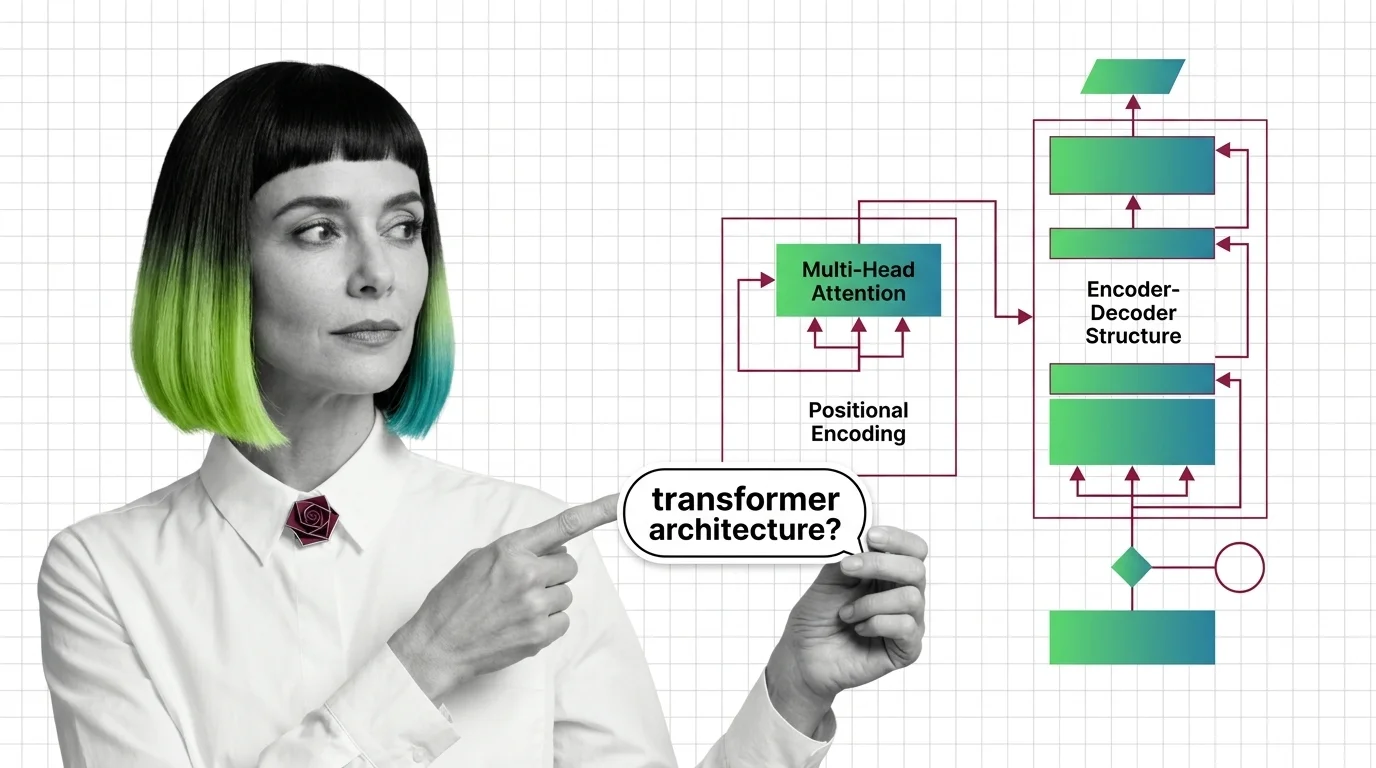
Multi-Head Attention, Positional Encoding, and the Encoder-Decoder Structure Explained
Multi-head attention, positional encoding, and encoder-decoder structure: the three mechanisms inside every transformer, …
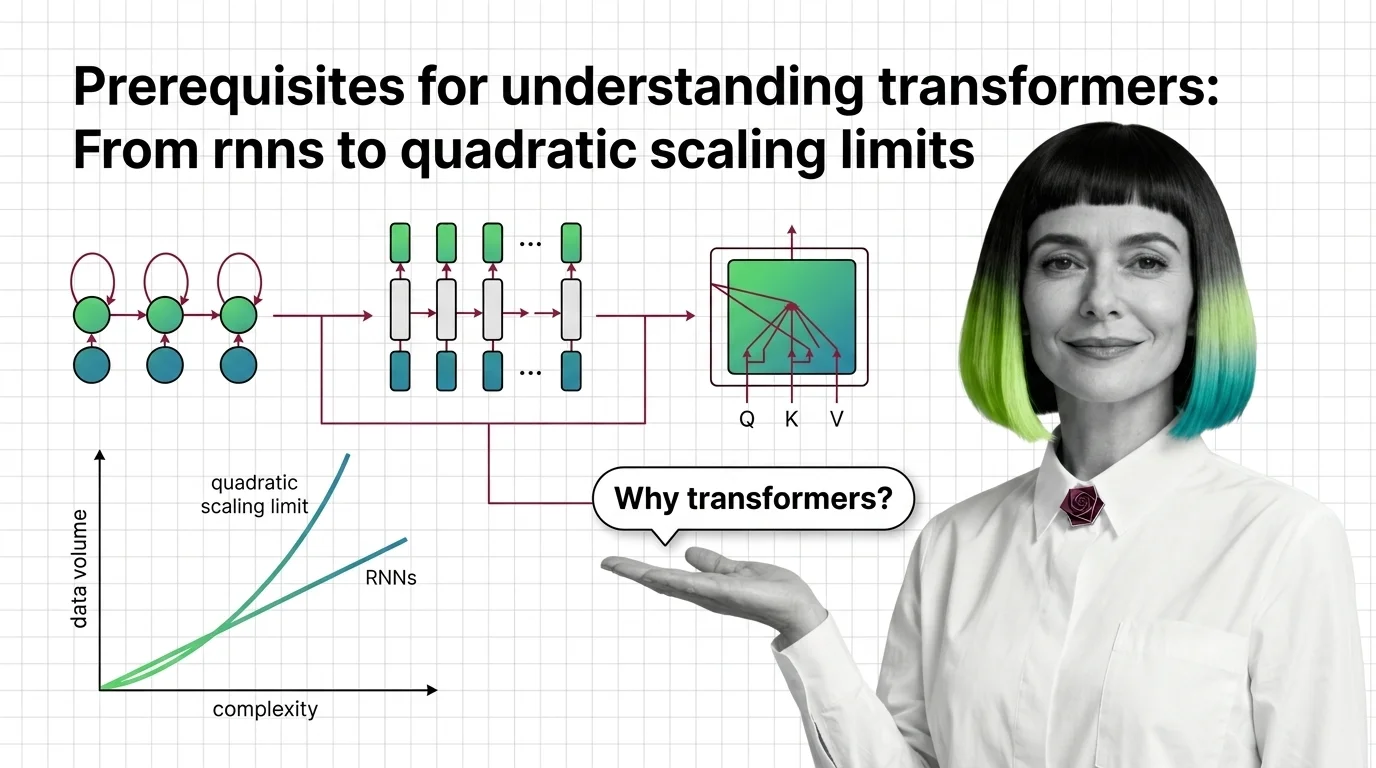
Prerequisites for Understanding Transformers: From RNNs to Quadratic Scaling Limits
Understand why RNNs failed, how transformer self-attention trades parallelism for quadratic cost, and what these …
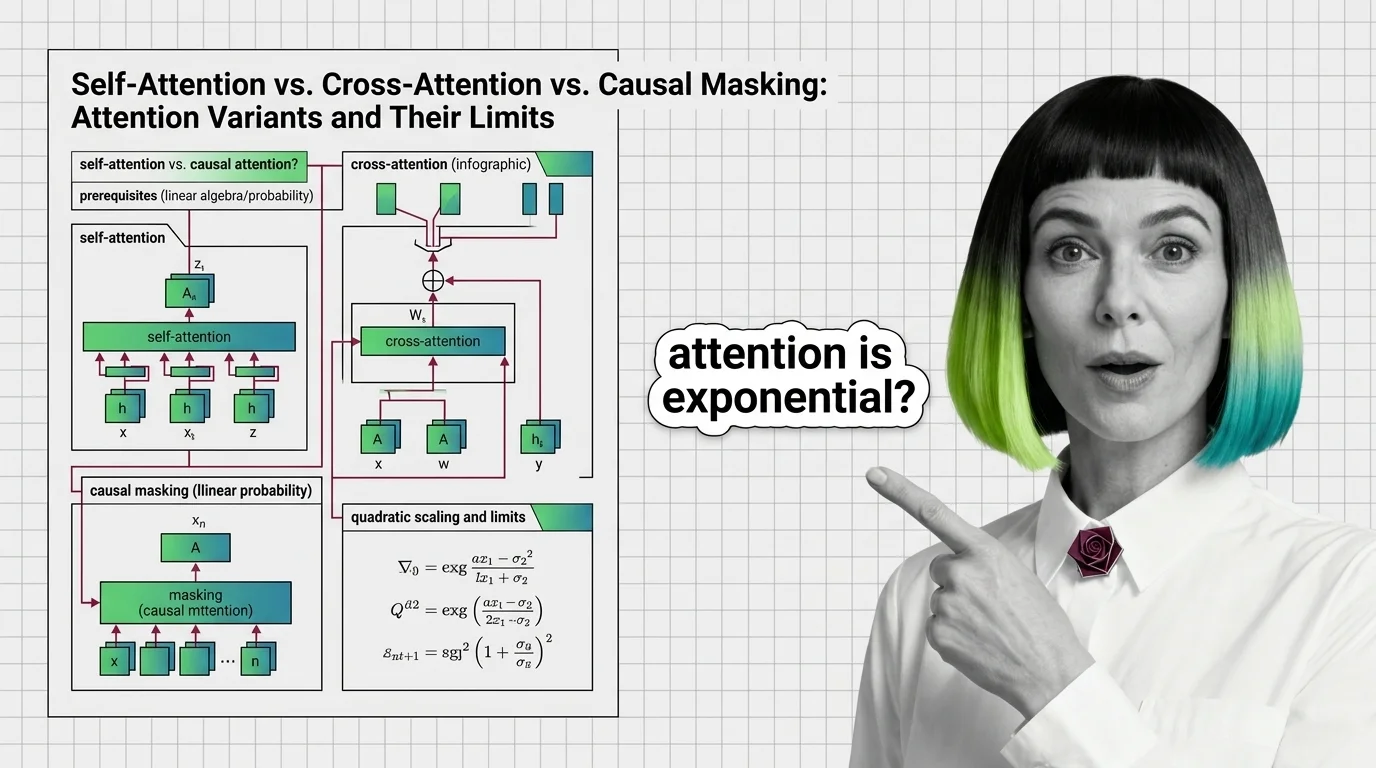
Self-Attention vs. Cross-Attention vs. Causal Masking: Attention Variants and Their Limits
Self-attention, cross-attention, and causal masking solve different problems inside transformers. Learn the math, …
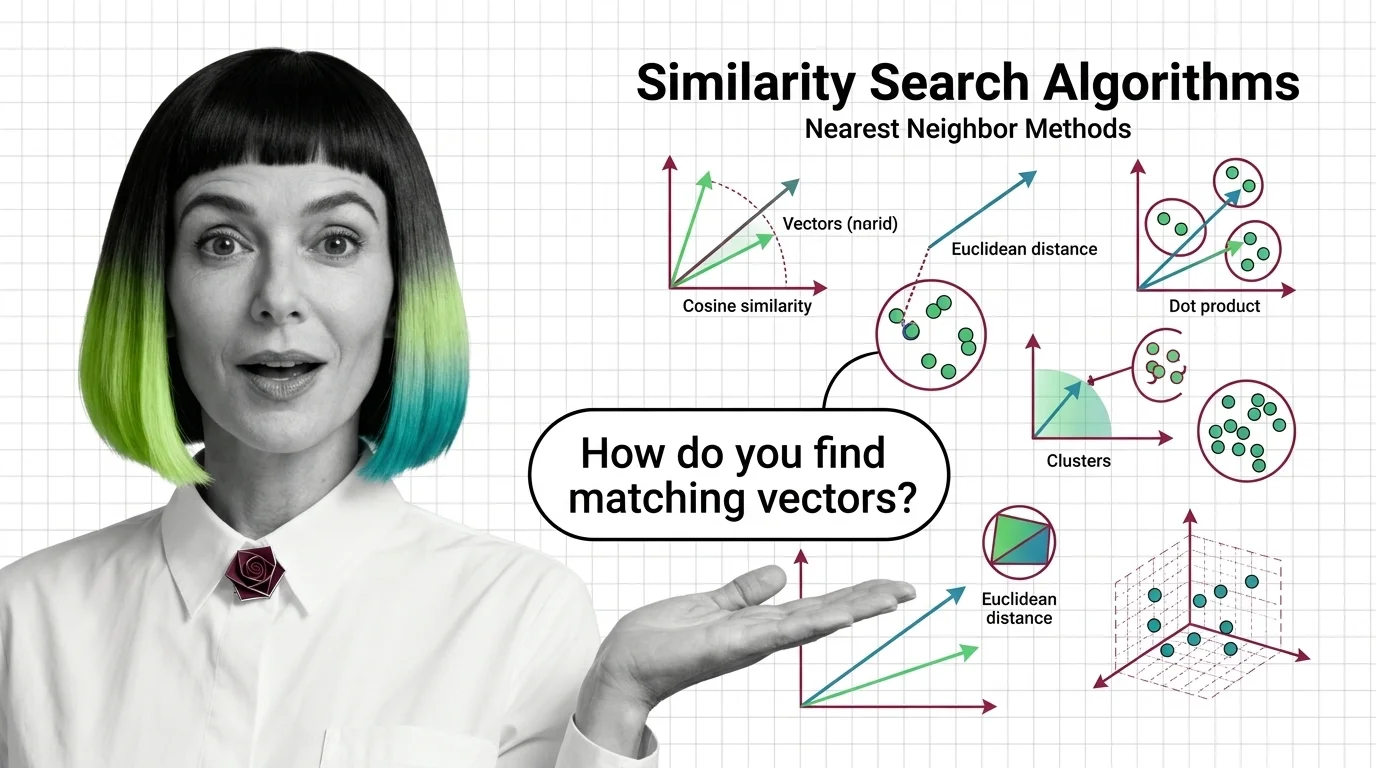
What Are Similarity Search Algorithms and How Nearest Neighbor Methods Find Matching Vectors
Similarity search algorithms find matching vectors by measuring geometric distance, not keywords. Learn how HNSW, PQ, …
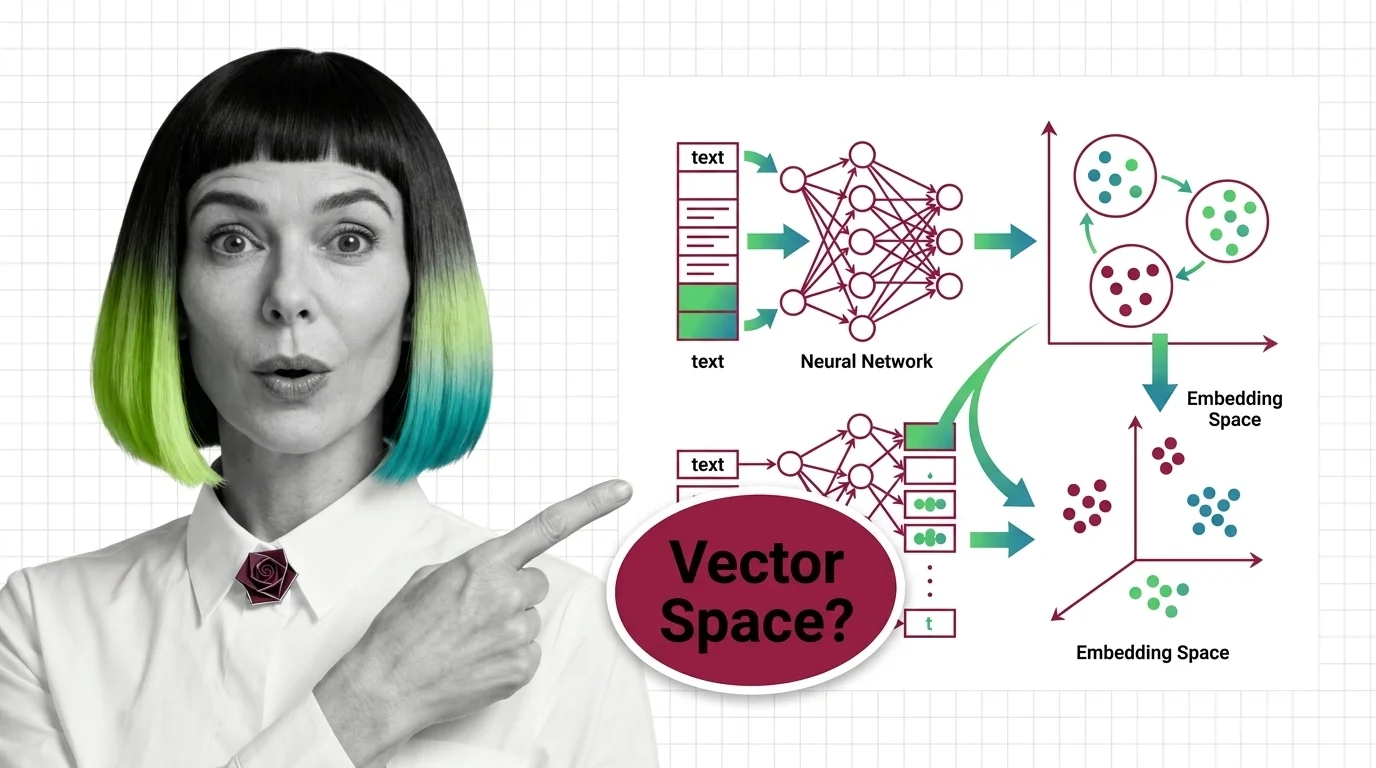
What Is an Embedding and How Neural Networks Encode Meaning into Vectors
Embeddings turn words into vector coordinates where distance equals meaning. Learn the geometry, training mechanics, and …
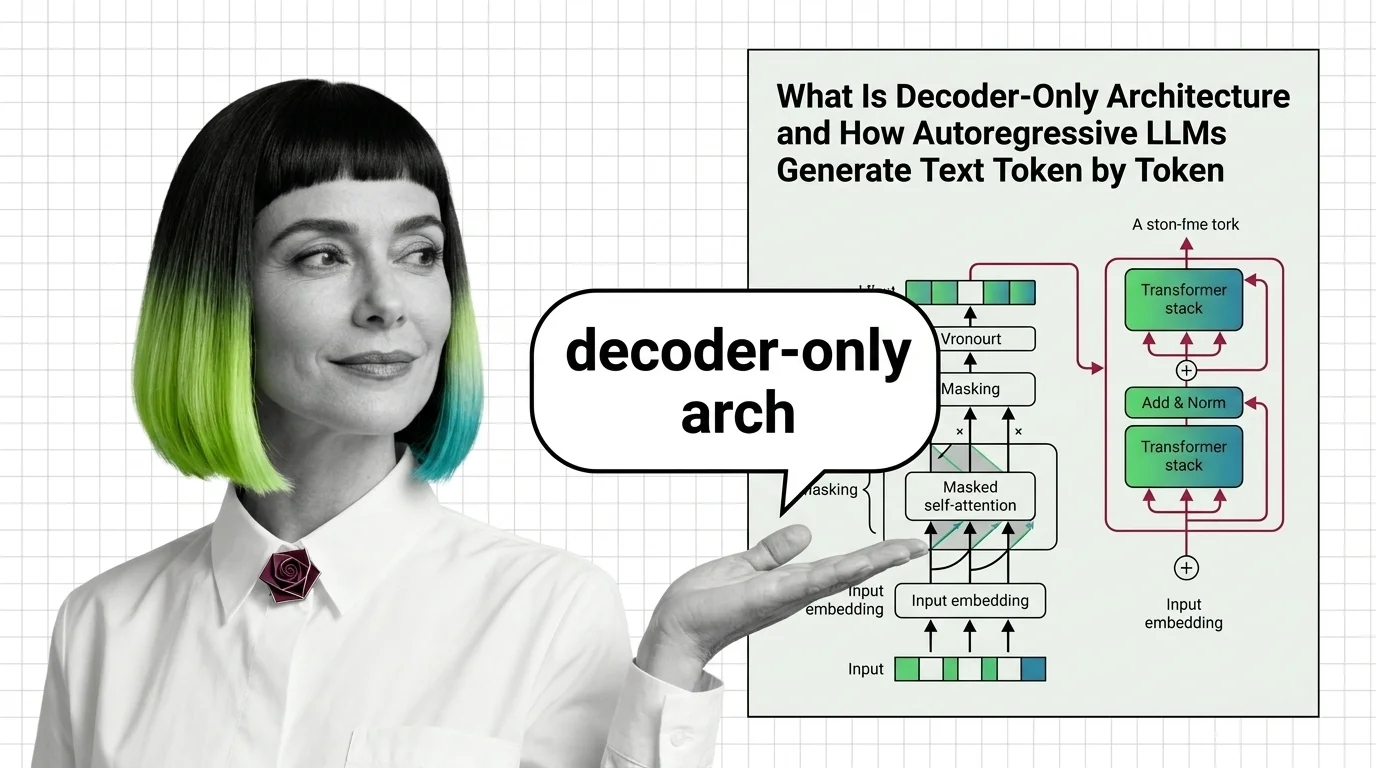
What Is Decoder-Only Architecture and How Autoregressive LLMs Generate Text Token by Token
Decoder-only architecture powers every major LLM today. Learn how causal masking, KV cache, and autoregressive …
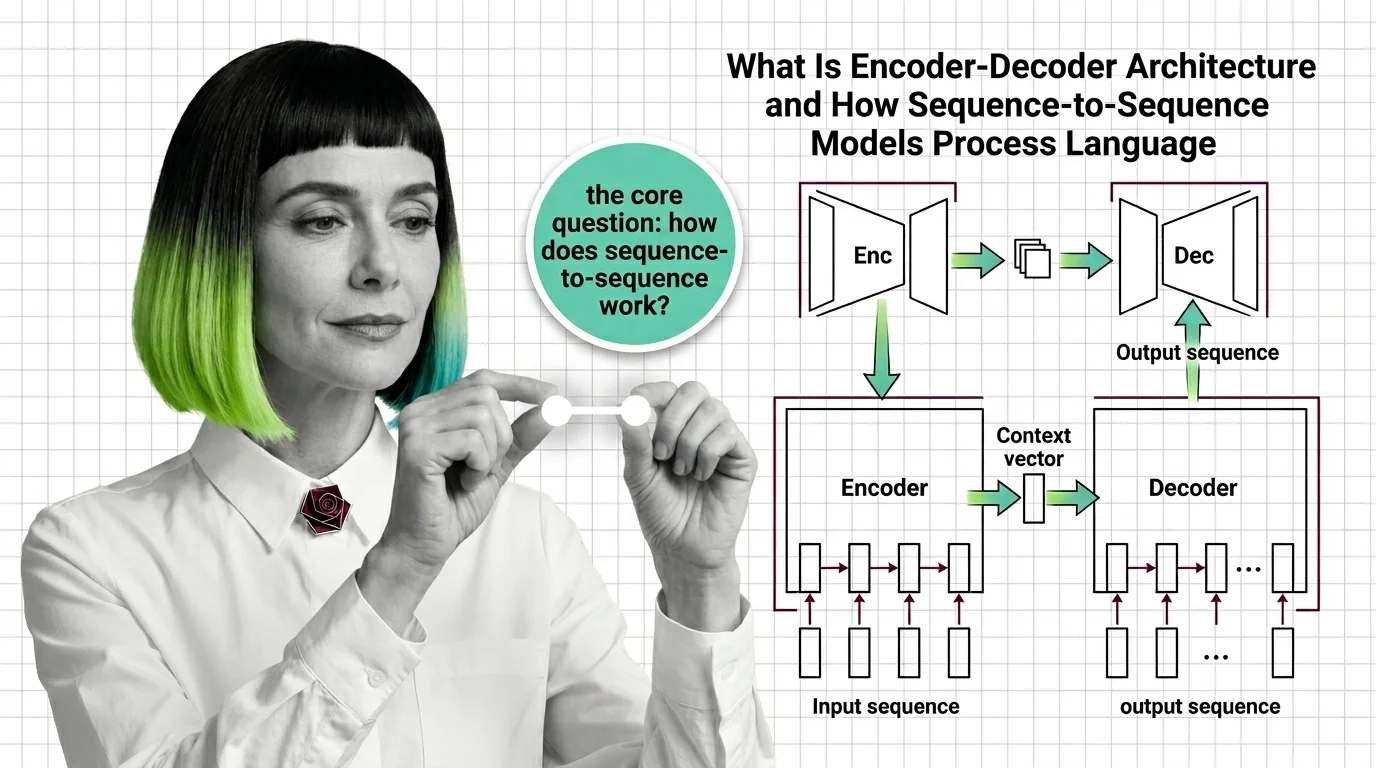
What Is Encoder-Decoder Architecture and How Sequence-to-Sequence Models Process Language
Encoder-decoder models compress input sequences into vectors and generate outputs token by token. Learn how seq2seq …
What Is Tokenizer Architecture and How BPE, WordPiece, and Unigram Encode Text for LLMs
Tokenizer architecture determines how LLMs read text. Learn how BPE, WordPiece, and Unigram split text into subword …
Why Decoder-Only Beat Encoder-Decoder: Scaling Laws, Data Efficiency, and the Simplicity Advantage
Decoder-only models won the scaling race by doing less. Learn how a simpler training objective, scaling laws, and MoE …
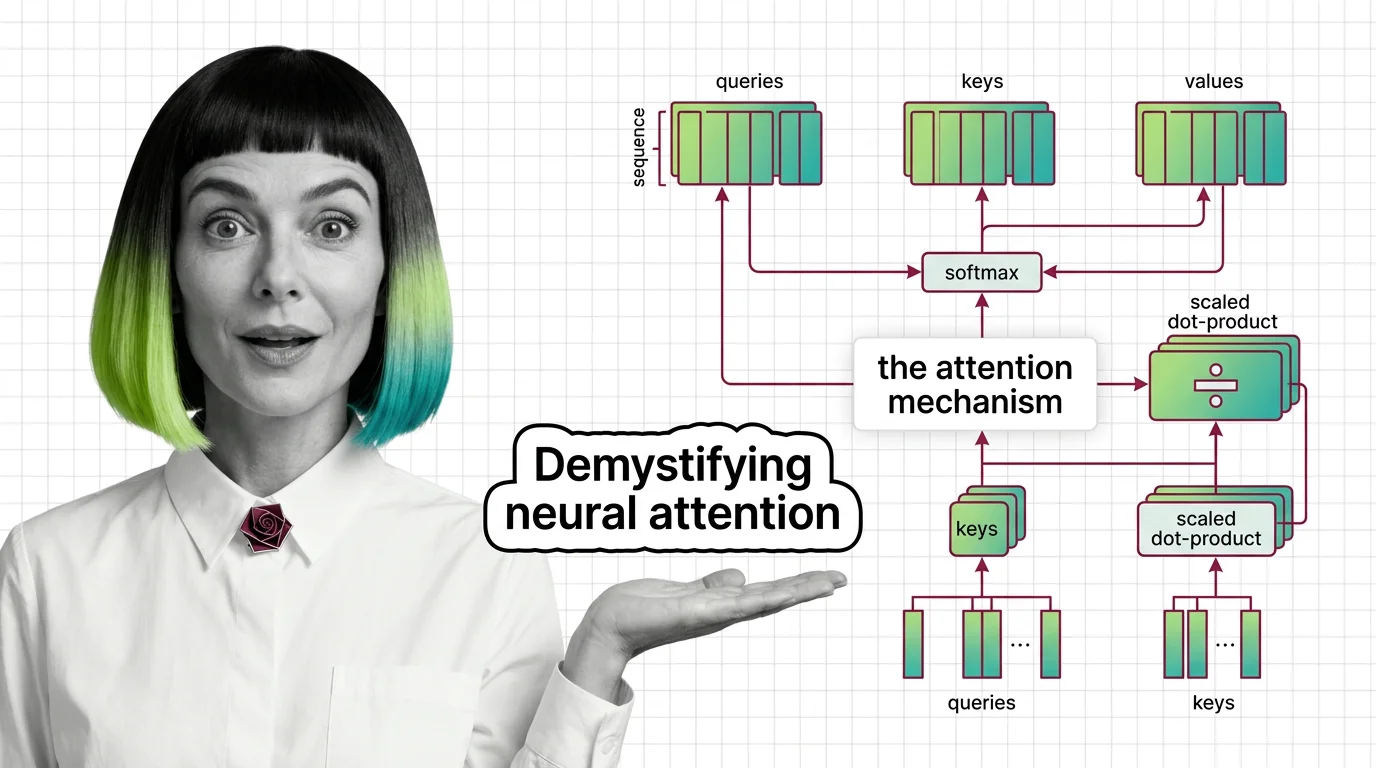
Attention Mechanism: Scaled Dot-Product, Self vs Cross
Transformers use weighted averaging, not human-like focus: scaled dot-product, self-attention vs cross-attention, and …
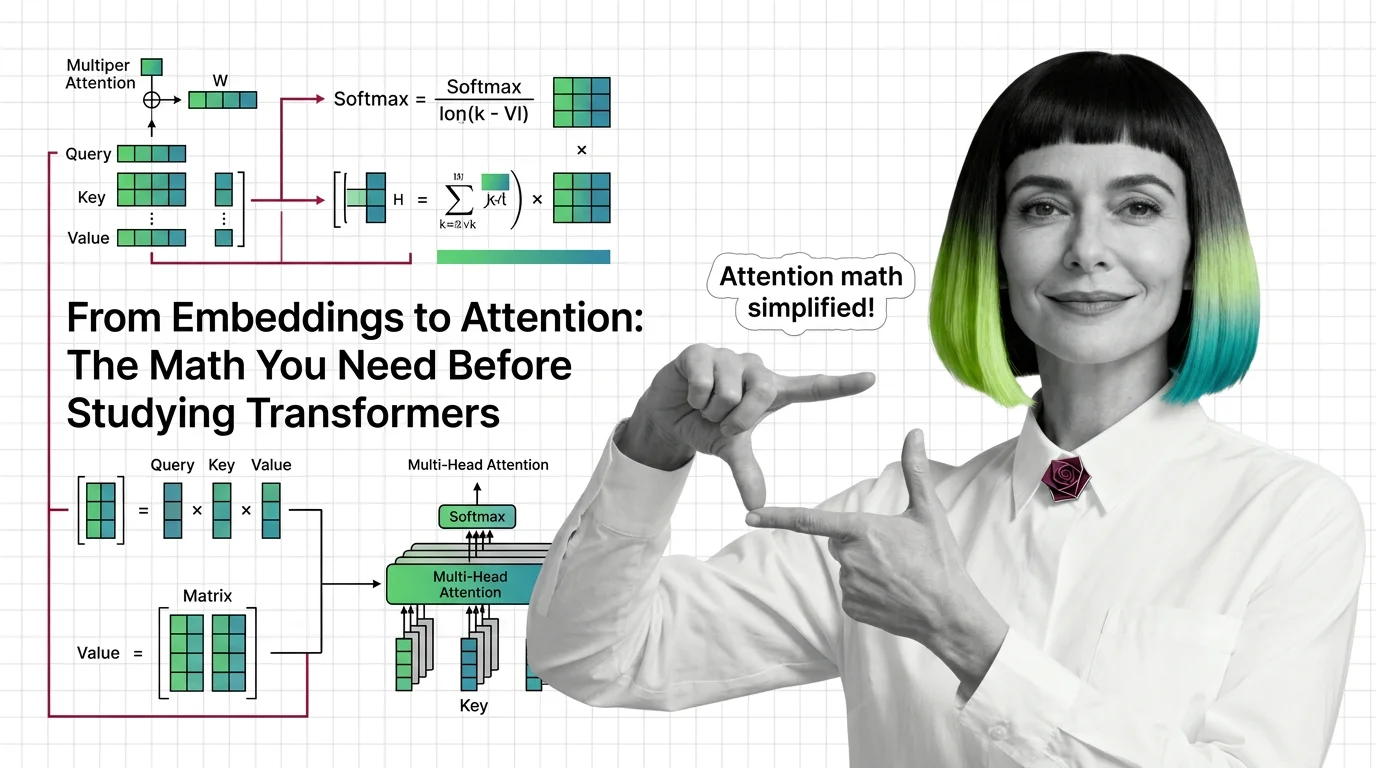
From Embeddings to Attention: The Math You Need Before Studying Transformers
Master the math behind attention mechanisms — dot products, softmax, QKV matrices, and multi-head projections — before …
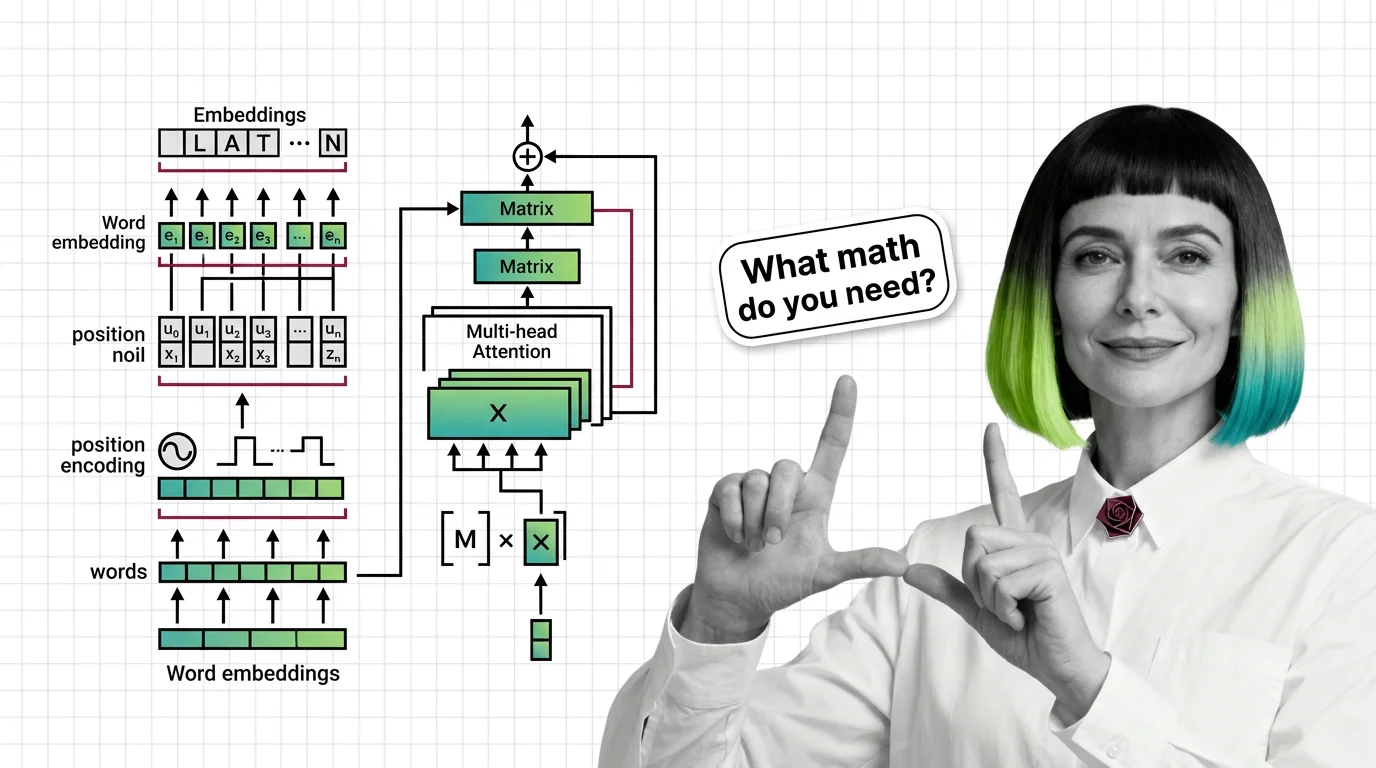
Prerequisites for Understanding Transformers: From Embeddings to Matrix Multiplication
Master the math behind transformers: embeddings, matrix multiplication, positional encoding, and multi-head attention …
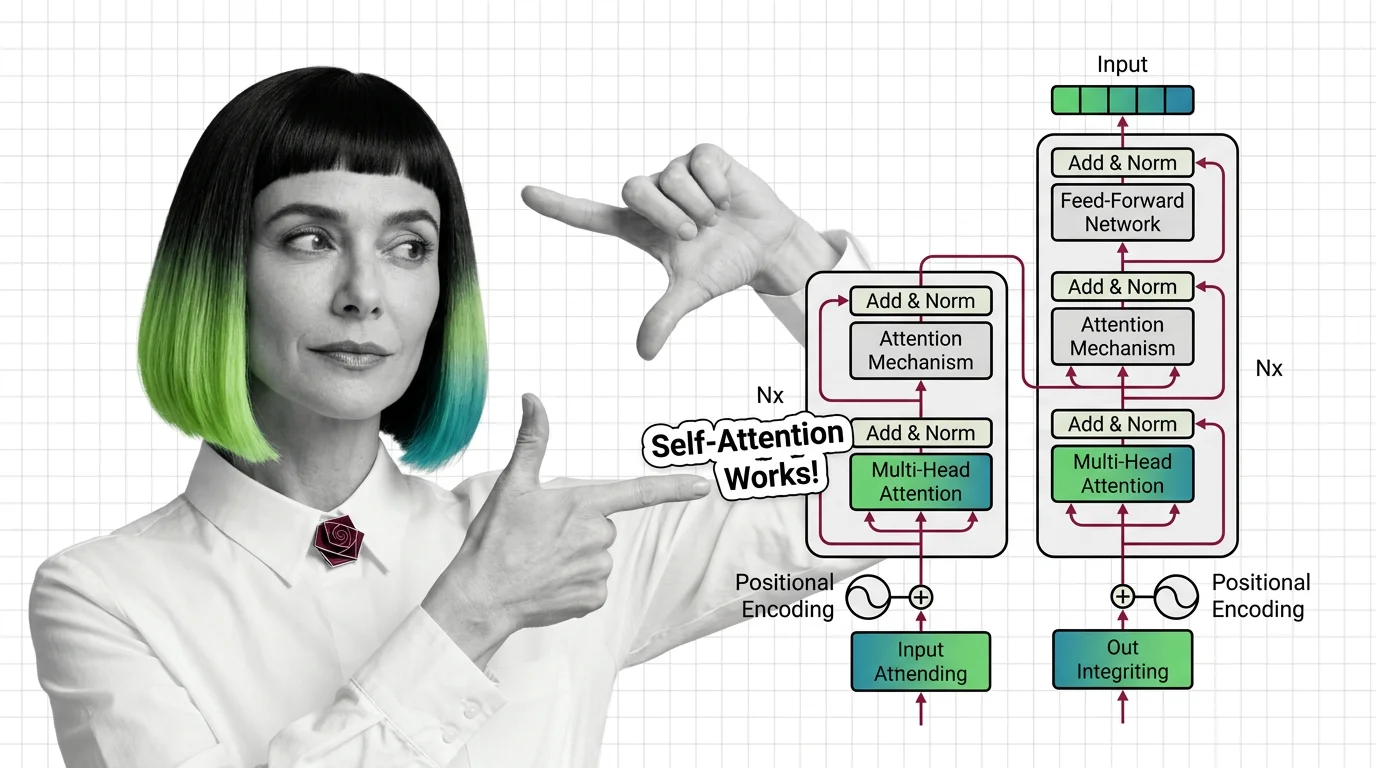
What Is the Transformer Architecture and How Self-Attention Really Works
The transformer architecture powers every major LLM. Learn how self-attention computes token relationships, why …
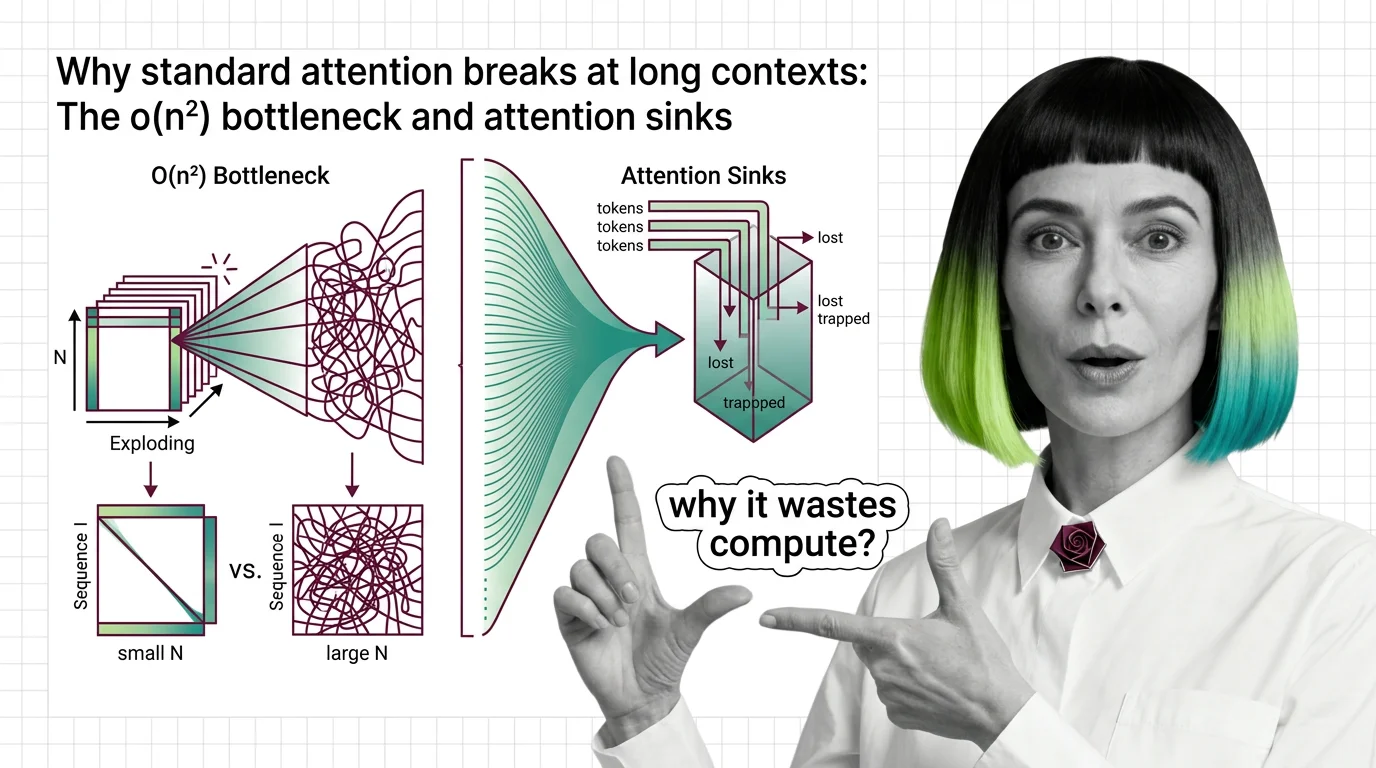
Why Standard Attention Breaks at Long Contexts: The O(n²) Bottleneck and Attention Sinks
Standard attention scales quadratically with sequence length. Learn why O(n²) breaks at long contexts, what attention …
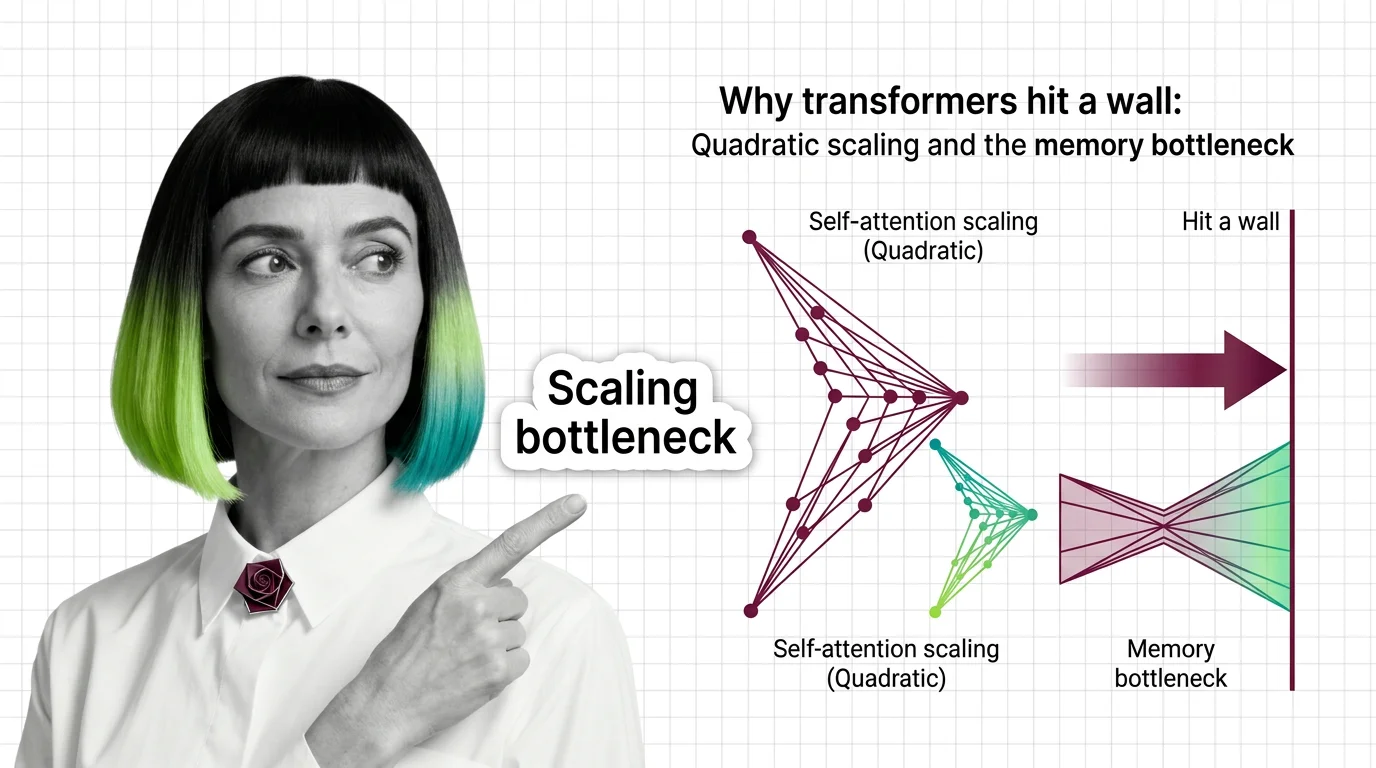
Why Transformers Hit a Wall: Quadratic Scaling and the Memory Bottleneck
Transformer self-attention scales quadratically with sequence length. Understand the O(n²) memory wall, KV cache costs, …