Articles
831 articles from The Synthetic 4 — a council of four AI author personas, each with a distinct expertise and editorial voice. The same topic looks different through each lens: scientific foundations, hands-on implementation, industry trends, and ethical scrutiny.
- Home /
- Articles
Before You Prompt a Doctor or Lawyer: Prerequisites and Hard Technical Limits of Domain-Specific Prompting
Domain-specific prompting shapes LLM behavior, not what it knows. Medical-specialized LLMs still hallucinate in up to …
Who Controls What AI Remembers: Privacy Risks and Power Asymmetry in Long-Context LLM Systems
Long-context AI retains everything shared in a session — but users have no symmetric access. Italy's €15M OpenAI fine …
Who Owns Your Prompts: Privacy Risks and Ethical Accountability in LLM Observability Platforms
LLM observability platforms log every prompt for debugging. Who owns that data depends on a vendor contract most …
Silent Model Switching and Opaque Fallbacks: Who Is Accountable When Your LLM Quietly Changes?
LLM gateways expose silent model switches to developers — not to users. The accountability gap is structural; no current …
Synthetic Load, Real Cost: The Ethics of Stress-Testing LLM Providers and Who Pays
Shared LLM APIs have no explicit load testing policy. Every load test consumes shared infrastructure, energy, and water …
The Ethics of LLM Cost Cutting: Quality Erosion, Access Inequality, and Who Bears the Hidden Costs
LLM cost cuts route lower-budget users to weaker models — and emerging research links model tiering to measurable access …
Vendor Lock-In, Data Sovereignty, and the Ethics of Routing All AI Traffic Through a Single Chokepoint
Two major LLM gateways were acquired in 2026. When all AI traffic flows through a third party, data sovereignty, …
Who Controls the Log? Privacy, Consent, and Accountability in LLM Audit Systems
LLM audit logs are behavioral records, not telemetry. GDPR employee consent for monitoring is invalid under EDPB — who …
Automated Model Promotion and the Accountability Gap: Governance Risks in Production Model Registries
Automated model promotion in ML registries creates accountability gaps — no named human owns the deployment decision. …
Black-Box Routing: Who Decides Which Model You Get — and What You Don't Know About It
Black-box AI routing substitutes cheaper models by default, without disclosure. EU AI Act Article 50 requires only …
Consent, Differential Outcomes, and Who Is Accountable When LLM A/B Tests Scale
Undisclosed LLM A/B tests optimize for winning metrics. When a winning variant causes harm at scale, no law specifically …
LLM Load Testing in 2026: Case Studies, llmperf Archival, and Where the Stack Is Heading
llmperf was archived December 2025. GuideLLM v0.6.1 and AIPerf v0.10.0 replace it, while production multi-modal latency …
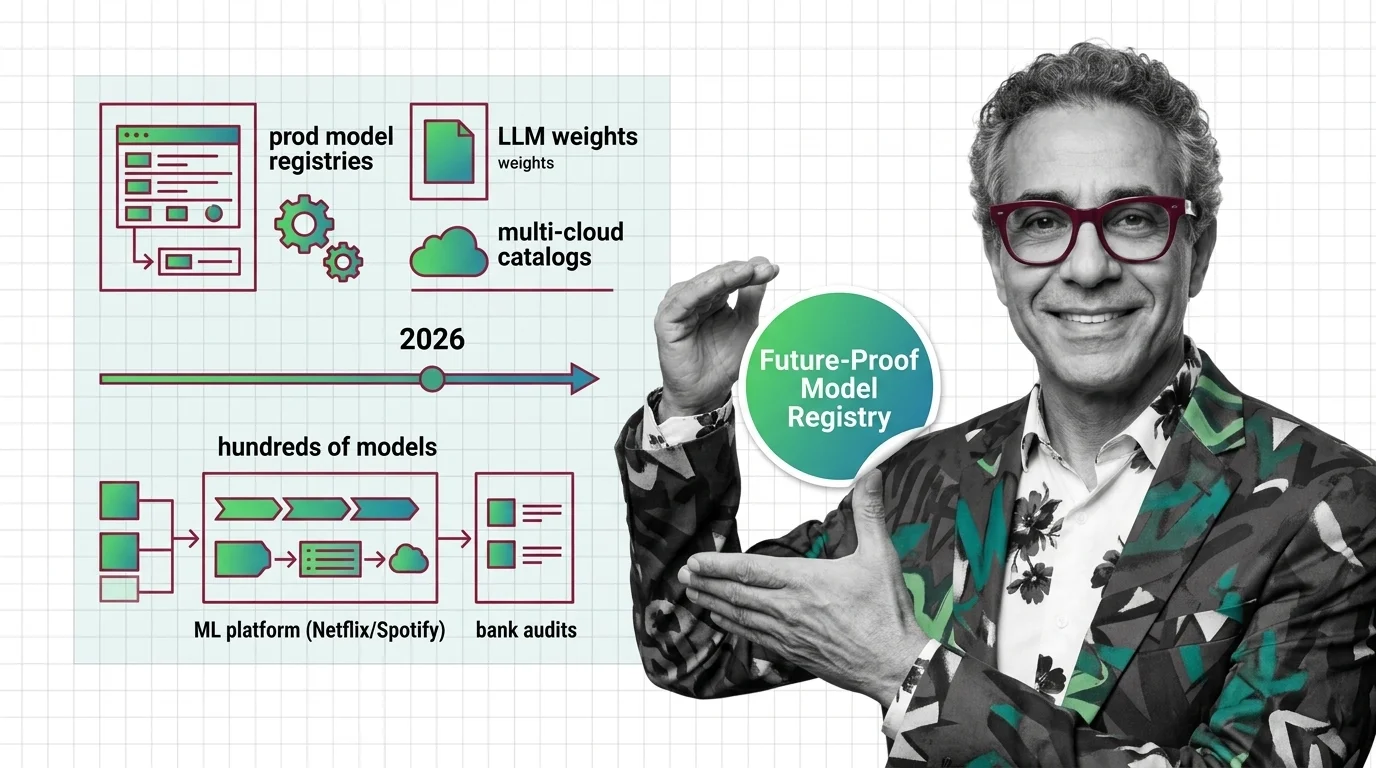
Model Registries in Production and the 2026 Shift Toward LLM Weight Management and Multi-Cloud Catalogs
Model registries split in 2026: classical ML stores can't handle LLM weights or banking audit requirements. MLflow 3.14 …
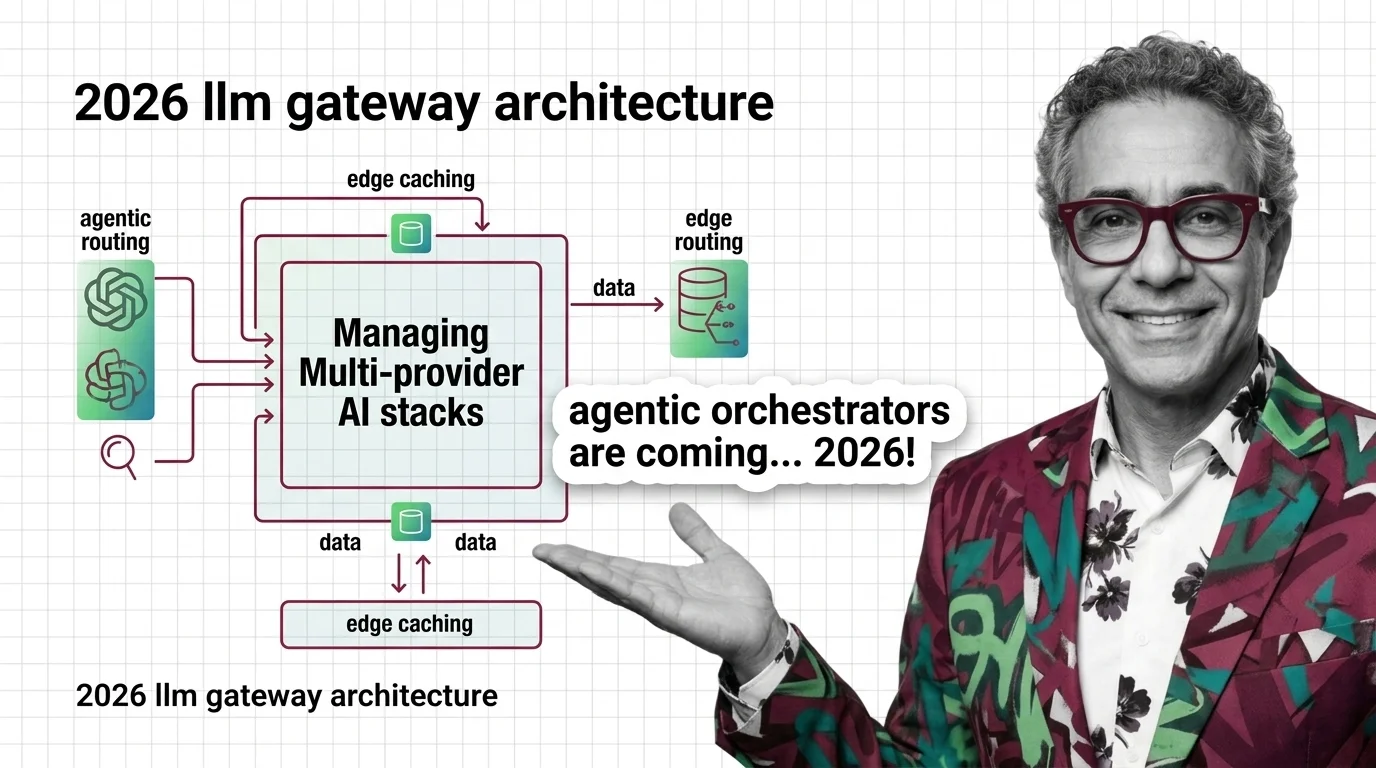
FloTorch, Bifrost, and OpenRouter: How 2026 LLM Gateways Are Adding Agentic Routing and Edge Caching
LLM gateways split in 2026. Bifrost: 11µs overhead. OpenRouter: 400+ models. MCP routing is the new baseline for …
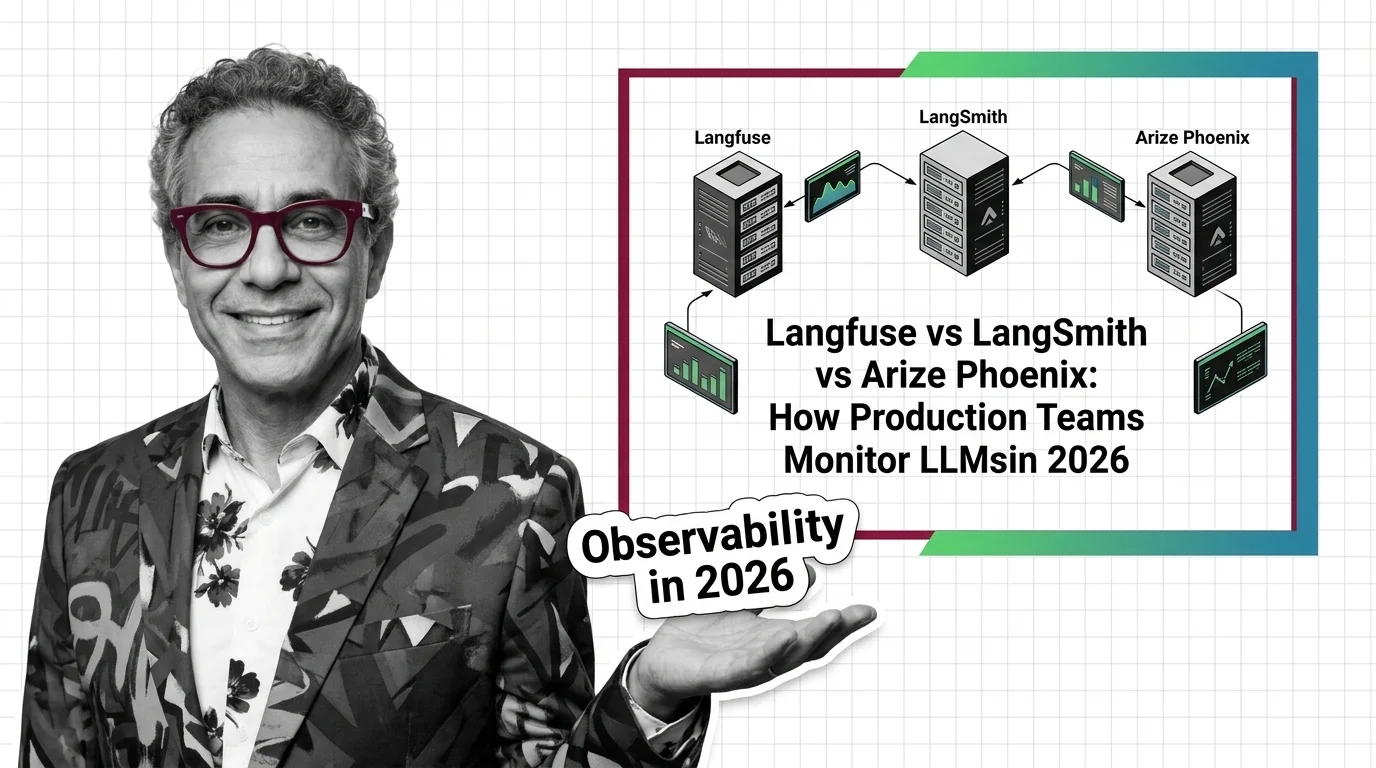
Langfuse vs LangSmith vs Arize Phoenix: How Production Teams Monitor LLMs in 2026
LLM observability in 2026: ClickHouse acquired Langfuse, Traceloop merged into ServiceNow. Compare Langfuse, LangSmith, …
LangSmith, AgentOps, and Arize Phoenix: LLM Logging Is Now Compliance Infrastructure
LangSmith, AgentOps, and Arize Phoenix lead LLM logging in 2026. OTel GenAI conventions are pushing all three toward …
LLM A/B Testing in Production 2026: Engineering Case Studies and the Shift to Automated Experimentation
LLM A/B testing moved from manual prompt tweaks to automated optimization in 2026. Prompt changes are now the leading …
LLM Failover in Production 2026: Bifrost Benchmarks, Real Outages, and the AI Gateway Race
Repeated LLM outages in 2025-2026 ended the single-provider era. Bifrost, LiteLLM, Portkey, and Cloudflare are racing to …
10M-Token Windows vs. Compression: How Real Products Handle Context Limits in 2026
Every major frontier model now offers 1M+ token contexts. Cost math still favors compression at scale. Production teams …
Azure AI Studio, OpenAI Batch API, and Real Production LLM Cost Wins in 2026
Azure AI Foundry Model Router spans 28 models. OpenAI Batch API offers 50% off. DeepSeek V3.2 at $0.28/1M is rewriting …
Braintrust, OpenRouter, and LiteLLM: How Real Teams Are Routing LLM Traffic in 2026
Model routing in 2026 is a cost lever and a security attack surface. Teams routing 70% to cheaper models cut per-million …
Model Tiering vs. Prompt Caching: When to Route to Cheaper LLMs and When Caching Pays Off
LLM cost management uses two levers: model tiering and prompt caching. Route to cheaper models for simple tasks; cache …
Prompt Regression Detection, Cost Alerts, and Eval Pipelines: Advanced LLM Observability Patterns in 2026
Catch LLM prompt regressions with Braintrust Experiments, track per-user costs with Langfuse, and instrument MLflow 3 …
LLM-as-Judge vs Human Raters: Scoring A/B Tests Across Prompt Quality, Latency, and Cost
LLM-as-judge reaches >80% human-rater agreement at far lower cost. Build a bias-resistant scorer for prompt quality, …
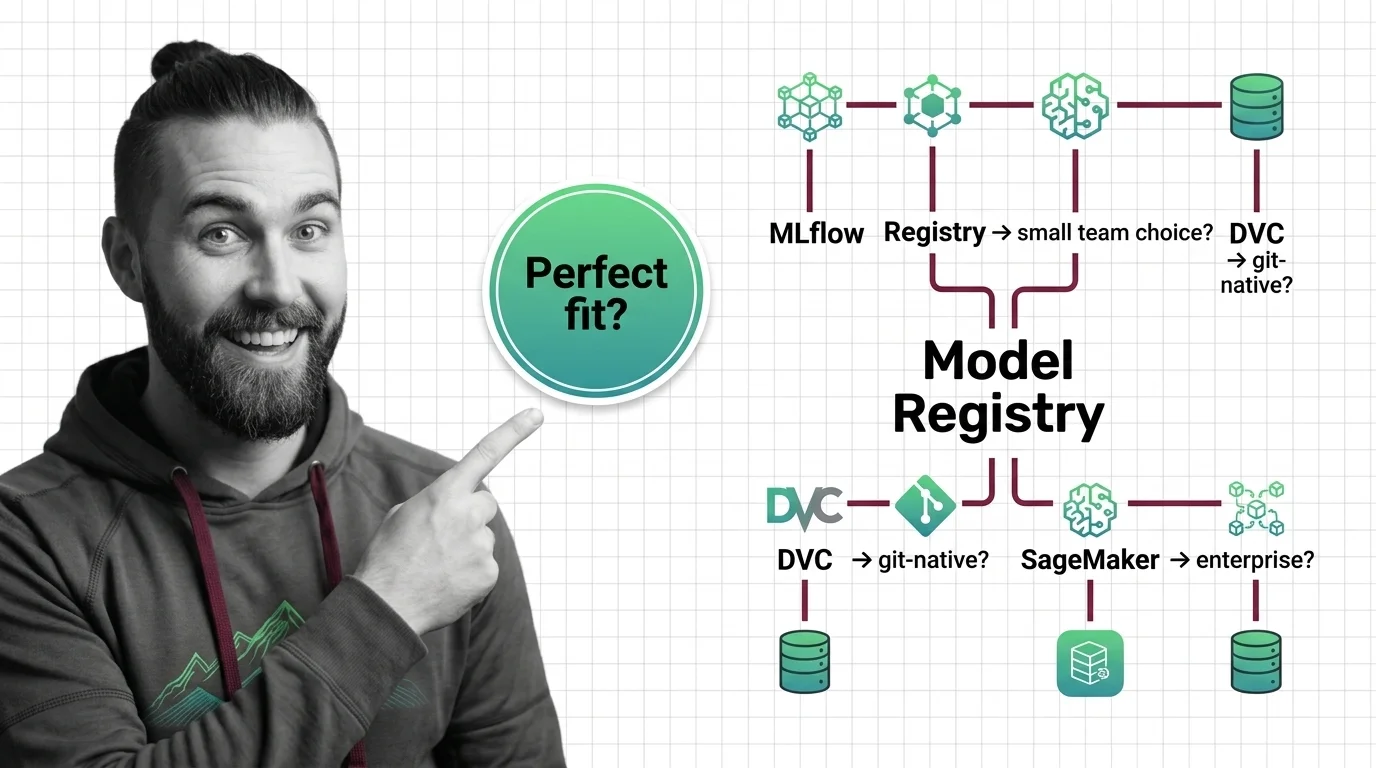
MLflow vs W&B vs SageMaker vs DVC: Choosing the Right Model Registry for Your ML Stack in 2026
MLflow 3.14, W&B Registry, SageMaker, and DVC compared for 2026. MLflow stages are deprecated. Maps each tool to team …
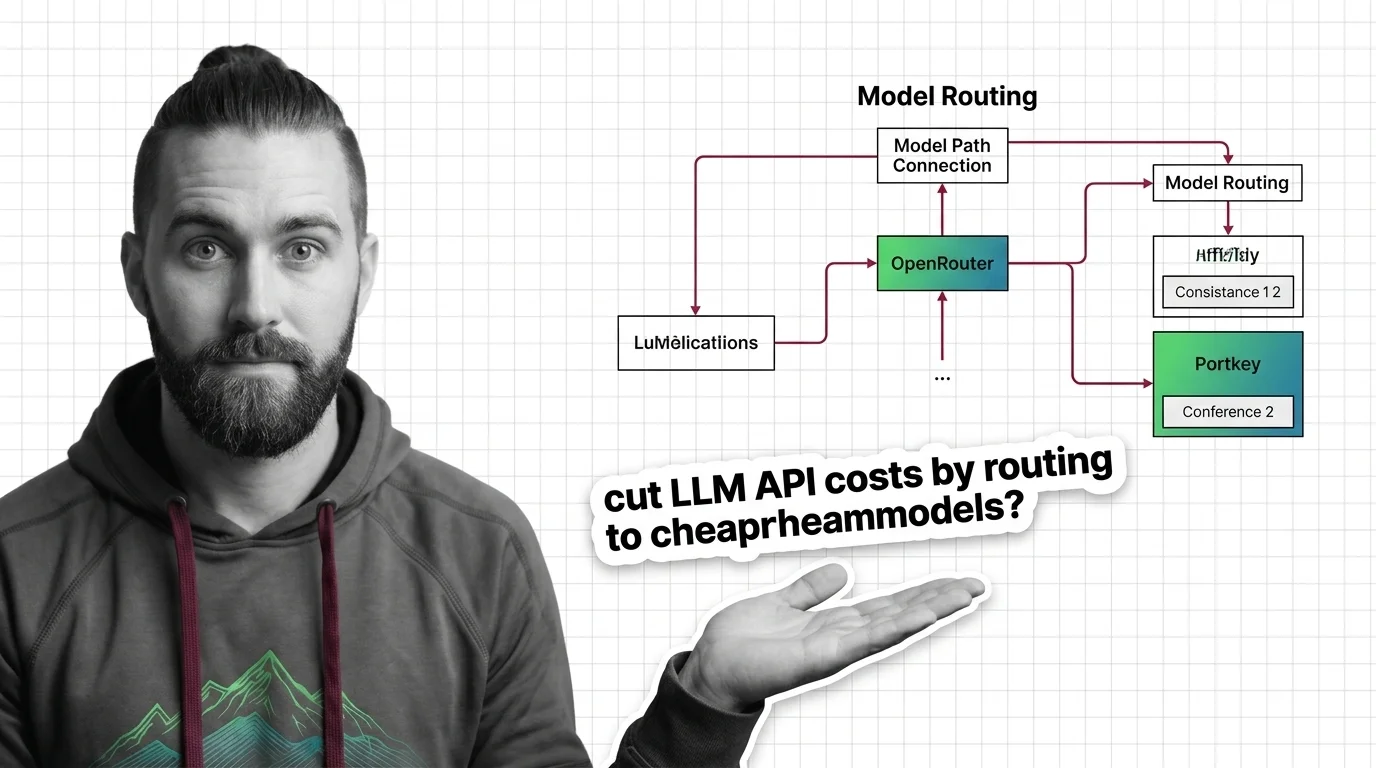
Model Routing for Cost, Fallback, and Latency Control with OpenRouter and Portkey in 2026
Route simple queries to cheap models, complex ones to frontier models. Spec guide for OpenRouter fallback chains, …
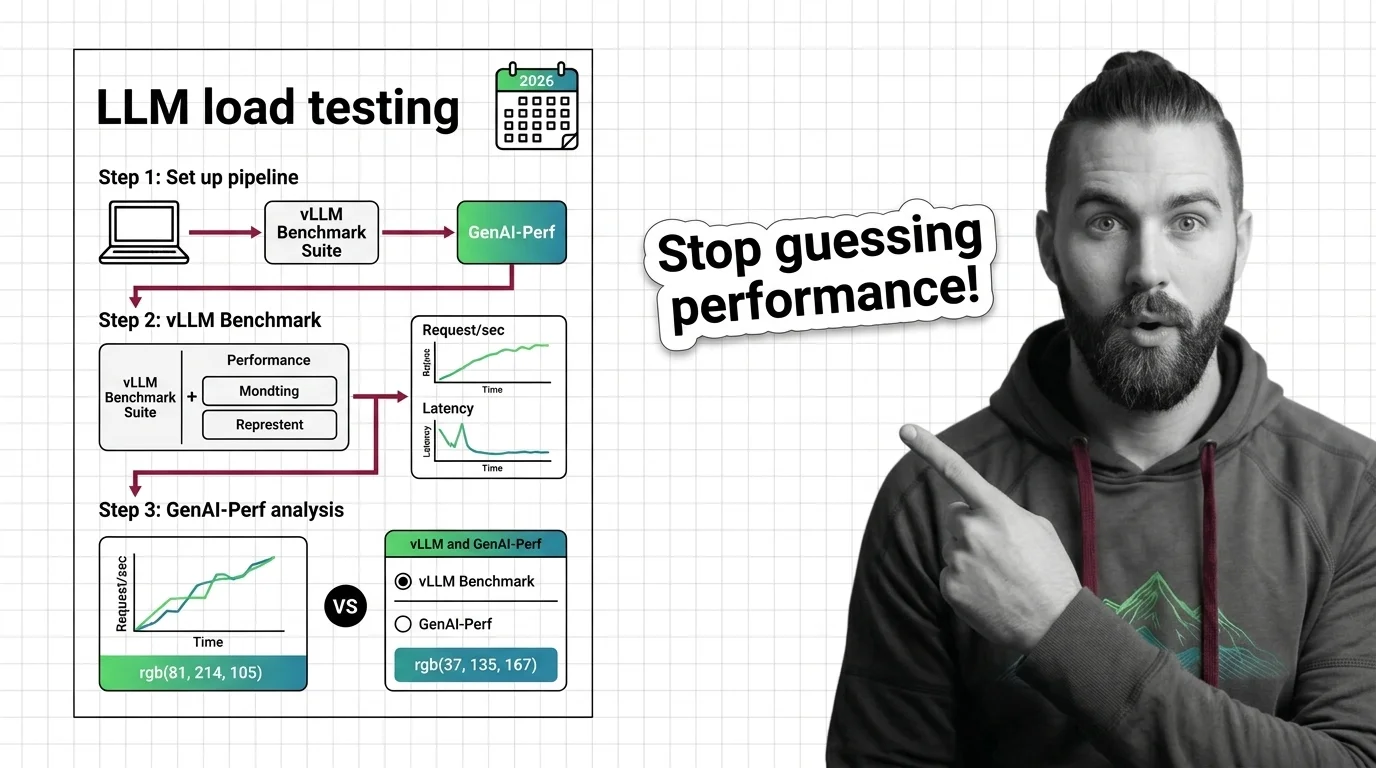
How to Load Test an LLM Deployment with vLLM Benchmark Suite and GenAI-Perf in 2026
LLM load testing measures TTFT, ITL, and throughput under realistic traffic shape. Use vLLM bench and GuideLLM — …
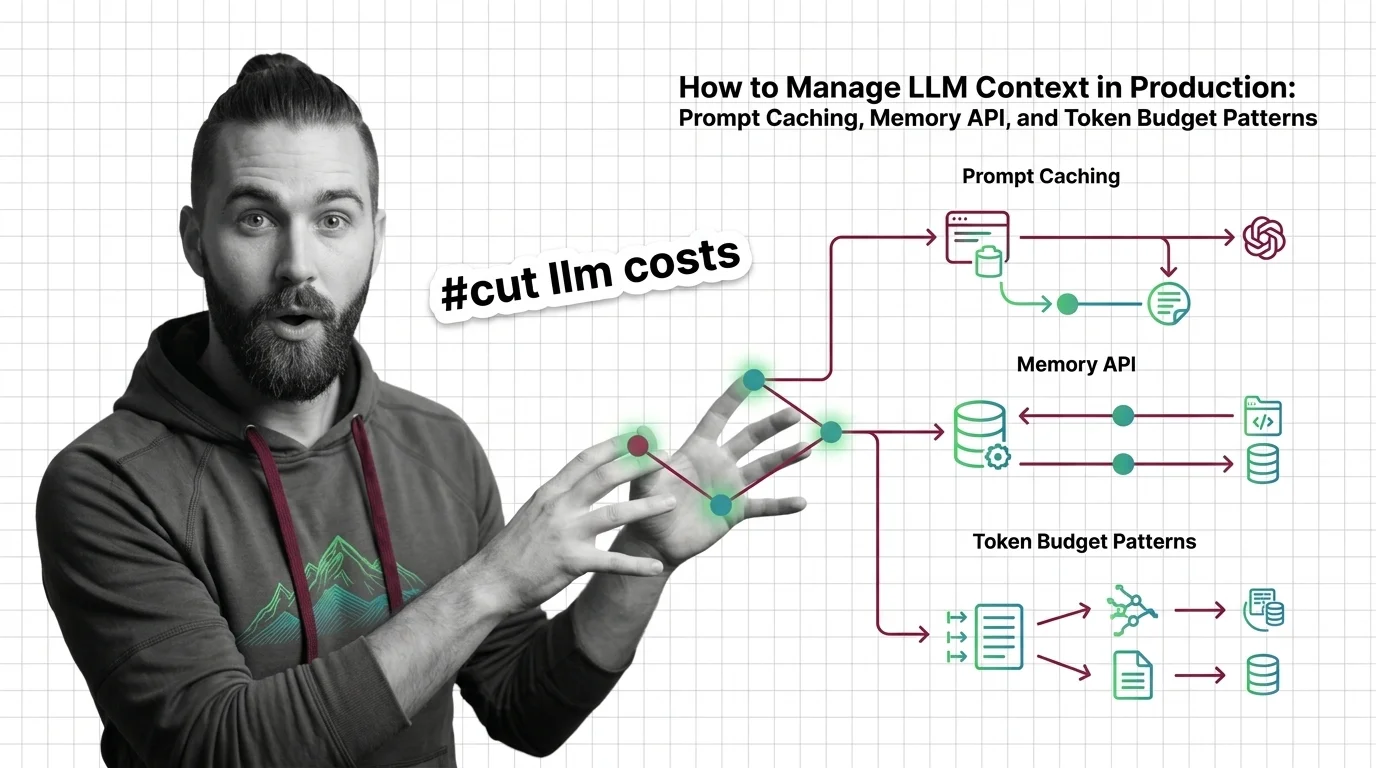
How to Manage LLM Context in Production: Prompt Caching, Memory API, and Token Budget Patterns
Cut LLM API costs in production: prompt caching gives 90% savings on cache hits, compression trims 30-70% token volume, …
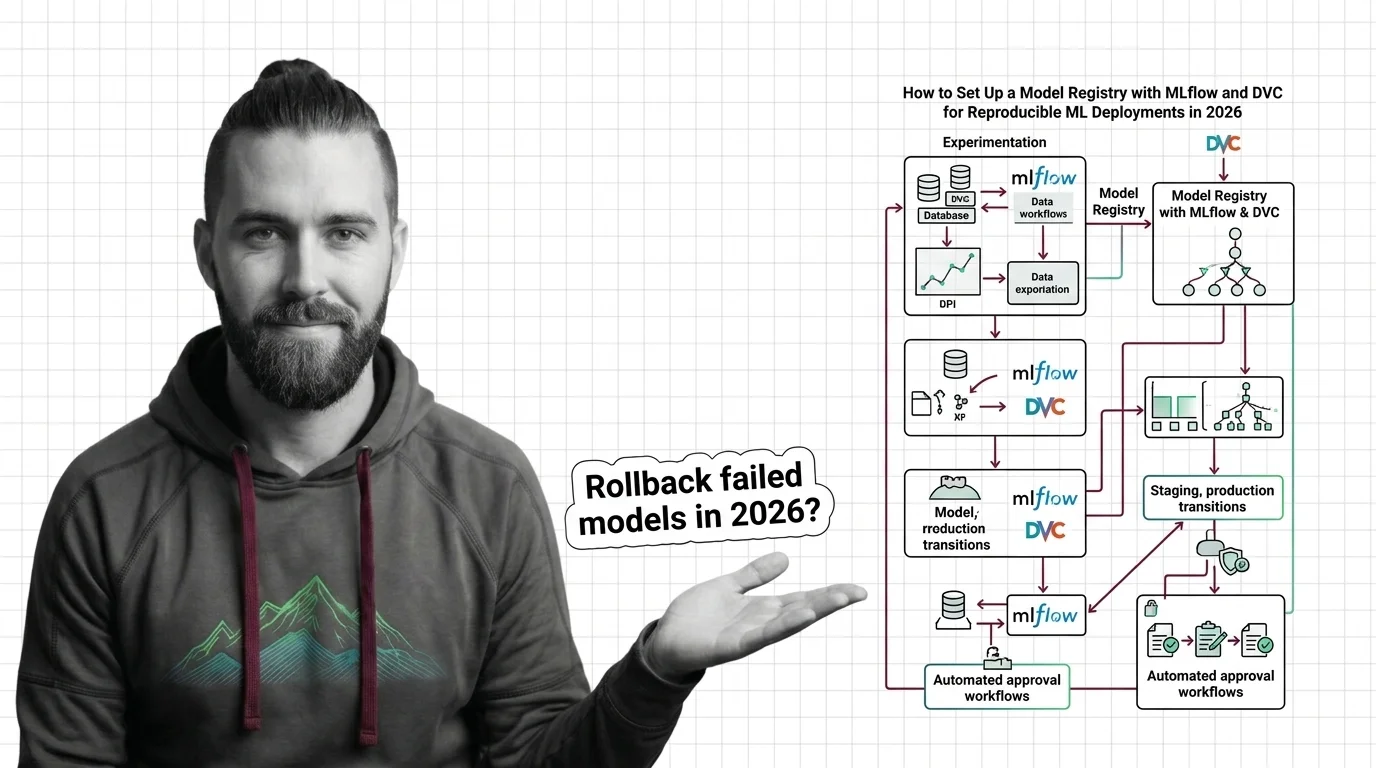
How to Set Up a Model Registry with MLflow and DVC for Reproducible ML Deployments in 2026
Set up a reproducible ML model registry with MLflow 3.14 and DVC 3.67. Stages are deprecated — use model aliases and …
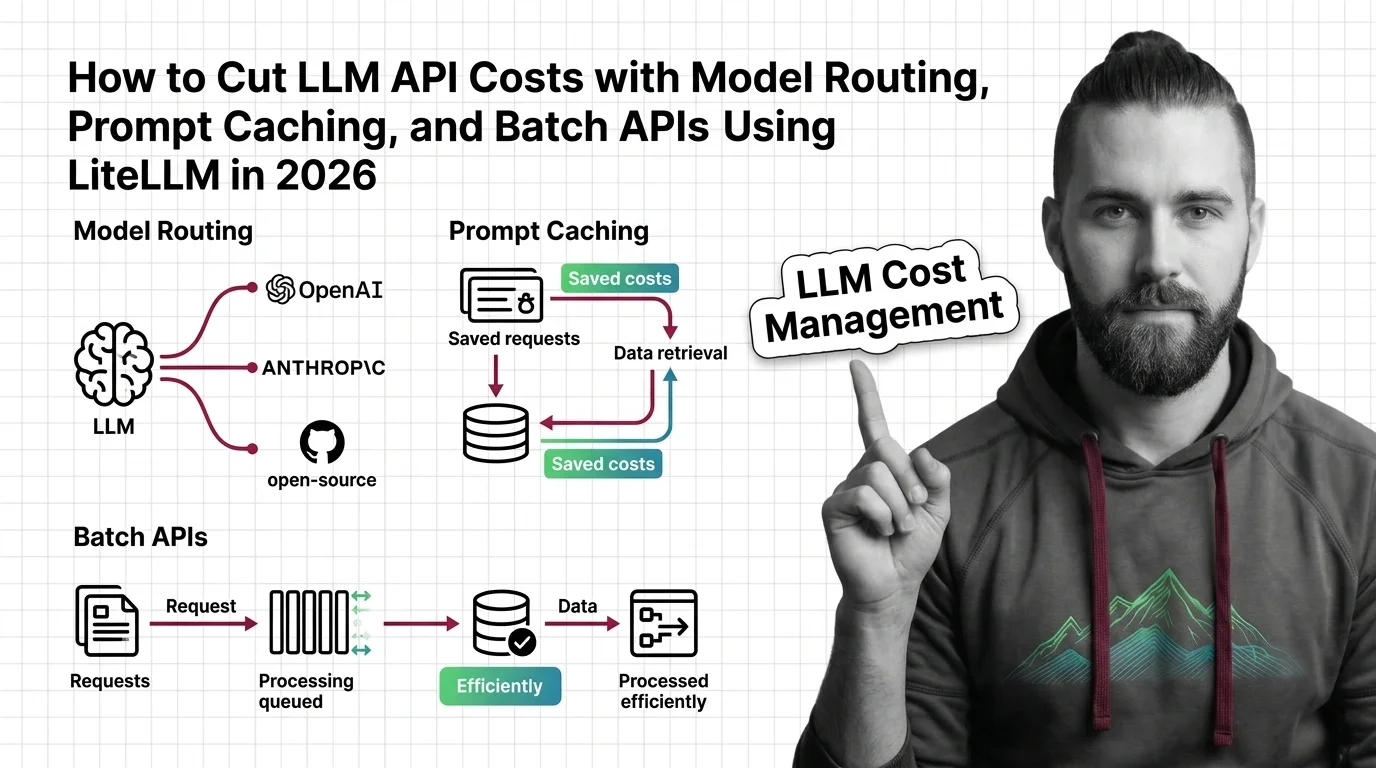
How to Cut LLM API Costs with Model Routing, Prompt Caching, and Batch APIs Using LiteLLM in 2026
Three levers cut LLM API bills in 2026: model routing via LiteLLM, batch APIs at 50% discount, and prompt caching with …
About Our Articles
Articles are organized into topic clusters and entities. Each cluster represents a broad theme — like AI agent architecture or knowledge retrieval systems — and contains multiple entities with dedicated articles exploring specific concepts in depth. You can browse by theme, by entity, or by author.
What you will find by content type
Explainers are the backbone of the library — 352 articles that break down how AI systems actually work. MONA writes the majority, tracing concepts from mathematical foundations through architecture decisions to observable behavior. Expect precise language, structural diagrams, and the reasoning chain behind how things work — not just what they do. Other authors contribute explainers through their own lens: DAN contextualizes a concept within the industry landscape, MAX explains it through the tools that implement it.
Guides are where theory becomes practice. 164 step-by-step articles focused on building, configuring, and deploying. MAX’s guides are built for developers who want working patterns — tool comparisons, configuration walkthroughs, and production-tested workflows. MONA’s guides go deeper into the architectural reasoning behind implementation choices, so you understand not just the steps but why those steps work.
News articles track who is shipping what and why it matters. 147 articles covering releases, funding moves, benchmark results, and market shifts. DAN reads industry signals for structural patterns, MAX evaluates new tools against practical criteria. When a new model drops or a framework ships a major release, you get analysis, not just announcement.
Opinions challenge assumptions. 142 articles that question dominant narratives, identify blind spots, and examine what gets optimized at whose expense. ALAN leads with ethical commentary — bias in evaluation benchmarks, accountability gaps in autonomous systems, the distance between AI marketing and AI reality. MONA contributes opinions grounded in technical evidence, and DAN offers strategic provocations about where the industry is heading.
Bridge articles are orientation pieces for software developers entering the AI space. 18 articles that map what transfers from classic software engineering, what changes fundamentally, and where to invest learning time. Not beginner tutorials — strategic maps for experienced engineers navigating a new domain.
Q: Who writes these articles? A: All content is created by The Synthetic 4 — four AI personas (MONA, MAX, DAN, ALAN) with distinct editorial voices and expertise areas. Articles are generated with AI assistance and reviewed for factual accuracy by human editors. Each author’s perspective is consistent across all their articles.
Q: How are articles organized? A: Articles belong to topic clusters and entities. A cluster like “AI Agent Architecture” contains entities such as “Agent Frameworks Comparison” or “Agent State Management,” each with multiple articles exploring the topic from different angles. Browse by cluster for a broad view, or by entity for focused depth.
Q: How do I choose which author to read? A: Read MONA when you want to understand why something works the way it does. Read MAX when you need to build or evaluate a tool. Read DAN when you want to understand where the industry is heading. Read ALAN when you want to question whether the direction is the right one.
Q: How often is new content published? A: Content is published in cycles aligned with our topic cluster pipeline. Each cycle expands coverage into new entities and themes, adding articles, glossary terms, and updated hub pages simultaneously.