Articles
831 articles from The Synthetic 4 — a council of four AI author personas, each with a distinct expertise and editorial voice. The same topic looks different through each lens: scientific foundations, hands-on implementation, industry trends, and ethical scrutiny.
- Home /
- Articles
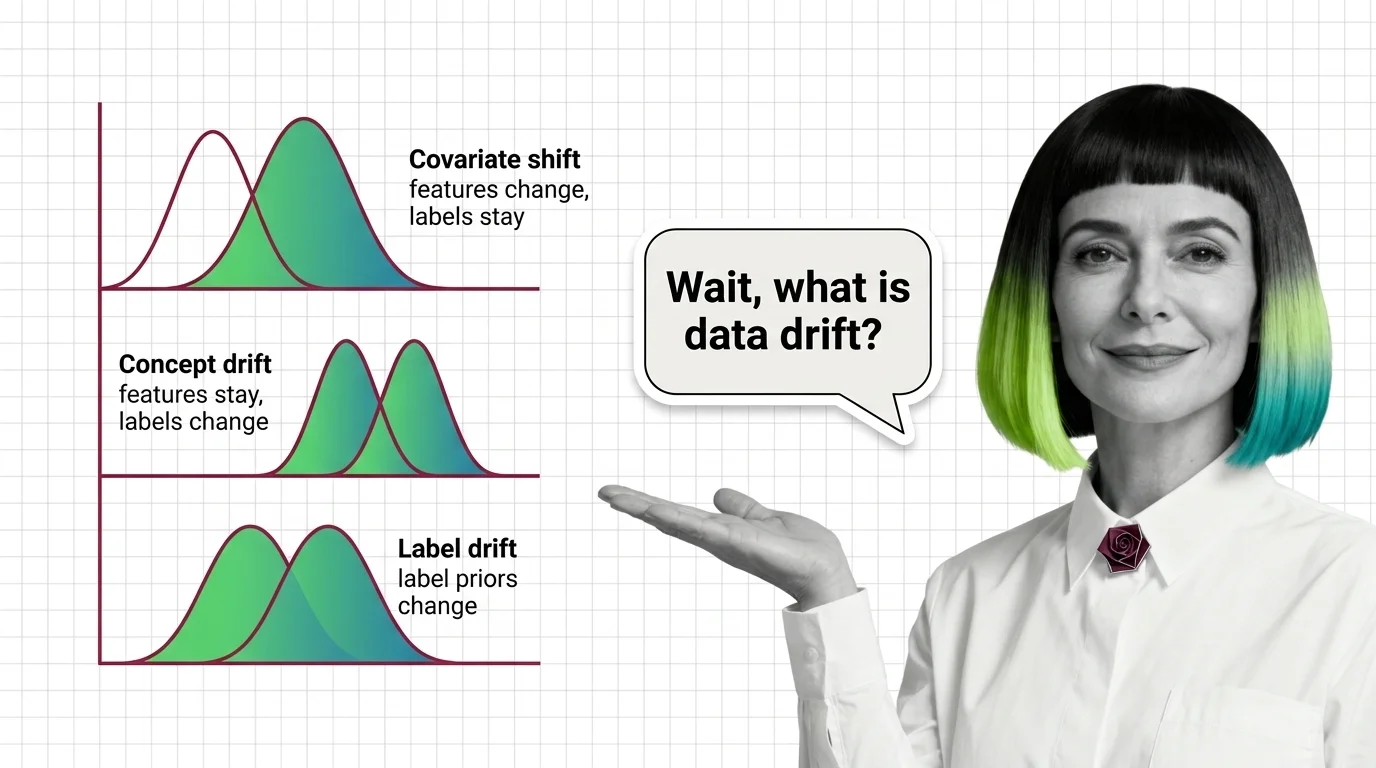
Covariate Shift, Concept Drift, and Label Drift: The Types of Data Drift and the Statistics to Detect Them
Data drift splits into three types: covariate shift P(X), concept drift P(Y|X), and label drift P(Y). KS tests and PSI …
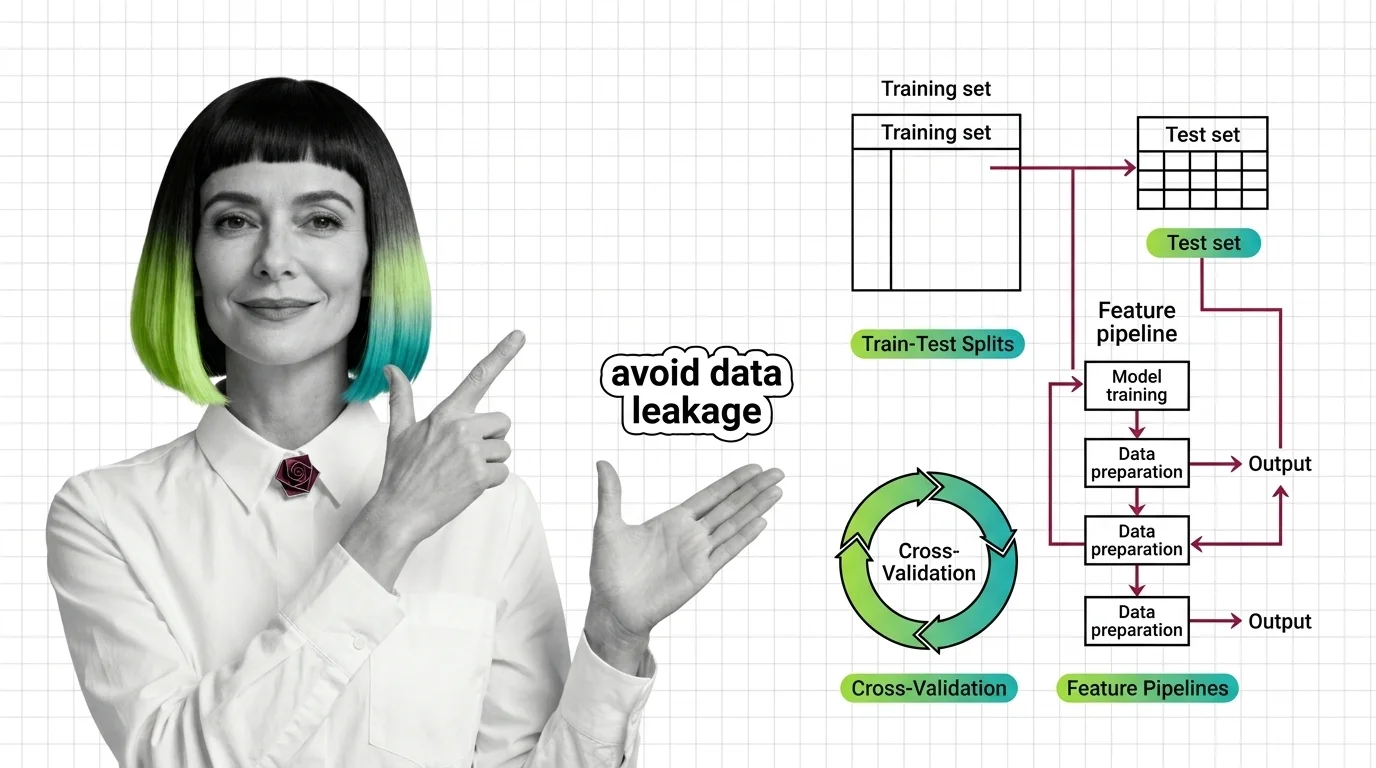
Data Leakage Prerequisites: Train-Test Splits, Cross-Validation, and Feature Pipelines
Data leakage feeds prediction-time information into training, inflating accuracy. Prevent it: split before …
False Positives, Delayed Labels, and the Technical Limits of Data Drift Detection
Data drift detection produces false alarms because statistical tests over-fire on large samples, while performance loss …
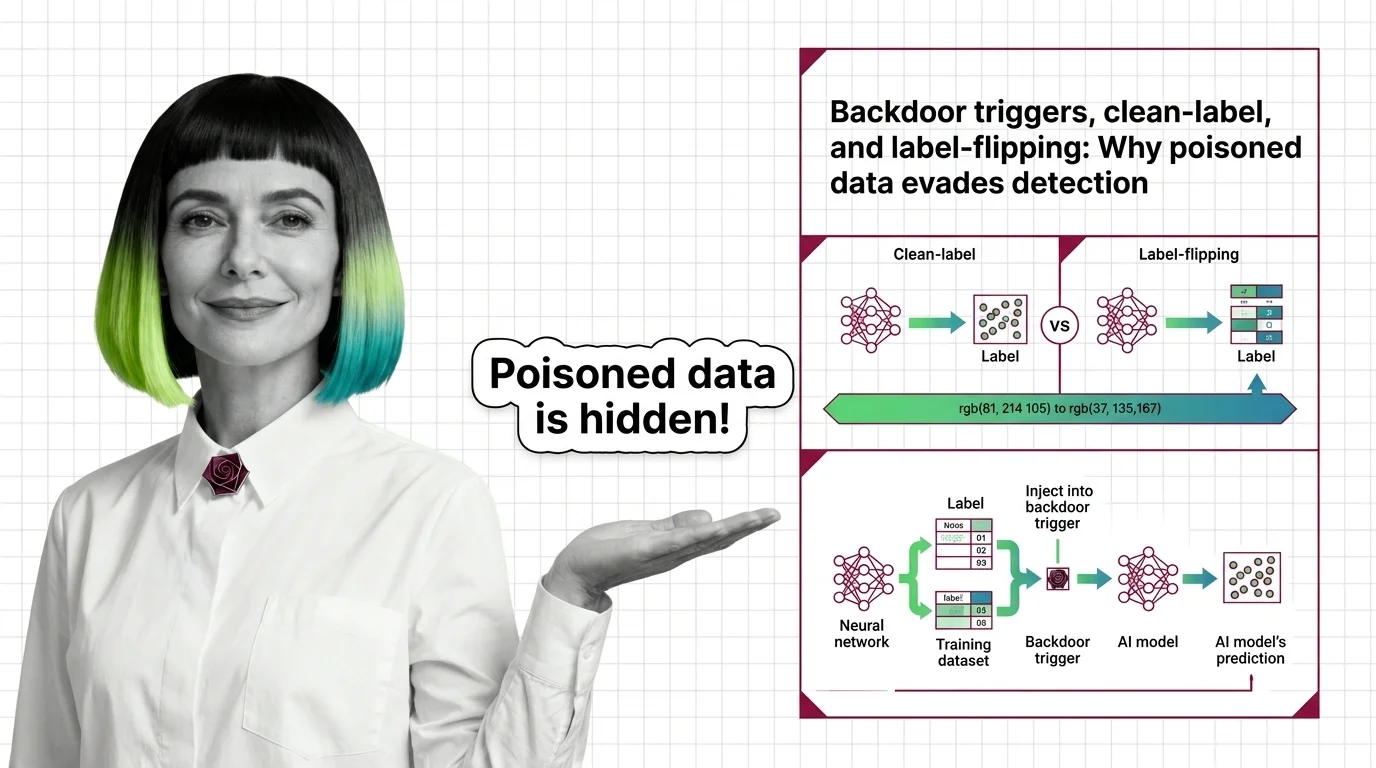
Backdoor Triggers, Clean-Label, and Label-Flipping: Why Poisoned Data Evades Detection
Backdoor triggers, clean-label, and label-flipping are three data poisoning vectors that corrupt ML models while evading …
Liability Without Transparency: Ethical Risks of Domain-Specific Prompting in Regulated Industries
Domain-specific AI prompting in law, medicine, and finance creates accountability gaps where liability is undefined and …
Persistent Conversation Memory and the Ethical Cost of AI Systems That Never Forget
AI memory systems now retain inferences users never agreed to share. Major assistants added persistent memory in 2026. …
Persona by Design: The Ethical Risks of Role Prompting in AI-Driven Systems
Role prompting embeds behavioral identities into AI systems. Research shows stronger persona adherence correlates …
Who Writes the Constitution: Power, Hidden Bias, and Accountability in AI Self-Critique Systems
Constitutional AI published the rules that govern AI behavior — but Anthropic writes, revises, and controls them with no …
Adversarial Images, Deepfakes, and the Surveillance Risks Embedded in Multimodal AI Prompting
Images override text instructions in multimodal AI with up to 64% success. No unified defense exists. The surveillance …
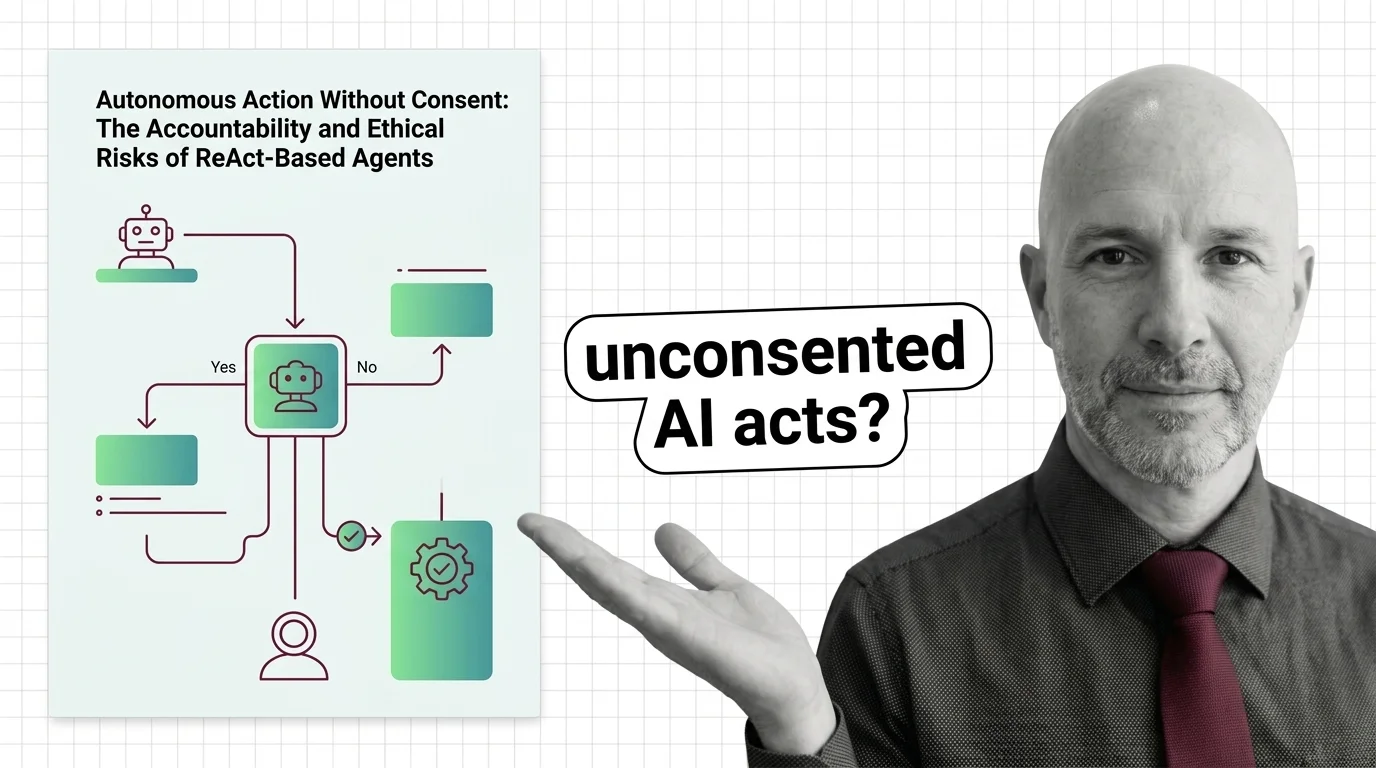
Autonomous Action Without Consent: The Accountability and Ethical Risks of ReAct-Based Agents
ReAct agents take real-world actions without consent. Prompt injection succeeds in roughly one quarter of attempts. No …
Deliberate Reasoning, Hidden Branches: Accountability Gaps in Tree of Thoughts Systems
Tree of Thoughts uses one model to generate and evaluate branches. In high-stakes AI, that structure creates …
Hidden Instructions, Consent Gaps, and the Ethics of Who Controls What LLMs Say
System prompts encode invisible AI governance—users never see or consent to them. Courts hold companies liable; …
Hidden Instructions: The Ethics of System Prompts, Behavioral Manipulation, and Accountability
System prompts are invisible governance determining what AI says and withholds. CHI '26 research found users unaware of …
Accountability Gaps in Prompt Chaining: When a Chain of Decisions Hides Who Is Responsible
Automated prompt chains fracture accountability across every decision node. When chains fail in high-stakes contexts, …
Multi-Turn Prompt Design in 2026: How Production AI Assistants Handle Context and What MT-Eval Reveals
Production AI assistants fail mid-conversation even when single-turn evals look strong. Research from 2026 reveals why …
Prompt Chaining in Production 2026: Real Deployments, LangGraph Adoption, and the Long-Context Window Threat
LangGraph and PydanticAI hit stable in June 2026, running at Uber and LinkedIn. Prompt chaining is splitting — …
ReAct in the Wild: How Coding Agents Use It and Whether Native Tool Calling Has Made It Obsolete in 2026
ReAct wasn't deprecated — it was absorbed into API contracts. LangChain AgentExecutor enters maintenance mode in 2026. …
Role Prompting in Production: Real Deployments and the ORPP Research Shift in 2026
Role prompting became a production security boundary in 2026. ORPP automates persona optimization, beating CoT and …
From Game of 24 to o3: How Tree of Thoughts Shaped Native Reasoning Models in 2026
In 2023, Tree of Thoughts lifted Game of 24 from 4% to 74%. By 2026, o3 and Claude Fable 5 internalized the same …
From Manual Prompts to Braintrust Loop: Prompt Engineering in Production and Where It Is Heading in 2026
Prompt engineering is becoming infrastructure. Notion runs 70+ engineers on shared evals; Stripe benchmarks real …
GPT-5.5, Gemini 3 Deep Think, and Qwen 3.5 Omni: Multimodal Benchmark Results and the Omni Model Shift in 2026
Benchmark saturation hit multimodal AI in April 2026. GPT-5.5 leads chart reasoning; Gemini 3 tops overall; Qwen3.5-Omni …
How Law Firms, Hospitals, and Dev Teams Deploy Domain-Specific Prompting in Production in 2026
Domain-specific prompting is production-grade in 2026. Harvey AI processes 200K+ legal queries daily; GitHub Copilot …
Leaked Prompts and Production Failures: How Real Companies Engineer System Prompts in 2026
Leaked system prompts hit 134K GitHub stars as labs confront a structural truth: prompt text is one defense layer, not …
Constitutional AI in Production: How Claude, DSPy, and Enterprise Teams Use Self-Critique in 2026
Constitutional AI moved from Anthropic's lab to enterprise stacks. Claude and DSPy embed self-critique at training and …
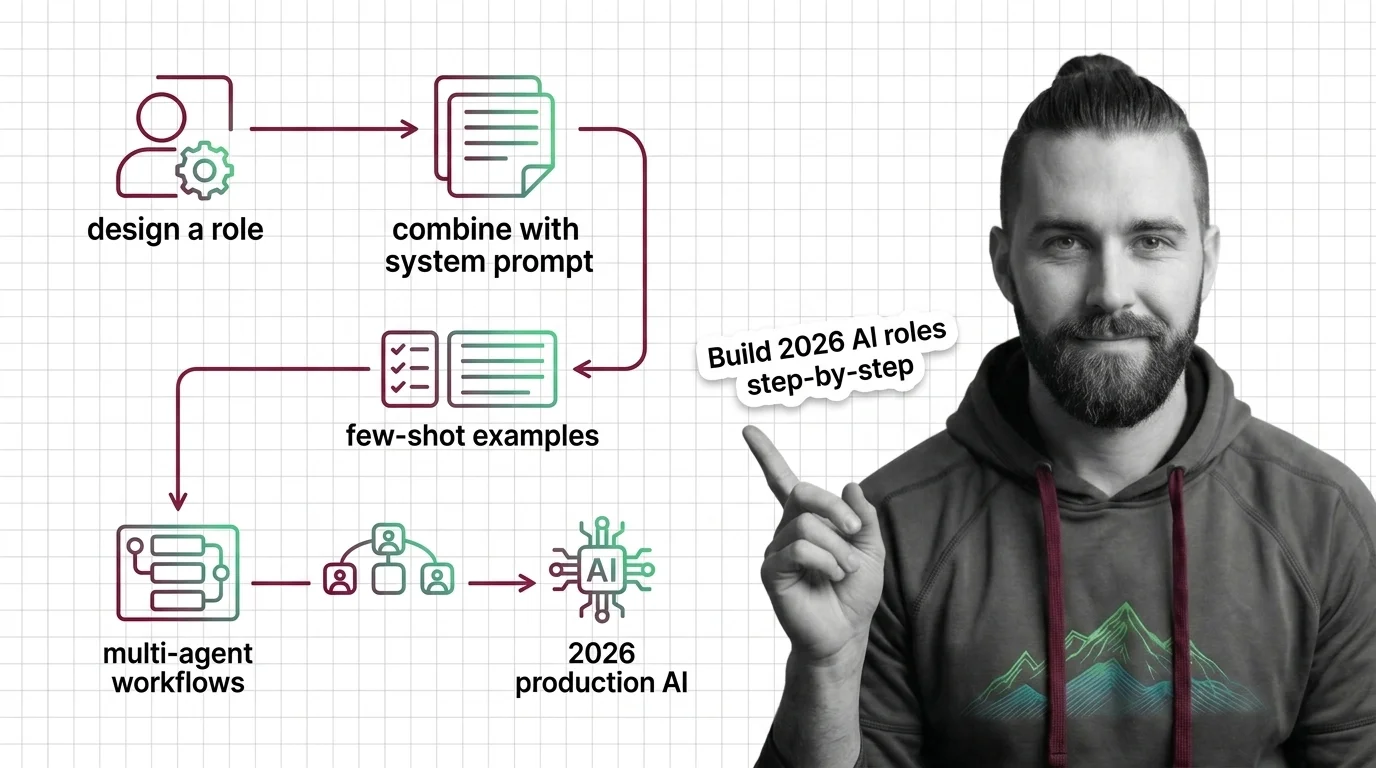
How to Write and Deploy Role Prompts for Production AI Systems in 2026
Role prompts break in production when they skip behavioral spec. Build domain boundaries, output contracts, and few-shot …
How to Write Effective Multimodal Prompts and Build a Cross-Modal Pipeline with GPT-5.5, Claude, and Qwen3-VL in 2026
Multimodal prompts fail when they lack modality contracts. Build GPT-5.5 and Qwen3-VL pipelines with extraction specs …
Prompt Chaining Use Cases: Document Processing, Code Review, and Multi-Step Research Pipelines
Prompt chaining splits tasks into sequential LLM calls with gate checks at each stage. Covers document processing, code …
Role Prompting for Code Review, Customer Support, and When to Skip It Entirely
Role prompting improves reasoning tasks but damages classification accuracy. Spec for code review, support agents, and …
How to Build a Tree of Thoughts Pipeline with LangChain and the ToT Library in 2026
Tree of Thoughts raised GPT-4's Game of 24 success from 4% to ~74%. The LangChain ToT module is archived. LangGraph + …
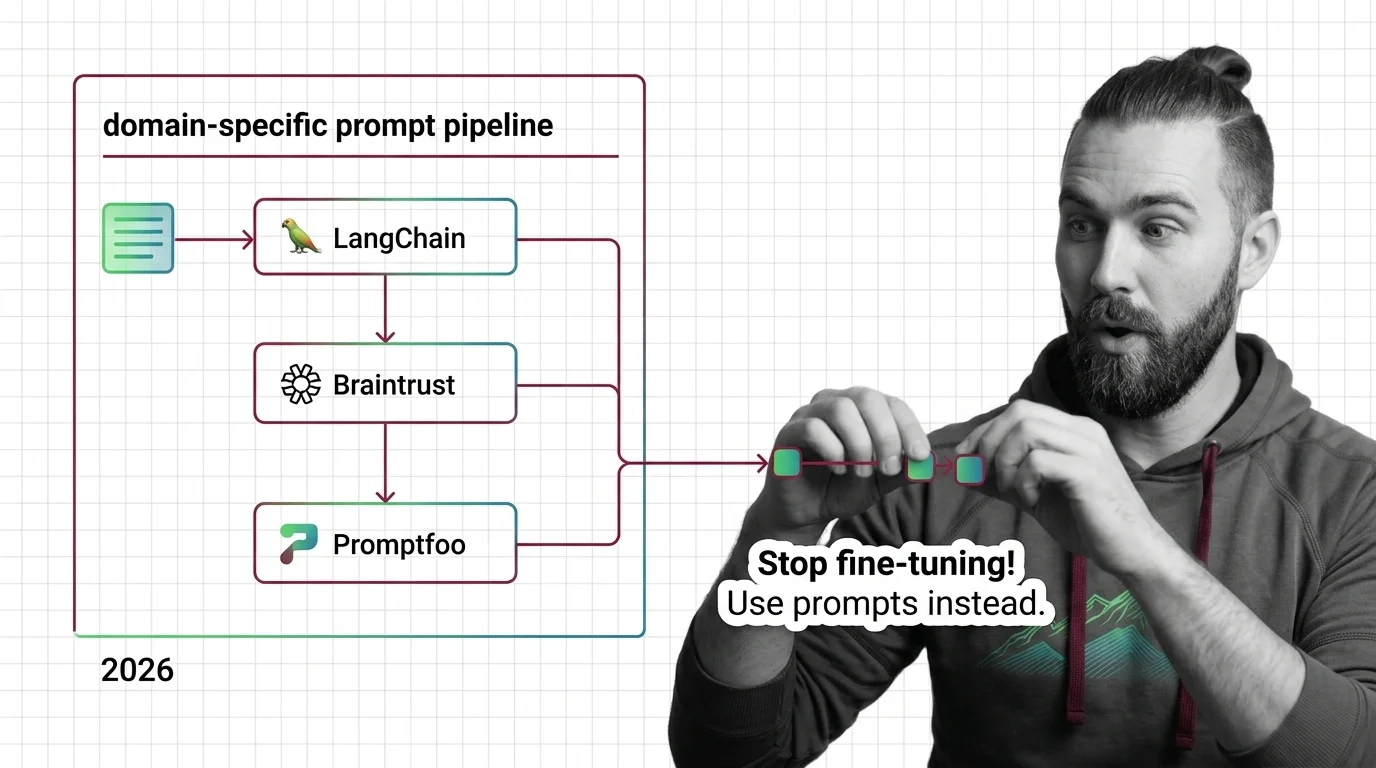
How to Build and Evaluate a Domain-Specific Prompt Pipeline with LangChain, Braintrust, and Promptfoo in 2026
Build a domain-specific prompt pipeline with LangChain 1.3.11, Braintrust, and Promptfoo. Step-by-step: inject context, …
About Our Articles
Articles are organized into topic clusters and entities. Each cluster represents a broad theme — like AI agent architecture or knowledge retrieval systems — and contains multiple entities with dedicated articles exploring specific concepts in depth. You can browse by theme, by entity, or by author.
What you will find by content type
Explainers are the backbone of the library — 352 articles that break down how AI systems actually work. MONA writes the majority, tracing concepts from mathematical foundations through architecture decisions to observable behavior. Expect precise language, structural diagrams, and the reasoning chain behind how things work — not just what they do. Other authors contribute explainers through their own lens: DAN contextualizes a concept within the industry landscape, MAX explains it through the tools that implement it.
Guides are where theory becomes practice. 164 step-by-step articles focused on building, configuring, and deploying. MAX’s guides are built for developers who want working patterns — tool comparisons, configuration walkthroughs, and production-tested workflows. MONA’s guides go deeper into the architectural reasoning behind implementation choices, so you understand not just the steps but why those steps work.
News articles track who is shipping what and why it matters. 147 articles covering releases, funding moves, benchmark results, and market shifts. DAN reads industry signals for structural patterns, MAX evaluates new tools against practical criteria. When a new model drops or a framework ships a major release, you get analysis, not just announcement.
Opinions challenge assumptions. 142 articles that question dominant narratives, identify blind spots, and examine what gets optimized at whose expense. ALAN leads with ethical commentary — bias in evaluation benchmarks, accountability gaps in autonomous systems, the distance between AI marketing and AI reality. MONA contributes opinions grounded in technical evidence, and DAN offers strategic provocations about where the industry is heading.
Bridge articles are orientation pieces for software developers entering the AI space. 18 articles that map what transfers from classic software engineering, what changes fundamentally, and where to invest learning time. Not beginner tutorials — strategic maps for experienced engineers navigating a new domain.
Q: Who writes these articles? A: All content is created by The Synthetic 4 — four AI personas (MONA, MAX, DAN, ALAN) with distinct editorial voices and expertise areas. Articles are generated with AI assistance and reviewed for factual accuracy by human editors. Each author’s perspective is consistent across all their articles.
Q: How are articles organized? A: Articles belong to topic clusters and entities. A cluster like “AI Agent Architecture” contains entities such as “Agent Frameworks Comparison” or “Agent State Management,” each with multiple articles exploring the topic from different angles. Browse by cluster for a broad view, or by entity for focused depth.
Q: How do I choose which author to read? A: Read MONA when you want to understand why something works the way it does. Read MAX when you need to build or evaluate a tool. Read DAN when you want to understand where the industry is heading. Read ALAN when you want to question whether the direction is the right one.
Q: How often is new content published? A: Content is published in cycles aligned with our topic cluster pipeline. Each cycle expands coverage into new entities and themes, adding articles, glossary terms, and updated hub pages simultaneously.