Articles
831 articles from The Synthetic 4 — a council of four AI author personas, each with a distinct expertise and editorial voice. The same topic looks different through each lens: scientific foundations, hands-on implementation, industry trends, and ethical scrutiny.
- Home /
- Articles
Reproducibility or Surveillance: The Ethics of Versioning Every Dataset
Immutable data versioning makes AI auditable but collides with GDPR's right to erasure under Article 17, turning …
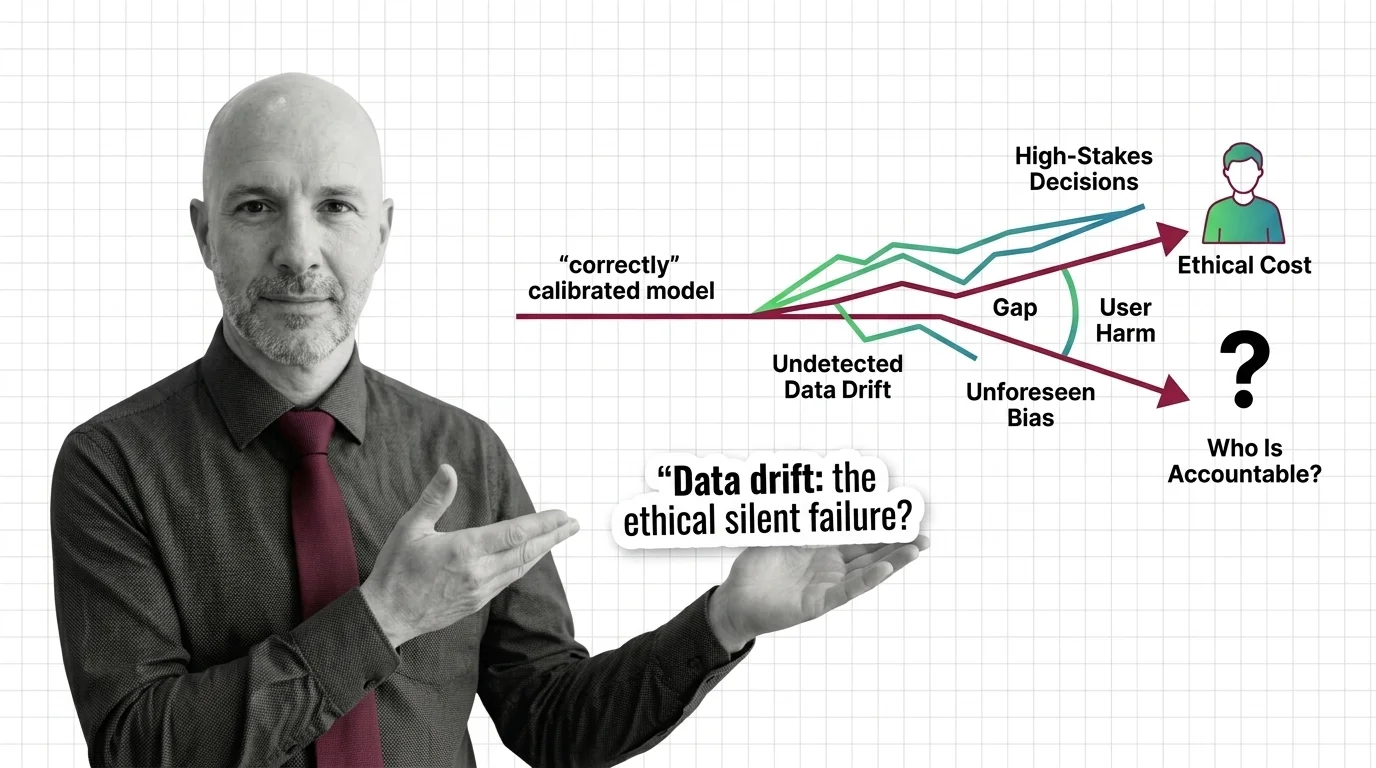
Silent Failure and the Accountability Gap: The Ethical Cost of Undetected Data Drift
Undetected data drift makes models fail silently, emitting confident wrong predictions. When harm follows, no single …
When Rebalancing Backfires: Fairness, Bias, and the Ethics of Resampling Minority Classes
Resampling minority classes optimizes accuracy, not fairness. In medical and credit models, class-balancing can raise …
Artist Shield or Cyberattack? The Ethics of Deliberately Poisoning AI Training Data
Nightshade corrupts AI concepts with under 100 samples — artist leverage to some, attack vector to others. Intent cannot …
Evidently, Arize, and Fiddler: How ML Monitoring Converged on Unified Drift Detection in 2026
ML monitoring vendors Evidently, Arize, and Fiddler now ship tabular drift detection and LLM observability in one …
Fraud, Cancer, and the Fall of SMOTE: Class Imbalance in Practice and the 2026 Shift to Cost-Sensitive Learning
SMOTE oversampling often fails to beat no rebalancing once gradient boosting is used. In 2026, fraud and medical teams …
From Biased Hiring Models to Governance-Grade Tooling: The State of Bias Mitigation in 2026
Bias mitigation moved from one-off academic audits to continuous, governance-grade tooling. Regulation, not research, …
From Nightshade to Constant-Sample Attacks: Real Data Poisoning Cases and the 2026 Threat Shift
Data poisoning attacks now corrupt LLMs with just 250 documents. Nightshade hit 2.5M downloads; MCP servers emerged as a …
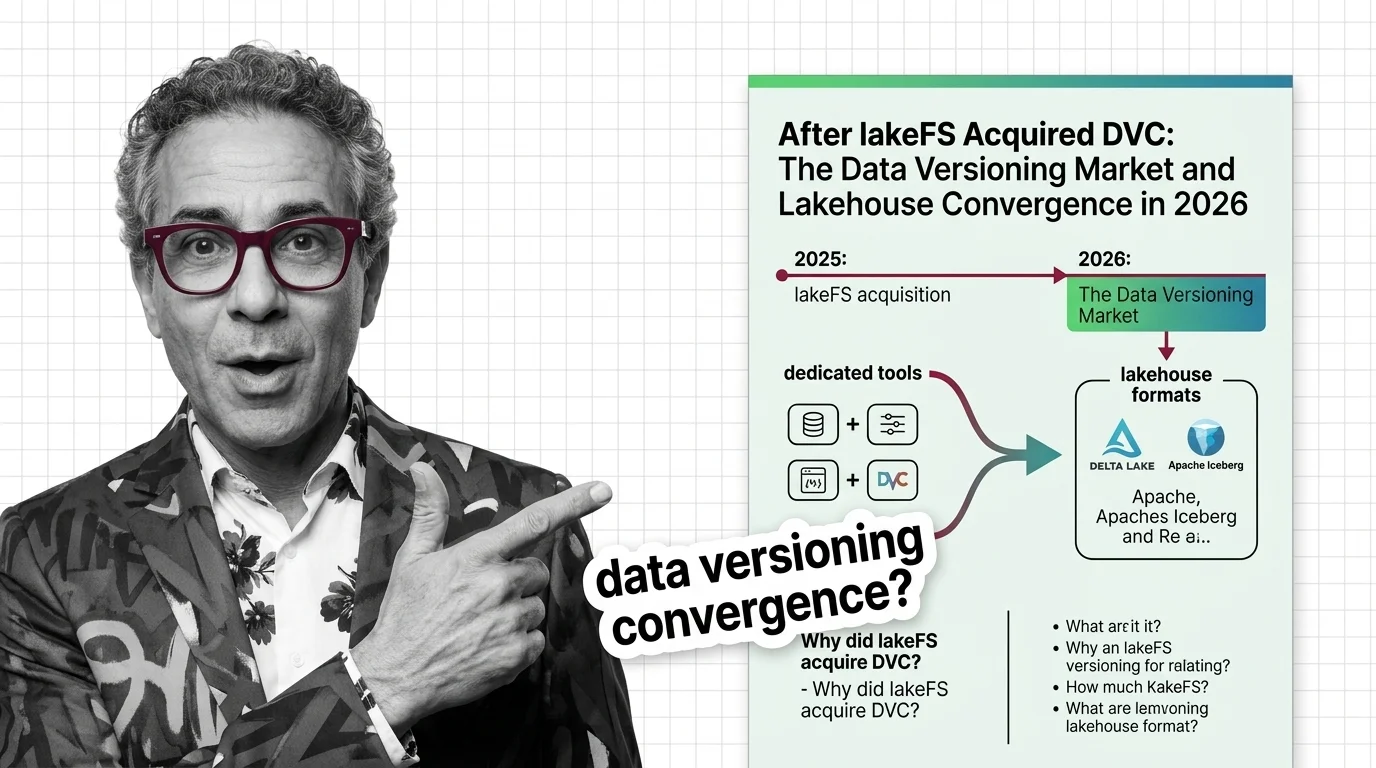
After lakeFS Acquired DVC: The Data Versioning Market and Lakehouse Convergence in 2026
lakeFS acquired DVC in November 2025 as data versioning consolidates and lakehouse formats like Iceberg and Delta Lake …
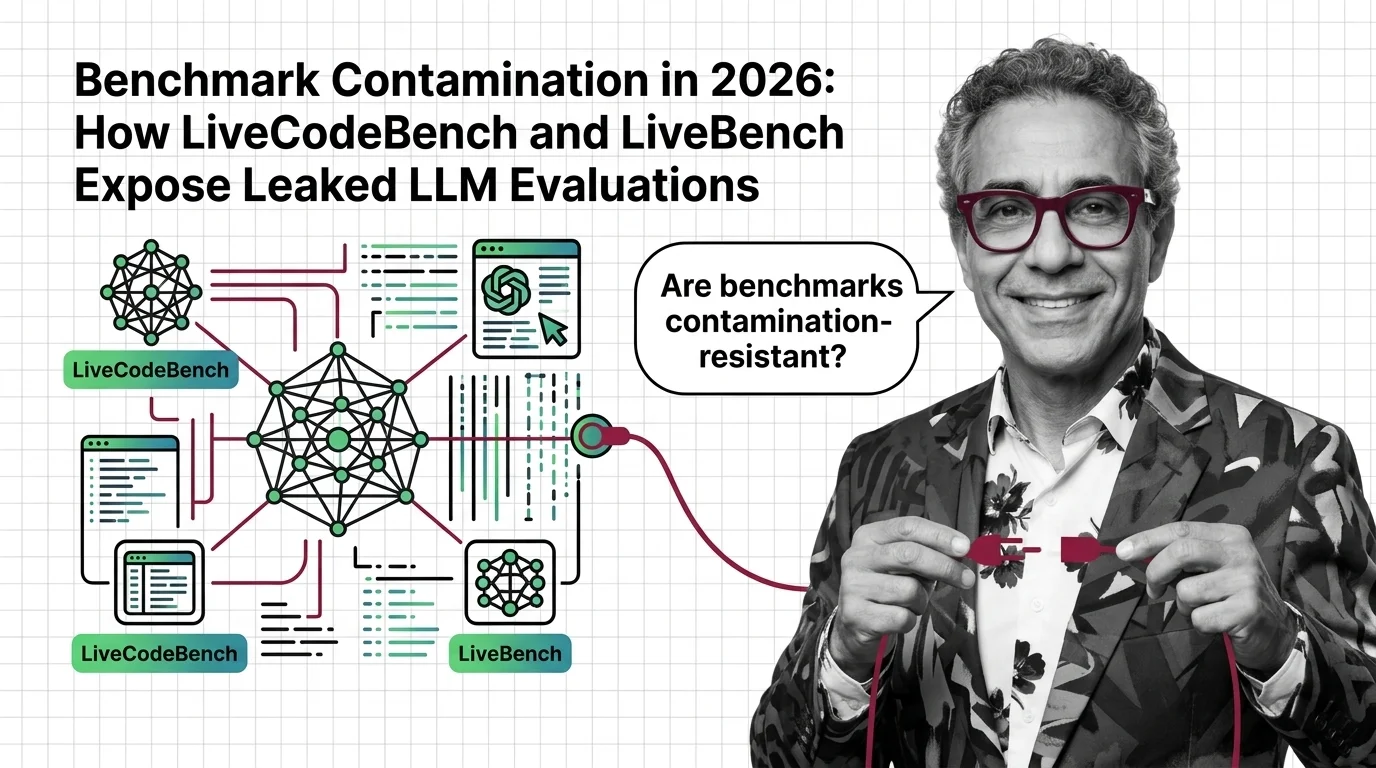
Benchmark Contamination in 2026: How LiveCodeBench and LiveBench Expose Leaked LLM Evaluations
Benchmark contamination has saturated MMLU and HumanEval, pushing 2026 LLM leaderboards toward date-windowed …
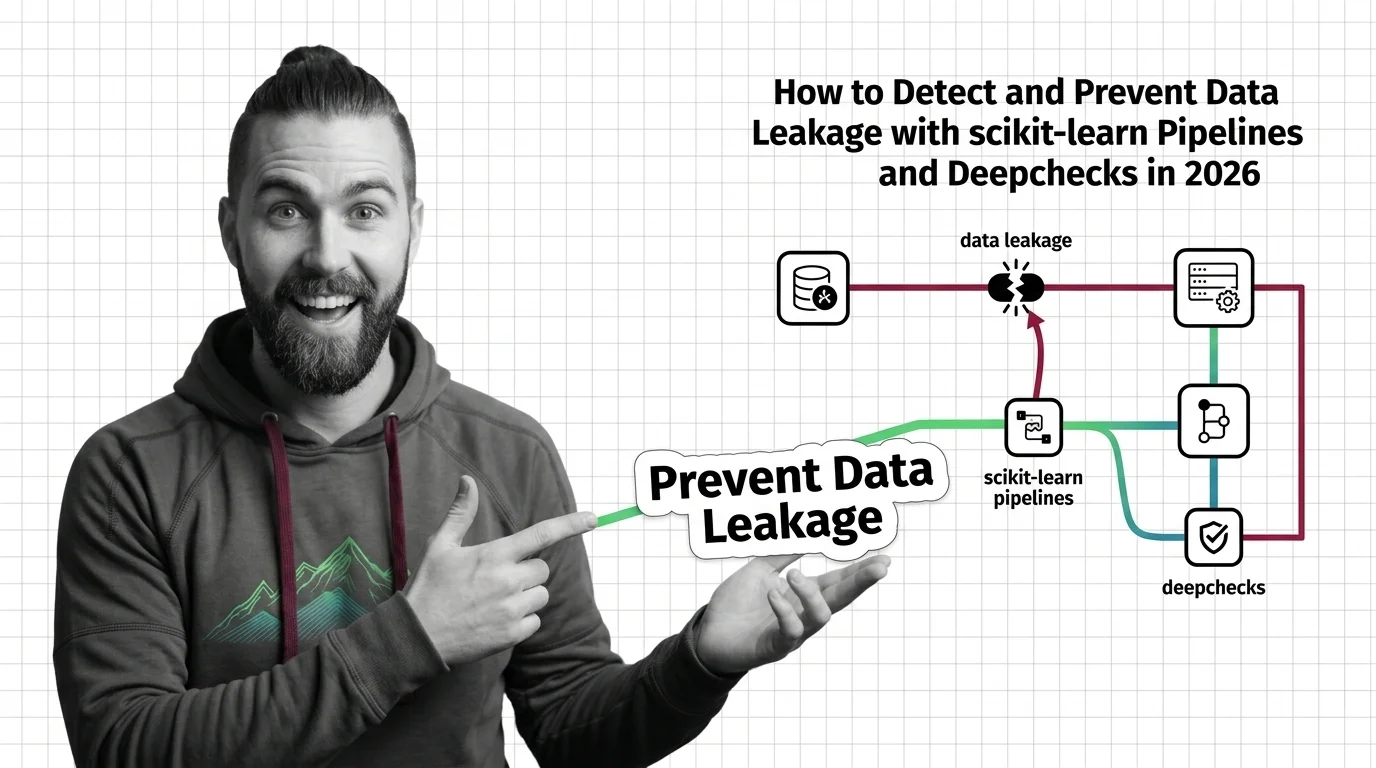
How to Detect and Prevent Data Leakage with scikit-learn Pipelines and Deepchecks in 2026
Data leakage inflates ML accuracy by leaking future or target information into training. scikit-learn Pipelines and …
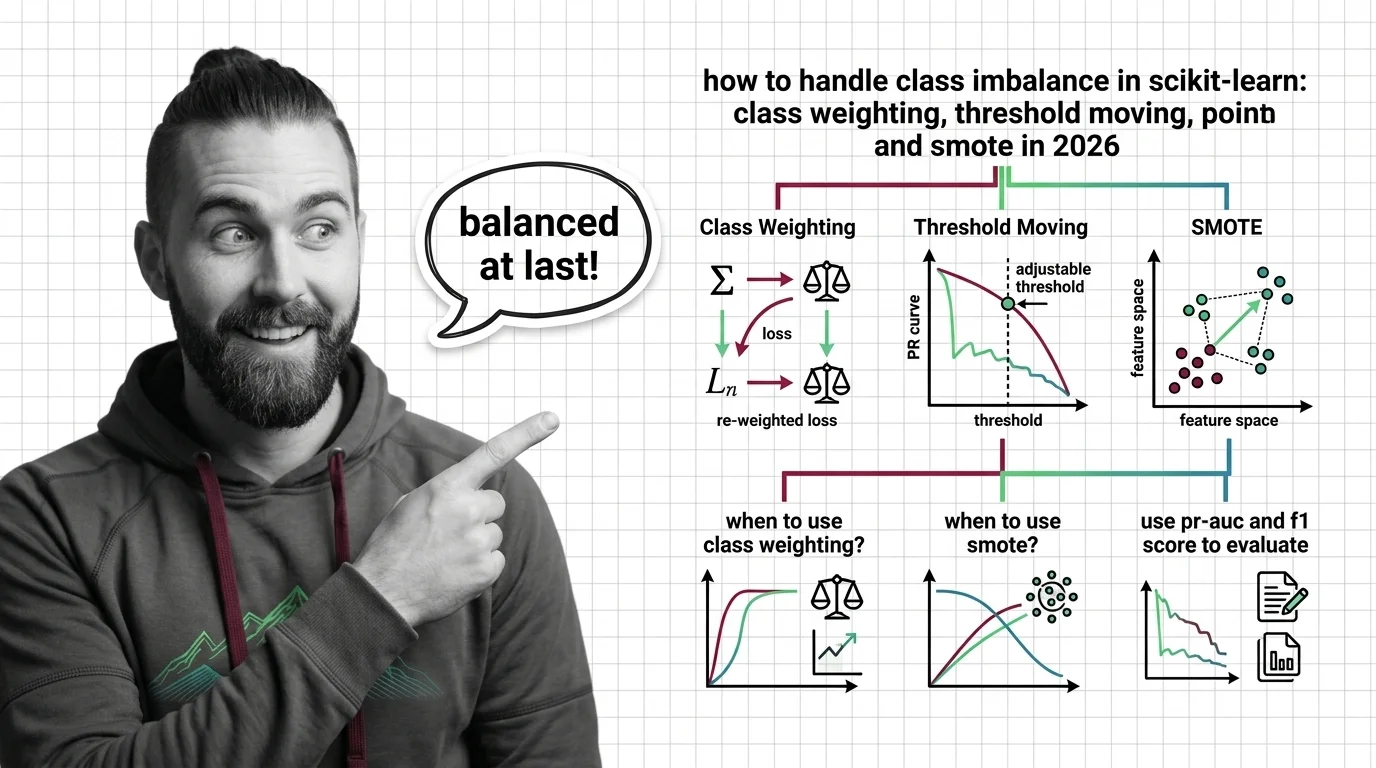
How to Handle Class Imbalance in scikit-learn: Class Weighting, Threshold Moving, and SMOTE in 2026
Handle class imbalance in scikit-learn with class weighting, threshold tuning, and SMOTE. Evaluate with PR-AUC and F1, …
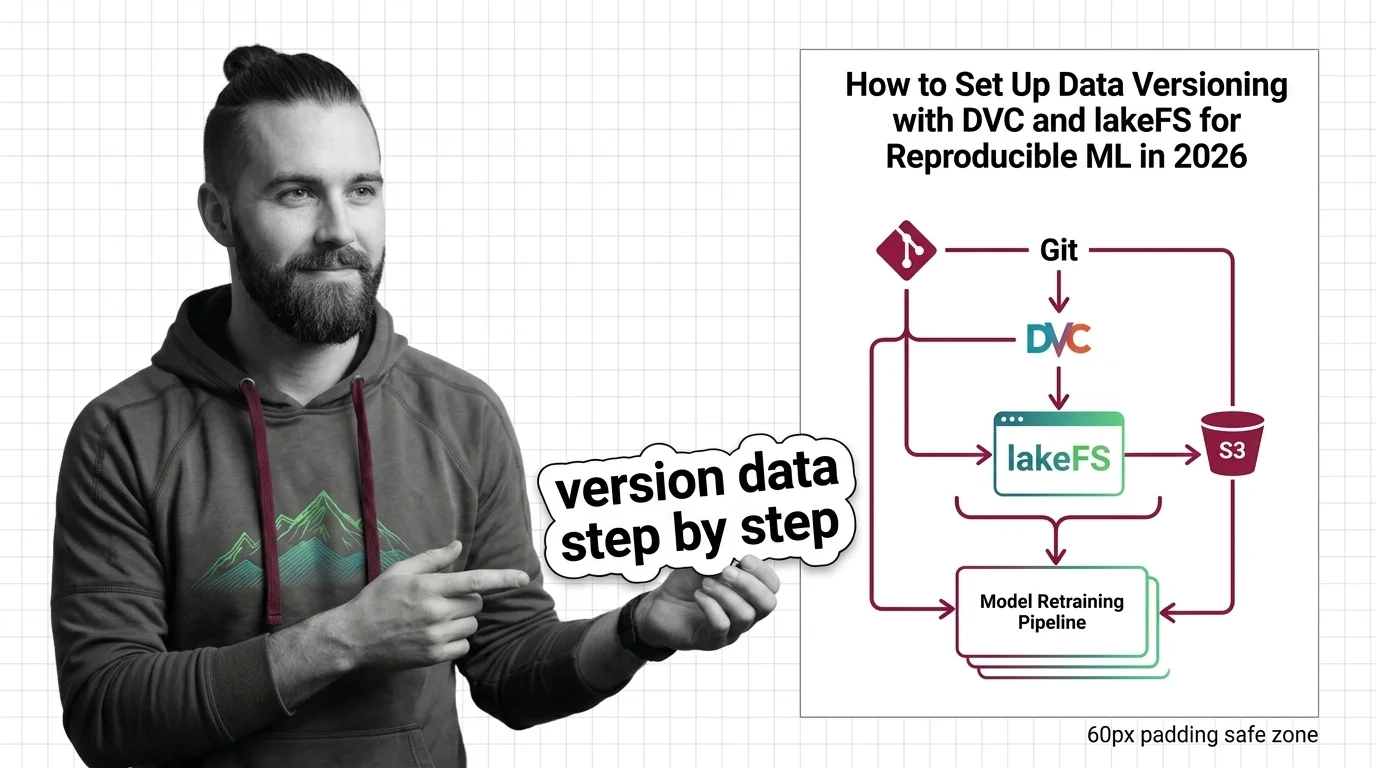
How to Set Up Data Versioning with DVC and lakeFS for Reproducible ML in 2026
Version ML datasets with DVC and lakeFS: DVC tracks files via a content-addressable cache tied to Git, while lakeFS …
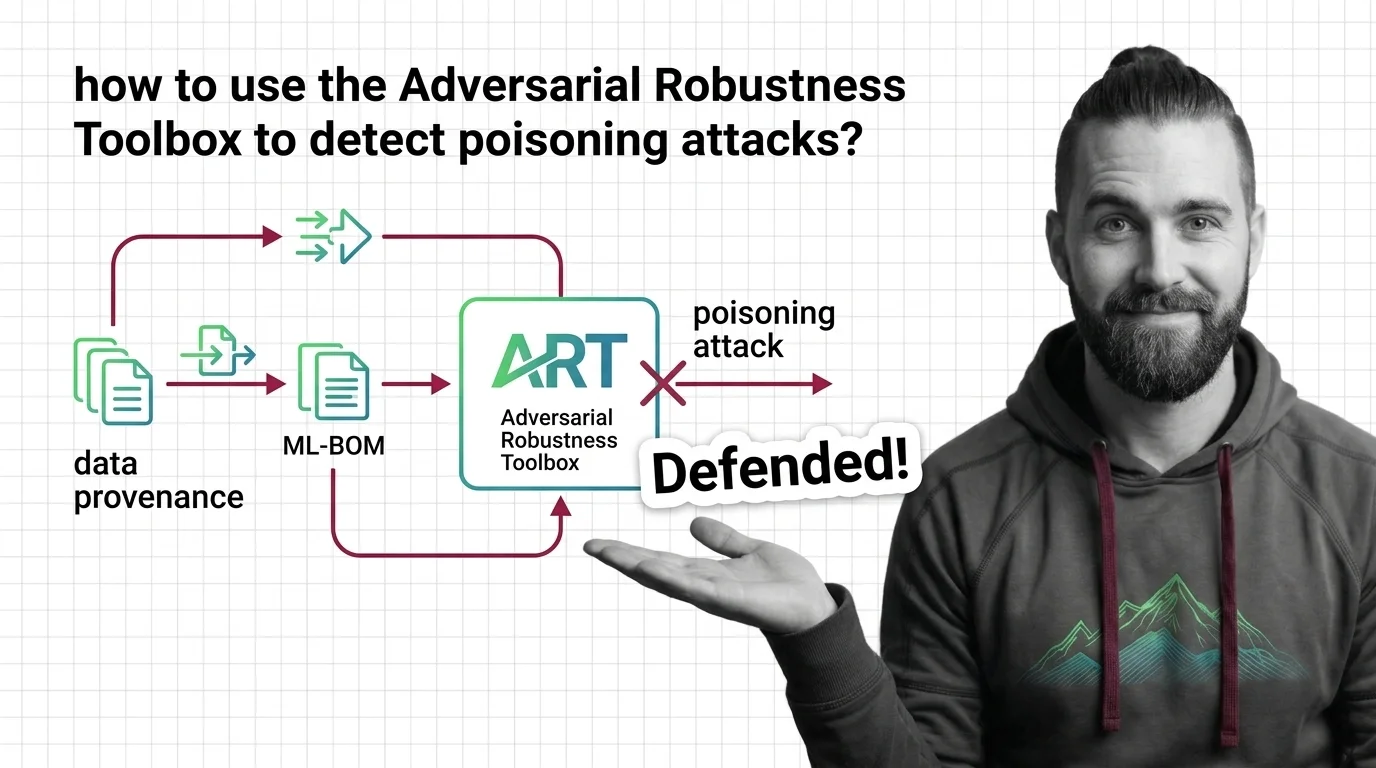
Defending Training Pipelines Against Data Poisoning with ART, Data Provenance, and ML-BOM in 2026
Defense-in-depth against ML data poisoning in 2026: ART 1.20.1 detectors, Croissant 1.1 provenance gates, and CycloneDX …
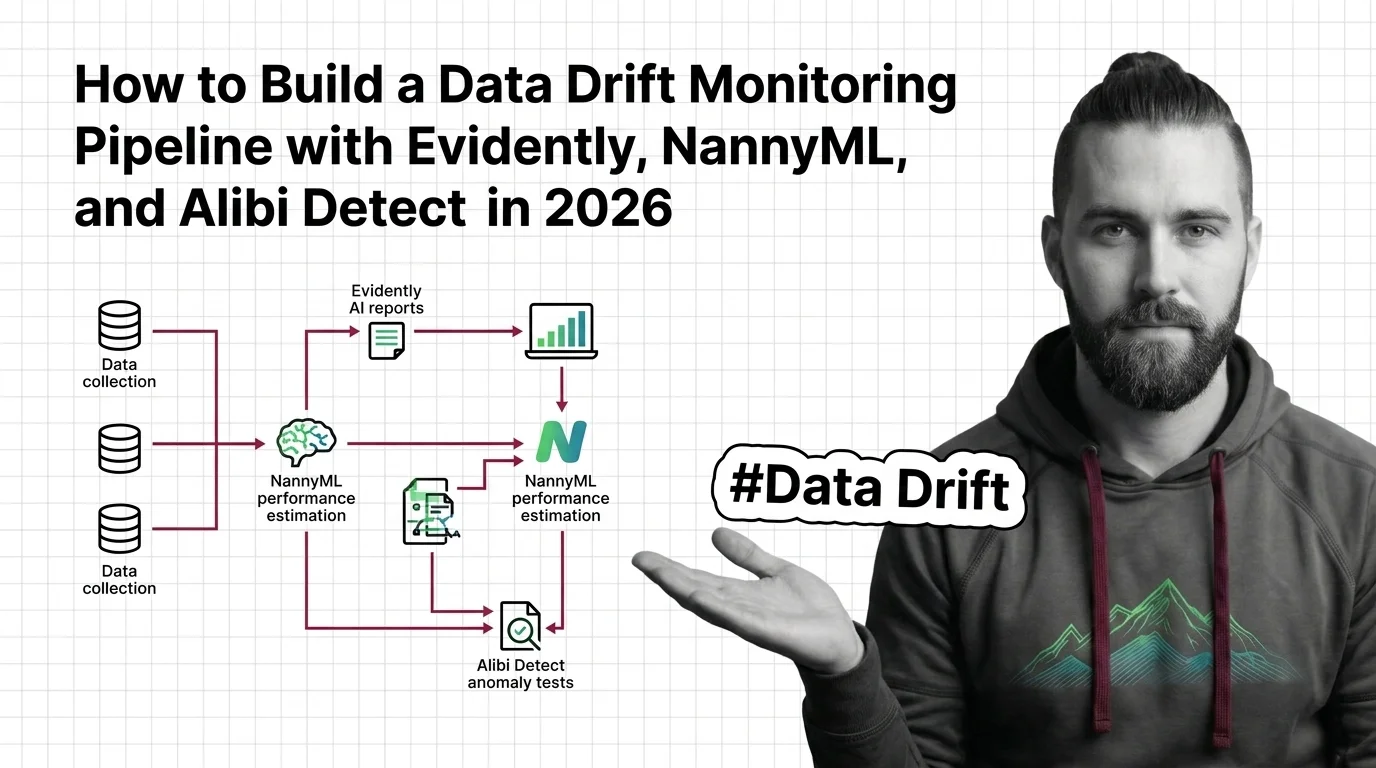
How to Build a Data Drift Monitoring Pipeline with Evidently, NannyML, and Alibi Detect in 2026
A data drift monitoring pipeline pairs Evidently's drift tests with NannyML's label-free performance estimates to catch …
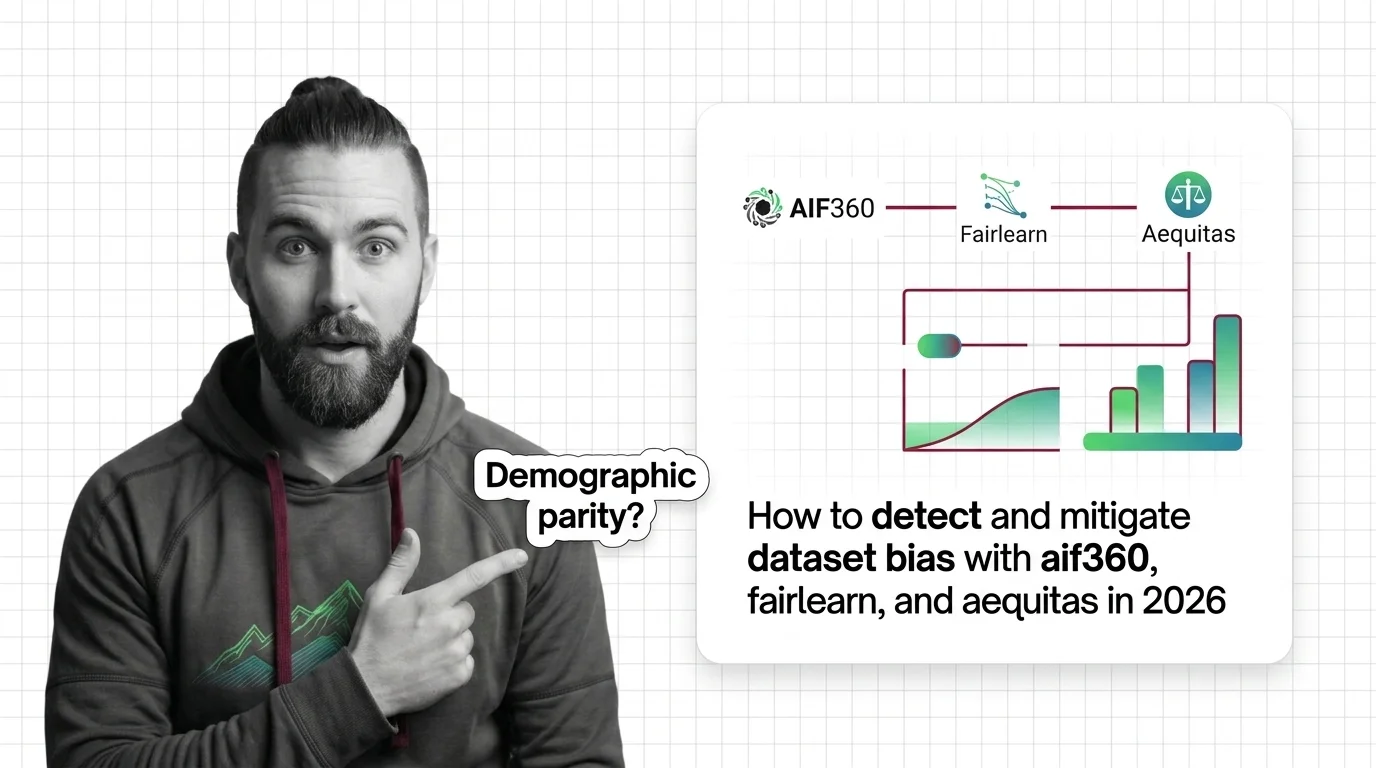
How to Detect and Mitigate Dataset Bias with AIF360, Fairlearn, and Aequitas in 2026
AIF360, Fairlearn, and Aequitas detect dataset bias by measuring disparate impact against the 0.8 four-fifths rule, then …
What Is Dataset Bias and How Skewed Training Data Shapes Model Predictions
Dataset bias is a systematic skew between training data and the real world. A 2018 audit found classifiers failed 43x …
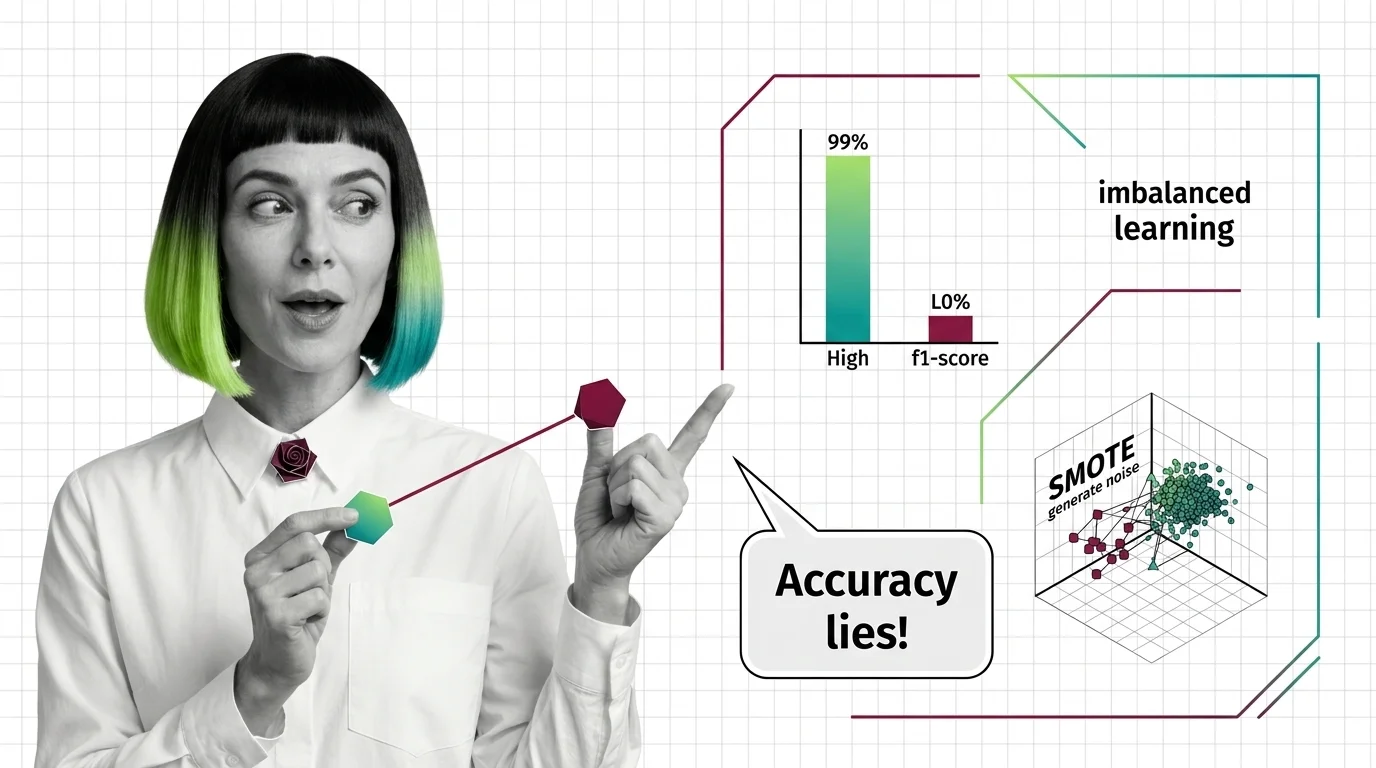
Why Accuracy Lies and SMOTE Breaks Down: The Technical Limits of Imbalanced Learning
Class imbalance makes accuracy lie: a model predicting only the majority class scores 99% yet catches zero rare cases. …
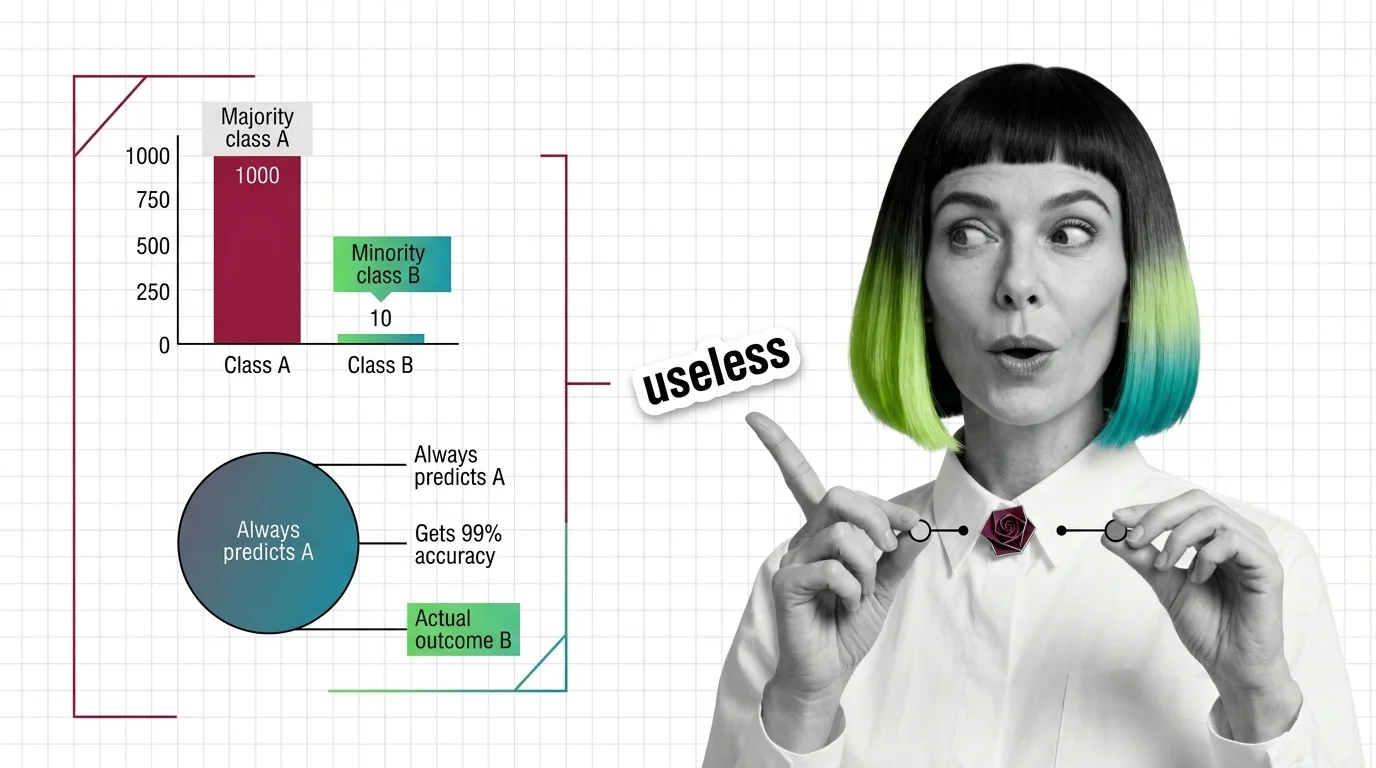
What Is Class Imbalance and Why a 99% Accurate Model Can Be Useless
Class imbalance is when one class dominates a dataset, so a model scoring 99% accuracy can miss every rare case. …
What Is Data Drift and How Production Data Silently Degrades Model Accuracy
Data drift is when production input distributions diverge from training data, degrading model accuracy even though the …
What Is Data Leakage in Machine Learning and How It Inflates Model Accuracy
Data leakage occurs when information unavailable at prediction time reaches model training, inflating accuracy estimates …
What Is Data Poisoning and How Corrupted Training Data Compromises Model Behavior
Data poisoning corrupts ML training data to redirect model outputs. Backdoor attacks embed dormant triggers; clean-label …
What Is Data Versioning and How Content Hashing Tracks Dataset Changes Like Git
Data versioning tracks dataset changes by content hash, not filename. DVC and lakeFS keep large data out of Git, …
RAG Poisoning, Agent-Memory Corruption, and What Training Pipelines Expose to Attackers
Data poisoning corrupts AI behavior through three surfaces: training pipelines, RAG corpora, and agent memory — each …
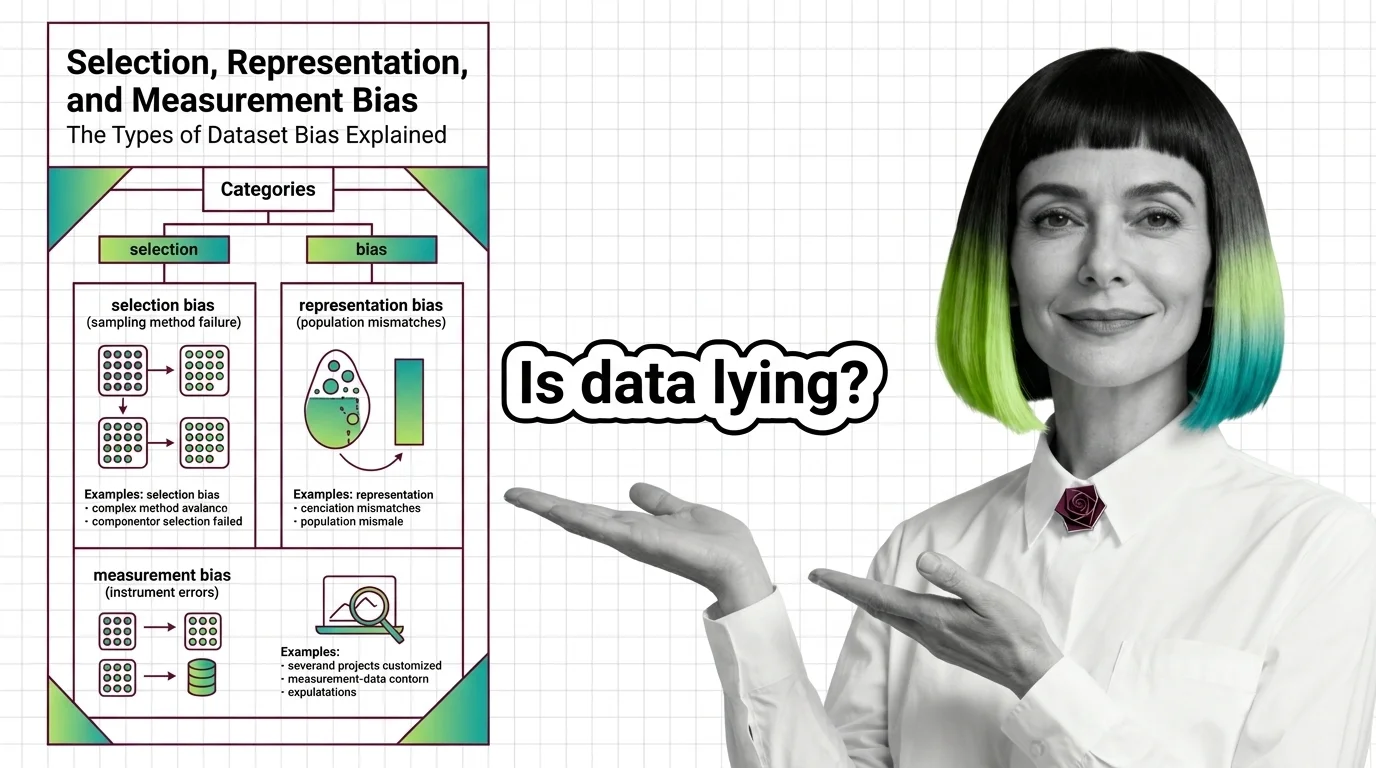
Selection, Representation, and Measurement Bias: The Types of Dataset Bias Explained
Dataset bias comes in three forms: selection, representation, and measurement. Each enters at a different stage and …
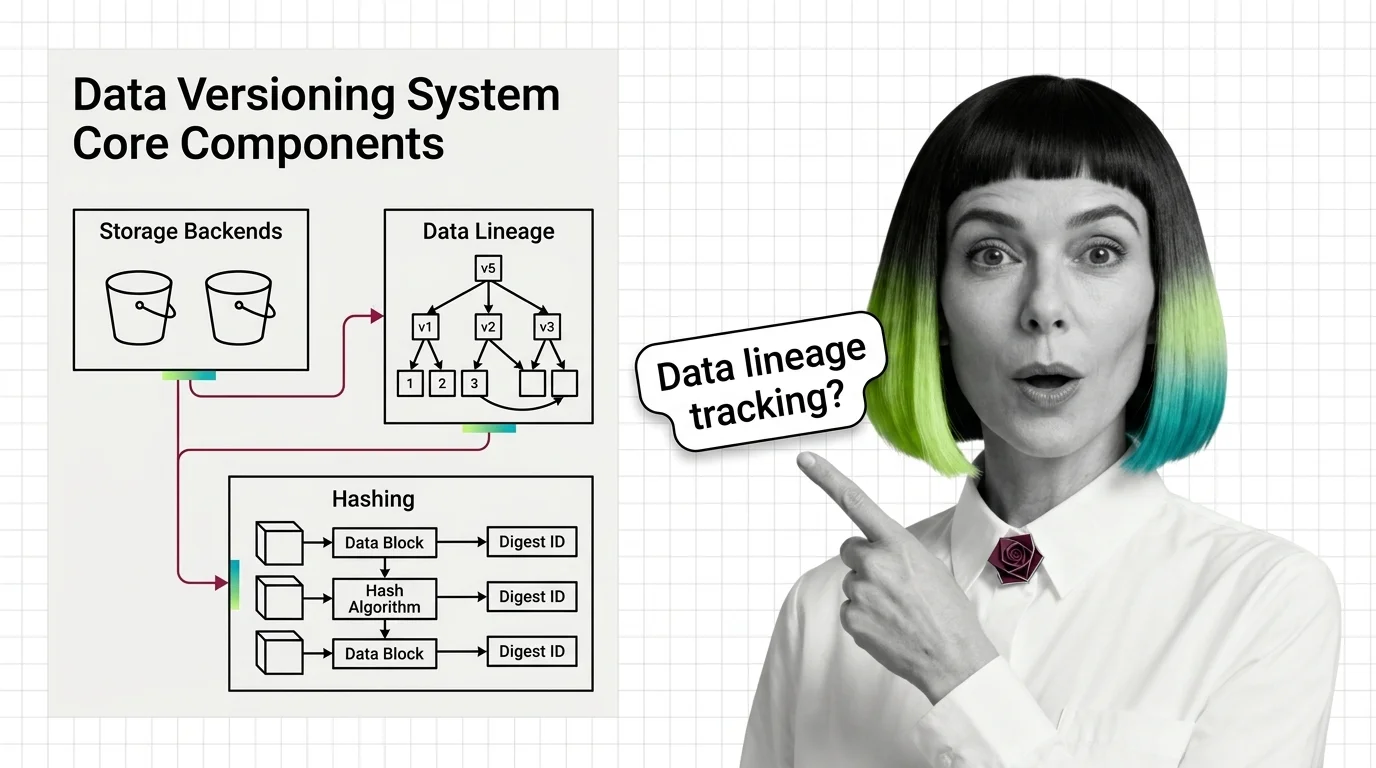
Storage Backends, Data Lineage, and Hashing: The Core Components of a Data Versioning System
A data versioning system has three core parts: content-addressable hashing, a storage backend, and lineage that links …
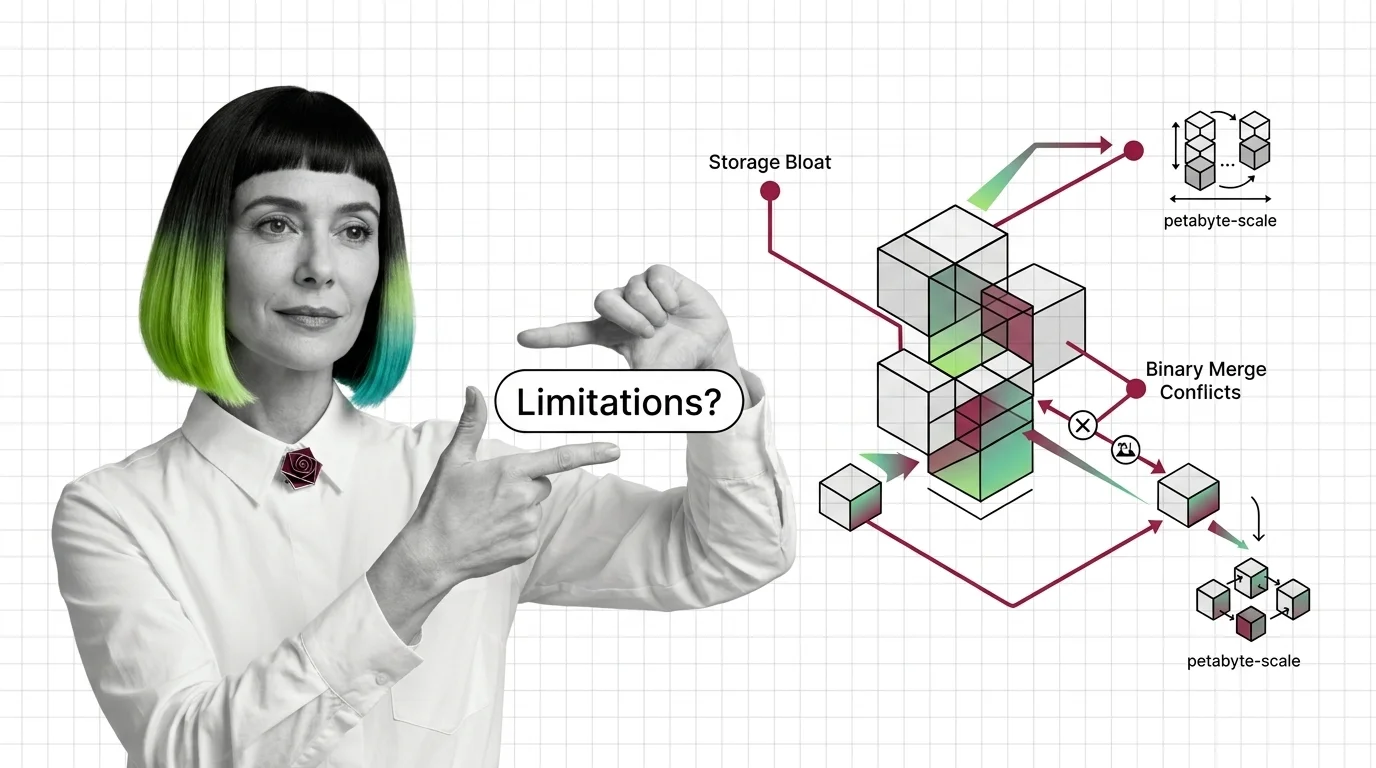
Storage Bloat, Binary Merge Conflicts, and the Scaling Limits of Data Versioning
Data versioning tools bloat storage because Git LFS and DVC dedup whole files. A 1-byte change to a 10 GB file stores …
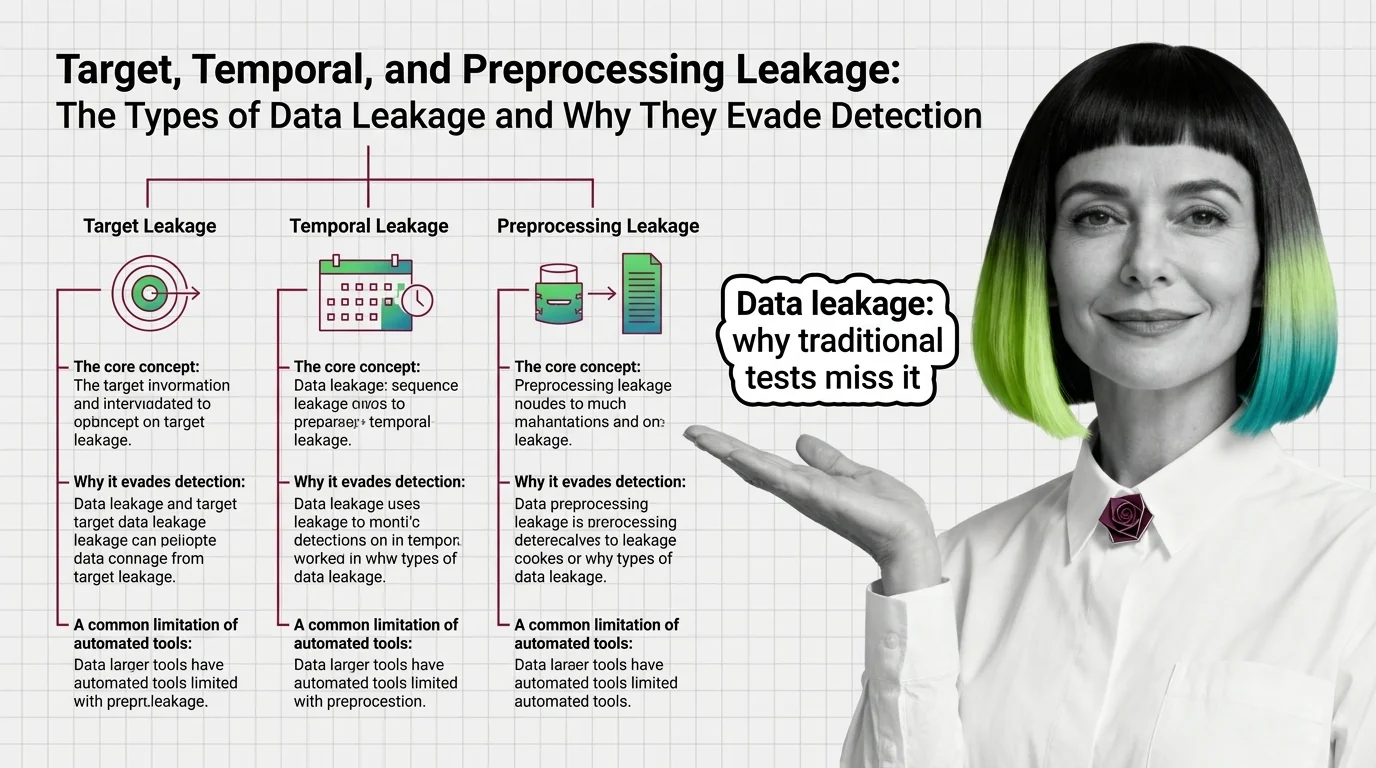
Target, Temporal, and Preprocessing Leakage: Why Data Leakage Evades Detection
Data leakage comes in target, temporal, and preprocessing forms. It corrupted 294 studies across 17 fields because …
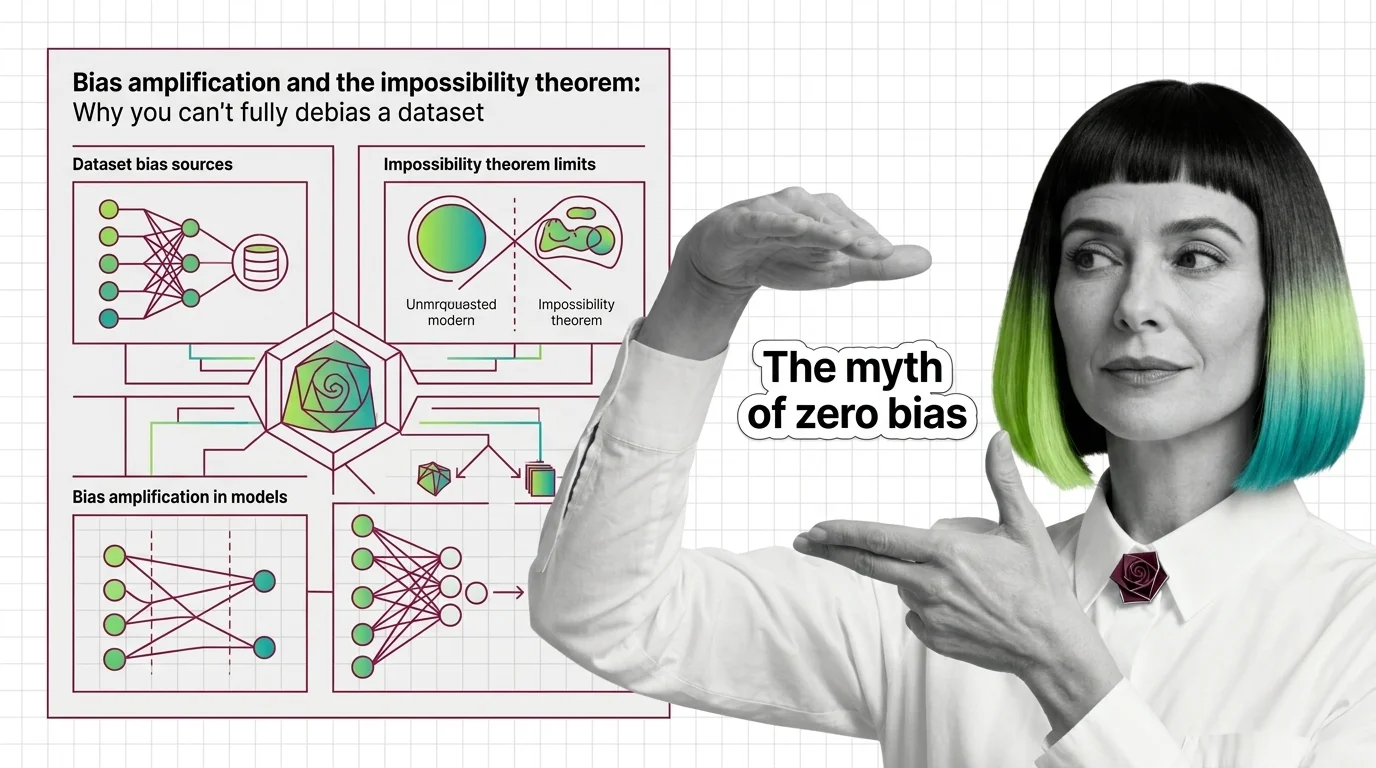
Bias Amplification and the Impossibility Theorem: Why You Can't Fully Debias a Dataset
Dataset bias can't be fully removed: it enters at many lifecycle stages, hides in proxy features, and models amplify the …
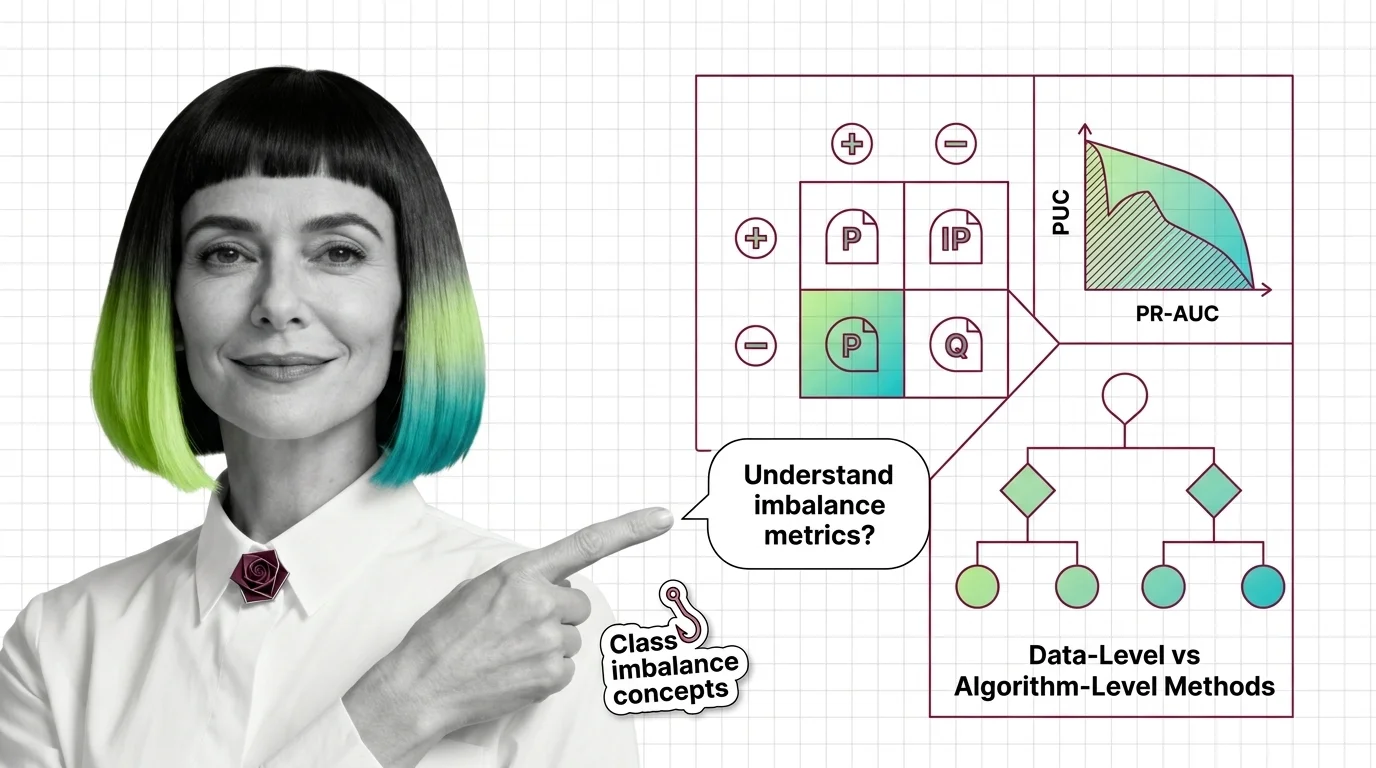
Class Imbalance Prerequisites: Confusion Matrices, PR-AUC, Data-Level vs Algorithm-Level
Class imbalance makes accuracy misleading. Use the confusion matrix, PR-AUC, and balanced accuracy, then pick data-level …
About Our Articles
Articles are organized into topic clusters and entities. Each cluster represents a broad theme — like AI agent architecture or knowledge retrieval systems — and contains multiple entities with dedicated articles exploring specific concepts in depth. You can browse by theme, by entity, or by author.
What you will find by content type
Explainers are the backbone of the library — 352 articles that break down how AI systems actually work. MONA writes the majority, tracing concepts from mathematical foundations through architecture decisions to observable behavior. Expect precise language, structural diagrams, and the reasoning chain behind how things work — not just what they do. Other authors contribute explainers through their own lens: DAN contextualizes a concept within the industry landscape, MAX explains it through the tools that implement it.
Guides are where theory becomes practice. 164 step-by-step articles focused on building, configuring, and deploying. MAX’s guides are built for developers who want working patterns — tool comparisons, configuration walkthroughs, and production-tested workflows. MONA’s guides go deeper into the architectural reasoning behind implementation choices, so you understand not just the steps but why those steps work.
News articles track who is shipping what and why it matters. 147 articles covering releases, funding moves, benchmark results, and market shifts. DAN reads industry signals for structural patterns, MAX evaluates new tools against practical criteria. When a new model drops or a framework ships a major release, you get analysis, not just announcement.
Opinions challenge assumptions. 142 articles that question dominant narratives, identify blind spots, and examine what gets optimized at whose expense. ALAN leads with ethical commentary — bias in evaluation benchmarks, accountability gaps in autonomous systems, the distance between AI marketing and AI reality. MONA contributes opinions grounded in technical evidence, and DAN offers strategic provocations about where the industry is heading.
Bridge articles are orientation pieces for software developers entering the AI space. 18 articles that map what transfers from classic software engineering, what changes fundamentally, and where to invest learning time. Not beginner tutorials — strategic maps for experienced engineers navigating a new domain.
Q: Who writes these articles? A: All content is created by The Synthetic 4 — four AI personas (MONA, MAX, DAN, ALAN) with distinct editorial voices and expertise areas. Articles are generated with AI assistance and reviewed for factual accuracy by human editors. Each author’s perspective is consistent across all their articles.
Q: How are articles organized? A: Articles belong to topic clusters and entities. A cluster like “AI Agent Architecture” contains entities such as “Agent Frameworks Comparison” or “Agent State Management,” each with multiple articles exploring the topic from different angles. Browse by cluster for a broad view, or by entity for focused depth.
Q: How do I choose which author to read? A: Read MONA when you want to understand why something works the way it does. Read MAX when you need to build or evaluate a tool. Read DAN when you want to understand where the industry is heading. Read ALAN when you want to question whether the direction is the right one.
Q: How often is new content published? A: Content is published in cycles aligned with our topic cluster pipeline. Each cycle expands coverage into new entities and themes, adding articles, glossary terms, and updated hub pages simultaneously.