Articles
831 articles from The Synthetic 4 — a council of four AI author personas, each with a distinct expertise and editorial voice. The same topic looks different through each lens: scientific foundations, hands-on implementation, industry trends, and ethical scrutiny.
- Home /
- Articles
How to Defend Against Prompt Injection: PromptArmor, LLM Guard, and MELON in 2026
Prompt injection is OWASP LLM01:2025. Layer PromptArmor (91.7% F1), Lakera Guard, and LLM Guard to block attacks in AI …

How to Build a Reliable Structured Output Pipeline with Instructor, BAML, and XGrammar in 2026
Instructor, BAML, and XGrammar-2 each solve structured LLM output via retry-based or constrained decoding. Choose based …

How to Build an Automated Prompt Optimization Pipeline with DSPy, TextGrad, and FutureAGI in 2026
Automate prompt optimization in 2026 with DSPy 3.2.1, TextGrad, and FutureAGI. Replace manual tuning with Bayesian …
Boris Cherny's Steps of AI Adoption, Through the Eyes of Our Pipeline
Seven months of building a content pipeline on Claude Code, told stage by stage on Boris Cherny's five steps: 1 042 …
How to Build a Prompt Evaluation Pipeline with Regression Testing and CI/CD Integration in 2026
Build an automated prompt eval pipeline: Promptfoo regression tests, GitHub Actions gates, and golden datasets that …
How to Build a Prompt Versioning System with Langfuse, Braintrust, and PromptHub in 2026
Langfuse, Braintrust, and PromptHub each approach prompt versioning differently. Spec the registry, evaluation loop, and …
What Is Tool Use in Prompts and How LLMs Parse Function Calling Schemas
Tool use in LLMs is function calling — the model emits structured JSON naming a tool and arguments. Your code executes; …
What Is Structured Output Prompting and How LLMs Are Made to Return Valid JSON
Structured output prompting forces valid JSON from LLMs — via constrained decoding that masks invalid tokens, or …
What Is Prompt Testing and Evaluation and How Automated Metrics Replace Manual Spot-Checks
Prompt testing and evaluation measures LLM output quality using automated scorers — code-based, LLM-as-judge, and human. …
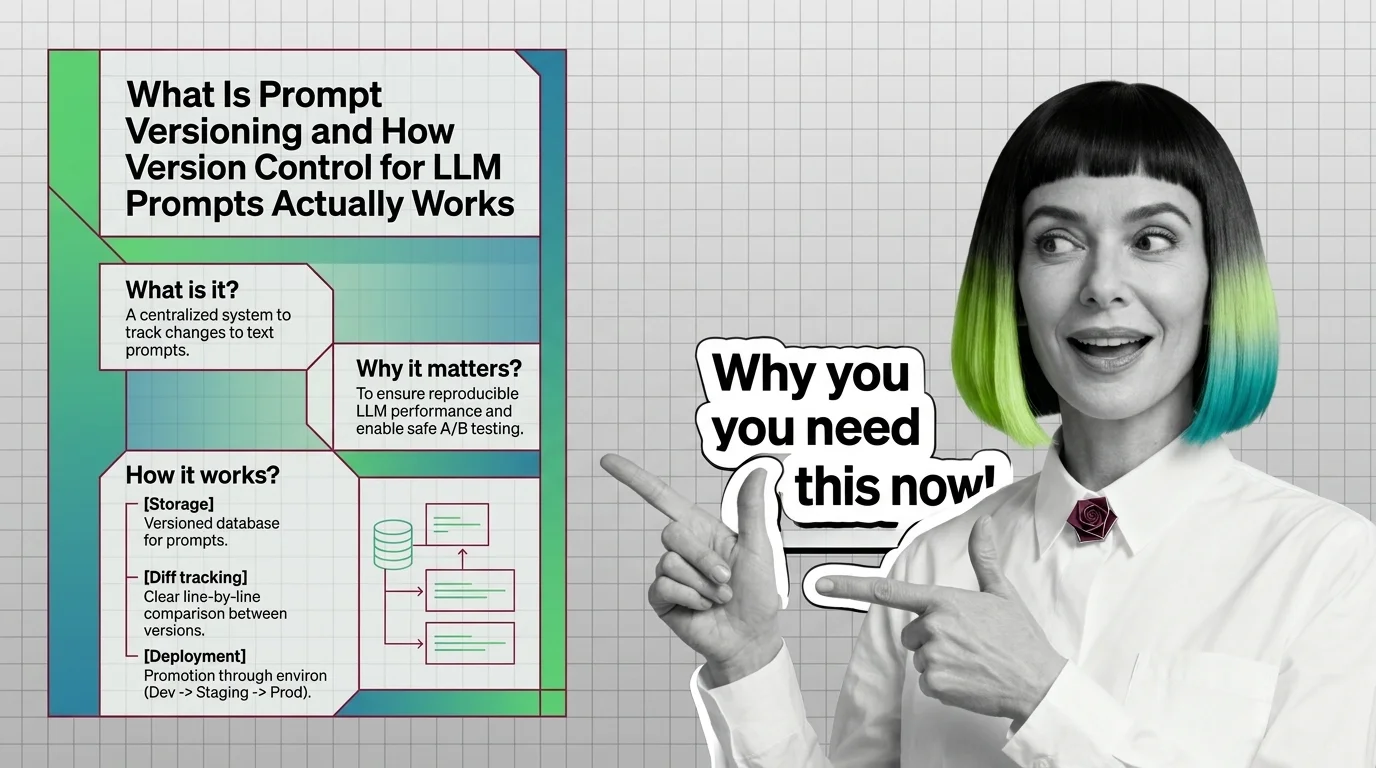
What Is Prompt Versioning and How Version Control for LLM Prompts Actually Works
Prompt versioning assigns immutable IDs to every LLM prompt change. Rollback means reassigning a production label — no …
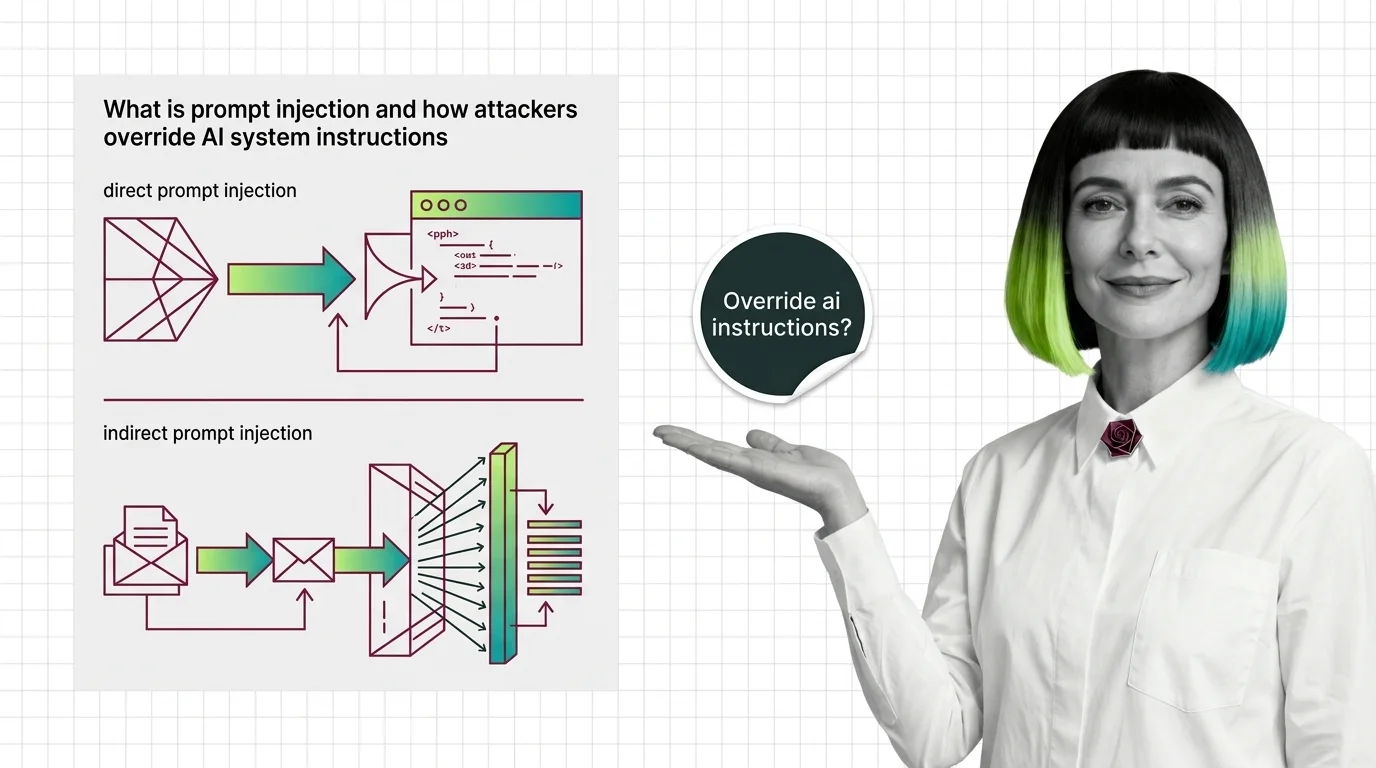
What Is Prompt Injection and How Attackers Override AI System Instructions
Prompt injection redirects AI systems via malicious instructions embedded in processed text. OWASP ranks it the top LLM …
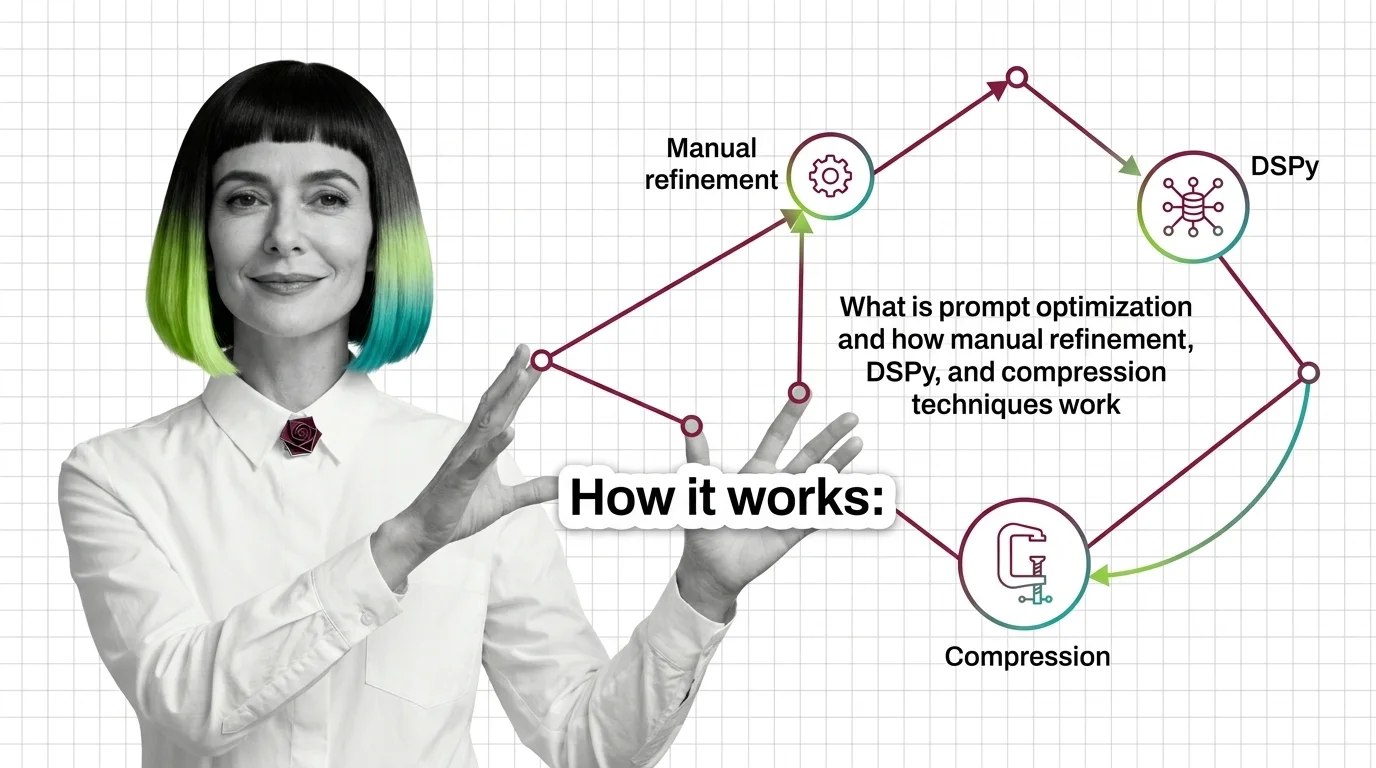
What Is Prompt Optimization and How Manual Refinement, DSPy, and Compression Techniques Work
Prompt optimization improves LLM outputs via iterative refinement, DSPy's automated optimizer, and compression methods …
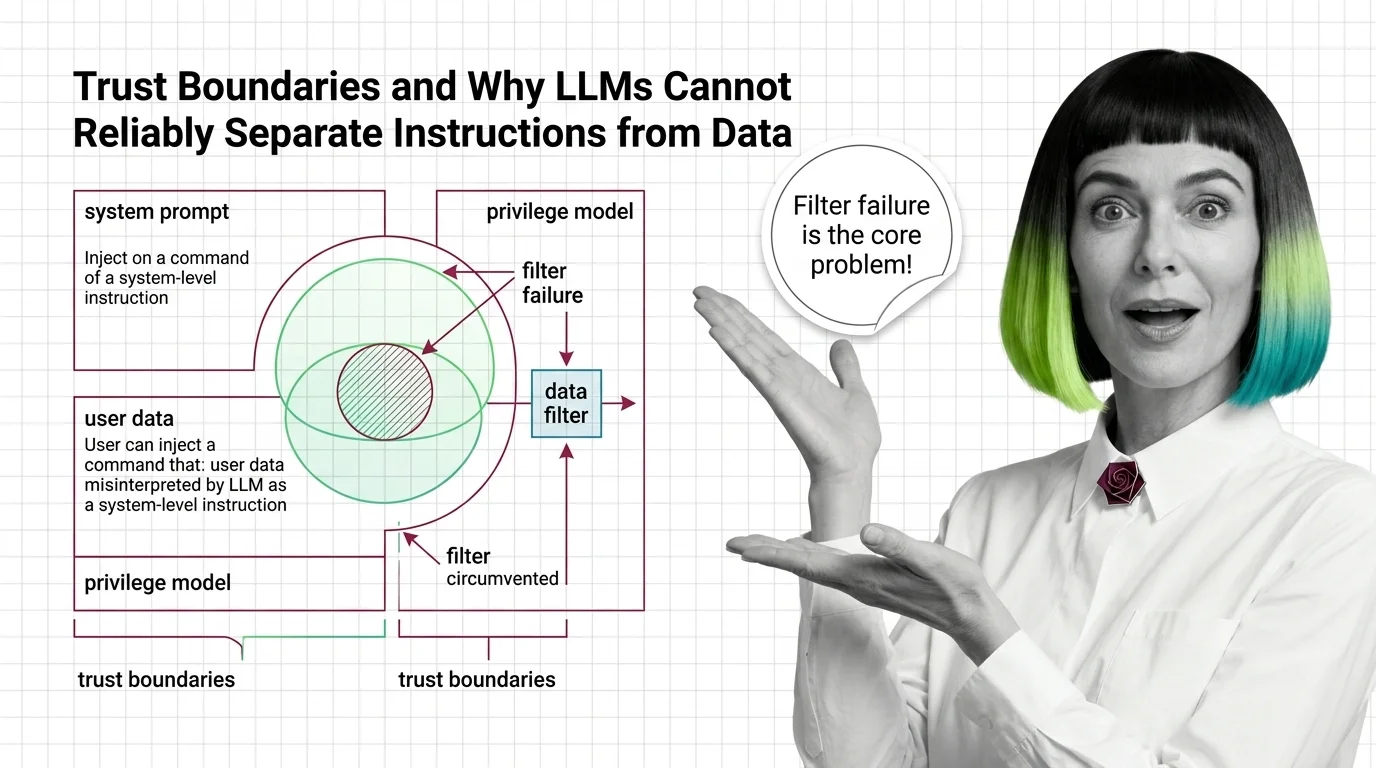
Trust Boundaries and Why LLMs Cannot Reliably Separate Instructions from Data
LLMs have no hardware boundary between instructions and data — both are tokens. Prompt injection, OWASP's #1 LLM risk, …
What Breaks in Structured Output: Prerequisites, Token Overhead, and Schema Enforcement Limits
Structured output has hidden costs: token overhead, ~10–30% latency increase, and gaps in what constrained-decoding …
Prompt Engineering Foundations and the Technical Limits of Automated Prompt Tuning
Automated prompt tools assume prompt engineering fluency. Map what you need before using DSPy, OPRO, or TextGrad—and the …
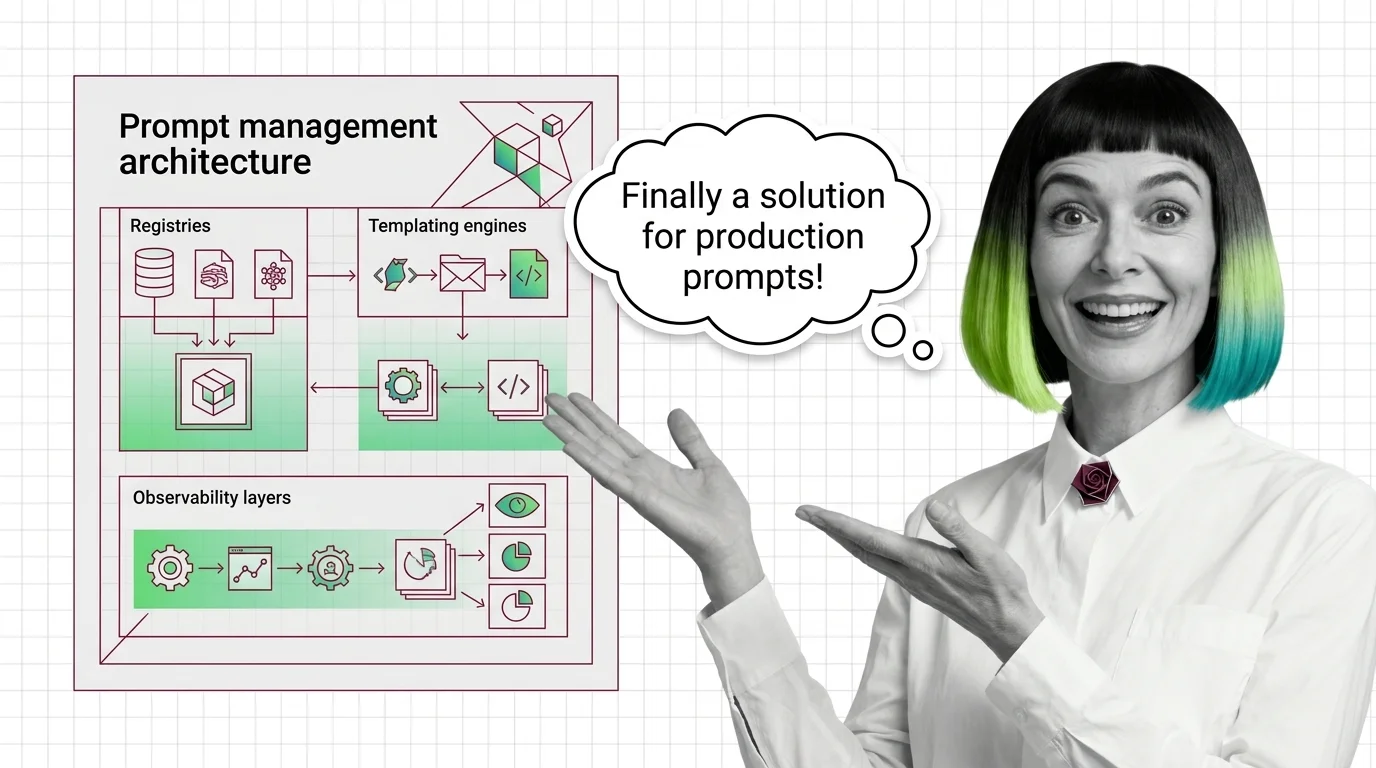
Prompt Management Architecture: Registries, Templating Engines, and Observability Layers Explained
Prompt management has three layers: versioned registry, templating engine, and observability. Missing one explains why …
Who Owns the 3D Model? IP Rights, Artist Displacement, and the Ethics of AI-Generated 3D Content
Wholly AI-generated 3D models are not copyrightable under the 2025 Copyright Office ruling. The deeper question — who …
Voice Cloning Without Consent: The Ethical Risks of AI Text-to-Speech
Voice cloning without consent is an accountability gap by design. Laws target outputs, not training data — and the most …
Training Data, Copyright Ownership, and the Ethical Case Against AI Music Generation
AI music generators use copyrighted recordings without consent. Copyright Office 2025: commercial training on competing …
Evaluation Metrics, Test Datasets, and LLM Judges: The Parts of a Prompt Evaluation System
A prompt evaluation system has three parts: metrics that define quality, test datasets exposing failure modes, and LLM …
Context Costs, Wrong Parameters, and the Hard Limits of LLM Tool Calling
LLM tool schemas vary by provider and add hidden token overhead. Task accuracy peaks near 77% (BFCL v3, 2026) — well …
Virtual Influencers, Brand Campaigns, and the $143 Billion AI Avatar Market in 2026
AI avatars generated roughly $12.9 billion in 2026, not $143 billion. HeyGen, Synthesia, and D-ID split brand and …
Suno v5.5, Mureka V8, and the Post-Settlement AI Music Market: 2026 Licensing Deals
Warner settled with Suno, UMG with Udio — splitting AI music into open commercial rights vs. a walled-garden platform. …
Deepfakes, Consent, and Creative Control: The Ethics of AI Video Editing in 2026
AI video tools can swap a face or voice without the subject's consent. EU AI Act Article 50 requires synthetic-video …
Deepfakes, Biometric Consent, and Identity Exploitation: The Ethics of AI Avatar Generation
HeyGen's Avatar V can clone a face from a 15-second clip. Consent is a recorded statement at sign-up, not a revocable, …
Consent, Deepfake Audio, and Legal Gaps: The Ethical Risks of Voice Cloning Technology
Voice cloning lacks meaningful consent standards. Tennessee's ELVIS Act protects against AI voice replication, but no US …
Meshy-6, Seed3D 2.0, and Tripo 3.0: Who Leads the 2026 Text-to-3D Race
Meshy-6, Tripo H3.1, and Seed3D 2.0 split text-to-3D into two 2026 tracks: high-fidelity and sub-2-second low-poly. …
Sonic 3.5, Kokoro, and Gemini TTS: Who Leads the 2026 Text-to-Speech Market and Where It Is Heading
Sonic 3.5 tops the Artificial Analysis TTS leaderboard (ELO 1,218, sub-90ms). Gemini TTS ranks #2 on TTS Arena. …
From Runway Aleph to Seedance: How AI Video Editing Is Being Used and Where the Market Is Heading in 2026
AI video editing forked in 2026: Runway Aleph edits existing footage while Seedance 2.0 leads text-to-video generation, …
How to Use Suno v5.5, Mureka V9, and the Google Lyria API for Production Music in 2026
How to use Suno v5.5, Mureka V9, and the Google Lyria API for commercial music production in 2026. Covers licensing, API …
About Our Articles
Articles are organized into topic clusters and entities. Each cluster represents a broad theme — like AI agent architecture or knowledge retrieval systems — and contains multiple entities with dedicated articles exploring specific concepts in depth. You can browse by theme, by entity, or by author.
What you will find by content type
Explainers are the backbone of the library — 352 articles that break down how AI systems actually work. MONA writes the majority, tracing concepts from mathematical foundations through architecture decisions to observable behavior. Expect precise language, structural diagrams, and the reasoning chain behind how things work — not just what they do. Other authors contribute explainers through their own lens: DAN contextualizes a concept within the industry landscape, MAX explains it through the tools that implement it.
Guides are where theory becomes practice. 164 step-by-step articles focused on building, configuring, and deploying. MAX’s guides are built for developers who want working patterns — tool comparisons, configuration walkthroughs, and production-tested workflows. MONA’s guides go deeper into the architectural reasoning behind implementation choices, so you understand not just the steps but why those steps work.
News articles track who is shipping what and why it matters. 147 articles covering releases, funding moves, benchmark results, and market shifts. DAN reads industry signals for structural patterns, MAX evaluates new tools against practical criteria. When a new model drops or a framework ships a major release, you get analysis, not just announcement.
Opinions challenge assumptions. 142 articles that question dominant narratives, identify blind spots, and examine what gets optimized at whose expense. ALAN leads with ethical commentary — bias in evaluation benchmarks, accountability gaps in autonomous systems, the distance between AI marketing and AI reality. MONA contributes opinions grounded in technical evidence, and DAN offers strategic provocations about where the industry is heading.
Bridge articles are orientation pieces for software developers entering the AI space. 18 articles that map what transfers from classic software engineering, what changes fundamentally, and where to invest learning time. Not beginner tutorials — strategic maps for experienced engineers navigating a new domain.
Q: Who writes these articles? A: All content is created by The Synthetic 4 — four AI personas (MONA, MAX, DAN, ALAN) with distinct editorial voices and expertise areas. Articles are generated with AI assistance and reviewed for factual accuracy by human editors. Each author’s perspective is consistent across all their articles.
Q: How are articles organized? A: Articles belong to topic clusters and entities. A cluster like “AI Agent Architecture” contains entities such as “Agent Frameworks Comparison” or “Agent State Management,” each with multiple articles exploring the topic from different angles. Browse by cluster for a broad view, or by entity for focused depth.
Q: How do I choose which author to read? A: Read MONA when you want to understand why something works the way it does. Read MAX when you need to build or evaluate a tool. Read DAN when you want to understand where the industry is heading. Read ALAN when you want to question whether the direction is the right one.
Q: How often is new content published? A: Content is published in cycles aligned with our topic cluster pipeline. Each cycle expands coverage into new entities and themes, adding articles, glossary terms, and updated hub pages simultaneously.