Opinion Articles
Thought-provoking perspectives on AI ethics, policy, and future directions. Expert viewpoints on the most important questions in AI.
- Home /
- Opinion Articles
Style Theft and Copyright Leakage: Ethics of Artist-Name Prompts
When you prompt 'in the style of Greg Rutkowski,' is it tribute or appropriation? An ethical look at artist-name tokens …
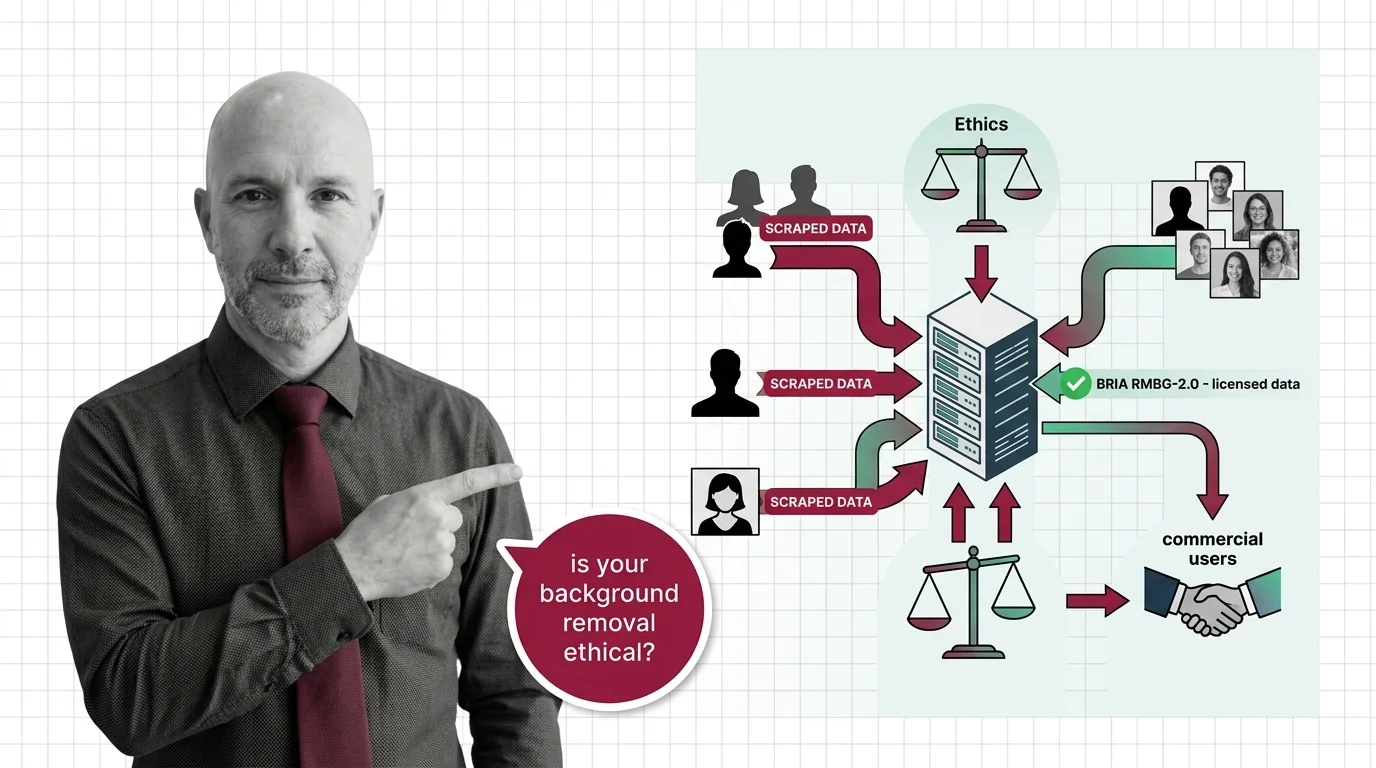
Scraped Photos, Stripped Subjects: The Training Data Ethics Behind Every Background Removal API
Background removal APIs strip subjects from scraped photos. Only one top model trains on licensed data. The ethics …
Invented Detail, Borrowed Faces: Diffusion Upscaler Risks
Diffusion upscalers invent detail and borrow faces from biased training data. The provenance, privacy, and forensic …
Trained on Whose Faces? LoRA Ethics: Likeness, Style Theft, Deepfakes
LoRAs made it possible to fine-tune any face in fifteen minutes. The consent gap stopped being hypothetical the moment …
Deepfakes, Copyright, Consent: The Ethical Reckoning of AI Image Editing
AI image editing has industrialized the act of lifting someone's likeness. Consent law, C2PA metadata, and new …
Deepfakes, Scraped Art, Consent: The Ethical Reckoning of Diffusion Models
Diffusion models scraped the internet before asking. Now lawsuits, legislation, and artist tools are forcing a consent …
Surveillance, Deepfakes, Consent: Multimodal AI's Ethical Crisis
Multimodal AI can now see, hear, and speak in one pass. The ethics haven't caught up. What consent, surveillance, and …
Biased Training Data and Patch-Level Attacks: The Ethical Risks of Vision Transformers in High-Stakes Systems
Vision Transformers deployed in healthcare and surveillance inherit bias from web-scraped datasets. From LAION to …
Linear-Time Efficiency, Unequal Access: Who Wins and Who Loses as State Space Models Scale
State space models slash inference costs and open long-context AI. But cheaper compute reshapes who holds power — and …
The Concentration Problem: Who Can Afford to Train Trillion-Parameter MoE Models and What That Means for AI Access
Trillion-parameter MoE models promise efficiency through sparse activation. But training costs keep rising, and the …
Amplified Bias and Opaque Connections: The Ethical Risks of Graph Neural Networks in High-Stakes Decisions
Graph neural networks judge people by connections. When those relationships encode historical inequality, bias amplifies …
Synthetic Faces and Learned Distributions: The Ethical Risks When VAEs Recreate Private Data
Variational autoencoders can memorize and recreate private training data. Why synthetic faces and medical records are …
Sequential Bias and Opaque Memory: The Ethical Risks of Recurrent Networks in High-Stakes Decisions
RNNs carry opaque sequential memory into high-stakes decisions. Explore why hidden states resist auditing and what that …
The Black Box Problem: Why Neural Network Opacity Undermines Accountability in LLM Decisions
Neural networks powering LLM decisions are opaque by design. This essay traces why that opacity creates an …
Trained on Bias, Deployed on Faces: The Ethical Cost of CNN-Powered Surveillance Systems
CNN-powered facial recognition hits 98% on benchmarks but fails along racial and gender lines. The ethical cost of …
Who Decides What Gets Measured: The Accountability Gap in Standardized LLM Evaluation
Standardized LLM evaluation harnesses shape which AI models succeed, yet their design choices go unaudited. Explore the …
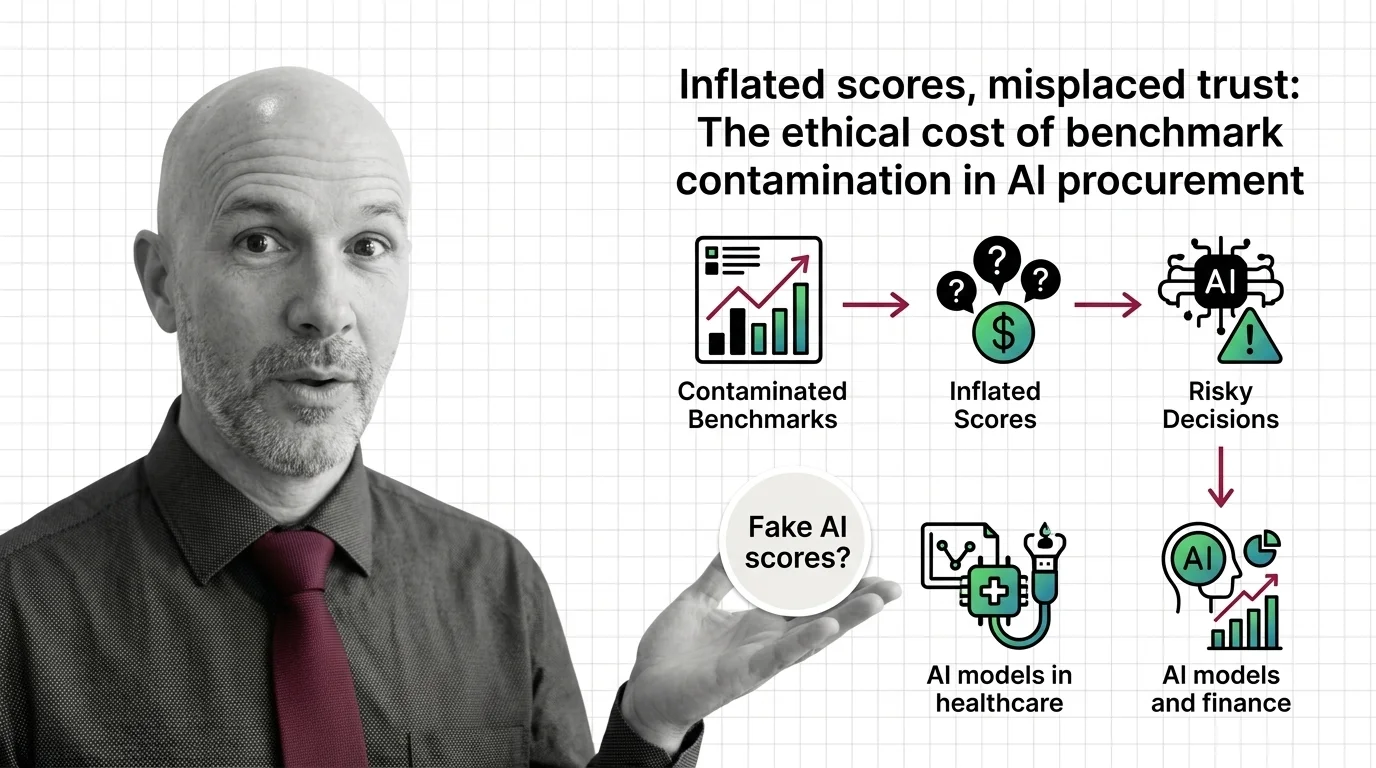
Inflated Scores, Misplaced Trust: The Ethical Cost of Benchmark Contamination in AI Procurement
Inflated benchmark scores shape AI procurement in healthcare and finance. An ethical examination of contamination, …
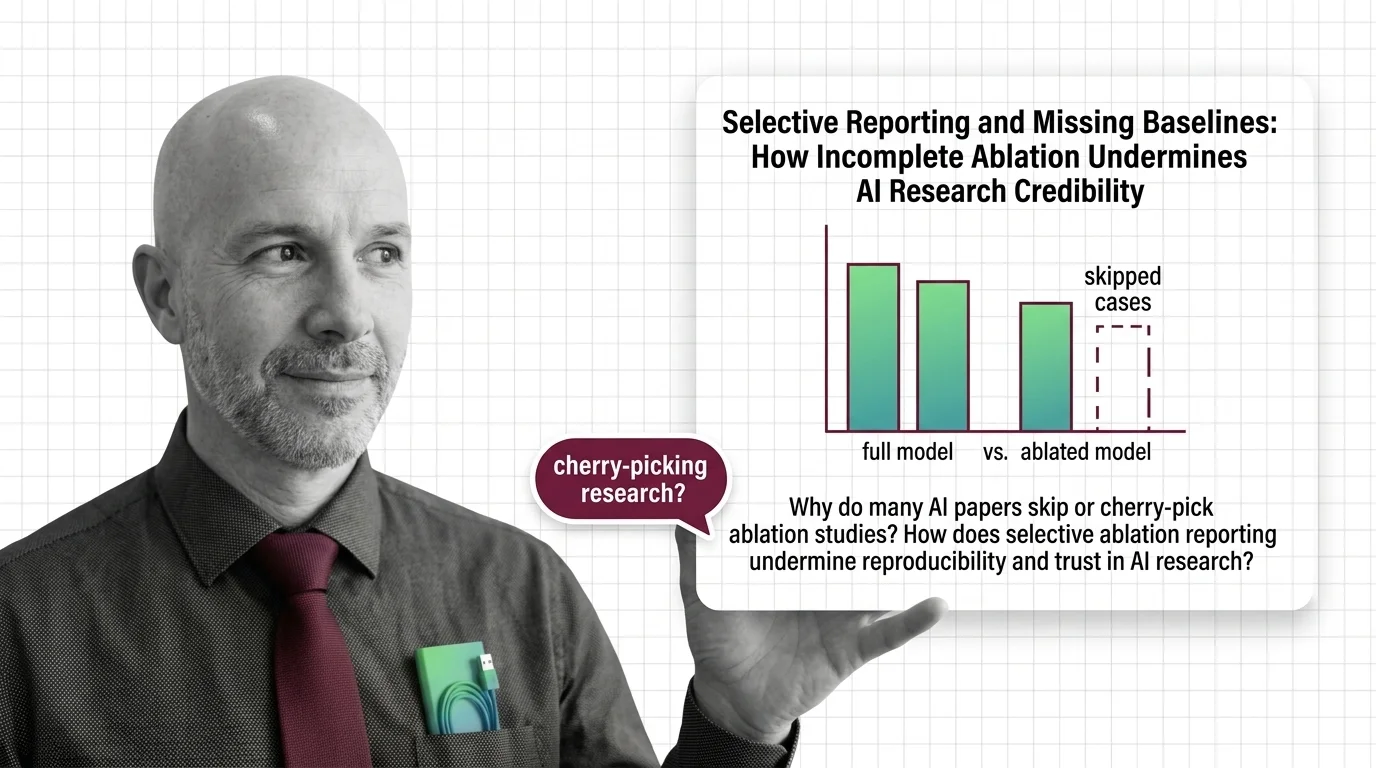
Selective Reporting and Missing Baselines: How Incomplete Ablation Undermines AI Research Credibility
Selective ablation reporting hides whether AI breakthroughs are real. Explore how missing baselines erode research trust …
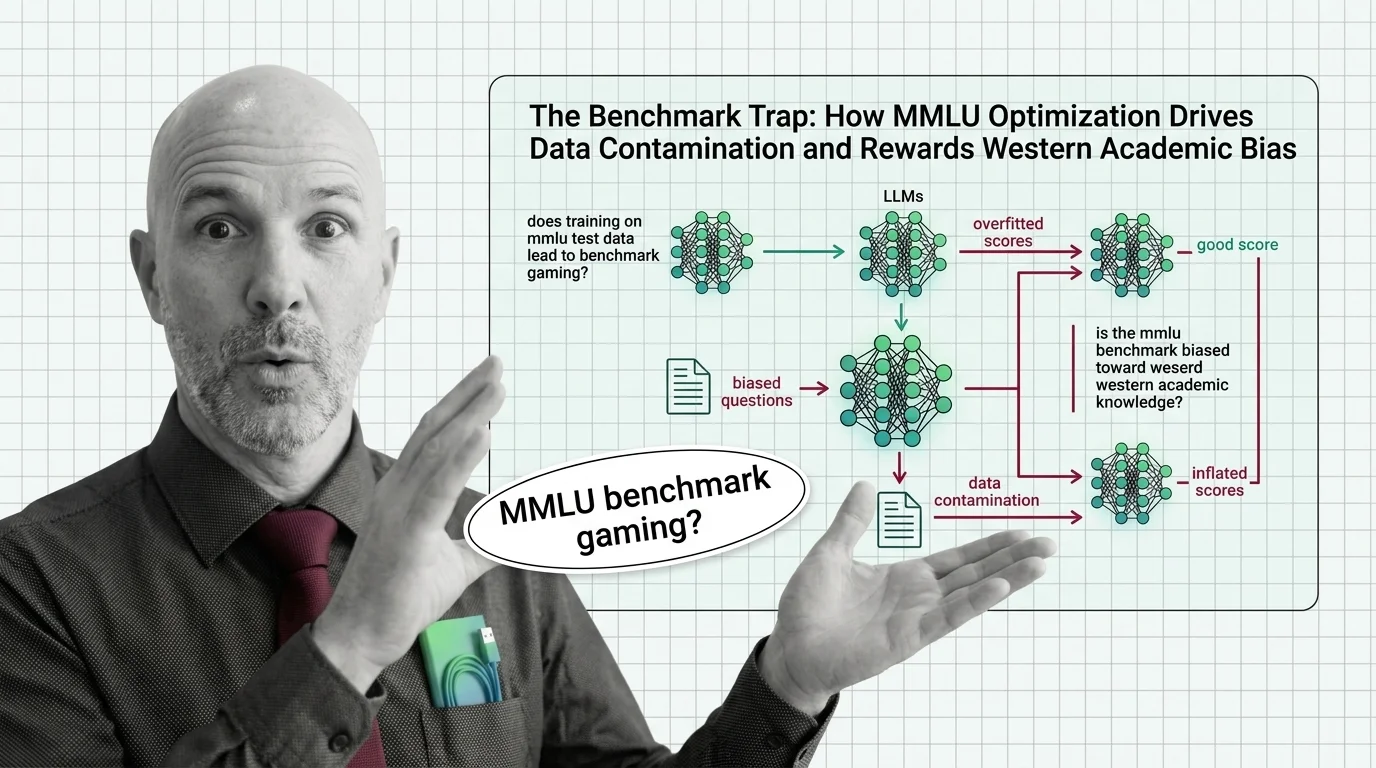
The Benchmark Trap: How MMLU Optimization Drives Data Contamination and Rewards Western Academic Bias
MMLU scores dominate AI headlines, but data contamination and cultural bias undermine what they actually measure. An …
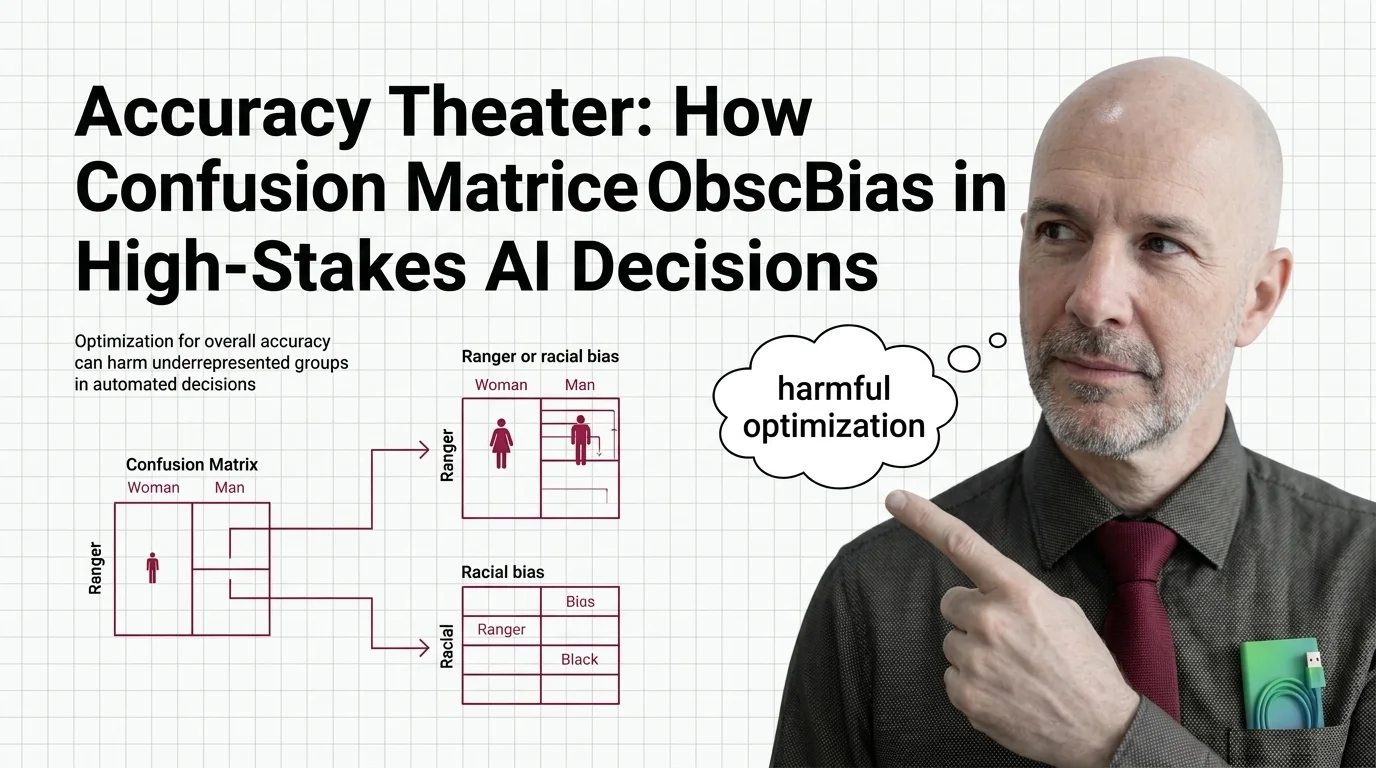
Accuracy Theater: How Confusion Matrices Obscure Bias in High-Stakes AI Decisions
Overall accuracy hides who bears the cost of AI errors. Explore how confusion matrices obscure racial and gender bias in …
Fairness by Numbers: When Bias Metrics Mask Structural Inequality Instead of Fixing It
Fairness metrics promise objectivity but can mask structural inequality. Learn why statistical parity fails to deliver …
Optimizing for the Wrong Number: How F1 Score Masks Disparate Impact in High-Stakes Classification
F1 score can mask racial and gender bias in hiring and criminal justice. Learn why aggregate metrics fail fairness and …
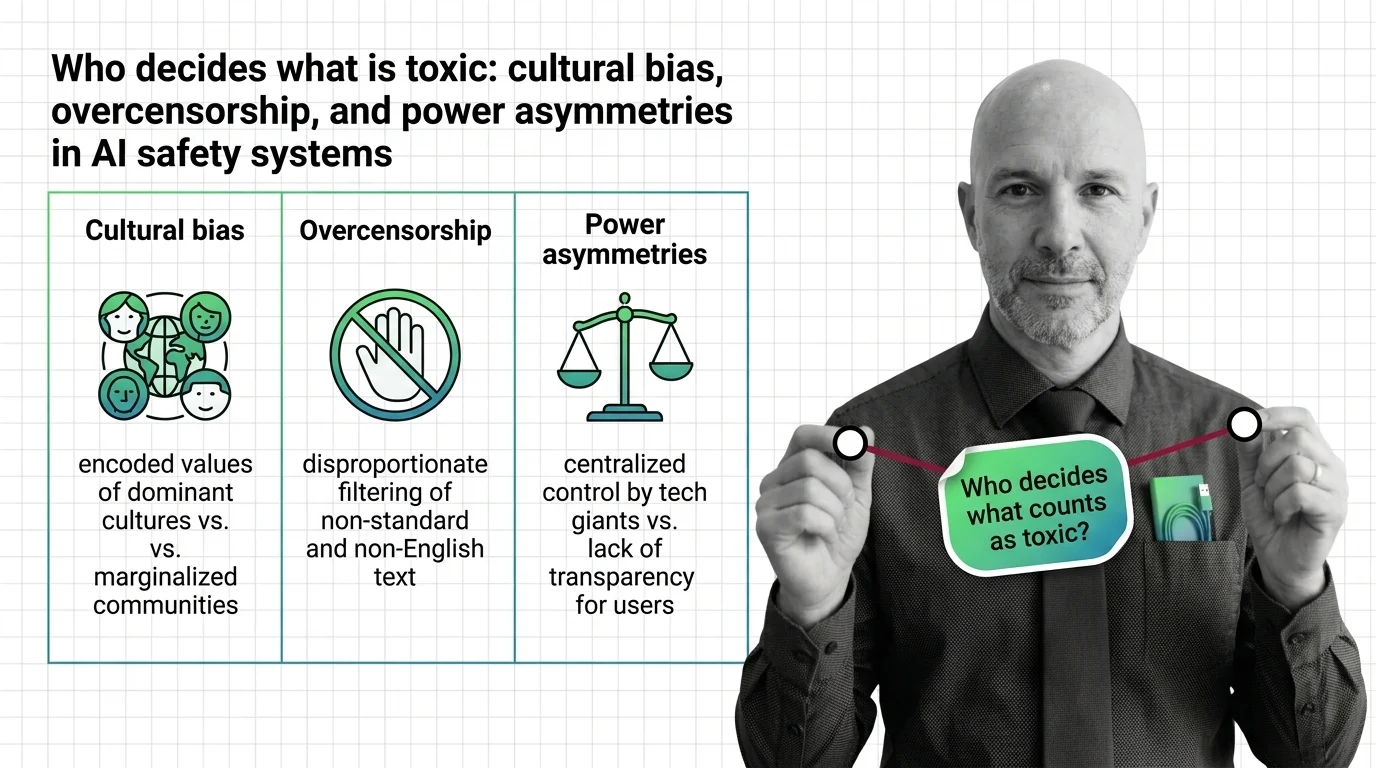
Who Decides Toxicity? Bias, Overcensorship, Power in AI Safety
AI toxicity classifiers embed cultural bias, creating disparate censorship of marginalized communities. Examine how …
Who Decides What Good Means: Cultural Bias and Power Asymmetry in LLM Benchmarks
LLM benchmarks encode their creators' cultural values. Explore how geographic bias, moral stereotyping, and power …
Always-On AI: The Environmental Price and Access Inequality of Large-Scale Inference
AI inference runs 24/7 on energy, water, and carbon. The environmental cost is real, the access gap is widening, and …
Compressed Intelligence, Unequal Access: The Hidden Costs of Quantized AI
Quantization makes AI accessible but the quality loss isn't evenly distributed. Explore who benefits from compressed …
Opaque Defaults and Locked Knobs: The Ethics of Who Controls LLM Sampling Parameters
Major LLM providers are locking sampling parameters like temperature and top-p. Explore who controls these defaults, …
Request Queues and GPU Access: Who Waits Longest When Continuous Batching Decides
Continuous batching boosts GPU throughput, but its scheduling quietly decides who waits. Examining fairness, priority, …
When AI Lies Confidently: Liability, Disclosure, and the Unsolved Ethics of LLM Hallucination
LLM hallucination is no longer a quality bug. It is a liability, disclosure, and governance problem. Explore who bears …
Who Gets to Break the Model: Power, Access, and Accountability Gaps in AI Red Teaming
AI red teaming promises safety through adversarial testing, but who selects the testers, defines harm, and bears …