News Articles
Latest developments, trends, and updates in the AI industry. Timely coverage of new releases, market movements, and emerging technologies.
- Home /
- News Articles
From Game of 24 to o3: How Tree of Thoughts Shaped Native Reasoning Models in 2026
In 2023, Tree of Thoughts lifted Game of 24 from 4% to 74%. By 2026, o3 and Claude Fable 5 internalized the same …
From Manual Prompts to Braintrust Loop: Prompt Engineering in Production and Where It Is Heading in 2026
Prompt engineering is becoming infrastructure. Notion runs 70+ engineers on shared evals; Stripe benchmarks real …
GPT-5.5, Gemini 3 Deep Think, and Qwen 3.5 Omni: Multimodal Benchmark Results and the Omni Model Shift in 2026
Benchmark saturation hit multimodal AI in April 2026. GPT-5.5 leads chart reasoning; Gemini 3 tops overall; Qwen3.5-Omni …
How Law Firms, Hospitals, and Dev Teams Deploy Domain-Specific Prompting in Production in 2026
Domain-specific prompting is production-grade in 2026. Harvey AI processes 200K+ legal queries daily; GitHub Copilot …
Leaked Prompts and Production Failures: How Real Companies Engineer System Prompts in 2026
Leaked system prompts hit 134K GitHub stars as labs confront a structural truth: prompt text is one defense layer, not …
Constitutional AI in Production: How Claude, DSPy, and Enterprise Teams Use Self-Critique in 2026
Constitutional AI moved from Anthropic's lab to enterprise stacks. Claude and DSPy embed self-critique at training and …
LLM Load Testing in 2026: Case Studies, llmperf Archival, and Where the Stack Is Heading
llmperf was archived December 2025. GuideLLM v0.6.1 and AIPerf v0.10.0 replace it, while production multi-modal latency …
Model Registries in Production and the 2026 Shift Toward LLM Weight Management and Multi-Cloud Catalogs
Model registries split in 2026: classical ML stores can't handle LLM weights or banking audit requirements. MLflow 3.14 …
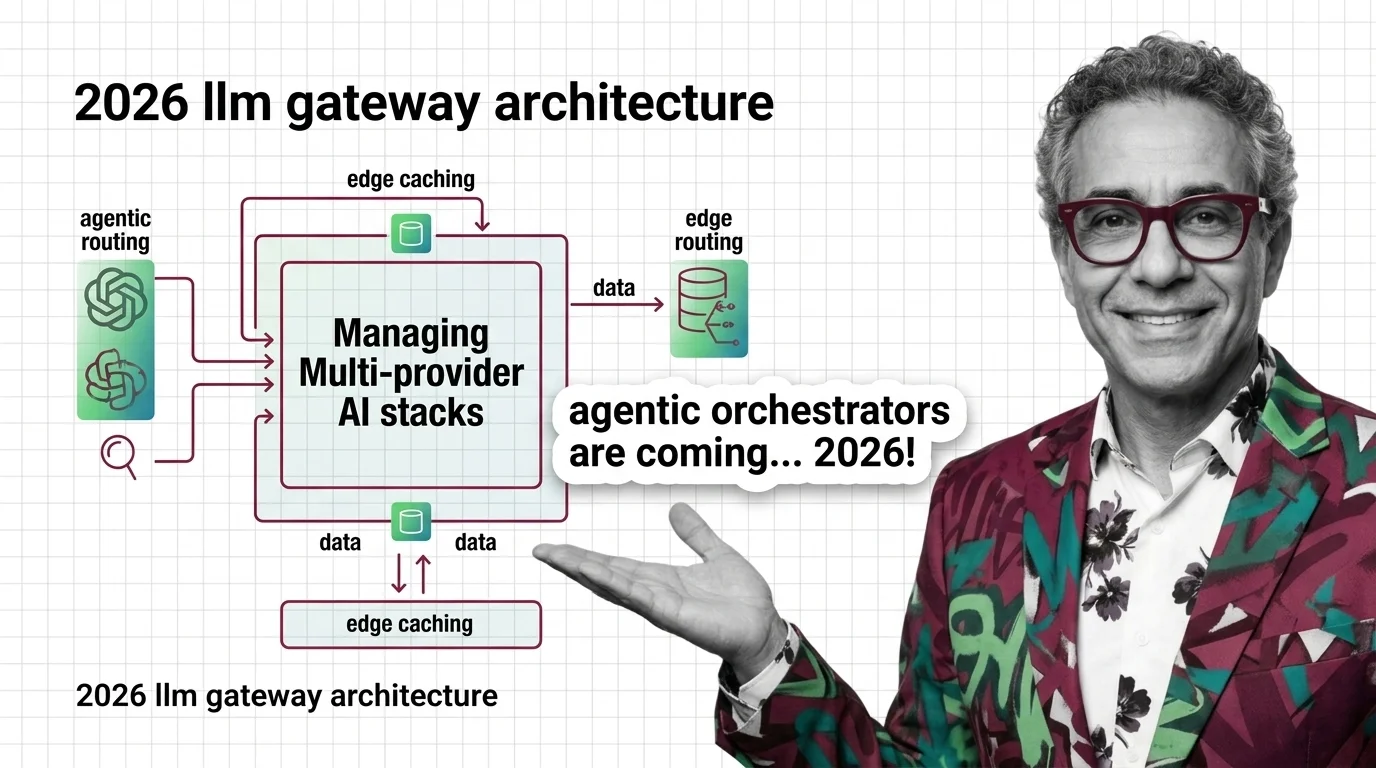
FloTorch, Bifrost, and OpenRouter: How 2026 LLM Gateways Are Adding Agentic Routing and Edge Caching
LLM gateways split in 2026. Bifrost: 11µs overhead. OpenRouter: 400+ models. MCP routing is the new baseline for …
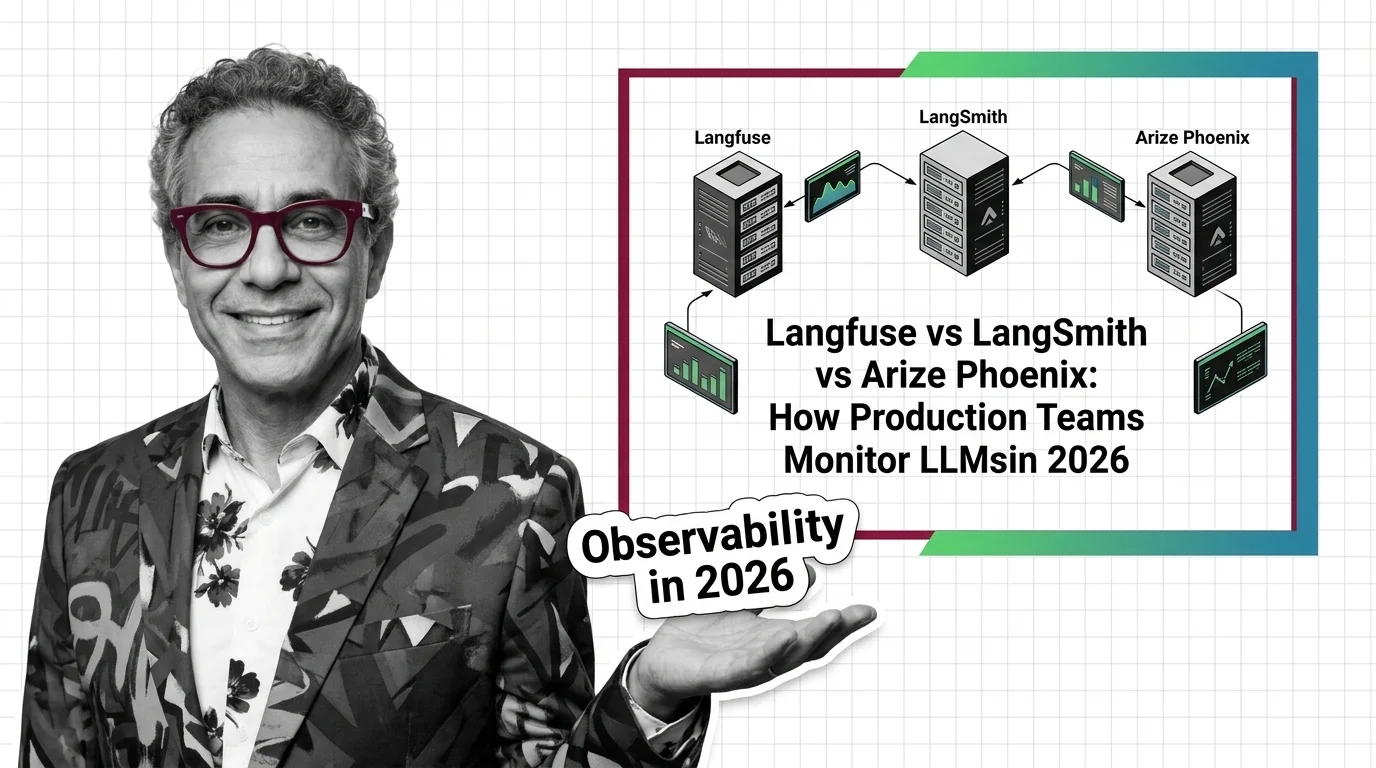
Langfuse vs LangSmith vs Arize Phoenix: How Production Teams Monitor LLMs in 2026
LLM observability in 2026: ClickHouse acquired Langfuse, Traceloop merged into ServiceNow. Compare Langfuse, LangSmith, …
LangSmith, AgentOps, and Arize Phoenix: LLM Logging Is Now Compliance Infrastructure
LangSmith, AgentOps, and Arize Phoenix lead LLM logging in 2026. OTel GenAI conventions are pushing all three toward …
LLM A/B Testing in Production 2026: Engineering Case Studies and the Shift to Automated Experimentation
LLM A/B testing moved from manual prompt tweaks to automated optimization in 2026. Prompt changes are now the leading …
LLM Failover in Production 2026: Bifrost Benchmarks, Real Outages, and the AI Gateway Race
Repeated LLM outages in 2025-2026 ended the single-provider era. Bifrost, LiteLLM, Portkey, and Cloudflare are racing to …
10M-Token Windows vs. Compression: How Real Products Handle Context Limits in 2026
Every major frontier model now offers 1M+ token contexts. Cost math still favors compression at scale. Production teams …
Azure AI Studio, OpenAI Batch API, and Real Production LLM Cost Wins in 2026
Azure AI Foundry Model Router spans 28 models. OpenAI Batch API offers 50% off. DeepSeek V3.2 at $0.28/1M is rewriting …
Braintrust, OpenRouter, and LiteLLM: How Real Teams Are Routing LLM Traffic in 2026
Model routing in 2026 is a cost lever and a security attack surface. Teams routing 70% to cheaper models cut per-million …
Judge Models in 2026: Atla Selene, Prometheus 2, and the Race to Replace Human Eval
Dedicated judge models like Atla Selene and Prometheus 2 grade LLM outputs at scale. In 2026, production teams pair them …
SWE-bench Pro, ARC-AGI-2, and Humanity's Last Exam: The Benchmarks Defining Frontier Models in 2026
OpenAI dropped SWE-bench Verified in February 2026 over contamination. SWE-bench Pro, ARC-AGI-2, and Humanity's Last …
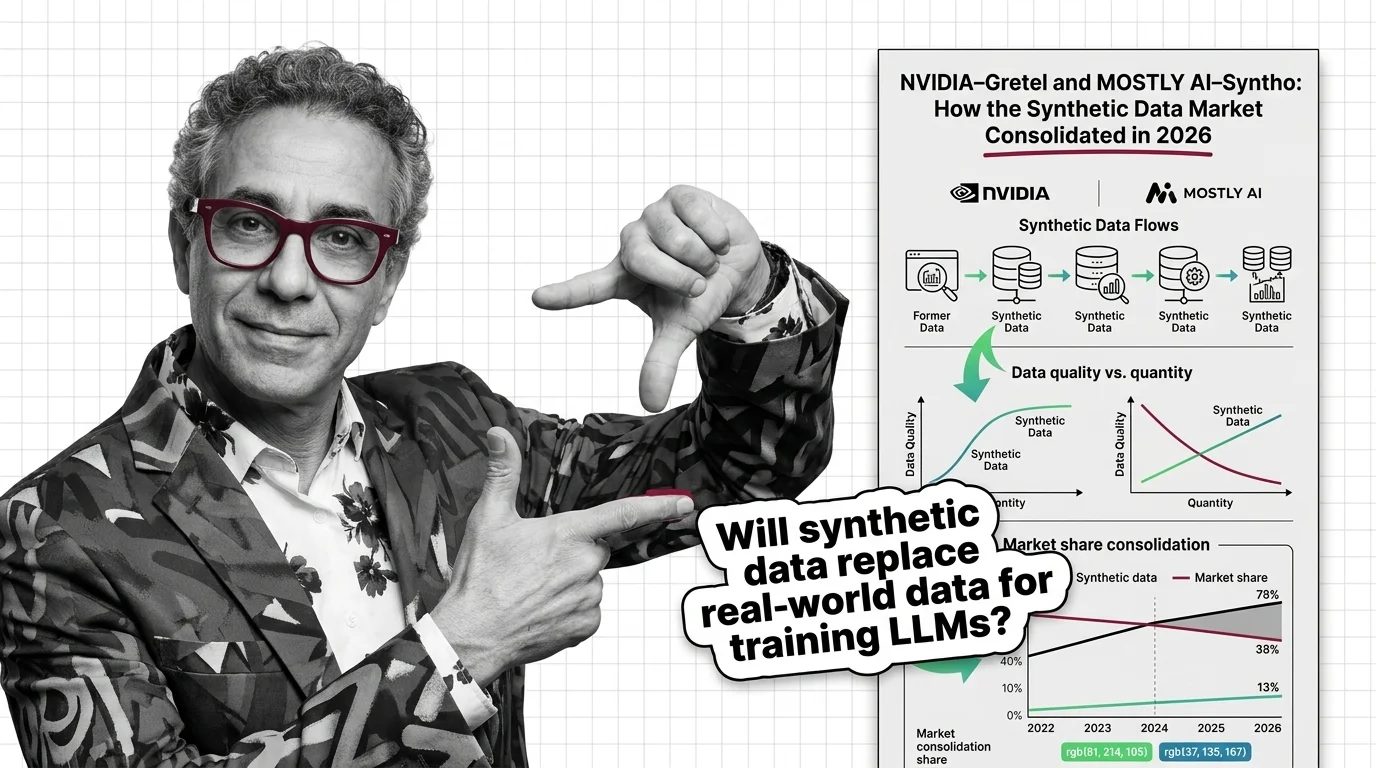
NVIDIA–Gretel and Syntho–MOSTLY AI: How the Synthetic Data Market Consolidated in 2026
NVIDIA reportedly bought Gretel in 2025; Syntho took the MOSTLY AI brand in 2026. Synthetic-data vendors are …
Active Learning in Practice: Real Annotation-Cost Savings and Where the Field Is Heading in 2026
Active learning cuts annotation cost 50%+ in biomedical imaging by choosing which examples humans label — and in 2026 it …
SlimPajama, SemDeDup, and the GPU Dedup Race: Real Results and Where It's Heading in 2026
Data deduplication moved to GPU-accelerated semantic curation in 2026. SlimPajama cut 49.6% of RedPajama; SemDeDup …
pandas vs Polars and the Rise of GPU Preprocessing: Where Data Prep Tooling Is Heading in 2026
Data-prep tooling consolidates on Apache Arrow in 2026: pandas 3.0, Polars, and RAPIDS cuDF interoperate zero-copy. …
From Back-Translation to LLM Synthetic Data: Where Data Augmentation Is Heading in 2026
Data augmentation is splitting in 2026: vision keeps mixup and CutMix, text shifts to LLM synthetic data. Model collapse …
From Scale AI's $15B Meta Deal to Programmatic Labeling: The Data Annotation Market in 2026
Meta's ~$14.3B stake in Scale AI split the data-labeling market: rivals like Surge, Mercor, and Snorkel absorbed the …
AI for Technical Debt in 2026: Agentic Refactoring and the AI-Generated-Debt Surge
AI now writes ~41% of new code as duplication climbs and refactoring collapses. Agentic tools like CodeScene ACE and …
AI Technical Debt Tools in Action: CodeScene, CodeAnt, and Real Refactoring Wins
CodeScene ranks refactoring hotspots by pairing code health with change frequency. AI edits to low-health code carry a …
Data-Centric AI in Practice: How Teams Boosted Models by Fixing Data, Not Models, in 2026
Data-centric AI is outpacing model scaling in 2026. A controlled study lifted accuracy 3-7 points by fixing labels and …
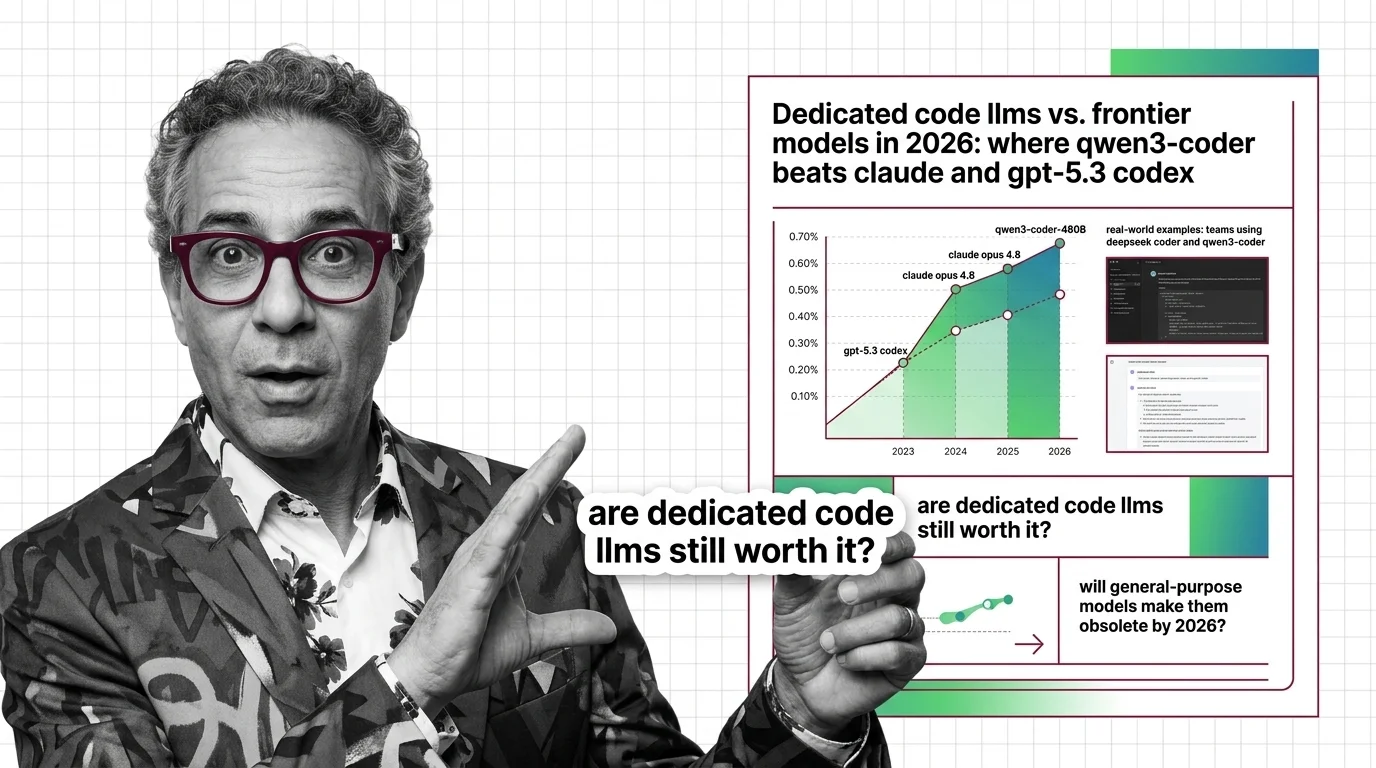
Dedicated Code LLMs vs. Frontier Models in 2026: Where Qwen3-Coder Beats Claude and GPT-5.3 Codex
Claude Opus 4.8 tops SWE-bench Verified at 88.6%, but Qwen3-Coder wins on cost and open weights. The 2026 code-LLM …
GitLab Duo, GitHub Agentic Workflows, and the Self-Healing Pipeline Race in 2026
GitLab Duo, GitHub Agentic Workflows, and CircleCI now ship agents that read failing pipelines and open fix PRs without …
Claude Opus 4.7 Hits 87.6% on SWE-bench: Inside the 2026 Coding Agent Race
Claude Opus 4.7 hit 87.6% on SWE-bench Verified in April 2026; Cognition raised $1B at a $25B valuation. The coding …