Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
Agent State Management: Threads, Checkpointers, Hard Limits
Agent state is not memory — it is plumbing that replays snapshots between steps. Mona explains threads, checkpointers, …
Agent Evaluation Prerequisites: LLM-as-Judge to Cost-Per-Task
Agent evaluation needs three signals: outcome, trajectory, cost. Learn why LLM-as-judge has known biases and where major …
Agent Evaluation: How Trajectory Analysis Measures AI Agents
Agent evaluation grades the path, not just the final answer. Learn how trajectory analysis exposes silent reasoning …
From Chain-of-Thought to Tool Use: Prerequisites and Technical Limits of Agent Planning
Agent planning rests on three primitives — chain-of-thought, tool use, and the ReAct loop. Learn the prerequisites and …
Multi-Agent Systems: Prerequisites and Hard Technical Limits
Before multi-agent systems, master tool use, the ReAct loop, and memory. Then face the limits: context blow-up, error …
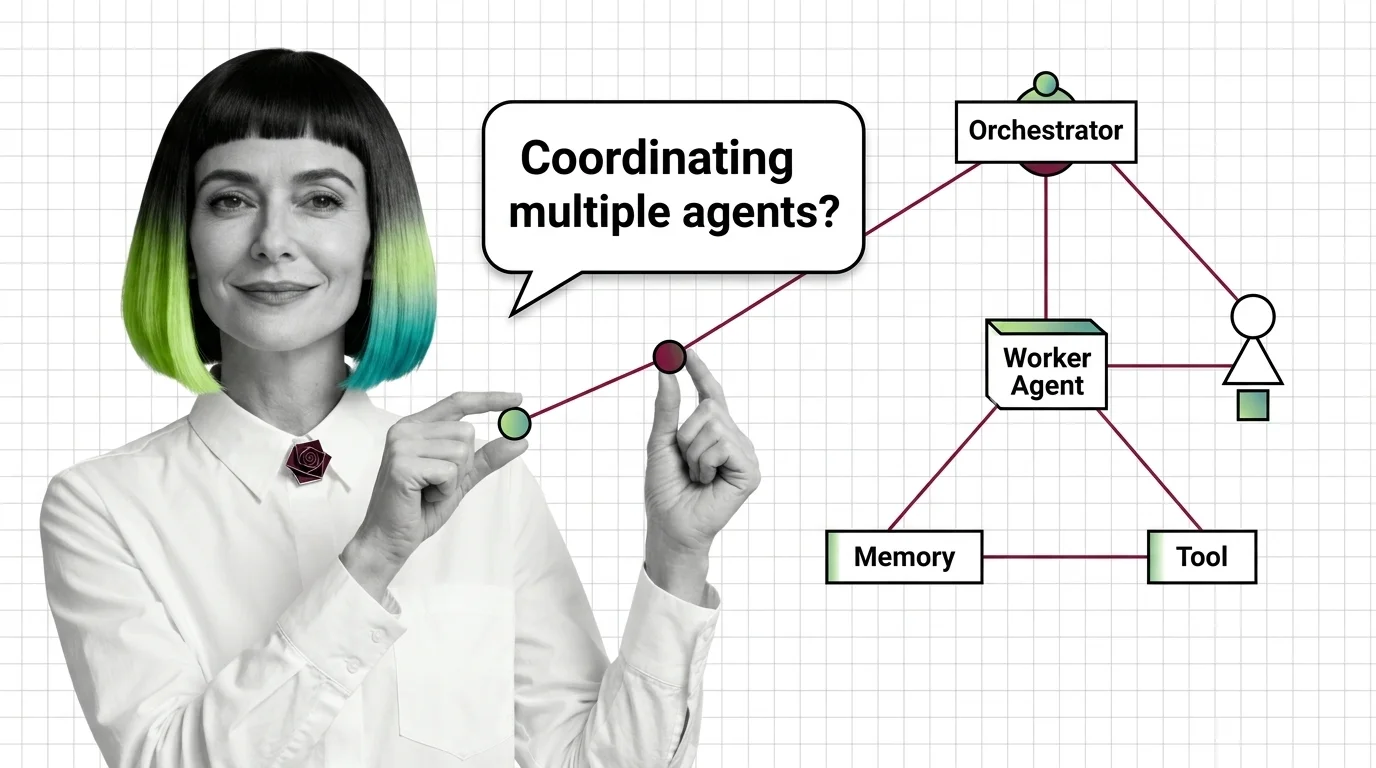
Multi-Agent Systems: Supervisor, Debate, and Swarm Patterns
Multi-agent systems coordinate specialized AI agents through supervisor, debate, or swarm patterns. Here is how each …
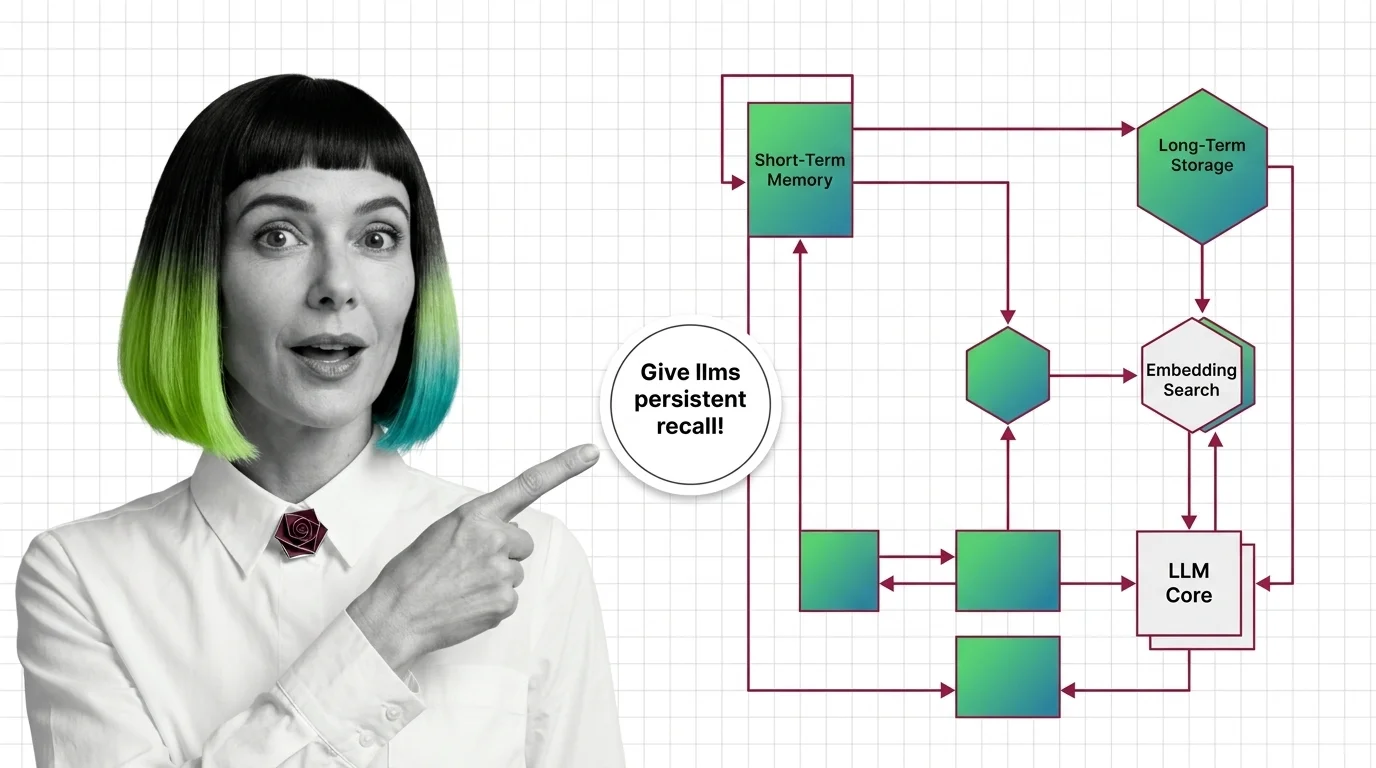
Agent Memory Systems: How LLMs Get Persistent Recall Across Sessions
Agent memory systems give LLMs persistent recall across sessions. Inside the architectures: temporal graphs, …
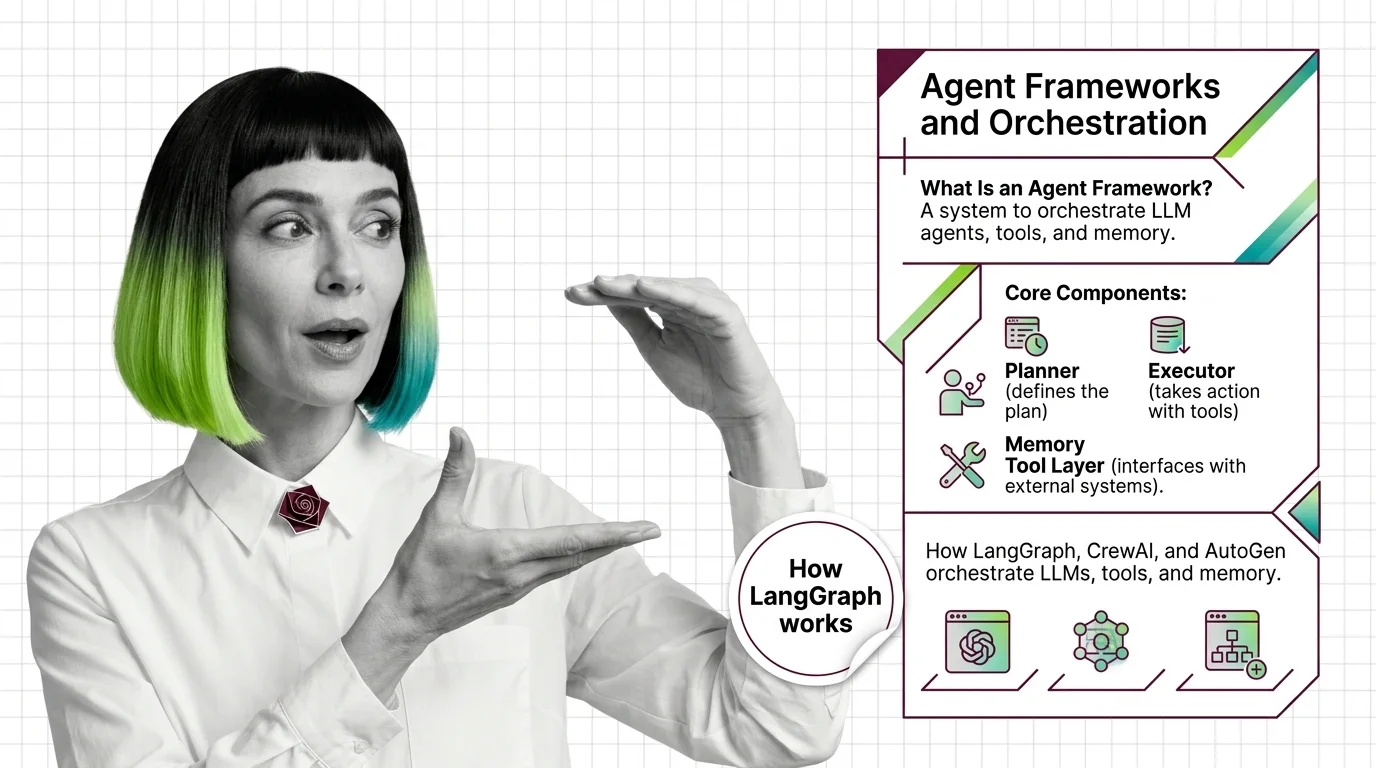
Agent Frameworks: How LangGraph, CrewAI, and AutoGen Orchestrate LLMs
Agent frameworks orchestrate LLM calls, tools, and memory — but each one bets on a different abstraction. Learn what …
Agent Memory Architectures: Prerequisites and Hard Limits
Agent memory isn't a bigger context window. Learn the prerequisites for designing agent memory systems and the hard …
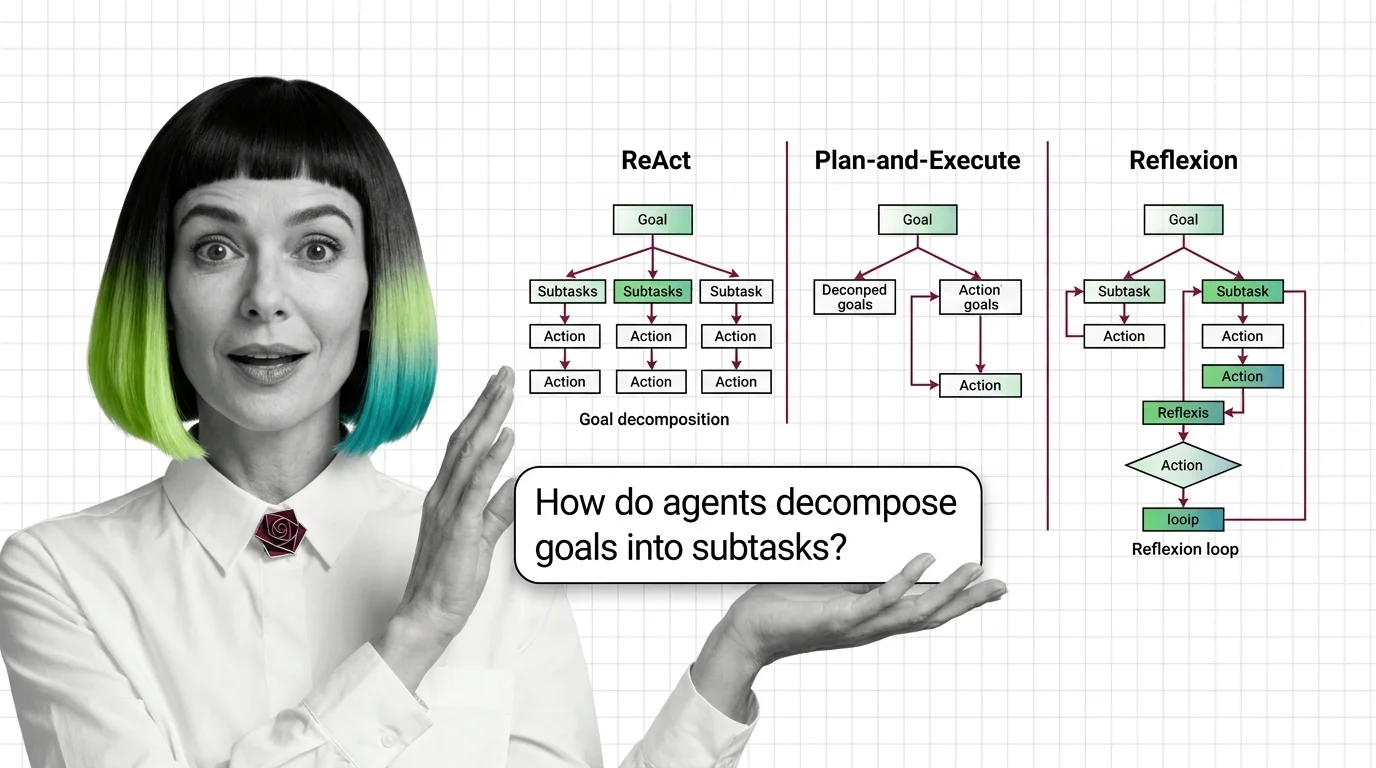
Agent Planning and Reasoning: ReAct, Plan-and-Execute, Reflexion
Agent planning is not human cognition — it is token generation conditioned on observations. How ReAct, Plan-and-Execute, …
Graph vs Conversation vs Crew: LangGraph, AutoGen, CrewAI Patterns
LangGraph, AutoGen, and CrewAI commit to three different theories of how AI agents coordinate. The pattern you pick …
What Is Multimodal RAG and How It Retrieves Across Images, Tables, and Text
Multimodal RAG isn't text RAG with images bolted on. Learn how unified embeddings, text summaries, and vision-first …
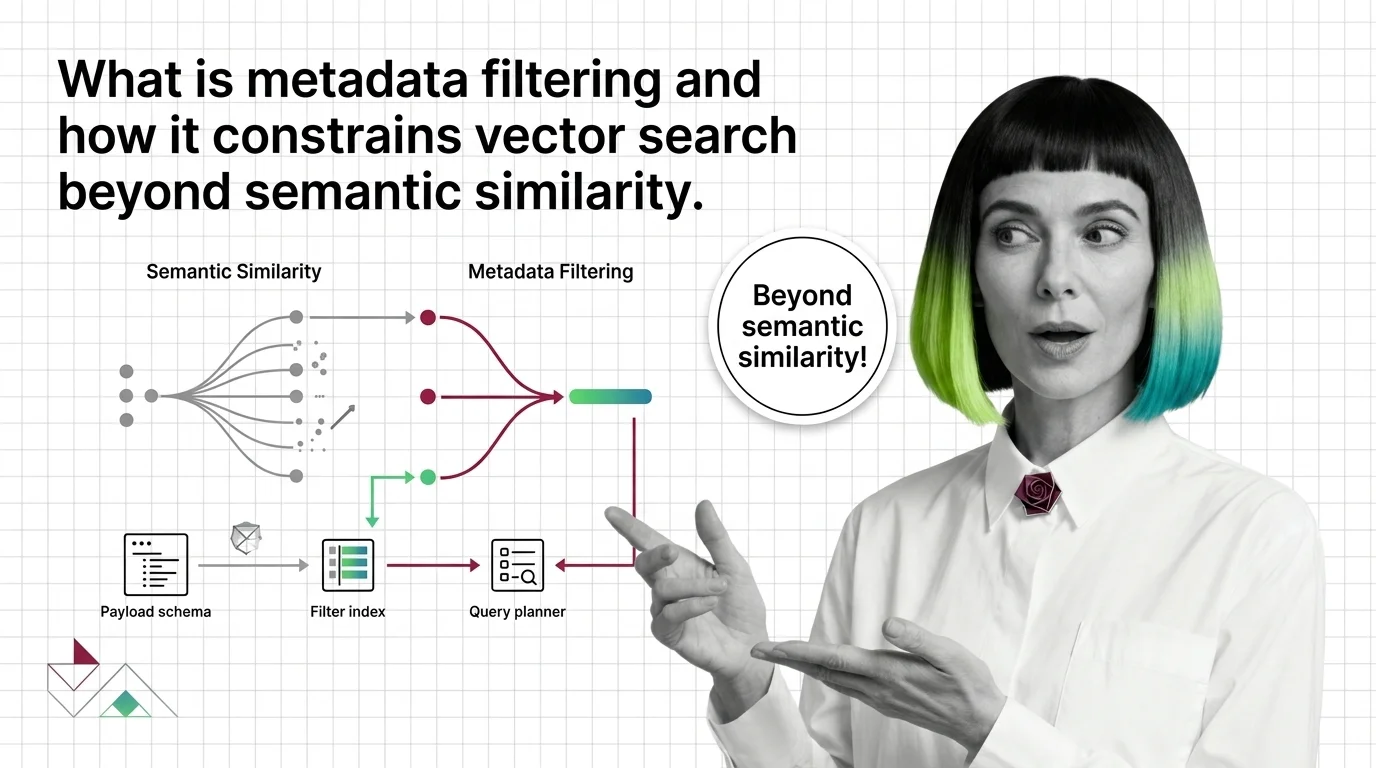
What Is Metadata Filtering and How It Constrains Vector Search Beyond Semantic Similarity
Metadata filtering attaches typed key-value payloads to each vector and applies predicates during search, narrowing …
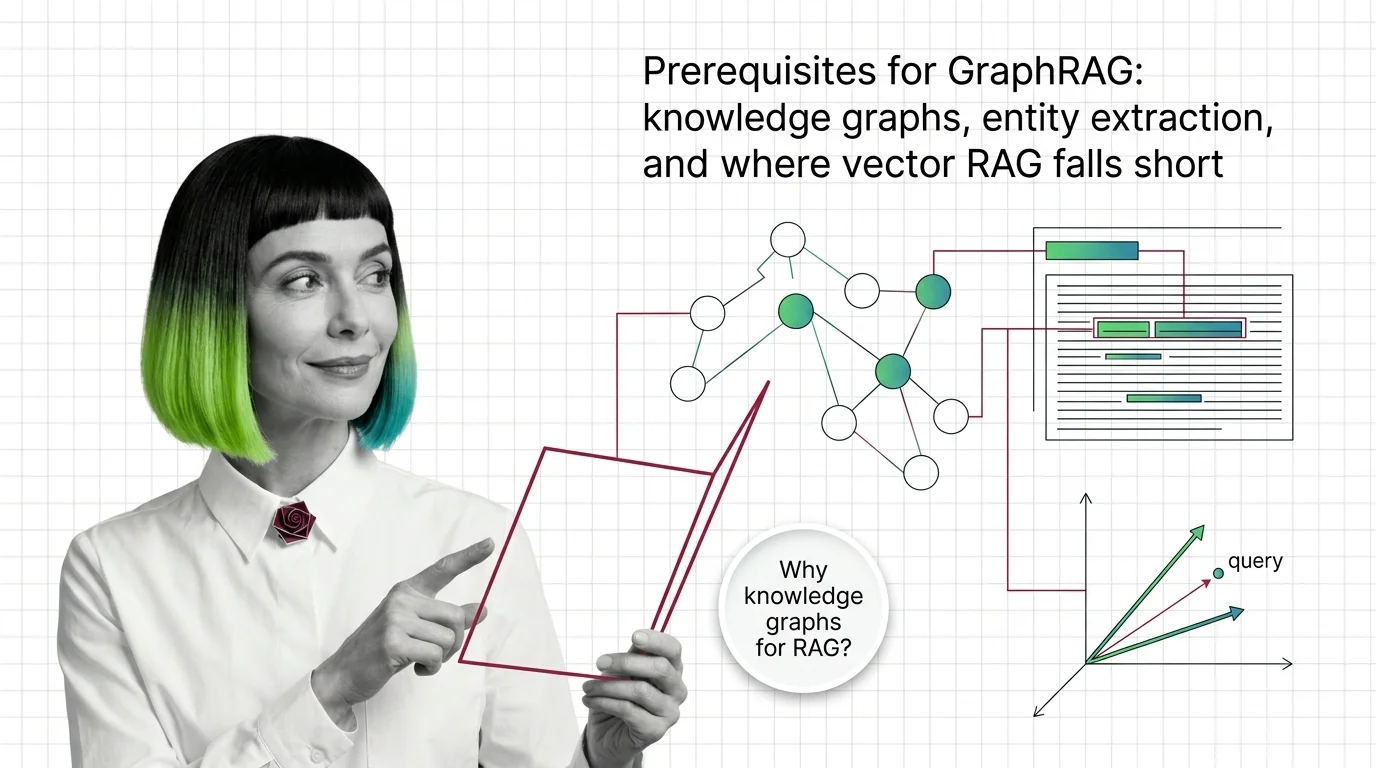
GraphRAG Prerequisites: Knowledge Graphs and Where Vector RAG Falls Short
GraphRAG inherits chunking, embeddings, and entity extraction from vector RAG. Learn what you need first and where the …
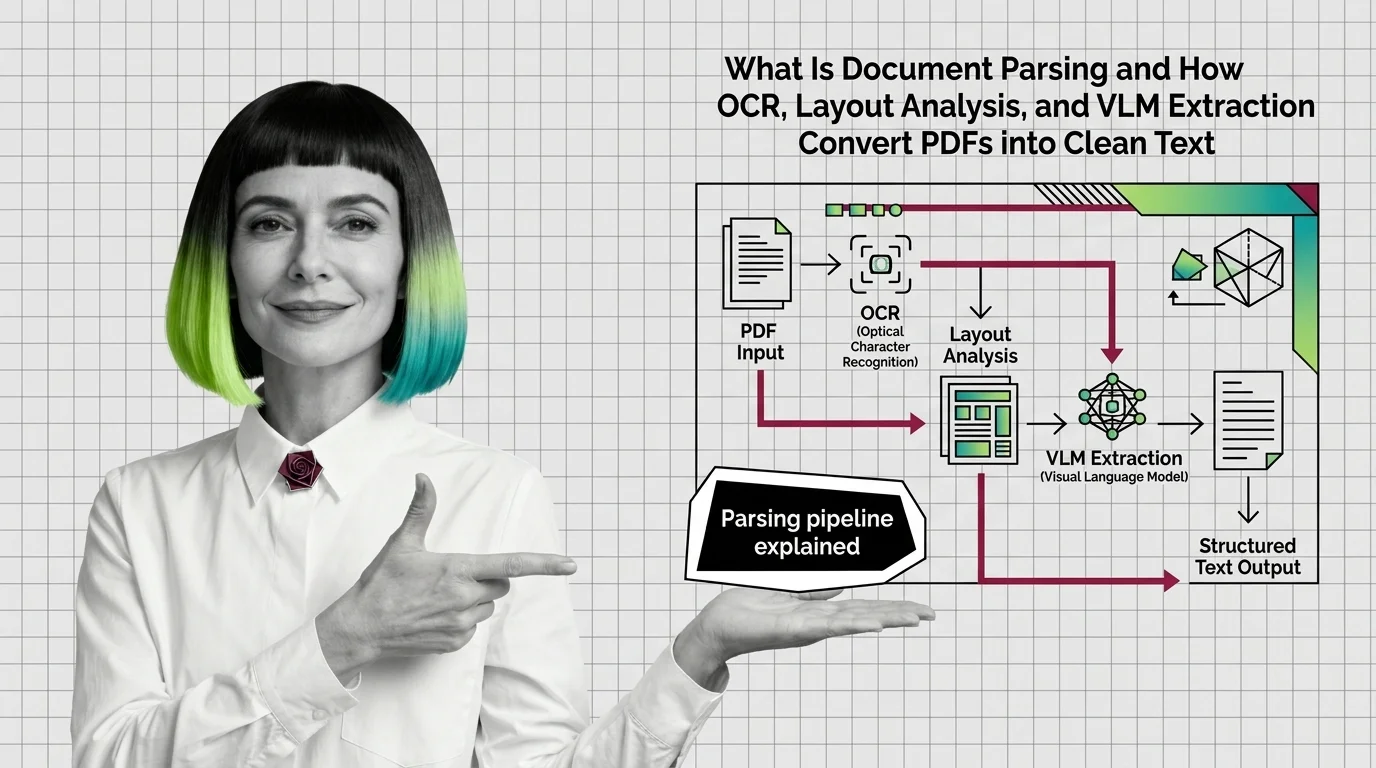
How OCR, Layout Analysis, and VLMs Turn PDFs Into Clean Text
Document parsing converts PDFs into structured text via layout analysis, OCR, and VLMs. Here is how each component works …
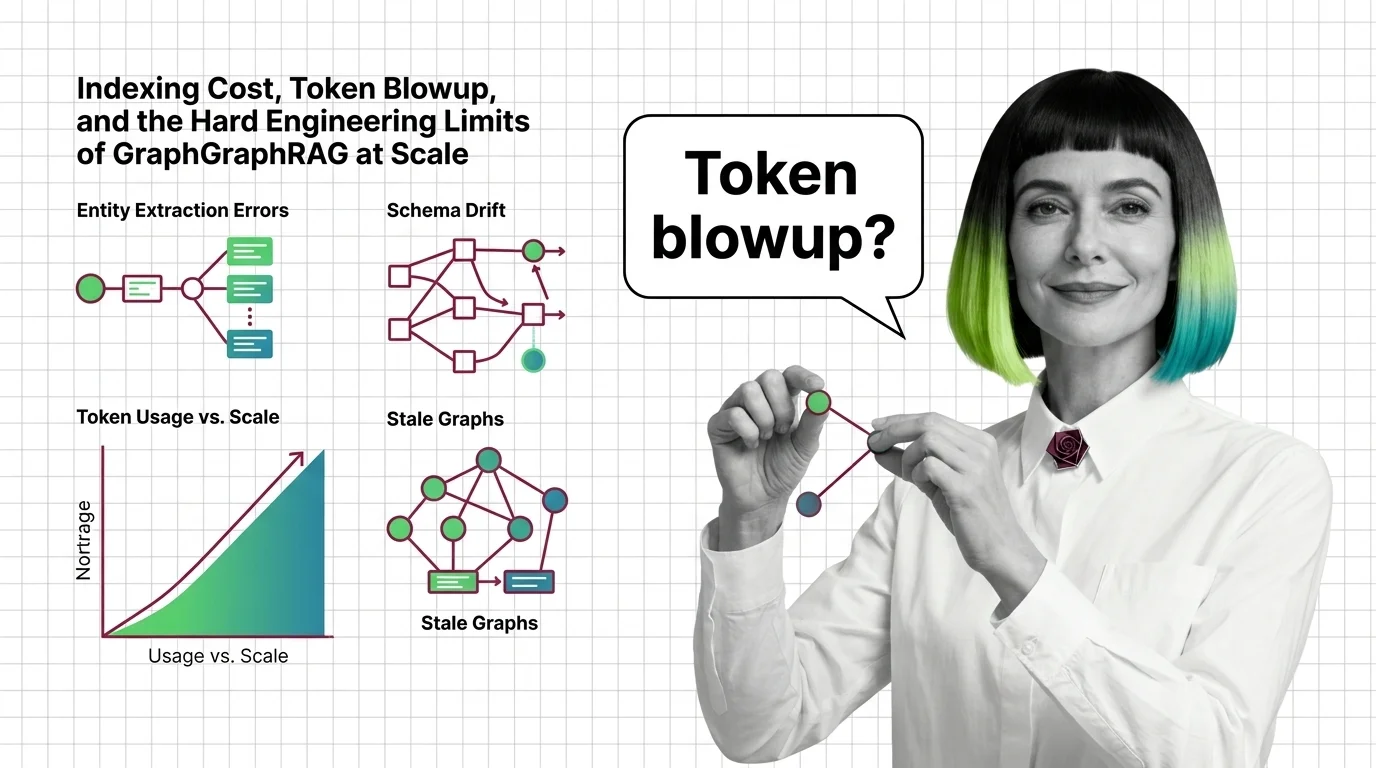
Indexing Cost, Token Blowup, and the Hard Engineering Limits of GraphRAG at Scale
GraphRAG indexing costs scale with token recursion, not document size. A breakdown of the cost cliff, hallucinated …
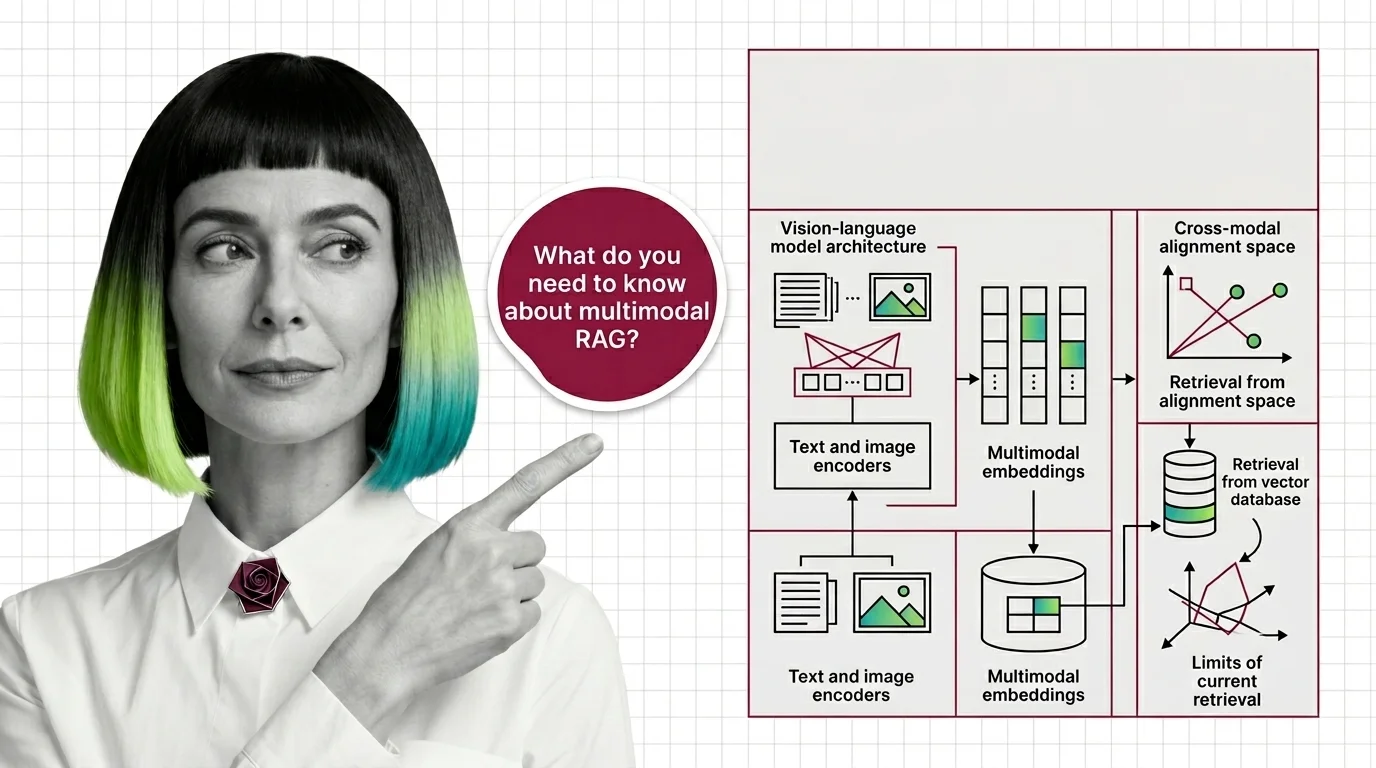
Multimodal RAG Prerequisites: Vision-Language Models, Cross-Modal Alignment
Before multimodal RAG works, you need vision-language models, shared embeddings, and a theory of cross-modal retrieval. …
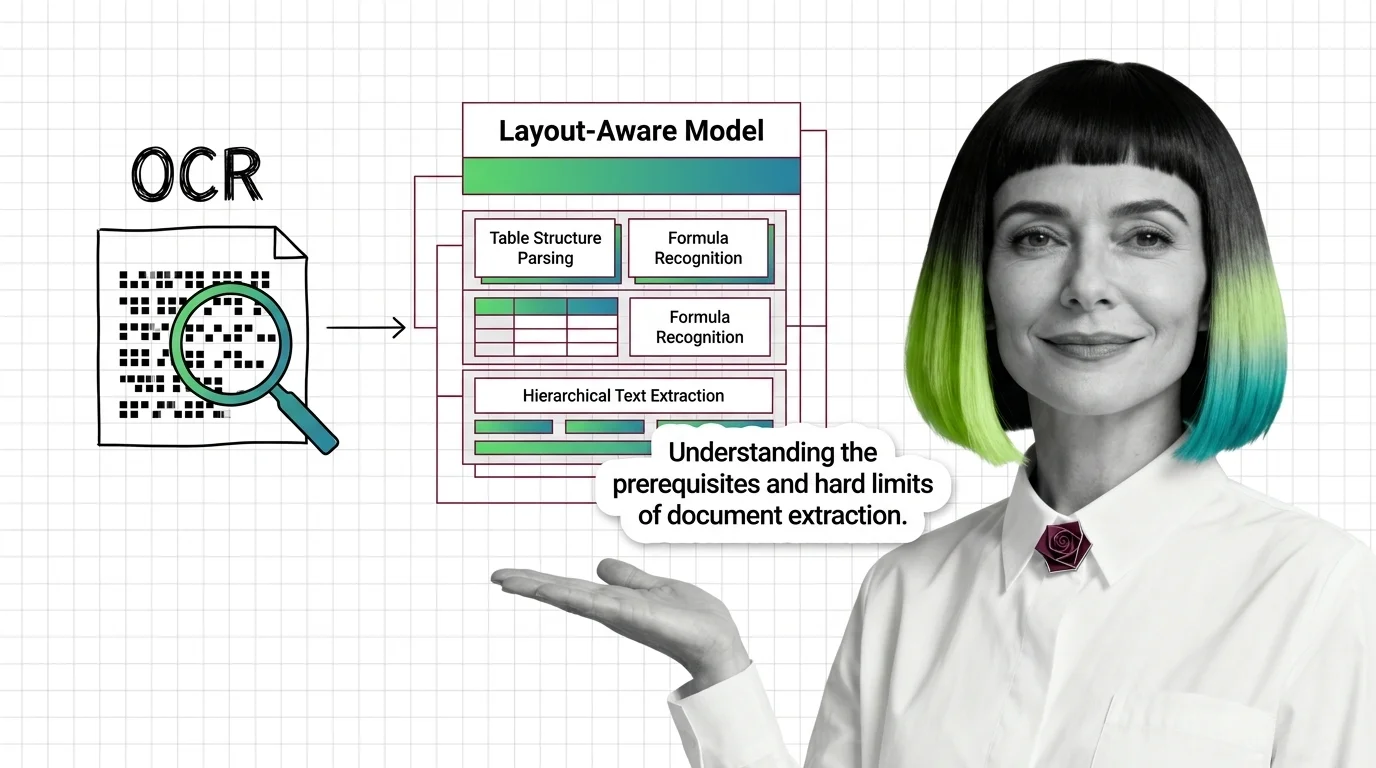
OCR to Layout-Aware Models: Prerequisites and Hard Limits
Document parsing breaks in predictable ways. Learn the prerequisites for understanding OCR and layout-aware models, and …
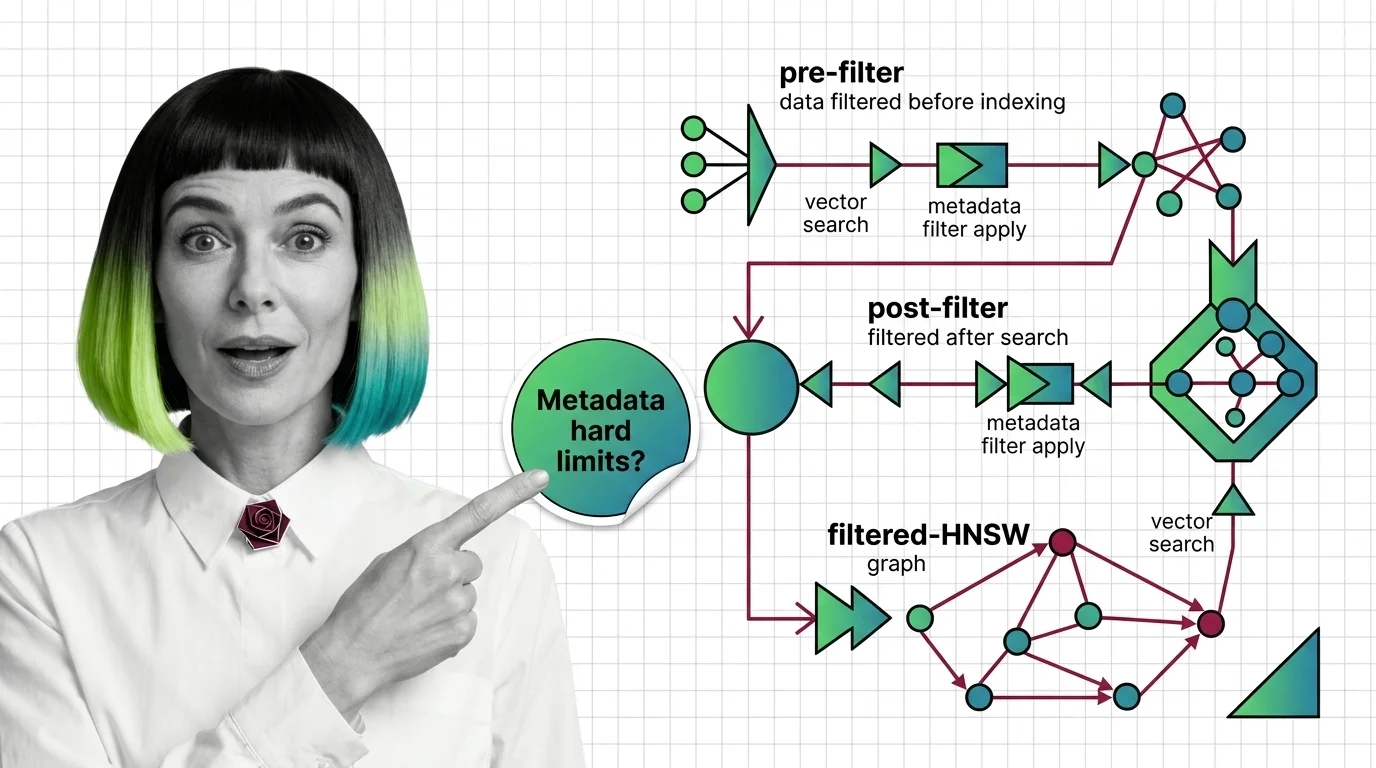
Pre-Filter vs Post-Filter vs Filtered-HNSW: Metadata Filtering at Scale
Why metadata filtering breaks vector search at scale — the HNSW prerequisites, payload indexing, and Boolean predicates …
What Is GraphRAG? Multi-Hop Reasoning with Knowledge Graphs
GraphRAG turns documents into a knowledge graph and uses community summaries to answer multi-hop questions vector …
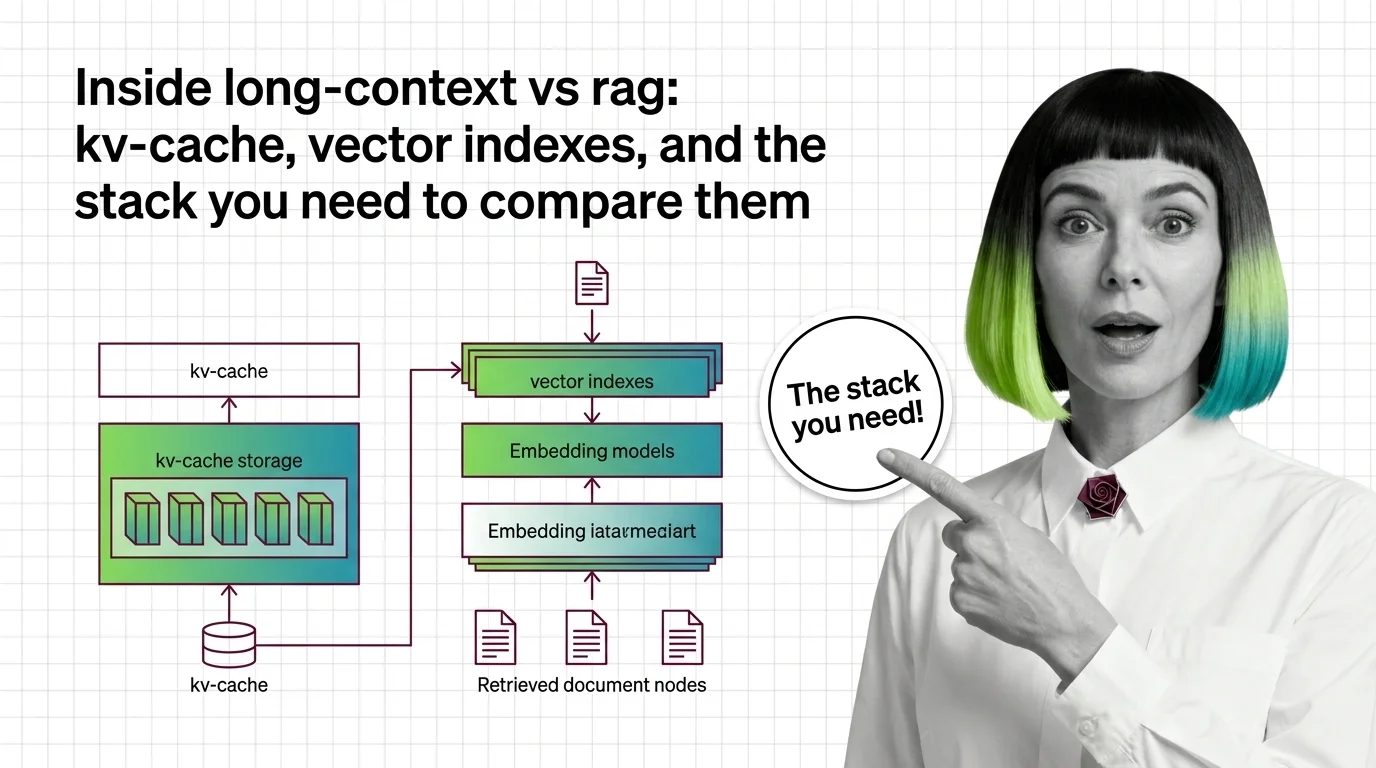
Inside Long-Context vs RAG: KV-Cache, Vector Indexes, and the Stack You Need to Compare Them
Long-context models and RAG pipelines compete for the same job with different parts. A component-by-component map of KV …
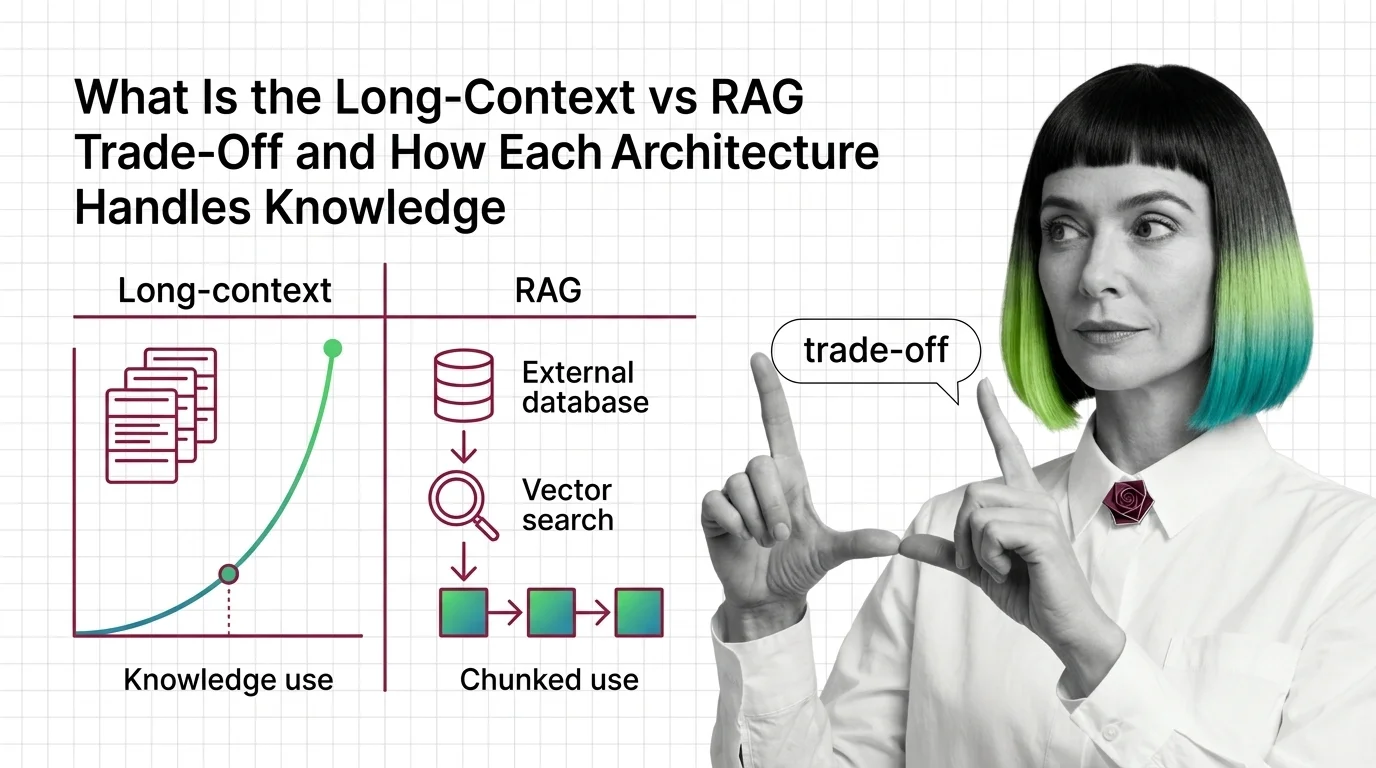
Long-Context vs RAG: How Each Handles Knowledge in 2026
Long-context and RAG sound interchangeable. They are not. The mechanics, failure modes, and cost curves diverge — see …
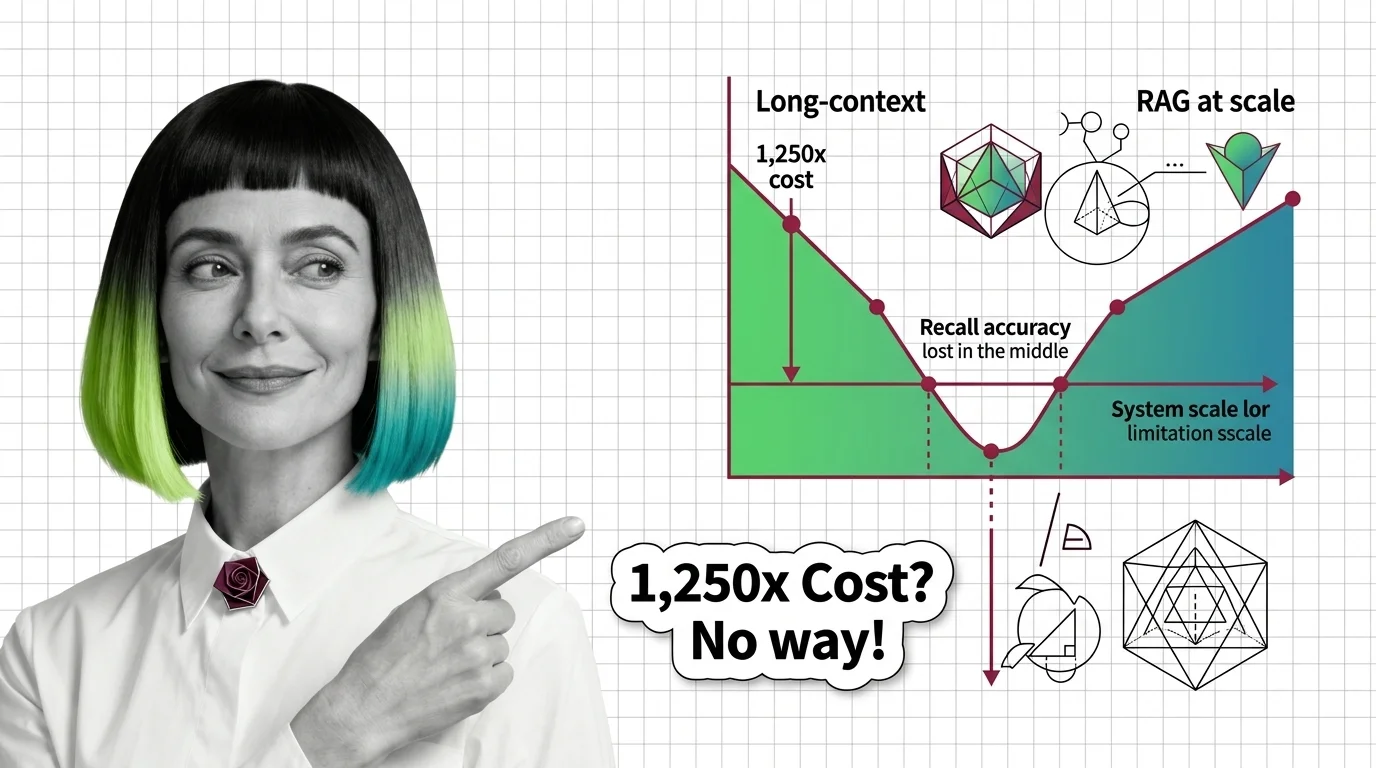
Lost in the Middle, 1,250x Cost: The Limits of Long-Context vs RAG
Long-context windows promise simplicity, but lost-in-the-middle, 1,250x cost gaps, and effective-context collapse at 32K …
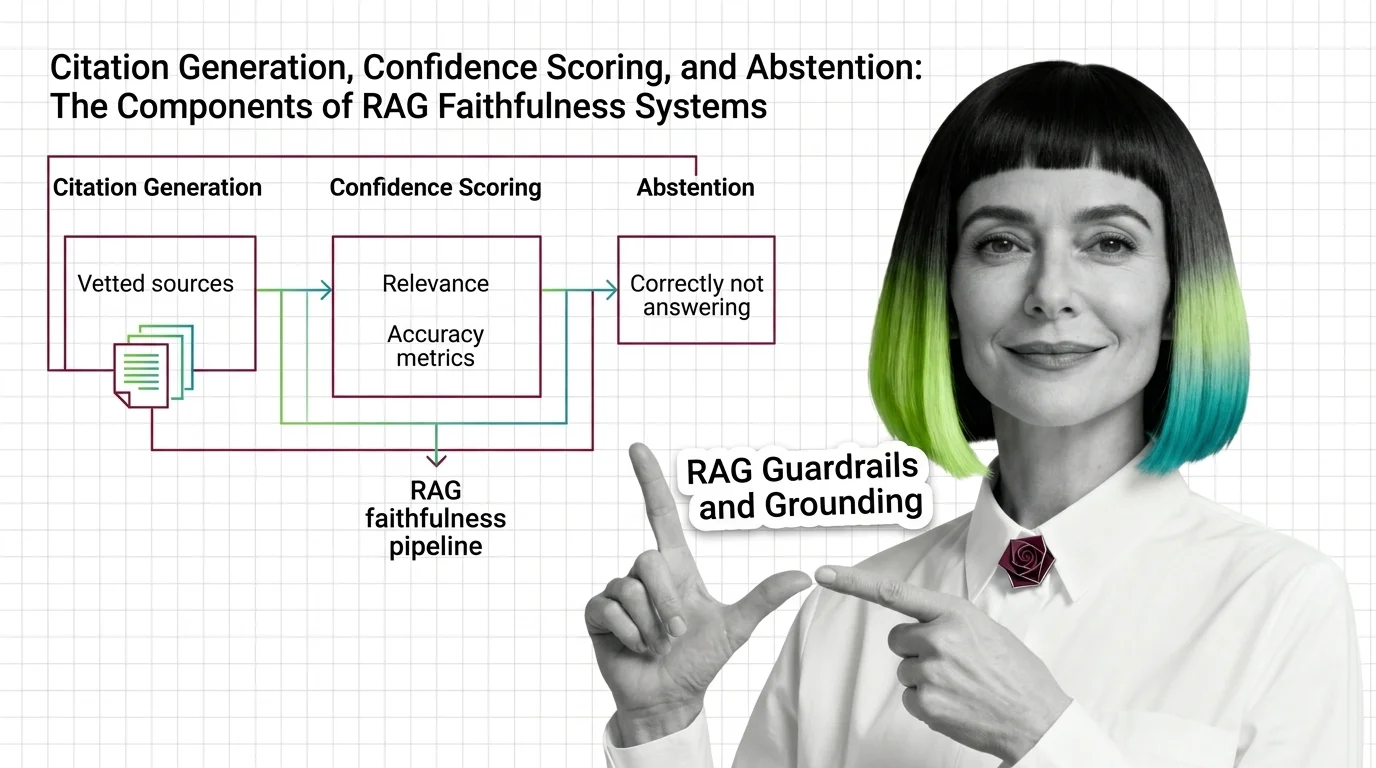
Citation, Confidence, and Abstention: The 3 Layers of RAG Faithfulness
RAG grounding splits into three layers: citation generation, confidence scoring, and abstention. See how each fails …
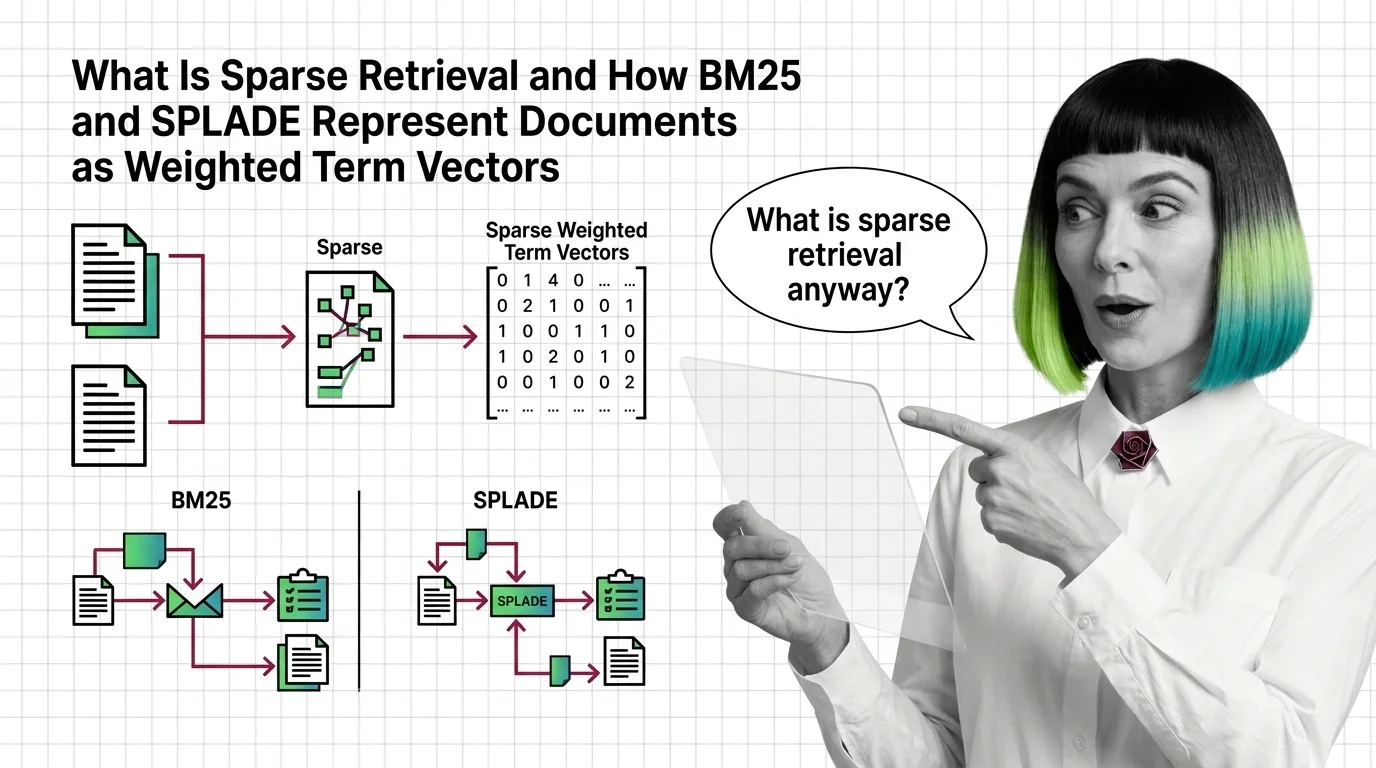
What Is Sparse Retrieval and How BM25 and SPLADE Represent Documents as Weighted Term Vectors
Sparse retrieval encodes documents as weighted term vectors. Here is how BM25 and SPLADE produce those weights and why …
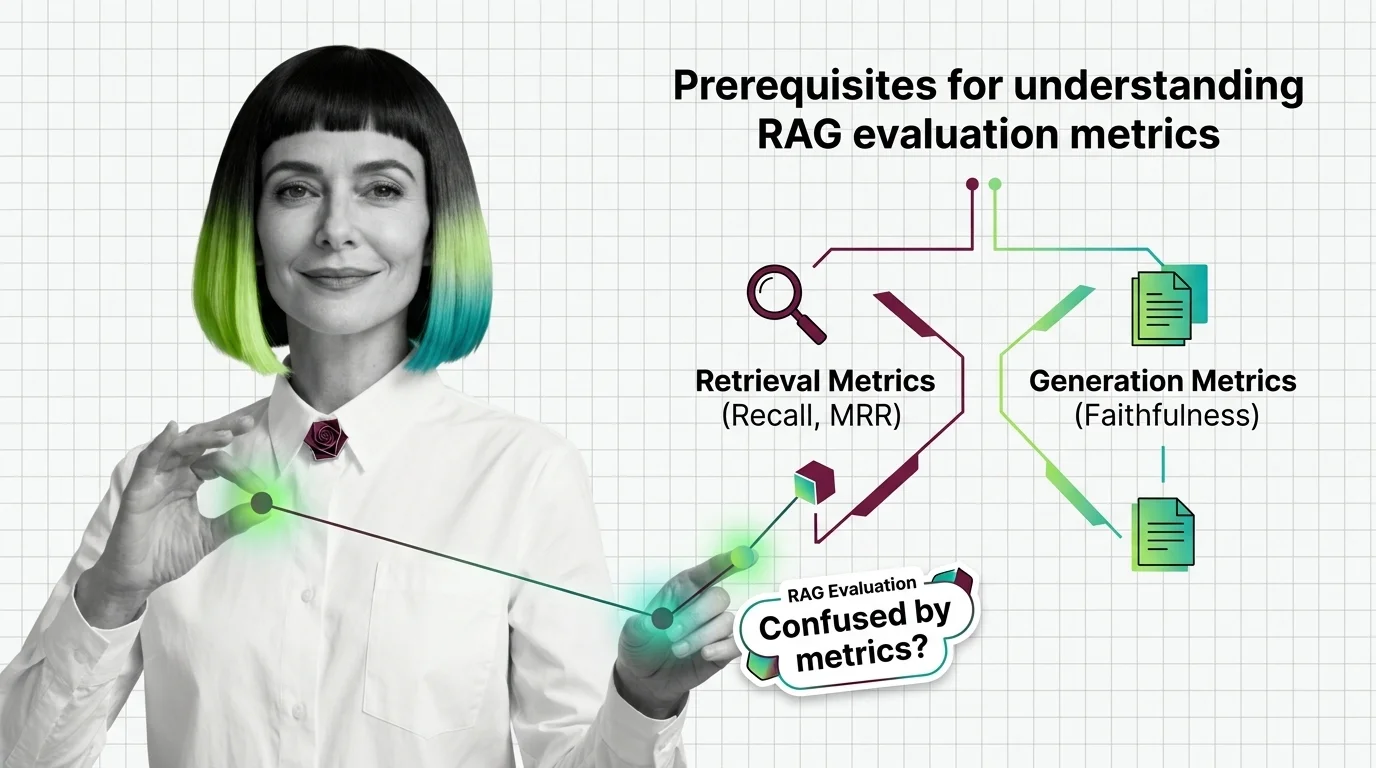
From Recall and MRR to Faithfulness: RAG Evaluation Prerequisites
RAG evaluation needs more than one accuracy score. Learn the IR and generation metrics — Recall, MRR, Faithfulness, …
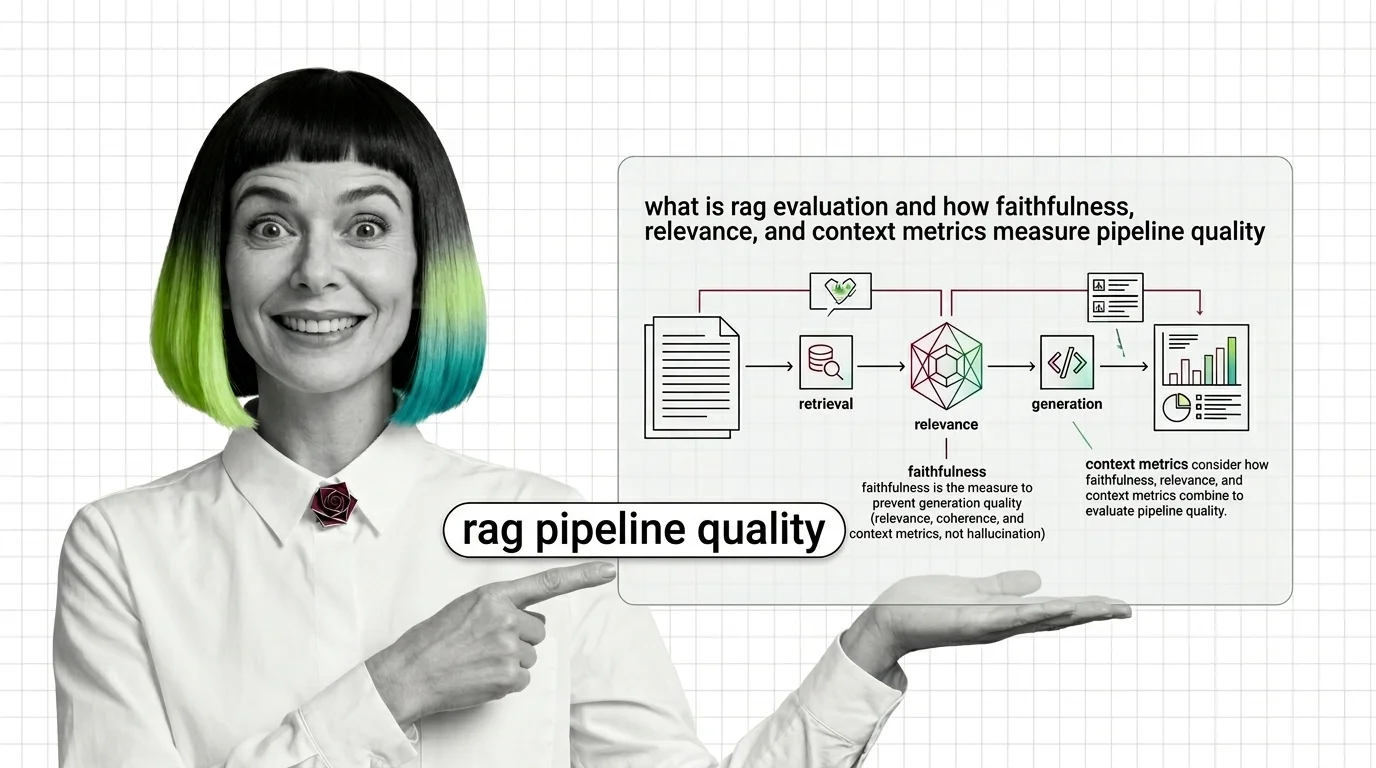
RAG Evaluation Explained: Faithfulness, Relevance, Context Metrics
RAG evaluation splits your pipeline into retriever and generator and scores each. Learn how Faithfulness, Relevance, and …
From TF-IDF to Learned Sparse: Prerequisites and Hard Limits of BM25, SPLADE, and ELSER
Sparse retrieval starts with BM25 and ends with ELSER and SPLADE-v3. Learn the math, the prerequisites, and where each …
LLM-as-Judge Bias and the Technical Limits of RAG Evaluation
RAG evaluation frameworks like RAGAS rely on LLM judges with documented biases. Why faithfulness and answer relevancy …
Prerequisites for RAG Grounding: Retrieval Quality, the RAG Triad, and Faithfulness Metrics
Before you bolt guardrails onto a RAG pipeline, learn the RAG Triad — context relevance, groundedness, answer relevance …