Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
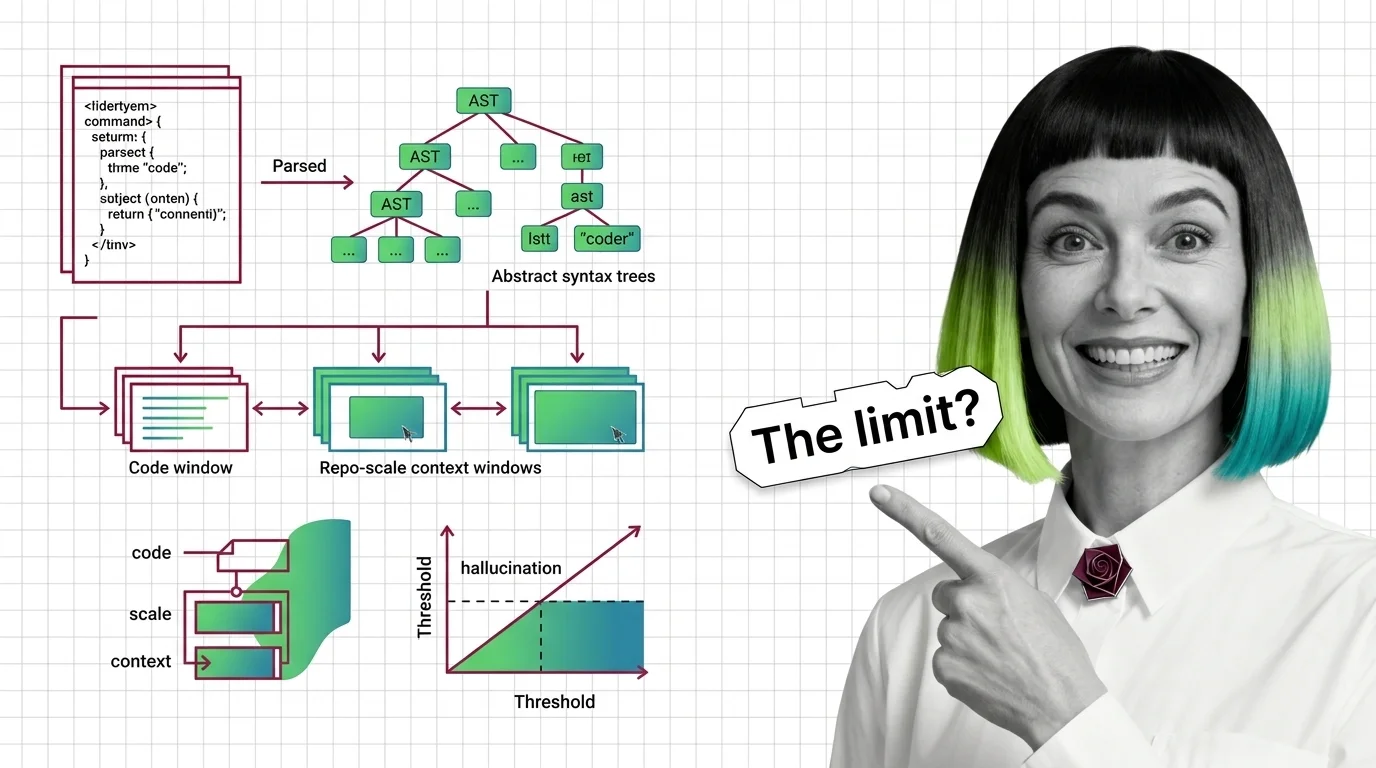
Prerequisites for AI Documentation Generation: From AST Parsing to Repo-Scale Context Windows and Hallucination Limits
AI documentation generators don't read code — they parse ASTs, embed chunks, and retrieve context. Open-source models …
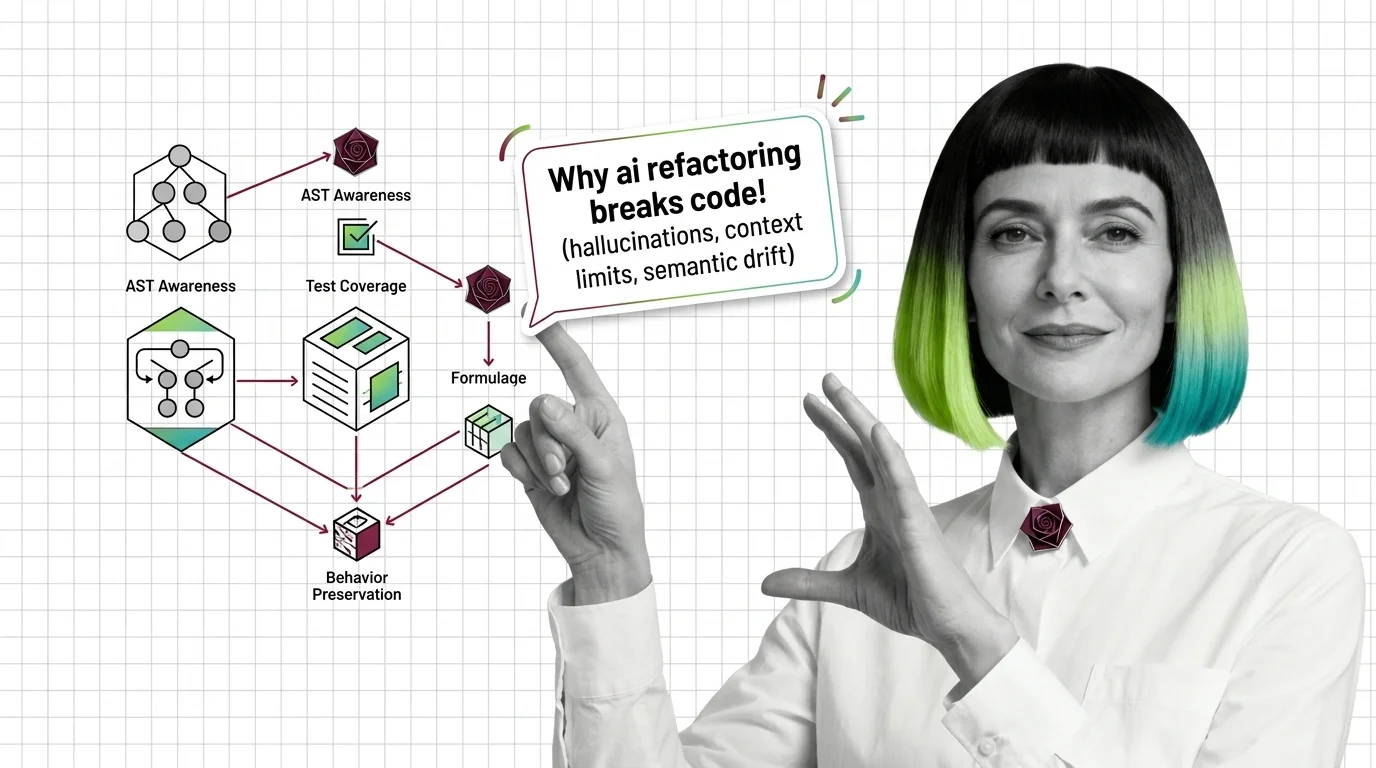
Prerequisites for AI-Assisted Refactoring: From AST Awareness to Test Coverage and Behavior Preservation
AI-assisted refactoring needs four prerequisites: behavior preservation, AST awareness, test coverage, and mitigation of …
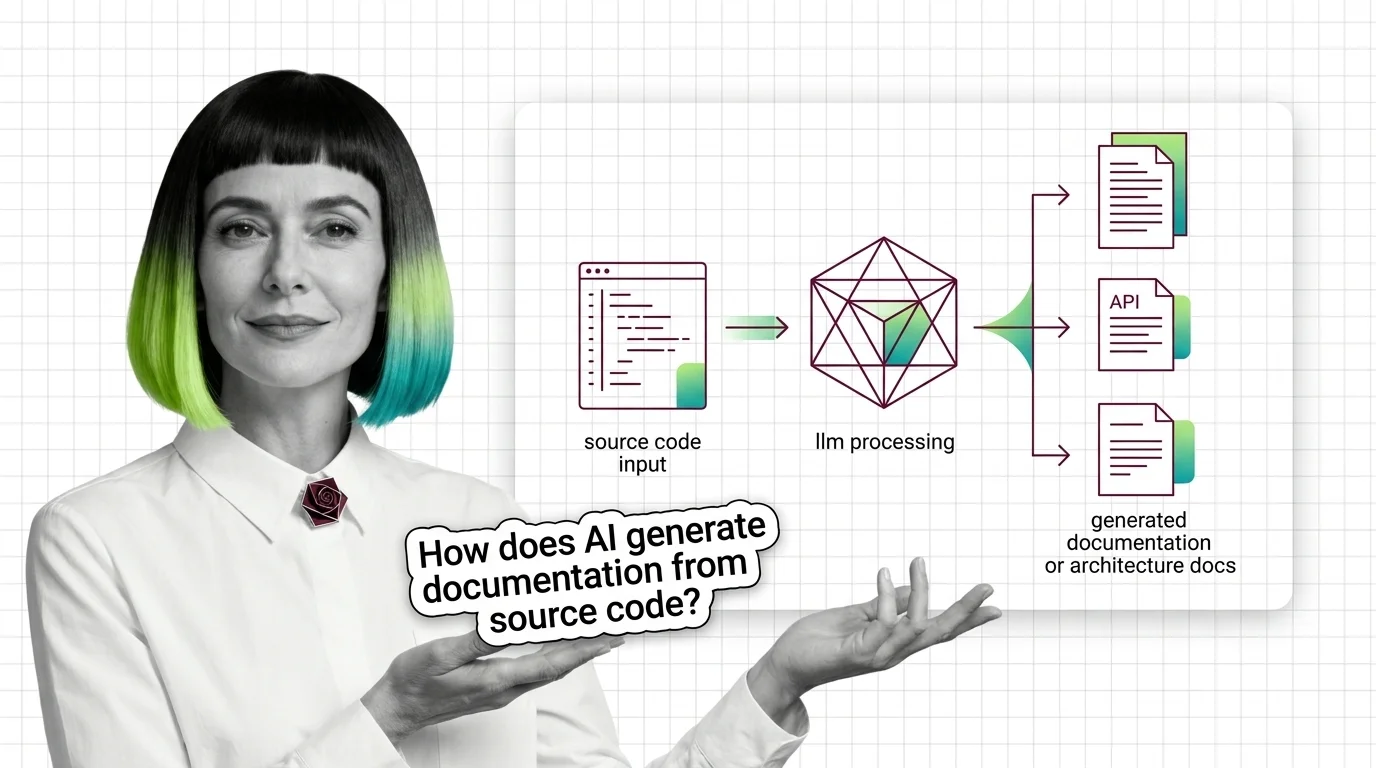
What Is AI Documentation Generation? How LLMs Turn Code Into Docstrings and Architecture Docs
AI documentation generation uses LLMs to produce docstrings, API references, and architecture docs by traversing code …
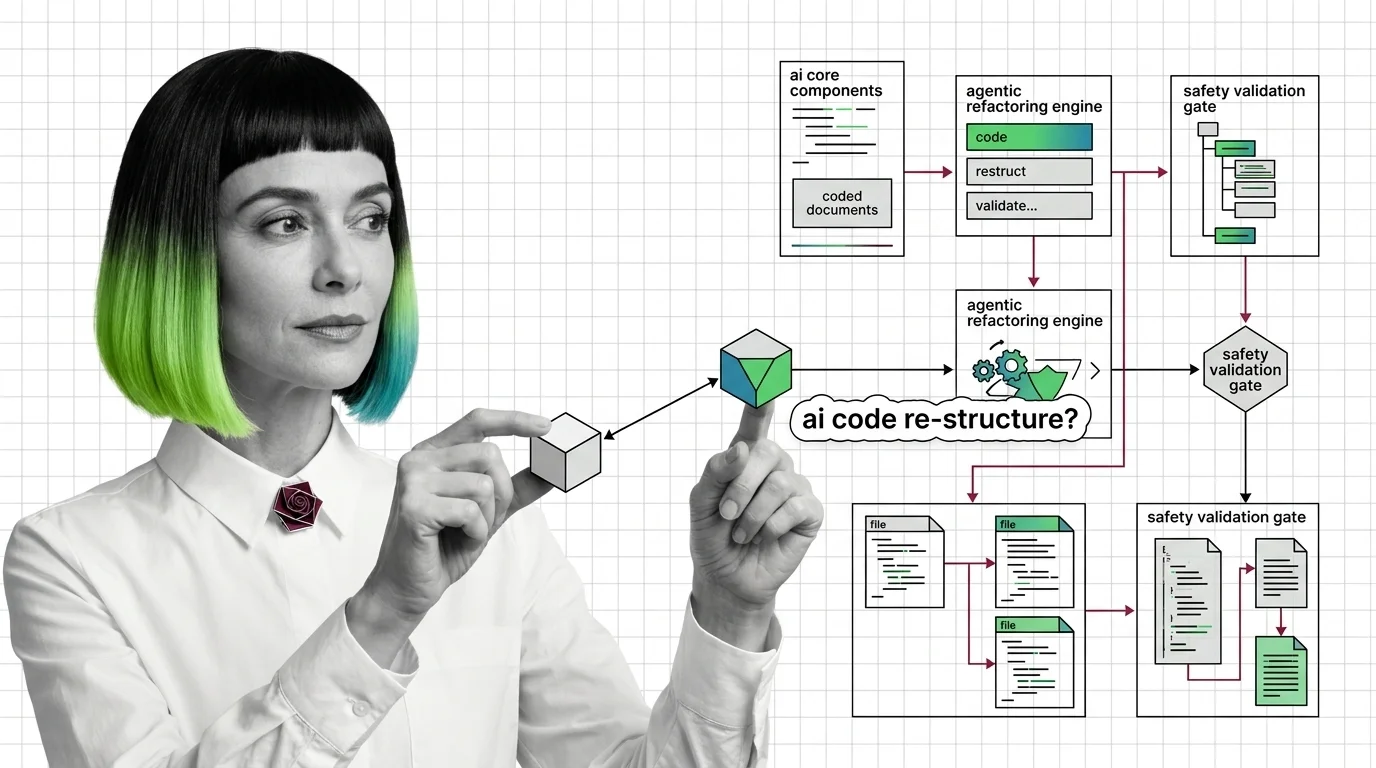
What Is AI-Assisted Refactoring and How Agentic Tools Restructure Code Without Breaking It
AI-assisted refactoring parses code into a syntax tree, plans behavior-preserving edits, and verifies them with tests — …
Prerequisites for AI-Assisted Debugging: Stack Traces, Context Windows, and Why Models Still Hallucinate Fixes
AI debuggers sample probable fixes from a finite context window. Even top 2026 models invent plausible symbols, the …
From Coverage Metrics to Mutation Testing: What You Need to Know Before Using AI Test Generators
Coverage measures whether tests run code. Mutation testing measures whether assertions catch bugs. AI test generators …
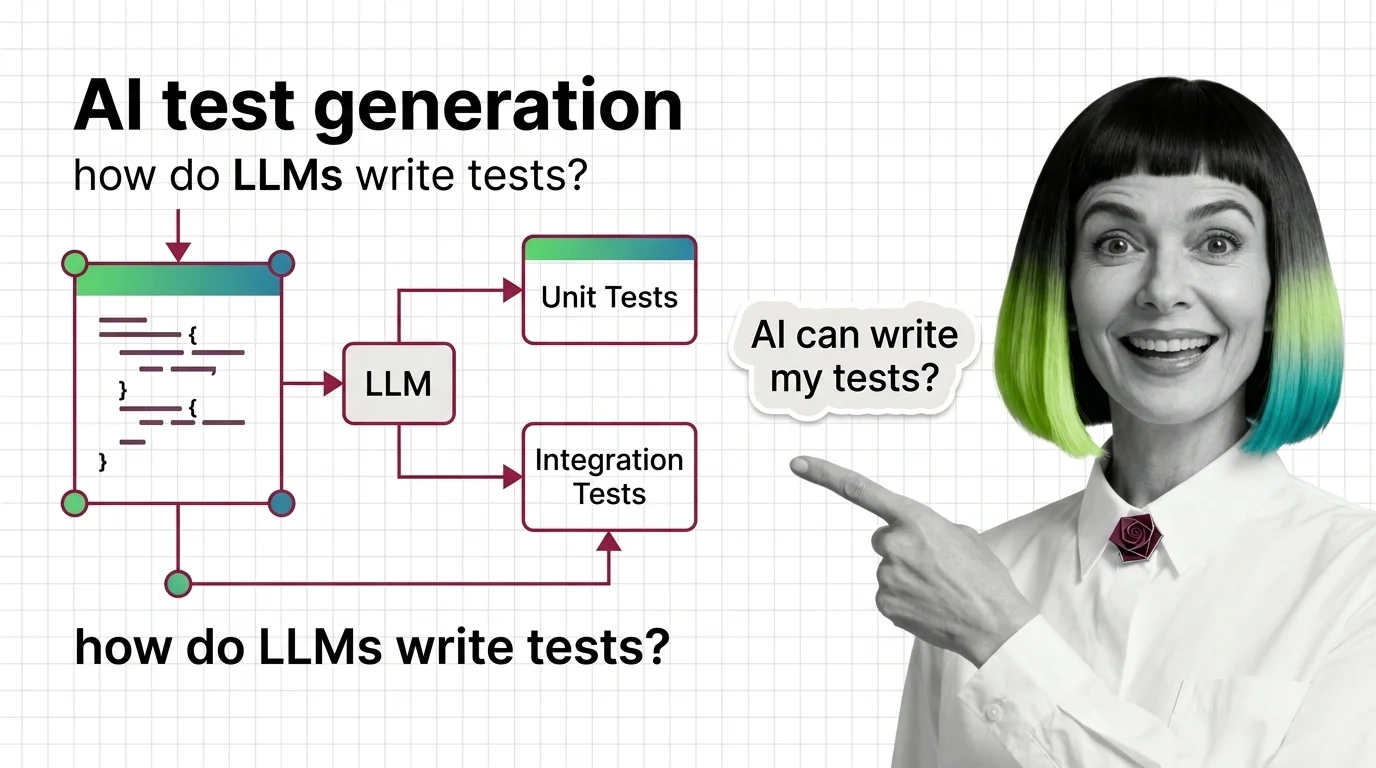
What Is AI Test Generation and How LLMs Write Unit and Integration Tests from Code
AI test generation uses LLMs to write unit tests from source code. A two-phase pipeline produces candidates, then …
What Is AI-Assisted Debugging and How LLMs Analyze Stack Traces to Find Bugs
AI-assisted debugging uses LLMs to parse stack traces, generate fix hypotheses, and validate them against runtime …
What Is AI Code Review and How LLM-Powered PR Reviewers Catch Bugs Before Humans
AI code review uses LLM agents to inspect pull requests for bugs, security flaws, and architectural drift before human …
From Context Windows to Speculative Decoding: Prerequisites and Technical Limits of Inline Code Completion
Inline AI code completion rests on four prerequisites: tokenization, context windows, FIM, and speculative decoding. …
Prerequisites for AI Code Review: RAG, Static Analysis, and the Hard Limits of LLM Bug Detection
AI code review combines retrieval-augmented context, static analysis, and LLM triage. Without grounding, models …
What Is AI Code Completion and How LLM-Powered Inline Suggestions Predict the Next Token
AI code completion uses Fill-in-the-Middle prompting on small, latency-optimized LLMs that score tokens against code …
What Is a Computer Use Agent? How AI Sees and Clicks Through Your Browser
A computer use agent is an AI model that uses a browser or desktop like a person. See how it sees a page, why it is …
From RAG to Agentic RAG: Prerequisites and Technical Limits of Retrieval-Augmented Agents
Retrieval-augmented agents wrap RAG primitives as tools inside a reasoning loop. Latency stacks, cost climbs, …
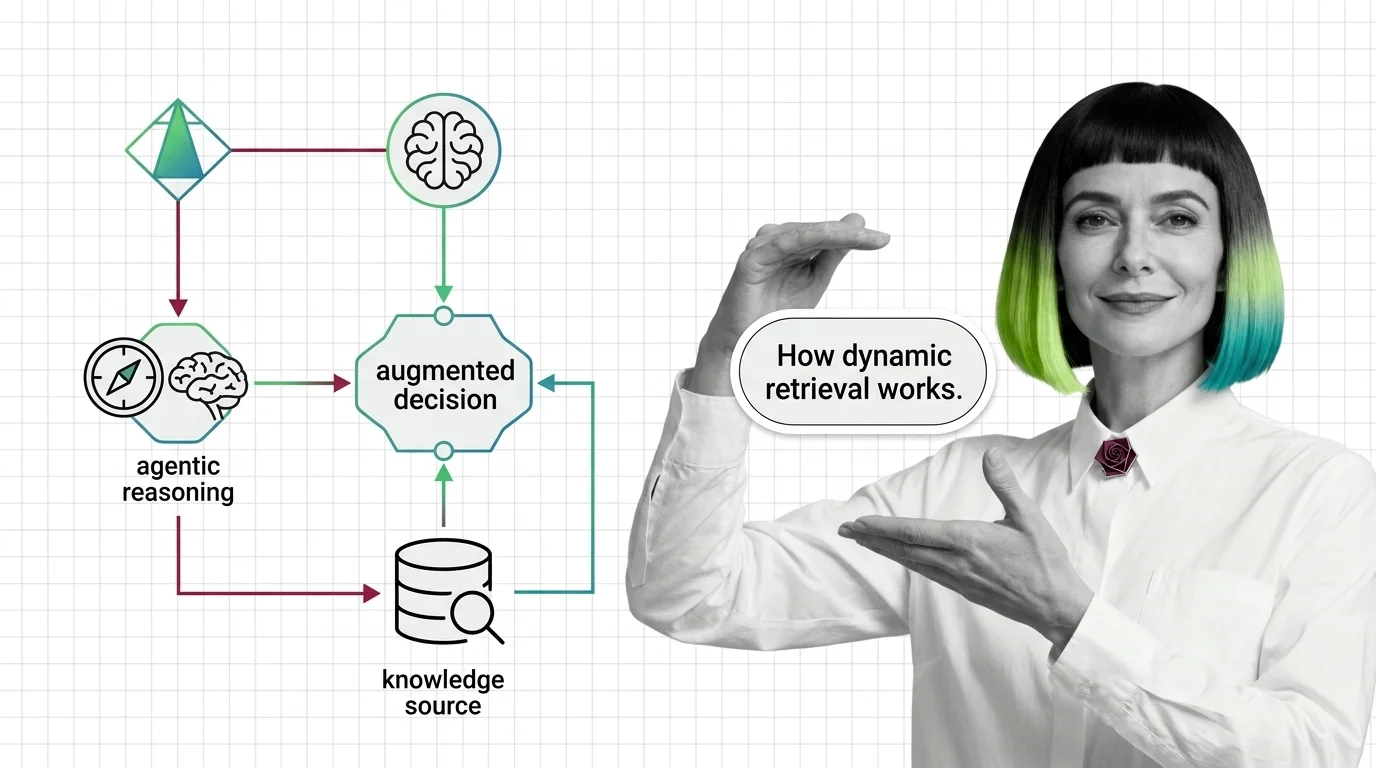
What Are Retrieval-Augmented Agents and How They Combine Agentic Reasoning with Dynamic Retrieval
Retrieval-augmented agents let the LLM decide when, what, and how often to retrieve — turning RAG from a fixed pipeline …
Cold Starts, Flaky Tests, and Context Blowup: The Technical Limits of Code Execution Agents in 2026
Code execution agents fail at three limits in 2026: sandbox cold-start vs isolation, flaky benchmark tests, and context …
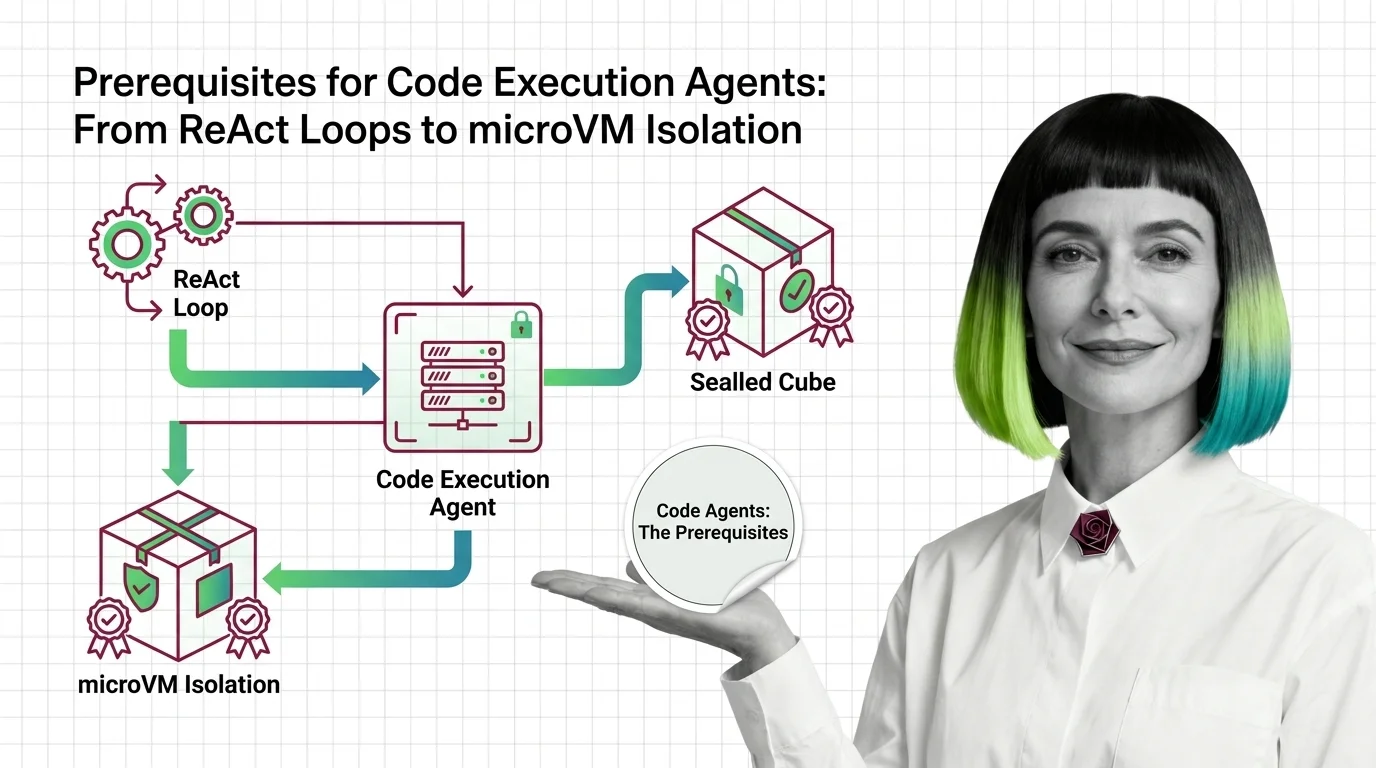
Prerequisites for Code Execution Agents: From ReAct Loops to microVM Isolation
Building a code execution agent requires three layers: a ReAct-style reasoning loop, a sandbox runtime, and microVM or …
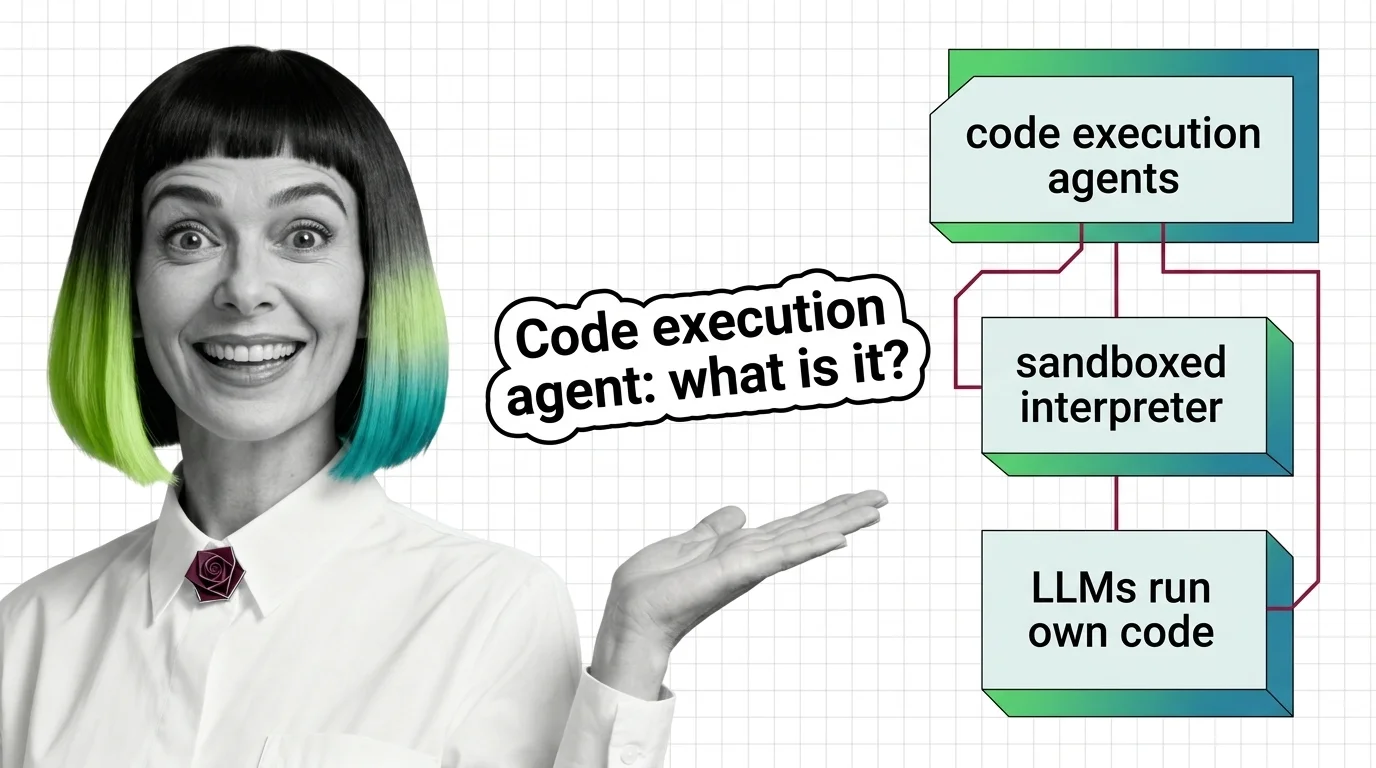
What Are Code Execution Agents and How Sandboxed Interpreters Let LLMs Run Their Own Code
Code execution agents are LLMs that write and run Python inside sandboxed containers. CodeAct showed up to 20% higher …
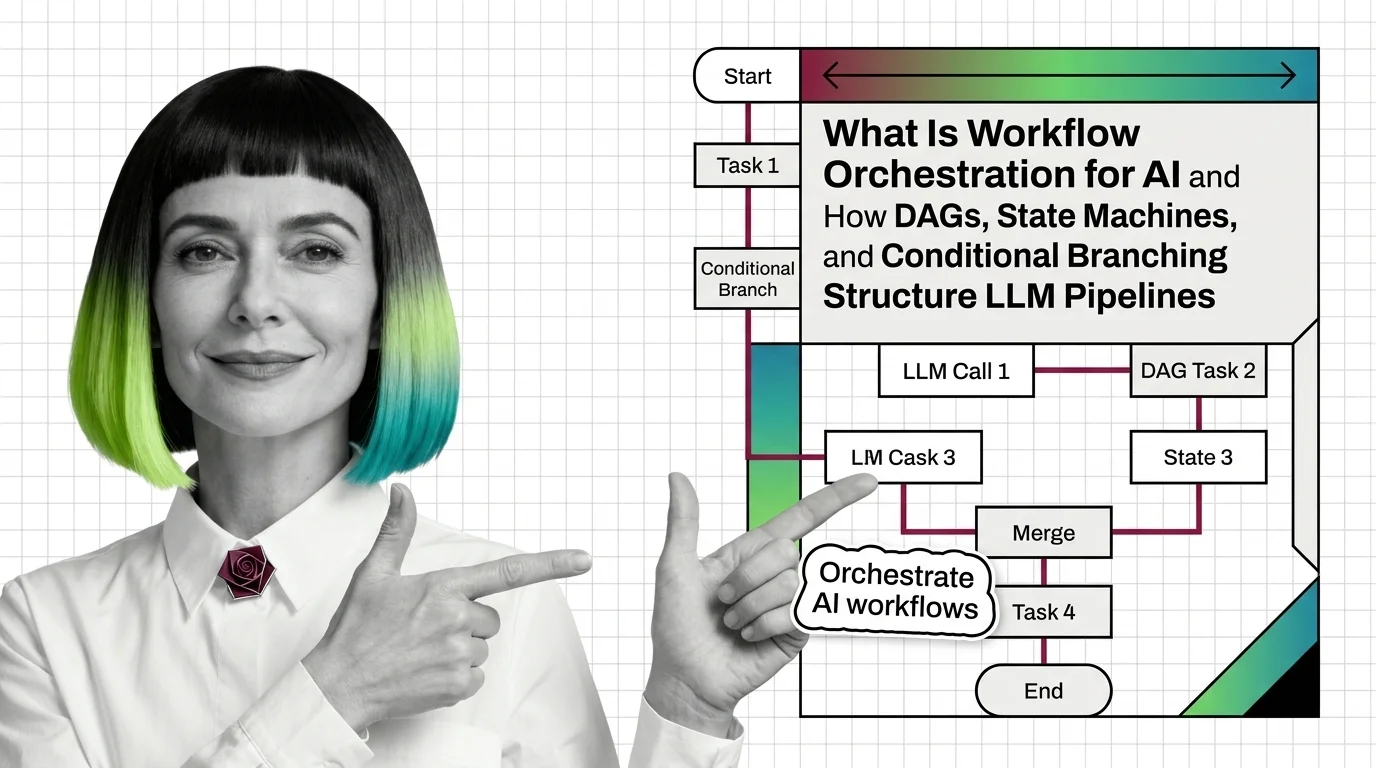
What Is LLM Orchestration? DAGs, State Machines and AI Workflows Explained
LLM orchestration coordinates the steps of an AI workflow, including decisions and recovery when a process fails. See …
Agent Error Handling: How Agents Recover From Tool and LLM Failures
Agent error handling turns brittle LLM loops into resilient systems. Learn how guardrails, retries, and checkpoints …
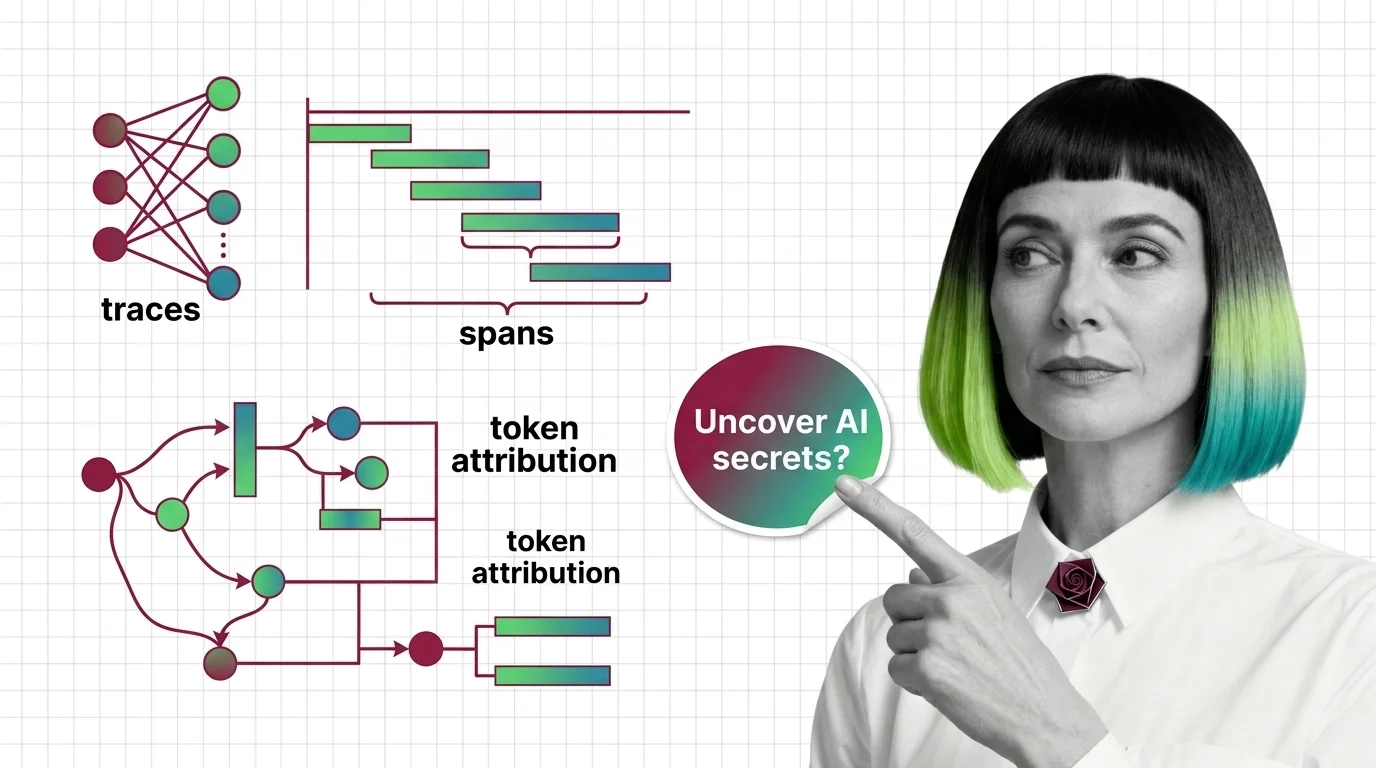
What Is Agent Observability? Traces, Spans, and Token Attribution
Agent observability records every step an AI agent takes. Learn how traces, spans, and token attribution reveal what …
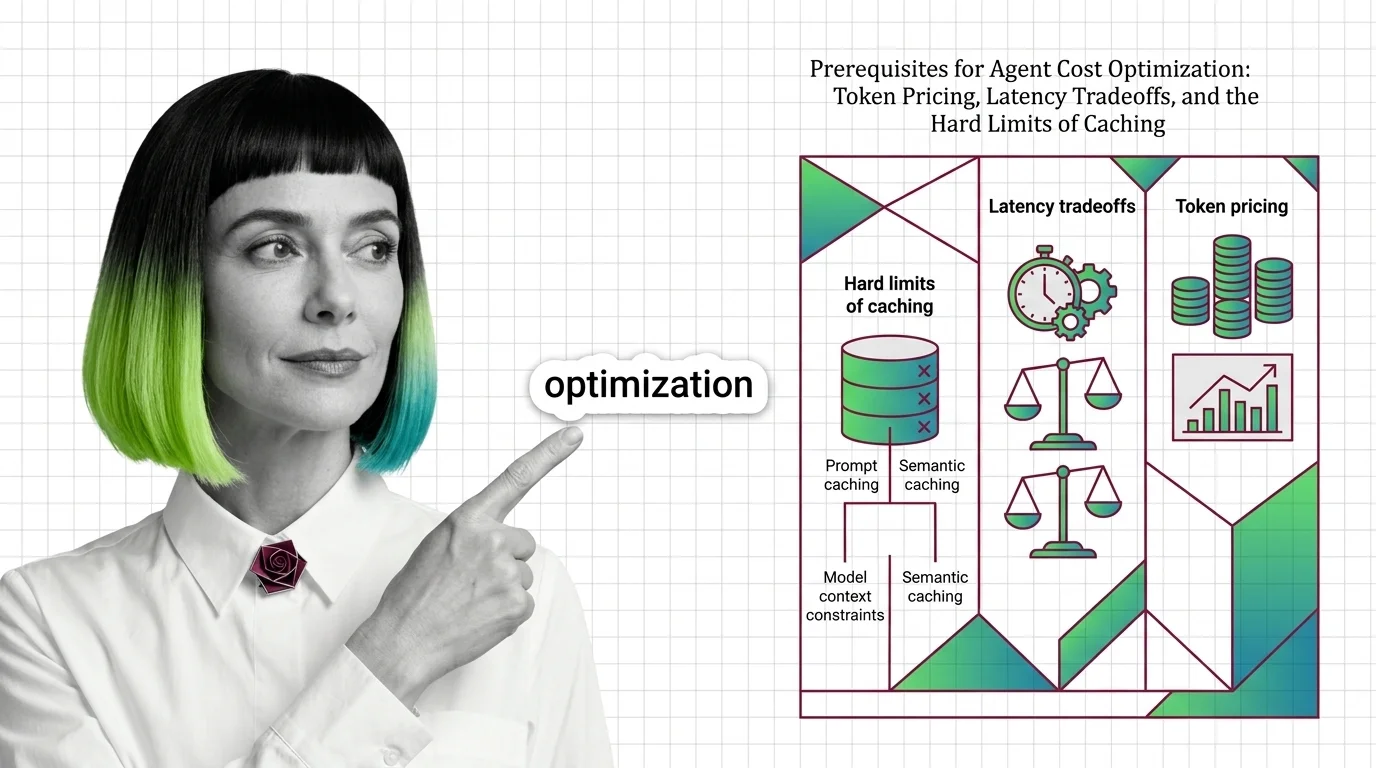
Agent Cost Optimization Prerequisites: Pricing, Latency, Caching Limits
Before optimizing agent costs, understand token pricing asymmetry, prefill vs decode latency, and why prompt and …
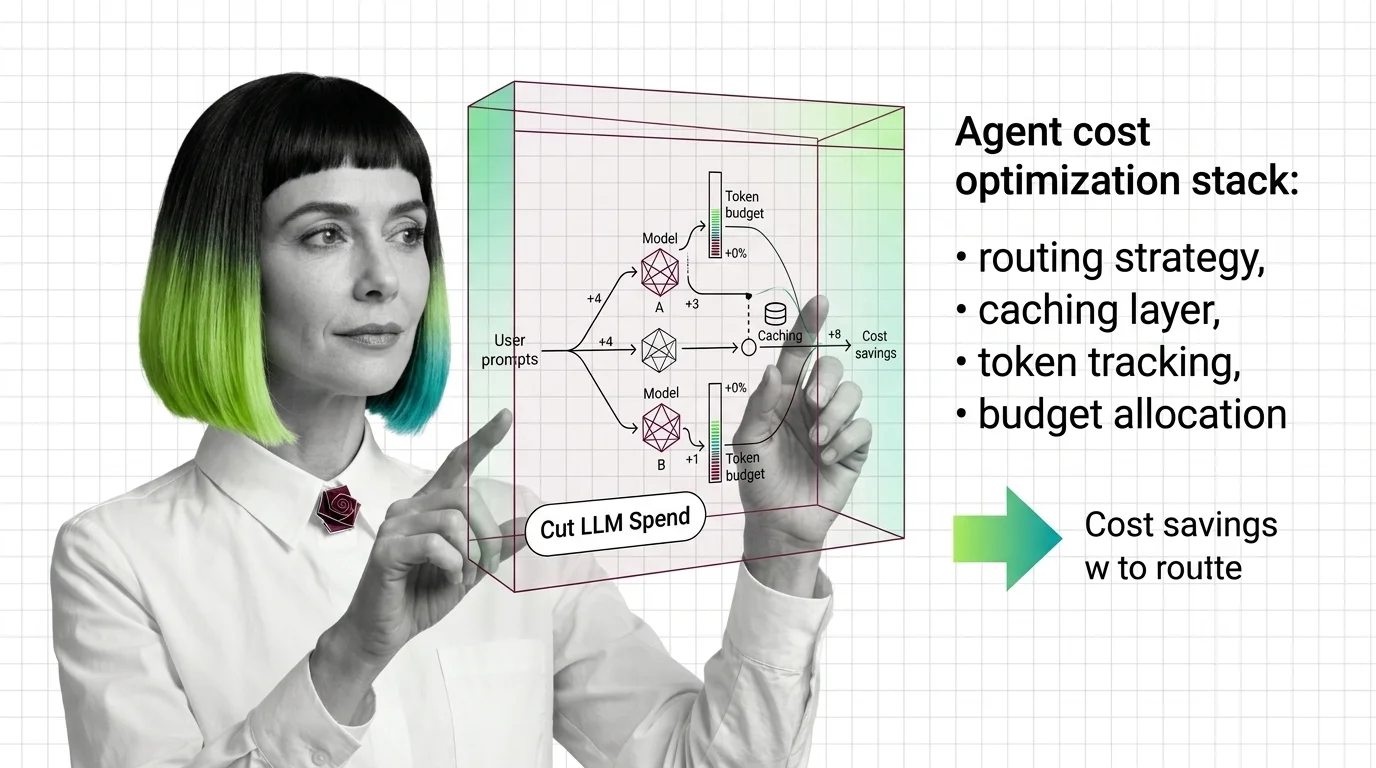
Agent Cost Optimization: Routing, Caching, and Token Budgets for LLMs
Agent cost optimization routes requests to the right model, caches reusable computation, and caps runaway loops before …
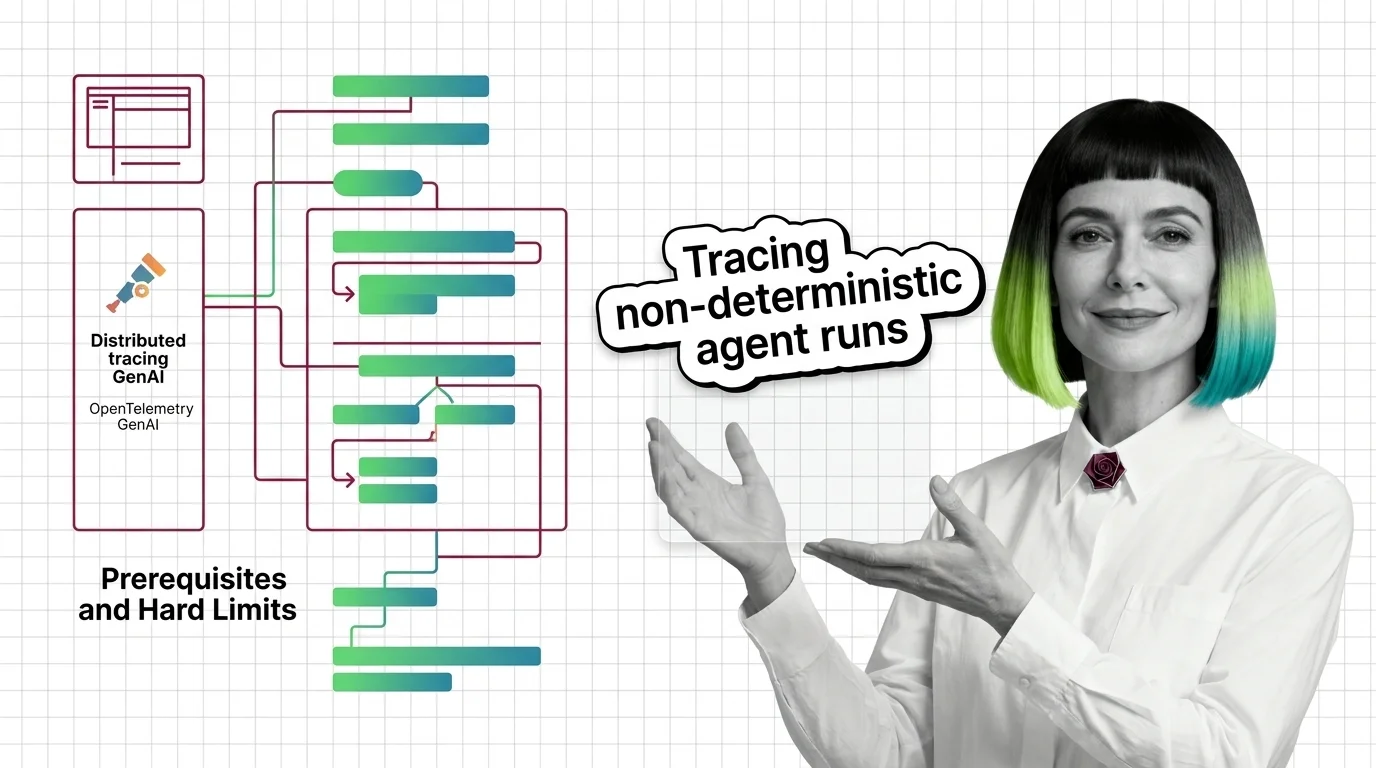
OpenTelemetry GenAI: Prerequisites and Limits of Agent Tracing
OpenTelemetry GenAI semconv is still in Development. What you need to know about tracing prerequisites and hard limits …
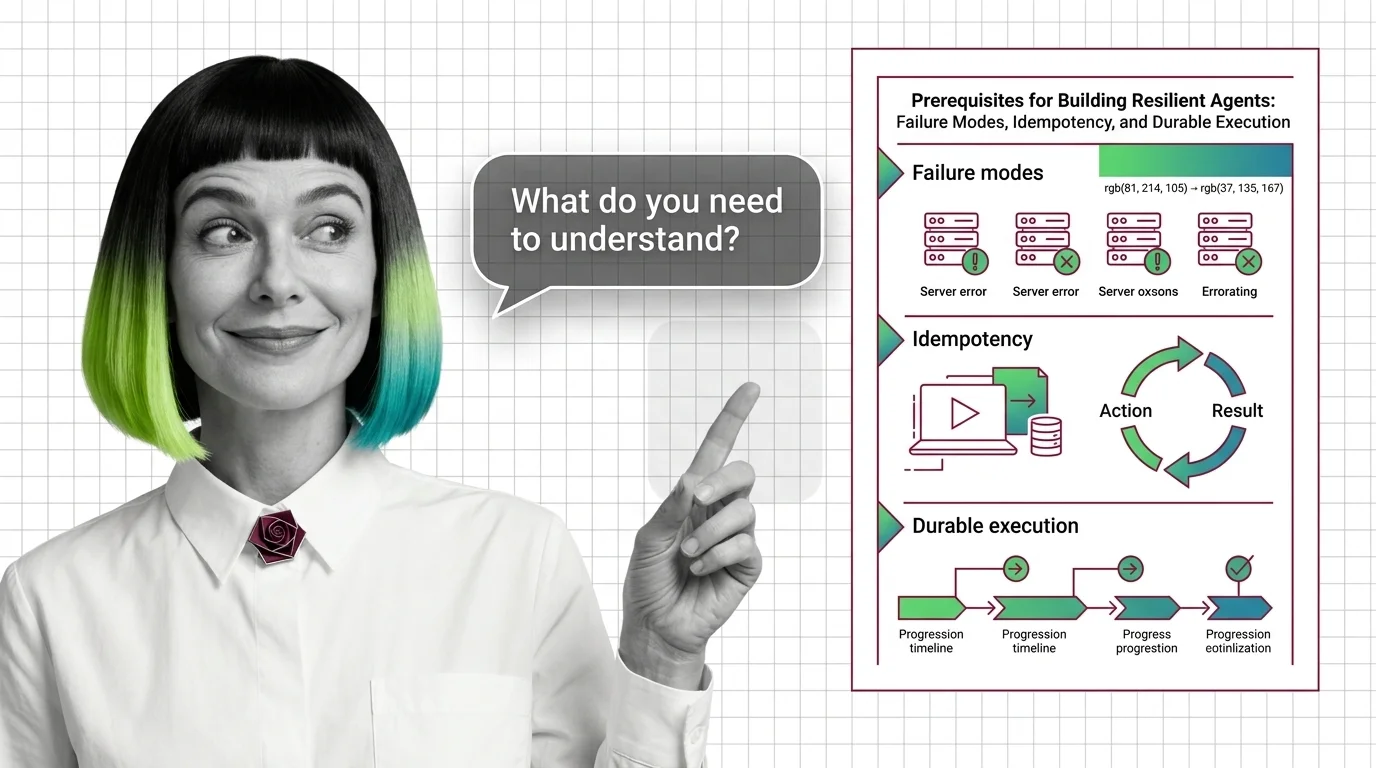
Resilient AI Agents: Failure Modes, Idempotency, Durable Execution
Reliable AI agents need three foundations: a failure-mode taxonomy, idempotent action boundaries, and durable execution …
What Are Agent Guardrails? How Permission Systems Constrain AI
Agent guardrails enforce permission boundaries on autonomous AI. Learn how Claude SDK, NeMo, and Llama Guard constrain …
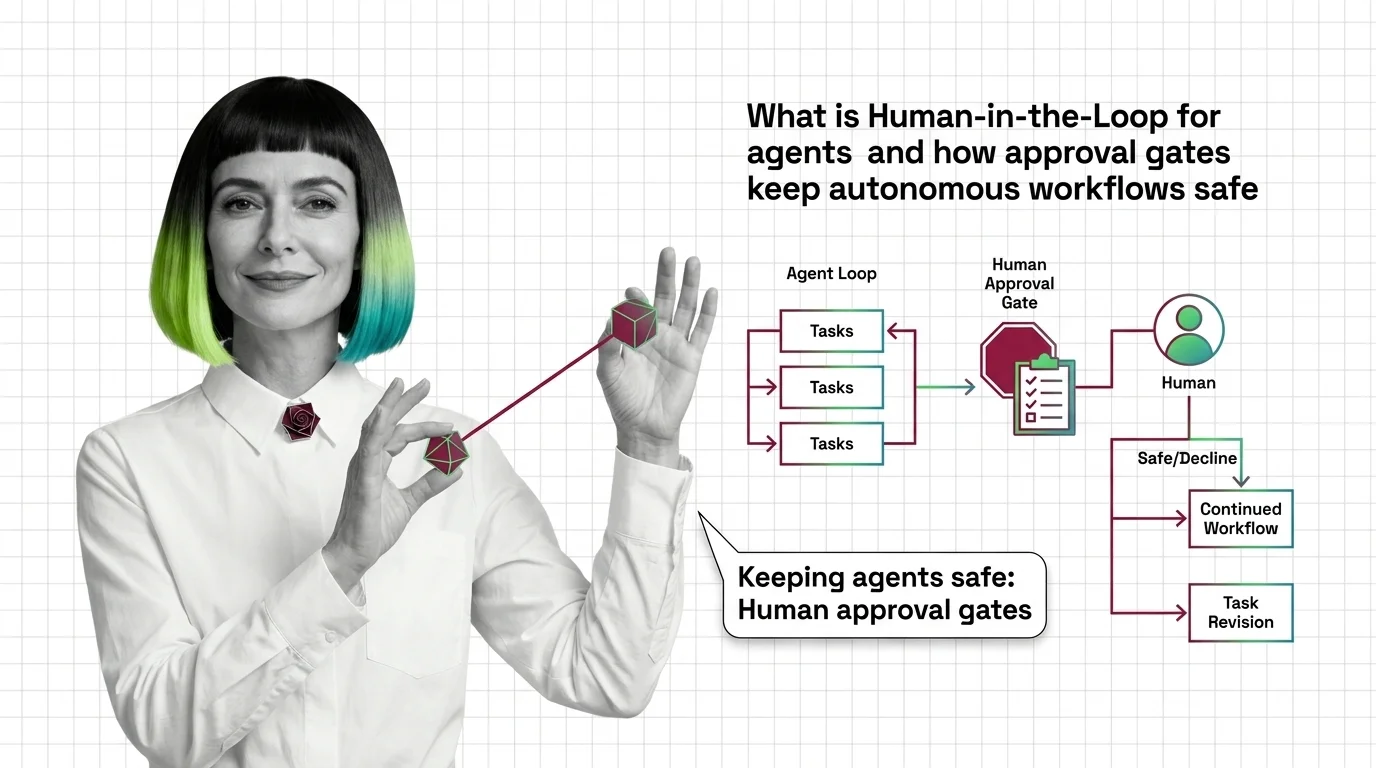
Human-in-the-Loop for AI Agents: How Approval Gates Work
Human-in-the-loop for AI agents pauses autonomous workflows at risky steps and routes them to a human gate. Here's how …
Prerequisites and Technical Limits of HITL for AI Agents
HITL for agents is easy to start and hard to scale. Learn the prerequisites — durable state, idempotency, escalation — …
Prerequisites for Agent Guardrails: Tool Use and Runtime Limits
Agent guardrails are runtime classifiers wrapped around tool-use loops — useful, partial, and demonstrably evadable. …
Agent State Management: How Checkpointing Persists Memory Across Turns
Agent state management decides whether your agent remembers. See how LangGraph checkpointers, threads, and reducers …