Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
Uncertainty Sampling Explained: Entropy, Margin, and Least-Confidence Query Strategies
Uncertainty sampling is an active-learning strategy that labels the data a model is least confident about — via entropy, …
What Is Active Learning and How Models Pick the Most Informative Samples to Label
Active learning lets a model query only the most informative unlabeled samples to label, hitting target accuracy with …
What Is Data Deduplication and How MinHash LSH Detects Near-Duplicate Training Samples
Data deduplication removes near-duplicate training samples using MinHash LSH. Lee et al. found dedup cuts verbatim …
Before You Preprocess: Data Types, Distributions, and Train-Test Splits You Need to Understand First
Split data into train and test sets before preprocessing to prevent data leakage. Fitting scalers on the full dataset …
Data Leakage, Lost Information, and the Technical Limits of Preprocessing Pipelines
Data leakage occurs when information unavailable at prediction time enters training, inflating validation accuracy while …
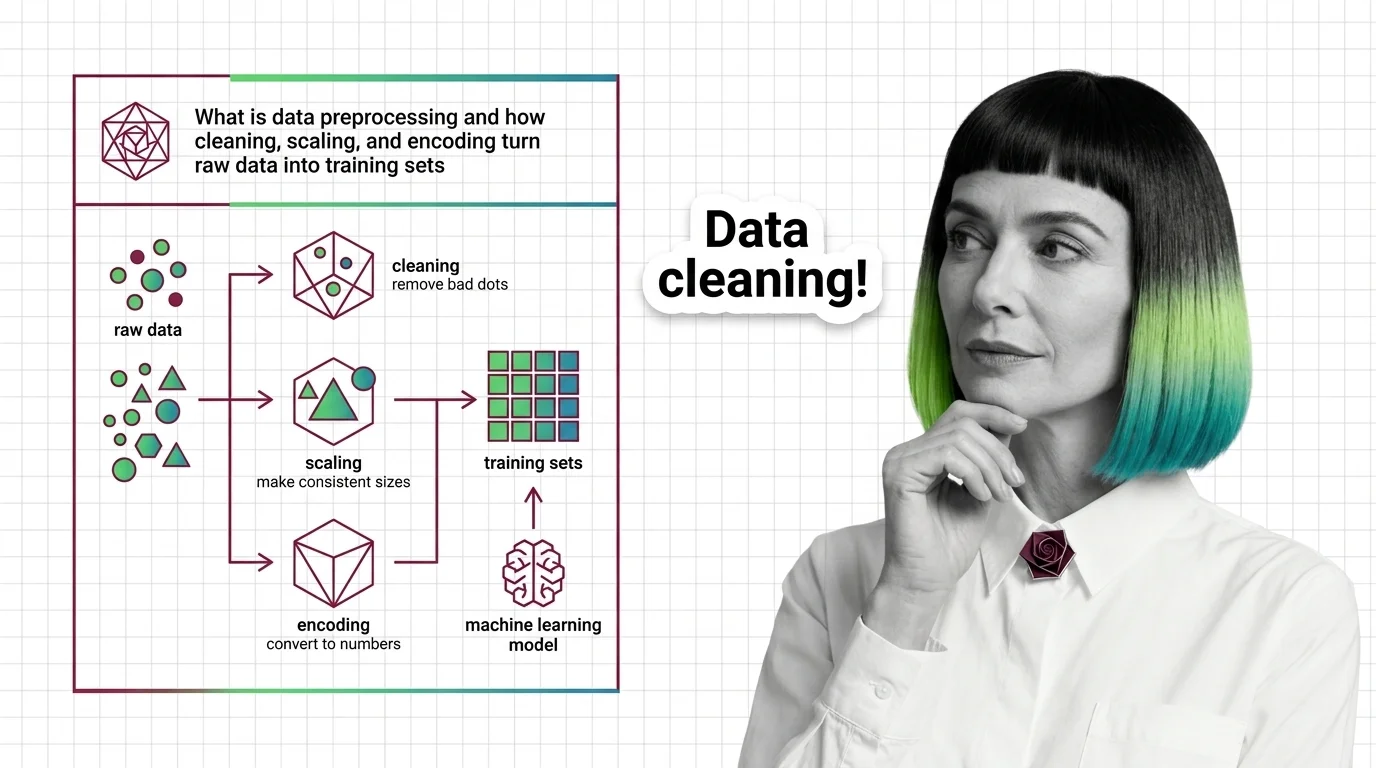
What Is Data Preprocessing and How Cleaning, Scaling, and Encoding Turn Raw Data into Training Sets
Data preprocessing cleans, scales, and encodes raw data into model-ready features. Fitting transformers before the …
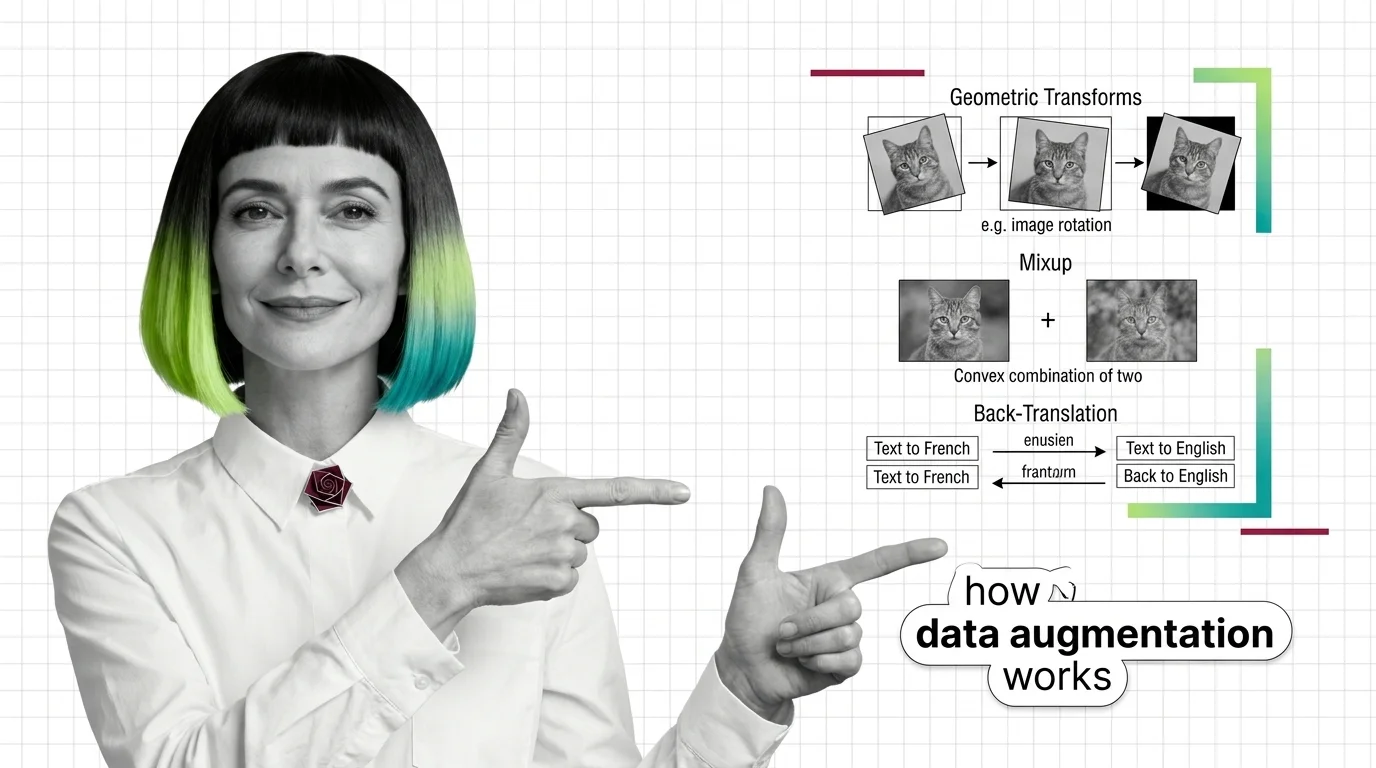
Geometric Transforms, Mixup, and Back-Translation: How Core Augmentation Methods Work
Data augmentation transforms existing examples — flips, mixup blends, CutMix patches, back-translation — to teach models …
Inter-Annotator Agreement, Annotation Guidelines, and the Building Blocks of a Labeling Project
Inter-annotator agreement measures label quality beyond chance. Cohen's kappa corrects raw match rates, exposing …
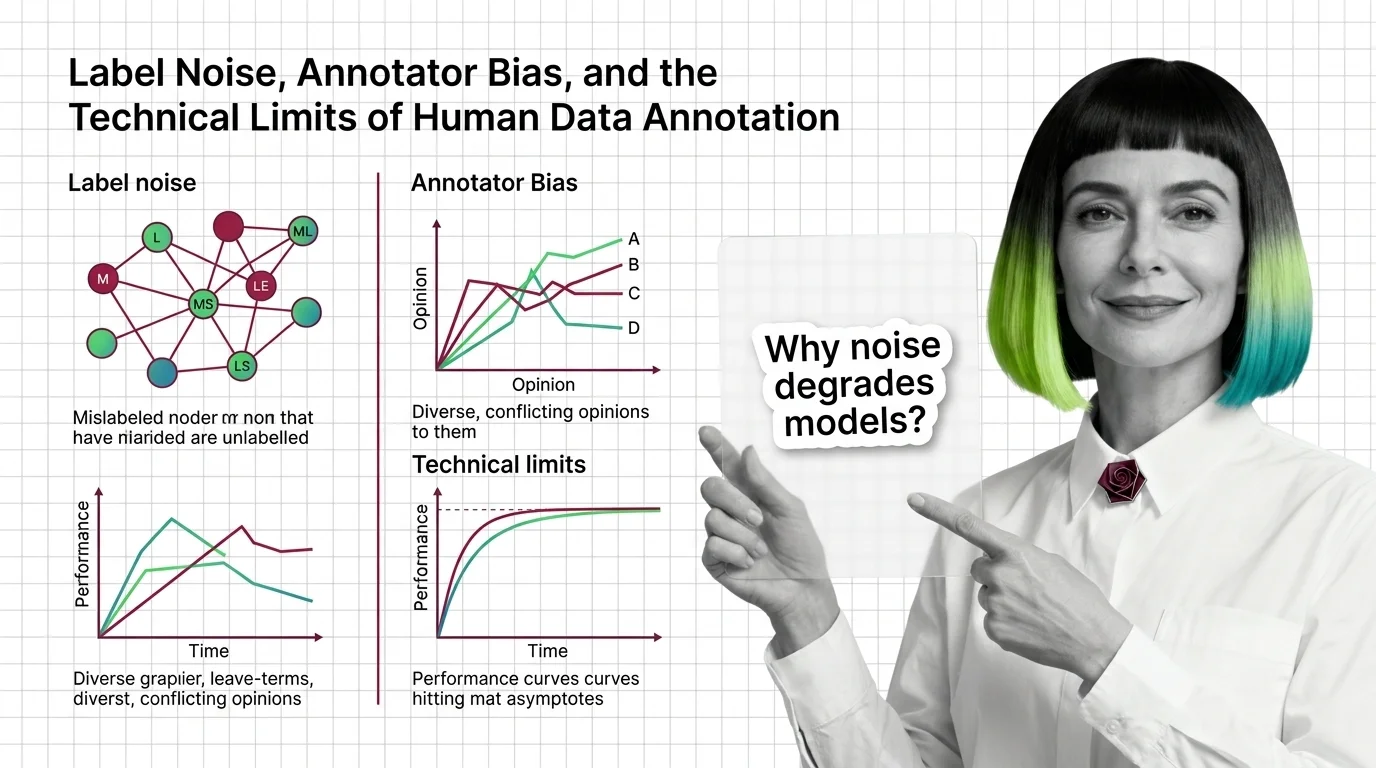
Label Noise, Annotator Bias, and the Technical Limits of Human Data Annotation
Label noise averages an estimated 3.4% across major ML test sets, distorting supervised model accuracy and even flipping …
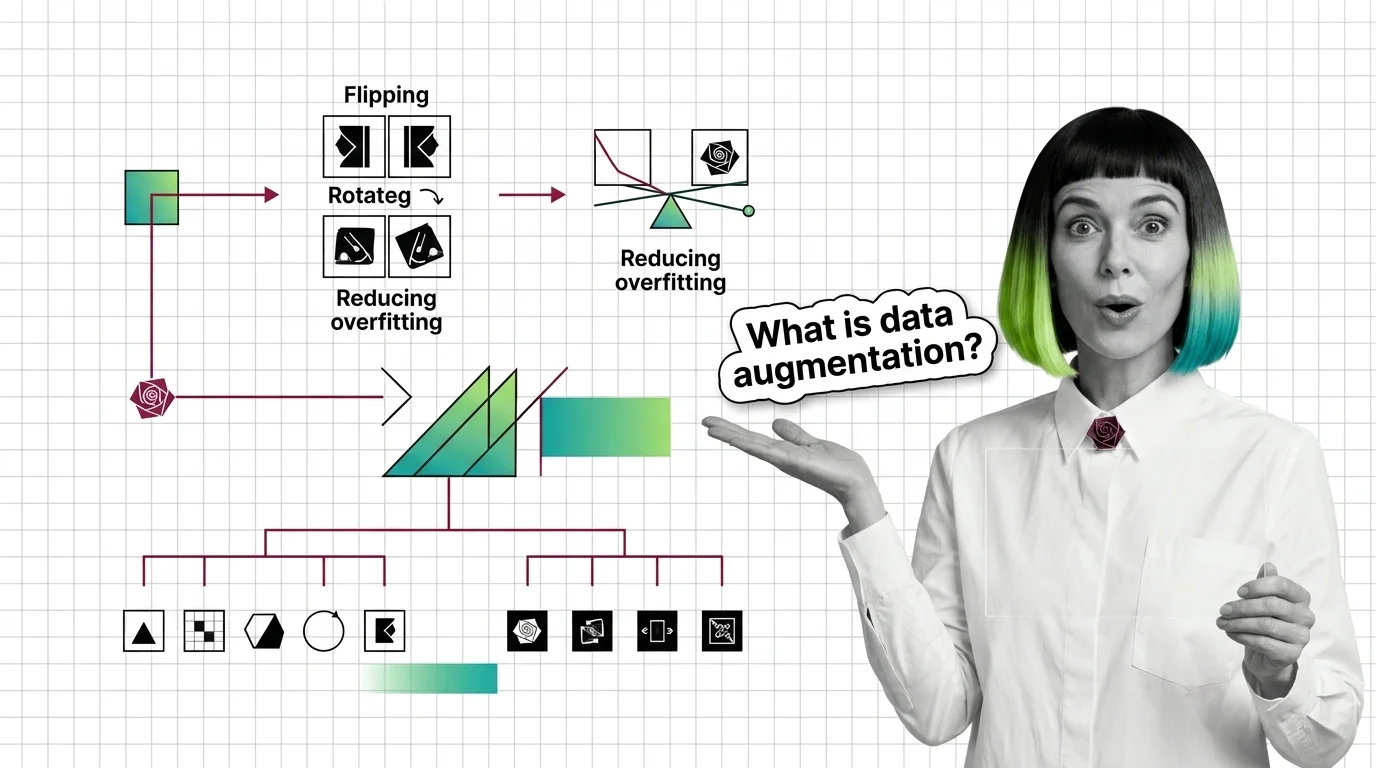
What Is Data Augmentation and How Transforming Samples Expands Training Data
Data augmentation expands training data by transforming existing samples—rotations, mixup, masking—to reduce overfitting …
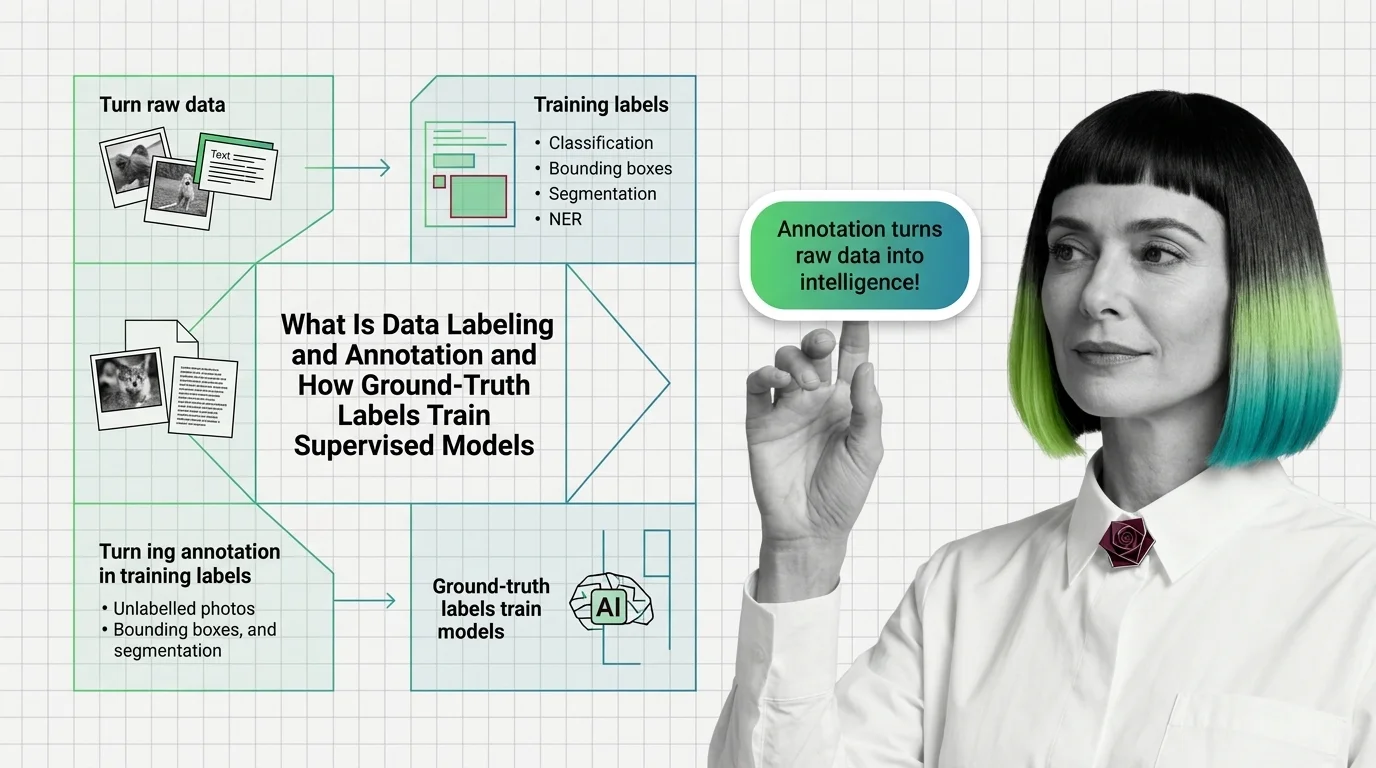
What Is Data Labeling and Annotation, and How Ground-Truth Labels Train Supervised Models
Data labeling assigns ground-truth labels to raw data so supervised models learn a mapping. Label noise propagates into …
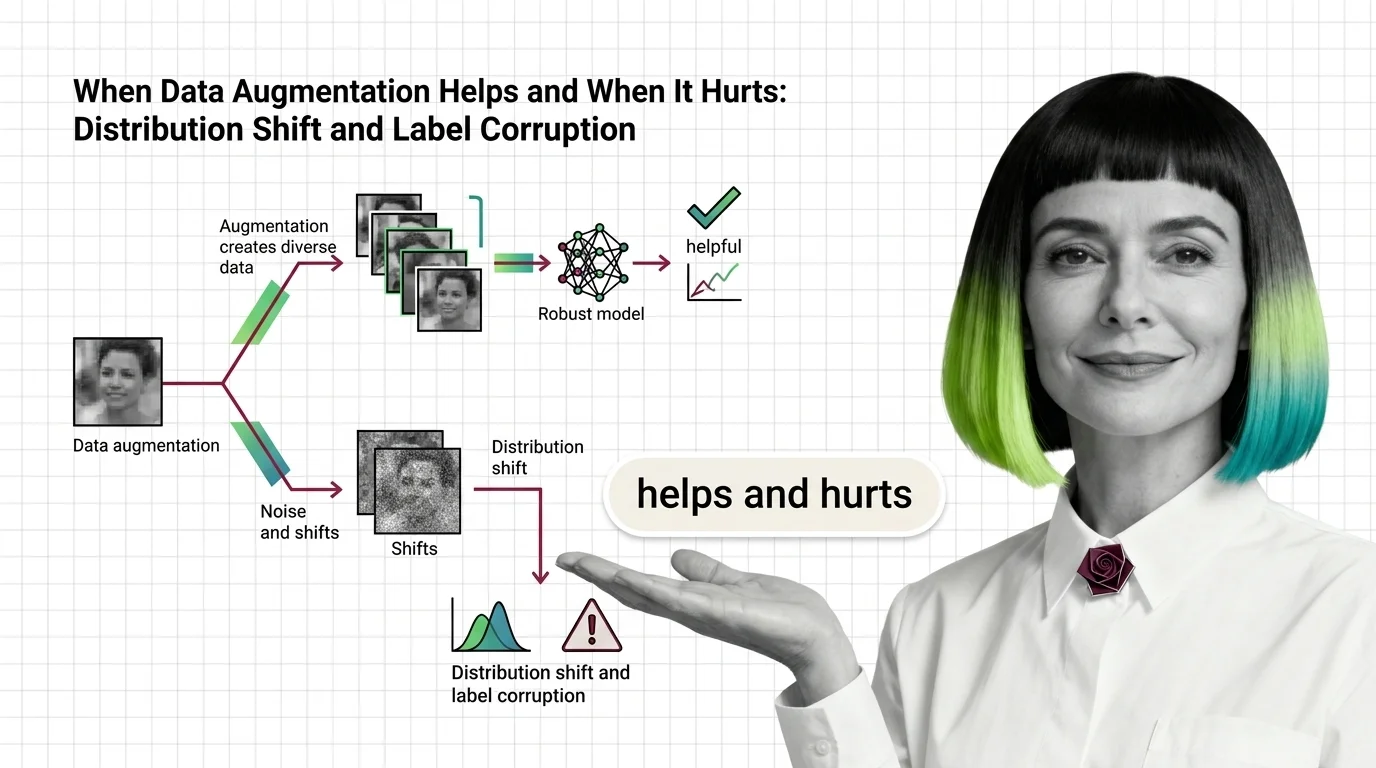
When Data Augmentation Helps and When It Hurts: Distribution Shift and Label Corruption
Data augmentation helps until synthetic samples drift from real data or break the input-label mapping, creating …
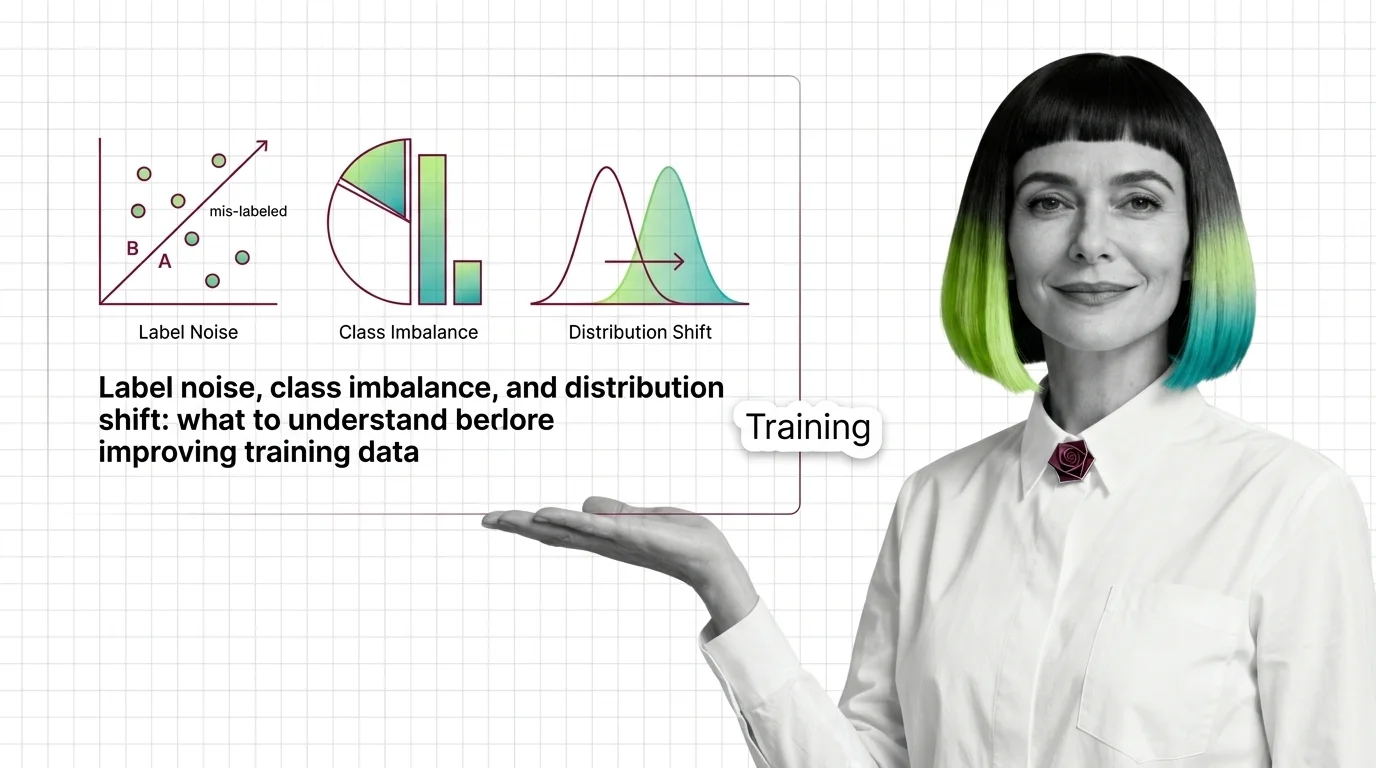
Label Noise, Class Imbalance, and Distribution Shift: What to Know Before Fixing Training Data
Label noise, class imbalance, and distribution shift degrade models more than architecture choices. Understand all three …
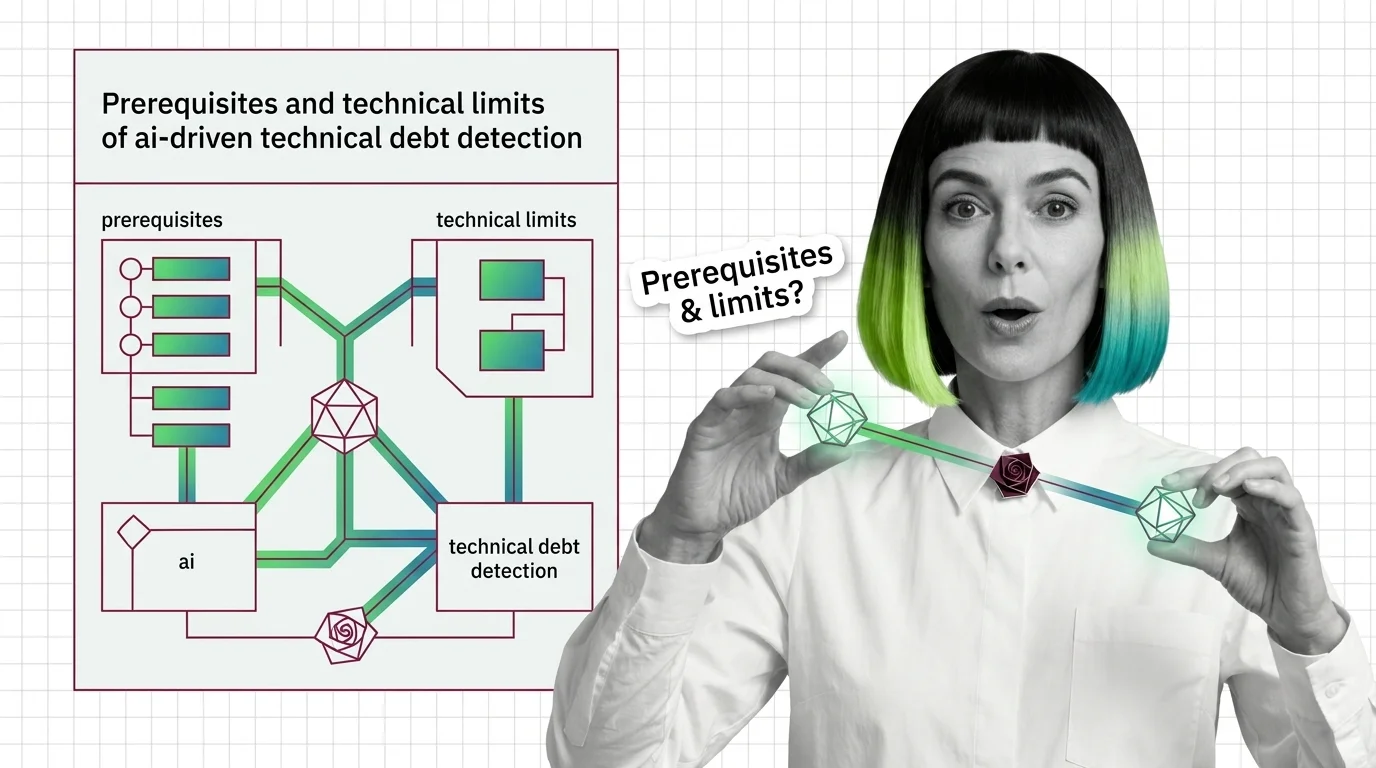
What AI Technical-Debt Tools Actually Measure — and Where the Numbers Break
AI technical-debt tools measure proxies like complexity and code churn, not debt itself. Vendor false-positive rates …
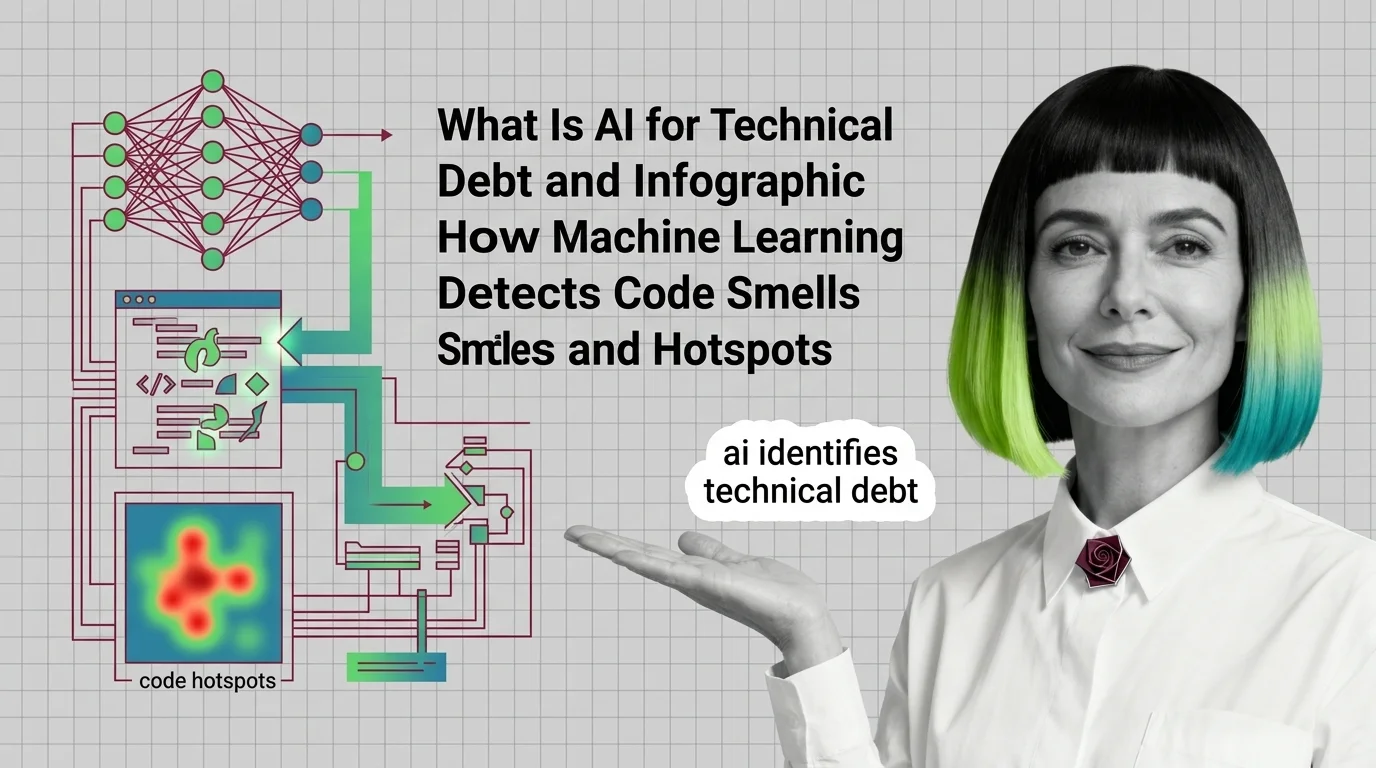
What Is AI for Technical Debt and How Machine Learning Detects Code Smells and Hotspots
AI for technical debt combines ML and behavioral code analysis to find decay hotspots — a small fraction of files drives …
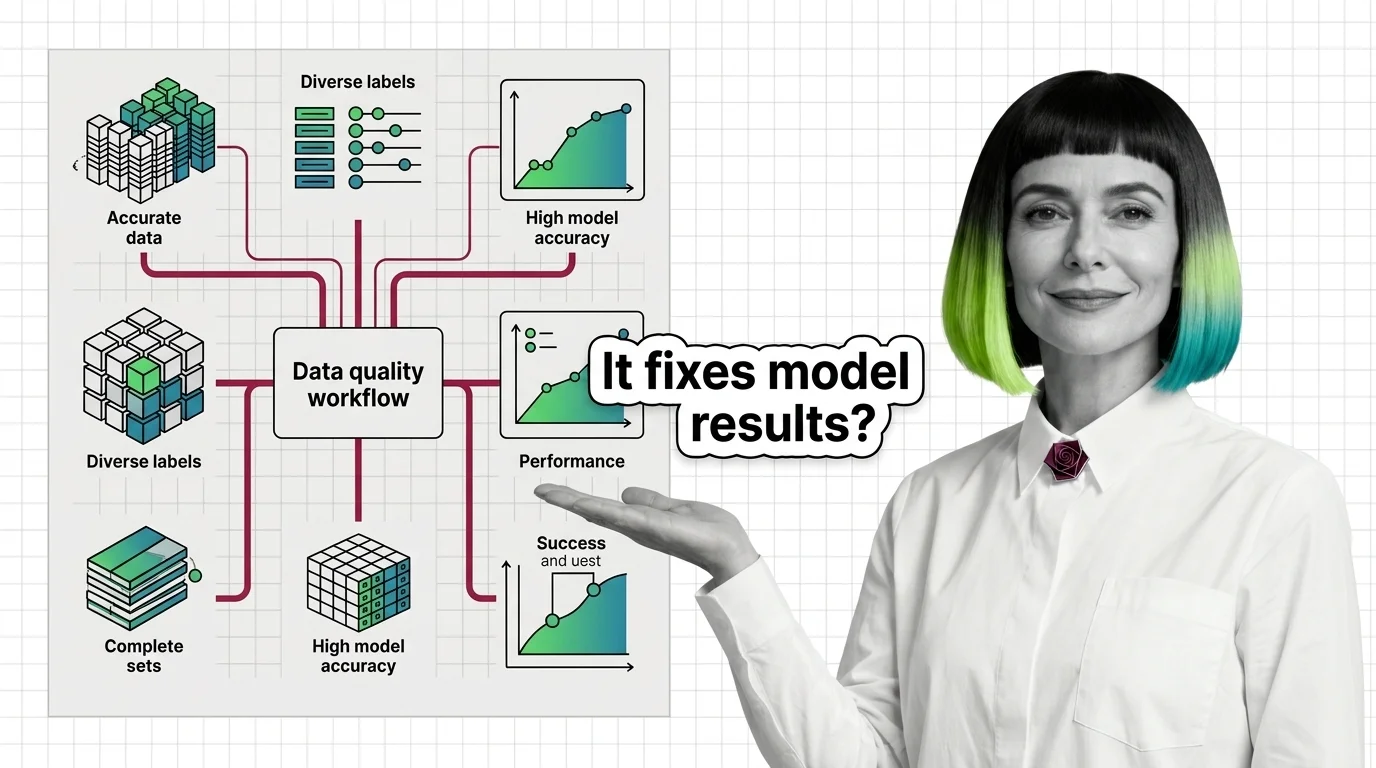
What Is Training Data Quality and How It Determines Model Performance
Training data quality is the systematic engineering of label correctness, deduplication, and provenance — it sets the …
Why Perfectly Clean Data Is Impossible: The Technical Limits of Data Curation at Scale
Cleaning training data at scale hits hard limits: label errors average 3.4% across top ML datasets, and automated …
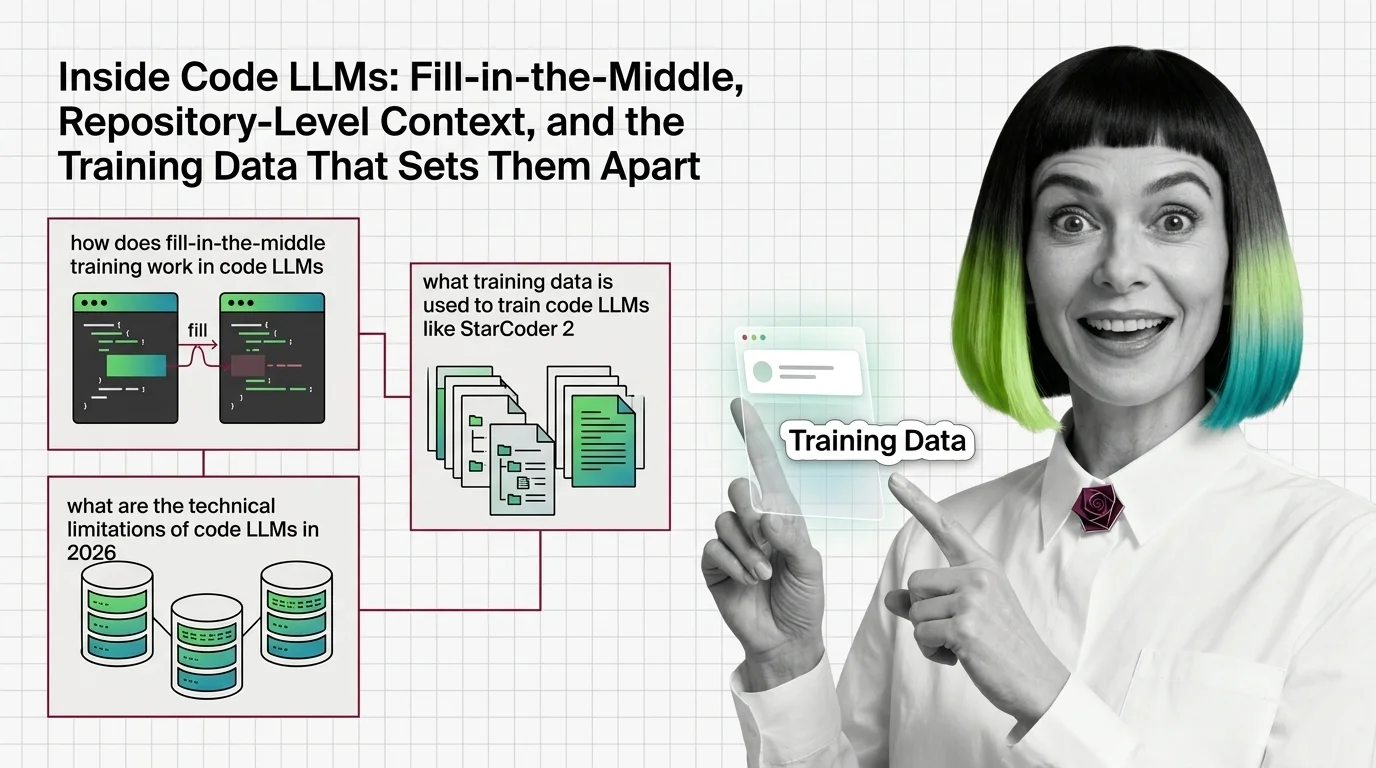
Inside Code LLMs: Fill-in-the-Middle and the Training Data Behind Them
Fill-in-the-middle reorders code into prefix-suffix-middle triplets, letting code LLMs like StarCoder 2 complete code …
Prerequisites and Technical Limits of AI in CI/CD: DevOps Foundations to Flaky-Test False Positives
AI in CI/CD requires a deterministic pipeline-as-code foundation first. Its main failure mode: misclassifying real …
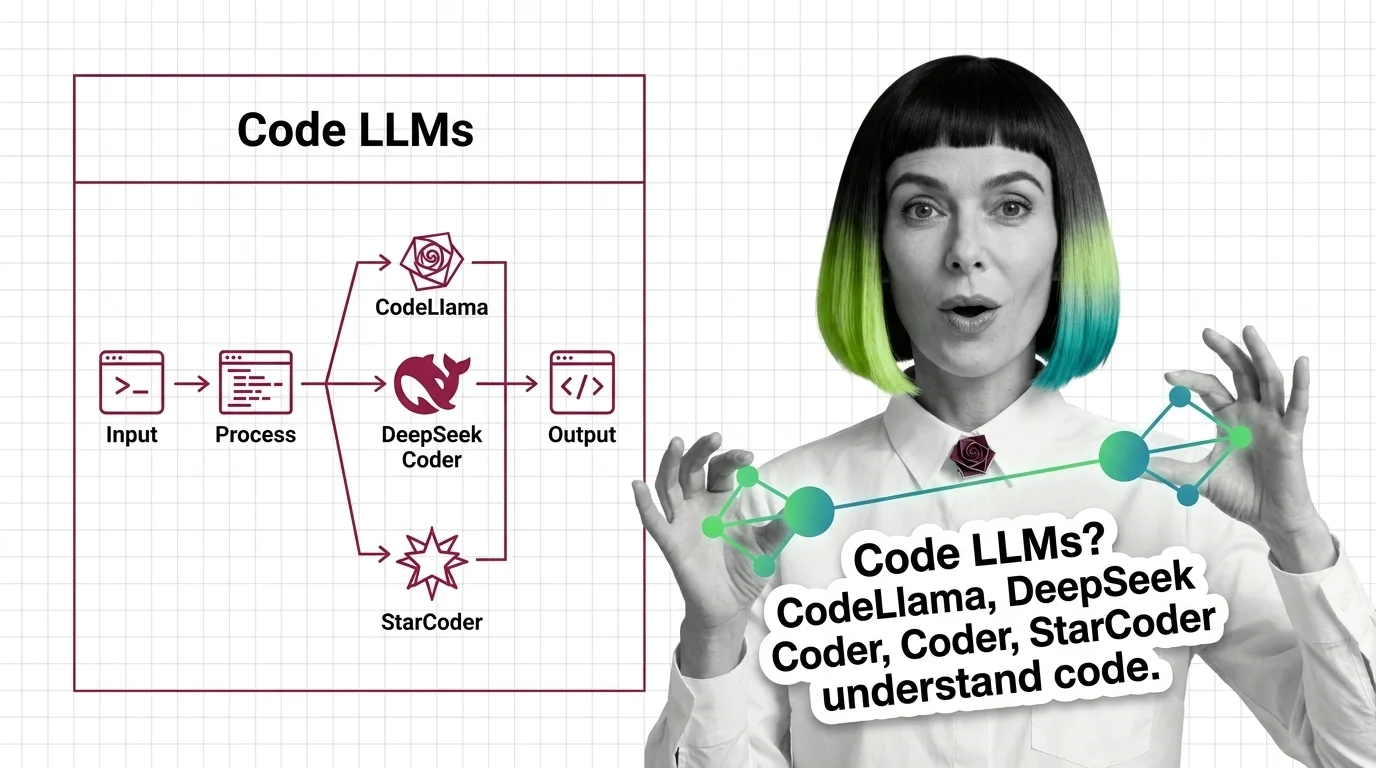
What Are Code LLMs and How CodeLlama, DeepSeek Coder, and StarCoder Understand Source Code
Code LLMs are transformers trained on billions of code tokens, not prose. Fill-in-the-Middle training lets them complete …
What Is AI in CI/CD Pipelines and How Automated Code Analysis and Deployment Checks Work
AI in CI/CD pipelines uses ML trained on build history to prioritize tests, predict build failures, and score deployment …
Context Window Collapse, Tool-Call Loops, and the Hard Technical Limits of Coding Agents in 2026
Coding agents in 2026 stall on long contexts and tool-call loops. Even top SWE-bench scorers fail one in five tasks …
Prerequisites for Agentic Coding: Tool Use, Scaffolding, and the Plan-Execute-Verify Loop
Agentic coding needs three layers: tool calls, scaffolding, and a plan-execute-verify loop. Scaffolding shifts SWE-bench …
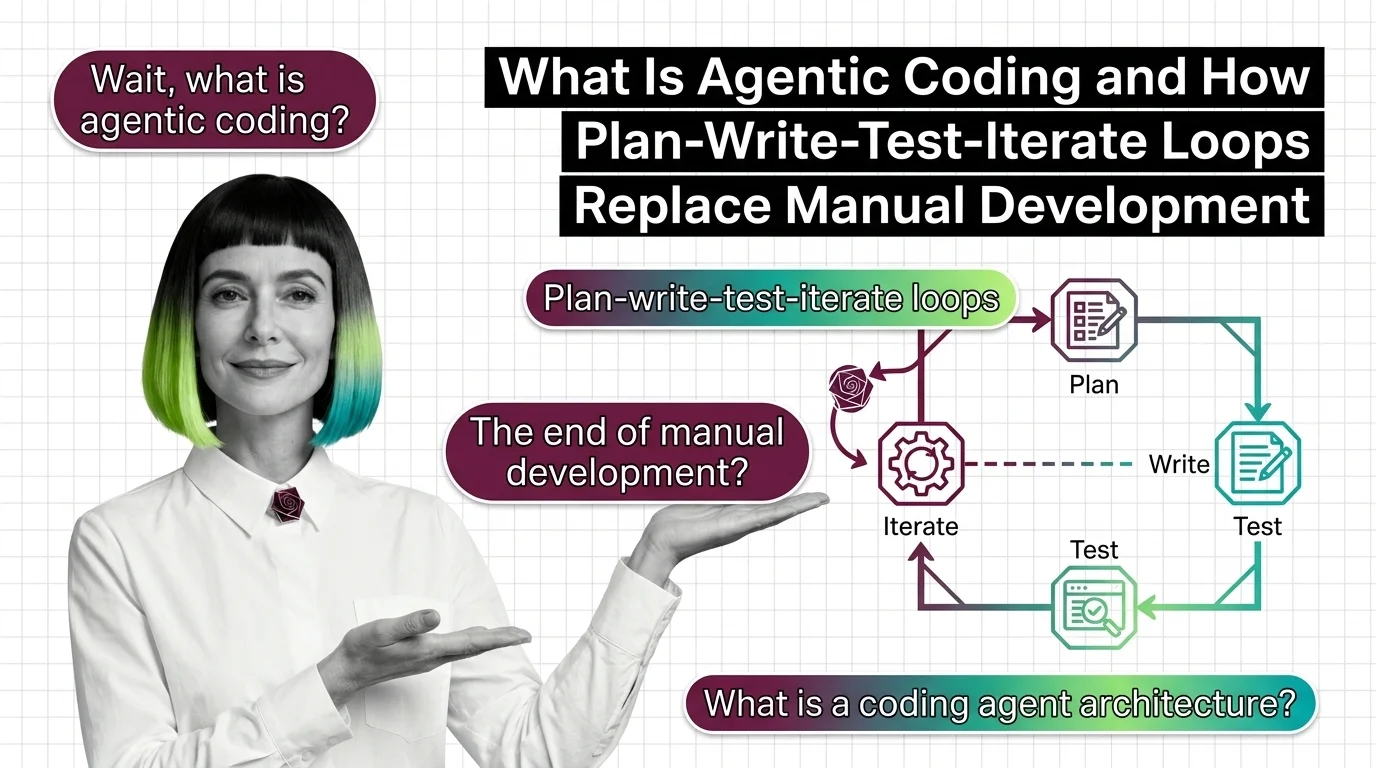
What Is Agentic Coding and How Plan-Write-Test-Iterate Loops Replace Manual Development
Agentic coding is a loop where an LLM plans, writes, tests, and revises code using real dev tools. Claude Code hits …
What Is Context Engineering for Coding Agents? How It Shapes What an AI Coding Assistant Writes
Context engineering for coding agents means choosing what an AI coding tool reads before it writes, so its code fits …
What Is Vibe Coding? How It Works and Where It Breaks
Vibe coding means describing software to an AI and accepting the code it writes. How the loop works, how it differs from …

What Is the Model Context Protocol (MCP)? How It Connects AI to Tools
The Model Context Protocol (MCP) connects AI applications to external tools and data through a shared interface.

AI Code Migration: AST Parsing, Test Coverage, and the Problem of Silent Regressions
AI code migration transforms syntax via AST tools but can't guarantee behavior. A Copilot agent hit 100% migration …

MCP Architecture Explained: Hosts, Clients, Servers and What They Exchange
MCP architecture connects an AI host to a server through a client that exchanges messages to use tools, resources and …

What Is AI Code Migration and How LLM Agents Translate Languages and Modernize Legacy Codebases
AI code migration uses LLM agents to translate legacy COBOL and PL/SQL into Java or Python, pairing deterministic AST …