Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
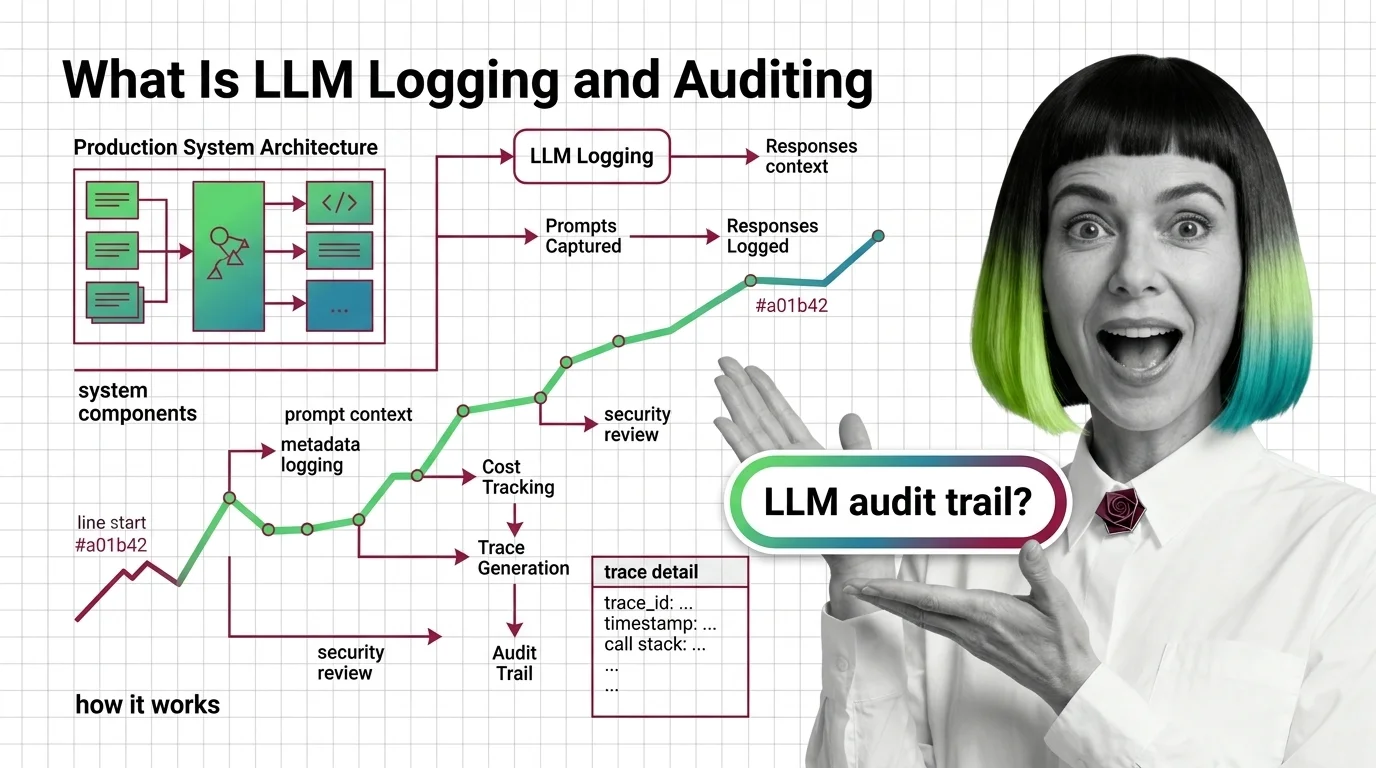
What Is LLM Logging and Auditing and How Production Systems Capture Prompts, Costs, and Traces
LLM logging captures prompts, tokens, latency, and costs per call. OTel GenAI trace hierarchies let teams reconstruct …
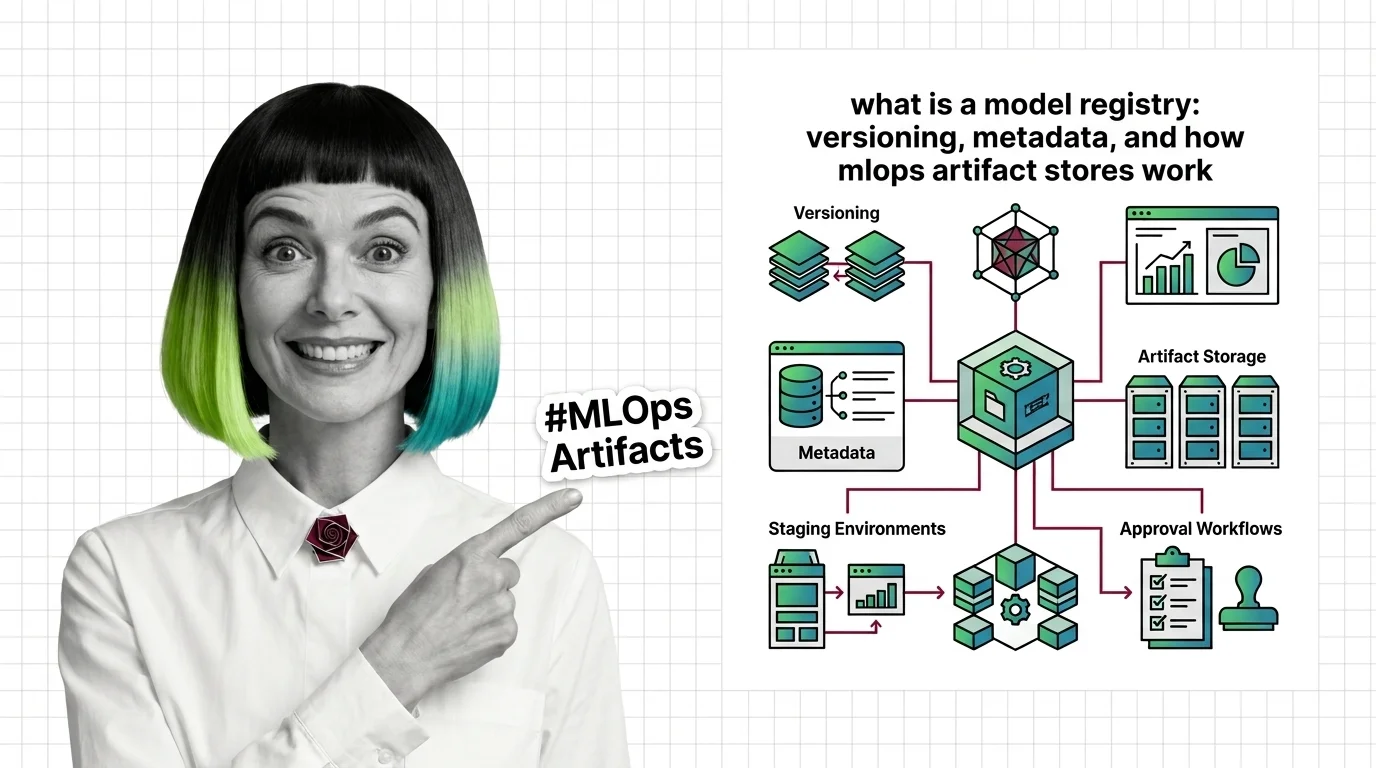
What Is a Model Registry: Versioning, Metadata, and How MLOps Artifact Stores Work
A model registry tracks ML model versions, weights, and deployment configs. MLflow 3 replaced fixed stages with named …
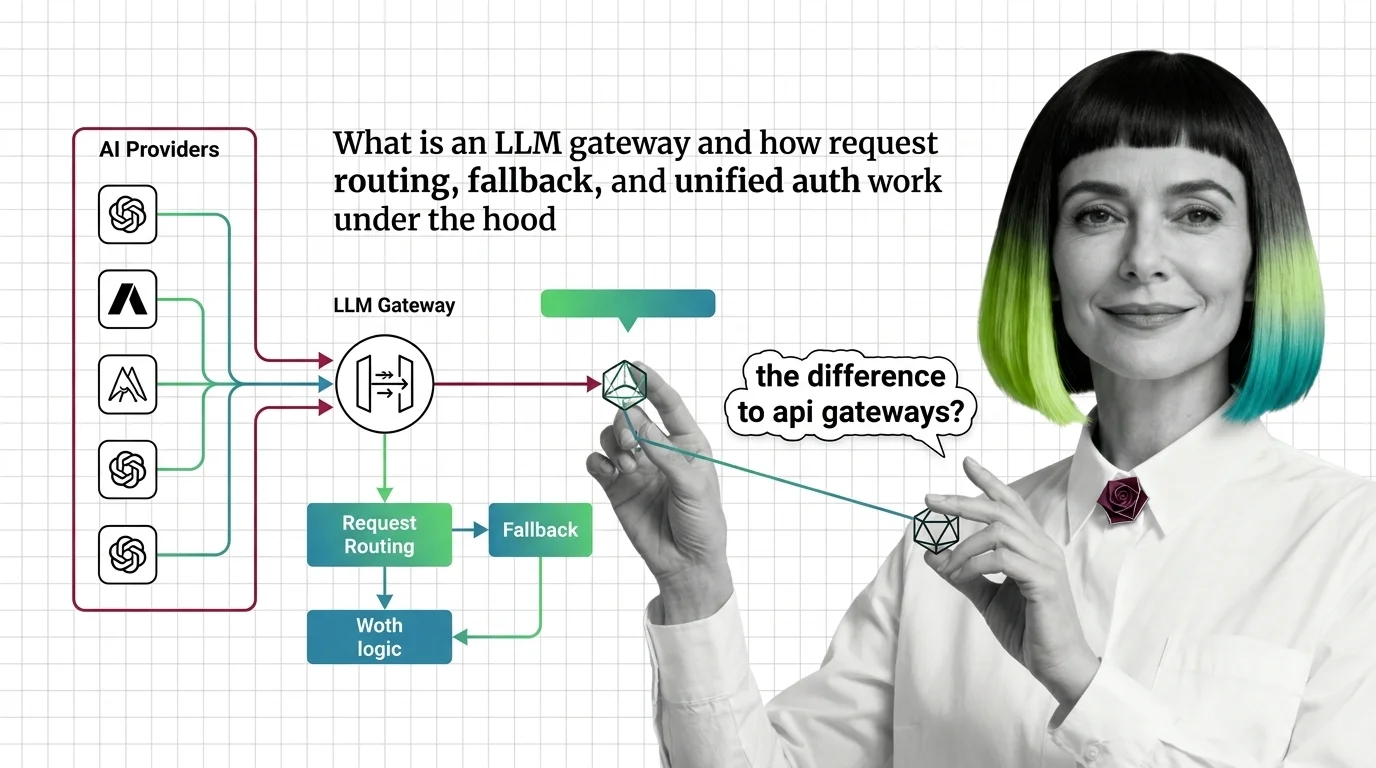
What Is an LLM Gateway and How Request Routing, Fallback, and Unified Auth Work Under the Hood
LLM gateway: middleware routing app requests across AI providers, with fallback, unified auth, and token tracking. …
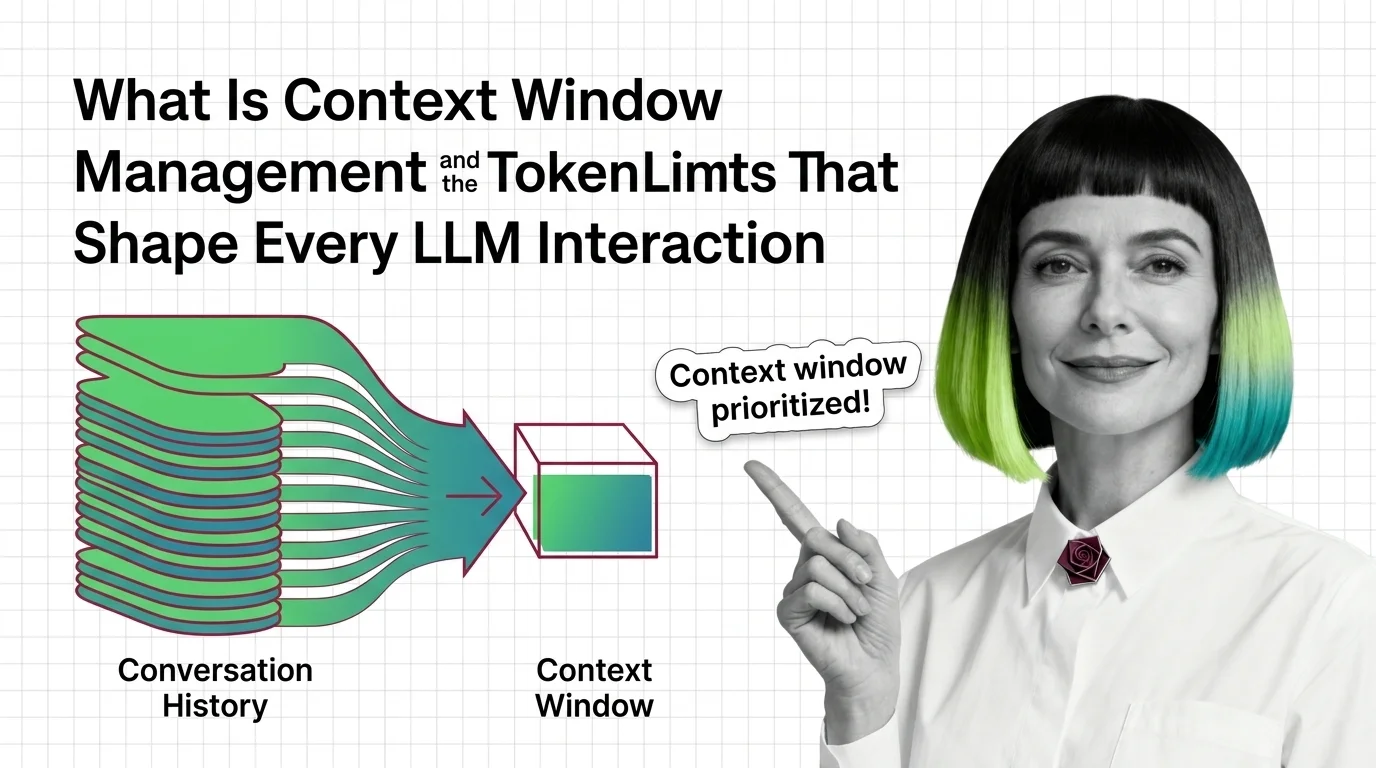
What Is Context Window Management and the Token Limits That Shape Every LLM Interaction
Context window management controls what an LLM sees at inference time. Past 15K words, latency can spike sevenfold — how …
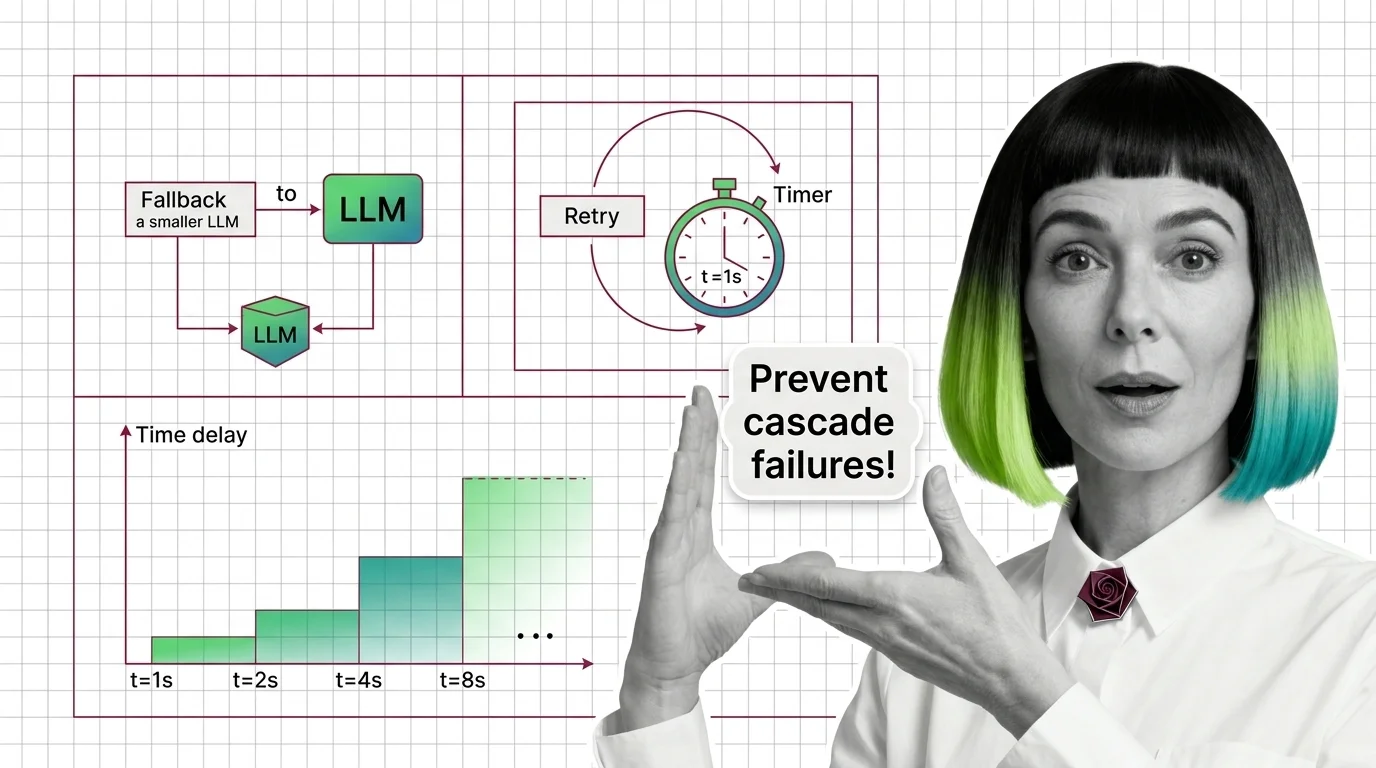
What Are LLM Fallback and Retry Patterns and How Exponential Backoff Prevents API Cascade Failures
LLM fallback and retry patterns reroute failed calls to backup models. Exponential backoff with jitter stops retry …
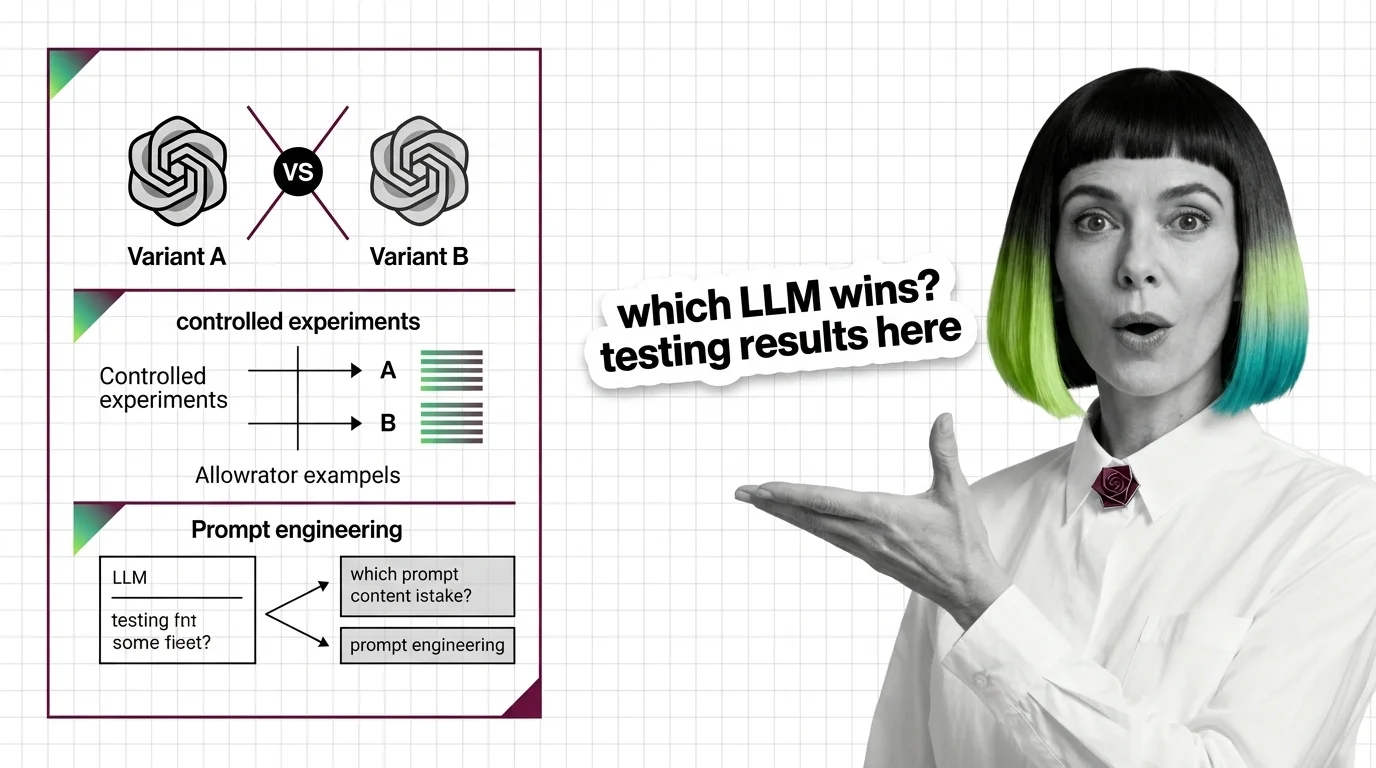
What Is A/B Testing for LLMs and How Controlled Experiments Evaluate Prompt and Model Variants
A/B testing for LLMs evaluates prompt and model variants by splitting production traffic and measuring quality, latency, …
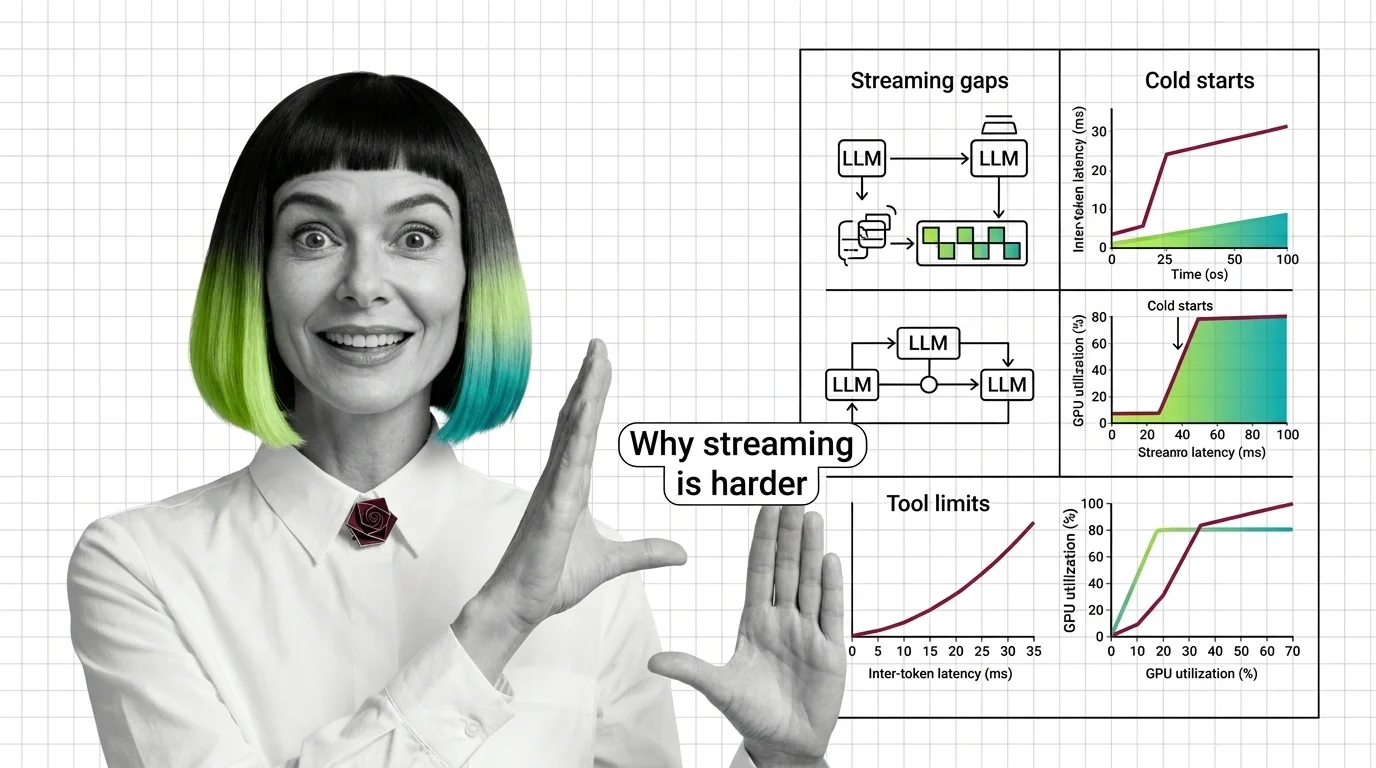
Streaming Gaps, Cold Starts, and Tool Limits: The Hard Technical Constraints of LLM Load Testing
LLM load tests fail silently on streaming gaps, KV cold starts, and tool metric inconsistencies—three flaws that make …
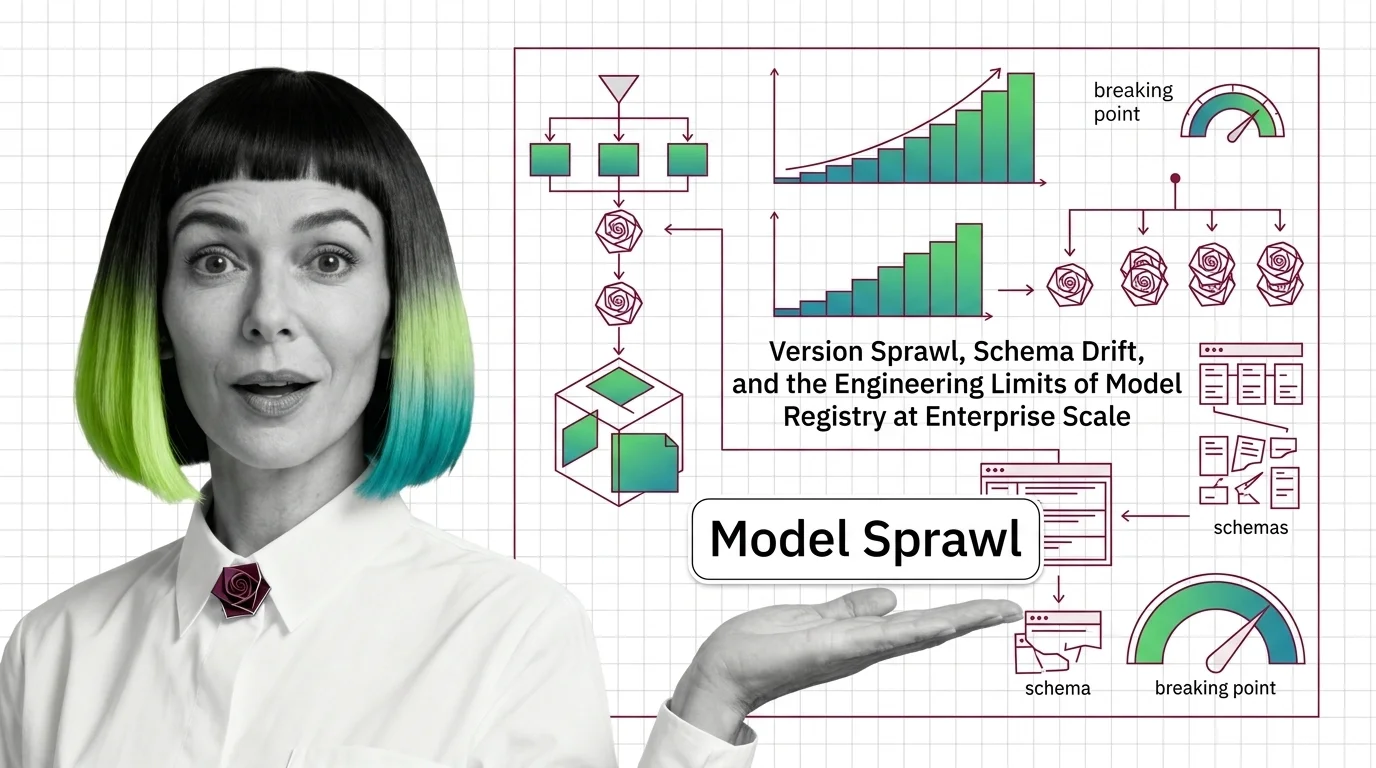
Version Sprawl, Schema Drift, and the Engineering Limits of Model Registry at Enterprise Scale
A model registry tracks versions. It does not enforce input contracts, cross-team isolation, or output schema. At scale, …
Sample Size, Statistical Power, and Why Measuring LLM Output Quality Is Harder Than Click-Through Rates
LLM output quality has up to 34% within-model variance — enough to invalidate a standard A/B test. The sample size math …
Sliding Windows, Summarization, KV Cache, and the Hard Technical Limits of Context Compression in 2026
Production LLMs use sliding windows, KV caching, and summarization to manage context. GPU memory — not token limits — …
PII Redaction, Trace Sampling, and the Technical Limits of LLM Logging at Production Scale
LLM logging at scale pits capture fidelity against PII risk and cost. Tail sampling, PII redaction, and immutable audit …
Provider Failover, Timeout Handling, and Thundering Herd: What Makes LLM Retry Logic Break
LLM retry logic breaks in a specific way: pure exponential backoff synchronizes all clients, creating a thundering herd …
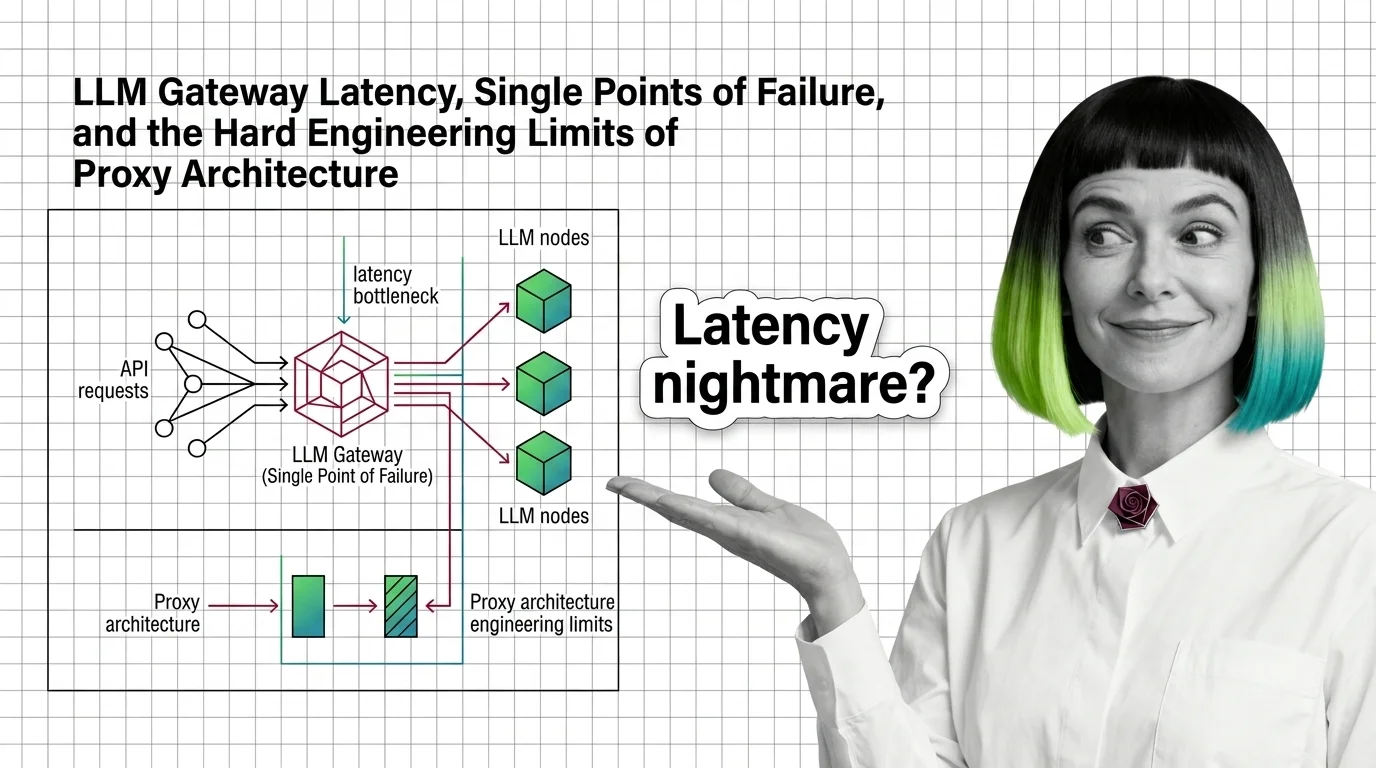
LLM Gateway Latency, Single Points of Failure, and the Hard Engineering Limits of Proxy Architecture
LLM gateways add 2–240ms overhead. Latency is rarely the bottleneck — single points of failure and security …
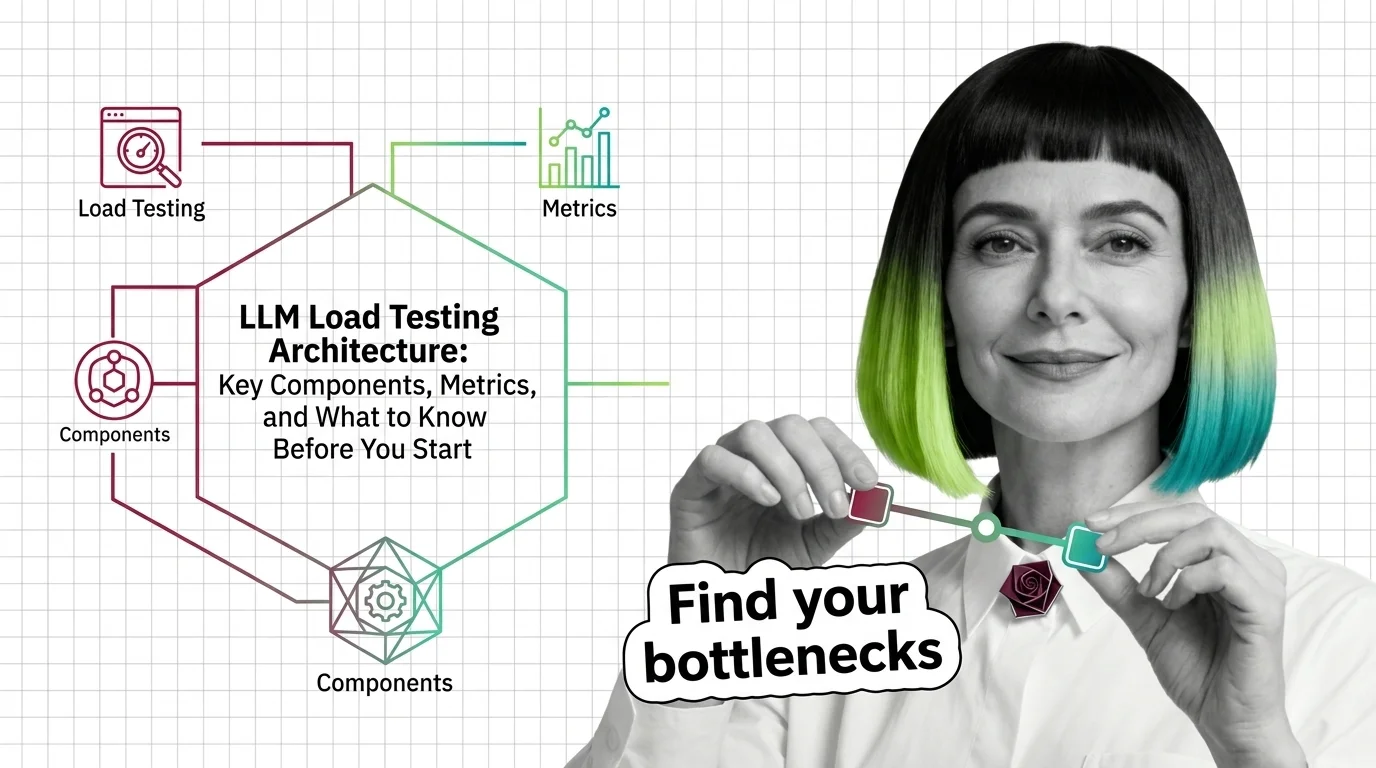
LLM Load Testing Architecture: Key Components, Metrics, and What to Know Before You Start
LLM load testing requires metrics standard tools miss. TTFT, inter-token latency, and goodput determine whether an …
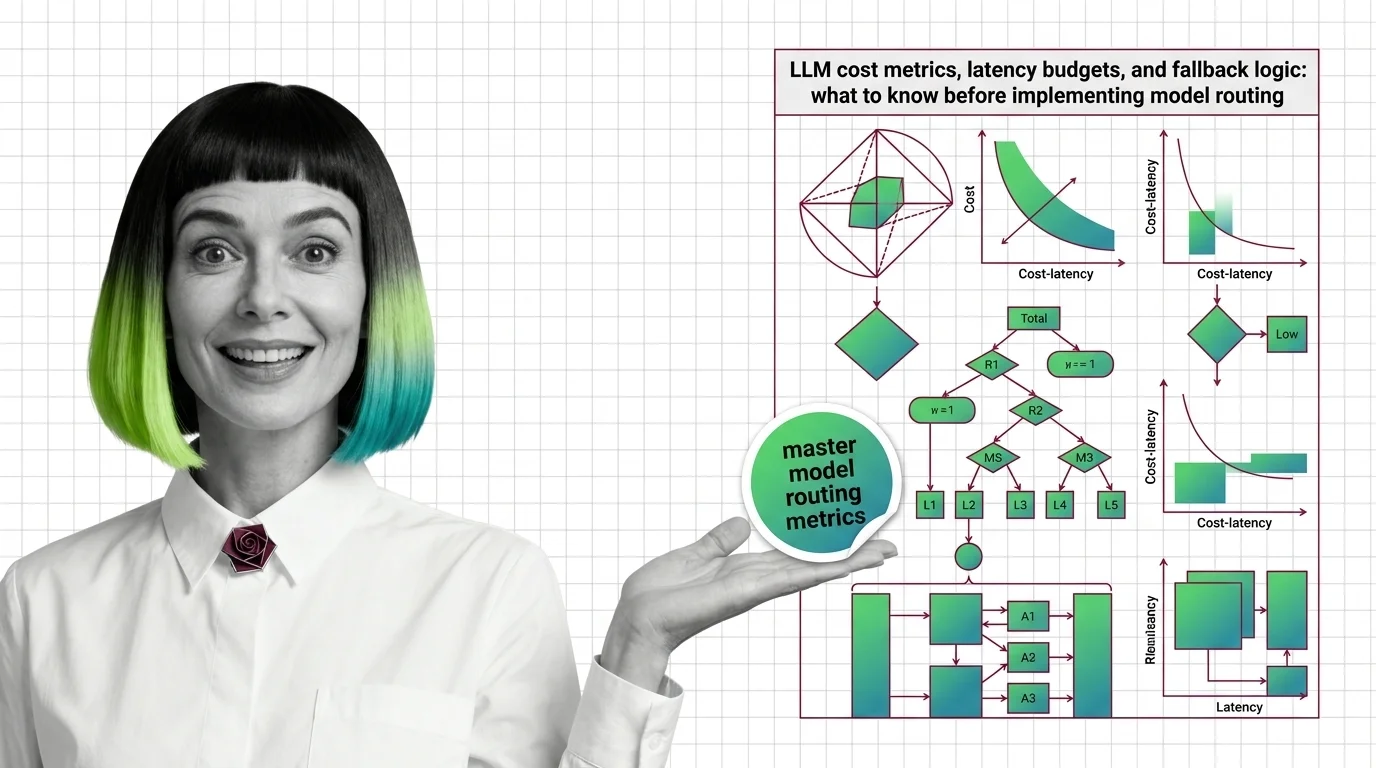
LLM Cost Metrics, Latency Budgets, and Fallback Logic: Before Implementing Model Routing
Model routing rests on three prerequisites: token cost asymmetry, P99 latency SLOs by workload, and circuit breaker …
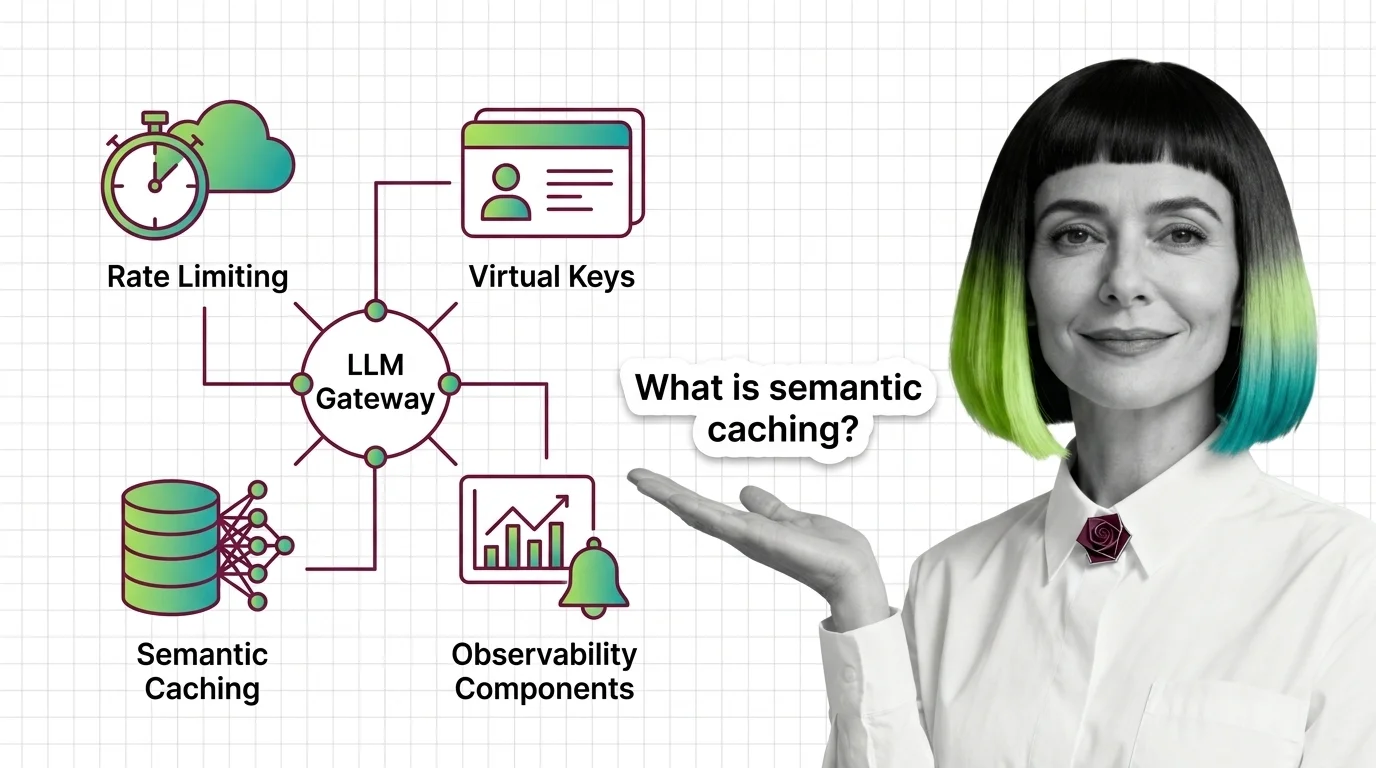
LLM Gateway Architecture: Rate Limiting, Virtual Keys, Semantic Caching, and Observability Components
LLM gateways govern AI traffic via four components: rate limiting (RPM/TPM/budget), scoped virtual keys, semantic …
Before You Monitor LLMs: MLOps Prerequisites and the Technical Limits No Observability Tool Can Fix
LLM observability needs baselines before the first trace. No tool prevents hallucinations or non-deterministic output — …
Context Windows, KV Cache, and Model Pricing: Prerequisites for Optimizing LLM Spend
LLM API cost optimization requires understanding KV cache mechanics, input/output token asymmetry, and prompt caching …
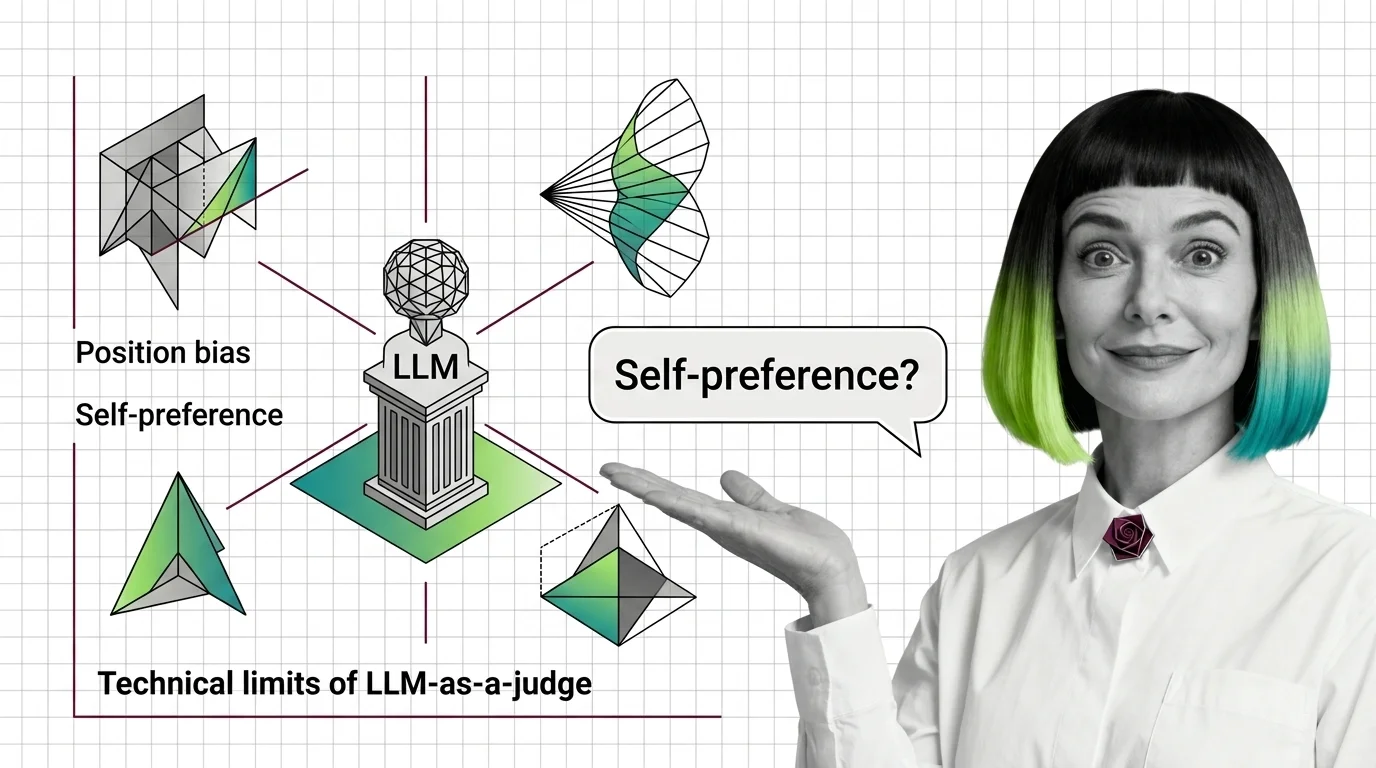
Position Bias, Self-Preference, and the Technical Limits of LLM-as-a-Judge
LLM-as-a-judge shows systematic position bias and self-preference: GPT-4 flips its verdict on ~35% of pairs when answer …
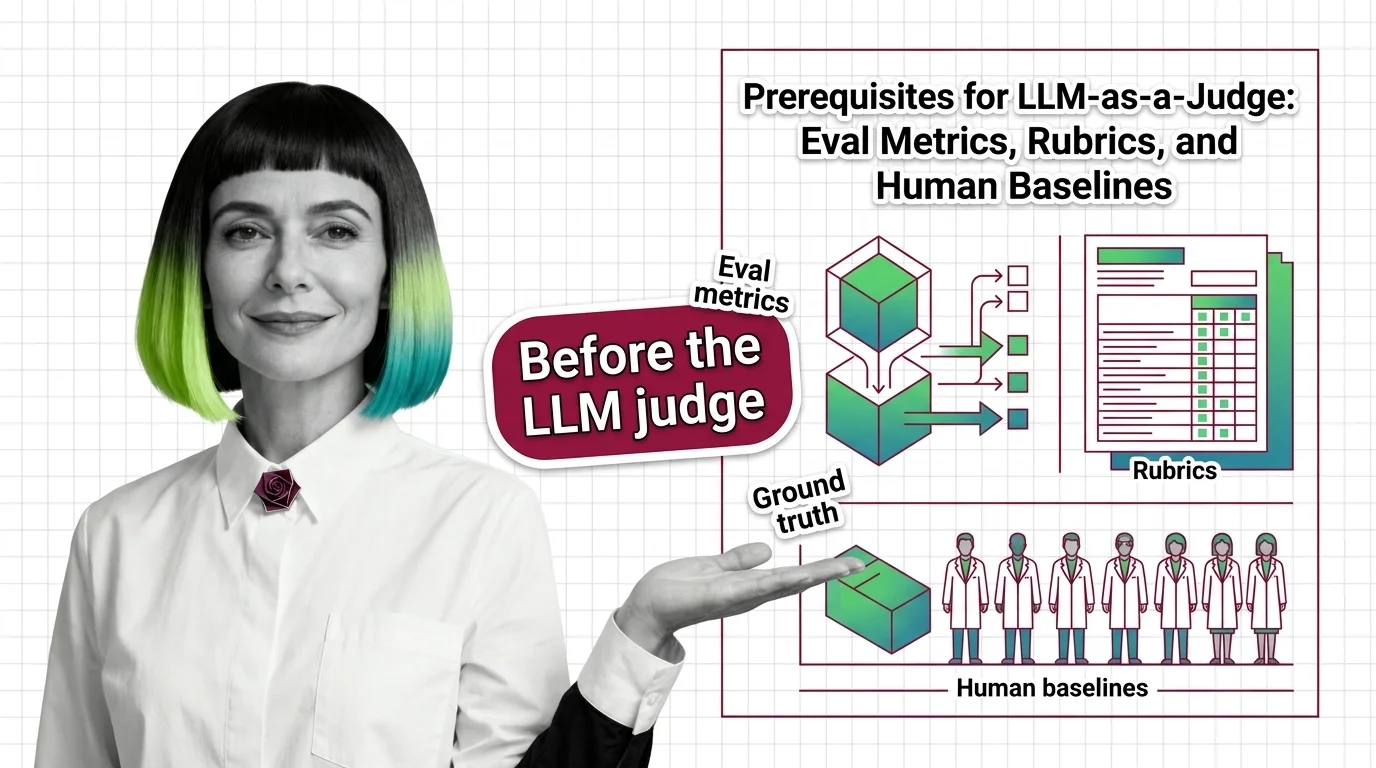
Prerequisites for LLM-as-a-Judge: Eval Metrics, Rubrics, and Human Baselines
An LLM-as-a-judge is only as reliable as its scaffolding: ground-truth labels, rubrics, and a human baseline. GPT-4 …
What Is LLM-as-a-Judge and How One Model Scores Another's Outputs
LLM-as-a-judge uses one model to grade another's output via pointwise, pairwise, or rubric scoring. Fast, but prone to …
Prerequisites for Reading AI Benchmark Scores: Metrics, Pass@k, and Contamination
AI benchmark scores hide three variables: what the metric counts, the pass@k sampling regime, and whether the test …
Saturation, Contamination, and Construct Validity: The Technical Limits of AI Benchmarks
AI benchmarks fail through saturation, contamination, and construct validity. Decontamination cut HumanEval scores …
What Are Benchmark Datasets and How GLUE, MMLU, and SWE-bench Measure LLM Performance
Benchmark datasets are fixed test sets that score and rank LLMs. MMLU's 15,908 questions and SWE-bench's 2,294 GitHub …
Model Collapse, Fidelity Gaps, and Re-Identification: The Technical Limits of Synthetic Data
Synthetic data faces three hard limits: model collapse from recursive training, fidelity-privacy tradeoffs, and …
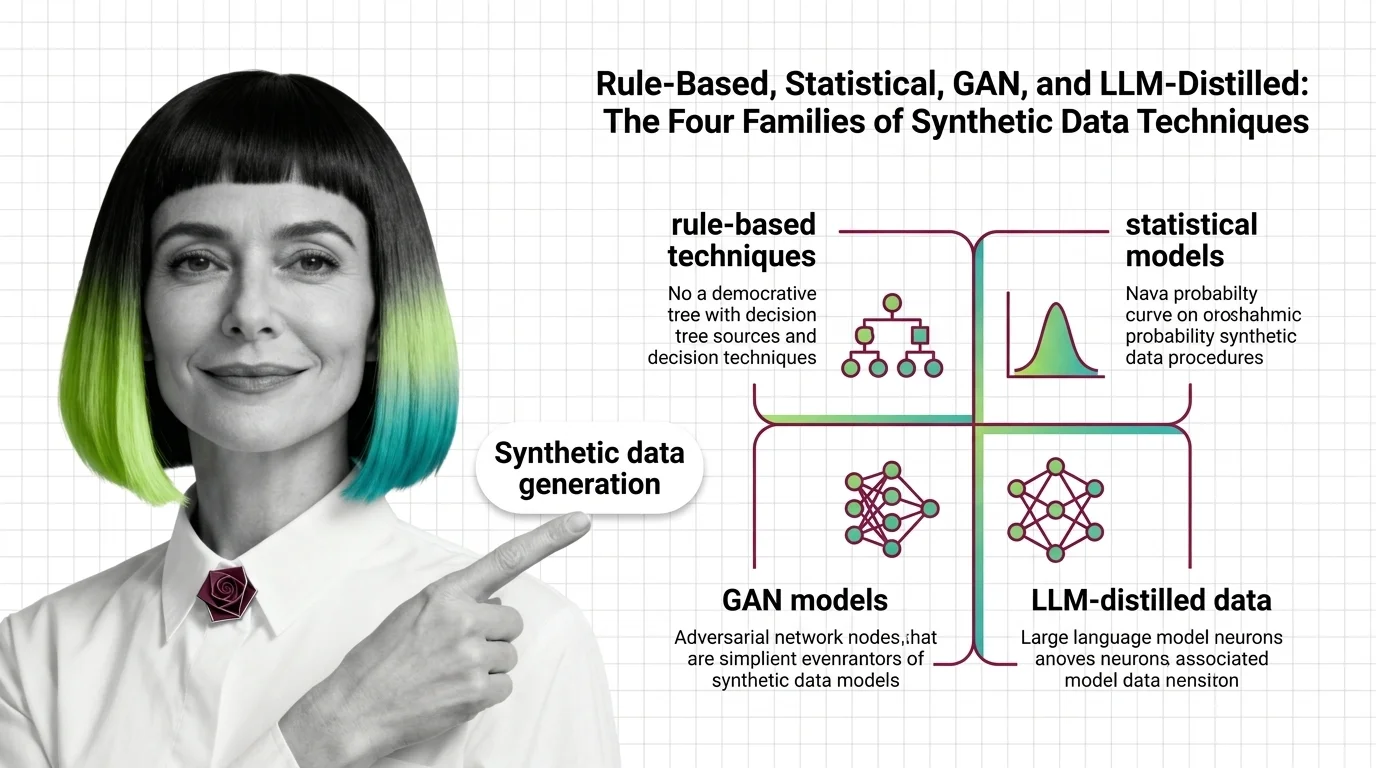
Rule-Based, Statistical, GAN, and LLM-Distilled: The Four Families of Synthetic Data Techniques
Synthetic data generation spans four families — rule-based, statistical, GAN-based, and LLM-distilled — each preserving …
What Is Synthetic Data Generation and How Artificial Training Data Is Created
Synthetic data generation creates artificial records that mimic a dataset's statistics without reusing real rows, via …
Before Active Learning: Prerequisites, Building Blocks, and the Hard Limits of Query Strategies
Active learning lets a model pick which examples to label instead of sampling at random — but sampling bias and …
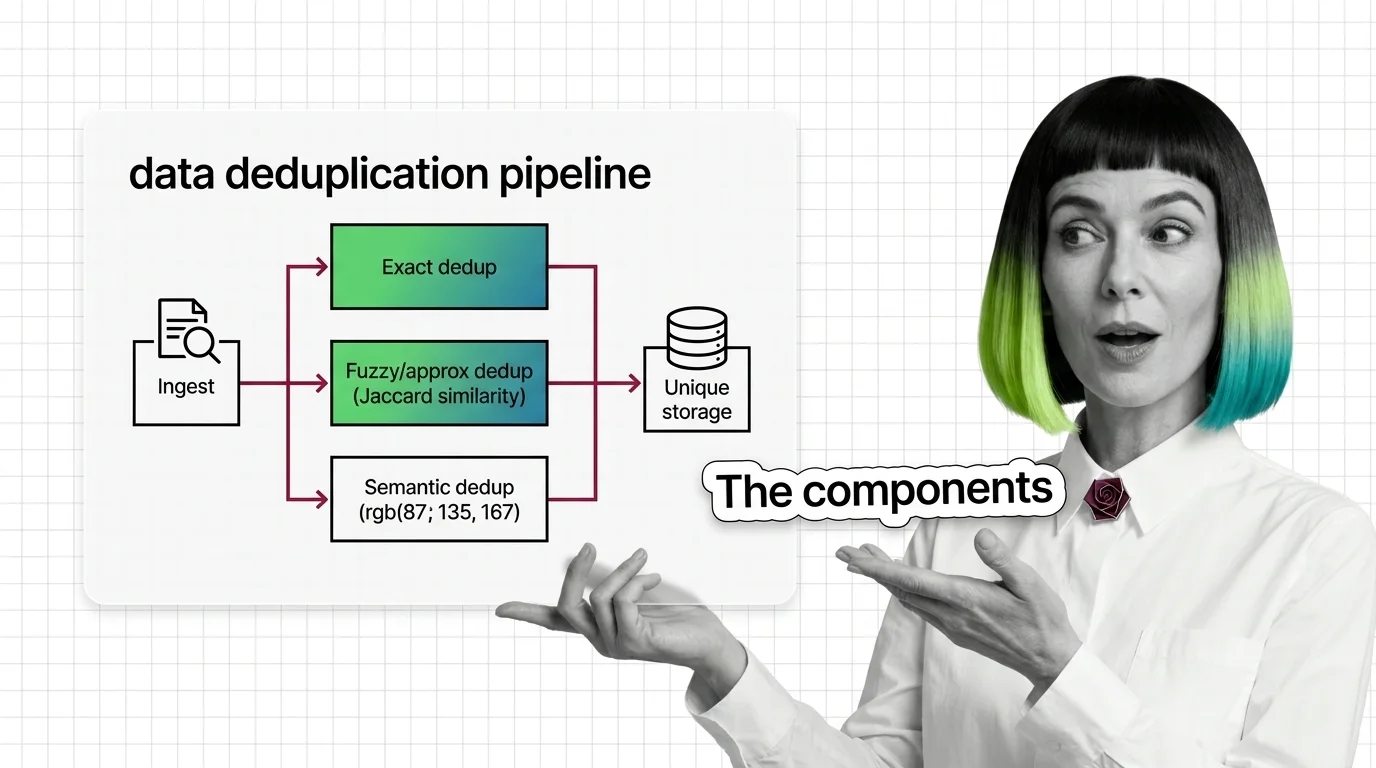
Exact, Fuzzy, and Semantic Deduplication: The Components and Prerequisites of a Dedup Pipeline
Data deduplication runs in three tiers: exact (hashing), fuzzy (MinHash+LSH), and semantic (embeddings). SemDeDup …
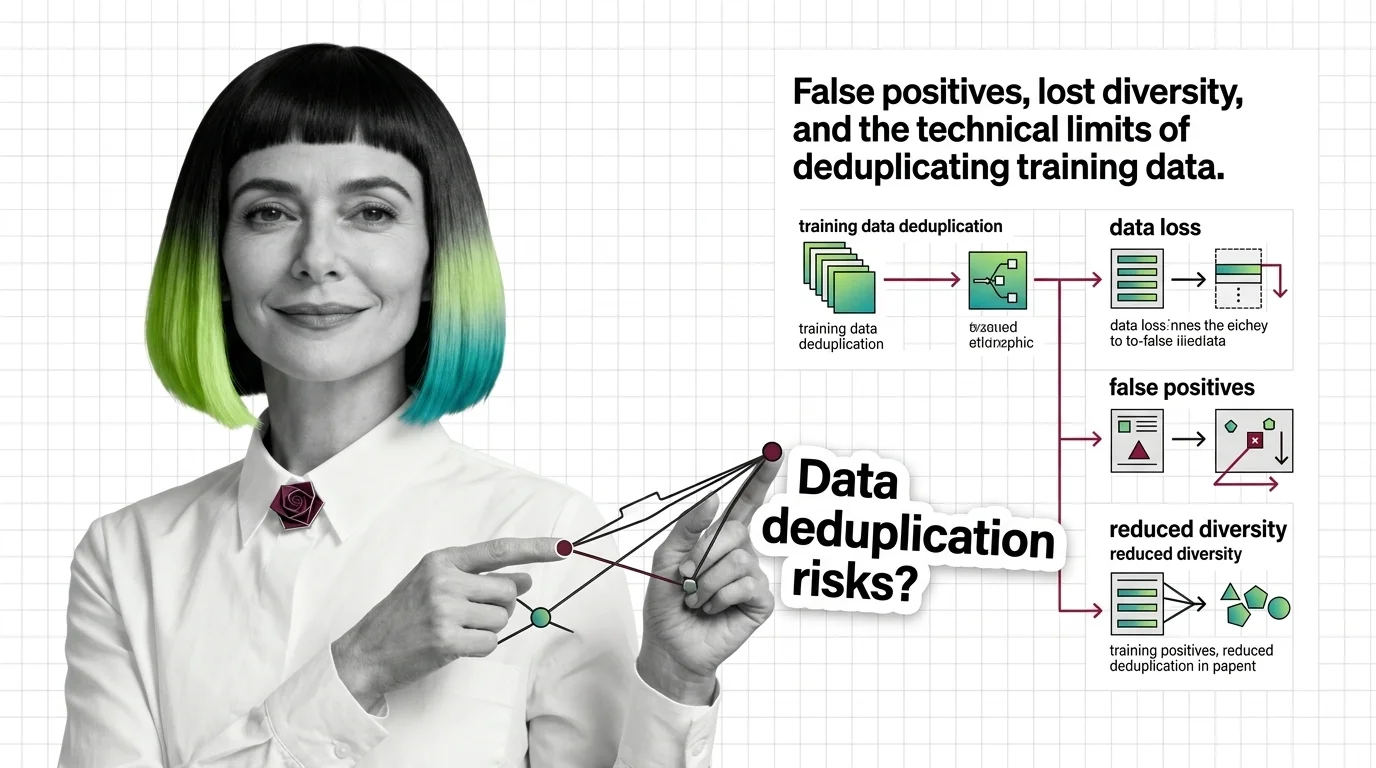
False Positives, Lost Diversity, and the Technical Limits of Deduplicating Training Data
Data deduplication measures surface overlap, not meaning, so it deletes rare examples as false positives and misses …