Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
False Positives, Delayed Labels, and the Technical Limits of Data Drift Detection
Data drift detection produces false alarms because statistical tests over-fire on large samples, while performance loss …
Backdoor Triggers, Clean-Label, and Label-Flipping: Why Poisoned Data Evades Detection
Backdoor triggers, clean-label, and label-flipping are three data poisoning vectors that corrupt ML models while evading …
Why Prompts Break: Context Window Ceilings, Phrasing Sensitivity, and the Technical Limits of Prompt Engineering in 2026
Prompt engineering has architectural failure points: position bias drops recall 30%+ in long contexts, and prompts …
What Is Prompt Chaining and How Sequential LLM Calls Enable Complex AI Reasoning
Prompt chaining sequences multiple LLM calls where each output feeds the next. Mechanism, building blocks, and failure …
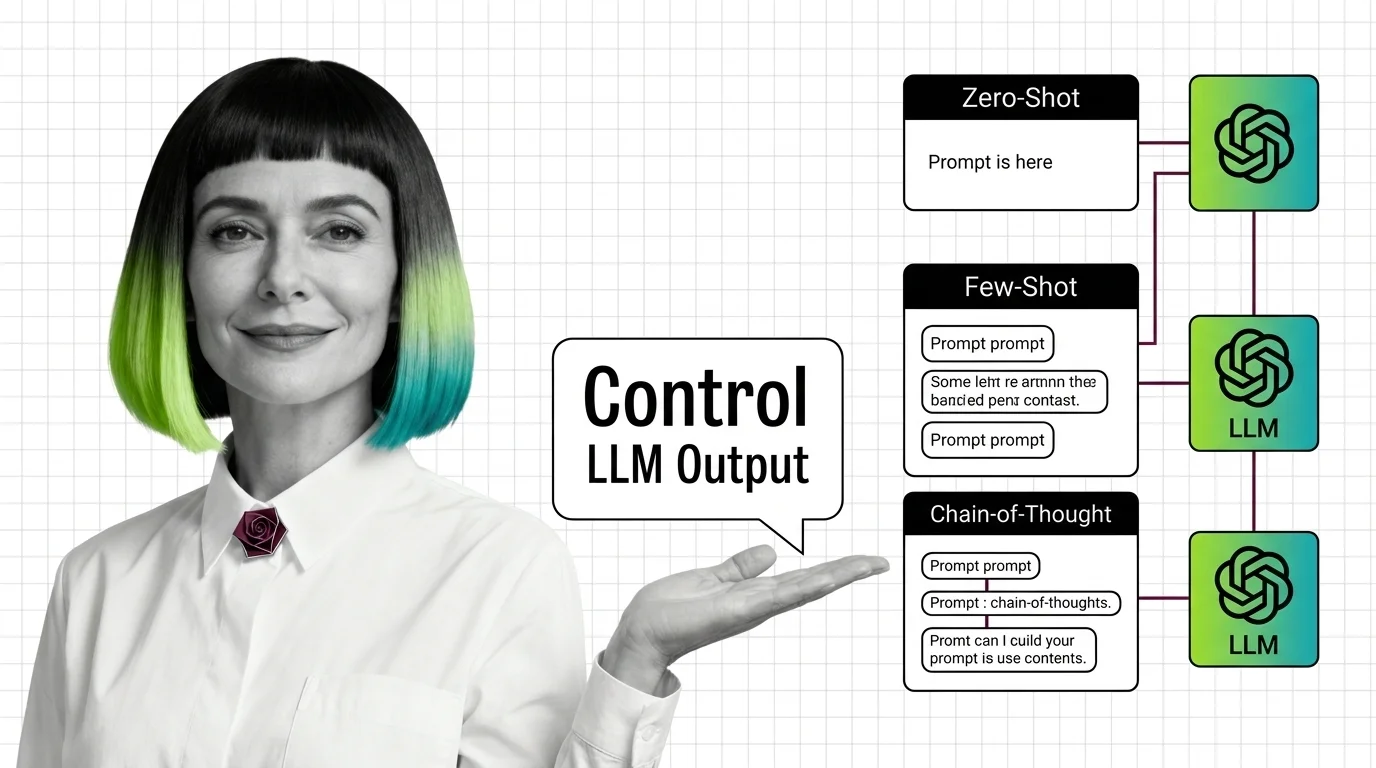
What Is Prompt Engineering and How Zero-Shot, Few-Shot, and Chain-of-Thought Techniques Control LLM Output
Prompt engineering structures LLM inputs to control output without retraining. Three core techniques: zero-shot, …
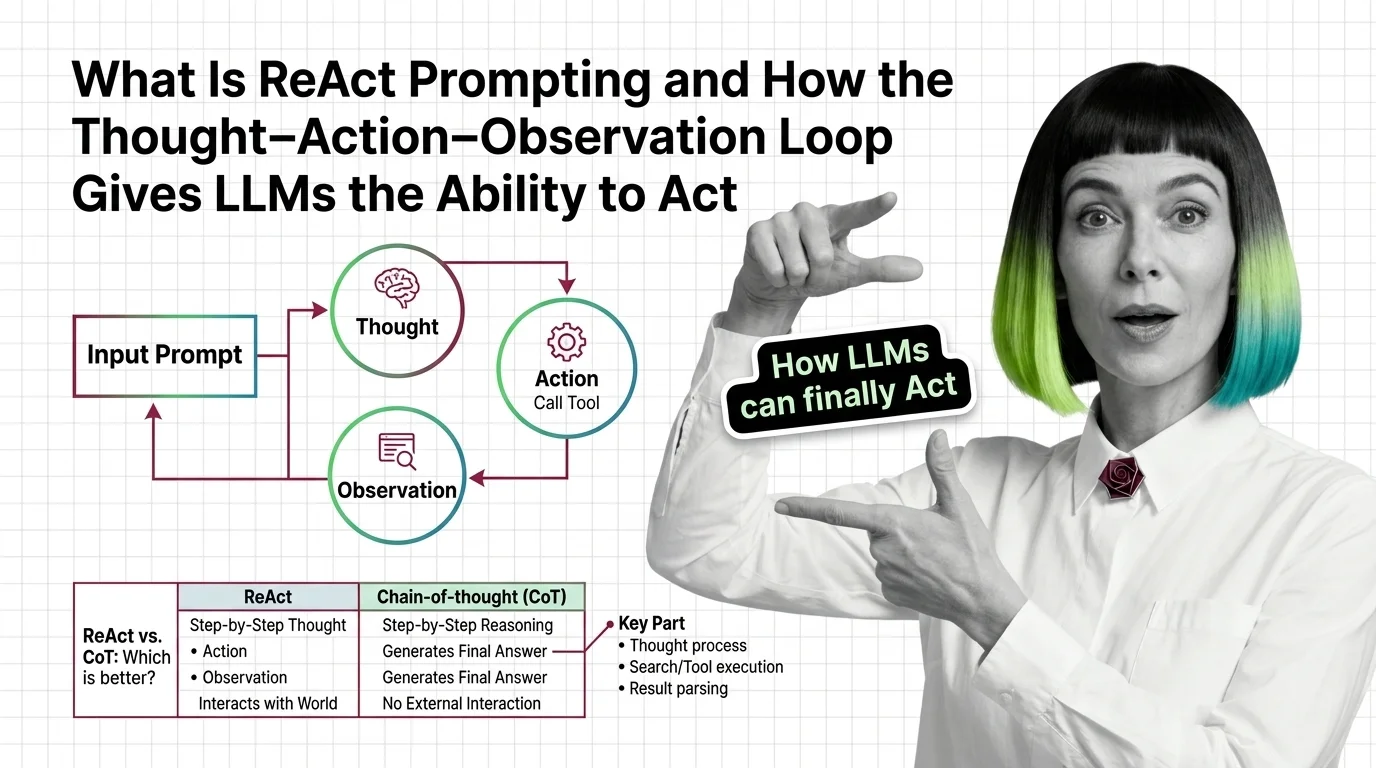
What Is ReAct Prompting and How the Thought–Action–Observation Loop Gives LLMs the Ability to Act
ReAct prompting interleaves LLM reasoning with real-world tool calls. Published at ICLR 2023, it improved agentic task …
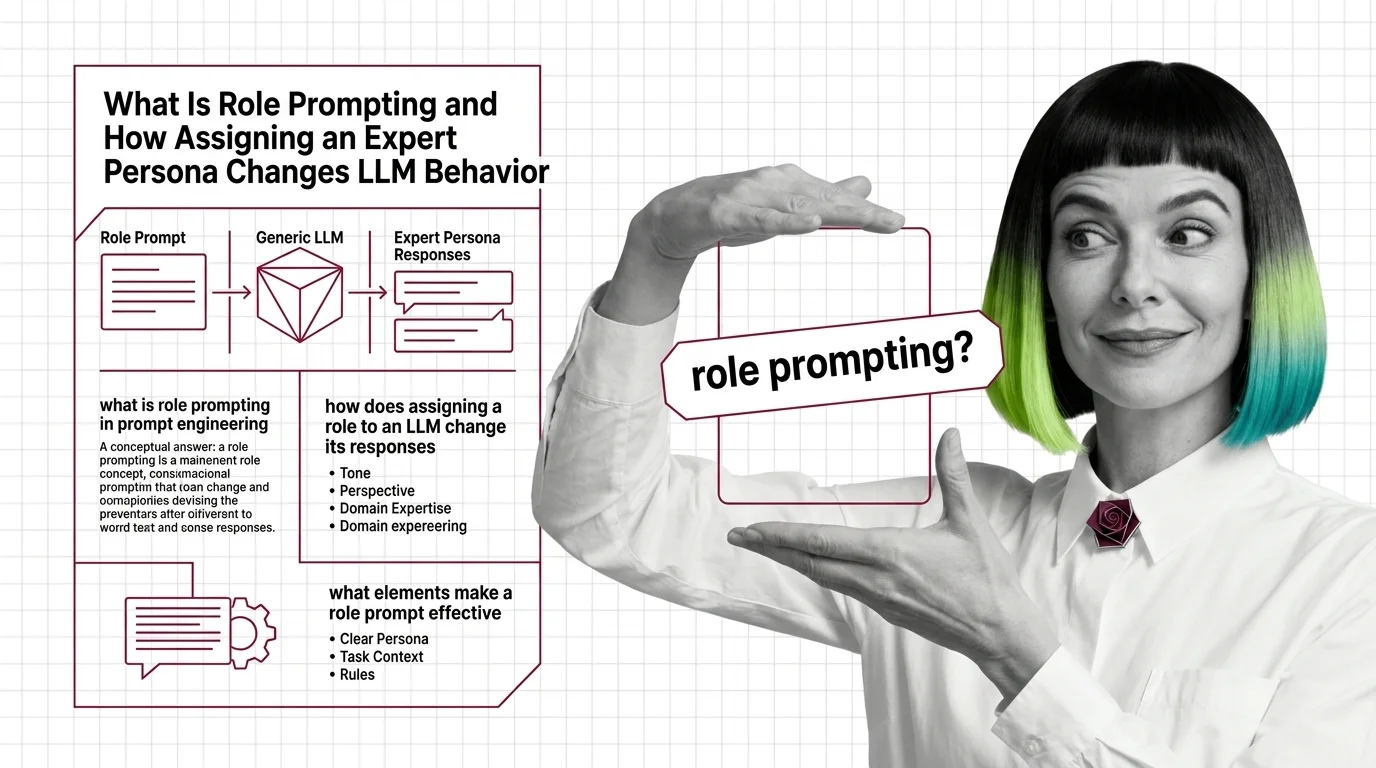
What Is Role Prompting and How Assigning an Expert Persona Changes LLM Behavior
Role prompting assigns an expert persona via the system prompt, shifting how an LLM samples tokens. It helps advisory …
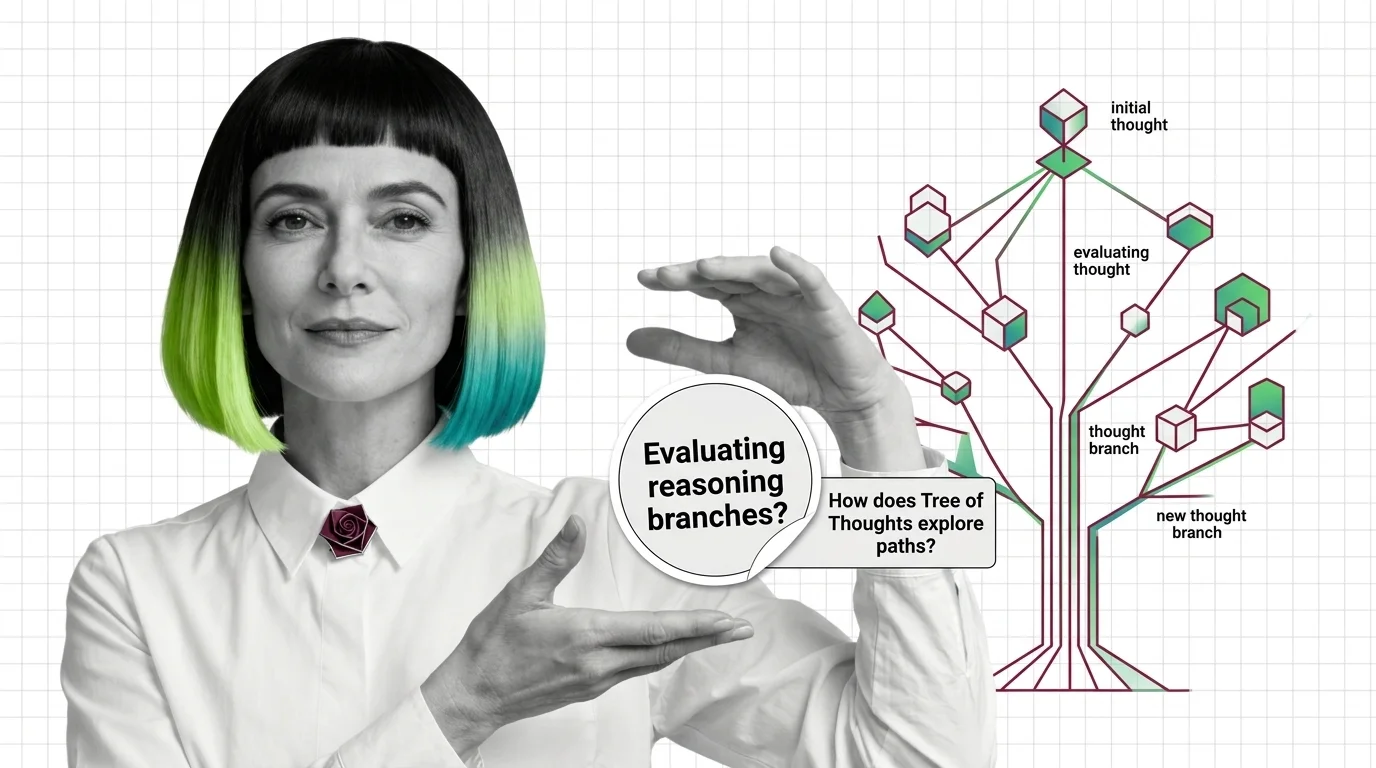
What Is Tree of Thoughts and How It Extends Chain-of-Thought Reasoning
Tree of Thoughts extends chain-of-thought via BFS/DFS search over reasoning branches. Yao et al. (NeurIPS 2023) showed …
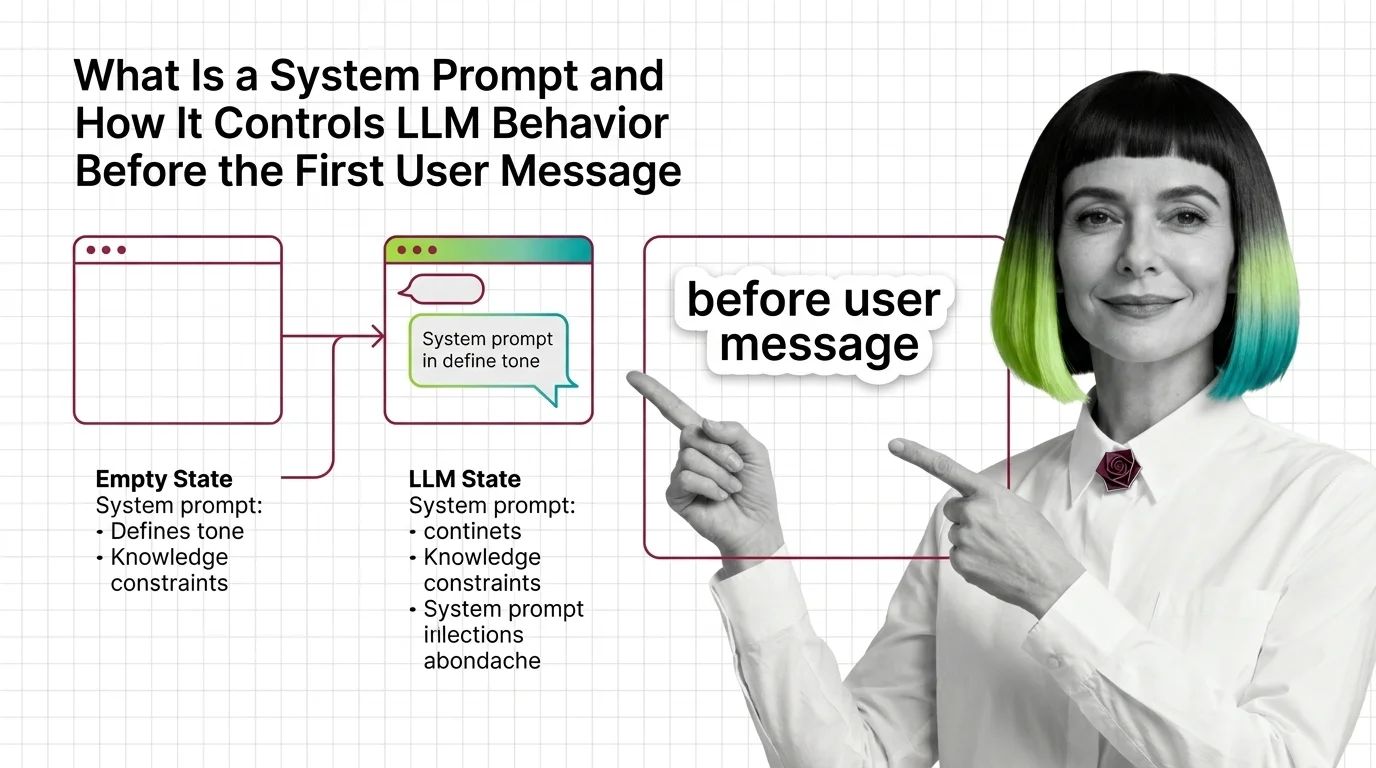
What Is a System Prompt and How It Controls LLM Behavior Before the First User Message
System prompts configure LLM identity, guardrails, and output format before any user message. They outrank user input in …
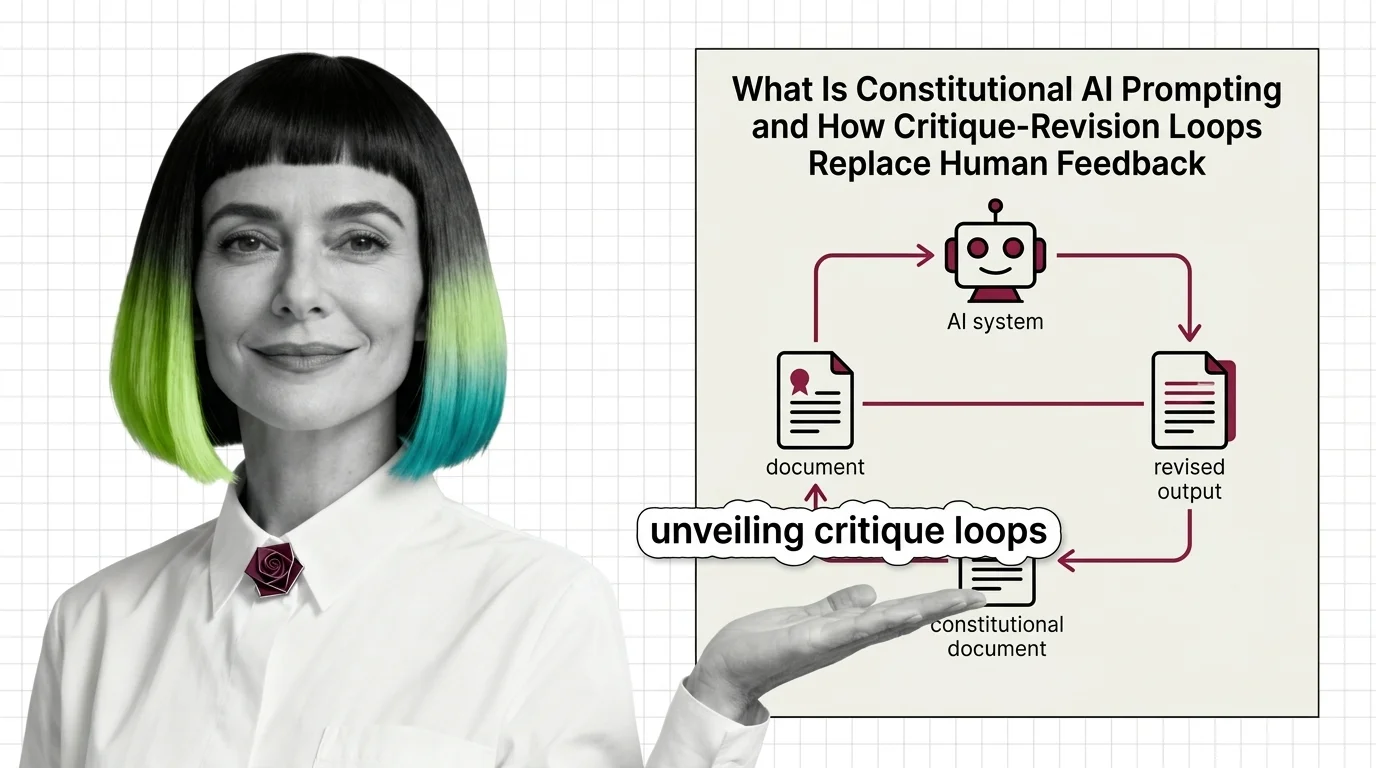
What Is Constitutional AI Prompting and How Critique-Revision Loops Replace Human Feedback
Constitutional AI prompting is a critique-revision loop: a model checks its own outputs against explicit principles, …
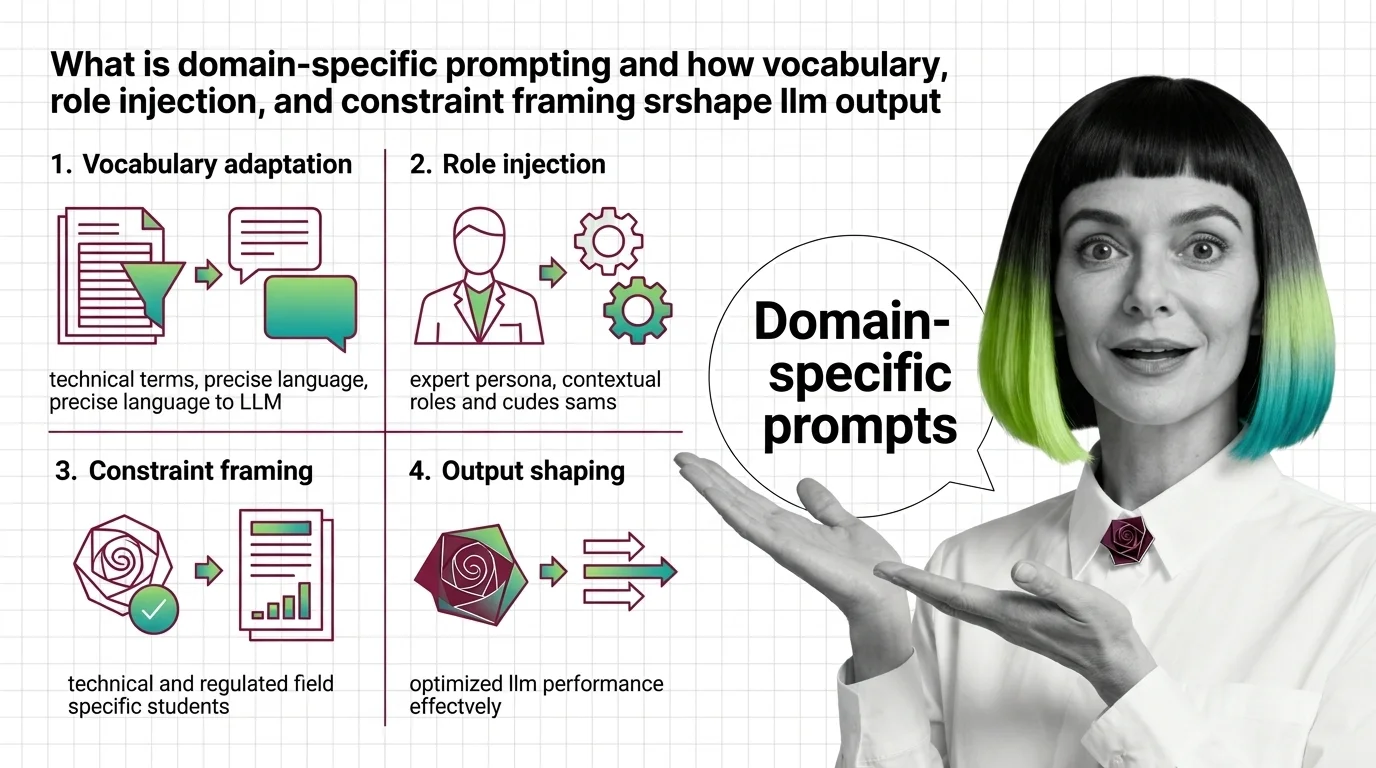
What Is Domain-Specific Prompting and How Vocabulary, Role Injection, and Constraint Framing Shape LLM Output
Domain-specific prompting adapts LLM output per field via vocabulary, role, and constraints — no retraining. Prompt …
What Is Multi-Turn Prompt Design and How Context Accumulates Across LLM Turns
Multi-turn prompt design passes full message history as tokens on every API call. Context accumulates linearly until the …
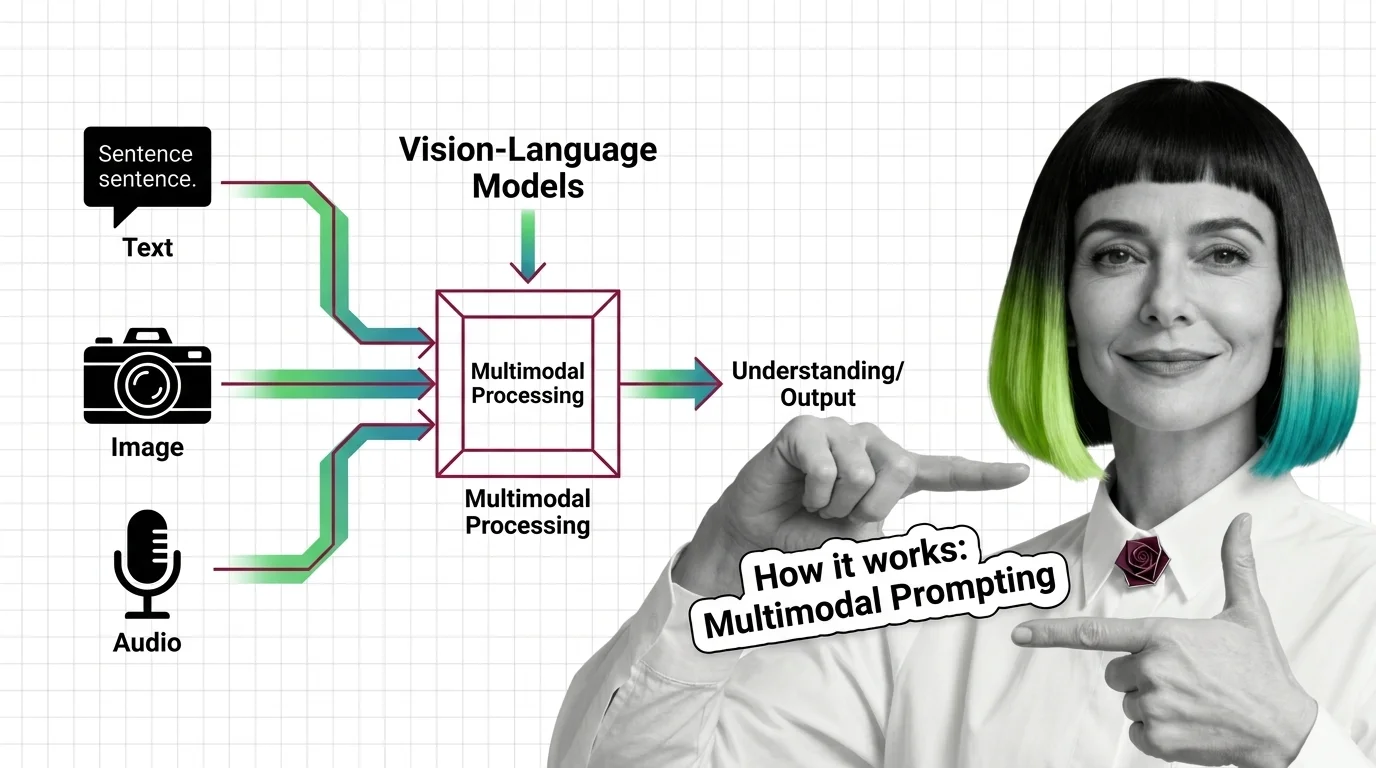
What Is Multimodal Prompting and How Vision-Language Models Process Images, Audio, and Text Together
Multimodal prompting sends images or audio alongside text in one query. A VLM encodes each image as patch tokens, then …
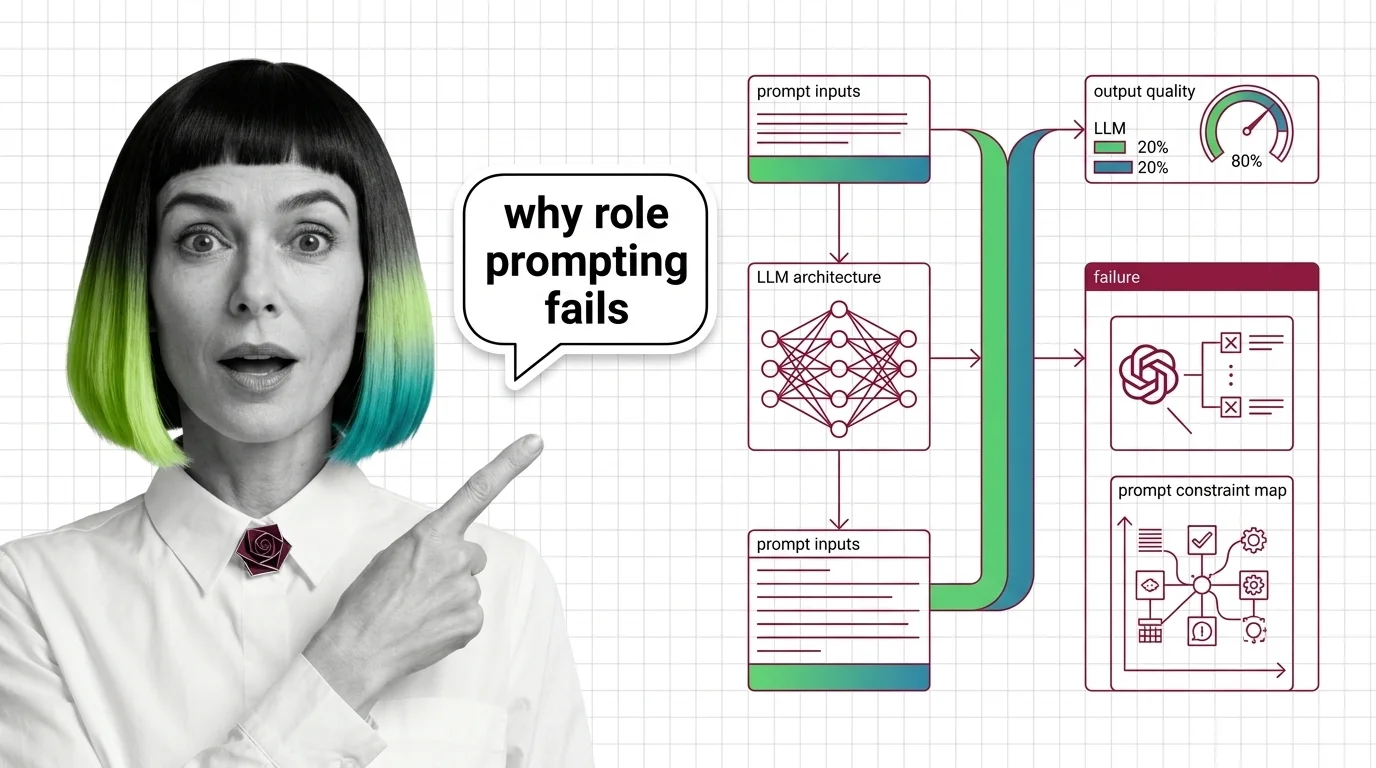
Prerequisites for Role Prompting and When It Technically Fails
Role prompting shifts LLM tone reliably but gains ~0.01% accuracy on factual benchmarks. Expert personas degrade …
System Prompts, Role Instructions, and Output Constraints: Anatomy of a Production Prompt
A production LLM prompt has four layers: instruction, context, input data, and output indicator. The layer you ignore is …
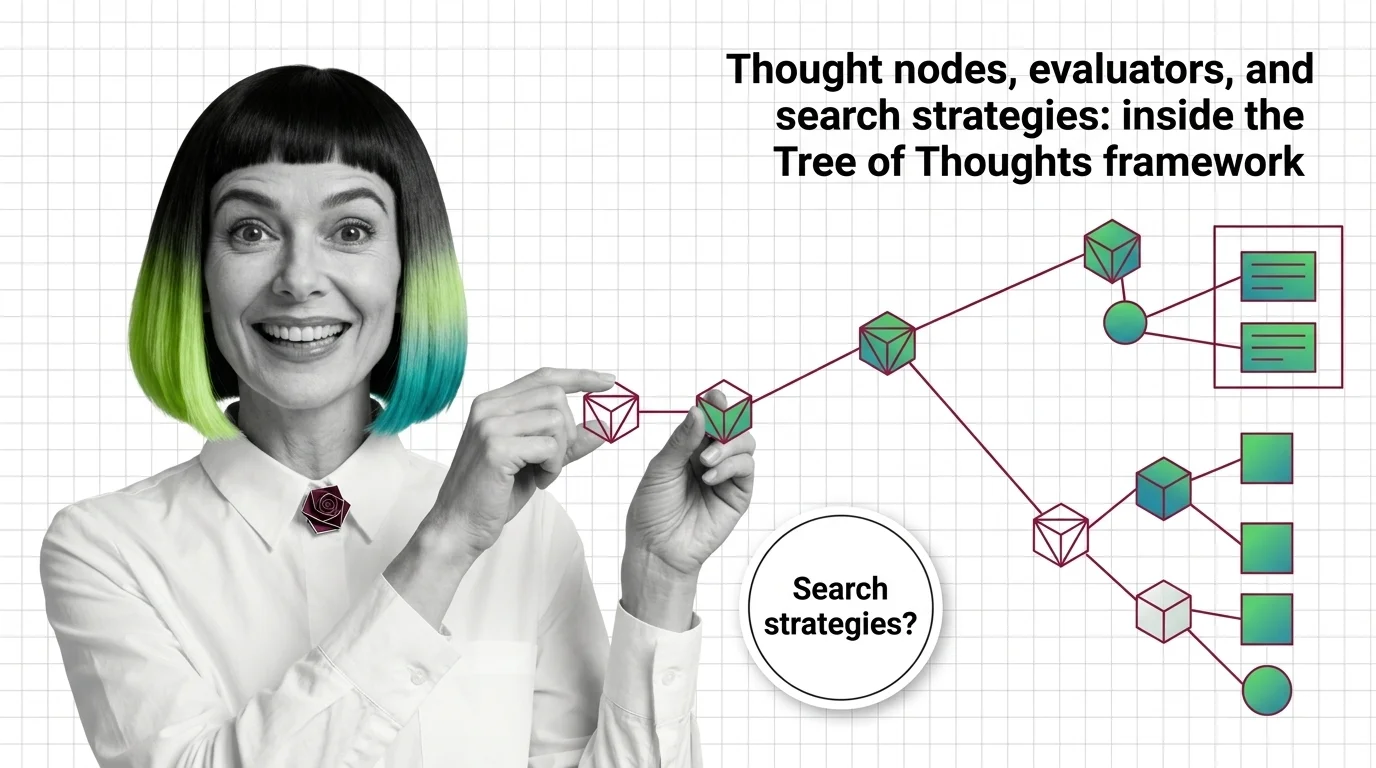
Thought Nodes, Evaluators, and Search Strategies: Inside the Tree of Thoughts Framework
Tree of Thoughts gives LLMs branching search via four components and two algorithms. GPT-4 scored 74% on Game of 24 — …
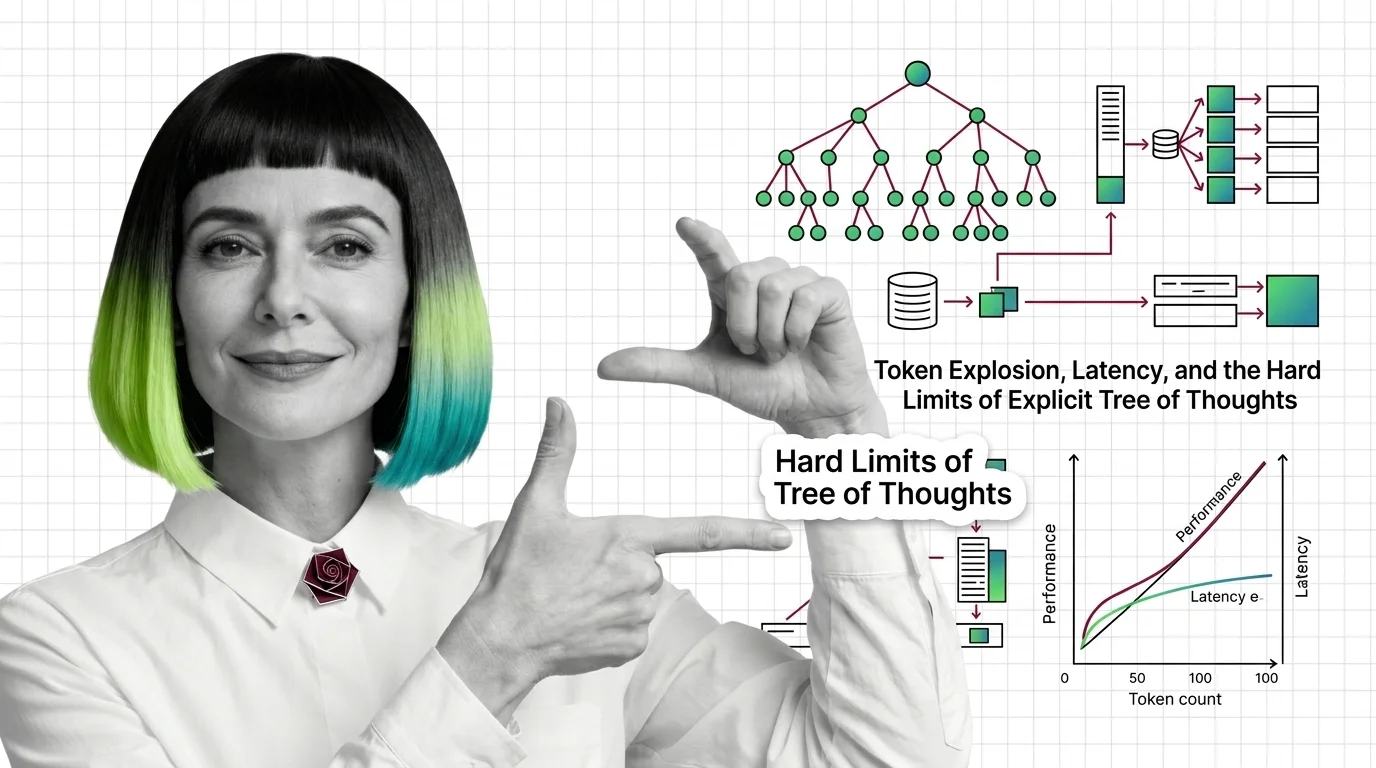
Token Explosion, Latency, and the Hard Limits of Explicit Tree of Thoughts
Tree of Thoughts uses 5–100× more tokens than CoT. On Game of 24, ToT hits 74% vs CoT's 4% — but at equal token budgets, …
Visual Hallucination, Resolution Caps, and the Unsolved Technical Limits of Multimodal Prompting in 2026
Two hallucination types explain why multimodal AI invents absent image details. Resolution caps and language priors are …
Context Rot, Lost-in-the-Middle, and the Hard Technical Limits of Multi-Turn LLM Conversations
LLMs degrade in multi-turn conversations via attention dilution, position bias, and context rot — degradation begins …
Context Windows, Token Budgets, and Why System Prompts Longer Than 300 Words Backfire
LLM position bias drops accuracy 30%+ when instructions sit mid-context — explaining why system prompts beyond 300 words …
Conversation History, Memory Layers, and the Prerequisites for Multi-Turn LLM Design
LLM conversation APIs are stateless: full history is re-injected on every call. Semantic, episodic, and procedural …
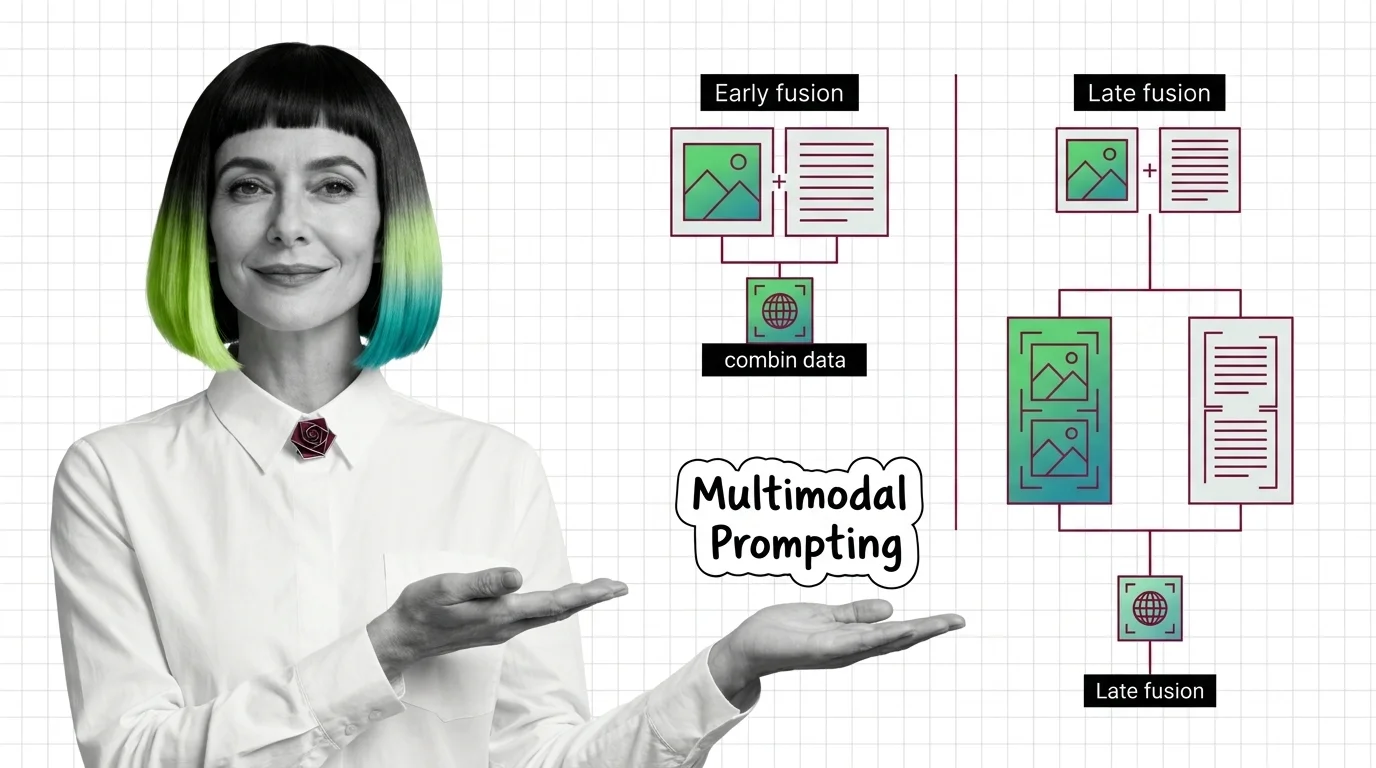
Early Fusion, Late Fusion, and What You Must Understand Before Writing Multimodal Prompts
Early fusion processes image and text tokens from layer one; late fusion merges at output only. Architecture determines …
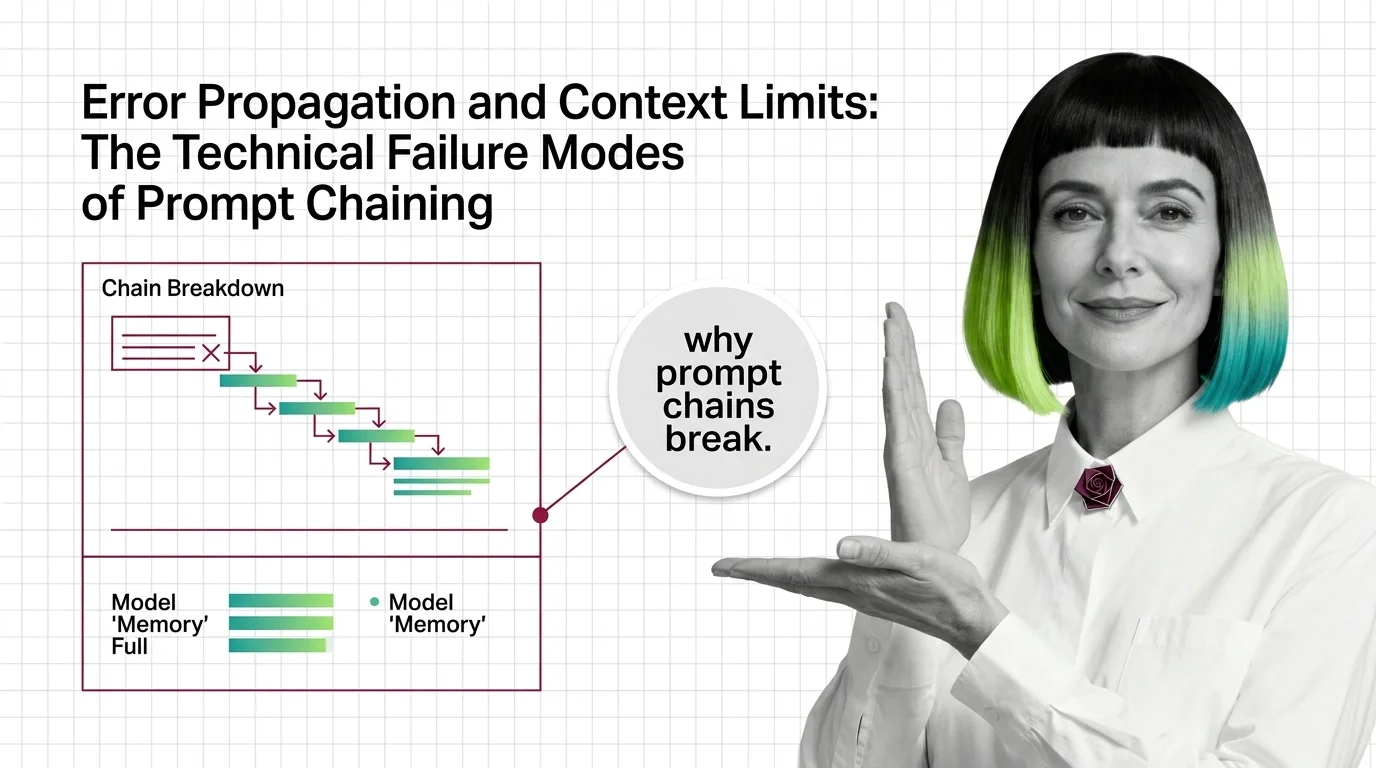
Error Propagation and Context Limits: The Technical Failure Modes of Prompt Chaining
Prompt chaining fails when early errors compound downstream and attention degrades at mid-context — accuracy drops …
Before Constitutional AI Prompting: Core Concepts and the Technical Limits of Self-Critique Loops
Constitutional AI prompting adapts Anthropic's CAI training method for runtime self-critique. Understand prerequisites …
Before You Build a ReAct Agent: Prerequisite Concepts and Technical Failure Modes Explained
ReAct pairs reasoning with tool calls in a loop. Context rot, exemplar mismatch, and token growth are failure modes that …
Before You Prompt a Doctor or Lawyer: Prerequisites and Hard Technical Limits of Domain-Specific Prompting
Domain-specific prompting shapes LLM behavior, not what it knows. Medical-specialized LLMs still hallucinate in up to …
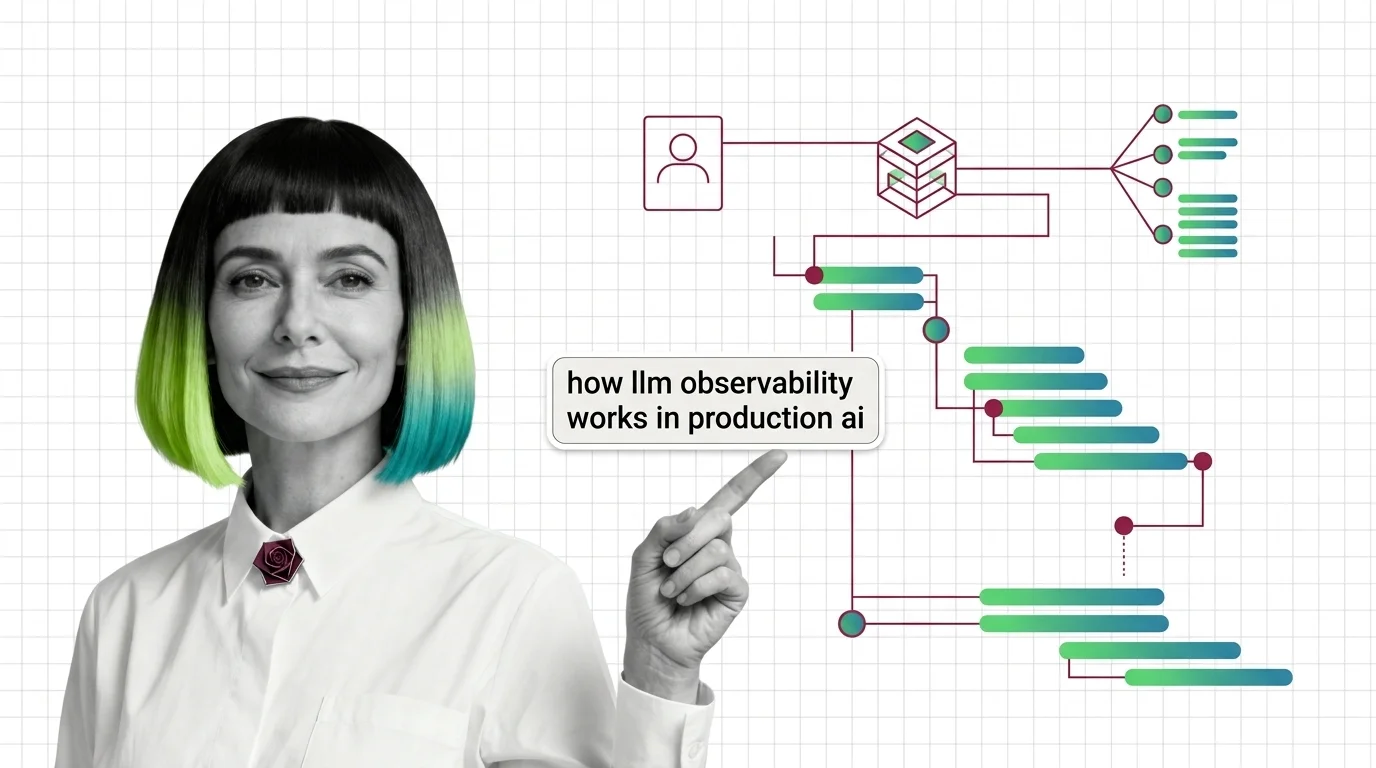
What Is LLM Observability and How Span-Based Tracing Captures Every Step of a Prompt Chain
LLM observability applies distributed tracing to AI chains. Five span types (LLM, Task, Workflow, Tool, Agent) give each …
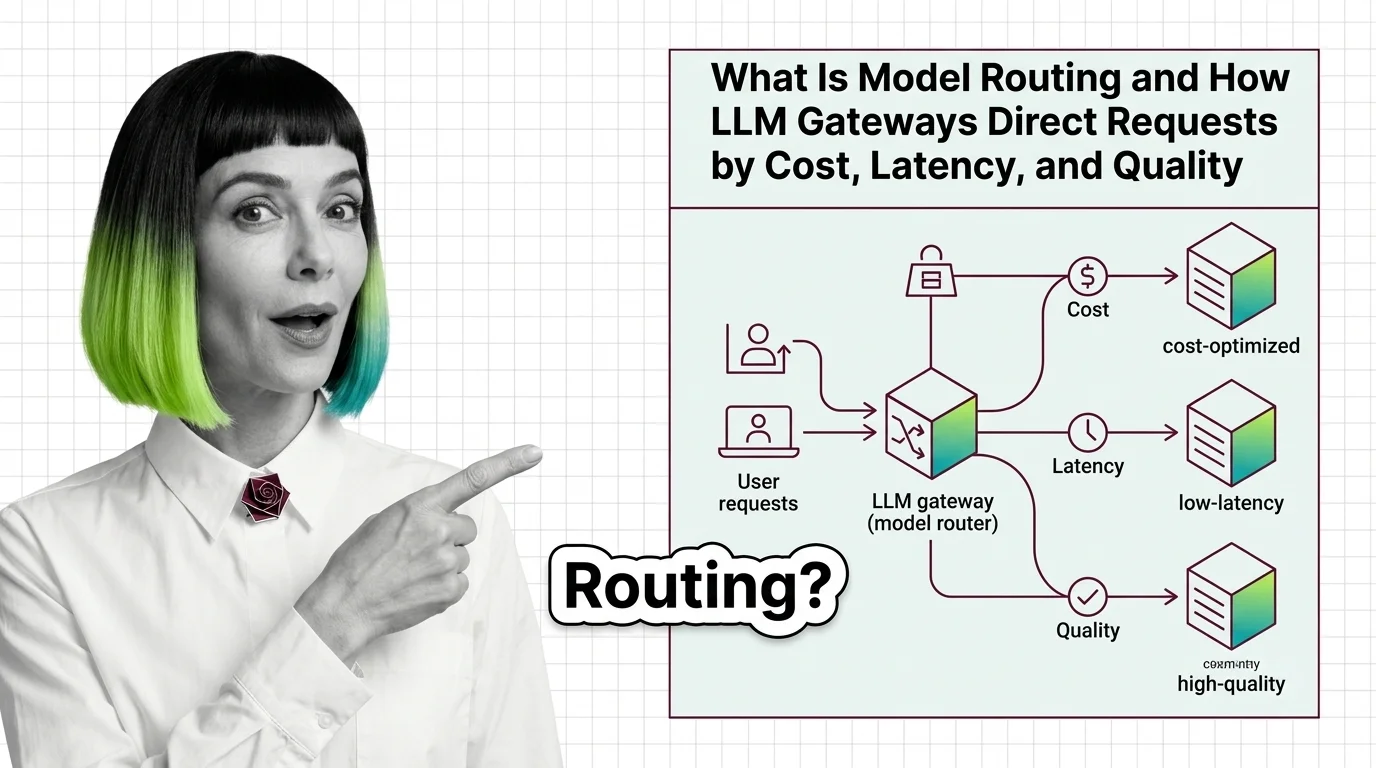
What Is Model Routing and How LLM Gateways Direct Requests by Cost, Latency, and Quality
Model routing is a decision layer between your app and multiple LLMs that directs each request to the optimal model by …
What Is LLM Cost Management and How Token-Based Pricing Scales in Production
LLM cost management controls token-based API costs at production scale. Output tokens cost 2–6× more than input; …
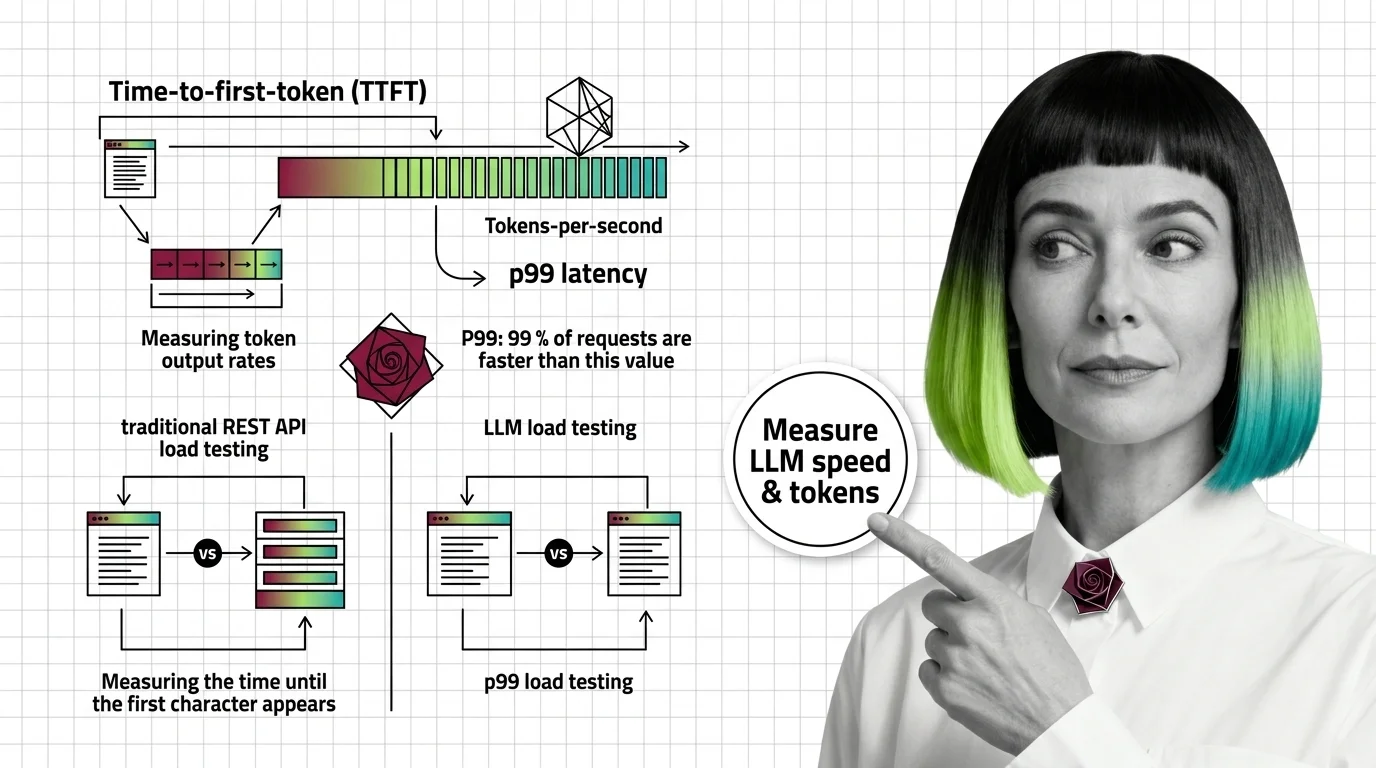
What Is LLM Load Testing and How TTFT, Tokens-Per-Second, and p99 Latency Are Measured
LLM load testing measures TTFT, TPS, and p99 latency under concurrent load. KV-cache GPU memory—not CPU threads—is the …