Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
Evaluation Metrics, Test Datasets, and LLM Judges: The Parts of a Prompt Evaluation System
A prompt evaluation system has three parts: metrics that define quality, test datasets exposing failure modes, and LLM …
Context Costs, Wrong Parameters, and the Hard Limits of LLM Tool Calling
LLM tool schemas vary by provider and add hidden token overhead. Task accuracy peaks near 77% (BFCL v3, 2026) — well …
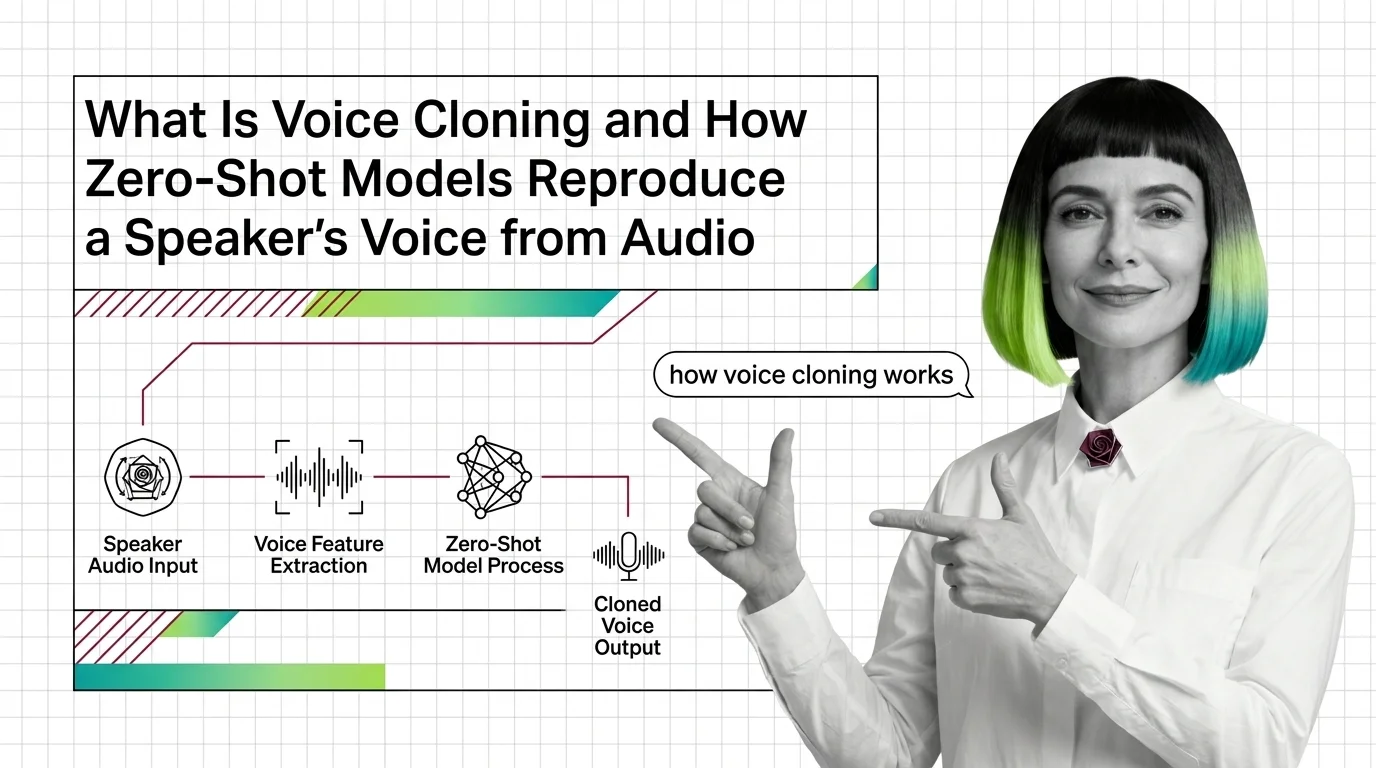
What Is Voice Cloning and How Zero-Shot Models Reproduce a Speaker's Voice from Audio
Voice cloning uses speaker embeddings and zero-shot conditioning to reproduce a target voice from 6–10 seconds of …
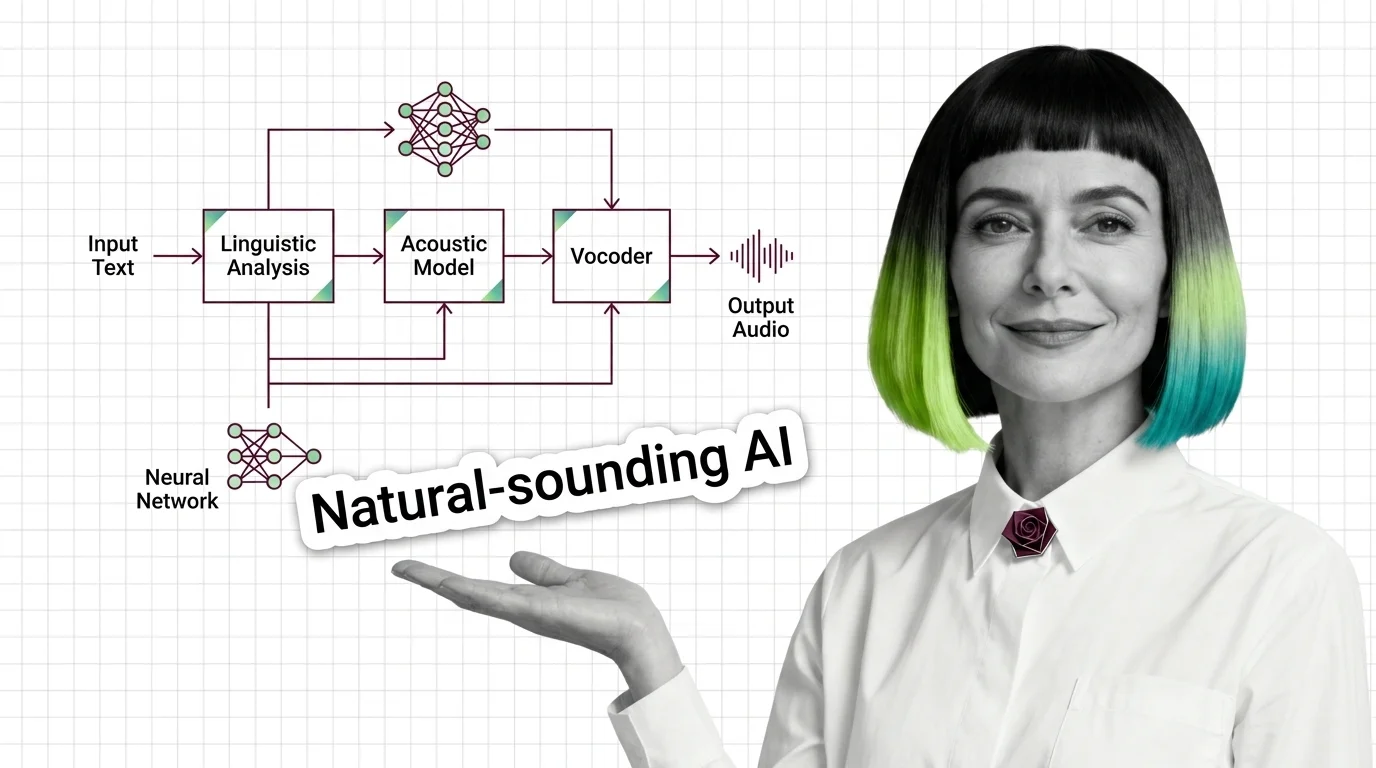
What Is Text-to-Speech AI and How Neural TTS Architectures Convert Text into Speech
Neural TTS converts text into speech through learned acoustic models. Tacotron 2 scored 4.53 MOS at ICASSP 2018; current …
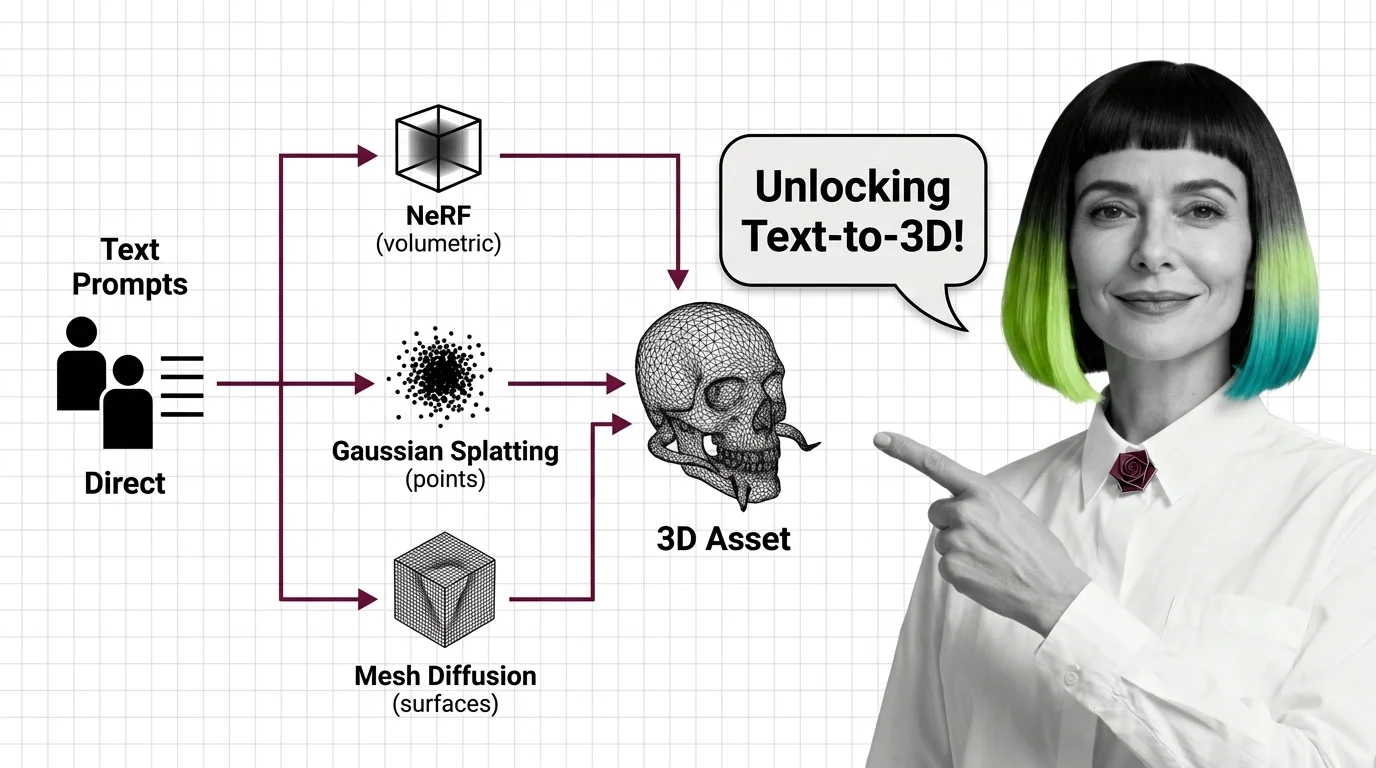
What Is Text-to-3D: How NeRF, Gaussian Splatting, and Mesh Diffusion Turn Text Prompts into 3D Assets
Text-to-3D uses Score Distillation Sampling to convert text into 3D meshes via NeRF or Gaussian splatting — no labeled …
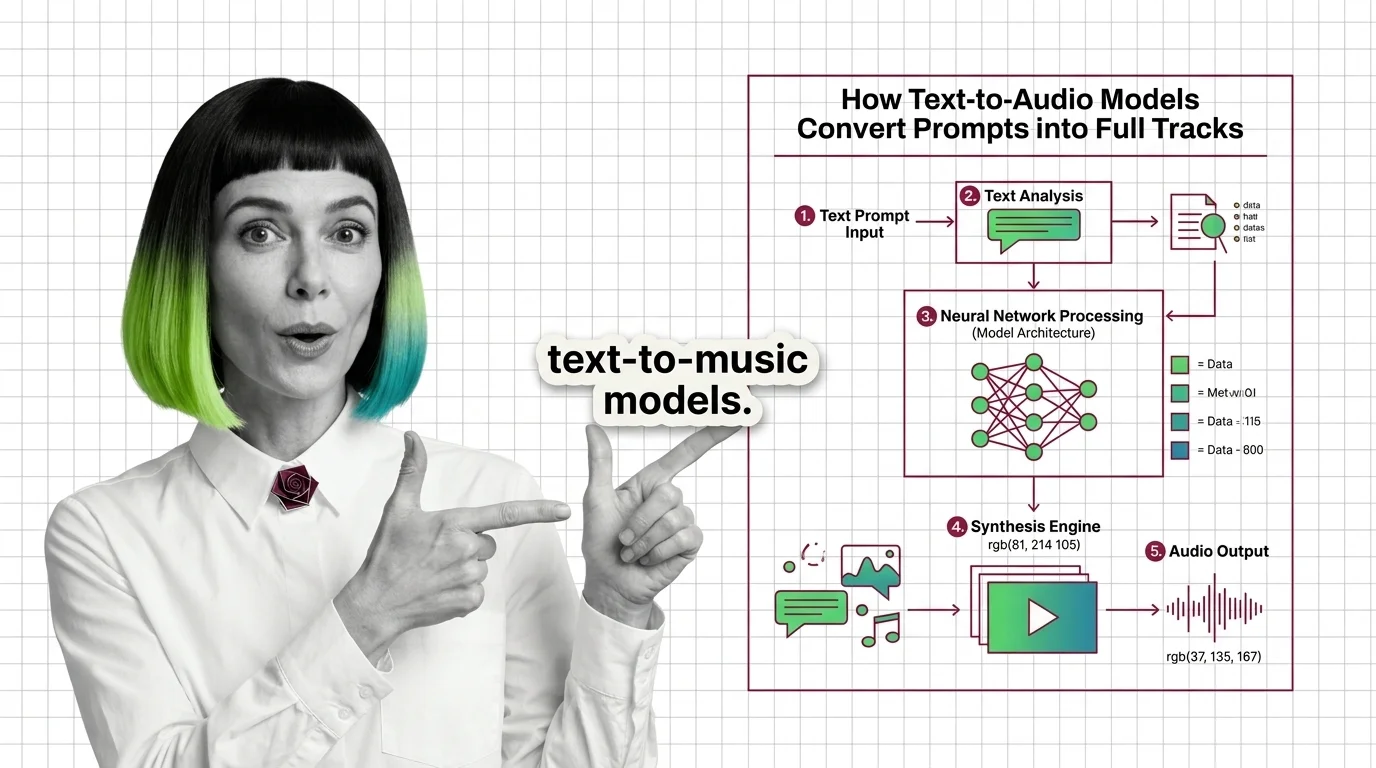
What Is AI Music Generation and How Text-to-Audio Models Convert Prompts into Full Tracks
AI music generation converts text prompts into audio tracks. Neural codecs compress waveforms into tokens; transformers …
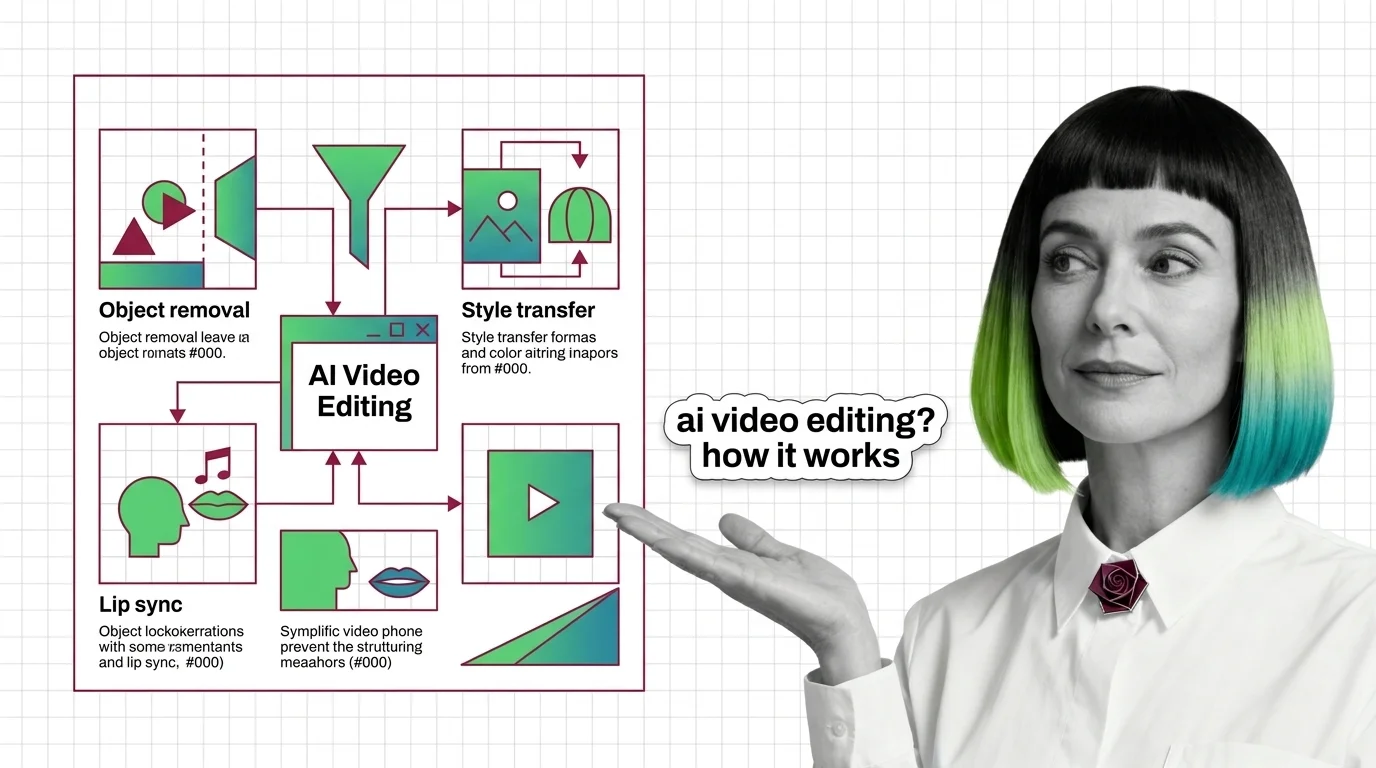
What Is AI Video Editing and How Object Removal, Style Transfer, and Lip Sync Actually Work
AI video editing uses diffusion models to edit footage directly — Runway Aleph and Pika remove objects, transfer style, …
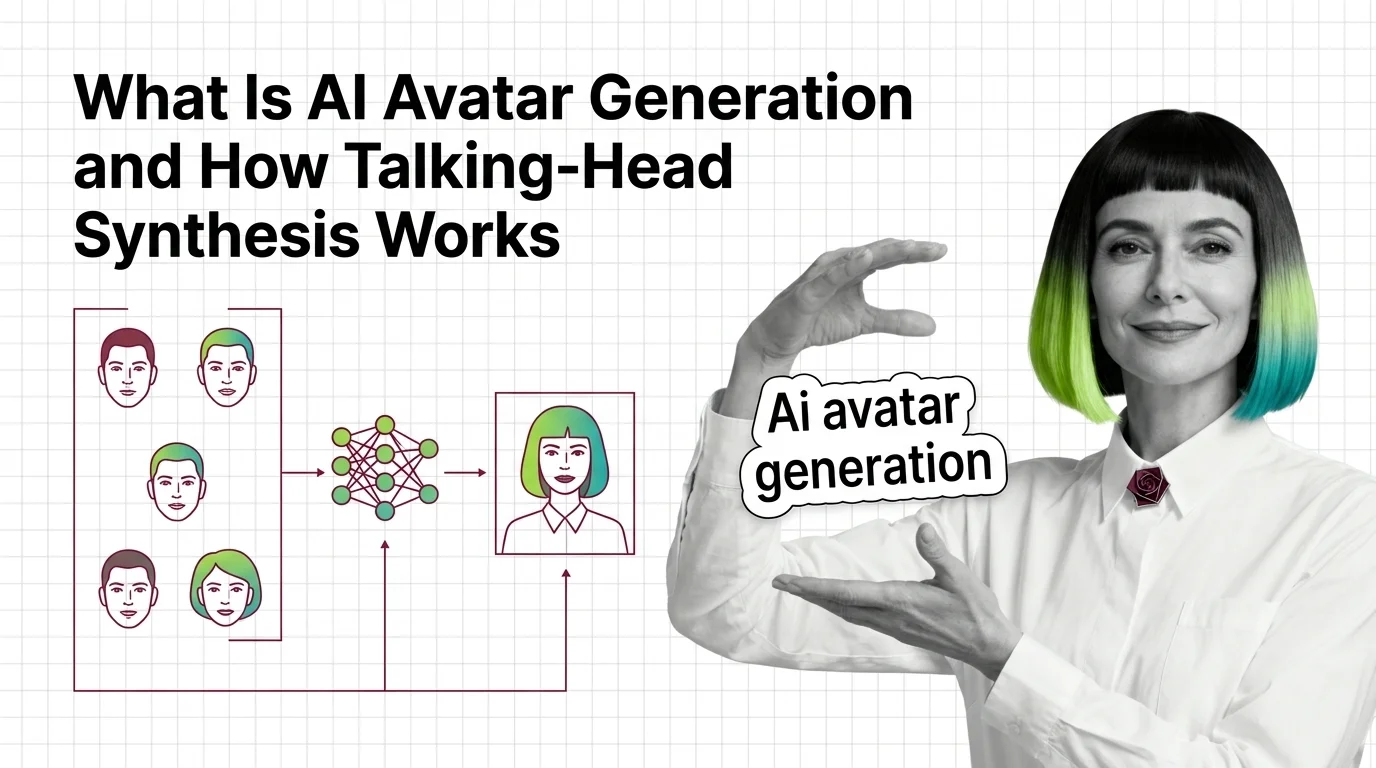
What Is AI Avatar Generation and How Talking-Head Synthesis Works
AI avatar generation reanimates a face from audio using two pipelines: 2D lip-sync over real video, or 3D reconstruction …
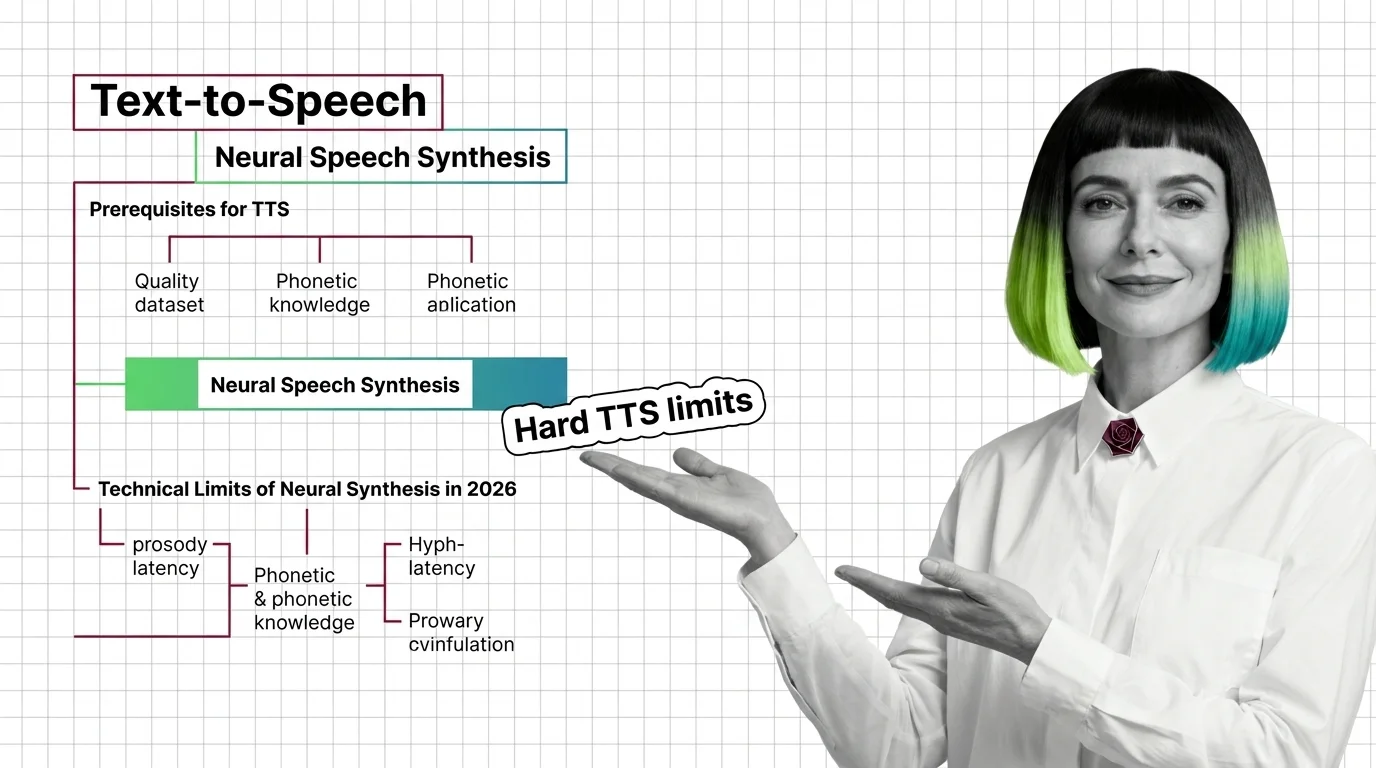
Prerequisites for TTS and the Hard Technical Limits of Neural Speech Synthesis in 2026
Neural TTS converts text to audio via phoneme processing, prosody modeling, and vocoders. In 2026, expressiveness and …
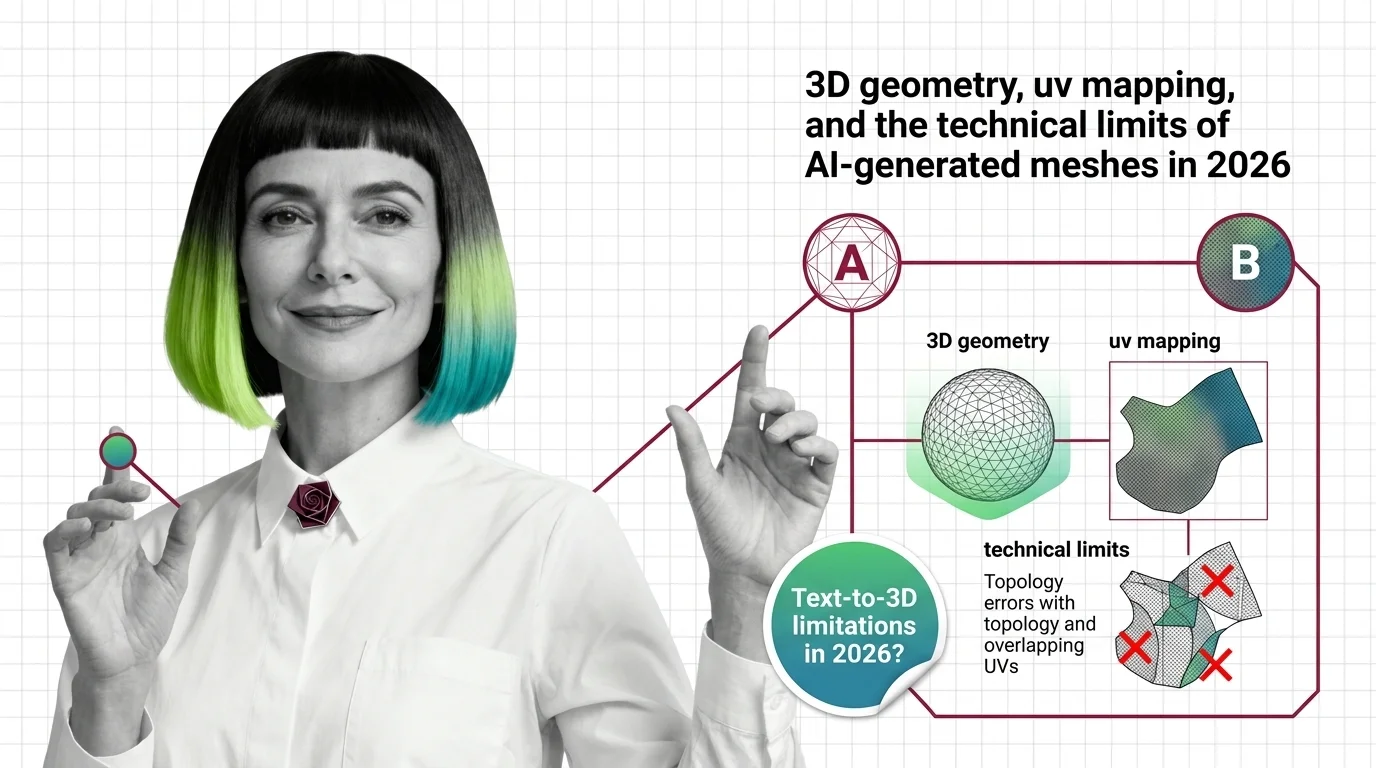
3D Geometry, UV Mapping, and the Technical Limits of AI-Generated Meshes in 2026
Text-to-3D tools produce non-manifold meshes with broken UV maps. Topology errors, splat format gaps, and multi-view …
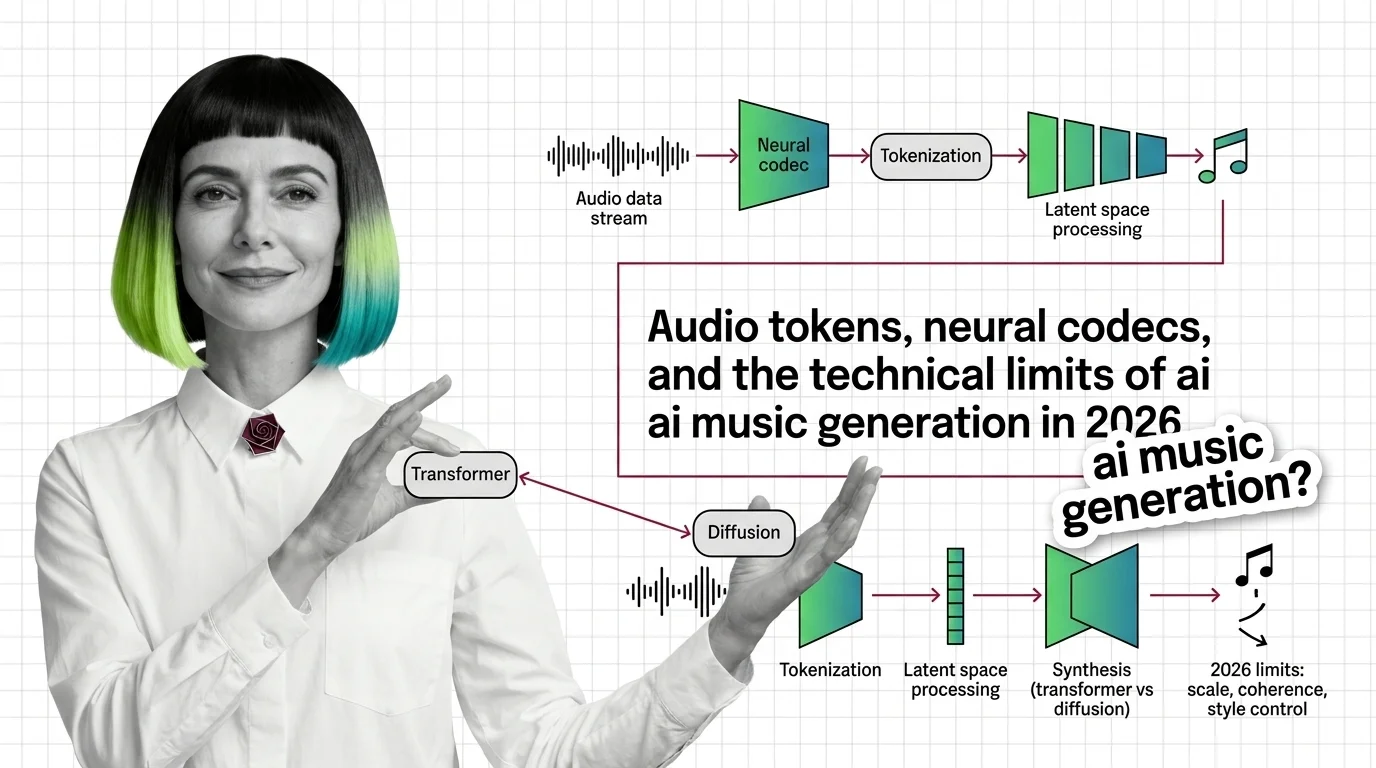
Audio Tokens, Neural Codecs, and the Technical Limits of AI Music Generation in 2026
Neural codecs tokenize audio into discrete sequences for AI music models. Codec fidelity is largely solved in 2026; …
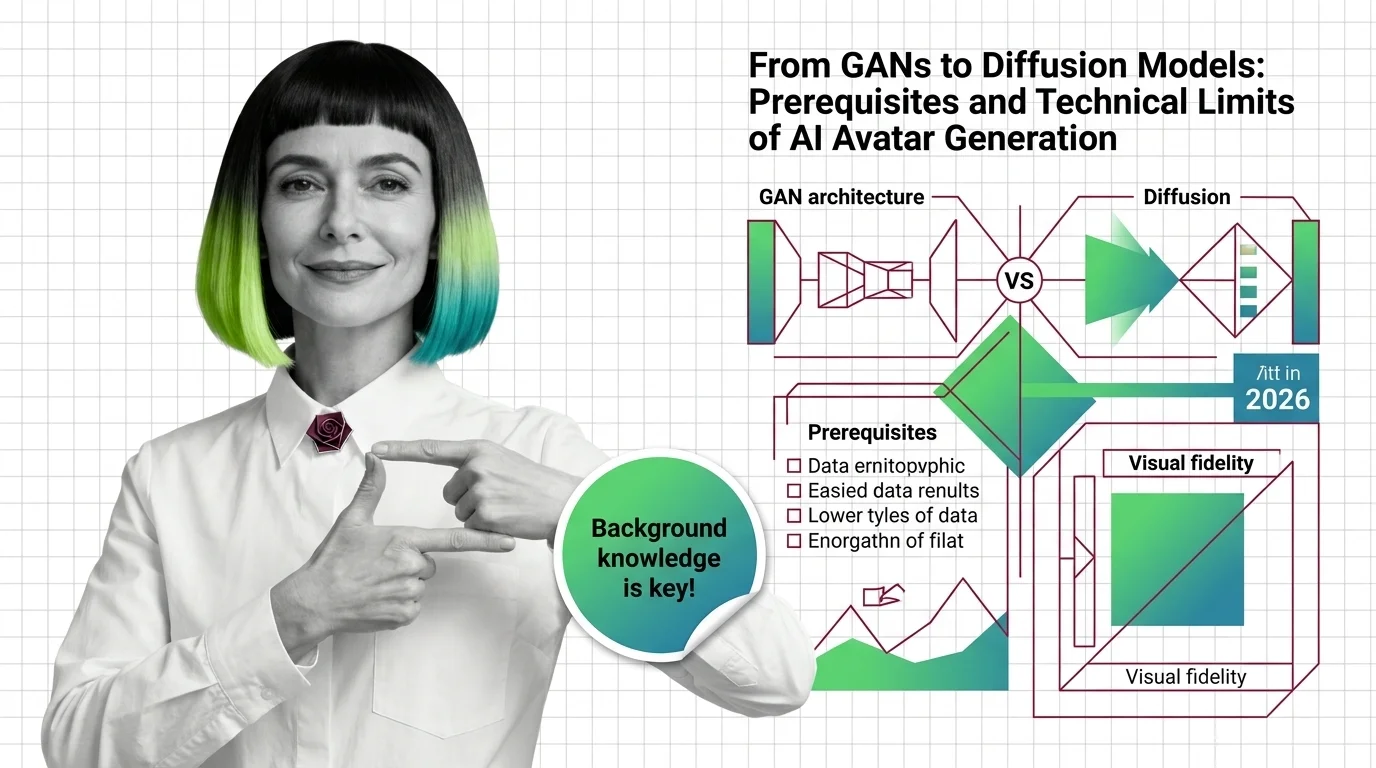
From GANs to Diffusion Models: Prerequisites and Technical Limits of AI Avatar Generation
AI avatar generation now runs on diffusion transformers, not GANs — HeyGen and Synthesia both switched in 2026, but …
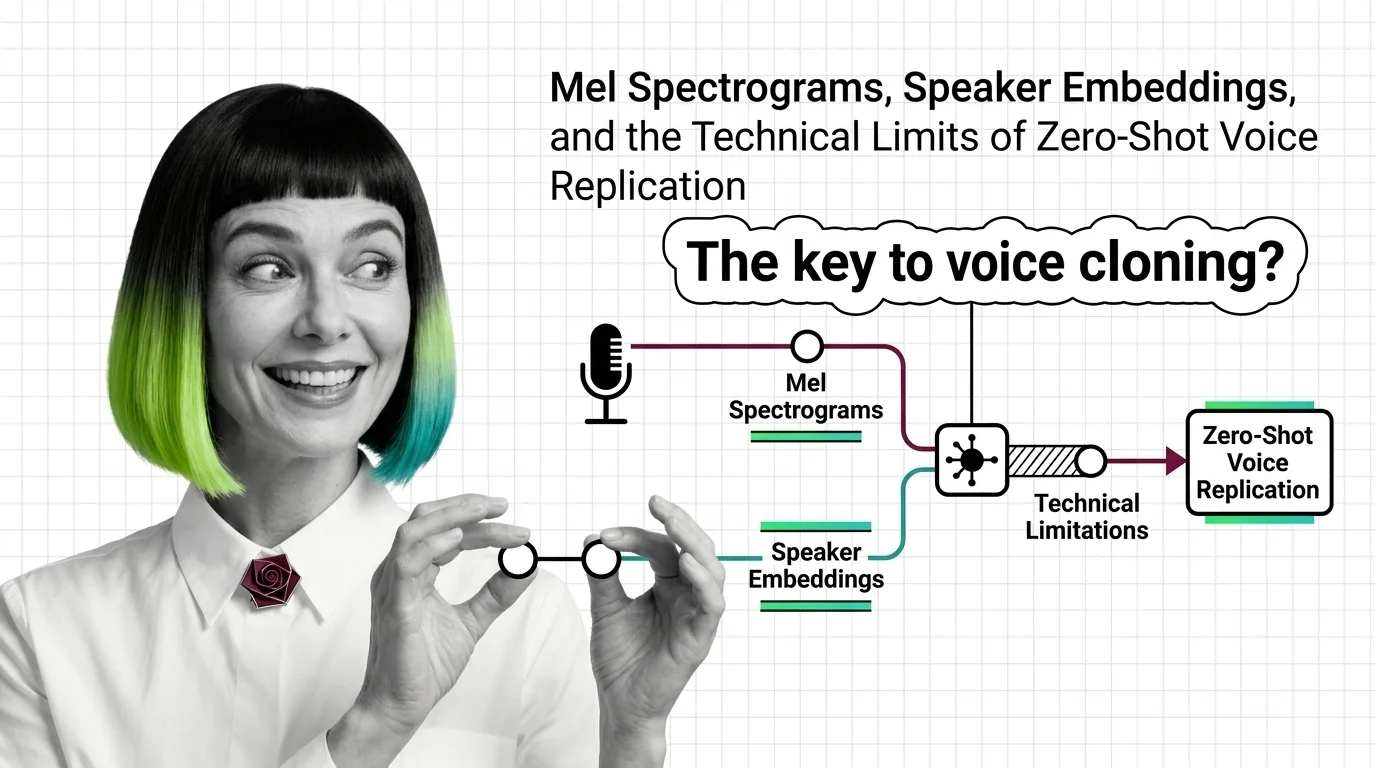
Mel Spectrograms, Speaker Embeddings, and the Technical Limits of Zero-Shot Voice Replication
Mel spectrograms and speaker embeddings are the core of voice cloning. Zero-shot models clone from 3 seconds but fail on …
Temporal Consistency, Identity Drift, and the Technical Limits of AI Video Editing
AI video editing tools regenerate each frame via diffusion, not edit pixels—causing temporal drift. Runway Aleph 2.0 …
What Is Dataset Bias and How Skewed Training Data Shapes Model Predictions
Dataset bias is a systematic skew between training data and the real world. A 2018 audit found classifiers failed 43x …
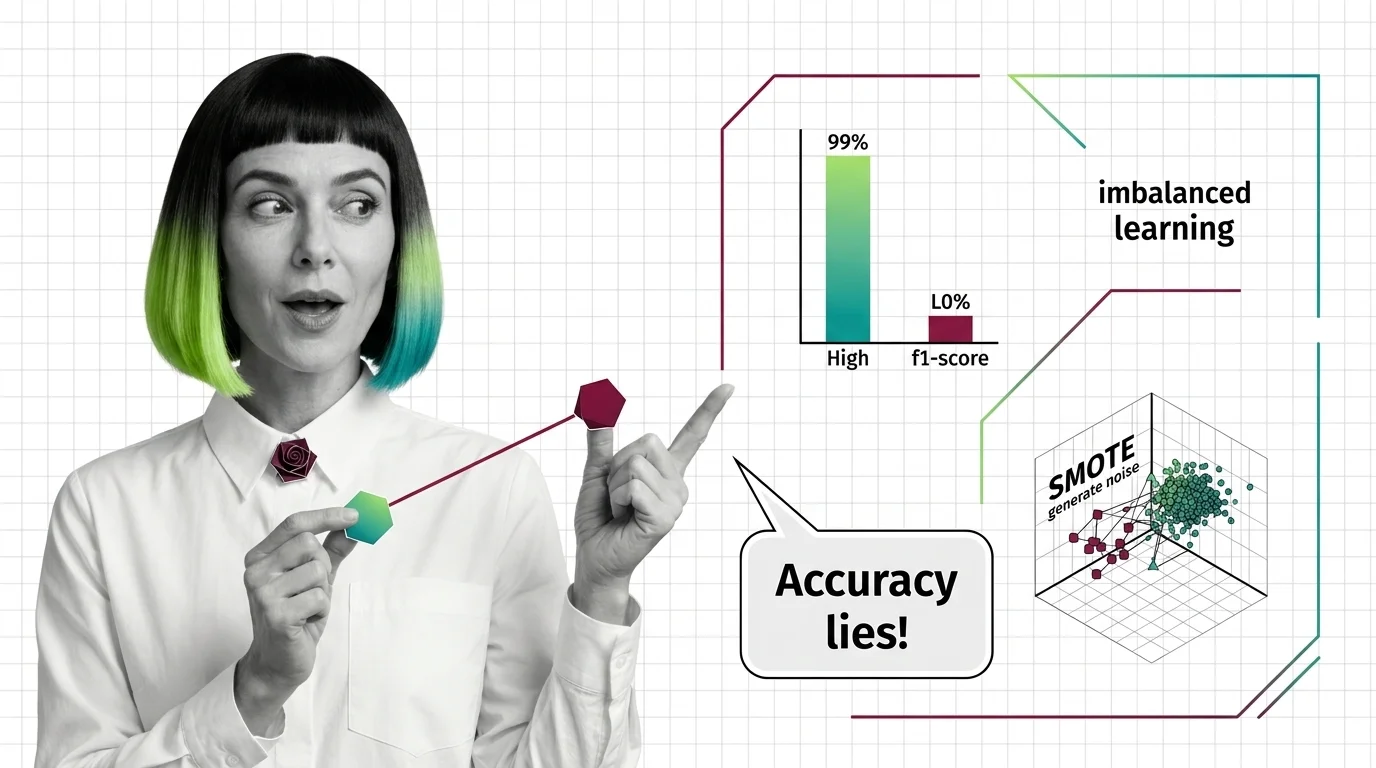
Why Accuracy Lies and SMOTE Breaks Down: The Technical Limits of Imbalanced Learning
Class imbalance makes accuracy lie: a model predicting only the majority class scores 99% yet catches zero rare cases. …
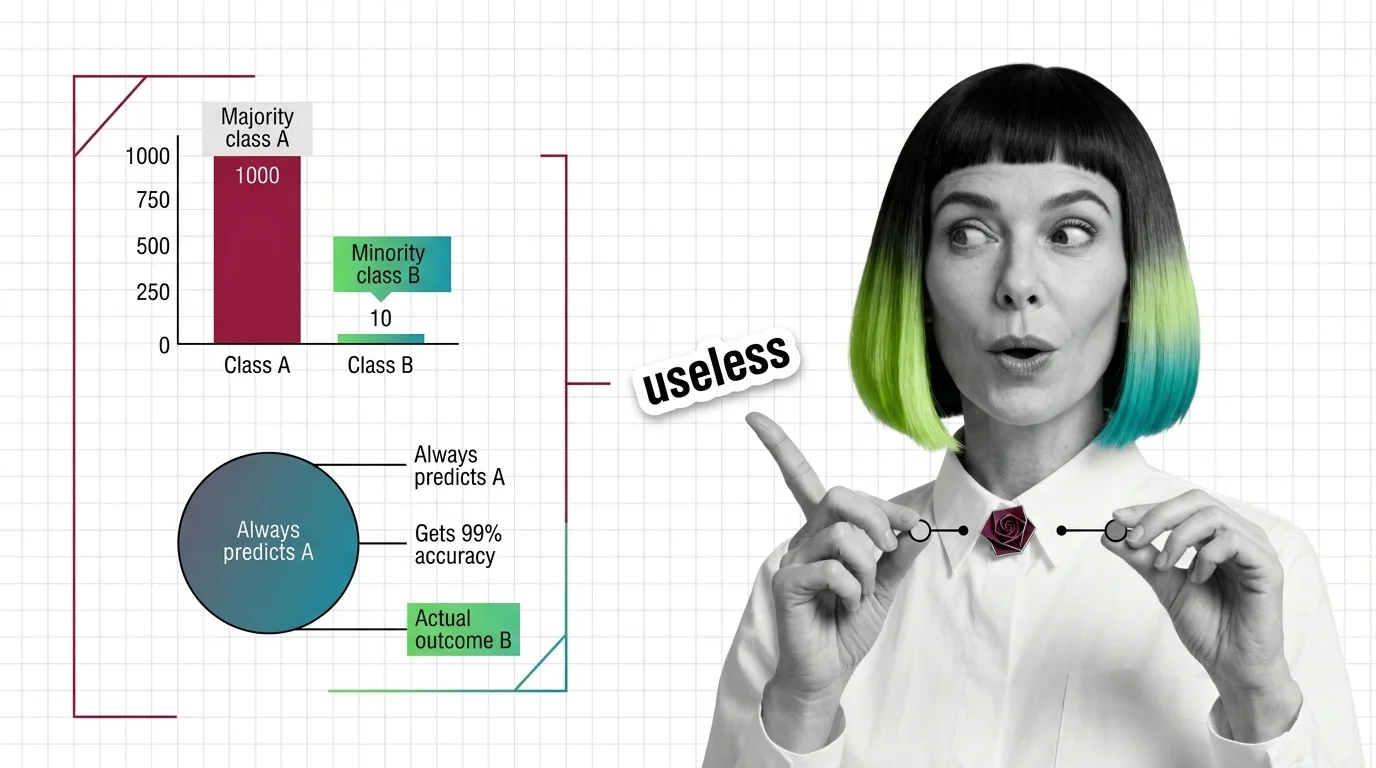
What Is Class Imbalance and Why a 99% Accurate Model Can Be Useless
Class imbalance is when one class dominates a dataset, so a model scoring 99% accuracy can miss every rare case. …
What Is Data Drift and How Production Data Silently Degrades Model Accuracy
Data drift is when production input distributions diverge from training data, degrading model accuracy even though the …
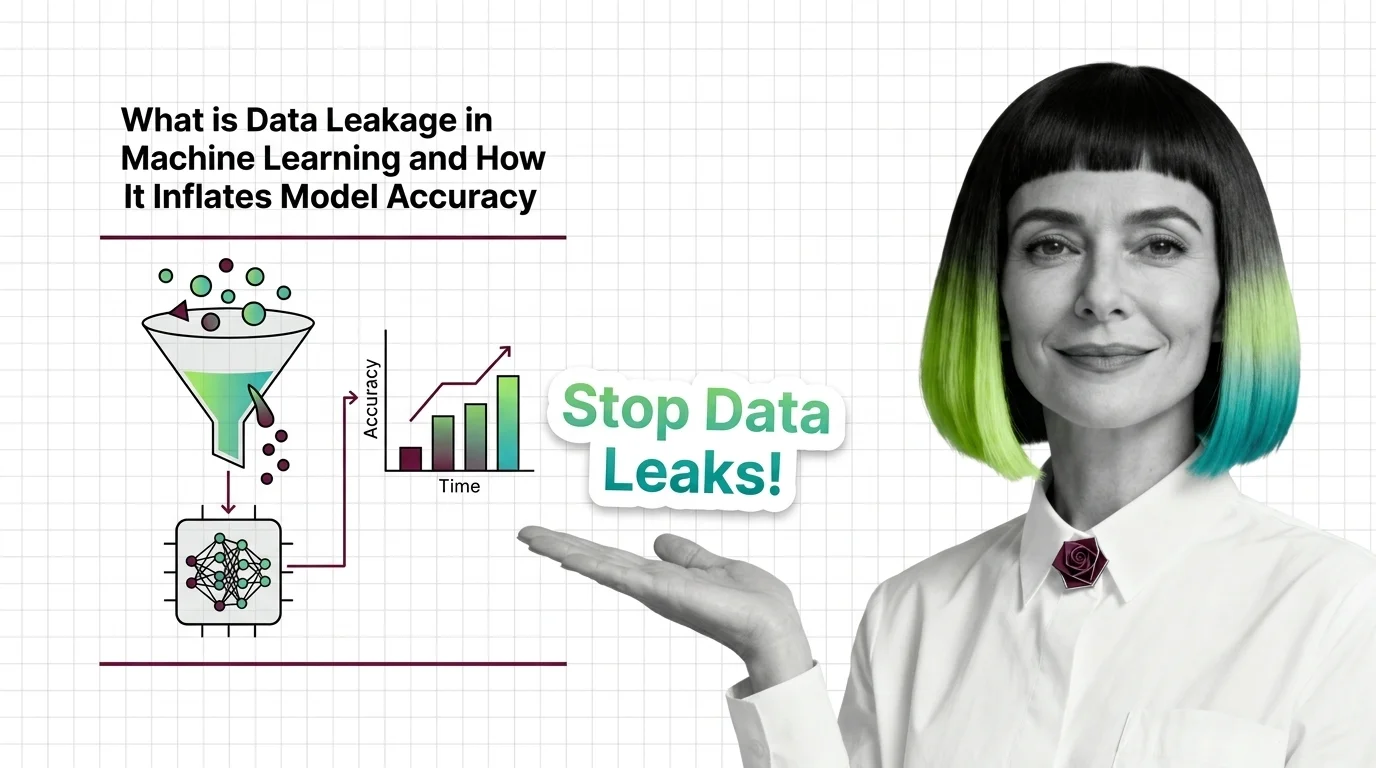
What Is Data Leakage in Machine Learning and How It Inflates Model Accuracy
Data leakage occurs when information unavailable at prediction time reaches model training, inflating accuracy estimates …
What Is Data Poisoning and How Corrupted Training Data Compromises Model Behavior
Data poisoning corrupts ML training data to redirect model outputs. Backdoor attacks embed dormant triggers; clean-label …
What Is Data Versioning and How Content Hashing Tracks Dataset Changes Like Git
Data versioning tracks dataset changes by content hash, not filename. DVC and lakeFS keep large data out of Git, …
RAG Poisoning, Agent-Memory Corruption, and What Training Pipelines Expose to Attackers
Data poisoning corrupts AI behavior through three surfaces: training pipelines, RAG corpora, and agent memory — each …
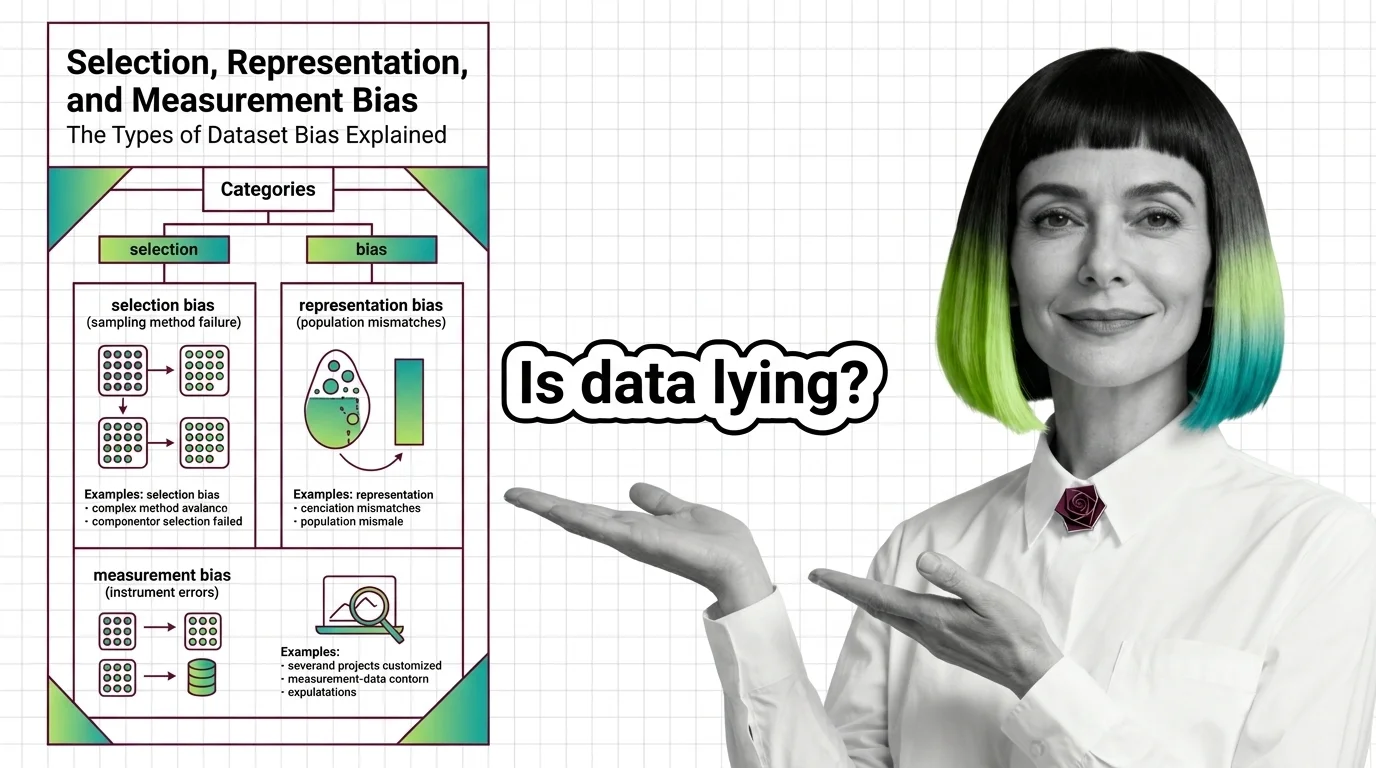
Selection, Representation, and Measurement Bias: The Types of Dataset Bias Explained
Dataset bias comes in three forms: selection, representation, and measurement. Each enters at a different stage and …
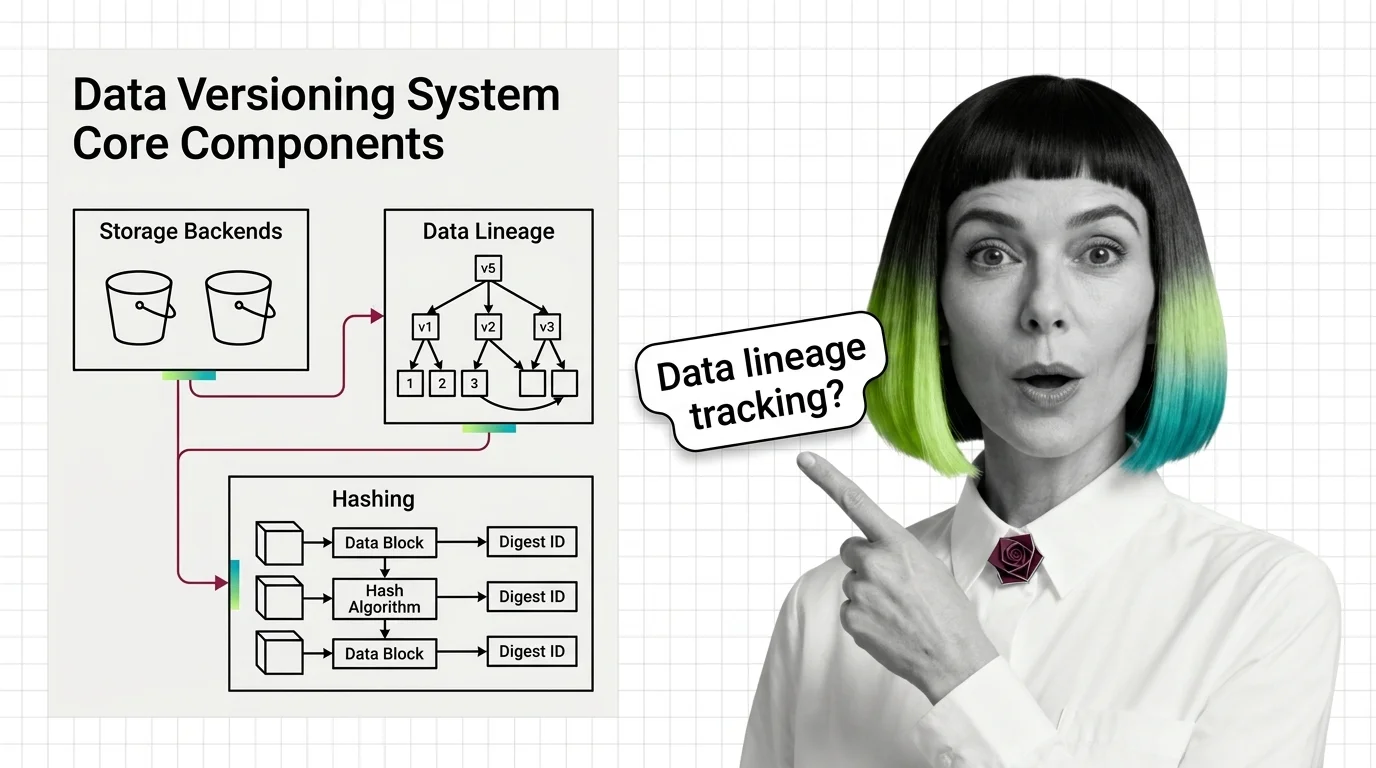
Storage Backends, Data Lineage, and Hashing: The Core Components of a Data Versioning System
A data versioning system has three core parts: content-addressable hashing, a storage backend, and lineage that links …
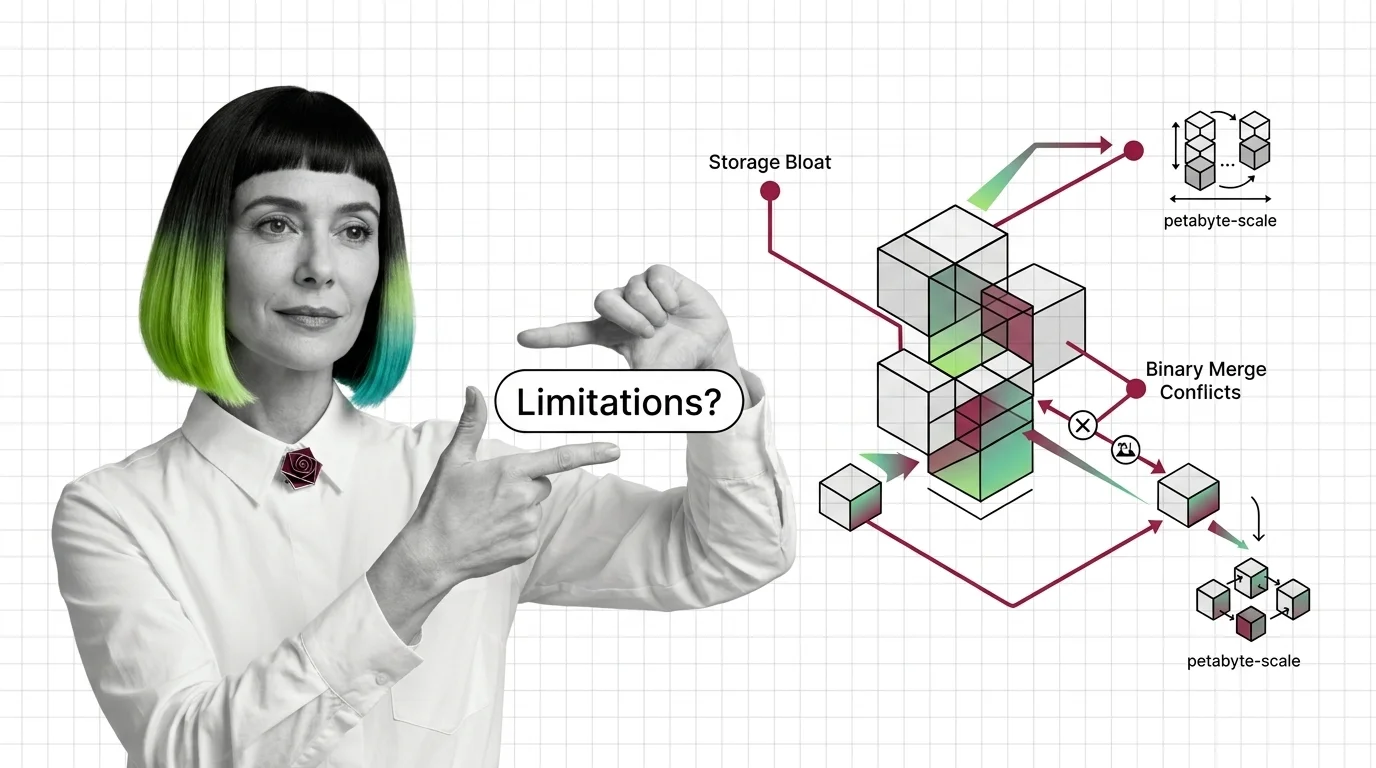
Storage Bloat, Binary Merge Conflicts, and the Scaling Limits of Data Versioning
Data versioning tools bloat storage because Git LFS and DVC dedup whole files. A 1-byte change to a 10 GB file stores …
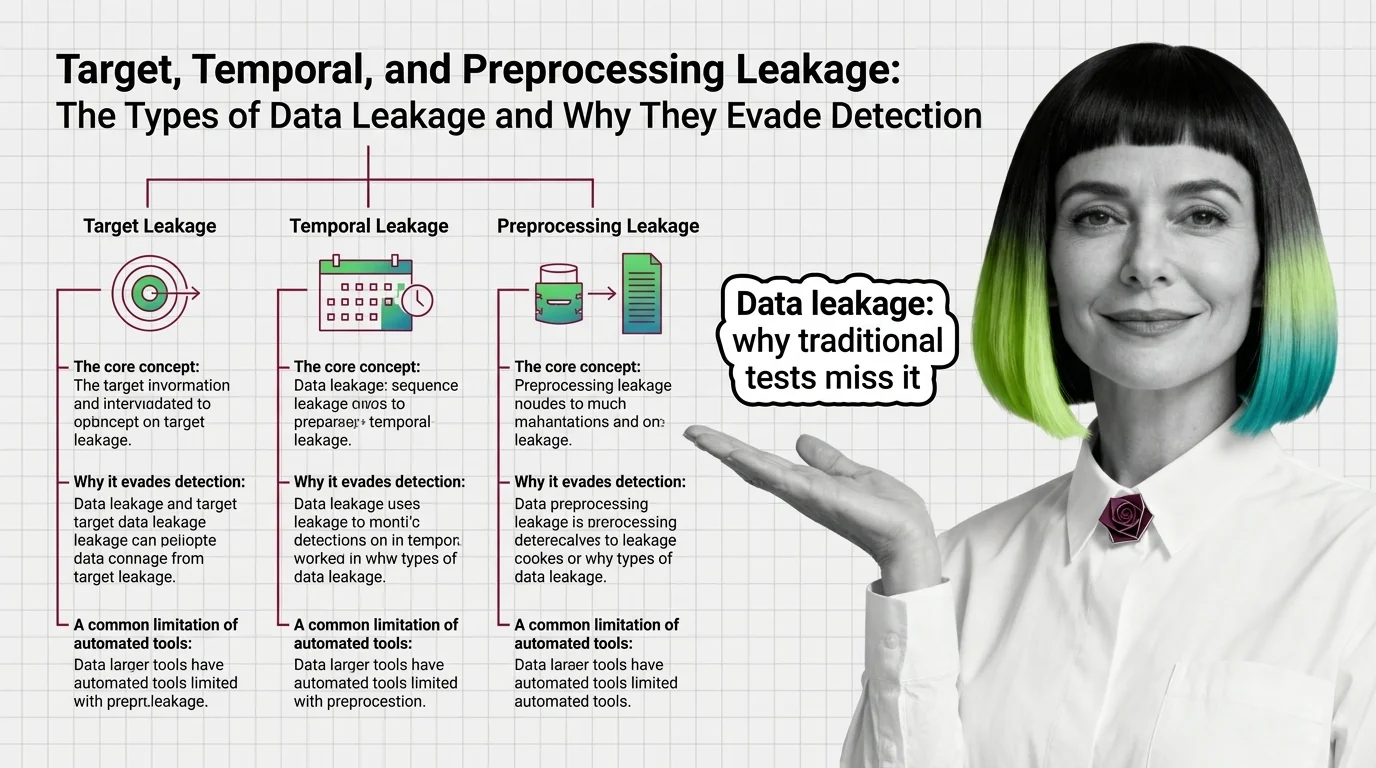
Target, Temporal, and Preprocessing Leakage: Why Data Leakage Evades Detection
Data leakage comes in target, temporal, and preprocessing forms. It corrupted 294 studies across 17 fields because …
Bias Amplification and the Impossibility Theorem: Why You Can't Fully Debias a Dataset
Dataset bias can't be fully removed: it enters at many lifecycle stages, hides in proxy features, and models amplify the …
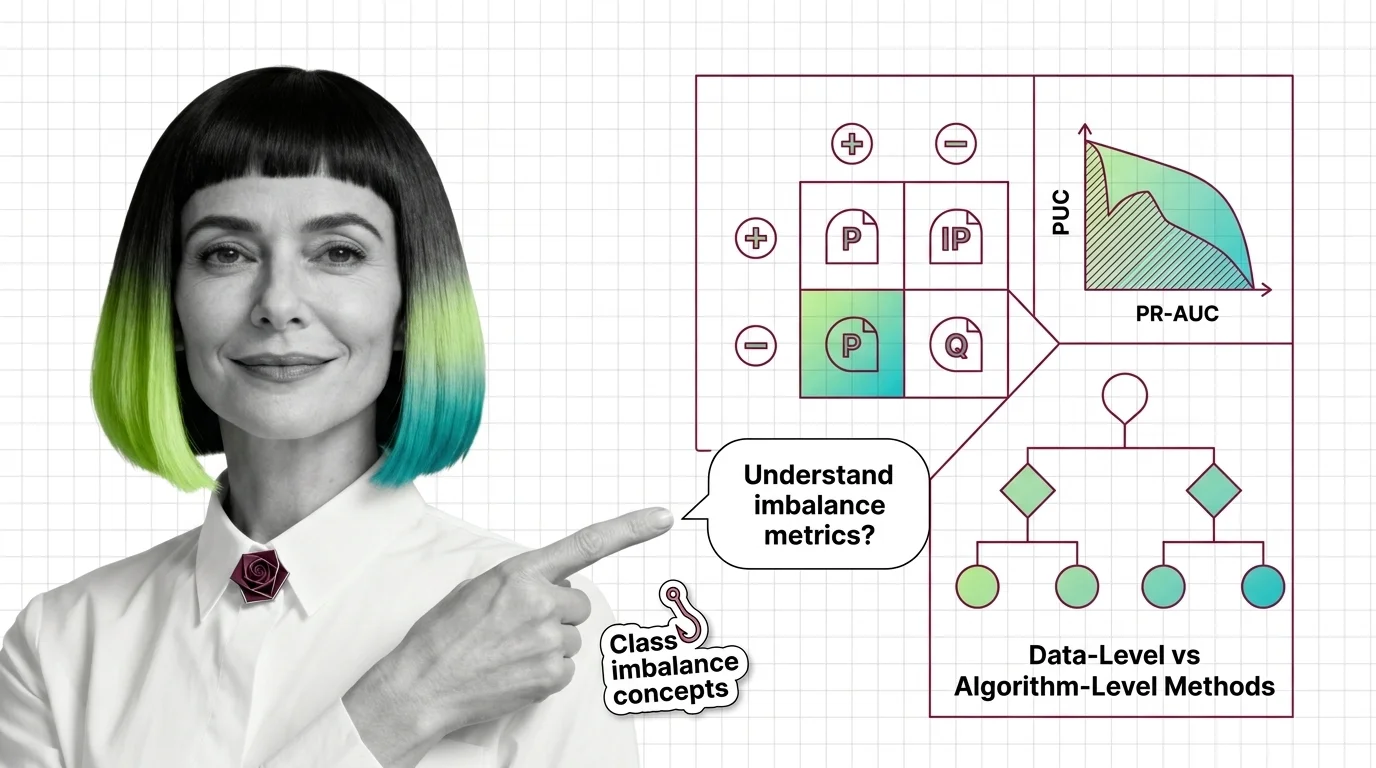
Class Imbalance Prerequisites: Confusion Matrices, PR-AUC, Data-Level vs Algorithm-Level
Class imbalance makes accuracy misleading. Use the confusion matrix, PR-AUC, and balanced accuracy, then pick data-level …
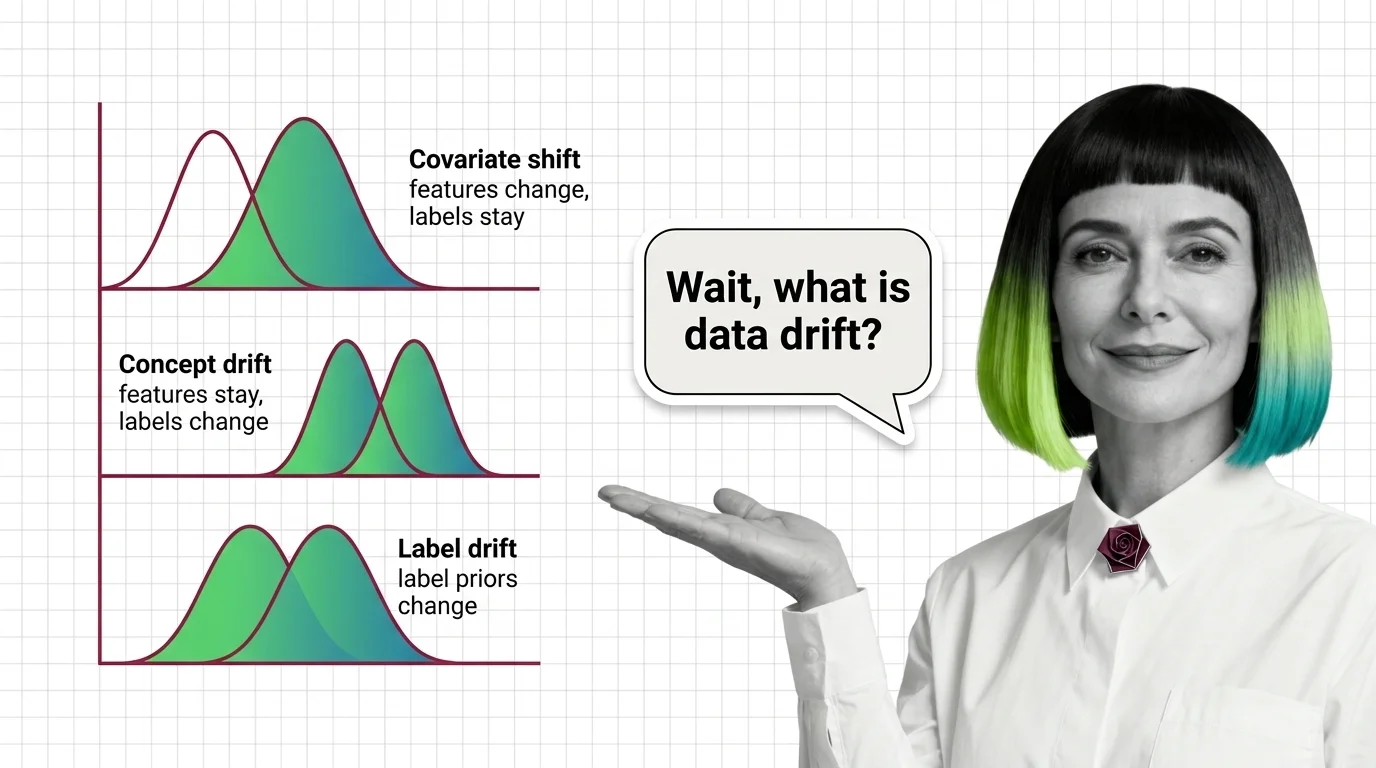
Covariate Shift, Concept Drift, and Label Drift: The Types of Data Drift and the Statistics to Detect Them
Data drift splits into three types: covariate shift P(X), concept drift P(Y|X), and label drift P(Y). KS tests and PSI …
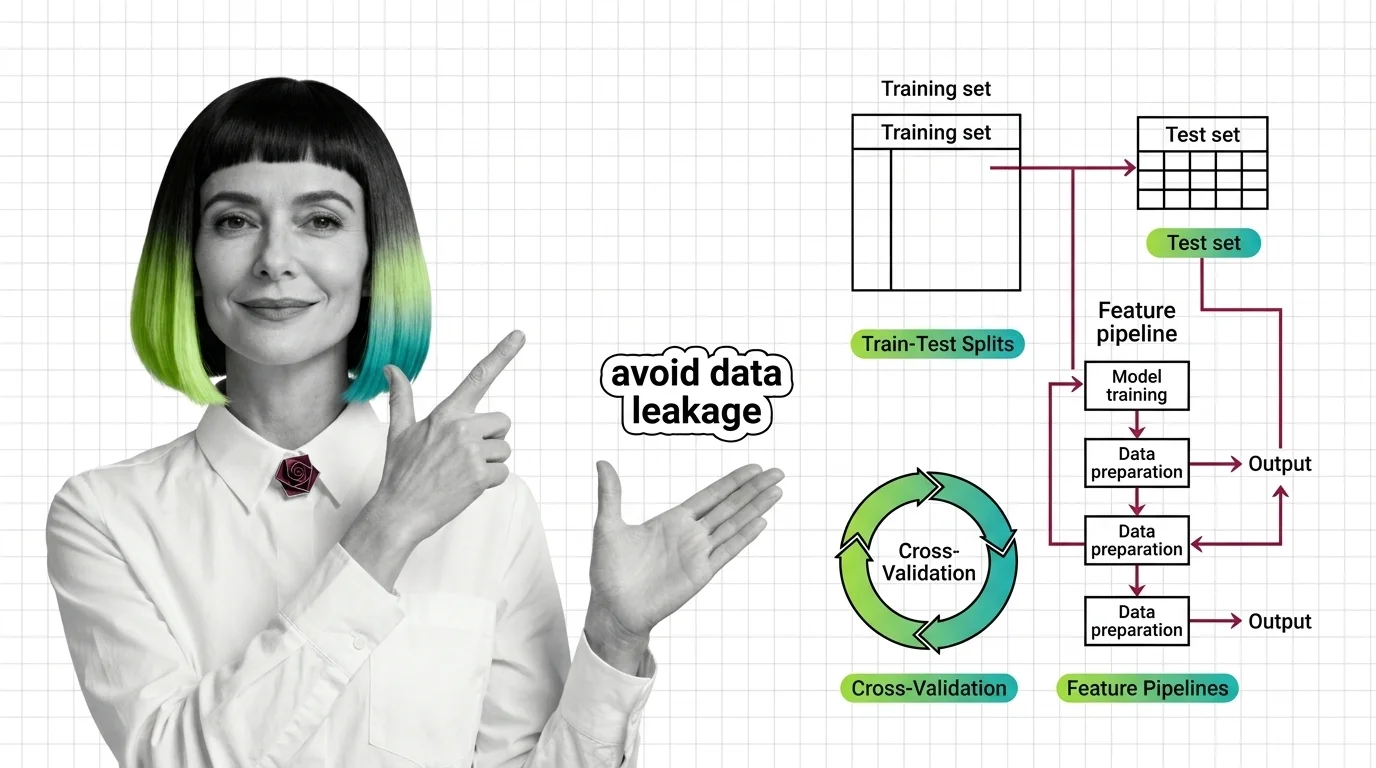
Data Leakage Prerequisites: Train-Test Splits, Cross-Validation, and Feature Pipelines
Data leakage feeds prediction-time information into training, inflating accuracy. Prevent it: split before …