Explainer Articles
In-depth explanations of AI concepts, architectures, and principles. Educational content that breaks down complex topics into understandable insights.
- Home /
- Explainer Articles
What Is Synthetic Data Ethics and How Generated Records Can Re-Identify Real People
Synthetic data ethics covers the privacy, bias, and consent risks of machine-made records. A faithful generator can …
The Fidelity-Privacy Tradeoff: Technical Limits of Anonymity Claims in Synthetic Data
Synthetic data is not anonymous. Membership inference can reveal who was in the training set, and differential privacy …
Why High SWE-bench Scores Mislead: Contamination, Test Leakage, and Flawed Tasks
High SWE-bench scores overstate coding skill: frontier models near 80% on Verified collapse to roughly 45% on …
What Is Human Evaluation for AI and How Human Raters Score Model Outputs
Human evaluation for AI uses people to compare, score, or rank model outputs — generating the ground truth that …
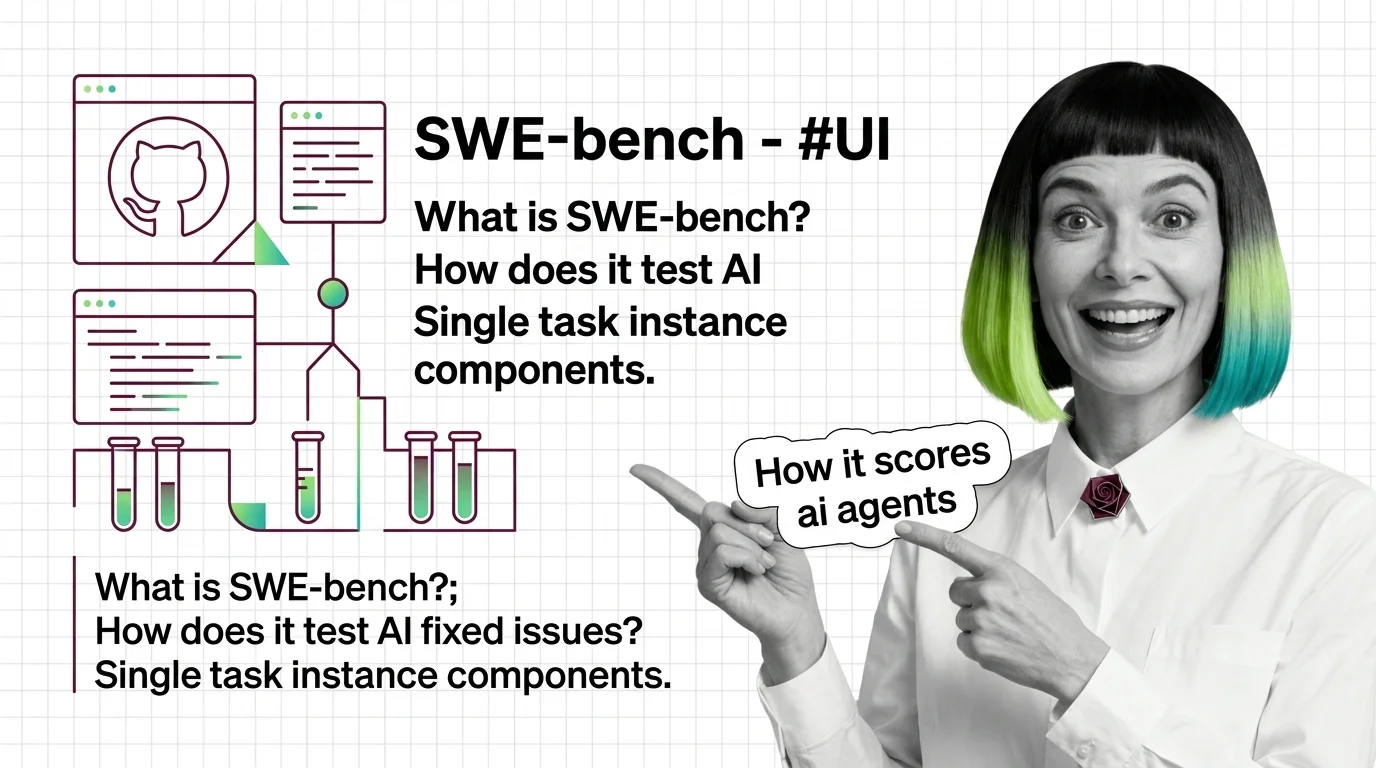
What Is SWE-bench and How Its Patch-and-Test Harness Scores AI Coding Agents
SWE-bench scores AI coding agents on 2,294 real GitHub issues by running each repo's test suite. The patch either passes …
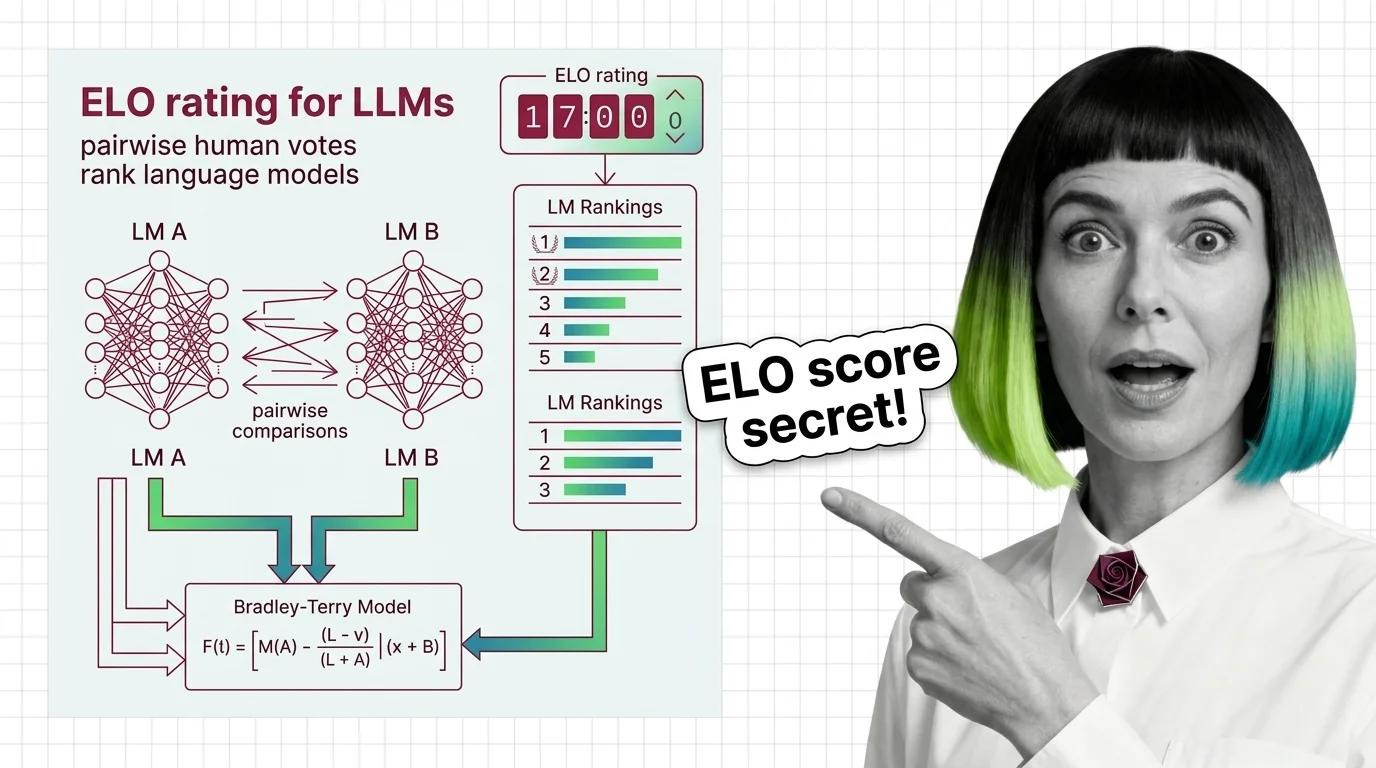
What Is ELO Rating for LLMs and How Pairwise Human Votes Rank Language Models
ELO rating for LLMs ranks models by blind pairwise votes. Arena.ai's Bradley-Terry model converts comparisons into …
The Leaderboard Illusion: Style Bias, Vote Rigging, and the Technical Limits of LLM ELO
Arena ELO scores measure preference, not LLM capability. Length bias shifts rankings 5+ positions; vote injection can …
SWE-bench Verified, Lite, Full, and Multimodal: Choosing the Right Benchmark Split
SWE-bench grades AI coding against real GitHub PR tests. Five splits differ in rigor; its most-cited split was …
Prerequisites and Technical Limits of Human Evaluation: Why Automated Metrics Can't Replace Raters
Human evaluation for AI is only valid above Cohen's Kappa 0.6. LLM judges hit 80% human agreement but carry position, …
Prerequisites for LLM ELO Ratings: Chess Elo, Blind A/B Voting, and Confidence Intervals
LLM Elo ratings come from blind preference votes. Arena's top models cluster within ~55 ELO points, often within …
Inter-Annotator Agreement, Rubric Design, and Calibration in Human AI Evaluation
Reliable LLM evaluation requires IAA metrics, anchored rubrics, and rater calibration. Cohen's kappa and Krippendorff's …
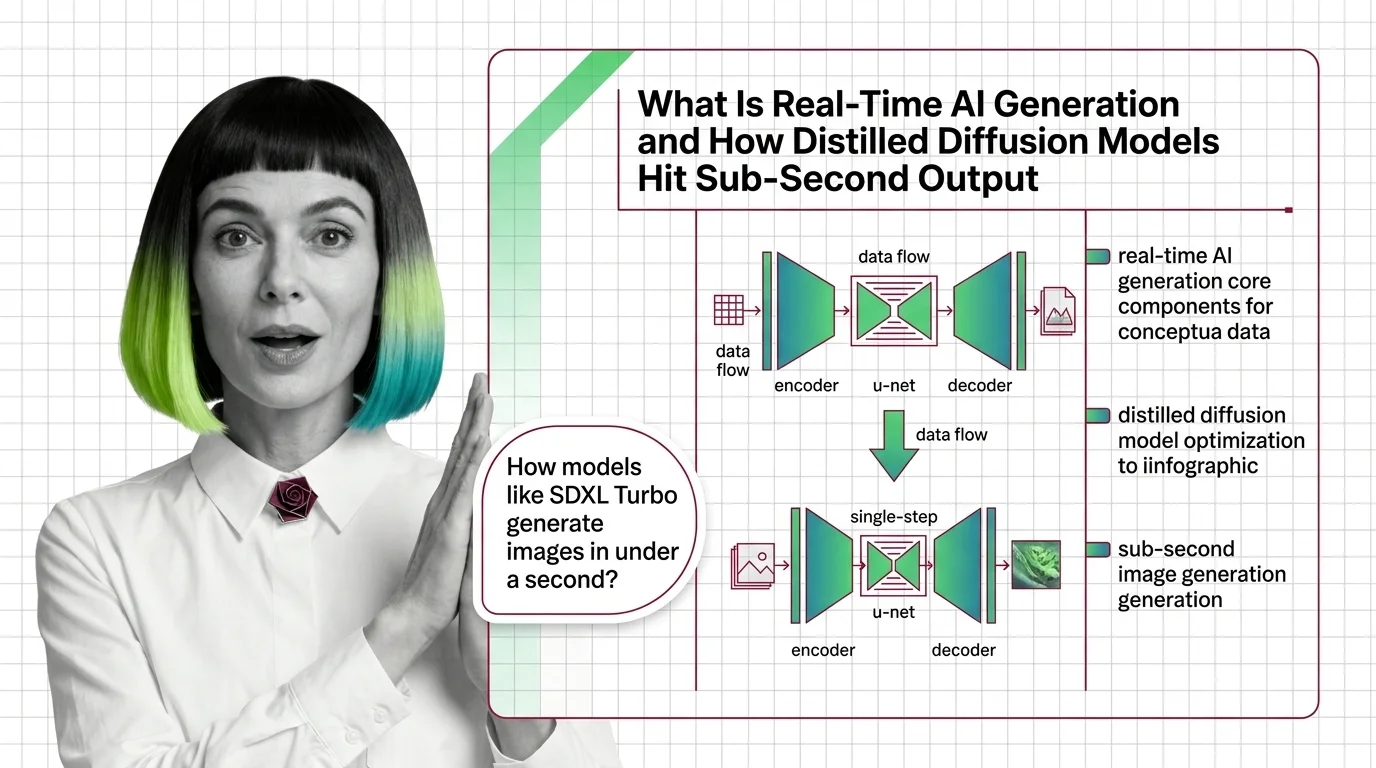
What Is Real-Time AI Generation and How Distilled Diffusion Models Hit Sub-Second Output
Real-time AI generation produces images or audio in under a second; SDXL Turbo renders a 512x512 image in 207ms via …
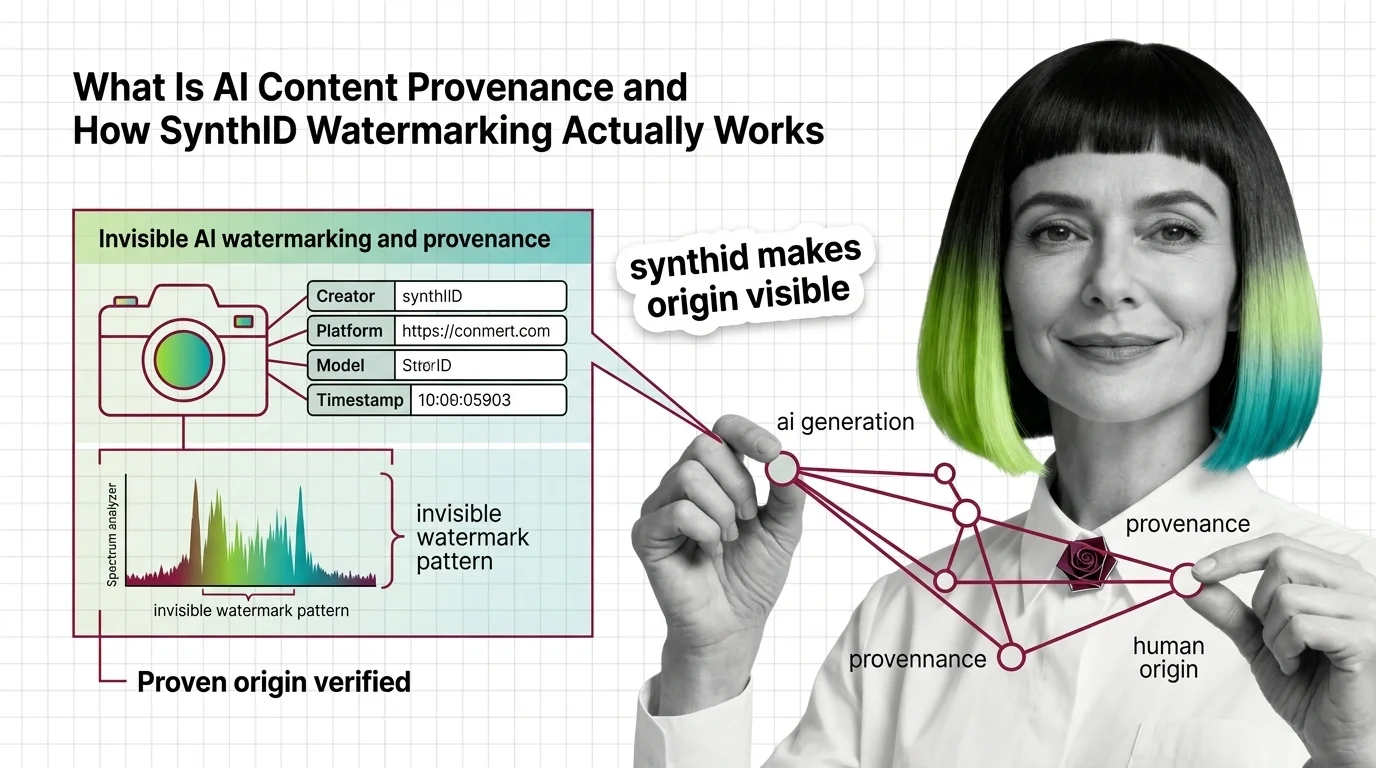
What Is AI Content Provenance and How SynthID Watermarking Actually Works
SynthID embeds an invisible signal in AI images, audio, and text without retraining; a 2025 academic attack cut its …
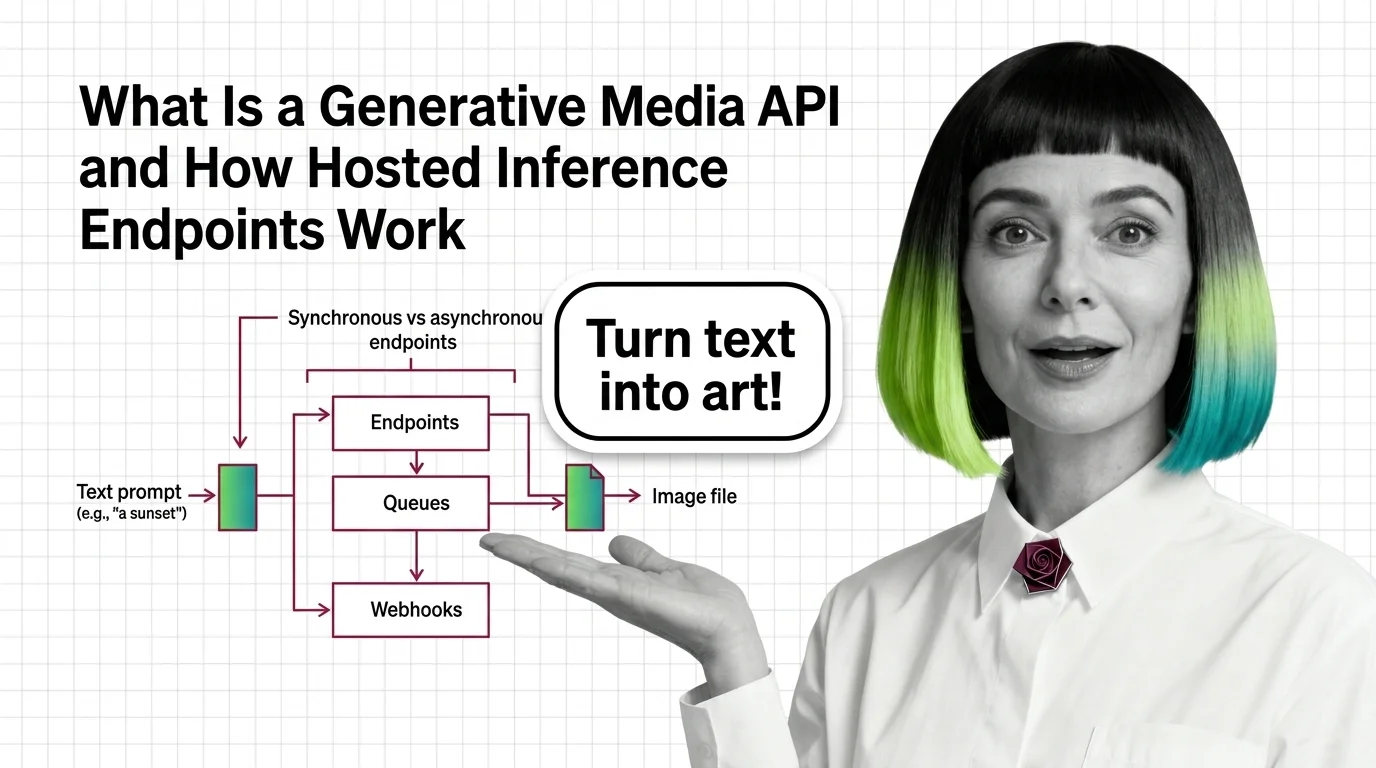
What Is a Generative Media API and How Hosted Inference Endpoints Work
A generative media API turns a text prompt into an image, video, or audio file via hosted inference endpoints, async …
What Is a Generative Media Pipeline and How Generation, Gating, and Publishing Connect
A generative media pipeline chains async generation, human gating, and automated publishing — enterprise builds stitch a …
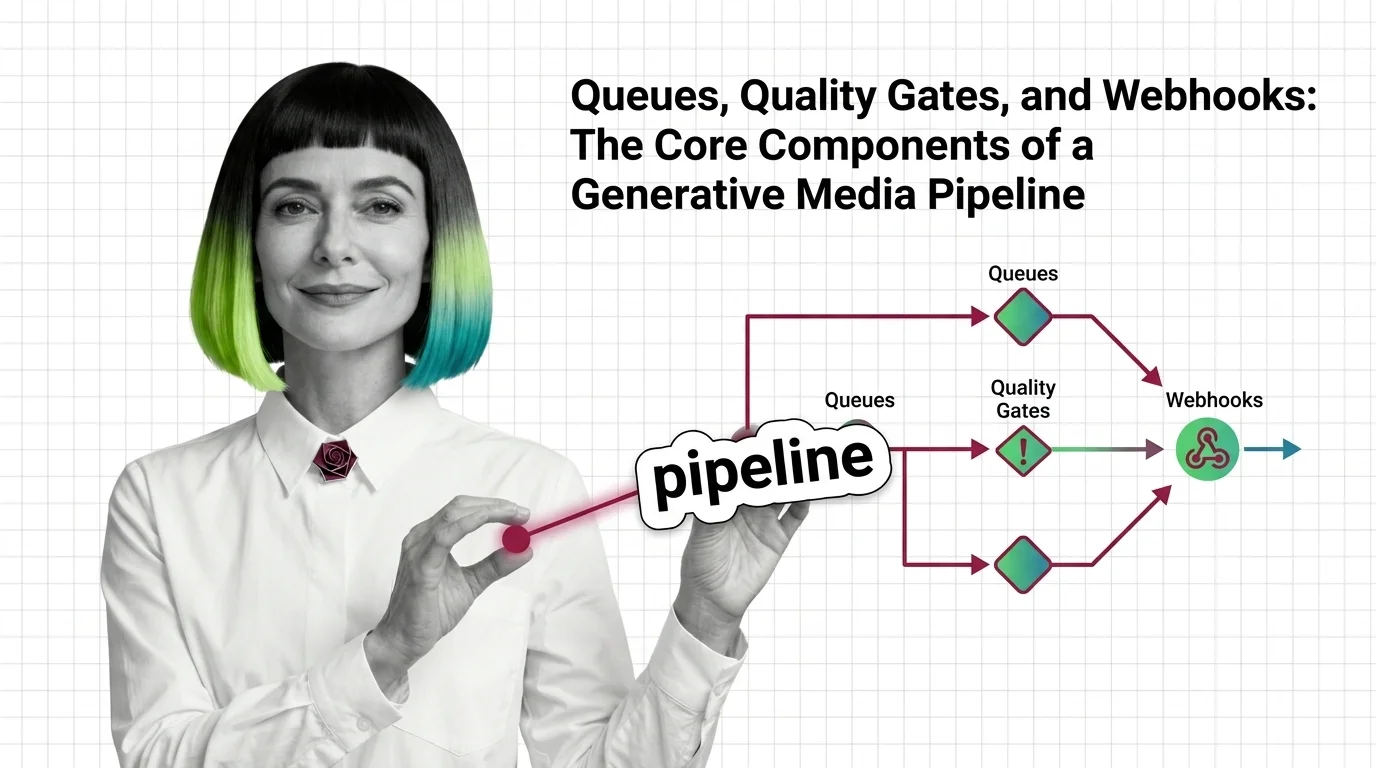
Queues, Quality Gates, and Webhooks: The Core Components of a Generative Media Pipeline
Generative media APIs return a job ID, not an image. Queues, quality gates, and webhooks turn that async ticket into a …
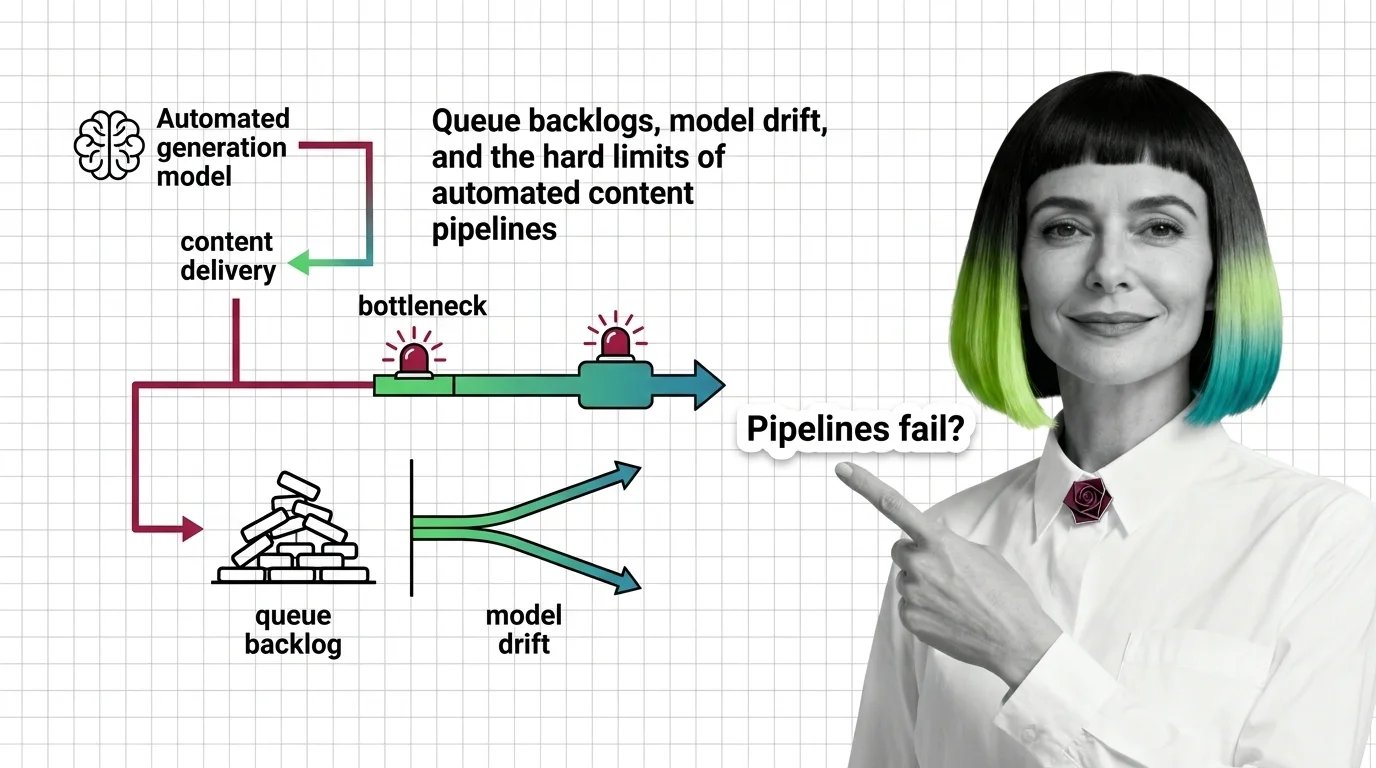
Queue Backlogs, Model Drift, and the Hard Limits of Automated Content Pipelines
Generative media pipelines break from queue limits and webhook timeouts, not model quality. Modal Labs caps functions at …
Prerequisites and Hard Limits of Real-Time AI Generation: Inference to Hardware Bottlenecks
Real-time AI generation needs sub-second inference. SDXL Turbo renders images in 207ms, but AI video still exceeds …
Prerequisites and Technical Limits of Generative Media APIs
Generative media APIs run as async job queues, not REST calls. fal.ai cold starts take 10-90 seconds; Replicate caps …
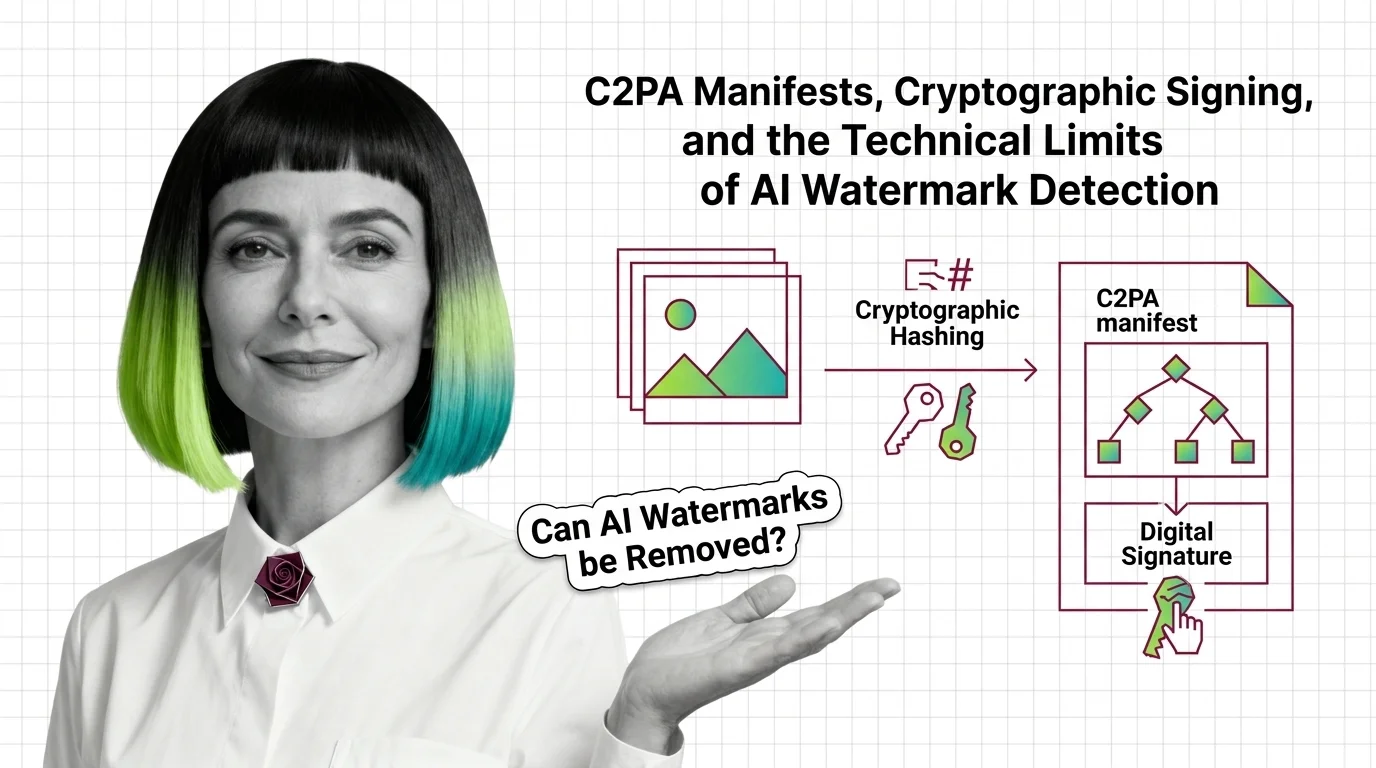
C2PA Manifests, Cryptographic Signing, and the Technical Limits of AI Watermark Detection
C2PA v2.4 Content Credentials use COSE-signed manifests to track edit history, not pixel content — the chain breaks the …
What Is Tool Use in Prompts and How LLMs Parse Function Calling Schemas
Tool use in LLMs is function calling — the model emits structured JSON naming a tool and arguments. Your code executes; …
What Is Structured Output Prompting and How LLMs Are Made to Return Valid JSON
Structured output prompting forces valid JSON from LLMs — via constrained decoding that masks invalid tokens, or …
What Is Prompt Testing and Evaluation and How Automated Metrics Replace Manual Spot-Checks
Prompt testing and evaluation measures LLM output quality using automated scorers — code-based, LLM-as-judge, and human. …
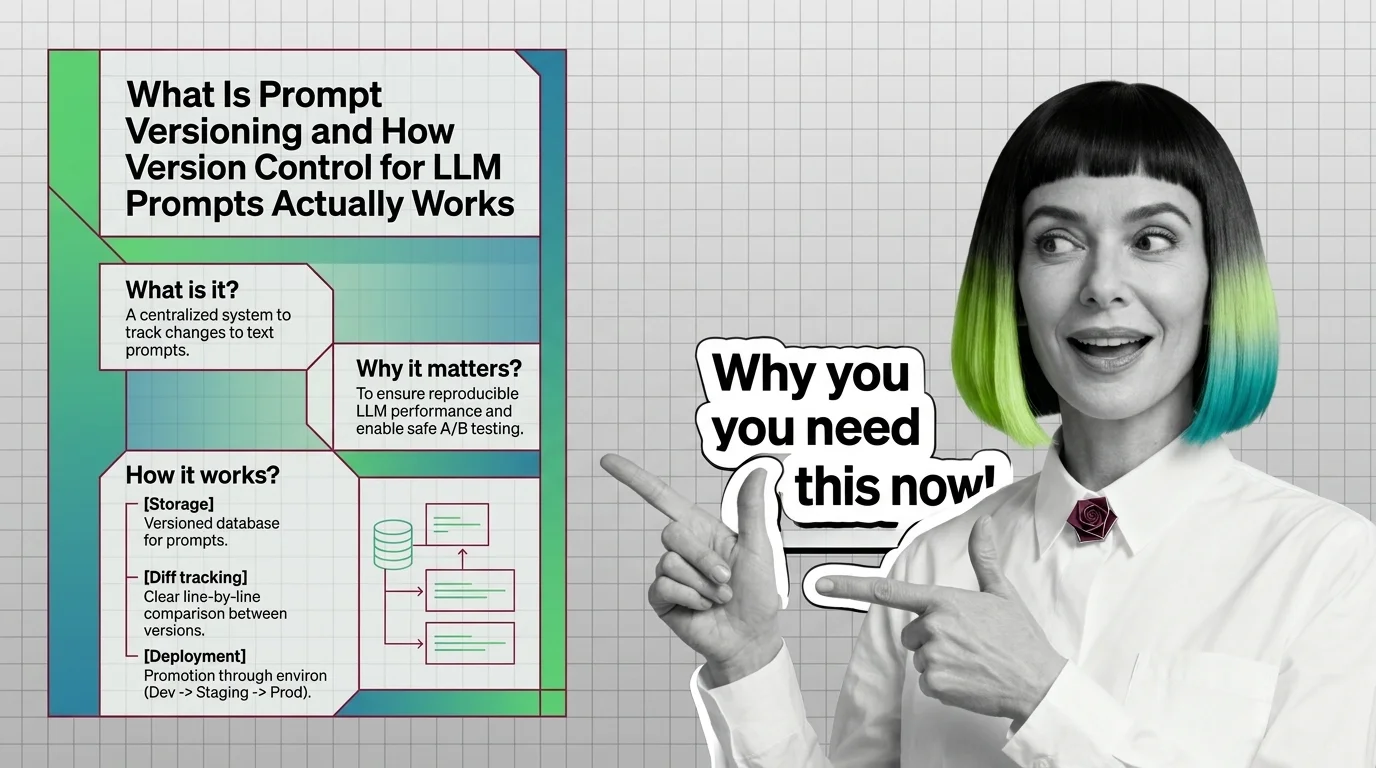
What Is Prompt Versioning and How Version Control for LLM Prompts Actually Works
Prompt versioning assigns immutable IDs to every LLM prompt change. Rollback means reassigning a production label — no …
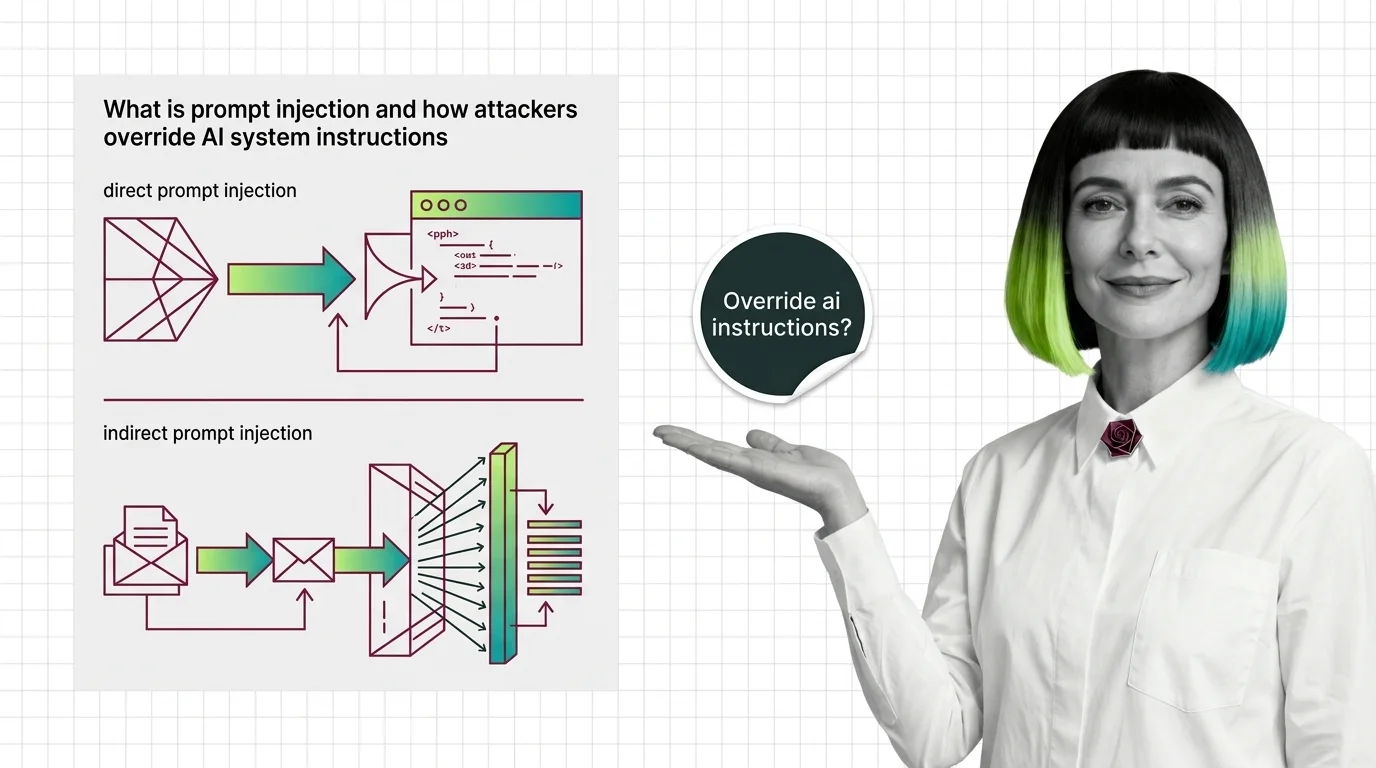
What Is Prompt Injection and How Attackers Override AI System Instructions
Prompt injection redirects AI systems via malicious instructions embedded in processed text. OWASP ranks it the top LLM …
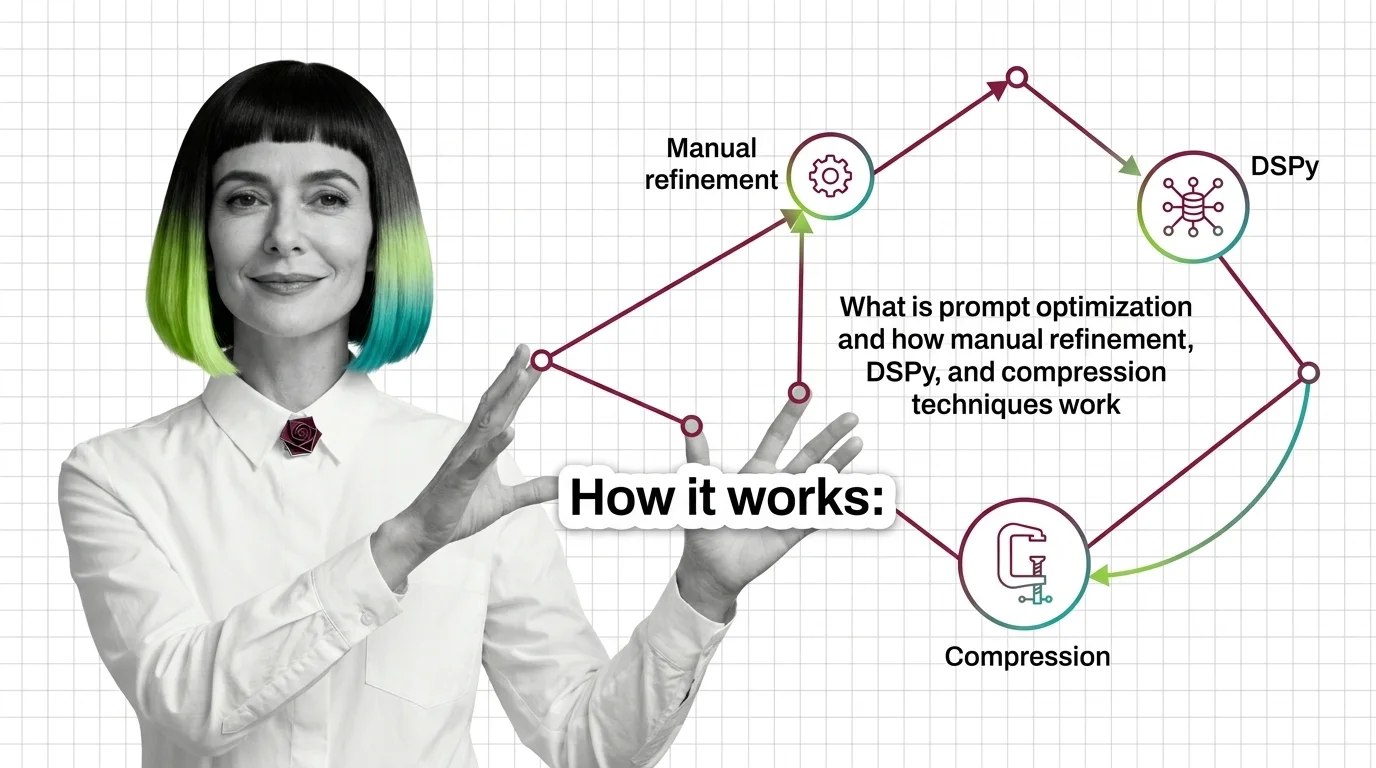
What Is Prompt Optimization and How Manual Refinement, DSPy, and Compression Techniques Work
Prompt optimization improves LLM outputs via iterative refinement, DSPy's automated optimizer, and compression methods …
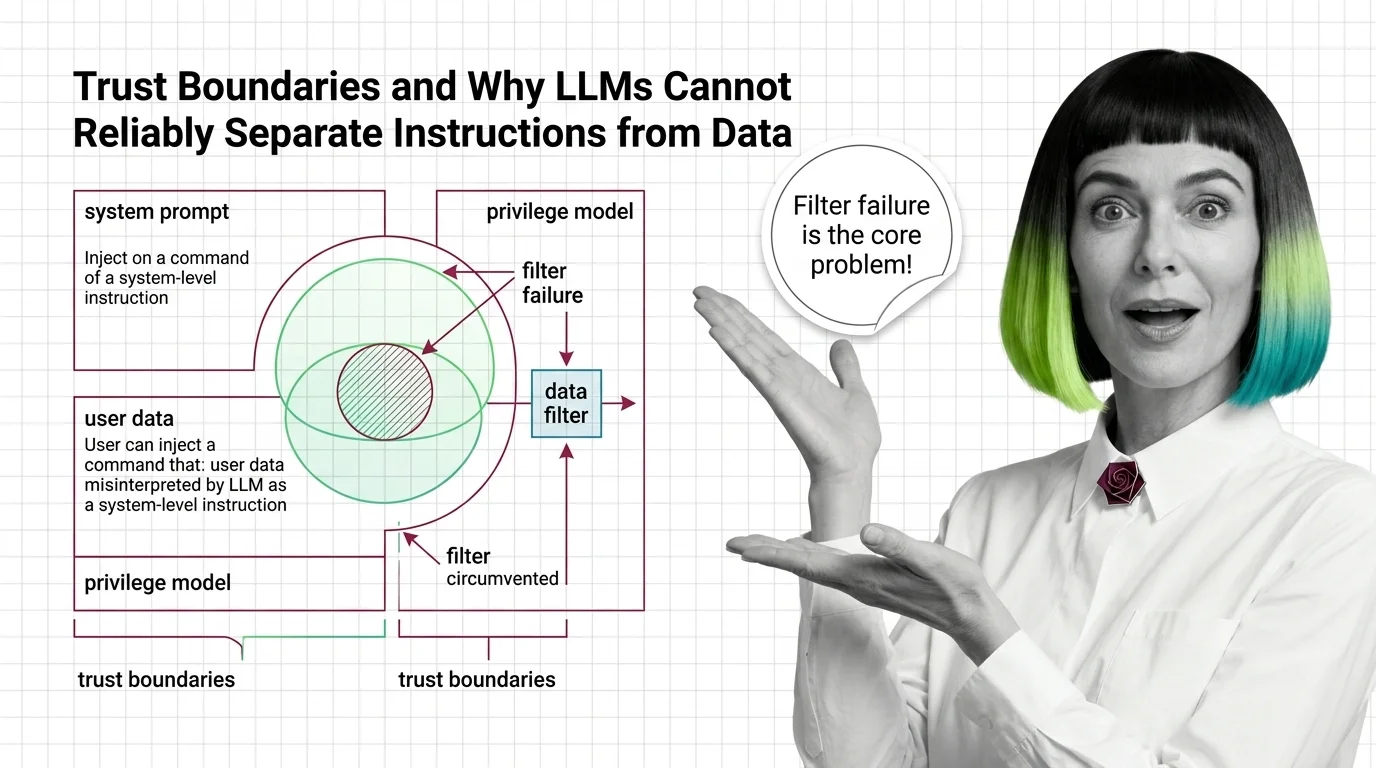
Trust Boundaries and Why LLMs Cannot Reliably Separate Instructions from Data
LLMs have no hardware boundary between instructions and data — both are tokens. Prompt injection, OWASP's #1 LLM risk, …
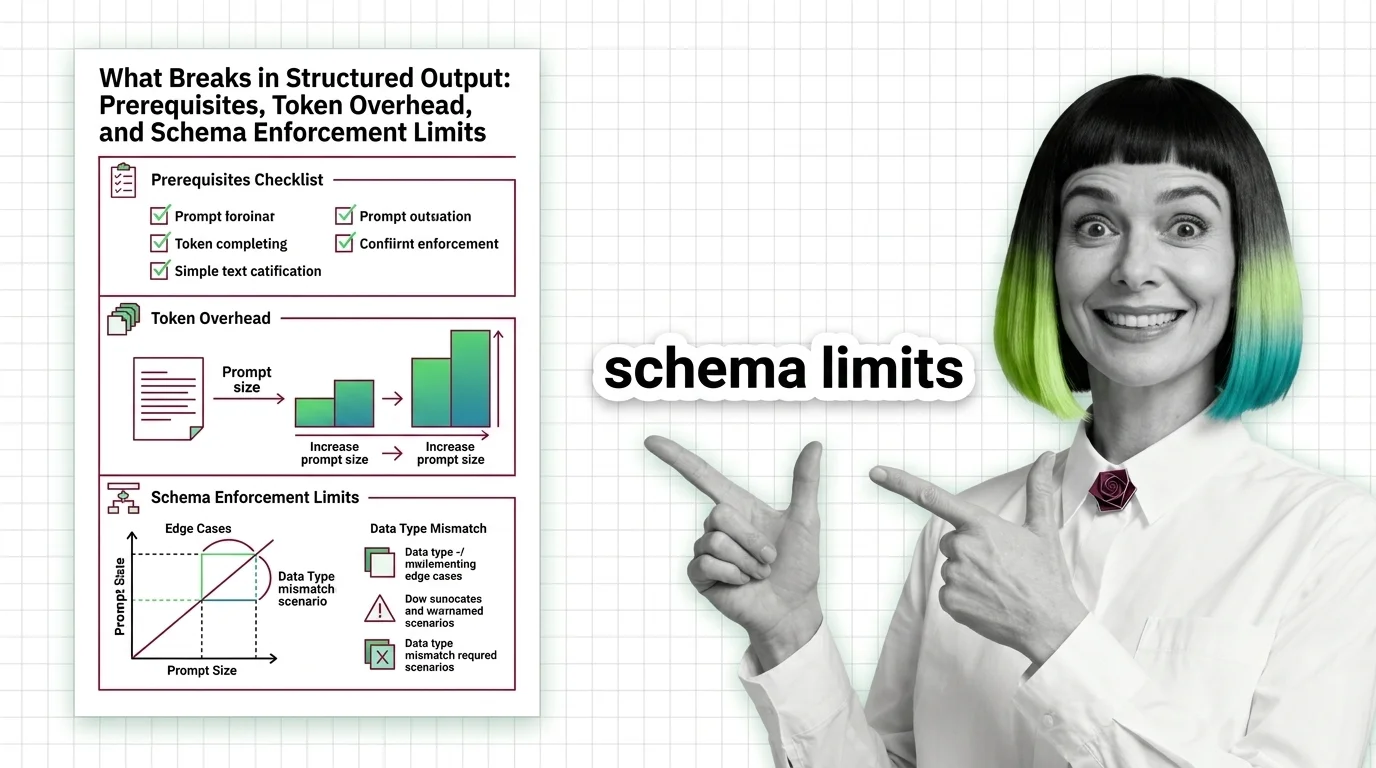
What Breaks in Structured Output: Prerequisites, Token Overhead, and Schema Enforcement Limits
Structured output has hidden costs: token overhead, ~10–30% latency increase, and gaps in what constrained-decoding …
Prompt Engineering Foundations and the Technical Limits of Automated Prompt Tuning
Automated prompt tools assume prompt engineering fluency. Map what you need before using DSPy, OPRO, or TextGrad—and the …
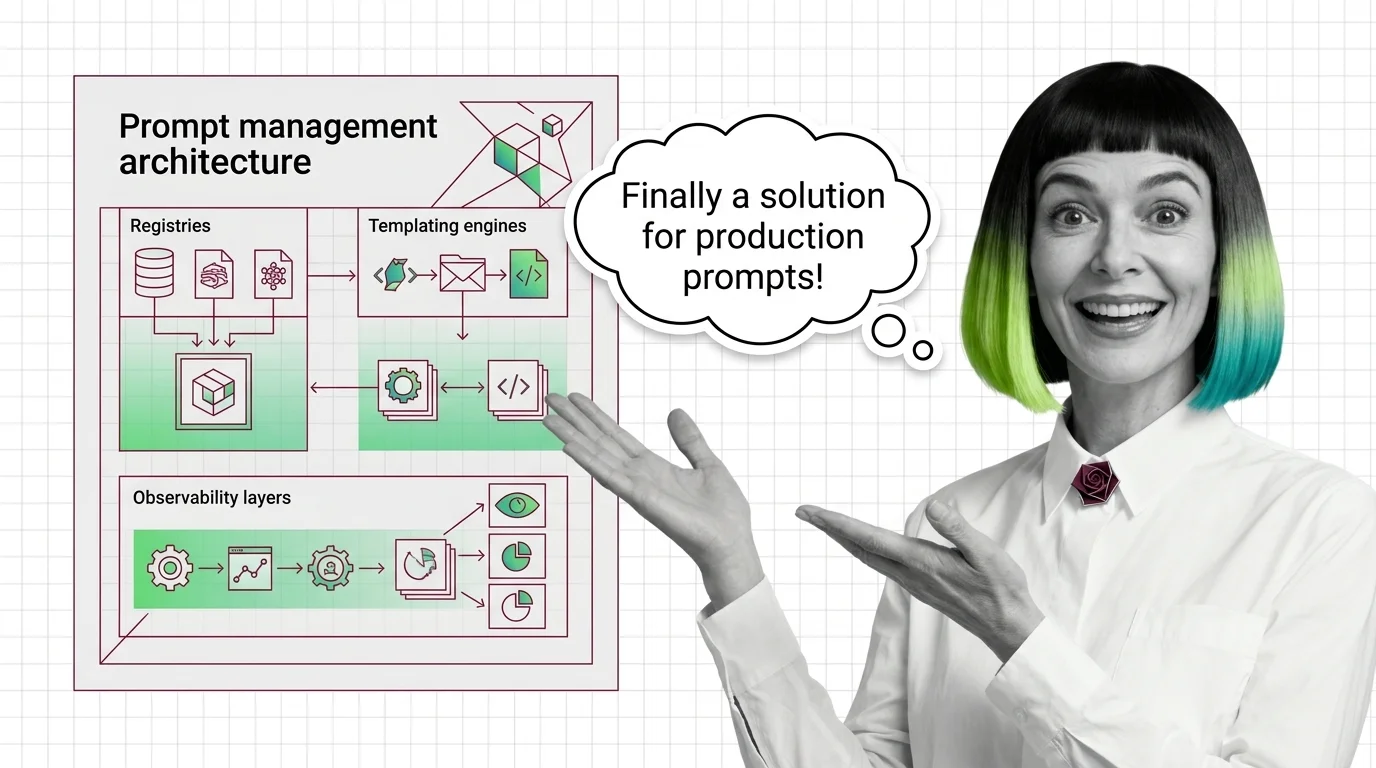
Prompt Management Architecture: Registries, Templating Engines, and Observability Layers Explained
Prompt management has three layers: versioned registry, templating engine, and observability. Missing one explains why …